Tag: Amazon Conversion Rate

  • Your Amazon Images Aren’t Ugly — They’re Answering the Wrong Questions

    Your Amazon Images Aren’t Ugly — They’re Answering the Wrong Questions

    Pull up almost any mid-ranking Amazon listing in a crowded category and you’ll see the same thing. The photography is clean. The lighting is professional. There’s an infographic with icons, a lifestyle shot with a smiling model, and a “what’s in the box” flat-lay. Nothing about it is bad.

    And yet the listing converts at a fraction of the rate of the competitor two spots above it, whose images look, if anything, slightly less polished.

    This is the most common image problem on Amazon in 2026, and it’s rarely an aesthetics problem. It’s a relevance problem. The images are answering questions the shopper never asked, while ignoring the two or three doubts that actually stop them from clicking “Add to Cart.”

    Most advice on Amazon listing images focuses on specs and styling: hit 1600 pixels, use a pure white background, add a lifestyle shot, include an infographic. That advice is correct, but it’s the floor, not the ceiling. Every serious competitor already does it. What separates a well-performing image stack from a forgettable one is whether each image was planned around a specific buyer hesitation.

    This article takes that angle all the way through. Instead of a checklist of image types, you’ll get a process: how to mine your reviews, Q&A, and return reasons for the objections that matter; how to assign one job to each image slot; how to write a brief that a photographer or designer can actually execute; how to make text readable on a phone held at arm’s length; and how to test changes without fooling yourself with noisy data.

    If you’ve already got “good” images and you’re wondering why they aren’t pulling their weight, this is for you.
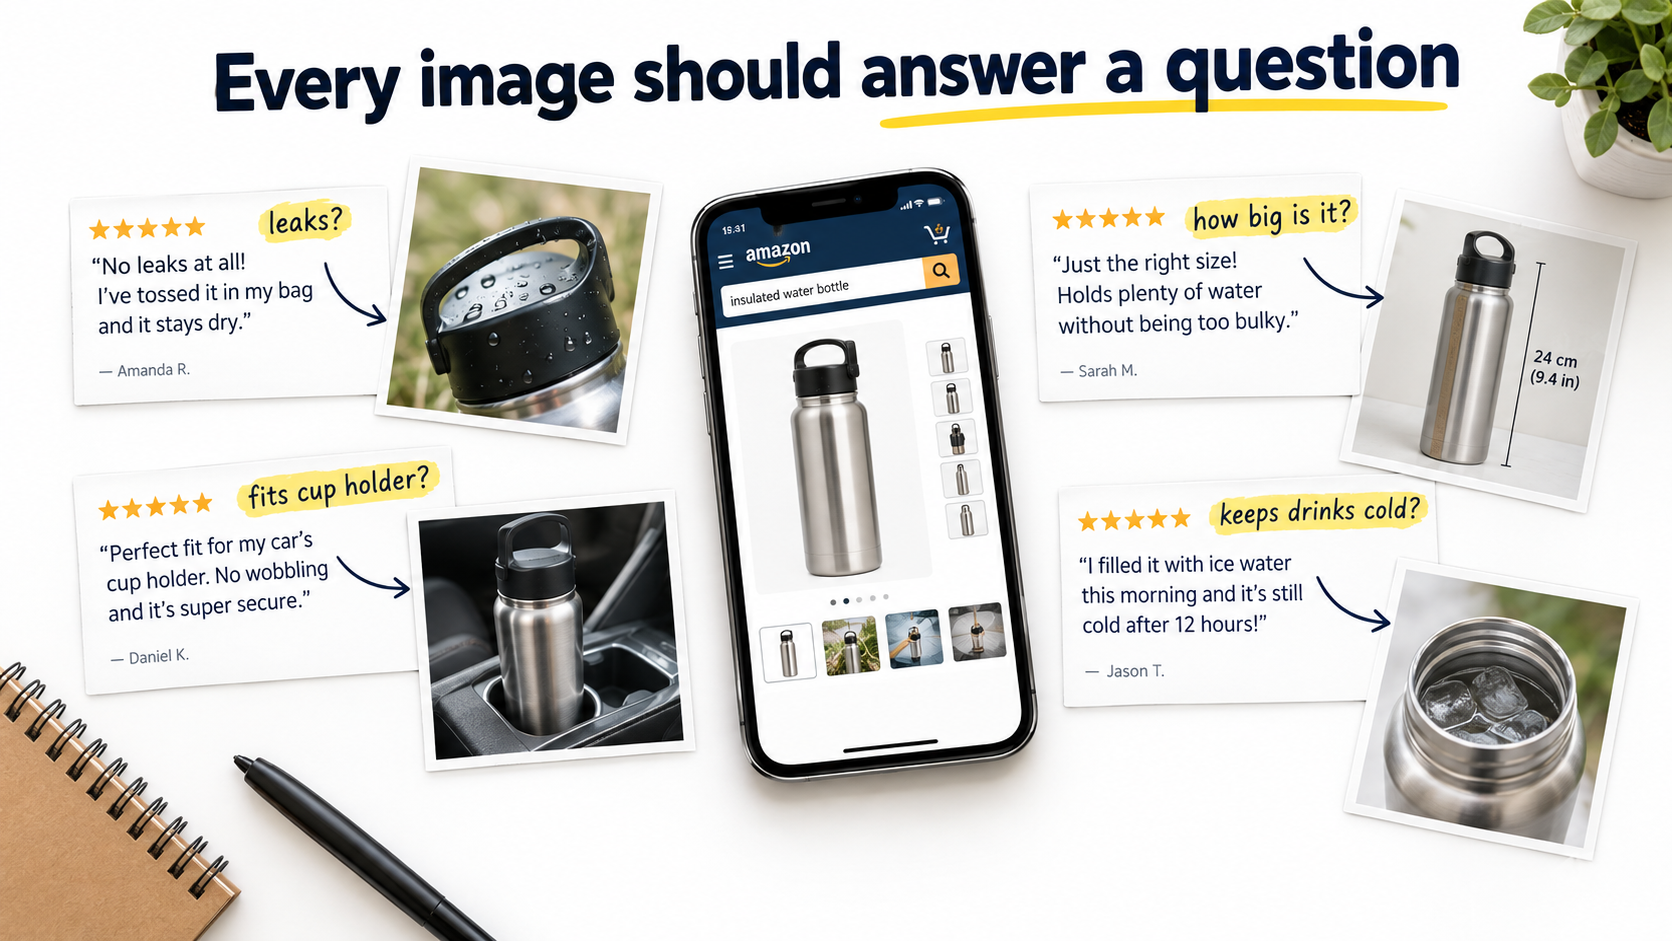
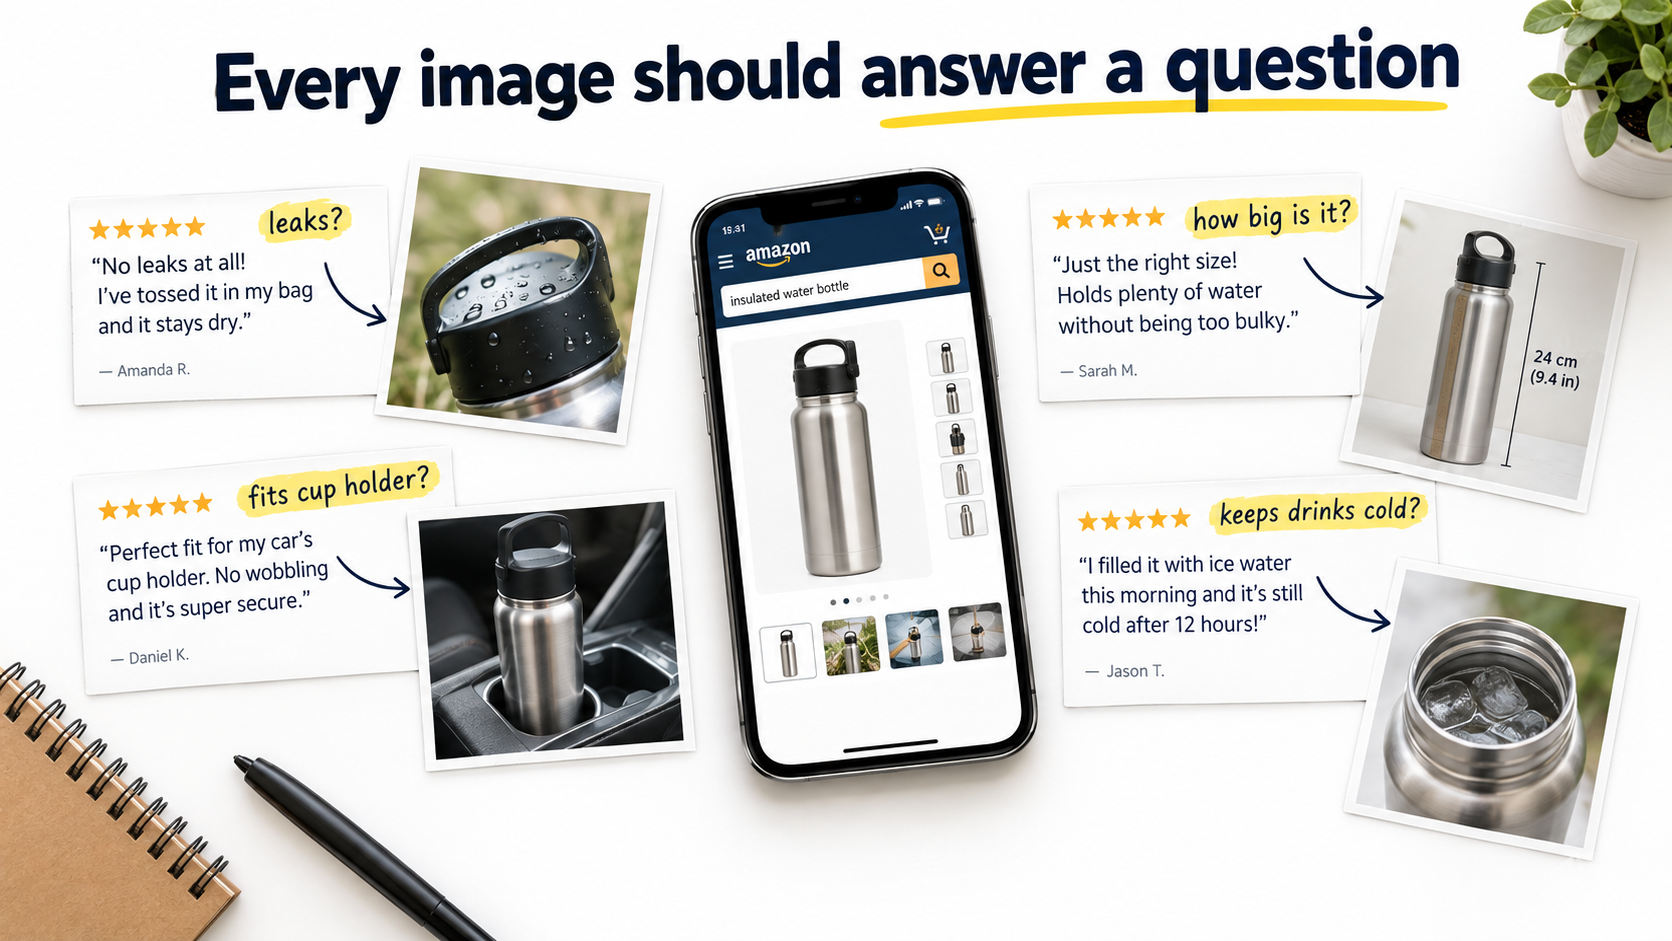
    Seller desk with a phone showing an Amazon product gallery surrounded by customer review snippets connected by arrows to matching product photos, headline reads Every image should answer a question

    Why Good-Looking Images Still Fail to Convert

    An Amazon shopper on a product detail page is not browsing a magazine. They’re running a quick, mostly subconscious risk assessment. Will this fit? Will it break? Is it the size I think it is? Does it work with the thing I already own? Is it worth more than the cheaper option I just saw?

    Images are the fastest way to answer those questions, because most shoppers swipe through the gallery before they read a single bullet point. If the gallery resolves their doubts, they buy. If it doesn’t, they hit the back button and try the next listing. The beauty of the photography is a secondary factor at best.

    The “brochure” trap

    Many image sets are designed like a brand brochure. They lead with mood, lifestyle, and broad claims (“Premium Quality,” “Built to Last,” “Perfect Gift”). These claims are unfalsifiable, which means shoppers have learned to ignore them. Every competing listing makes the same claims with the same stock-style icons.

    Brochure-style images feel productive to create because they look finished. But they spend valuable gallery slots on reassurance that doesn’t reassure anyone. A shopper worried that a lunch box leaks is not comforted by a photo of a family picnic. They want to see the lunch box upside down, full of soup, with nothing dripping out.

    The “feature dump” trap

    The opposite failure is the infographic stuffed with every feature the product has. Twelve callouts, three fonts, and arrows pointing everywhere. The logic is understandable: if each feature might matter to someone, why not show them all?

    The problem is that equal emphasis on everything means no emphasis on anything. The one feature that actually decides the purchase gets the same visual weight as a trivial detail. On a phone screen, most of the text becomes unreadable anyway.

    What high-converting image stacks do differently

    The listings that consistently outperform tend to share one trait: their images feel like they were made by someone who read the reviews. They show the exact thing people worried about. They show scale in the context people care about. They pre-empt the most common complaint about the category. They feel specific rather than generic.

    That specificity isn’t an accident of good taste. It comes from a deliberate research step that most sellers skip entirely, which is where the process starts.

    Start With Objections, Not Aesthetics: Mining the Data You Already Have

    Before anyone picks up a camera or opens a design tool, you need a ranked list of the reasons people hesitate to buy your product, or products like it. You already have most of this data. It’s just scattered across several places.

    Source 1: Your own reviews (especially 3-star)

    Five-star reviews tell you what delighted people. One-star reviews often reflect shipping damage, defective units, or mismatched expectations. Three-star reviews are frequently the most useful, because they come from customers who liked the product but had a specific reservation.

    Read through them and note every recurring phrase. “Smaller than I expected.” “Wish it came with a case.” “Hard to tell from the photos that it’s matte.” “The lid is tricky at first.” Each of these is a gap your images failed to close before purchase.

    Source 2: Competitor reviews

    If your listing is new or has few reviews, your competitors have done the market research for you. Read the critical reviews on the top five to ten listings in your niche. Category-wide complaints show up fast. If every competing blender gets complaints about noise, then noise is a buyer concern for the whole category, and whoever addresses it visually gains an edge.

    Source 3: Customer questions on the detail page

    The questions section is a direct record of what shoppers couldn’t figure out from your listing. Questions like “Will this fit a 2019 model?” or “Is the fabric see-through?” are essentially requests for a specific image. If the same question appears repeatedly, your gallery has a hole in it.

    Source 4: Return reasons and buyer messages

    Return reason codes and buyer-seller messages reveal expectation mismatches. A cluster of “not as described” or “too small” returns usually means the images set the wrong expectation. Fixing that is a two-for-one: it can lift conversion and reduce returns at the same time, because you’re attracting buyers who know exactly what they’re getting.

    Building the objection map

    Pull everything into a simple spreadsheet with four columns:

    • Objection: phrased the way the customer would say it (“Does it leak?”).
    • Source: reviews, competitor reviews, Q&A, returns, or messages.
    • Frequency: a rough count of how often it appears.
    • Image slot: which gallery position will answer it (filled in later).

    Sort by frequency. In most products, three to five objections account for the bulk of hesitation. Those become the backbone of your image plan. Everything else is secondary.
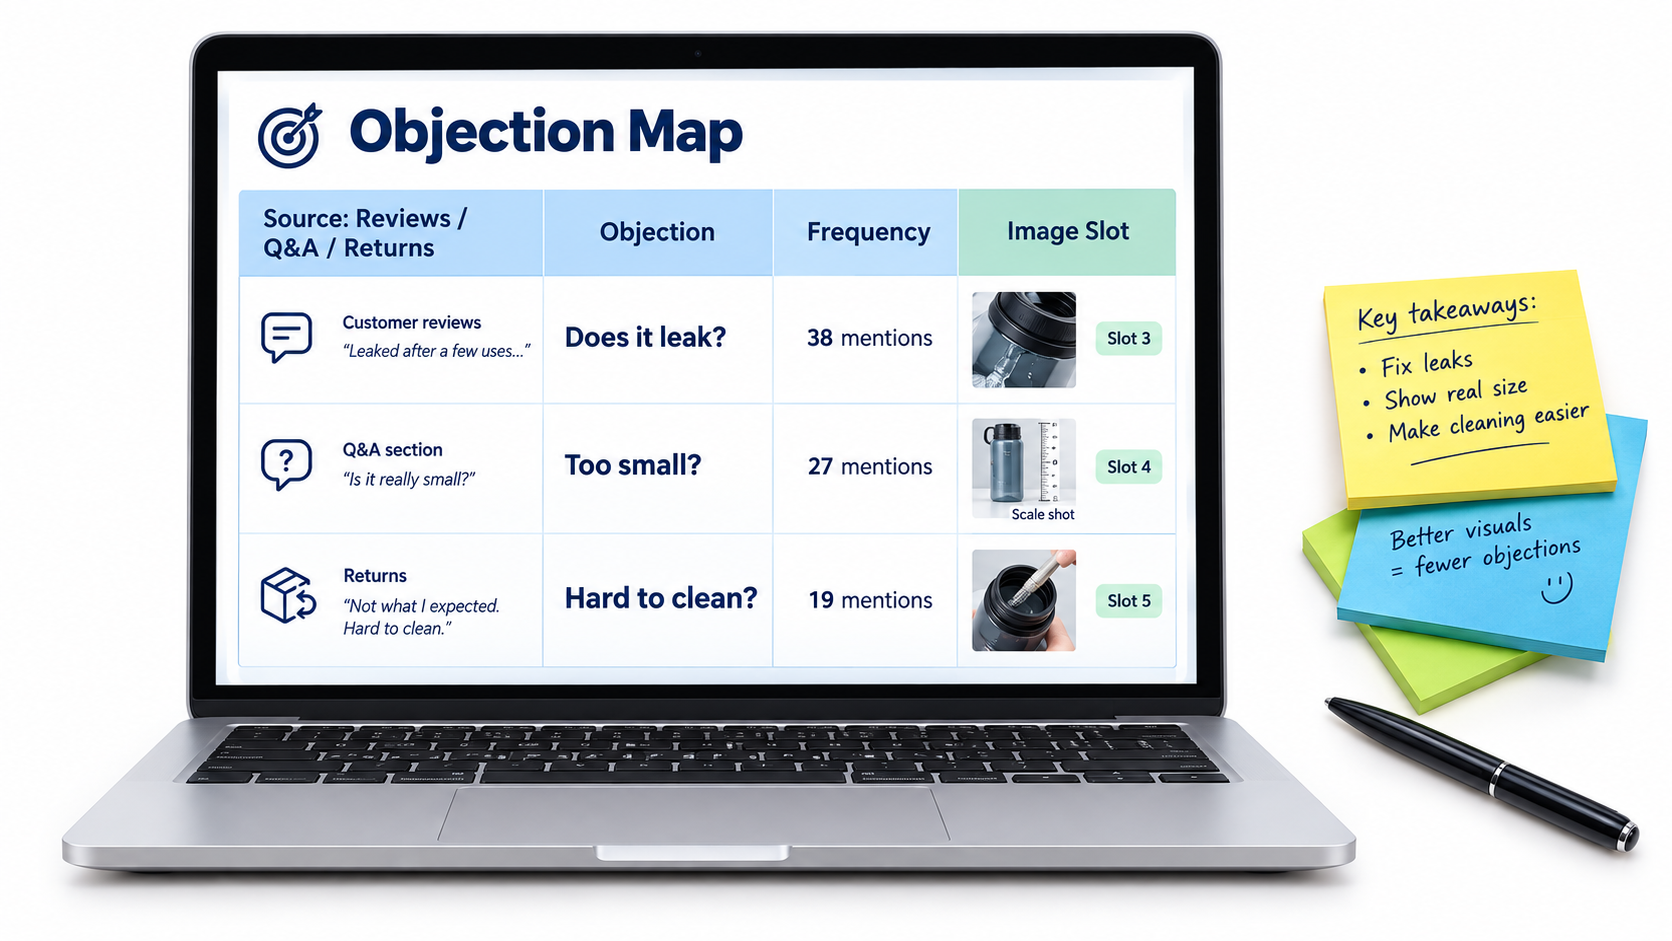
    Laptop spreadsheet titled Objection Map listing customer objections by source and frequency mapped to specific Amazon image slots

    Separate objections from desires

    Not everything on the list will be a worry. Some entries will be positive motivators: “Love that it fits in my backpack,” “Great for travel.” These are desires, and they deserve images too. But objections usually carry more weight, because a single unresolved doubt can kill a sale that five appealing features couldn’t save. Prioritize objections first, then fill remaining slots with the strongest desires.

    The Main Image: Compliance Is the Floor, the Thumbnail Is the Ceiling

    The main image has a different job from every other image in your gallery. It has to win the click in search results, where it competes against a grid of nearly identical white-background photos. And it has to do that while following Amazon’s strictest set of rules.

    The rules you can’t bend

    Amazon’s main image requirements are specific, and violating them can get a listing suppressed. As summarized by Jungle Scout from Amazon’s guidelines, the core rules include:

    • A pure white background (RGB 255, 255, 255).
    • A professional photograph of the actual product, not an illustration, mockup, or placeholder.
    • No text, logos, borders, color blocks, watermarks, or other graphics over the product or background.
    • No multiple views of a single product.
    • The entire product shown, not cut off by the frame edge (with exceptions such as necklaces).
    • No excluded accessories or props that might confuse the customer about what’s included.
    • The product shown out of its packaging, unless the packaging is an important feature.

    Across all images, Amazon specifies that the product should fill at least 85% of the frame, and that files should be 1600 pixels or larger on the longest side for the best zoom experience. Amazon’s own guidance notes that zoom “has been shown to help enhance sales.” The minimum for zoom is 1000 pixels, and JPEG is the preferred format.

    Why the thumbnail matters more than the full-size image

    Here’s the part many sellers overlook. In search results, especially on mobile, your main image is displayed at a small size. The detail you obsessed over in the full-resolution file is invisible. What matters is how the product reads as a small shape on white.

    Open the Amazon app, search your main keyword, and look at your listing among the results. Then ask:

    • Can you tell what the product is in under a second?
    • Does it look the same size as competitors, or noticeably smaller and lost in white space?
    • Does the angle show the product’s most recognizable side?
    • If it’s a multi-pack or bundle, is the quantity obvious at a glance?
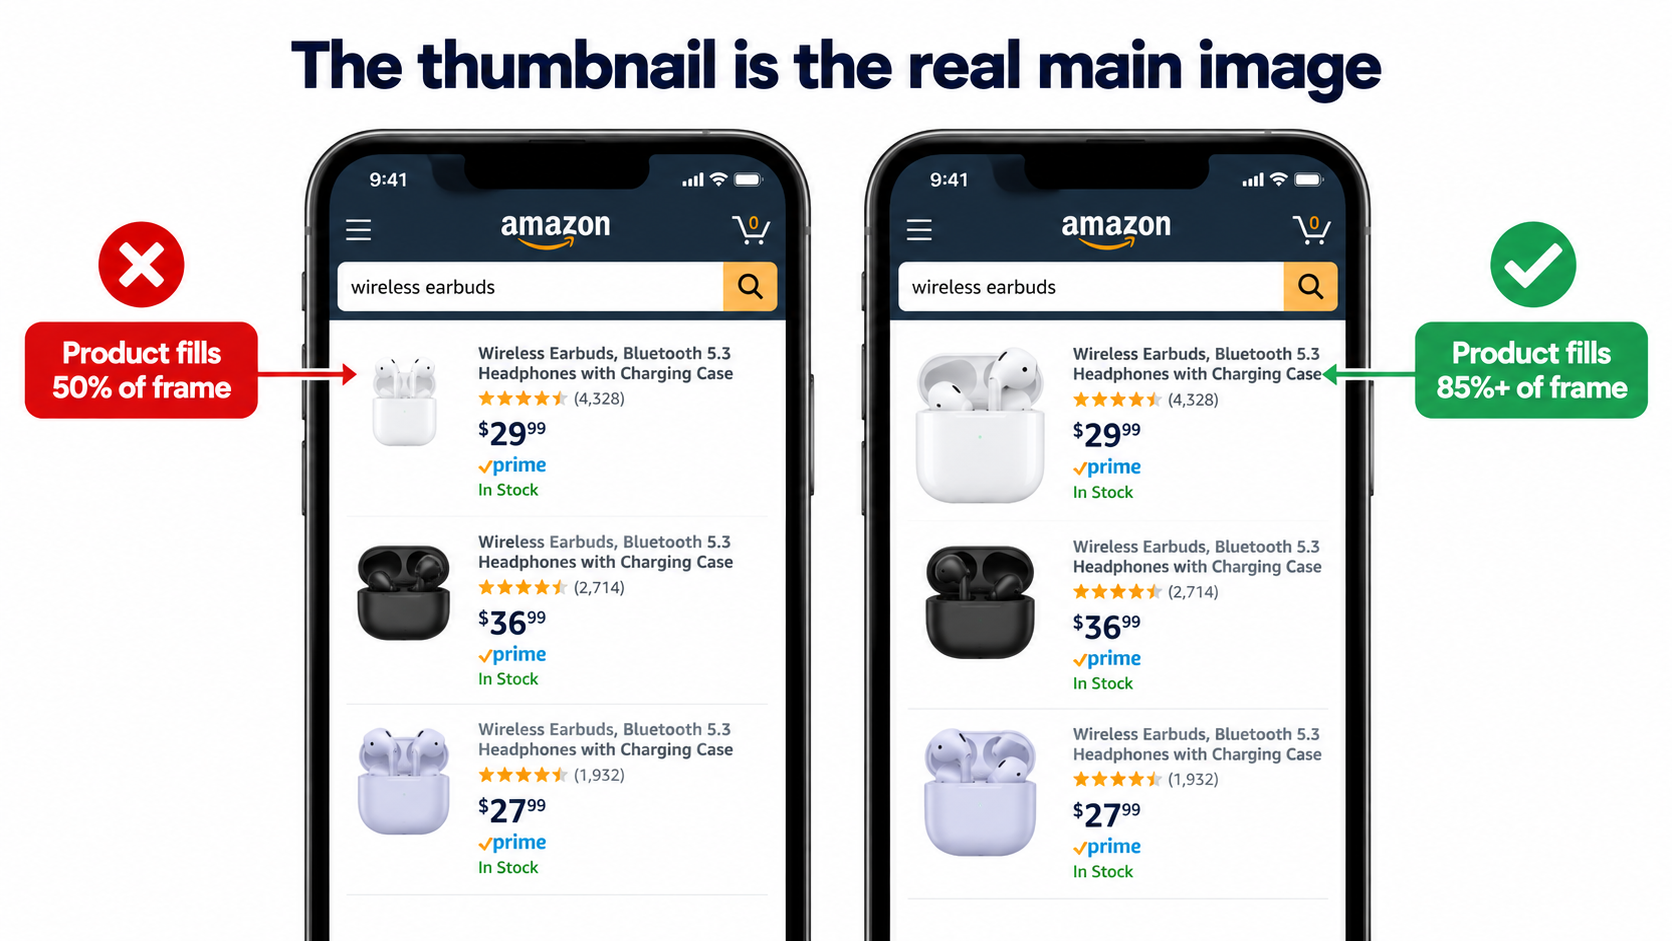
    Phone screen comparison of Amazon search thumbnails showing a product filling 50 percent of the frame versus one filling 85 percent or more

    Legitimate ways to stand out within the rules

    You can’t add badges or text, but you still have real levers:

    • Frame fill: Crop tight. A product that fills the frame looks bigger and more substantial than one floating in white space.
    • Angle: A three-quarter angle often reveals more depth and form than a flat front view. Test which angle makes your product most recognizable.
    • Showing what’s included: If your product comes with genuinely included items that competitors don’t include, showing them (without props that aren’t included) can differentiate the offer.
    • Color and finish accuracy: A true-to-life color rendering builds trust and reduces returns. Overly saturated edits can backfire when the product arrives.
    • Lighting that shows material: Subtle shadows and highlights communicate texture, which matters for products where material quality is a buying factor.

    The main image should answer the top objection if it can

    Sometimes the most common objection can be partly addressed even in the main image. If shoppers in your category worry about quantity, a clean arrangement showing all units in the pack does that. If they worry about whether a cable is long enough, a neatly coiled cable that visibly reads as long helps. The main image can’t explain, but it can show.

    One Job Per Slot: Turning the Gallery Into a Sequence

    Once the main image wins the click, the remaining images have to win the sale. The most effective way to plan them is to give each image exactly one job, tied to an entry on your objection map.

    Why sequence matters

    Shoppers swipe through images in order, and many don’t reach the end. That means the order you choose is effectively a ranking of importance. The objection that blocks the most sales should be answered early, not buried in the sixth slot behind a lifestyle photo.

    A sample slot plan

    Every product is different, but a sequence like this works as a starting framework:

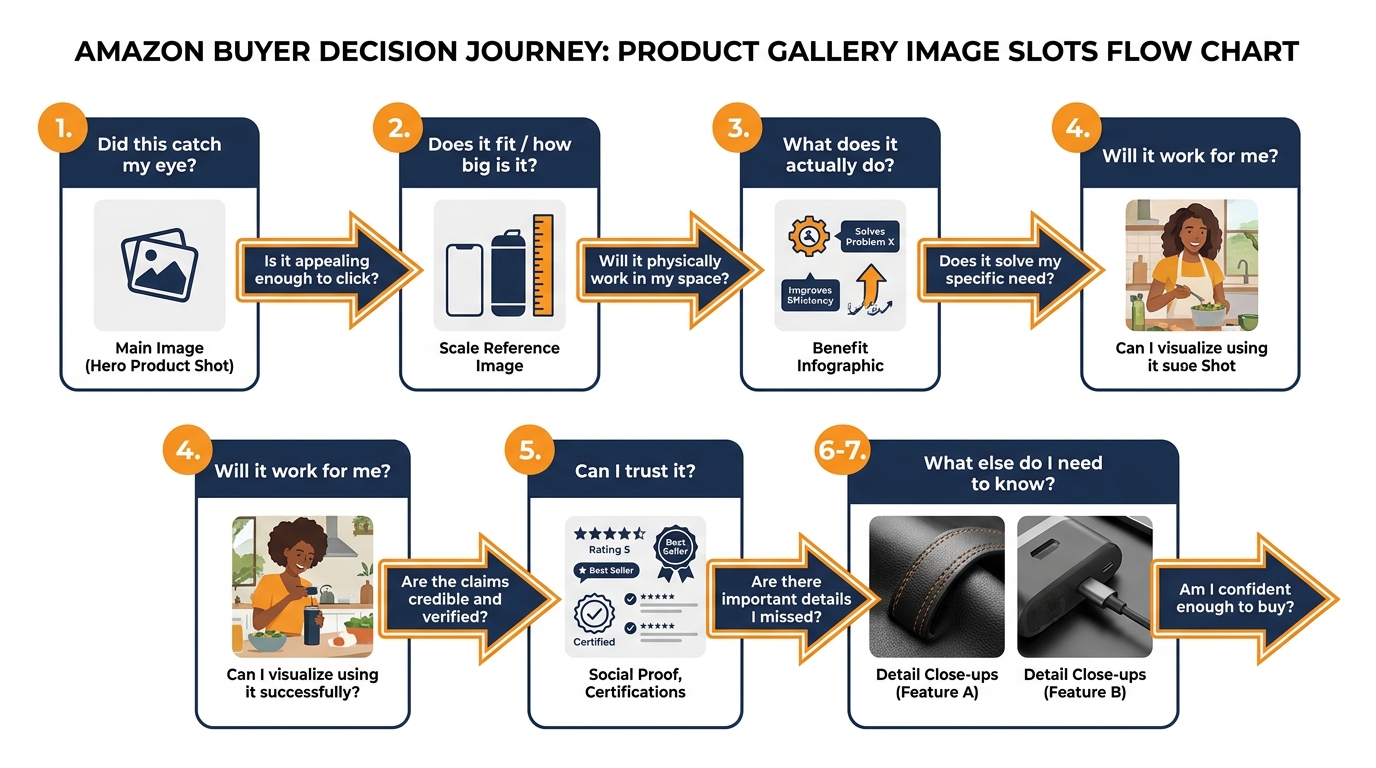
    1. Main image: What is it? Clean, compliant, thumbnail-readable.
    2. Primary benefit: The single biggest reason to choose this product, shown visually with a short headline.
    3. Top objection resolved: Proof of the feature people doubt most (leak-proof, waterproof, quiet, durable).
    4. Scale and fit: The product in a hand, on a body, next to a common object, or in its intended space, with dimensions.
    5. In use: A realistic context showing how and where it’s used, aimed at the primary customer.
    6. What’s included: Every component, clearly laid out, so there are no surprises.
    7. Second objection or comparison: Care instructions, compatibility, or a comparison against generic alternatives (without naming competitors).
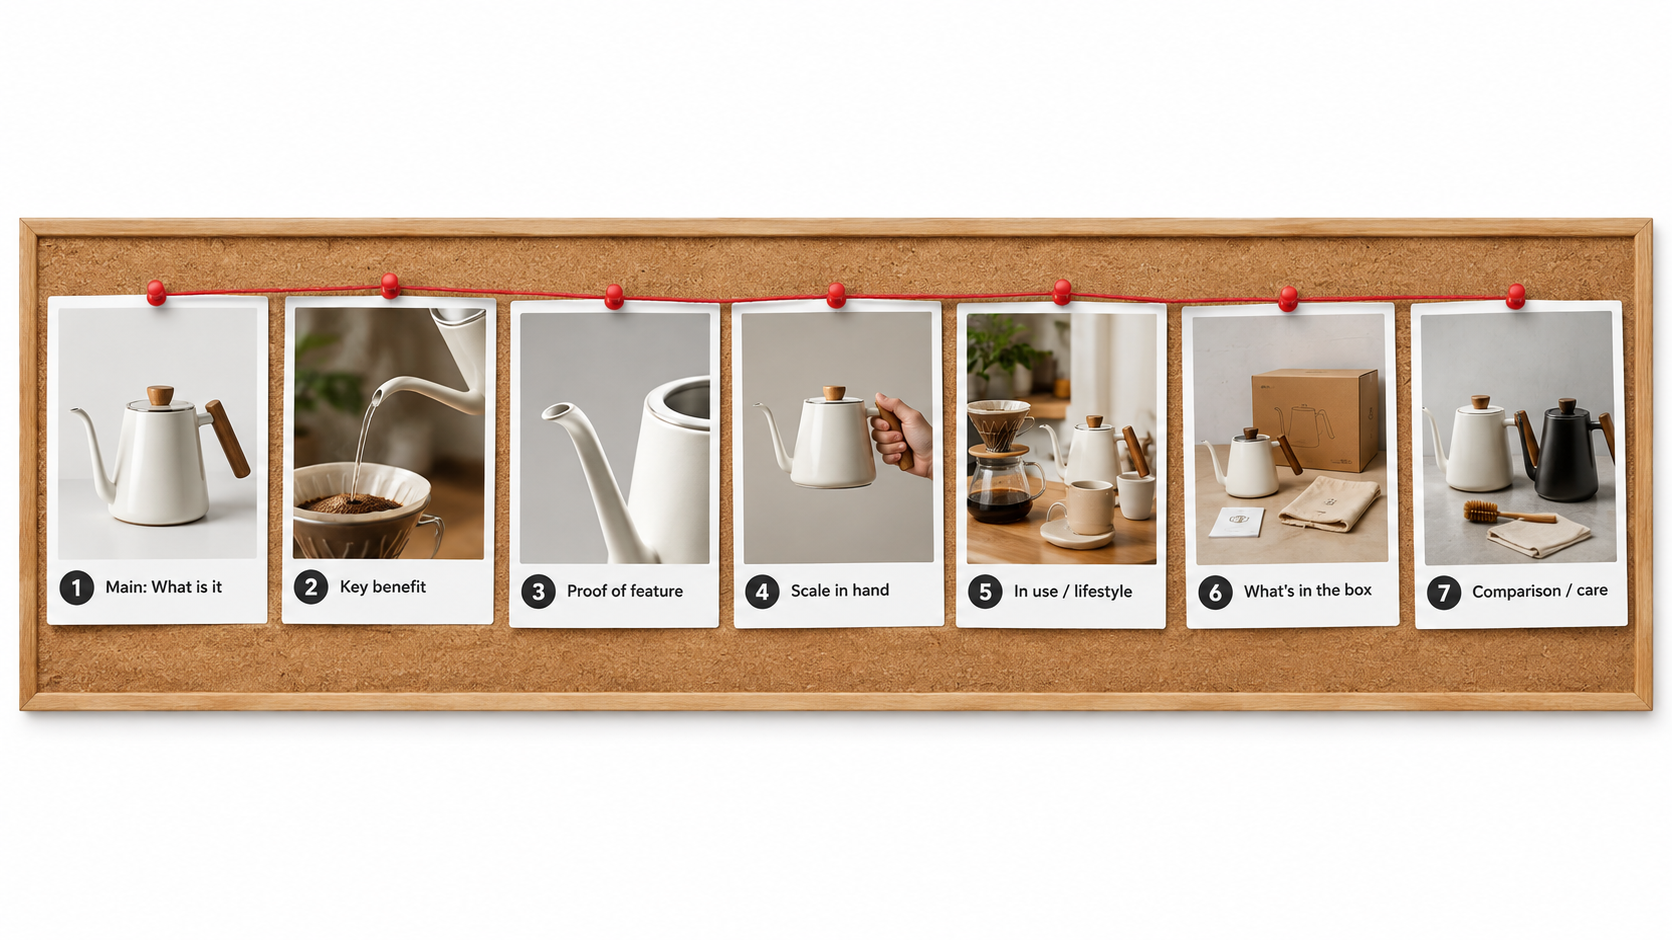
    Corkboard storyboard of seven Amazon image cards for a coffee kettle, each labeled with its job from main image to comparison and care

    Proof beats claims

    Notice that the plan above emphasizes demonstration. “Leak-proof” as a text label is a claim. A photo of the container upside down over a white shirt is proof. “Durable” is a claim. A close-up of reinforced stitching with a short label explaining the stitch count is evidence.

    Whenever you can, convert a claim into a visual demonstration. Shoppers discount claims automatically. They take demonstrations seriously.

    Scale is the most underrated slot

    “Smaller than expected” is one of the most common complaints across Amazon categories. Dimension text alone doesn’t fix it, because most people can’t picture 7.5 inches. A scale image does: the product in an average adult hand, next to a smartphone, inside a standard kitchen drawer, or worn by a model with height listed.

    If scale shows up anywhere on your objection map, give it a dedicated slot with both a visual reference and printed dimensions.

    Lifestyle images need a target, not a mood

    Lifestyle photos are often the weakest images in a gallery because they’re made to look aspirational rather than relevant. A better approach: identify your primary customer from your reviews (who’s actually buying and why) and show that person in that context. If reviews show your camping stove is mostly bought by people for emergency kits, a remote mountain scene misses the point. A shot of it in a home preparedness kit speaks directly to the buyer.

    Use your video slot deliberately

    If you have access to video on your listing, treat it as an extension of the same plan rather than a separate brand film. A short clip demonstrating the top objection being resolved (the lid sealing, the fabric stretching, the device pairing) often does more than a cinematic montage.

    Writing the Image Brief: How to Get What You Actually Need

    Most disappointing image sets trace back to a weak brief. A seller sends a product and a note saying “need 7 Amazon images, white background plus lifestyle and infographics.” The photographer or designer, reasonably, produces a generic set. Nobody did anything wrong, but nobody solved the actual problem either.

    What a strong brief contains

    A good image brief gives the creative team the “why” behind each image, not just the “what.” For each slot, include:

    • Slot number and job: “Slot 3: prove the bottle doesn’t leak when tipped over in a bag.”
    • The objection it answers, in the customer’s words: paste two or three review quotes.
    • The single message: one sentence the viewer should take away.
    • Visual direction: composition, props, setting, angle, and what must be visible.
    • Text overlay (if any): a headline of a few words and no more than three short callouts.
    • Must-avoid items: props that could imply they’re included, unverifiable claims, competitor references.
    • Reference examples: screenshots of images (from any category) with the feel you want.

    Shot list vs. design list

    Split the brief into two parts. The shot list covers what needs to be photographed: angles, close-ups, model shots, scale shots, in-context setups. The design list covers what happens afterward: text overlays, callouts, arrows, comparison layouts.

    This split prevents a common problem: discovering during design that you needed a specific angle or close-up that was never shot. Planning the overlay first tells the photographer exactly which raw shots to capture, including extra negative space where text will sit.

    Shoot more than you need

    Ask for alternates on your most important slots, particularly the main image and the top-objection image. Two or three angles for the main image give you material for testing later without a reshoot. A reshoot to get one alternate angle costs far more than capturing it during the original session.

    Specify the product variants up front

    If your listing has color or size variations, decide early whether each variant gets its own full image set or only a unique main image with shared secondary images. Shoppers who switch variants and see images of the wrong color lose confidence quickly. At minimum, each variant’s main image should show that exact variant.

    A sample brief entry

    Slot 4 — Scale and fit. Objection: “Smaller than I thought” (appears in 14 reviews, 6 questions). Message: “Holds a full-size laptop and still fits under an airplane seat.” Visual: backpack on a woman of average height (list height in a small caption), shot from the side; inset photo of a 15-inch laptop sliding into the sleeve. Text: headline “Fits 15" laptops” plus dimensions. Avoid: airline logos, any item not included in the box appearing as if it’s part of the product.

    A brief like this takes longer to write. It also turns a generic image set into one that was built to sell this specific product to these specific buyers.

    Text on Secondary Images: Designing for a Phone at Arm’s Length

    Secondary images can include text, and done well, text overlays make images dramatically clearer. Done poorly, they turn into unreadable clutter that shoppers swipe past.

    The arm’s-length test

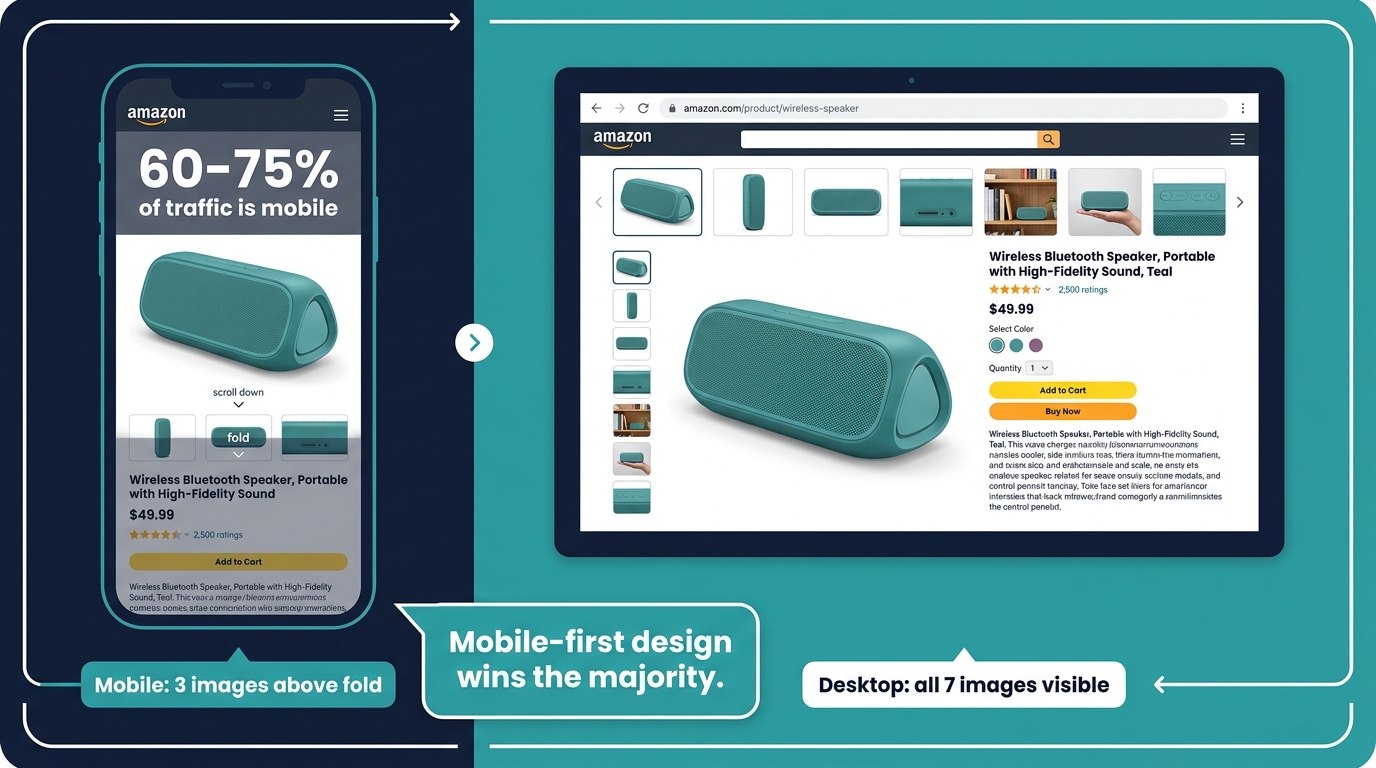
    Most Amazon browsing happens on phones. Before approving any image with text, view it on a phone at normal holding distance, not zoomed in, not on a desktop monitor. If you have to squint, the text is too small or there’s too much of it.

    A practical rule: if a callout can’t be read comfortably on a phone without zooming, cut it or enlarge it. Designers working on large monitors routinely underestimate how small their text becomes on a mobile screen.
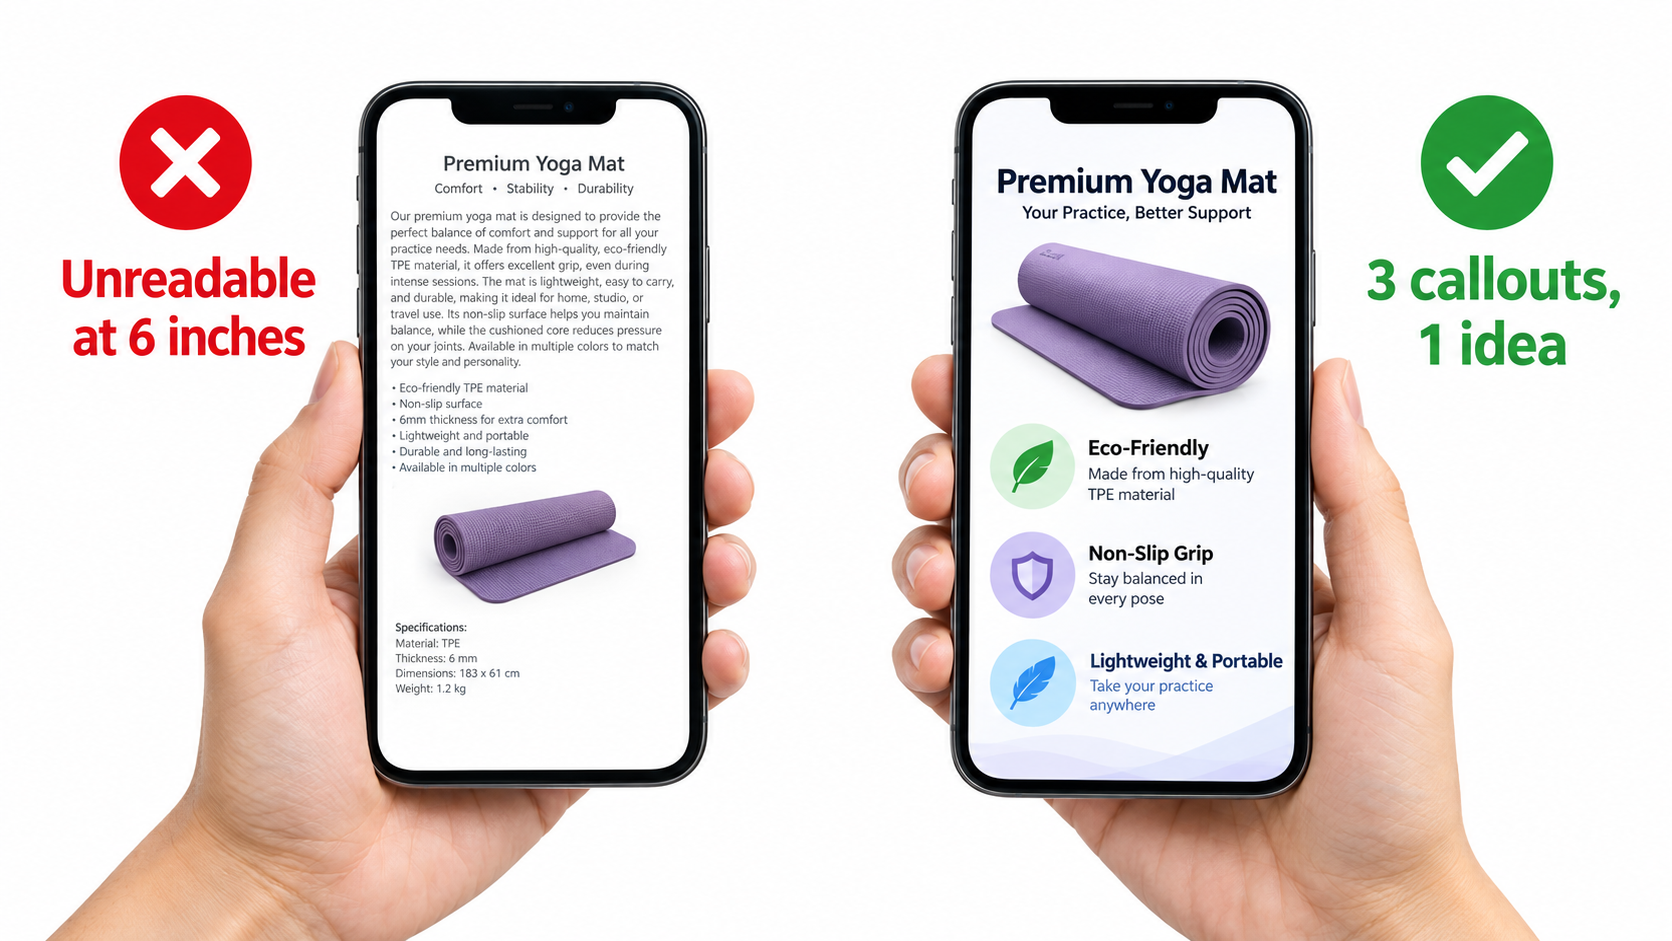
    Hand holding a phone comparing a cluttered yoga mat infographic marked unreadable at arm's length with a clean version using three large callouts

    One idea per image

    Every secondary image should communicate one idea. That idea gets a headline of a handful of words. Supporting callouts, if any, should be limited to around three. If you find yourself needing six callouts, you probably have two or three images’ worth of content crammed into one.

    Hierarchy and contrast

    • Headline first: The largest, boldest text states the benefit, not the feature name. “Stays cold 24 hours” beats “Double-wall vacuum insulation.”
    • Supporting detail second: Smaller text can explain the how (“double-wall vacuum insulation”) for shoppers who want it.
    • High contrast: Dark text on light areas or light text on dark areas. Avoid placing text over busy parts of a photo.
    • Consistent fonts: One or two typefaces across the whole gallery. Mixed fonts make the set feel assembled rather than designed.

    Icons are not a substitute for proof

    Icon rows (“BPA-free,” “Dishwasher safe,” “Eco-friendly”) are common because they’re fast to produce. They can be useful as a quick summary, but they shouldn’t occupy a high-priority slot. They’re the visual equivalent of bullet points, and they don’t demonstrate anything. If “dishwasher safe” is a real buying concern in your category, show the product on a dishwasher rack.

    Write for shoppers who won’t read bullets

    A useful mindset: assume some shoppers will never scroll to your bullet points. If the gallery were the only thing they saw, would they understand the product, its key benefit, its size, what’s included, and why it’s better than the alternative? If not, the gallery has gaps that text overlays can fill.

    Don’t contradict the rest of the listing

    Make sure numbers in your images match your title, bullets, and product specs. Mismatched dimensions or capacities between an infographic and the bullet points erode trust and can lead to returns. Amazon’s guidelines also require that images accurately represent the product and match the product title.

    Category Rules That Change Your Image Strategy

    Amazon’s image requirements aren’t uniform across categories. Some of the most important rules apply only to certain product types, and getting them wrong can mean suppression rather than just lower conversion.

    Apparel and accessories

    According to Amazon’s guidelines as summarized by Jungle Scout, main images for women’s and men’s clothing must show the product on a human model. Multi-pack apparel items and accessories must be photographed flat (off-model) for the main image. Clothing accessories’ main images must not show any part of a mannequin, including clear or hanger-style forms. All images of kids’ and baby clothing must be photographed flat, off-model.

    For apparel, the objection map is usually dominated by fit, fabric feel, and sheerness. Secondary images should show fit from multiple angles, close-ups of fabric texture, and, where relevant, model height and size worn. A size chart image is also valuable, as long as it’s legible on mobile.

    Footwear

    Main images of shoes must show a single shoe, facing left at a 45-degree angle. Secondary images commonly address sole construction, interior comfort, width, and how the shoe looks on foot. Sizing is often the dominant objection, so an image explaining how the sizing runs can directly reduce returns.

    Models and poses

    Amazon’s main image rules state that a human model must not be shown sitting, kneeling, leaning, or lying down, though showing various physical mobilities with assistive technology like wheelchairs or prosthetics is encouraged. Keep this in mind for any category where a model appears in the main image.

    Consumables and supplements

    For consumables, the objection map often centers on ingredients, serving size, quantity per container, taste or texture, and how long a container lasts. Clear, legible label imagery and a “how many servings” visual tend to address real buyer questions. Be especially careful with claims: anything resembling a health claim in an image is subject to the same scrutiny as claims in your text.

    Electronics and accessories

    Compatibility is usually the top objection. “Will this work with my device?” A dedicated compatibility image listing supported models or standards, plus a photo of the product connected to a common device, often matters more than a lifestyle shot. Port close-ups and cable length visuals also address frequent questions.

    Home and kitchen

    Scale, cleaning, and material are recurring themes. Showing the product in a realistic kitchen or room for scale, demonstrating cleaning ease, and close-ups of material finish tend to answer what shoppers ask about most.

    Check the current rules before every shoot

    Amazon updates its style guides, and category-specific guides can be more detailed than general rules. Before a new shoot, check Seller Central’s current image requirements and any style guide for your specific category. A compliant plan is cheaper than a reshoot after a suppression.

    Testing Without Fooling Yourself

    Once you’ve built an objection-led image stack, you’ll want to know whether it actually performs better. This is where many sellers go wrong, not because they don’t test, but because they misread the results.

    Manage Your Experiments

    Amazon’s Manage Your Experiments tool, available to brand-registered sellers on eligible ASINs with sufficient traffic, lets you run A/B tests on listing content, including main images. Traffic is split between two versions, and the tool reports results including the probability that one version outperforms the other.

    This is the most reliable way to test main images on Amazon because it controls for seasonality, ad spend, and pricing changes that affect both versions equally. If your ASIN qualifies, use it before making major main image changes.
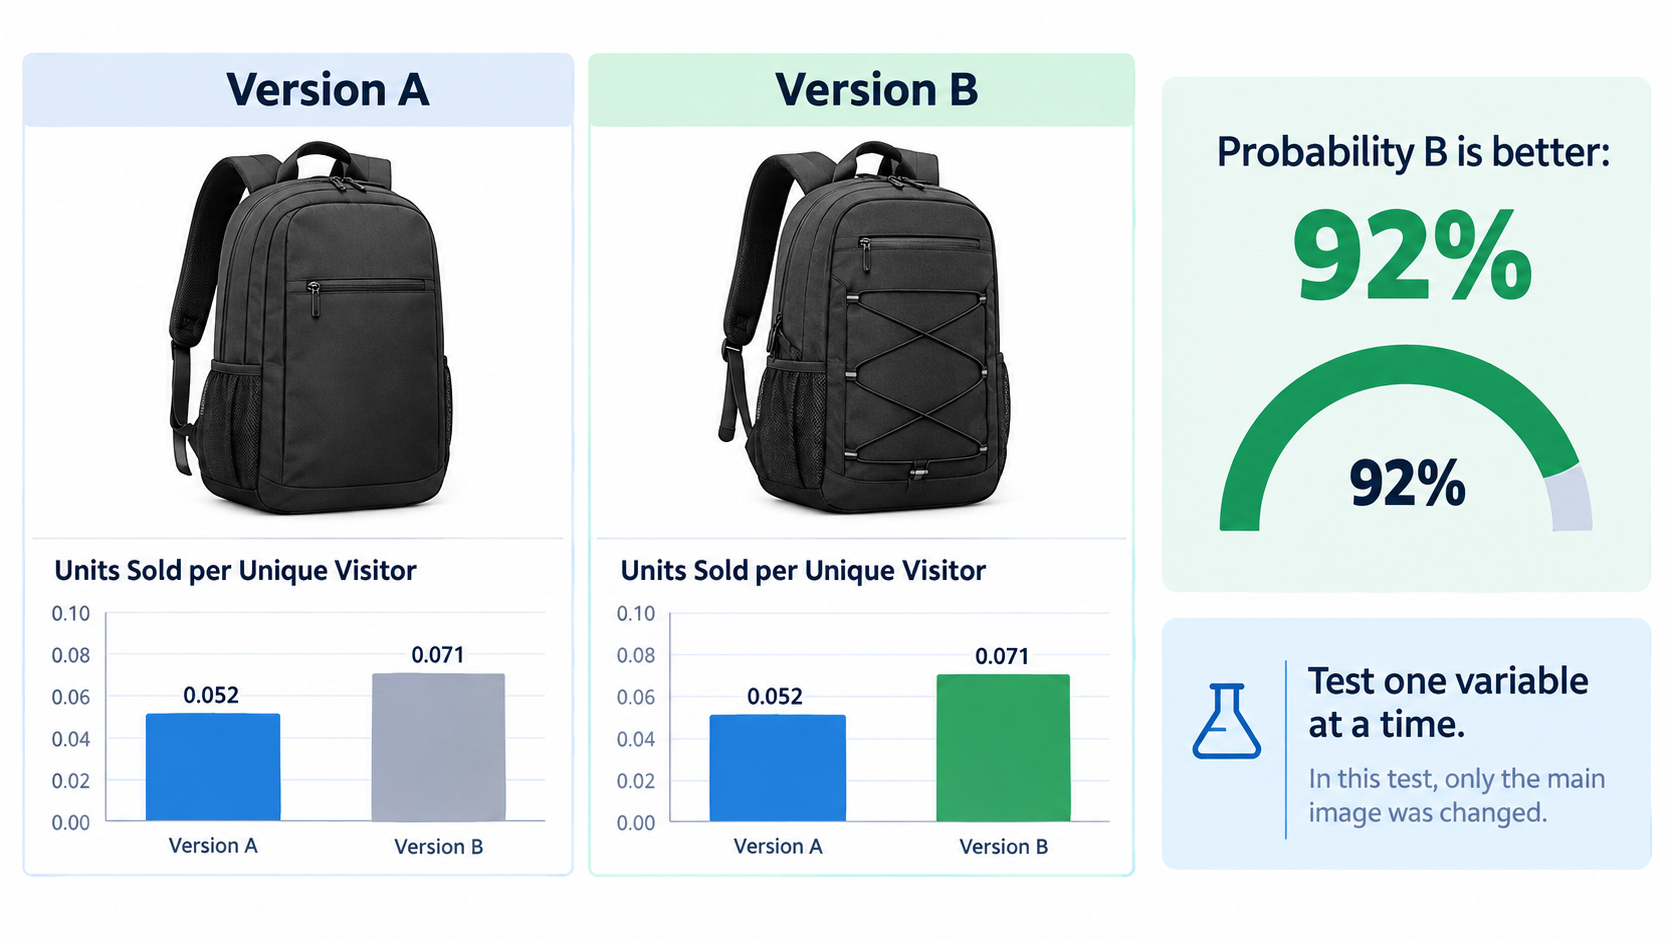
    A/B test dashboard comparing two Amazon main image versions of a backpack with charts showing units sold per visitor and a probability meter

    Rules for clean tests

    • Change one variable at a time. If Version B has a new angle, a new crop, and a new color edit, you won’t know which change mattered.
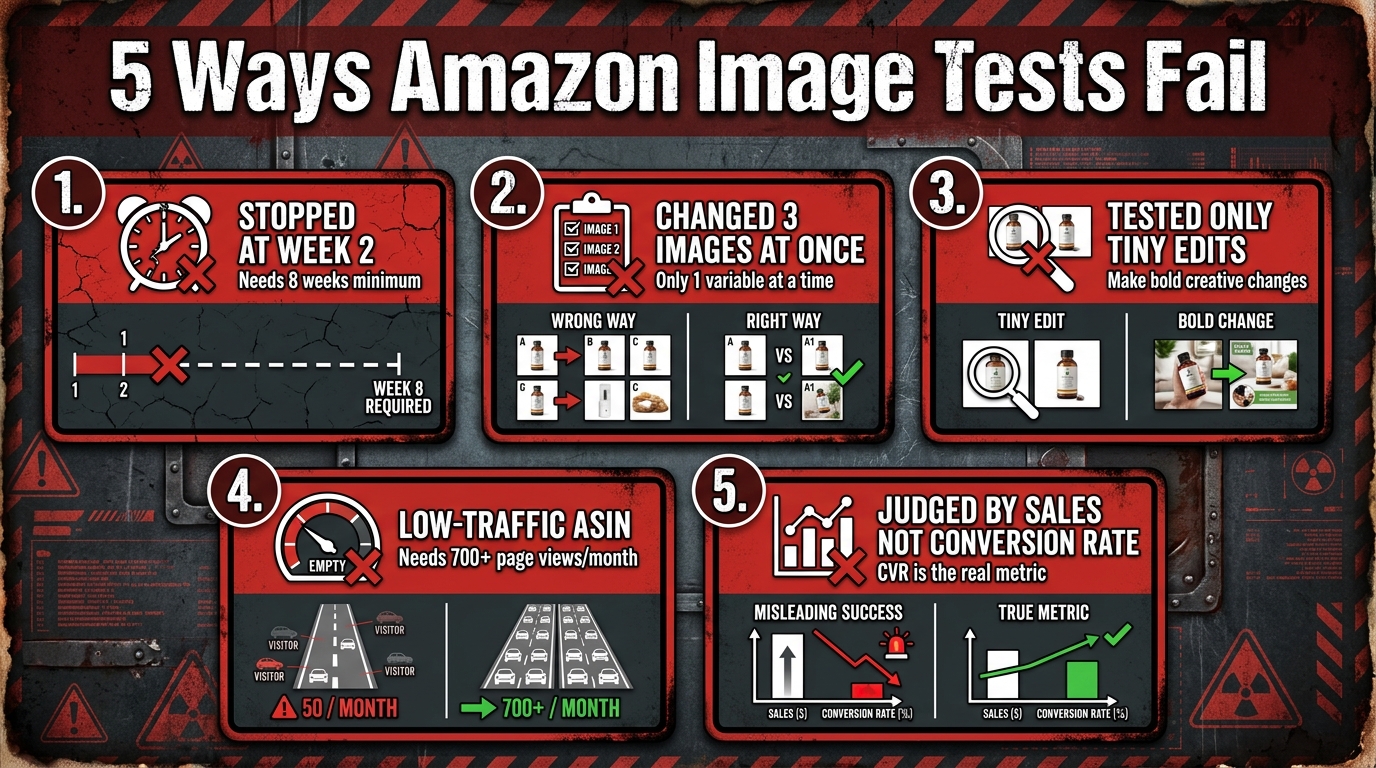
    • Let it run. Stopping a test after a few days because one version is “winning” is the fastest way to adopt a false result. Early swings are normal.
    • Avoid overlapping changes. Don’t run a major price change, coupon, or ad restructure during an image test if you can avoid it.
    • Respect inconclusive results. If neither version clearly wins, that’s useful information. It means the variable you tested isn’t what’s holding you back.

    Before-and-after comparisons are weak evidence

    If you can’t use Manage Your Experiments, you might compare conversion before and after an image change. Treat these comparisons with skepticism. A week of improved conversion after new images could reflect a competitor going out of stock, a seasonal shift, a coupon, or a change in ad traffic mix. Look at longer windows and check what else changed during the period.

    Pre-launch polling

    Consumer polling tools let you show image variations to panels of respondents and ask which they’d click or buy. These polls are fast and useful for eliminating weak options before they ever go live, especially for new listings with no traffic to test against. Their limitation is that respondents aren’t real shoppers with real intent, so treat polls as a filter, not a final verdict.

    Which metrics to watch

    For main images, click-through rate from search matters most, since the main image’s job is winning the click. For secondary images, the unit session percentage (conversion rate) on the detail page is the relevant measure. Brand Analytics data, where available, can help you compare your click and purchase share against the rest of the search results for your key terms.

    Test the objection, not just the picture

    The most valuable tests don’t compare two pretty photos. They compare two hypotheses. “Does showing the product in-hand for scale increase conversion more than showing it on a table?” A test framed this way teaches you something about your buyers that you can apply to the rest of your catalog.

    Seven Failure Patterns to Audit For Right Now

    Before redoing an entire gallery, audit what you have. These patterns show up repeatedly on underperforming listings.

    1. The main image fails the thumbnail test

    The product is too small in the frame, shot at an angle that makes it unrecognizable, or so similar to competitors that nothing distinguishes it. Fix: tighter crop, better angle, test alternates.

    2. The top objection is answered in slot 6 (or not at all)

    The thing customers worry about most is buried late in the gallery, or missing entirely. Fix: move the objection-resolving image to slot 2 or 3.

    3. Lifestyle images aimed at the wrong buyer

    The setting and model don’t match the people who actually buy. Fix: revisit your reviews to identify the real customer and use cases, then reshoot to match.

    4. No scale reference

    Dimensions exist in text, but there’s no visual comparison. “Smaller than expected” complaints keep coming in. Fix: add a dedicated scale image with a common reference object or a hand.

    5. Unreadable infographics

    Too much text, too small, too many callouts. Fix: one idea per image, a short headline, and no more than about three callouts. Check on a phone.

    6. Props that imply inclusion

    A camera shown with a microphone that’s sold separately, or a phone shown in a mount listing, without clarity about what’s included. This is both a compliance risk for main images and a source of “missing parts” returns. Fix: make inclusions unambiguous, and keep non-included items out of the main image.

    7. Inconsistency across the gallery

    Different lighting, color grading, fonts, and styles across images make the listing feel pieced together, which can quietly undermine trust. Fix: a consistent visual system across all slots.

    Running the audit

    Go through your top ten ASINs by revenue. Score each against these seven patterns. The ASINs with the most issues and the highest traffic are your best candidates for an image refresh, because they combine the most room to improve with the most visitors to benefit.

    Keeping Images Current: A Refresh Cadence That Makes Sense

    Images aren’t a one-time project. Your buyers, your competitors, and your product all change. A gallery that was well-targeted a year ago may now be answering last year’s questions.

    Triggers for a refresh

    • New recurring objections: A theme appears in recent reviews or questions that your gallery doesn’t address.
    • Rising return rates tied to expectation mismatches like size, color, or included parts.
    • Competitor shifts: A competitor upgrades their images and starts gaining click share in search results.
    • Product changes: New packaging, materials, colors, or included accessories. Images must accurately represent what ships.
    • Seasonal positioning: For giftable or seasonal products, secondary images can shift emphasis ahead of key periods.
    • Policy updates: Changes to Amazon’s image requirements or category style guides.

    A practical schedule

    For most sellers, a quarterly review of the objection map for top ASINs is a reasonable rhythm. Re-read recent reviews and questions, check return reasons, and look at the search results for your main keywords. If nothing has changed, leave the images alone. If something has, update the relevant slot rather than redoing the whole set.

    Update one slot at a time

    Incremental updates make performance easier to read. If you change the scale image and conversion improves over a meaningful period, you have a reasonable signal. If you change all seven images at once, you won’t know what worked.

    Build a reusable image system

    For sellers with larger catalogs, documenting a visual system pays off: consistent fonts, color palette, callout styles, slot sequence templates, and brief templates. New products can be planned faster, and the whole catalog looks like it belongs to one brand. This consistency also helps shoppers who browse multiple products in your storefront.

    Keep a record

    Log every image change with the date, what changed, and why. Pair that log with your conversion and click-through data. Over time, you’ll build a body of evidence about what your specific buyers respond to, which is worth more than any generic best-practice list.

    Conclusion: Build Images Around What Buyers Doubt

    Amazon listing images that perform well aren’t defined by expensive photography or flashy design. They’re defined by relevance. Each image answers a real question that a real shopper has, in the order those questions matter.

    The process comes down to a few disciplined steps:

    1. Mine the objections. Pull recurring doubts from your reviews (especially 3-star), competitor reviews, customer questions, and return reasons. Rank them by frequency.
    2. Treat compliance as the floor. Meet Amazon’s main image rules (pure white background, 85% frame fill, 1600px+ for zoom, no text or graphics), then make the main image win at thumbnail size.
    3. Give each slot one job. Answer the biggest objection early. Prioritize proof over claims. Always include a scale reference.
    4. Write a real brief. Explain the why behind every image, include customer quotes, separate the shot list from the design list, and capture alternates.
    5. Design for phones. One idea per image, a short benefit headline, about three callouts at most, and text that’s readable at arm’s length.
    6. Respect category rules. Apparel, footwear, kids’ items, and other categories have specific requirements. Check them before every shoot.
    7. Test honestly. Use Manage Your Experiments where eligible, change one variable at a time, let tests run, and treat before-and-after comparisons with caution.
    8. Refresh based on signals, not a calendar alone. Review objection maps quarterly and update individual slots when buyer concerns shift.

    If your images already look good and still aren’t converting, the fix probably isn’t a prettier reshoot. It’s a more specific one. Start by reading your last fifty reviews with a notepad open, and you’ll likely find the image your listing has been missing all along.
  • What Your Amazon Image Tests Are Actually Telling You (And Why Most Sellers Misread the Data)

    What Your Amazon Image Tests Are Actually Telling You (And Why Most Sellers Misread the Data)

    There is a version of image testing that feels very productive and produces almost nothing. You swap a new lifestyle photo into slot three, run it for two weeks, look at your conversion rate, notice it barely moved, and conclude that image testing doesn’t really work for your category. Then you move on.

    That conclusion is almost certainly wrong — but the testing process that produced it was also almost certainly flawed. The image variables that move click-through rate are not the same variables that move conversion rate. The slots that affect your ad spend efficiency are not the same slots that reduce your return rate. And the A/B testing framework that works for a main image test will produce garbage data if you apply it unchanged to an A+ content experiment.

    This is the core problem with how most sellers approach image testing in 2026: they run tests without a clear hypothesis about which funnel stage they’re trying to influence, which metric should move, and what a meaningful result actually looks like. They get data, but they can’t read it. They make changes, but they can’t explain why the changes worked or failed.

    This post is a systematic breakdown of what the evidence actually shows about image testing on Amazon — from main image CTR experiments to A+ module architecture to the specific image types that consistently produce conversion lift. The goal is not to give you a list of “winning” image formats. It’s to give you a diagnostic framework so that every test you run teaches you something you can act on.

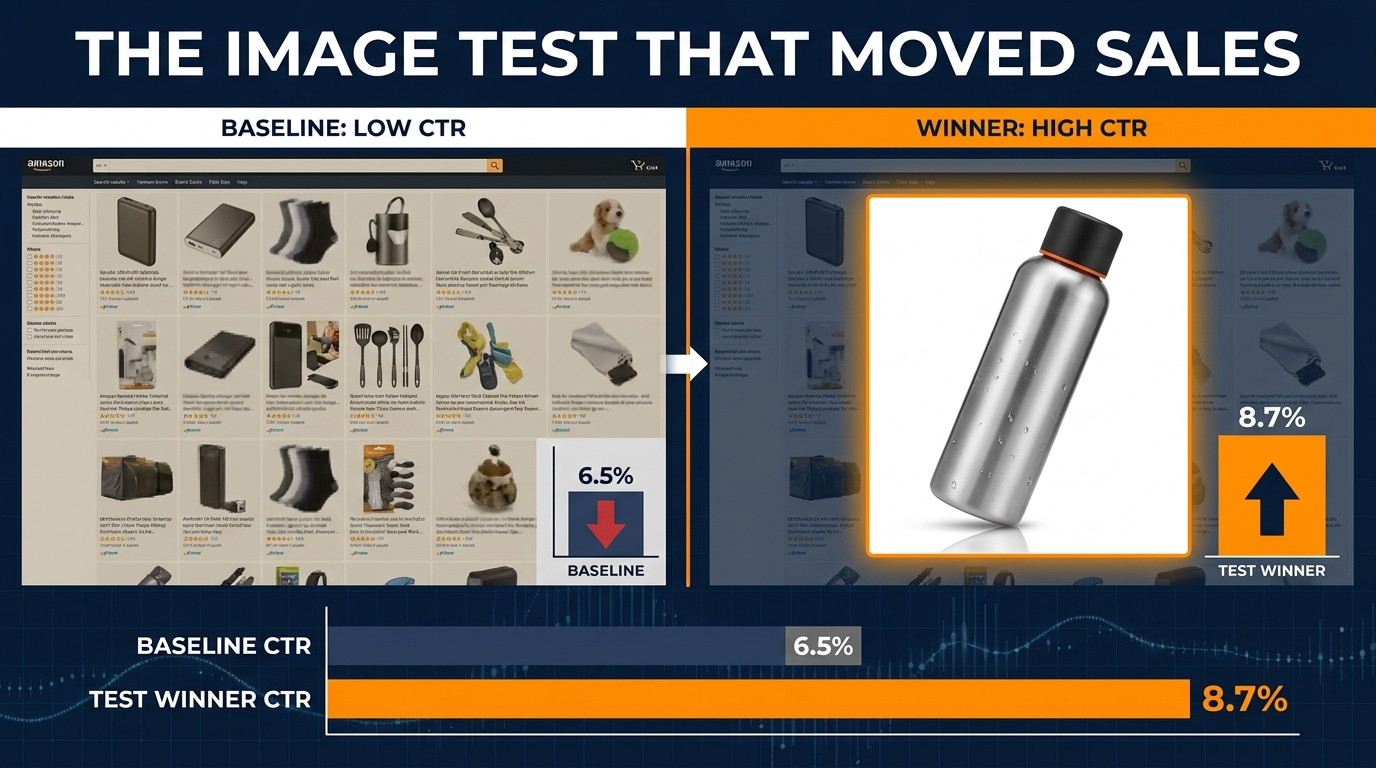
    Amazon product image CTR testing split screen showing baseline vs. winning image with +34% CTR result

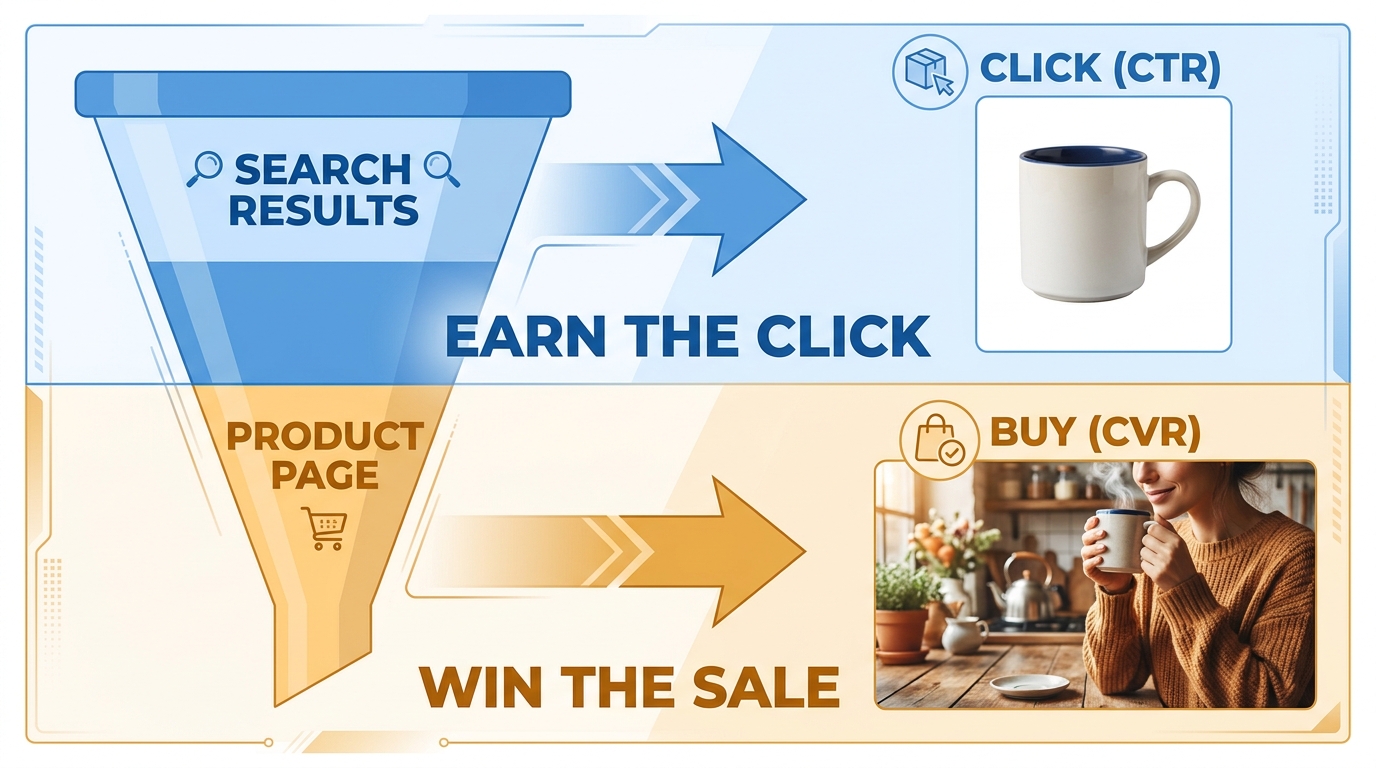
    Why CTR and CVR Are Two Completely Different Conversations

    The most common mistake in Amazon image testing is treating click-through rate and conversion rate as interchangeable outcomes — as if improving one automatically improves the other, or as if a test that didn’t move sales must mean the image change didn’t matter.

    They operate at different stages of the buying journey, respond to different visual signals, and are driven by different image slots. Conflating them produces tests that either measure the wrong thing entirely or deliver results too muddled to act on.

    CTR lives in the search grid. CVR lives on the product page.

    When a shopper searches for “insulated water bottle,” they see a grid of thumbnails. The decision to click happens in under two seconds, based almost entirely on the main image. That’s a recognition decision — does this product look like what I’m looking for, and does the thumbnail stop my scroll?

    Once they click, the decision shifts to evaluation. Now they’re scanning your secondary images, reading bullet points, checking reviews, and building a mental case for or against buying. Conversion rate is what happens when that evaluation goes well.

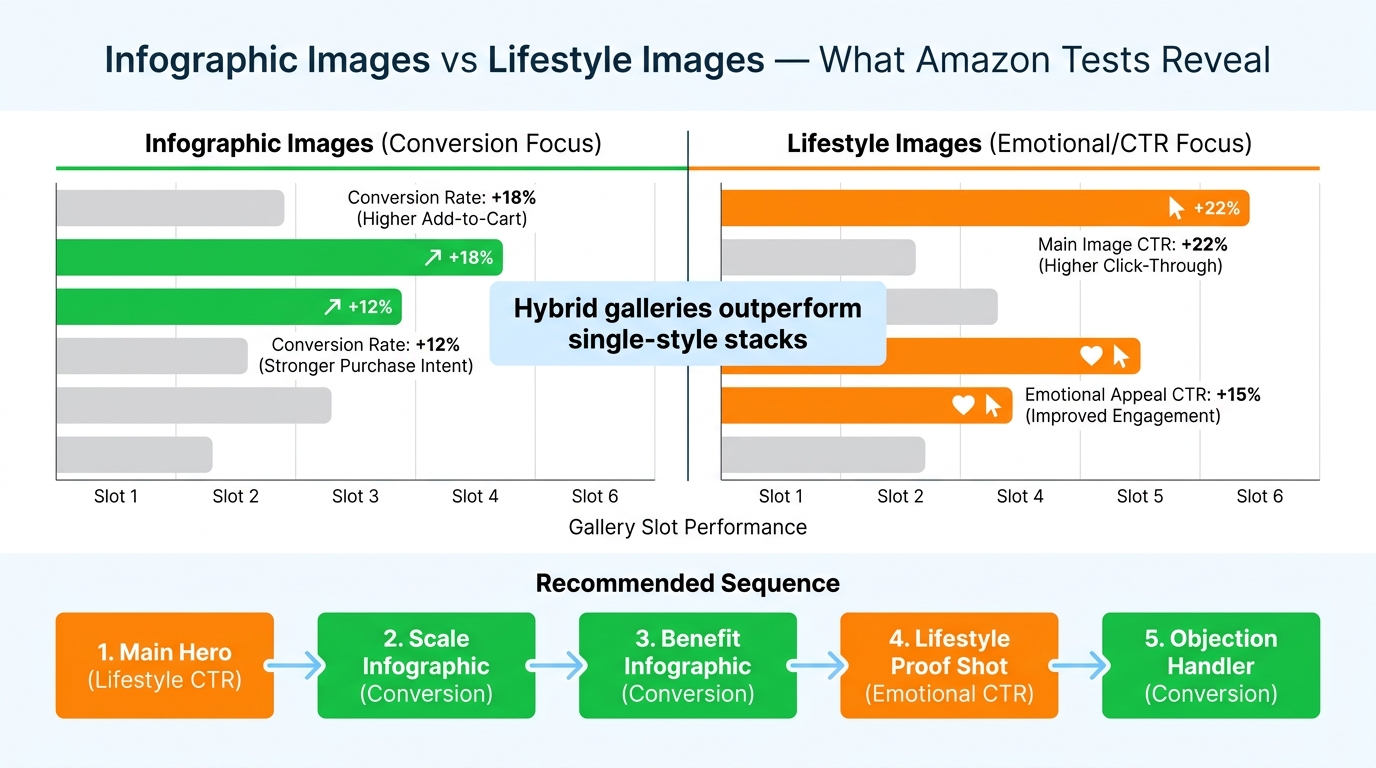
    The implication is direct: your main image is a CTR tool. Your secondary image stack is a CVR tool. Your A+ content is a late-stage trust and persuasion tool. Each layer has a different job, and testing them without that distinction in mind produces data that looks like noise.

    The metric mismatch problem

    If you change your main image and measure conversion rate as the primary outcome, you’re likely to miss the real effect. A better main image may bring in more clicks, but it also changes the composition of who’s clicking — sometimes attracting shoppers who are slightly less pre-sold on your product. CTR goes up, CVR appears flat or slightly down, and a seller who doesn’t understand the relationship concludes the test “didn’t work.”

    The right framework: use CTR (or CTR market share percentage vs. impression share) as the primary metric for main image tests, and conversion rate plus units sold per unique visitor as the primary metrics for secondary image and A+ content tests. Amazon’s own Manage Your Experiments tool reports on sales, conversion rate, units sold, and units sold per unique visitor — which means it’s already configured for post-click evaluation, making it better suited for A+ and secondary image experiments than for pure CTR testing.

    Two-stage image funnel infographic: Earn the Click with main image, Win the Sale with secondary images

    The Main Image’s Only Job Is the Click — Stop Asking It to Do More

    Every year, sellers find creative ways to load their main images with information: benefit callouts, bundle indicators, badge-style trust signals, variant selectors, and multi-angle composite shots. And every year, the evidence from testing says the same thing: simplicity wins.

    A review of more than 40 main-image tests conducted across Amazon categories in 2026 found that simplified, high-contrast hero images beat information-rich images approximately 72% of the time, with an average CTR improvement of around 0.4 percentage points. That may sound modest — but on a high-impression ASIN, 0.4 percentage points in CTR can represent thousands of additional clicks per month without a single dollar of additional ad spend.

    The product fill rule: 85% minimum, 90%+ optimal

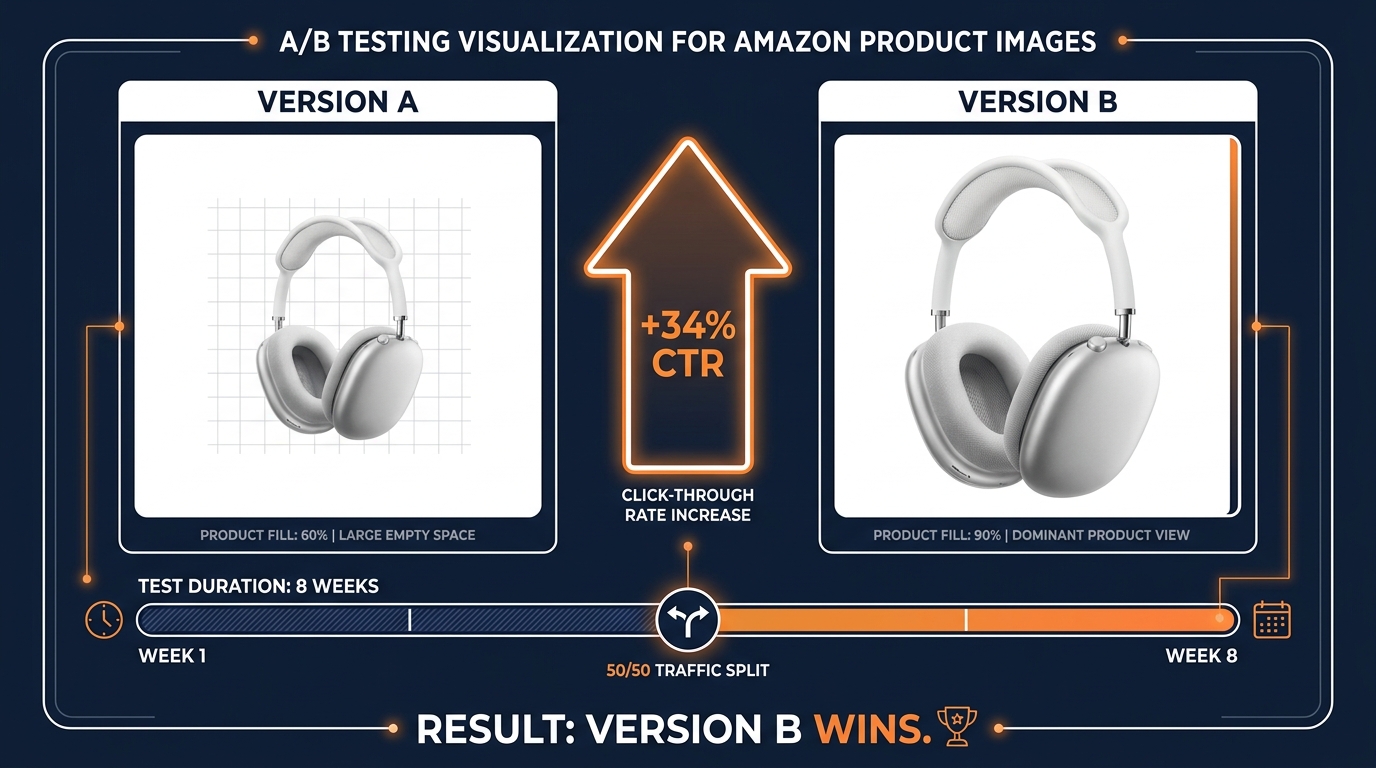
    Amazon requires the product to fill at least 85% of the main image frame. Most testing data suggests the optimal fill for CTR is even higher — closer to 90–92%. The reasoning is visual: in a search grid crowded with competing thumbnails, the product that appears larger and more prominent commands attention faster. A product that fills 60–65% of the frame with significant white space around it looks visually smaller relative to competitors, even at the same pixel dimensions.

    This is one of the clearest and most actionable findings in the testing literature. If you’re looking for a fast main-image test that consistently produces readable results, testing product fill percentage against your current hero image is the most reliable starting point.

    What you can’t test on the main image (and should stop trying)

    Amazon’s main image requirements prohibit text overlays, logos, badges, watermarks, borders, color blocks, and graphics over or behind the product. These rules aren’t just compliance guardrails — they reflect a design reality that testing consistently confirms. Shoppers processing a thumbnail in 1–2 seconds are making a shape-recognition decision. Text overlays add cognitive load to a moment when the brain wants instant pattern recognition, not reading.

    The legitimate variables to test on a main image are: product angle, product fill percentage, background treatment (pure white vs. off-white vs. light shadow), and for apparel, on-model vs. flat-lay. These are meaningful variables with documented CTR effects. Everything else belongs in secondary slots.

    A real CTR test example worth understanding

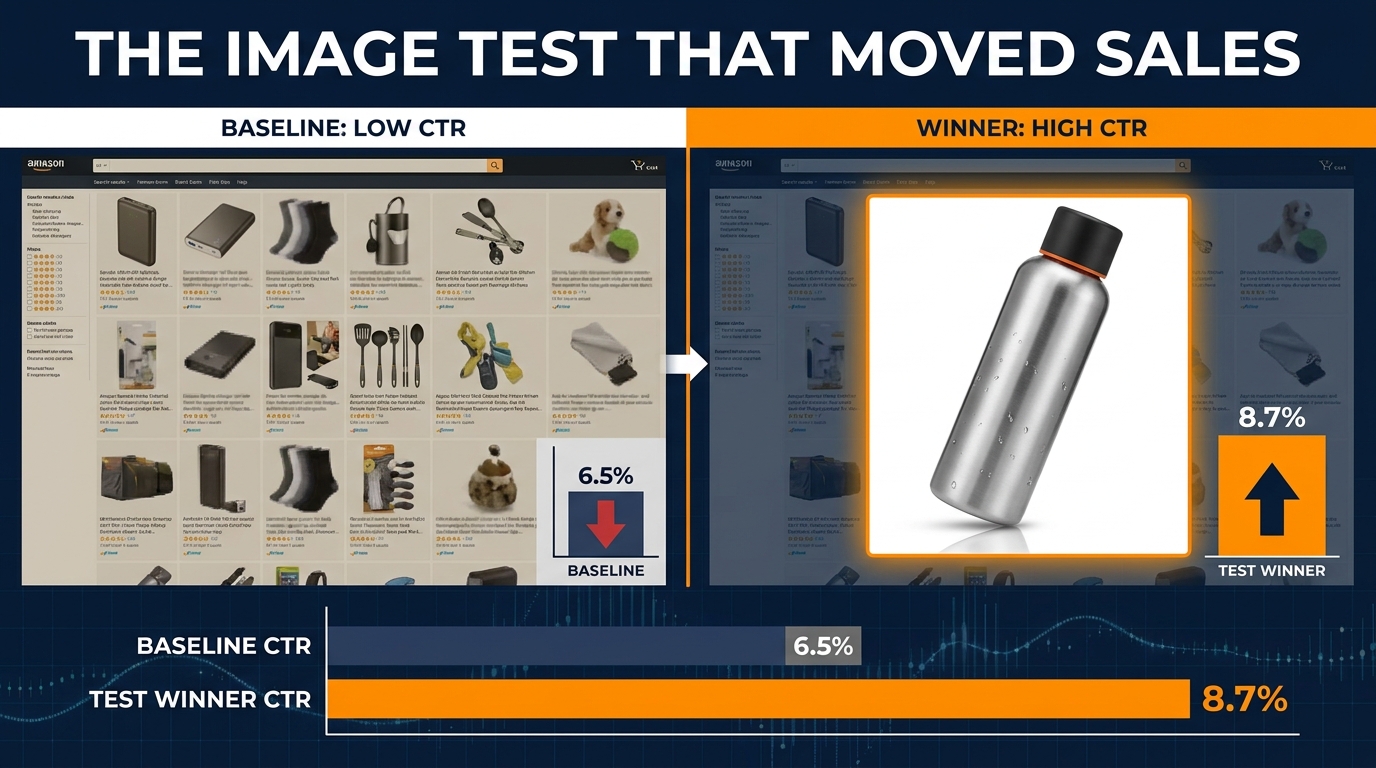
    A back-to-school product test conducted across 2.4 million impressions and 847 ASINs reported an 8.7% CTR for the optimized main image group versus a 6.5% baseline — a 34% relative improvement. The winning images shared three characteristics: the product filled more than 88% of the frame, edge contrast against the white background was sharper (achieved through shadow depth and product color), and the primary product feature was immediately identifiable at thumbnail size without any text assistance.

    That last point matters: the visual should communicate the product category and primary use case before the shopper reads the title. If your thumbnail requires a title read to understand what the product is, your image is doing less than half its job.

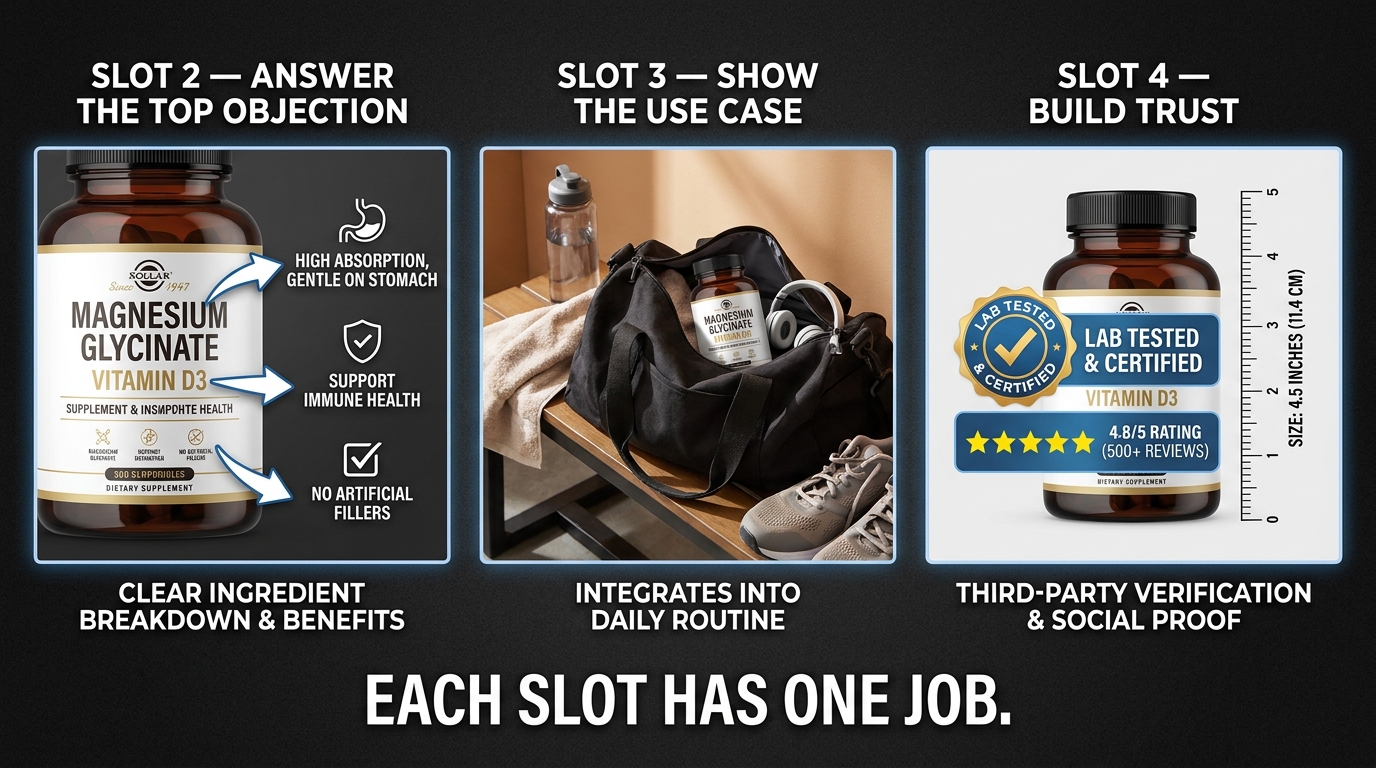
    The Second Image Is Your Highest-Leverage CVR Slot (And Most Sellers Waste It)

    Once a shopper clicks your listing, the evaluation process begins. The first thing most shoppers look at after the main image is slot two — the second image. On mobile, which now accounts for the majority of Amazon browsing, this image appears immediately below the fold or as the second swipe in the image carousel. It is seen by nearly everyone who clicks. It is also, consistently, the most underused conversion lever in the entire image stack.

    Most sellers put a different-angle product shot in slot two. It’s a reasonable default, but it leaves conversion on the table. A different angle answers the question “what does this look like from another direction” — which is not usually the top purchase objection your buyer is carrying when they first click.

    Find your top objection, then design slot two around it

    The most effective slot-two images directly answer the single biggest purchase objection for the product. For a water bottle, that might be “will it fit in my car cupholder?” For a supplement, it might be “what are the actual ingredients?” For a kitchen tool, it might be “how big is this, actually?” The fastest way to identify the top objection is to read your negative reviews and your competitor’s negative reviews — you will find the same three or four objections mentioned repeatedly. The buyer who converts is the buyer whose objection gets answered before they leave the listing.

    Testing has consistently shown that slot-two images designed around a specific objection outperform secondary-angle shots by meaningful margins in conversion rate. The specific lift varies by category, but the pattern is consistent: answer the real question, not a tangential one.

    The slot-two infographic: when it works and when it doesn’t

    An infographic in slot two — showing key specs, dimensions, ingredient breakdowns, or compatibility details — performs very well when the primary objection is informational. Shoppers evaluating technical products (electronics, supplements, fitness equipment, kitchen appliances) want data, and an infographic delivers it faster than bullet points. Testing data from category-level experiments suggests that strong secondary infographics can lift conversion rate by 5–15% on information-heavy products.

    For impulse-category or low-consideration products, infographics in slot two tend to perform more modestly. If your product is something a shopper buys without much evaluation (a simple household staple, a sub-$15 item), the objection-answering job is smaller, and a lifestyle image that makes the product feel desirable may outperform a data-heavy infographic. The principle is the same: the image type should match the actual decision process for your specific buyer.

    Three Amazon secondary image slots each with a distinct job: answer objection, show use case, build trust

    What Infographic Images Actually Test Well In (And Where They Disappoint)

    Infographic images — product photos overlaid with callout arrows, dimension annotations, ingredient labels, comparison charts, or feature bullets — have become one of the dominant image styles in Amazon listings across most categories. Their popularity is partly deserved and partly a product of trends outrunning evidence. The testing picture is more nuanced than the hype.

    Where infographics genuinely lift performance

    The categories where infographic secondary images consistently produce measurable conversion lift share a common trait: high information demand before purchase. Supplement and nutrition products, electronics and tech accessories, fitness and exercise equipment, home improvement and tools, and kitchen appliances all involve buyers who want to verify specs, understand compatibility, compare ingredients, or confirm dimensions before committing. For these categories, a well-designed infographic reduces the friction between clicking and buying.

    The most effective infographic formats in these categories are: dimension drawings with actual measurements labeled (not just “compact size”), ingredient or component callout panels showing what’s included and why it matters, compatibility charts (“works with X, Y, Z systems”), and before/after visual comparisons where the product’s benefit is demonstrable. These formats work because they answer specific buyer questions faster than text alone.

    Where infographics underperform and why

    Infographics designed around features — rather than buyer questions — consistently underperform in testing. A list of product features presented as callout arrows (“patented design,” “premium materials,” “ergonomic handle”) tells the buyer what the brand thinks is important, not what the buyer is actually asking. Shoppers on Amazon move fast; if your infographic requires them to read and interpret rather than instantly absorb, a significant portion will swipe past it.

    The other consistent failure mode is information overload. Infographics that try to communicate more than three or four ideas in a single image lose focus. The buyer’s eye doesn’t know where to land, the hierarchy of information collapses, and the image ends up communicating less than a clean lifestyle shot would. The discipline of identifying one primary message per image slot is as important for infographics as for any other format.

    Mobile rendering: the infographic killer most sellers ignore

    A significant portion of infographic images are designed at full resolution and look great on desktop — then become unreadable on a mobile screen where text shrinks to near-invisible. If your infographic contains text smaller than approximately 24pt at the rendered image size, a substantial share of your mobile audience cannot read it without pinching to zoom. Most will not zoom. They will swipe.

    Test your infographic images at actual mobile thumbnail size before publishing. If any text element requires zooming to read, the infographic needs to be redesigned — either by reducing the amount of information, increasing text size, or splitting the content across two slots.

    Lifestyle Images: The Funnel Stage Most Sellers Get Wrong

    The lifestyle image debate — whether lifestyle shots outperform studio or technical shots — has generated a substantial amount of contradictory advice in the Amazon seller community. The reason for the contradiction is that lifestyle images, like all image types, are only as effective as their placement in the right funnel stage for the right product.

    What lifestyle images actually do in the buyer’s mind

    Lifestyle images work through a specific psychological mechanism: they transfer desire by showing the buyer a version of themselves (or their life) that the product enables. A camping cookware set shot in a beautiful forest campsite doesn’t just show the product — it sells the camping experience, and the buyer’s brain connects ownership of the cookware to access to that experience. That’s a powerful conversion driver when it matches the buyer’s aspiration.

    This mechanism works best when three conditions are met: the buyer is in an aspirational or desire-driven purchase mode (rather than purely functional/informational), the lifestyle scenario is specific enough to feel real (generic stock-photo aesthetics undermine the effect), and the product is clearly visible and identifiable in the scene. A lifestyle image where the product is decorative background loses most of its conversion value.

    When lifestyle images lift conversion (with data)

    For considered-purchase categories — home décor, kitchenware, fitness apparel, outdoor gear, beauty and personal care — well-executed lifestyle images in secondary slots consistently improve conversion rate metrics. A fashion retailer test found that a lifestyle hero image increased conversion rate from 2.1% to 2.9% and add-to-cart rate from 4.2% to 5.8% — an approximately 38% relative lift in both metrics. For higher-price-point items in these categories, industry benchmarks suggest lifestyle images in the secondary stack can produce 15–40% conversion improvements compared to studio-only galleries, though the effect is highly category and execution dependent.

    The key qualifier is “well-executed.” Low-quality stock photography with obviously staged scenarios and mismatched aesthetics can actively hurt conversion by making a brand feel inauthentic. The lifestyle image standard has risen across Amazon as more sellers have adopted the format — a mediocre lifestyle image now competes against excellent ones, and shoppers have become more visually literate in detecting inauthenticity.

    When product-only images win instead

    Lifestyle images do not always win. Tests in functional, utilitarian, or specification-heavy categories have found product-only images outperforming lifestyle in conversion rate — in some documented cases by significant margins. Industrial supplies, replacement parts, technical accessories, baby safety products, and medical or health monitoring devices tend to be purchased based on specs and specifications verification rather than aspirational desire. In these categories, a lifestyle image can actually distract from the verification process the buyer needs to complete before they trust the purchase.

    The test-your-category-first principle applies here more than anywhere else. Lifestyle images are not a universal upgrade. They are a specific tool for a specific buyer psychology, and when you apply them to the wrong buyer state, they underperform studio alternatives.

    Sequencing Your Image Stack Like a Buyer Journey, Not a Product Catalog

    The shift from treating an Amazon image gallery as a product showcase to treating it as a structured persuasion sequence is the most significant evolution in image strategy over the past two years. Sellers who still think in terms of “show the product from multiple angles” are competing against brands that think in terms of “answer every objection before the buyer articulates it.”

    Amazon image stack as buyer journey diagram showing 7 slots mapped to buyer stages from click to purchase

    A working sequence framework

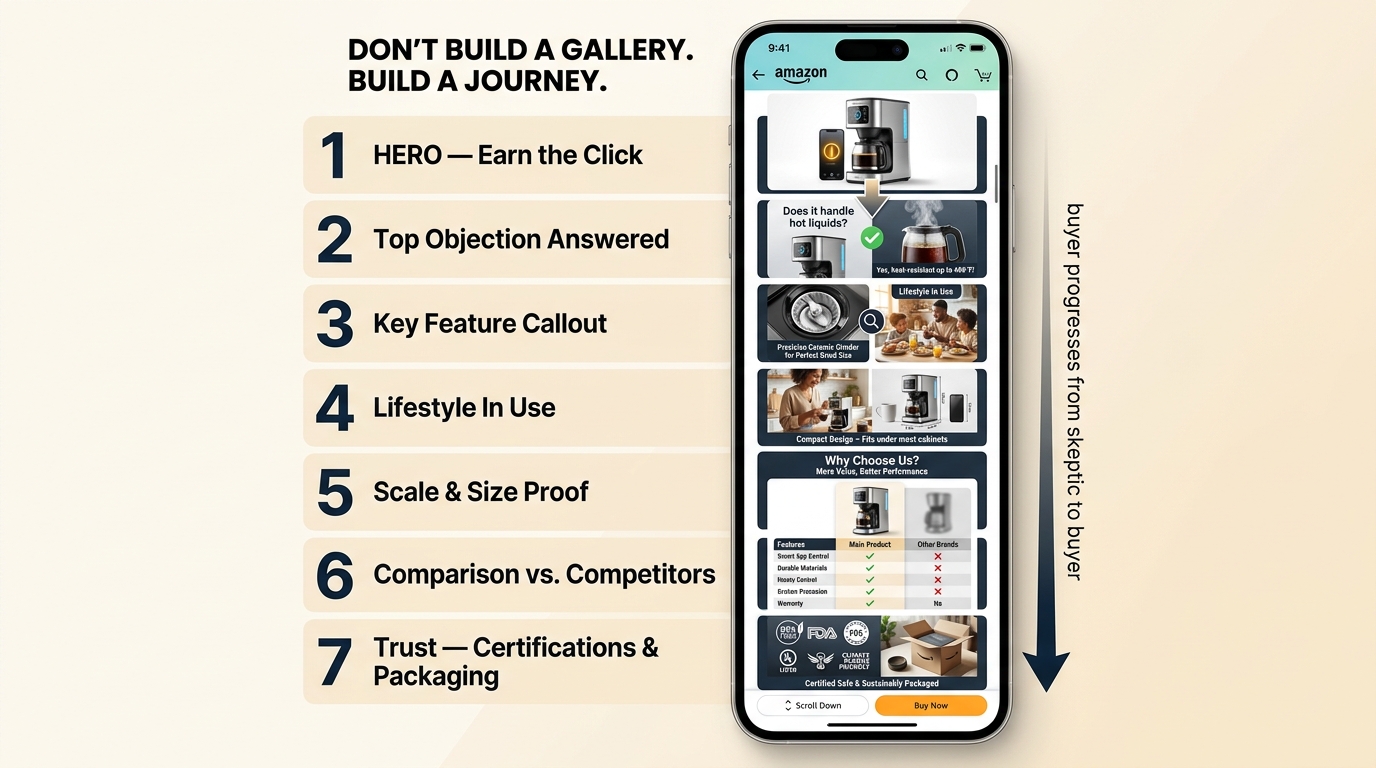
    The most consistently cited and tested image sequence framework across current Amazon seller guidance maps seven slots to seven buyer stages:

    • Slot 1 (Main Image): Win the click. Compliant, clean, high product fill, maximum thumbnail clarity.
    • Slot 2: Answer the top purchase objection. This should be the single biggest reason a buyer in your category doesn’t buy.
    • Slot 3: Show the primary benefit or key feature. Not a feature list — the single most compelling thing this product does, shown visually.
    • Slot 4: Show the product in use. Lifestyle context that lets the buyer visualize themselves using it in a realistic scenario.
    • Slot 5: Scale and size proof. Show the product next to a common reference object, or show it in a hand, or provide precise dimension visuals. Returns from “product was smaller than expected” are preventable with this slot.
    • Slot 6: Comparison or differentiation. Either a comparison chart against alternatives, or a visual demonstration of what makes this product different from the generic version.
    • Slot 7: Trust and conviction. Certifications, quality indicators, packaging contents, or a summary of the value proposition.

    Why sequence matters more than individual image quality

    Multiple 2026 seller guides and conversion specialists emphasize that the order of images matters as much as their quality. A strong lifestyle image in slot two — before the top objection has been addressed — can actually hurt conversion, because it signals that the brand is more interested in looking aspirational than answering buyer questions. The sequence needs to track the buyer’s cognitive journey: skeptical interest → objection resolution → desire → conviction.

    The practical implication is that when you’re testing image changes, you should test sequence changes as aggressively as you test image type changes. Swapping slot two and slot three can produce measurable conversion differences on the same images. This is a low-cost test variable that is underutilized relative to its potential impact.

    The mobile-first constraint on sequence

    On mobile, the first two to three images in the carousel receive the vast majority of engagement. Slots five, six, and seven are seen by a much smaller fraction of shoppers — primarily the highly engaged ones who are close to a purchase decision. This doesn’t make those slots unimportant; the shoppers who scroll to slot seven are your highest-intent buyers, and giving them strong trust signals at that moment can close sales that would otherwise have stalled. But it does mean your most critical objection-handling work needs to happen in slots two and three, not buried in the back of the gallery.

    How to Run A/B Tests That Actually Produce Readable Results

    The majority of Amazon image tests fail to produce actionable conclusions — not because image testing doesn’t work, but because the tests are designed in ways that guarantee ambiguity. Understanding what makes a test readable is as valuable as understanding what to test.

    A/B test visualization showing Version A vs Version B image with +34% CTR result after 8-week 50/50 split test

    The one-variable rule is not optional

    If you change the image type (lifestyle vs. studio), the image content (objection vs. feature), the image slot, and the color treatment all at once, you cannot isolate what produced the result. You’ll know something changed, but you won’t know what — which means you can’t replicate the win or understand the loss. Testing one meaningful variable at a time is not a pedantic methodological preference; it’s the only way to extract learnings that compound over time.

    The practical corollary: make your Version B meaningfully different from Version A in exactly one dimension. If you’re testing whether a lifestyle slot-two image outperforms an infographic, keep everything else about the listing identical. If the difference is too subtle, the test won’t produce a statistically meaningful result even with enough traffic.

    Traffic thresholds and test duration

    For main image CTR tests run outside of Manage Your Experiments (using third-party tools or historical comparison), the standard guidance is to run for a minimum of four weeks, with at least 1,000 clicks per variant for any CTR finding to carry real weight. For A+ content and secondary image tests run inside Manage Your Experiments, Amazon recommends running experiments to completion — the tool itself calculates the required sample size and flags when statistical significance has been reached.

    The worst testing pattern is running a test for one or two weeks, seeing a promising early signal, and declaring a winner. Amazon traffic fluctuates significantly across days of the week, promotional periods, and seasonality windows. Short tests are contaminated by these patterns. The discipline to run tests to completion — typically eight to ten weeks for Amazon Experiments — is what separates teams that generate reliable data from teams that generate noise that looks like signal.

    What to do when the test “doesn’t produce a result”

    A test that runs to completion and finds no statistically significant difference between Version A and Version B is not a failed test. It’s a finding: this particular variable doesn’t move the needle meaningfully for your ASIN. That’s valuable information. It tells you where not to spend further testing resources and narrows your focus toward the variables that matter.

    The failure is not a null result — it’s stopping the test early, changing multiple variables at once, or running the test on a low-traffic ASIN where the sample size is too small to reach significance in any reasonable timeframe. High-traffic ASINs are your testing assets. Start there, generate learnings at scale, and then apply the validated changes to lower-volume SKUs.

    Building a testing backlog, not a testing one-off

    The sellers generating the most value from image testing in 2026 treat it as an ongoing practice, not a quarterly project. They maintain a prioritized backlog of test hypotheses, run one to two concurrent tests on their highest-traffic ASINs, document results in a shared format, and apply learnings systematically across the catalog. Over twelve months, that practice produces a library of validated findings specific to their category, their buyer, and their product type — a compounding asset that a seller who does one image refresh per year simply cannot build.

    A+ Content’s Real Job in the Funnel (It’s Not What You Think)

    A+ Content is frequently positioned as a brand storytelling tool — a place to showcase brand heritage, photography, and values. That framing isn’t wrong, but it’s incomplete, and it leads sellers to build A+ pages that are aesthetically impressive and commercially inert.

    The more accurate framing: A+ Content is a conviction module. Its job is to take a shopper who has reviewed your images, read your bullets, and is still not quite sure — and push them over the decision threshold. The buyer who reaches A+ content is a high-intent, high-consideration buyer who has objections that the listing’s primary content hasn’t yet resolved. A+ that treats this buyer to brand photography and lifestyle mood boards without addressing purchase friction will consistently underperform A+ that is structured around decision completion.

    The modules that actually move conversion

    Not all A+ modules are equal in their conversion impact. Based on current testing patterns and practitioner data, the modules with the most consistent post-click conversion impact are:

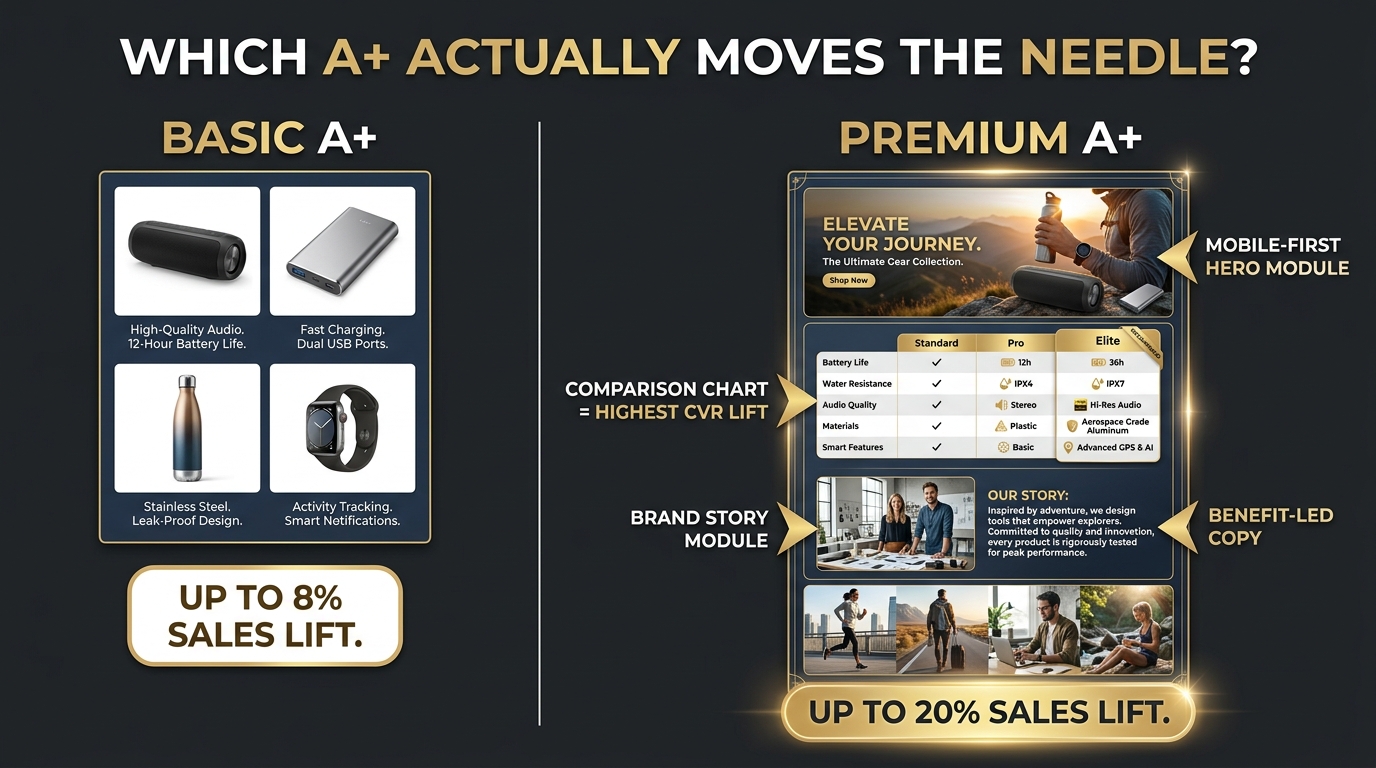
    • Comparison charts: Showing how your product compares to alternatives — either your own product line variants or the generic category option — is the single highest-converting A+ module type for most considered-purchase categories. It resolves the “am I getting the right one?” objection that stalls a significant share of ready-to-buy shoppers.
    • Benefit-led text modules: Short, punchy benefit statements that answer the “why this product specifically” question outperform long-form brand narrative copy. Each text block should answer one question a buyer would actually ask.
    • Dual image + text modules: Pairing a high-quality product or use-case image with a tight benefit statement creates a visual-verbal combination that works well for high-information buyers. This format also renders cleanly on mobile, which is critical since the majority of A+ content is now viewed on a phone screen.

    What A+ content does not do well

    Brand story modules positioned above the fold — before any objection-handling content has appeared — consistently underperform in conversion tests. The buyer who clicked on your listing did not click because they want to learn about your founding story; they clicked because they think your product might solve their problem. Leading with brand narrative before addressing purchase relevance tells the buyer the listing is about the brand, not about them. That misalignment costs conversions.

    The module order principle: put your highest-conviction content first. The comparison chart or primary benefit module should appear in the first visible A+ panel. Brand story and heritage content belongs toward the bottom — for the buyers who want it, it builds trust; for the buyers who don’t, it’s safely below the fold.

    Premium A+ vs. Basic A+: When the Upgrade Actually Pays Off

    Amazon’s published benchmarks for A+ content are frequently cited without the context that makes them actionable. Basic A+ content is associated with up to an 8% sales lift. Premium A+ — which includes full-width modules, interactive hover elements, video integration, and richer module options — is associated with up to a 20% sales lift.

    These are ceiling figures, not averages. Real-world performance data from practitioners typically shows Basic A+ delivering 3–10% conversion lift on well-executed pages, and Premium A+ delivering 8–20% on strong executions in the right categories. The gap between “up to 20%” and “actual 20%” is entirely about implementation quality and category fit.

    Premium A+ vs Basic A+ comparison infographic showing sales lift benchmarks and key conversion-driving modules

    When Premium A+ justifies the investment

    Premium A+ delivers its largest measurable returns in categories where the purchase involves significant consideration time, high price points, or complex feature sets. Home appliances, electronics, fitness equipment, beauty and personal care with complex ingredient questions, and outdoor or sporting goods are categories where the additional visual real estate and interactive module options in Premium A+ can meaningfully improve the buyer’s ability to evaluate and commit.

    The interactive elements — hover-activated image panels, expandable comparison tables, integrated video — are most valuable for products where the buyer benefits from exploring details at their own pace. If your product has multiple configurations, components, or use cases that benefit from interactive exploration, Premium A+ provides a canvas that Basic cannot match.

    When Basic A+ is the smarter allocation

    For low-consideration categories, high-velocity basics, or ASINs where the primary conversion barrier is price rather than information, Basic A+ typically delivers the same practical lift at a lower execution cost. Premium A+ requires significantly more design resources and production time to execute well; a poorly designed Premium A+ page can actually underperform a clean, well-structured Basic A+ page in head-to-head testing.

    Premium A+ also requires a published Brand Story across your catalog as an eligibility prerequisite. If your catalog does not have Brand Story content in place, satisfying that requirement is a precondition — factor that into the actual cost and timeline of upgrading. The eligibility change that made Premium A+ available at no additional charge to qualified brands was a meaningful development; it lowers the cost barrier but does not lower the execution quality bar.

    Testing your A+ content: the Manage Your Experiments approach

    Amazon’s Manage Your Experiments tool supports A/B testing of A+ Content on the same ASINs. The tool runs a controlled experiment, splits traffic between Version A and Version B, and reports results in conversion rate, units sold, sales, and units sold per unique visitor. The output is designed for post-click evaluation — exactly the right metric set for A+ content performance.

    The most productive A+ experiments currently involve: testing module order (particularly whether leading with a comparison chart vs. leading with a hero image produces different conversion outcomes), testing benefit-led copy against feature-led copy in the same module type, and testing the presence vs. absence of a comparison chart for ASINs where the category has multiple close alternatives. These are high-information tests because they produce learnings that apply across the catalog.

    What a Winning Image Test Result Actually Looks Like

    Understanding what counts as a “win” in image testing is less obvious than it appears. The metric that moved, the magnitude of the movement, the statistical confidence behind the result, and the downstream commercial implication all matter — and they rarely all point in the same direction.

    Defining a commercially meaningful lift

    A 0.4 percentage-point CTR improvement on a main image sounds modest. But on an ASIN receiving 50,000 monthly impressions, that improvement represents 200 additional clicks per month. At a 15% conversion rate and a $30 average selling price, that’s an additional $900 in monthly revenue from a single image change — without any additional ad spend. Over twelve months and applied to a catalog of ten ASINs with similar traffic, the compounding effect is substantial.

    The point: translate your percentage improvements into unit economics before judging whether a test result is worth acting on. A “small” CTR improvement on a high-impression ASIN is frequently worth more than a “large” conversion rate improvement on a low-traffic one.

    Signs a result is reliable vs. noise

    A reliable test result has four characteristics: it ran to statistical significance (not stopped early), the sample size was large enough relative to the effect size, the test period spanned multiple weeks to normalize for day-of-week and promotional fluctuations, and the metric that moved is the one the tested variable was designed to affect.

    Warning signs that a result may be noise: the test ran less than four weeks, the winning version’s advantage appeared in week one then flattened, the metric that moved was not the primary outcome for that test type (e.g., the main image test “won” on conversion rate but CTR was flat), or the magnitude of improvement is very large but the ASIN had low traffic and a short test window.

    Building a test result library

    Every test result — win, loss, or null — should be documented with a standard set of fields: the hypothesis tested, the ASIN and category, the test dates and duration, the primary metric and its change, the statistical confidence level, and a plain-language description of what the result means. Over time, this library becomes the most valuable image optimization asset your brand has. It tells you what works in your specific category for your specific buyer — not what works in the abstract for some hypothetical Amazon seller.

    Teams that maintain this library and review it quarterly find that image testing compounds in value. Early tests reveal broad patterns (lifestyle in slot four beats studio for our category). Later tests refine those patterns (lifestyle images featuring solo users convert better than group scenarios for our specific product type). That level of specificity is not available from any external guide — it only comes from your own validated history.

    Why Return Rate Is the Image Metric Nobody Tracks (But Should)

    Most image testing discussions focus entirely on CTR and conversion rate. Return rate — the percentage of orders that come back — is almost never part of the image testing conversation, which is a significant blind spot given that returns are directly attributable to image quality failures.

    The connection between image accuracy and returns

    The most common reason shoppers return Amazon orders is that the product differed from expectations — it was smaller than it appeared, a different shade than shown, had different material or texture, or included different components than the image suggested. These are image failures masquerading as product failures. The images communicated something inaccurate, and the customer responded rationally by returning a product that didn’t match what they thought they were buying.

    Size/scale images in slot five of your image sequence exist specifically to prevent this. A product photographed in isolation with no size reference leaves the buyer estimating from the thumbnail — and buyers consistently overestimate dimensions. A product shown next to a standard reference object (a hand, a common household item, a ruler overlay) sets accurate size expectations and dramatically reduces “smaller than expected” returns.

    Color and texture accuracy as a conversion and return lever

    Color-accurate photography is simultaneously a conversion tool and a return-reduction tool. Shoppers making color-sensitive purchases (apparel, home décor, bedding, paint-adjacent products) are more likely to convert when the image accurately reflects the product’s color under natural light — because they can confidently match it to what they need. They are also less likely to return, because the product matches expectations.

    The tension is that many product photography workflows prioritize dramatic, visually appealing images over color accuracy. A slightly enhanced, more saturated version of a blue product looks better on screen and may increase conversion in the short term — but generates returns at a higher rate from buyers for whom color accuracy matters. Testing both conversion rate and return rate together is the only way to identify whether an image change is actually improving economics or just shifting the problem downstream.

    Building an Image Testing Culture, Not a One-Time Fix

    The brands that generate the most consistent value from image optimization in 2026 are not the ones that did the most comprehensive image redesign last year. They’re the ones that built a continuous testing practice — one that produces learnings each month, applies them systematically, and compounds over time into a catalog of listings that are empirically better at converting than anything a competitor designed on instinct could match.

    What a sustainable testing rhythm looks like

    A practical image testing cadence for most catalog sizes involves running one or two simultaneous experiments via Manage Your Experiments at any given time on your highest-traffic ASINs, reviewing results monthly, applying winners within two weeks of a confirmed result, and documenting every outcome — including null results — in a shared library. That rhythm generates approximately twelve to twenty-four meaningful test results per year per seller, which compounds into significant catalog-level optimization over any twelve-month window.

    The bottleneck is almost never testing infrastructure. It’s the creative production pipeline: generating meaningfully different Version B images requires photography, design, or both. Brands that invest in modular image production workflows — where elements like backgrounds, text overlays, and lifestyle scenarios can be produced and swapped efficiently — can maintain higher testing velocity than those that treat every image as a custom production from scratch.

    The three tests to run before anything else

    If you’re building an image testing practice from zero, the three tests with the highest probability of producing an actionable result are, in order of priority:

    1. Main image product fill test: Test your current main image against a version where the product fills 88–92% of the frame. Measure CTR over six to eight weeks. This test produces a result on nearly every ASIN because fill percentage has a consistent, category-agnostic effect on thumbnail clarity.
    2. Slot-two objection test: Identify your top purchase objection from negative reviews, replace whatever is currently in slot two with an image that directly answers that objection, and measure conversion rate over eight weeks via Manage Your Experiments.
    3. A+ comparison chart test: If your A+ content does not currently include a comparison chart, add one as a Version B in Manage Your Experiments and measure conversion rate. For most considered-purchase categories, the comparison chart is the single highest-return A+ module.

    These three tests, run sequentially on your highest-traffic ASINs, will generate more actionable data about your catalog’s image performance than any external audit could provide. They’re also the tests most likely to produce commercially meaningful improvements in your unit economics — which is the real measure of whether image testing is working.

    From testing to systematic advantage

    The compounding dynamic is worth stating directly: every validated test result narrows the gap between where you are and where your optimal image stack is. A catalog that has had thirty validated image changes applied to it performs materially differently than a catalog where images are changed on gut instinct. The difference isn’t visible in any single metric on any single day — it shows up in conversion rate consistency across traffic fluctuations, in lower ad cost per sale because the organic conversion rate is higher, in lower return rates because images are more accurate, and in stronger review scores because customers received products that matched their expectations.

    Image testing, done rigorously, is one of the few catalog optimization practices that improves both the top line and the bottom line simultaneously, without requiring additional ad investment. That’s not a common combination in Amazon selling. It’s worth treating as the operational priority it actually is.

    Final takeaways

    • Separate CTR and CVR work. Test your main image for CTR. Test your secondary images and A+ for CVR. Don’t evaluate a main-image test by its conversion impact.
    • Fill your frame. If your main image product fill is below 88%, test higher fill first — it’s the fastest, most reliable CTR improvement available.
    • Slot two owns the top objection. Find your category’s biggest purchase barrier, design slot two around answering it, and test against your current slot-two image.
    • Sequence beats individual image quality. A mediocre image in the right slot, answering the right question, outperforms an excellent image in the wrong slot.
    • Run tests to completion. Four weeks minimum. Eight to ten weeks for Manage Your Experiments. No early winners.
    • Track return rates alongside conversion. An image change that lifts conversion but raises returns has not improved your economics — it has moved the problem.
    • Document everything. Every result, including nulls, builds the library that makes future tests faster and more predictive.
  • Why Most Amazon Image A/B Tests Give You the Wrong Answer — And How to Fix Your Testing Architecture

    Why Most Amazon Image A/B Tests Give You the Wrong Answer — And How to Fix Your Testing Architecture

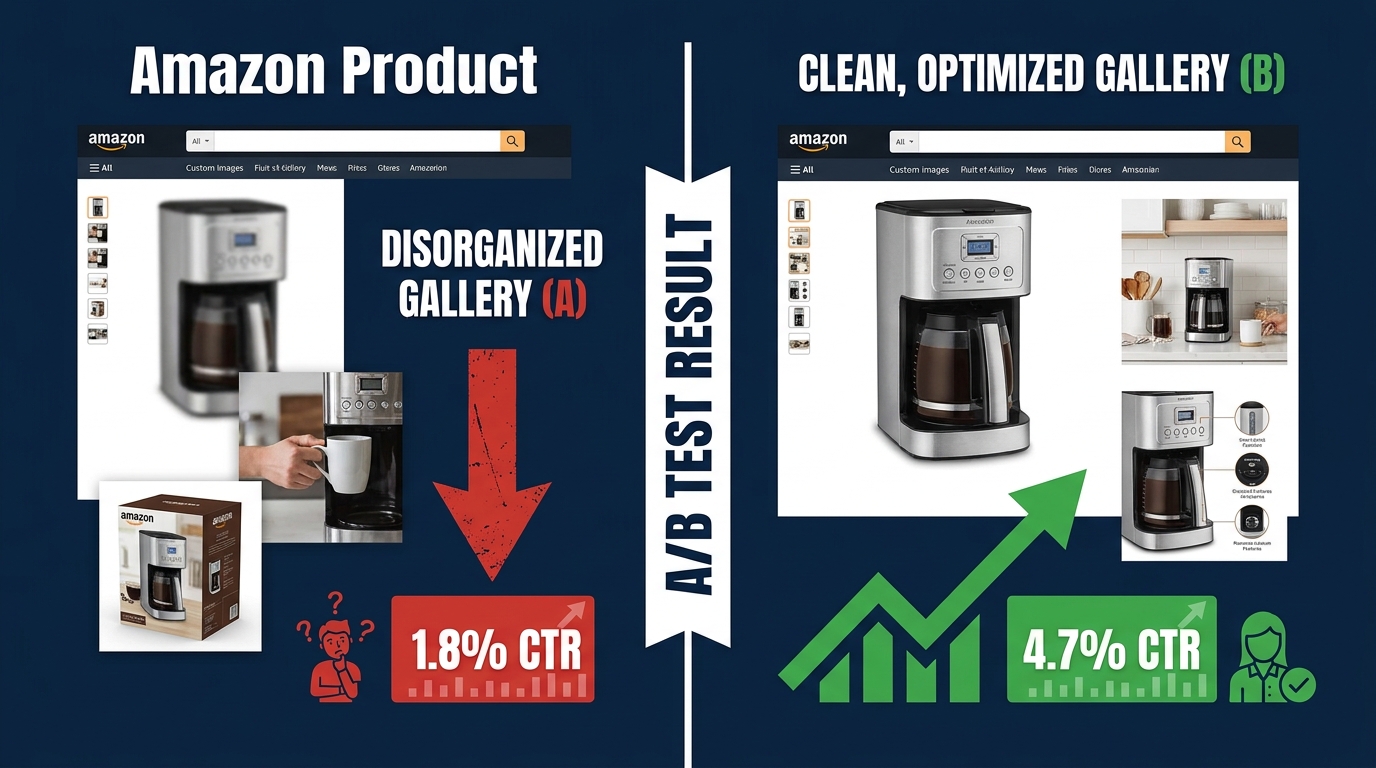
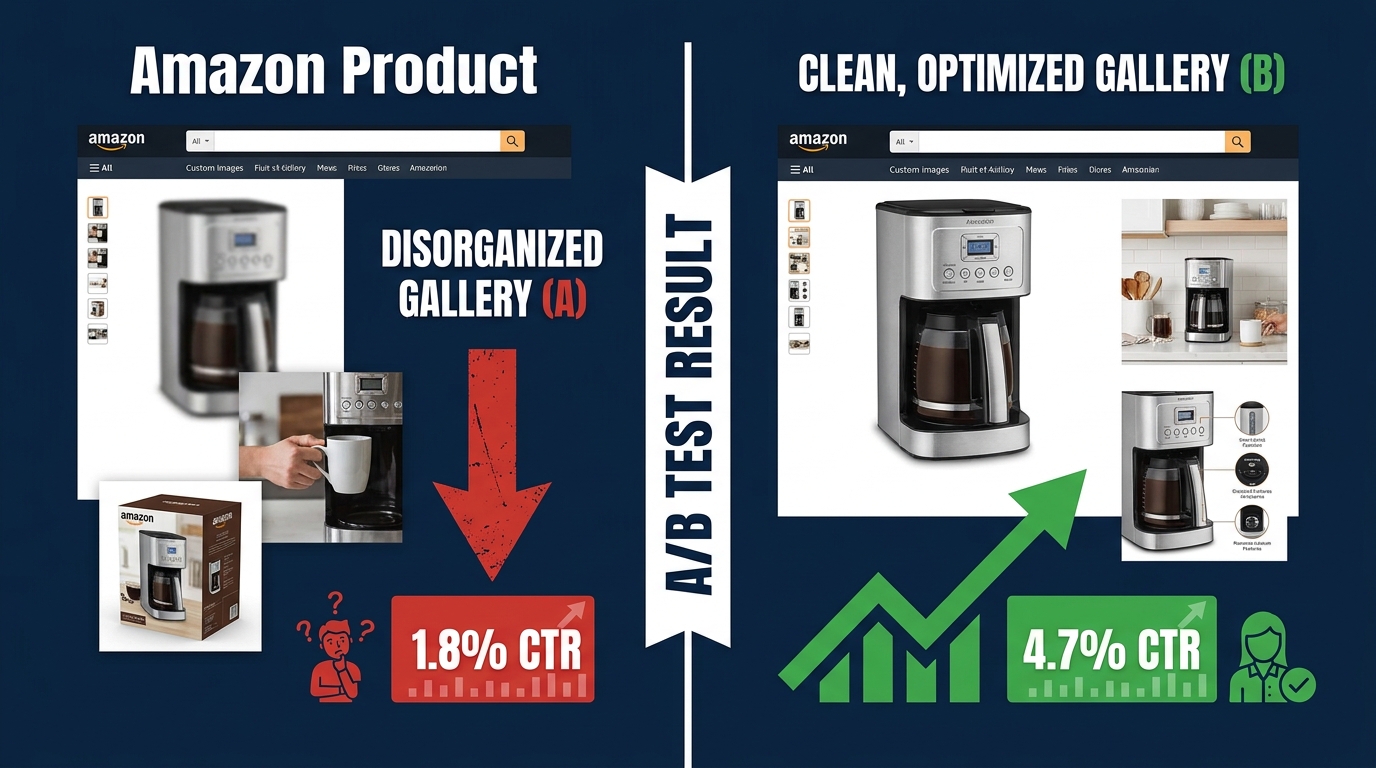
    Amazon image A/B testing split screen showing CTR improvement from 1.8% to 4.7% after gallery optimization

    There is a particular kind of confidence that comes from having run an experiment. You split-tested your main image, let it run for two weeks, saw Version B pulling slightly ahead, applied the winner, and moved on. The listing is updated. The test is done. The data has spoken.

    Except in most cases, it hasn’t. The data was inconclusive at best — and actively misleading at worst. Amazon’s own internal guidance recommends running image experiments for at least eight to ten weeks. Industry data shows most sellers stop theirs in under three. That gap is where the false confidence lives, and it is costing brands real conversion rate percentage points every single day.

    Amazon image testing is one of the highest-ROI activities a brand-registered seller can pursue. Amazon itself has documented listing optimizations producing sales lifts of up to 20–25% in controlled experiments, with even conservative image-specific tests regularly delivering 5–12% conversion rate improvements. But those results only materialize when the testing architecture is designed correctly — when you know what you’re testing, why you’re testing it, what metric actually measures success, and how long you need to wait before the result means anything.

    This article is not about whether to test your images. That question is settled: you absolutely should. This is about how the testing process breaks down, what a properly structured image testing architecture actually looks like, and how to build a gallery optimization system that compounds wins over time instead of producing noise.

    What Manage Your Experiments Actually Measures (And What It Doesn’t)

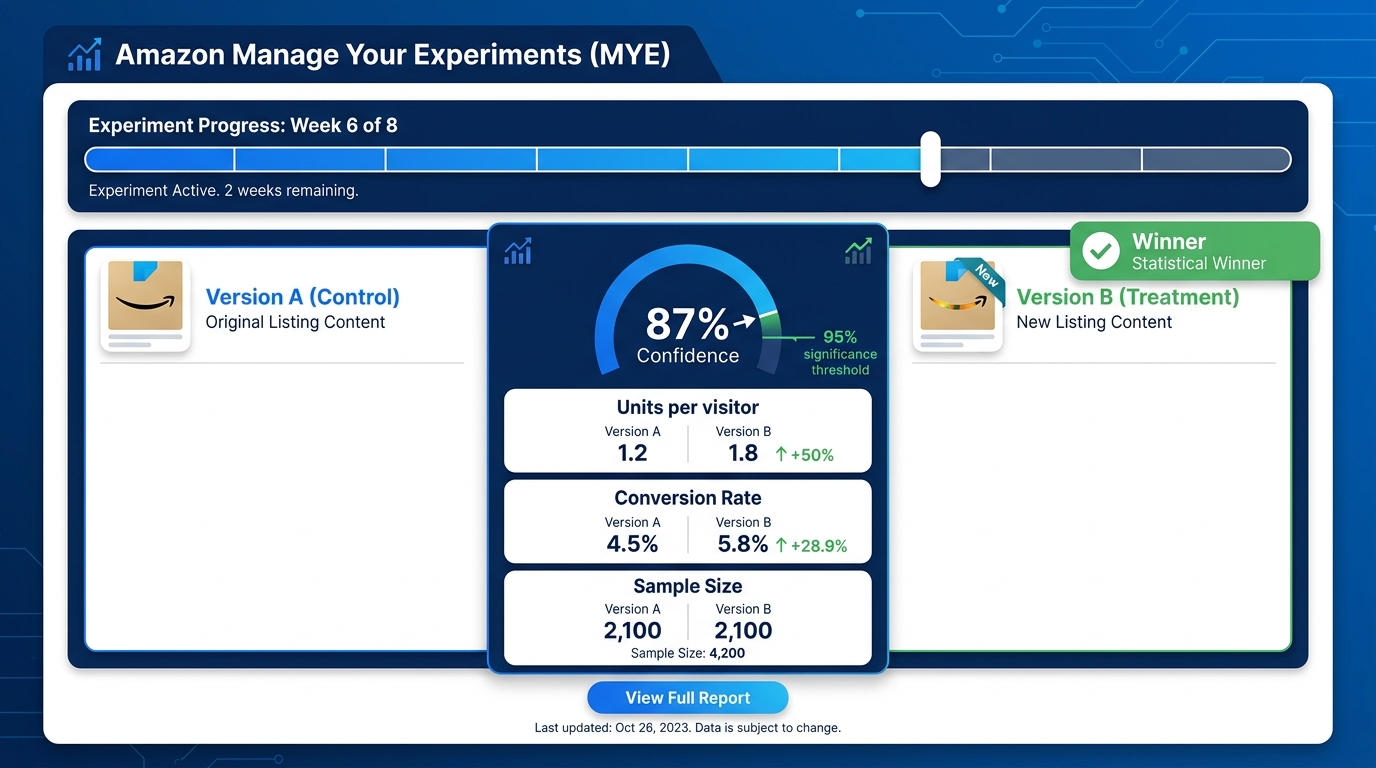
    Amazon Manage Your Experiments dashboard showing Version A vs Version B with 95% statistical significance threshold and key metrics

    Amazon’s Manage Your Experiments (MYE) tool, accessible via Seller Central under Brands → Manage Your Experiments, is the native A/B testing environment for Brand Registry sellers. It supports testing of main images, image stacks, titles, and A+ content. The mechanics are straightforward: traffic to your detail page is split randomly 50/50 between Version A and Version B, and Amazon tracks performance on both variants simultaneously.

    What MYE reports is genuinely useful — but it’s a narrower picture than most sellers assume.

    The Metrics MYE Tracks

    The MYE dashboard surfaces several core metrics on a weekly basis:

    • Units per unique visitor — the primary success metric Amazon uses to determine a winner
    • Conversion rate — the percentage of detail page visitors who complete a purchase
    • Units sold — raw unit volume per variant
    • Sample size — the number of unique shoppers who saw each version
    • Probability of winning — Amazon’s confidence estimate for which variant is better
    • Projected one-year impact — an estimated annualized sales difference based on current test data

    MYE reaches statistical significance when it achieves approximately 95% confidence that one version outperforms the other. That threshold requires sufficient sample size, which in practice means roughly 700 or more detail page views in the preceding 30 days as a minimum eligibility floor — and meaningfully more traffic than that before results become reliable.

    What MYE Does Not Tell You

    Here is where most sellers run into trouble. MYE measures on-page performance — what happens once a shopper lands on your detail page. It does not directly measure click-through rate from search results or sponsored ad placements. That means if your main image change primarily affects whether shoppers click on your listing from a search page, MYE will only partially capture that impact. The CTR lift shows up indirectly as increased traffic volume to the listing over time, but MYE itself is not a CTR measurement tool.

    MYE also cannot isolate the impact of images from concurrent changes. If your team updates ad bids, adjusts pricing, or runs a promotion during an active experiment, the results become impossible to interpret cleanly. This is not a flaw in the tool — it is a constraint every seller needs to understand and plan around.

    Eligibility Requirements in 2026

    Not every ASIN qualifies for MYE image testing. Amazon’s current requirements include active Brand Registry enrollment, sufficient recent traffic (the 700+ page views per 30 days benchmark is widely cited in the seller community), and the ASIN must be in good standing with no active policy violations. New or low-velocity products simply may not accumulate enough traffic to produce statistically meaningful results within a reasonable test window. This is not a technicality — it is one of the core reasons so many image tests produce inconclusive or misleading results.

    The Decision-Journey Framework: Mapping Each Image Slot to a Buyer Question

    Amazon gallery image slots mapped to buyer decision journey questions — from slot 1 hero image through slot 7 detail shots

    Before you can test anything intelligently, you need a model of what each image is supposed to accomplish. The most effective framework in current practice treats the Amazon gallery not as a collection of product photos, but as a structured answer to a sequential series of buyer questions. Shoppers arrive at your listing with a mental checklist — and your images either answer those questions in order, or they don’t.

    This matters because attention decays with every swipe. Research on e-commerce shopper behavior consistently shows that the majority of detail page visitors view images sequentially from left to right. Each additional image receives progressively less attention. The first three images carry disproportionate conversion weight. If you burn those slots on redundant or low-information visuals, you have already lost the majority of marginal buyers before your most compelling content appears.

    The Seven-Slot Question Map

    Here is the decision-journey mapping that leading Amazon-focused agencies and optimization specialists have converged on in 2026:

    • Slot 1 (Main Image): “Is this what I’m looking for?” — Pure recognition and category identification. Amazon’s white-background requirement constrains this slot, but everything within those constraints — product angle, negative space, size fill — is a testable variable that drives click-through from search.
    • Slot 2: “How big is it / will it fit?” — Scale and context. Shoppers need a reference point. A product shown next to a recognizable object, in a room context, or with explicit dimension callouts answers the scale question that text rarely resolves as effectively.
    • Slot 3: “What does it actually do for me?” — The primary benefit, expressed visually. This is typically the highest-impact conversion slot after the main image. An infographic or annotated lifestyle image that communicates the top value proposition clearly outperforms generic detail shots in this position.
    • Slot 4: “Will this work in my situation?” — Use-case contextualization. A lifestyle image showing the product in realistic use addresses the “but will it work for someone like me?” question. This slot should reflect your target customer’s actual context, not a generic aspirational scenario.
    • Slot 5: “Can I trust this product?” — Credibility and proof. Certifications, awards, material quality close-ups, or social proof elements belong here. This slot handles the risk-reduction phase of the decision journey.
    • Slots 6–7: “What else do I need to know?” — Secondary details, variants, bundle contents, compatibility information. These slots serve the more engaged buyer who has already mostly decided and is validating final specifics.

    Why This Framework Changes What You Test

    Once you assign each slot a specific job in the buyer journey, your test hypotheses become much more precise. Instead of “let’s try a different image in slot 3,” you’re asking: “Does communicating the primary benefit through an annotated infographic or through a lifestyle-in-use shot produce better conversion at this stage of the decision?” That is a testable question with a clear success metric. It will produce actionable data. Generic image swaps produce noise.

    The framework also reveals which slots have the most conversion leverage for your specific category. A product where the primary buyer objection is “I’m not sure if this is the right size” has its highest-impact test opportunity in slot 2, not slot 3. A product where the primary objection is “I’m not sure this brand is trustworthy” has its most important work to do in slot 5. The decision-journey map tells you where to focus your testing resources first.

    Main Image Testing: The One Test That Moves Everything Else

    If you can only run one test on any given ASIN, it should be the main image. No other single change to your listing — not your title, not your bullet points, not even your price in many cases — has the same upstream leverage. The main image determines whether your ASIN gets clicked from search results. Without clicks, no downstream conversion optimization matters.

    This upstream effect is what makes main image testing qualitatively different from testing secondary gallery images. A main image improvement compounds through your entire marketing funnel: more organic clicks, better ad click-through rates, higher quality scores for sponsored placements, and ultimately a more efficient cost-per-click across all campaigns. Estimated improvements in main image performance that lift CTR by even 1–2 percentage points can produce double-digit revenue changes on high-volume ASINs when the downstream math is fully accounted for.

    What to Actually Test in Your Main Image

    The most common mistake in main image testing is testing variations that are too similar to produce a detectable signal. Moving a product slightly left versus slightly right will not produce a statistically significant result in any reasonable test window. Meaningful tests require meaningful differences. The variables worth testing include:

    • Product angle: Front-facing versus three-quarter perspective versus overhead can produce dramatically different recognition rates depending on the category. Apparel, footwear, small electronics, and kitchen tools all have different “recognition angles” that convert differently.
    • Product fill and framing: Amazon’s requirement that the product occupy at least 85% of the image frame still leaves substantial room to test how the product is positioned within that frame. Products with multiple components benefit from tighter or looser compositions differently.
    • Variant shown: For listings with multiple colors, sizes, or configurations, which variant appears in the main image affects both CTR and downstream conversion. The most visually striking variant often outperforms the most popular seller.
    • Props and secondary elements: Amazon’s main image rules prohibit text and promotional badges but allow product-adjacent props in many categories. Testing with versus without contextual props — packaging, accessories, complementary items — can reveal whether context or isolation works better for your category.
    • White space distribution: More white space versus less, product higher versus lower in the frame — these subtle compositional choices affect how thumbnails render in search results, particularly on mobile screens where the image is small.

    Setting the Right Success Metric for Main Image Tests

    Because MYE measures on-page behavior and the main image’s primary job is to drive clicks from search, there is an inherent measurement challenge. The correct approach is to run MYE for the on-page conversion signal while simultaneously monitoring your Brand Analytics data for shifts in click-through rate from search. The two data sources together give you a complete picture of whether a main image change is working. Relying on MYE conversion data alone can cause you to prematurely declare a winner on a variant that converts slightly better on-page but is actually losing clicks in search — producing a net-negative outcome that the test appears to endorse.

    Gallery Slots 2–4: The Conversion Engine Most Sellers Underinvest In

    If the main image gets the click, slots 2 through 4 close the sale. This is where the majority of buying decisions are made or abandoned, and where the gap between optimized and unoptimized galleries is widest in practice. Yet most sellers either treat these slots as an afterthought — uploading whatever product photos were in the original shoot — or test them so infrequently that they go years without knowing whether their current configuration is anywhere near optimal.

    The Strategic Role of Each Slot

    The 2026 consensus among Amazon conversion specialists is to treat slots 2, 3, and 4 as three distinct conversion tools, each with a specific job:

    Slot 2 — Scale and Context: This slot addresses the single most common reason shoppers abandon product pages without purchasing: uncertainty about size. Dimension infographics, comparison shots showing the product next to everyday objects, or images showing the product in a clearly recognizable context all perform stronger here than aesthetic detail shots. Testing should focus on whether explicit measurement callouts, relative size comparisons, or in-context placement produces better conversion for your specific product category.

    Slot 3 — Primary Benefit Communication: Slot 3 is your first full infographic opportunity. The goal is to communicate your single most important value proposition as clearly and visually as possible. Best-performing implementations in 2026 show one hero benefit per image — not three benefits crowded into a single graphic. Testing should compare a single-benefit infographic against a multi-feature overview to understand whether your buyer needs persuasion depth or persuasion clarity at this stage.

    Slot 4 — Objection Handling: Every product category has a dominant purchase objection — a specific fear, uncertainty, or doubt that prevents otherwise interested shoppers from committing. Slot 4 should be engineered to address that objection directly. For a supplement, it might be an image highlighting third-party lab testing. For a kitchen appliance, it might be a dishwasher-safe components graphic. For a children’s toy, it might be safety certification callouts. The brands that have mapped their primary objection and addressed it explicitly in slot 4 consistently outperform those using generic lifestyle content in this position.

    Testing Gallery Slot Order vs. Image Content

    There are two distinct types of tests you can run on slots 2–4: testing what image goes in a slot and testing which order the slots appear in. These are separate questions requiring separate tests. Don’t conflate them. If you swap both the order and the content simultaneously, you have no way to know which change drove any performance difference you observe. Run content tests first — establish what the best image for each job is — then run order tests to optimize the sequence.

    Infographic vs. Lifestyle Images: How to Stop Arguing and Start Testing

    Comparison chart showing infographic images outperforming lifestyle shots in conversion for gallery slots 2-3 while lifestyle wins on CTR and emotional appeal in slots 4-5

    The infographic versus lifestyle debate is one of the most persistent and least productive arguments in Amazon optimization circles. Practitioners on both sides have strong opinions, war stories to support those opinions, and case studies that confirm their priors. The argument persists because both sides are correct — just not universally and not in the same slots.

    The current weight of evidence, based on aggregated A/B test results from brands running systematic gallery experiments, points to a consistent pattern:

    • Infographic-heavy galleries outperform lifestyle-only galleries on conversion rate — particularly in slots 2 through 4 where information density matters most.
    • Lifestyle images outperform pure infographics on click-through rate — they generate more emotional engagement in search results and in top-of-gallery placement.
    • Hybrid galleries outperform both single-style approaches — the highest-converting galleries use a structured alternation of infographic and lifestyle content, not a uniform aesthetic throughout.

    Why Infographics Win on Conversion

    The explanation is grounded in buyer psychology. Once a shopper has clicked through to your detail page, they are in an information-gathering mode. They are asking specific questions and evaluating specific criteria. An infographic that answers those questions explicitly — with labeled callouts, comparison data, or specification graphics — removes friction from the decision process. A lifestyle image of someone enjoying the product is emotionally appealing but functionally non-specific. For a buyer trying to determine whether a mattress topper will fit their California King bed, a clear dimension infographic eliminates the objection. A photo of someone sleeping peacefully does not.

    Why Lifestyle Images Win on CTR

    The click-through dynamic is the reverse. In search results, shoppers are scanning dozens of thumbnails in seconds. What catches attention at thumbnail size is color, emotional resonance, and visual novelty — qualities that lifestyle photography tends to deliver more effectively than information-dense infographics, which become illegible at small sizes. A main image infographic with text callouts often renders as visual noise in a search results thumbnail, while a bold lifestyle image communicates category and aspiration instantly.

    Building the Hybrid Gallery

    The practical implication is a deliberate gallery structure: lifestyle or clean hero for the main image (slot 1), infographic treatment for slots 2 and 3, lifestyle-in-use for slot 4, proof/credibility content for slot 5, and a mix of detail and secondary lifestyle for slots 6 and 7. This sequence uses each image type where it performs best. But — and this is critical — the optimal balance is category-specific and buyer-specific. The only way to know the right hybrid ratio for your ASIN is to test it directly with your actual traffic.

    The sellers who skip this testing and implement the “standard” hybrid sequence are still doing better than sellers with unoptimized galleries. But they’re leaving residual optimization on the table that only their own data can capture.

    Mobile-First Gallery Design: Why Desktop-Optimized Stacks Are Losing

    Mobile vs desktop Amazon gallery comparison showing 60-75% of traffic is mobile with only 3 images visible above fold on smartphone

    If you design your Amazon gallery images primarily on a desktop monitor, you are optimizing for a minority of your traffic. Current estimates across the Amazon seller community put mobile traffic at 60 to 75% of all Amazon detail page visits in 2026, with some category-specific data suggesting the mobile share may be even higher for impulse and convenience categories. The practical implication for image testing is that your test results are being driven primarily by mobile user behavior — which means mobile rendering quality determines whether your tests succeed or fail.

    How Mobile Changes What Works

    Mobile Amazon browsing is structurally different from desktop in ways that directly affect gallery performance:

    Above-the-fold visibility: On a mobile screen, typically only one to three images are visible without scrolling. The main image occupies most of the screen. Slots 2 and 3 require a swipe. Slot 4 onward requires more deliberate engagement. This means the “conversion window” is tighter on mobile — your first two to three images need to do more of the total persuasion work.

    Text legibility at swipe size: The infographic approach that works beautifully on a 27-inch desktop monitor frequently becomes unreadable on a 6-inch phone screen. Text callouts need to be larger, shorter, and more contrast-heavy to remain legible on mobile. Infographics with six or more annotation labels, multi-column layouts, or small supporting text tend to underperform on mobile even when they test well on desktop.

    Scroll behavior: Mobile shoppers swipe through images faster than desktop users scroll. Images that require five to ten seconds to fully absorb are skipped on mobile. The “one key message per image” principle is partly an aesthetic recommendation — but on mobile, it is a functional necessity. A mobile user who cannot instantly understand what an image is communicating will swipe past it without stopping.

    How to Test for Mobile Performance Specifically

    MYE does not segment results by device type, which creates a genuine blind spot for mobile-specific optimization. The workaround most brands use is off-platform testing (covered in the next section) combined with qualitative review of images on actual mobile devices before launching live tests. Before any image goes into an MYE experiment, it should be viewed on a physical iOS and Android device — not a browser developer tools emulation — at the full-screen gallery size and at the thumbnail size that appears in search results on mobile. Images that fail the readability test at mobile thumbnail size should be revised before burning four to eight weeks of live traffic data on them.

    The practical design guidelines that emerge from mobile-first testing: minimum 24-point equivalent font for any on-image text, maximum two to three key callouts per infographic, high-contrast color choices that remain legible at reduced size, and product fills that communicate clearly even when the image is cropped to a square thumbnail.

    Off-Platform Pre-Validation: The PickFu Layer Before You Burn Live Traffic

    One of the most significant shifts in how sophisticated Amazon brands approach image testing in 2026 is the adoption of off-platform pre-validation as a mandatory step before any live MYE experiment. The logic is straightforward: running a poorly designed image variant in a live test for eight weeks costs you real conversion rate and real revenue. Running it in a PickFu poll for $50 and 200 responses costs you $50 and two days. Pre-validation moves the failures out of your live listing and into the design phase where they belong.

    How the Pre-Validation Workflow Works

    The pre-validation process combines consumer research tools — most commonly PickFu, though ProductPinion and other platforms serve the same function — with Amazon’s native MYE in a two-stage workflow:

    1. Stage 1 — Concept Screening: Before investing in final production of image variants, run a poll with rough mockups or concept images asking targeted respondents which version they would be more likely to click on. The goal here is to eliminate obvious losers before they reach production. Poll respondents should be filtered to match your target buyer profile — age, gender, purchase history, relevant interests — not the general population.
    2. Stage 2 — SERP Simulation: For main image testing specifically, PickFu offers a search results page simulation format where your product appears alongside competitor listings. This tests for click-through in a competitive context — the actual environment where your main image’s job gets done. A main image variant that “wins” in an isolated head-to-head comparison may actually lose share in a real search results page where five competitors’ images are visible simultaneously.
    3. Stage 3 — MYE Confirmation: The variants that survive pre-validation then go into a live MYE test for statistical confirmation with real shopper behavior. Because only pre-validated images enter the live test, the quality of hypotheses is higher, and the probability of reaching statistical significance faster is meaningfully improved.

    The Performance Case for Pre-Validation

    The quantitative case for this two-stage approach is compelling. Brands that use PickFu pre-validation before MYE have reported reaching statistical significance in MYE in as few as seven days on high-traffic ASINs — compared to the typical six to ten weeks without pre-validation. The mechanism is straightforward: when the image variant entering the live test is already demonstrably stronger by consumer research standards, the performance gap between versions is larger, which requires less data to confirm statistically. Smaller differences require proportionally more data to detect.

    The secondary benefit is learning quality. Off-platform polls often include qualitative feedback — respondents can explain why they preferred one image over another. That qualitative data feeds directly back into the creative brief for the next round of image development, creating a systematic improvement loop that pure MYE testing cannot provide.

    The 5 Ways Image Tests Fail (And How to Prevent Each One)

    Five warning panels showing the most common Amazon image A/B test failure modes including premature stopping, testing multiple variables, and low-traffic ASINs

    After examining how Amazon image testing works in theory and in practice, the failure modes become predictable. Most teams encounter the same five problems repeatedly. Understanding each one specifically — including what it looks like in your data and how to prevent it — is what separates brands that compound wins over time from brands that run tests indefinitely without accumulating useful knowledge.

    Failure Mode 1: Premature Stopping

    This is the single most common cause of misleading image test results. A test that has been running for two weeks with a slight advantage for Version B is not evidence that Version B is better. It is evidence that you have accumulated approximately 25% of the data you need to reach 95% confidence. Stopping early is not just unhelpful — it actively produces false confidence. Amazon’s own guidance is explicit: image tests need four to ten weeks depending on traffic volume. High-volume ASINs can reach significance faster; low-volume ASINs may need the full ten weeks or more.

    Prevention: Set a calendar reminder to check results at the four-week mark, but commit to not acting on them until Amazon’s confidence indicator reaches at least 90% — and ideally the full 95% threshold that MYE uses to declare a winner. Use MYE’s “run to significance” option rather than setting a fixed end date wherever possible.

    Failure Mode 2: Testing Multiple Variables Simultaneously

    Updating the main image, swapping slot 3, and reordering slot 4 all within the same test period is not an experiment — it is a change event. When you observe a result (better or worse conversion), you have no way to know which change caused it. Every image test should isolate a single variable. One element, one test, one result. The throughput cost of this discipline — running tests sequentially rather than in parallel — is real but vastly outweighed by the cost of accumulating uninterpretable data.

    Prevention: Maintain a test queue, not a test batch. Prioritize which single change has the highest expected impact and test that first. Apply the winner before starting the next test. This sequential approach means each test builds on confirmed knowledge rather than uncertain confounds.

    Failure Mode 3: Testing Changes That Are Too Small

    A/B tests can only detect differences that are large enough to produce a measurable signal above the noise floor. An image where you moved the product angle by five degrees, changed the background from pure white (#FFFFFF) to off-white (#F5F5F5), or adjusted the shadow treatment is unlikely to produce a detectable conversion difference in any realistic test window. The change has to be substantive enough that a meaningful portion of buyers would actually notice and respond differently.

    Prevention: Apply the “would a different buyer population choose this?” test to your variants. If the two versions are so similar that any reasonable person would be indifferent between them, they will not produce a meaningful A/B test result. Reserve subtle refinements for after you have tested large conceptual differences that establish the right creative direction first.

    Failure Mode 4: Running Tests on Ineligible ASINs

    Amazon requires a minimum traffic threshold for MYE experiments to produce reliable results. The commonly cited benchmark is 700 or more detail page views in the prior 30 days, but in practice, getting to statistical significance quickly requires substantially more traffic than the minimum eligibility floor. Running image tests on low-velocity ASINs produces inconclusive results month after month — which some brands misinterpret as “no difference found” when the reality is “not enough data to detect a difference even if one exists.”

    Prevention: Tier your ASIN catalog by traffic volume and run active MYE tests only on high-volume products. For lower-traffic ASINs, use off-platform pre-validation tools and apply the learnings from high-traffic tests as informed defaults rather than waiting for statistically significant on-platform results that may never arrive.

    Failure Mode 5: Using the Wrong Success Metric

    Many sellers judge image tests by raw sales numbers in the first weeks of a test. This is problematic for two reasons: first, early sales data is too noisy to draw conclusions from; second, sales volume conflates organic traffic trends, paid advertising spend, and seasonal patterns with the actual image performance. The correct primary metric for gallery image tests is conversion rate (unit session percentage) — not total units sold. Conversion rate isolates the probability-of-purchase signal from traffic volume noise, making it a far cleaner measure of whether your image is doing its persuasion job.

    Prevention: When evaluating MYE results, lead with conversion rate and units per unique visitor. Use total sales as a secondary sanity check. Resist the instinct to call a winner based on a brief sales spike that coincides with a pricing change, coupon activation, or advertising budget increase during the test period.

    Building a Rolling Test Calendar: How to Compound Wins Over Time

    Individual A/B tests produce individual wins. A rolling test calendar produces a compounding optimization system. The difference in outcomes over a 12-month period between a brand that runs one or two tests per year and a brand that runs systematic quarterly testing across their top-10 ASINs is not marginal — it is often the difference between a stagnant conversion rate and a listing that has been continuously refined to near-optimal performance.

    How the Compounding Effect Works

    Imagine a brand that tests and improves their main image in Q1, winning a 3% CTR improvement. In Q2, they test gallery slots 2–3 using the learnings from Q1’s creative approach, winning a 6% conversion rate improvement. In Q3, they test lifestyle versus infographic in slot 4, winning another 4% conversion improvement. Each win compounds on top of the previous one, because the traffic improvements from Q1 mean Q2’s conversion test runs faster, and the improved conversion from Q2 means Q3’s test traffic is higher quality. The math accumulates faster than isolated tests suggest.

    The Practical Test Calendar Structure

    A functional rolling test calendar for a mid-size Amazon brand (20–50 active ASINs) looks something like this in practice:

    • Month 1–2: Main image test on your top 3 ASINs by revenue. These are your highest-leverage tests and should always be the first priority.
    • Month 2–3: Gallery slot 2–3 content tests on whichever ASINs completed their main image test. Apply the main image winner before starting the gallery test.
    • Month 3–4: Lifestyle versus infographic testing in slot 4 on the same high-priority ASINs.
    • Month 4–6: Begin the same cycle on the next tier of ASINs by traffic volume, while running refinement tests on the top ASINs based on prior results.

    The critical discipline is never running two overlapping tests on the same ASIN. Concurrent changes to the same listing contaminate both results. Use a simple shared spreadsheet or project management tool to track which ASINs are in active tests, what is being tested, when the test started, and what the result was. This institutional memory is more valuable than any individual test result.

    When to Retest

    A winning image variant is not permanent. Competitor creative evolves. Category visual norms shift. Seasonal buyer psychology changes. The general guidance in the Amazon optimization community is to retest your top ASINs’ main images every six to twelve months, with gallery slots tested on a 9–12 month cycle. A version that won convincingly 18 months ago may now be losing to newer competitor creative even though you haven’t changed anything.

    Measuring Beyond Conversion: What CTR, Returns, and Ad Efficiency Tell You

    Conversion rate is the most important metric for gallery image testing, but it is not the only one. A complete picture of image performance requires monitoring several downstream metrics that MYE does not directly surface — and which can reveal that an image is creating problems even when conversion data looks neutral or positive.

    Click-Through Rate from Organic and Paid Search

    As covered earlier, MYE does not directly measure click-through rate from search results. This creates a real measurement blind spot, particularly for main image tests. The workaround is to monitor your Brand Analytics data — specifically the Search Catalog Performance report, which shows click-through rates for your ASINs in search results — during and after image test periods. A main image change that lifts CTR even marginally on high-volume search terms produces disproportionate revenue impact, because it compounds across both organic and paid traffic.

    For sponsored product campaigns, watch your CTR metric at the campaign level during image test periods. If your main image change produces a significant CTR improvement in search results, you will see it reflected in your ad CTR within one to two weeks — well before MYE reaches statistical significance. This early signal can help validate that you are on the right creative track, even if it isn’t a final answer.

    Return Rate as an Image Quality Signal

    One of the most underused metrics in image testing is return rate. Images that overstate product quality, misrepresent color or size, or create expectations the physical product cannot meet may convert well in the short term — but they produce higher returns, negative reviews, and long-term conversion drag as the review score deteriorates. The most common return-driving image problem is color misrepresentation: product images that show colors more saturated or different from the actual product under normal lighting conditions.

    When evaluating a test winner, always check whether the winning variant is associated with a return rate increase. A 5% conversion rate improvement paired with a 3% return rate increase is not a net win — it is a warning signal that your new image may be over-promising.

    Advertising Efficiency and ROAS

    A well-optimized image gallery improves advertising efficiency because it increases the conversion rate of the shoppers your ads bring to the listing. If your gallery converts at 15% and your competitor’s converts at 22%, you are effectively paying 47% more per sale through the same advertising investment. Gallery optimization is, in this sense, one of the highest-leverage cost-reduction activities available to an Amazon advertiser — but it typically isn’t framed that way in budget discussions.

    Track your ROAS per campaign on your top-tested ASINs before and after image improvements. Sustained gallery optimization campaigns regularly produce 10–20% ROAS improvements over a 6–12 month period, simply by increasing the probability that a paid click converts. The advertising efficiency gains from systematic image testing are often larger in absolute dollar terms than the organic conversion rate improvements, because they reduce the cost basis for your entire paid traffic volume.

    Putting It All Together: The Testing Architecture That Actually Compounds

    The core insight that emerges from everything above is that Amazon image testing is not a one-time activity or a single-test improvement project. It is an architecture — a structured, sequential, hypothesis-driven system that produces compounding improvements over time when built correctly and produces noise when built incorrectly.

    The architecture has five interlocking components:

    1. The Decision-Journey Map: Assign each image slot a specific buyer question it must answer. This creates testable hypotheses instead of arbitrary creative swaps.
    2. The Pre-Validation Layer: Use off-platform tools to screen concepts before live traffic investment. This improves hypothesis quality and accelerates time to significance in live tests.
    3. The Live Testing Protocol: Run single-variable tests in MYE for the full recommended duration, using conversion rate as the primary success metric and monitoring CTR and returns as secondary signals.
    4. The Results Database: Maintain a documented record of every test hypothesis, result, and decision. This institutional memory prevents re-testing known losers and allows creative learnings to transfer across ASINs and categories.
    5. The Rolling Test Calendar: Schedule sequential tests on a structured cadence, prioritized by ASIN revenue and traffic volume, with retesting cycles built in for previously optimized listings.

    The brands that achieve sustained conversion rate improvements through image testing — the ones reporting 15–25% cumulative gains over a 12-month period — are not doing anything magical. They are simply running this architecture consistently, applying wins sequentially, and maintaining the discipline not to conflate noise with signal.

    Key Takeaways for Your Image Testing Program

    Before you run your next image test, use this checklist to assess whether your testing architecture is set up for success:

    • Traffic threshold: Does your ASIN have 700+ detail page views in the last 30 days? If not, prioritize off-platform testing instead of MYE.
    • Single variable: Are you testing exactly one change — and nothing else on the listing during the test period?
    • Meaningful difference: Are the two variants different enough that a genuine buyer would notice and potentially respond differently?
    • Slot assignment: Does each image in your gallery have a specific buyer question it is designed to answer?
    • Mobile rendering: Have you reviewed both test variants on physical mobile devices at gallery size and thumbnail size?
    • Duration commitment: Have you committed to not stopping the test before MYE reaches at least 90% confidence — and ideally 95%?
    • Pre-validation: Have you run off-platform concept screening before investing in final production versions?
    • Multi-metric monitoring: Are you tracking CTR (via Brand Analytics), return rate, and ad efficiency alongside MYE conversion data?
    • Results documentation: Is your test result going into a shared log that feeds future creative decisions?
    • Next test queued: Is the next test already scheduled so that improvement compounds continuously?

    Image testing is one of the few Amazon optimization activities where a disciplined, architecture-first approach consistently outperforms improvisation. The sellers who treat every gallery change as a hypothesis to be tested — rather than a design decision to be made — are the ones whose listings look completely different (and convert dramatically better) twelve months from now. That is the compounding dividend of building the testing architecture correctly from the start.