Author: algofuse

  • AWS Agent Marketplace: What It Actually Takes to Ship Your First Revenue-Ready AI Agent

    AWS Agent Marketplace: What It Actually Takes to Ship Your First Revenue-Ready AI Agent

    Developer at a command center with AWS Marketplace AI Agents console dashboards and an approved listing badge

    The hype cycle around AI agents has been deafening. Announcements pile up, demos proliferate, and LinkedIn is full of screenshots showing “autonomous” agents doing things that took entire teams before. But somewhere between a demo and a dollar, most AI agent projects stall.

    AWS Marketplace’s new AI Agents & Tools category changes that calculus — at least on paper. It offers a formal, structured path to turn an AI agent into a product that enterprise buyers can discover, purchase, and integrate directly into their AWS environments. No cold email sequences. No six-month procurement negotiation from scratch. Just a listing with a buy button attached to the most trusted B2B software marketplace on the planet.

    The catch: the path to a live, revenue-generating listing is more technically and operationally demanding than most builders expect. AWS has published detailed requirements, and the review process is neither automatic nor lenient. At the same time, the incentives for getting it right — a $75,000 MDF stack, enterprise co-sell motions, and Express Private Offers that can close five-figure deals in days — are genuinely compelling.

    This guide is for builders, ISVs, and technical founders who want the unvarnished facts: what listing tracks exist, what the technical contracts actually look like, how to price without leaving money on the table, and what a realistic first-90-day revenue ramp looks like on this platform. No fluff, no vendor cheerleading — just the mechanics you need to ship something that sells.

    What the AWS AI Agents & Tools Marketplace Actually Is (and Isn’t)

    Before diving into requirements, it’s worth being precise about what you’re dealing with. AWS Marketplace is not an app store in the consumer sense. It is a B2B procurement channel where enterprise buyers — particularly those already running workloads on AWS — can find, evaluate, and purchase third-party software. Transactions flow through existing AWS billing relationships, which is a significant adoption accelerator: the buyer doesn’t need to open a new vendor account, negotiate new payment terms, or get a new purchase order approved through a separate procurement process.

    In late 2025 and accelerating into 2026, AWS formally created an AI Agents & Tools category within this marketplace. This isn’t just a cosmetic label change. The category introduced specific product types, listing requirements, and technical integration paths that didn’t exist for standard SaaS software. It also aligned directly with Amazon Bedrock and the new Bedrock AgentCore runtime, meaning buyers can now deploy your agent directly into their Bedrock environment — the same environment where they’re already running foundation models.

    Product Types Now Available

    Within the AI Agents & Tools category, sellers can list four distinct product types:

    • API-based (SaaS) AI agents and tools — Agents exposed via REST or other HTTP APIs, billed as SaaS subscriptions or metered usage.
    • Container-based AI agents — Packaged as container images, deployed into buyer infrastructure via Amazon Elastic Container Service or AWS Bedrock AgentCore Runtime.
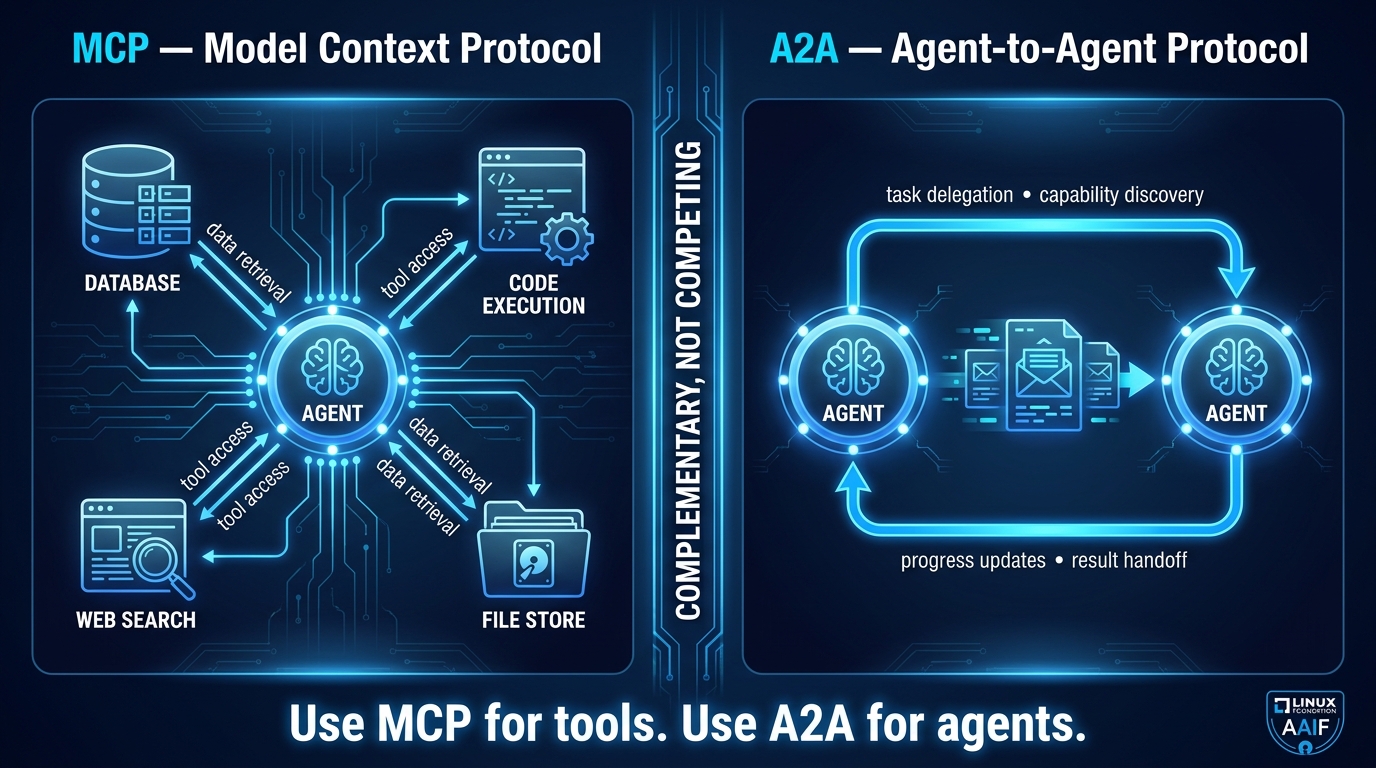
    • MCP servers — Model Context Protocol servers that expose tool capabilities to any MCP-compatible orchestrator, including Bedrock Agents.
    • A2A servers — Agent-to-Agent servers built on JSON-RPC 2.0, enabling interoperability between agents in multi-agent pipelines.

    What AWS Marketplace Is Not

    It’s equally important to understand what the platform doesn’t do. AWS Marketplace will not market your agent for you. Discovery relies on buyers actively searching within a category, and the Marketplace doesn’t run outbound campaigns on your behalf. It’s a distribution and transaction layer, not a demand generation engine. Sellers who treat listing approval as the finish line routinely see flat revenue curves. The listing is the starting gun, not the trophy.

    AWS Marketplace also doesn’t validate that your agent actually delivers business value. Listing approval confirms technical and security compliance; it does not certify ROI claims. Buyers have become savvier about this distinction, which means your listing copy and documentation need to carry the value story that the platform itself won’t tell.
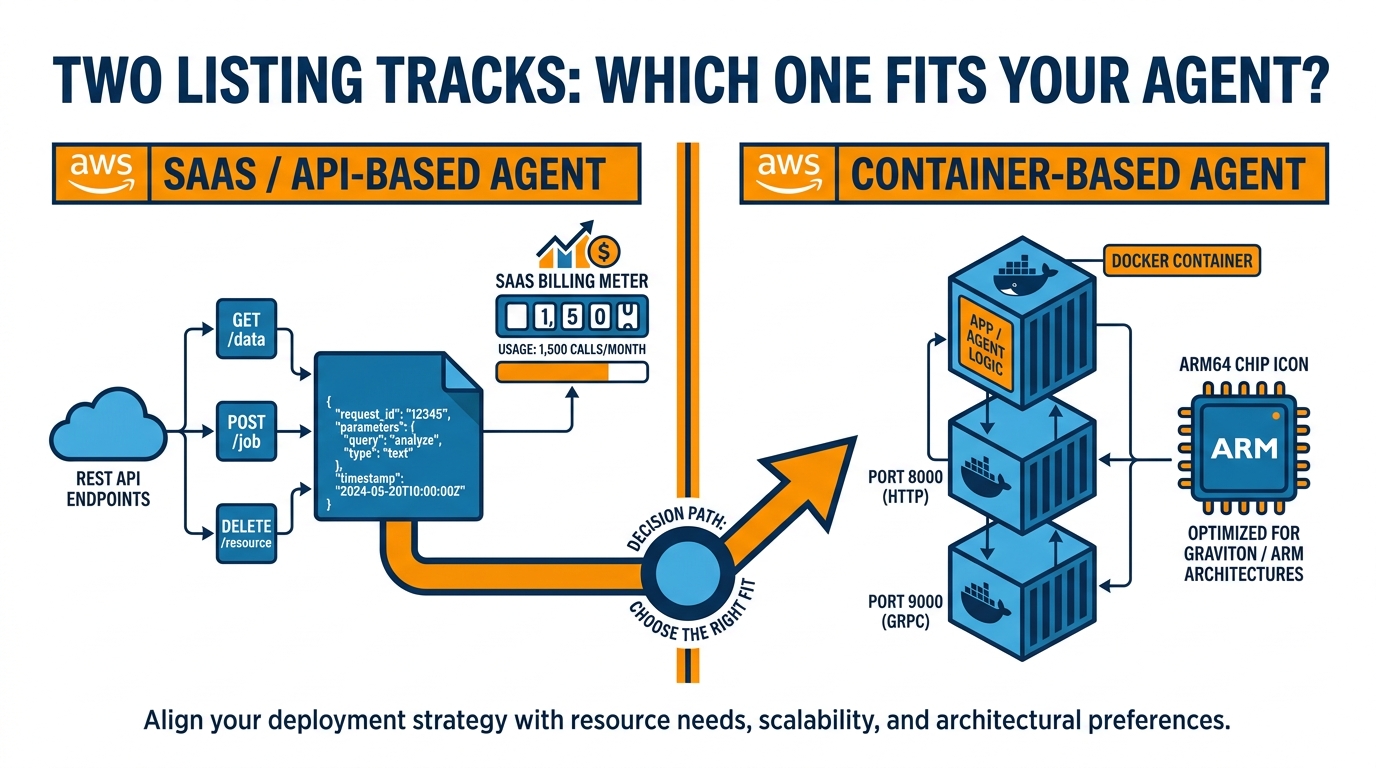
    Two-column comparison split: SaaS API-based agent listing track vs Container-based agent listing track for AWS Marketplace

    The Two Core Listing Tracks — and How to Choose the Right One

    The most consequential decision you’ll make before writing a single line of listing copy is which track your product belongs on. Choosing incorrectly means rework, delayed approval, and pricing models that don’t fit your delivery architecture. AWS has made the distinction reasonably clear, but the implications for your engineering and go-to-market motion are often misunderstood.

    Track One: SaaS / API-Based AI Agents and Tools

    This track is for agents that run in your infrastructure and expose their capabilities through an API. The buyer subscribes to access that API; they don’t run your code in their own AWS account. Think of this as the classic SaaS model, but with AWS handling billing, metering, and entitlement checks on your behalf.

    Operationally, this track requires you to maintain the availability, scalability, and security of your agent backend. If your agent goes down, your customers lose access. The tradeoff is control: you own the runtime, you can iterate quickly, and you don’t have to worry about packaging your agent to run in arbitrary customer environments.

    This track suits agents where the model weights, proprietary pipelines, or data connections that make the agent valuable are things you deliberately do not want to hand over to the buyer’s environment. Legal AI agents that connect to your proprietary case law database, for example, or market intelligence agents that require real-time feeds you control.

    Track Two: Container-Based AI Agents (Including AgentCore Runtime)

    The container track is for agents that run inside the buyer’s AWS environment. You package your agent as a container image — typically ARM64-compatible, given AgentCore’s architecture requirements — and the buyer deploys it into their infrastructure. This gives enterprise buyers the security and data-residency guarantees they often require: your agent processes their data without it ever leaving their VPC.

    This track includes the MCP and A2A server sub-types, which are specifically designed to participate in larger, multi-agent ecosystems running on Amazon Bedrock. If your agent is designed to be a component in an orchestrated pipeline rather than a standalone product, the container track with A2A capability is almost certainly where you belong.

    Decision Criteria That Actually Matter

    The real decision factors are three-fold. First: where does the sensitive data live? If the buyer’s data needs to stay in their environment, containers win. Second: how tightly coupled is your agent to your own proprietary infrastructure? If the magic is in your backend systems, SaaS wins. Third: who is your target buyer? Enterprise security teams nearly always prefer container deployments for agents that will process regulated data. Mid-market buyers often prefer the simplicity of an API subscription they can activate immediately.

    Many sellers ultimately build both, launching with the SaaS track for faster time-to-listing and then adding a container SKU once they understand what their enterprise buyers actually need. This is a legitimate sequencing strategy, but plan for it deliberately rather than discovering it after your first enterprise deal requires data residency guarantees you can’t meet.
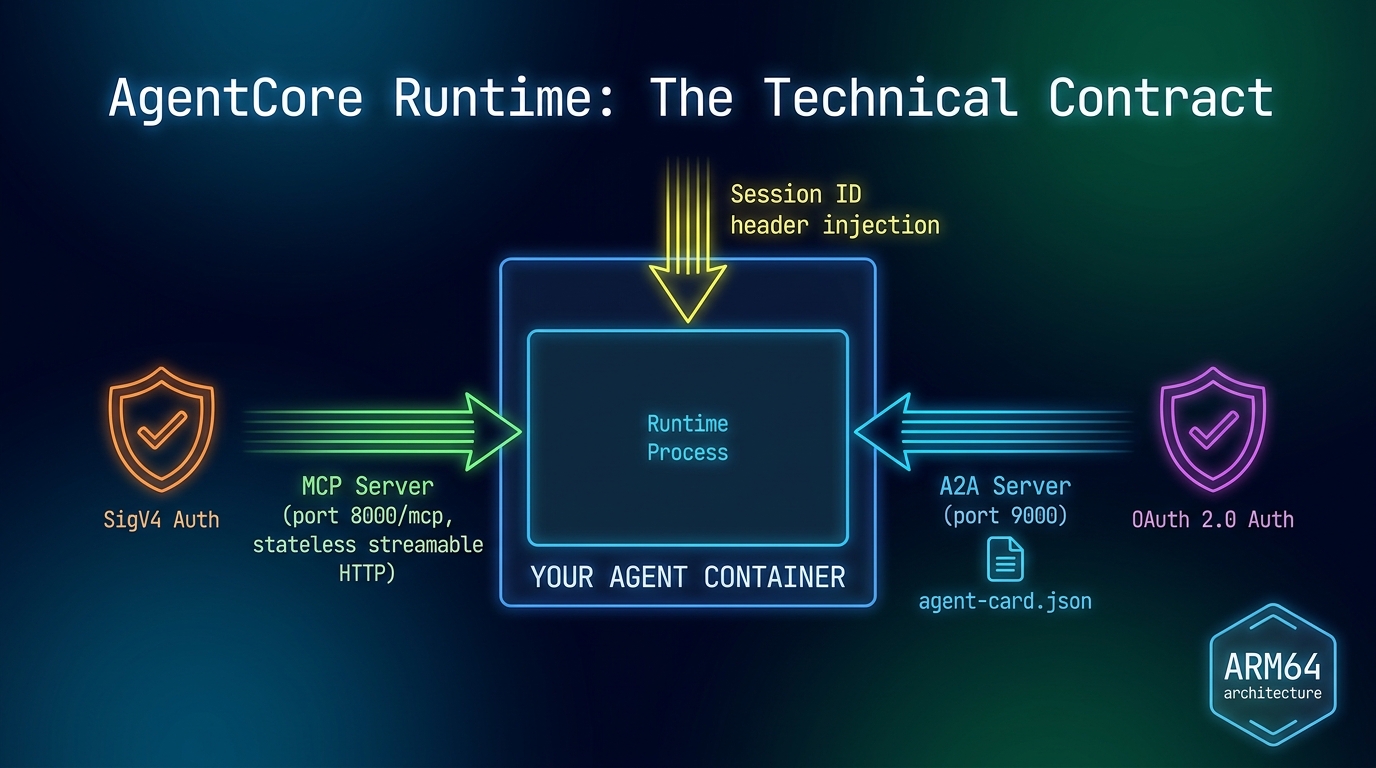
    Amazon Bedrock AgentCore Runtime architecture diagram showing MCP server on port 8000, A2A server on port 9000, SigV4 and OAuth 2.0 authentication

    The Technical Requirements You Cannot Ignore Before Submitting

    This is where many first-time sellers lose weeks. The AWS Marketplace technical requirements for AI agent listings are specific, non-negotiable, and not fully surfaced until you’re deep in the submission flow. The following is a consolidated view of what must be true before you click submit — particularly if you’re targeting the container track or AgentCore integration.

    MCP Server Requirements

    If you’re listing an MCP server for the AI Agents & Tools category — a tool that exposes capabilities to MCP-compatible orchestrators — your container must meet these exact runtime specifications:

    • Host binding: The server must listen on 0.0.0.0 (not localhost or a specific IP).
    • Port: MCP servers must expose port 8000.
    • Path: The MCP endpoint must be accessible at /mcp.
    • Protocol: Stateless streamable HTTP. AWS added support for stateful MCP in a March 2026 update, but stateless remains the default expectation unless you explicitly document stateful requirements.
    • Methods: Must implement both tools/list and tools/call at minimum.
    • Architecture: ARM64 container images are strongly preferred and required for native AgentCore Runtime deployment.

    A2A Server Requirements

    Agent-to-Agent servers follow a related but distinct set of requirements, designed for peer-to-peer agent communication in multi-agent pipelines:

    • Host binding: Again, 0.0.0.0.
    • Port: A2A servers run on port 9000 — distinct from port 8000 (MCP) and port 8080 (plain HTTP).
    • Path: Root path /.
    • Protocol: JSON-RPC 2.0 over HTTP.
    • Health checks: Must support GET /ping endpoint returning a valid health response.
    • Agent Card: An agent card JSON document must be published at /.well-known/agent-card.json. This is how other agents discover your agent’s capabilities in a multi-agent environment.
    • Authentication: Must support either SigV4 or OAuth 2.0 for inbound authentication. AgentCore injects a session header (X-Amzn-Bedrock-AgentCore-Runtime-Session-Id) which your agent must handle correctly.

    Session and State Management

    One subtlety that catches builders off guard: AgentCore passes A2A requests as a transparent proxy. It does not modify the JSON-RPC payload. This means your agent is responsible for parsing the session ID from the injected header and managing any stateful context itself — AgentCore won’t do it for you. Builders expecting the runtime to handle session continuity across multi-turn conversations will need to architect explicit session stores, typically using DynamoDB or ElastiCache, before the listing will function correctly in real-world usage.

    Documentation Requirements

    Technical functionality alone isn’t enough. AWS reviewers also assess your listing documentation. At minimum, your listing must include:

    • A clear description of the specific autonomous task your agent performs — generic descriptions citing “AI capabilities” without specifying the job to be done are a common rejection trigger.
    • Usage documentation explaining how buyers integrate and invoke the agent.
    • A description of what data the agent accesses, stores, and transmits, with explicit statements about buyer data handling.
    • Relevant security certifications or posture documentation (SOC 2 Type II is the benchmark most enterprise buyers expect).
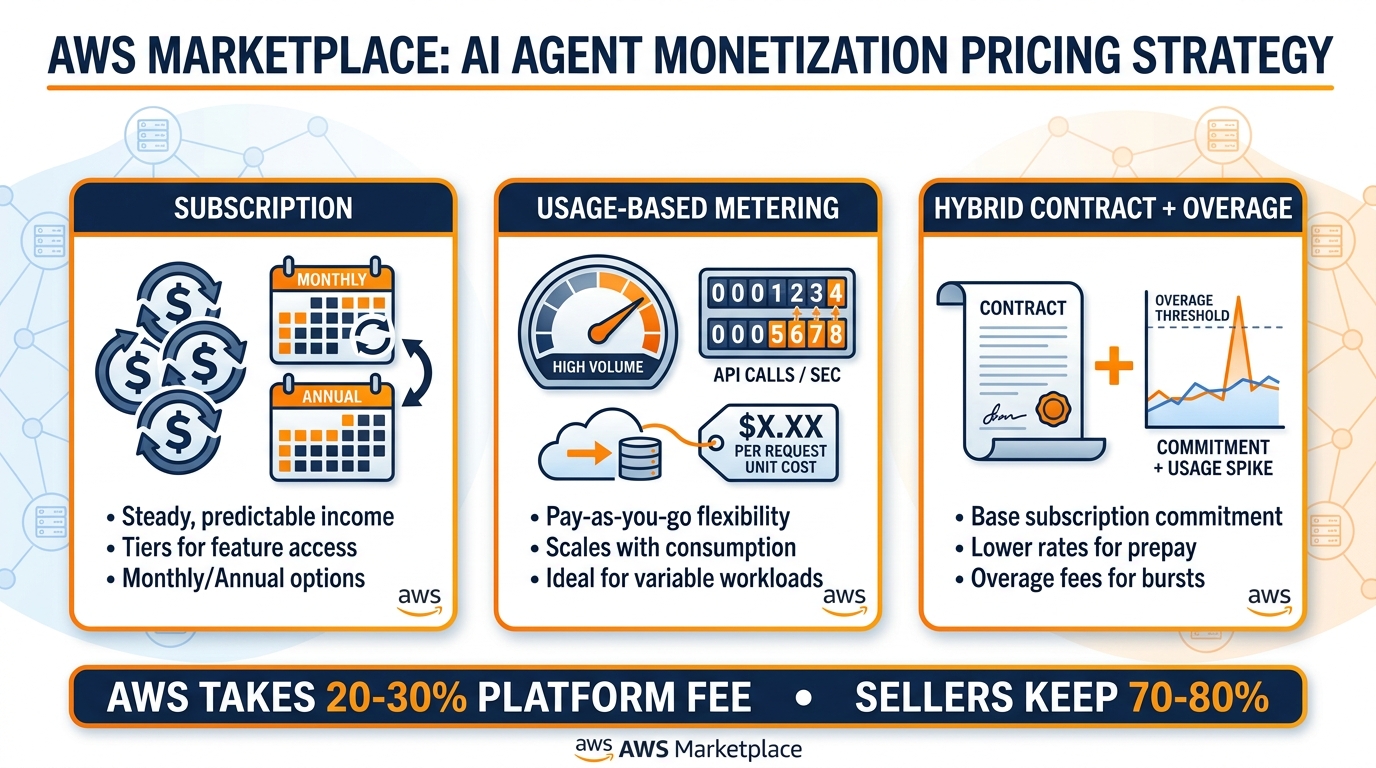
    AWS Marketplace AI agent pricing models: Subscription, Usage-Based Metering, and Hybrid Contract plus Overage with 70-80% seller revenue share

    Pricing Your Agent for Revenue, Not Vanity Metrics

    Pricing is where the most money gets left on the table in AI agent listings. Many sellers default to a flat monthly subscription because it feels safe and familiar. But AWS Marketplace’s metering infrastructure is genuinely sophisticated, and using it strategically — rather than ignoring it in favor of simplicity — is often the difference between a listing that generates mid-five-figures per month and one that plateaus at a few thousand dollars.

    The Three Core Pricing Models

    Contract-based pricing gives buyers an upfront entitlement — a defined quantity of agent use over a defined term. This might be a set number of conversations, documents processed, API calls, or agent-hours. Contracts are attractive for enterprise procurement because they fit into budget cycles. They’re predictable. The downside for sellers: if you underestimate usage, you’re leaving money on the table. If you overestimate, buyers feel overcharged and don’t renew.

    Usage-based metering charges buyers per unit of actual consumption. AWS’s metering infrastructure supports granular dimensions: per-request, per-inference call, per page processed, per generic compute unit. The advantage is alignment — buyers only pay for what they use, which reduces friction at the initial sale. The risk is unpredictability from the buyer’s budgeting perspective, which can slow enterprise procurement.

    Hybrid pricing — a base contract plus metered overages — has emerged as the dominant model for serious AI agent sellers in 2026. Buyers get the budget predictability of a contract for baseline consumption; they pay usage rates for anything above the committed tier. This model simultaneously reduces procurement friction, captures upside when agents deliver more value than expected, and creates natural expansion revenue as buyers scale usage.

    The Platform Fee Math

    AWS Marketplace charges sellers a platform fee that typically runs 20–30% of booked revenue, leaving sellers with 70–80%. For many sellers, this is a reasonable tradeoff given that the platform delivers qualified, AWS-credentialed buyers with existing billing relationships — but it must be factored into your unit economics from day one. An agent priced at $10,000 per month on Marketplace delivers $7,000–$8,000 to the seller after fees, not $10,000.

    Pricing Dimensions That Map to Agent Value

    One of the most common pricing mistakes is choosing dimensions that measure your costs (inference calls, compute time) rather than dimensions that map to buyer value (documents processed, decisions made, hours of human work replaced). A legal contract review agent, for example, creates value per contract reviewed — not per LLM inference call. Pricing per document reviewed aligns your revenue to the value the buyer perceives, which makes renewals and expansions far easier to justify.

    AWS’s metering system supports custom dimensions, which means you’re not locked into generic units. Define your dimension based on what the buyer cares about, then build the metering instrumentation in your agent to track and report that dimension to the Marketplace Metering Service. This requires integration work, but it’s among the highest-ROI technical decisions you’ll make before launch.

    Private Offers for Non-Standard Deals

    For enterprise deals with custom pricing, volume discounts, or negotiated terms, Private Offers are the mechanism. A Private Offer is a customized listing that you extend to a specific buyer, with pricing, terms, and entitlements tailored to that deal. AWS’s Express Private Offers automation has shortened the time to create and deliver a Private Offer significantly — sellers can now generate and send customized offers without the manual back-and-forth that characterized earlier versions of the system.

    Do not underestimate the enterprise procurement value of Private Offers. Large organizations that cannot approve a new vendor spend through a self-service click often can process a Private Offer through their existing AWS Enterprise Agreement. This is a significant procurement shortcut that removes one of the most common reasons large enterprise deals stall.

    The Approval Process: What AWS Actually Reviews

    The listing approval process for AI Agents & Tools has two distinct phases, and understanding the difference between them changes how you prepare your submission.

    Phase One: Automated Listing Validation

    The first phase is automated. AWS Partner Central runs checks against your listing metadata — title, description, category tags, pricing configuration, and product type selection. Common automated rejection triggers include:

    • Product descriptions that don’t demonstrate “autonomous” capability (the system looks for evidence the agent operates without constant human input).
    • Pricing configurations where the metered dimensions are not properly mapped to supported unit types.
    • Missing or incomplete documentation fields that are marked required for the AI Agents category.
    • Incorrect product type selection (for example, listing an A2A server under the SaaS track when it requires the container track).

    As of June 2026, AWS has added AI-assisted listing creation within Partner Central. The Partner Assistant can generate and validate listing content from existing product assets — documentation, GitHub READMEs, architecture diagrams. This materially reduces the time required to produce a compliant first draft, but it does not guarantee approval. Human review still follows.

    Phase Two: Human Review

    The human review phase covers security posture, compliance documentation, and functional verification of agent capabilities. AWS reviewers are looking for three things that no automated system can fully assess:

    First, whether the agent actually does what the listing claims. Functional verification means AWS will test the agent against its stated capabilities. Listings that over-claim autonomous behavior for what is effectively a glorified chatbot with a prompt wrapper get flagged here.

    Second, whether the data handling practices described in the listing accurately reflect what the agent actually does with buyer data. This is where many agents with poor security architecture fail — not because they’re insecure per se, but because the listing documentation doesn’t match the actual data flows.

    Third, whether the seller account and product setup meet the security requirements for the seller tier. This includes IAM role configuration, key management practices, and authentication implementation for the listed endpoints.

    The Most Frequent Rejection Reasons

    Based on ISV practitioner reports, the most common grounds for rejection are:

    1. Generic capability descriptions — Failing to specify precisely what autonomous task the agent performs.
    2. Security documentation gaps — Missing or vague statements about buyer data handling.
    3. Pricing model mismatch — The chosen pricing model doesn’t technically match the agent’s delivery architecture.
    4. Using personal or root AWS accounts rather than properly configured business seller accounts with IAM roles.
    5. Container images that don’t meet the AgentCore port/protocol specifications — A technical detail that seems minor but is a hard blocker.

    Build a pre-submission checklist against these five items and you’ll eliminate the most common first-pass rejections. The review cycle takes time; getting it right on the first submission is materially faster than iterating through rejections.
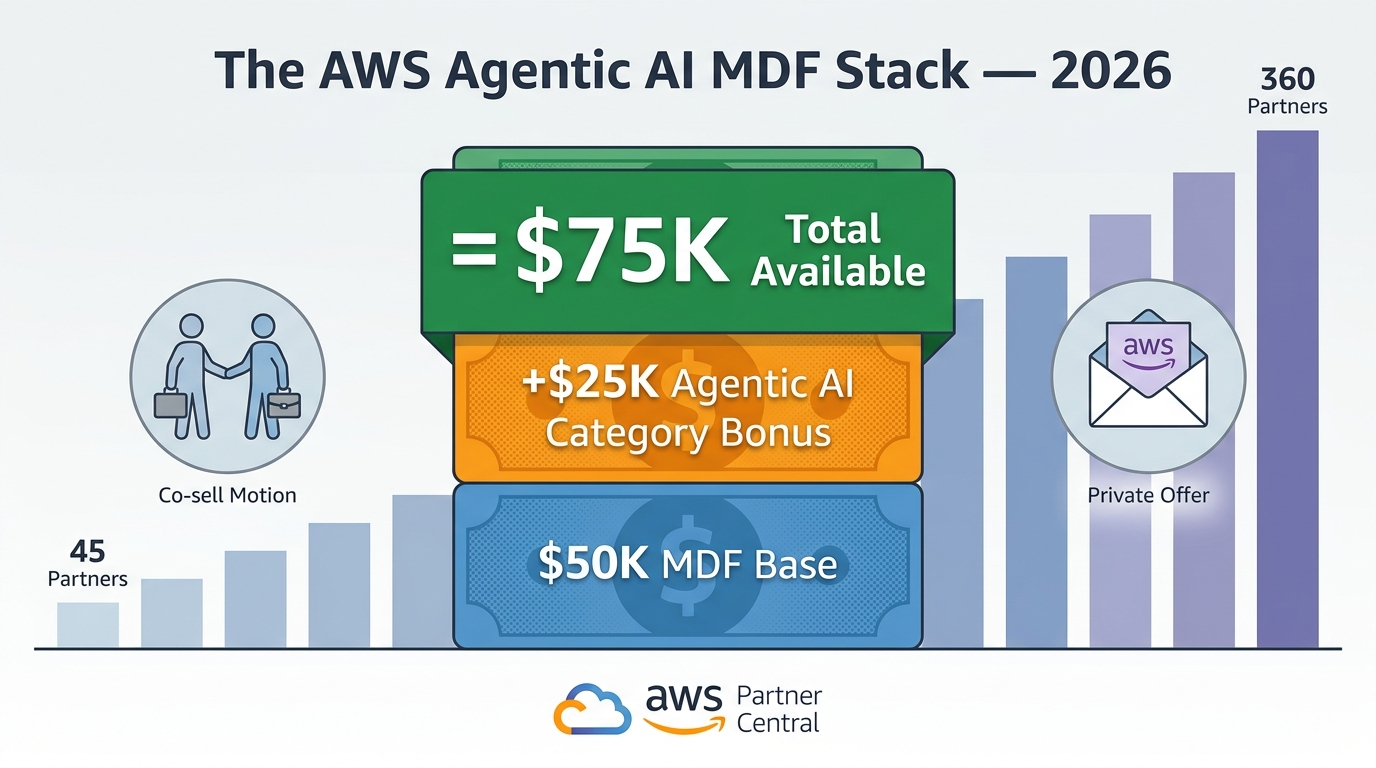
    AWS Agentic AI MDF Stack 2026: $50K base plus $25K Agentic AI category bonus equals $75K total available, with partner growth from 45 to 360 partners

    Co-Sell, Private Offers, and the MDF Incentive Stack

    Here’s the part that separates sellers who generate serious Marketplace revenue from those who collect listing badges. The AWS co-sell program and the MDF (Market Development Fund) incentive structure represent real money for sellers who engage with them — but the vast majority of new listers never activate them properly.

    The Agentic AI Partner Growth Story

    AWS’s AI Competency (launched as the Generative AI Competency in March 2024) has grown from 45 to 360 partners, supported by more than $115 million in AWS partner investment. In 2026, AWS formalized three new specialization categories within the AI Competency specifically for agentic AI:

    • Agentic AI Applications — End-to-end agent products serving specific business functions.
    • Agentic AI Tools — Components, infrastructure, and enabling technology for agent development.
    • Agentic AI Consulting Services — Professional services for agent deployment and customization.

    Partners who achieve validation in one of these agentic categories can access an additional $25,000 in MDF on top of the existing $50,000 base MDF pool — a total potential of $75,000 in co-marketing funds. This is not automatically distributed; it requires a formal MDF application and approved marketing activity plan. But for sellers willing to engage with the program, it represents a significant subsidy for demand generation activities that would otherwise come entirely out of the seller’s own marketing budget.

    The Co-Sell Motion

    Co-sell means partnering with AWS’s internal sales team to jointly pursue enterprise deals. The mechanism works through AWS Partner Central, where you register opportunities and request AWS seller involvement. When a qualified AWS account executive engages with your co-sell opportunity, they can introduce you to enterprise buyers through channels you cannot access independently — particularly buyers who have Enterprise Discount Program agreements with AWS and prefer transacting through Marketplace to maximize their committed spend.

    AWS has deployed AI agents within Partner Central itself to accelerate co-sell motions as of 2026. Automated opportunity scoring, recommended engagement plays, and AI-assisted proposal generation are now part of the Partner Central workflow. Sellers who engage with these tools — rather than treating Partner Central as a reporting burden — get meaningfully faster deal velocity.

    How Express Private Offers Change the Enterprise Sales Motion

    Enterprise deals that don’t fit standard Marketplace pricing tiers used to require long manual negotiation cycles. Express Private Offers automation changes this. Sellers can now configure pricing templates and eligibility rules in advance, then generate customized Private Offers rapidly when a specific deal requires negotiated terms.

    The practical impact: enterprise procurement cycles that previously took months because they required custom contract negotiations can now close in days, once the buyer has agreed on commercial terms. The Private Offer handles the procurement mechanics — billing integration, entitlement setup, contract terms — inside the buyer’s existing AWS billing relationship. Partners who have used this feature report meaningfully shorter time-to-close on large deals, with some citing five-figure transactions completing within a week of commercial agreement.

    Using Your MDF for Demand Generation That Actually Works

    MDF funds are not restricted to AWS-branded activities. Approved uses typically include field events, digital advertising targeting AWS customer segments, content production (webinars, technical white papers), and partner-led solution workshops. The most effective MDF deployment pattern for AI agent sellers in 2026 is investing in technical workshops where prospective buyers can integrate with a live version of your agent against their own data in a sandbox environment. This converts at significantly higher rates than traditional awareness marketing because it surfaces the agent’s value against the buyer’s actual use case.

    Common GTM Mistakes That Stall Revenue in the First 90 Days

    Even technically strong agents with well-structured listings can sit dormant for months if the go-to-market motion is poorly executed. These are the patterns that consistently stall revenue for first-time AWS Marketplace AI sellers.

    Mistake One: Treating the Listing as the Product

    The listing is a shop window, not a product. Enterprise buyers who discover your agent through Marketplace search rarely purchase without additional validation. They want documentation, case references, a free trial experience, or a technical call with someone who can answer integration questions. Sellers who optimize their listing copy but neglect to build the support infrastructure around it — trial environments, technical documentation, integration guides — consistently see high listing view rates with low conversion to paid subscriptions.

    Mistake Two: Wrong Pricing Model for the Delivery Architecture

    Choosing a subscription model for an agent that fundamentally delivers value per-task creates misalignment that buyers notice. A document intelligence agent priced at a flat $2,000/month doesn’t feel like good value to a buyer who processes 50 documents. The same capability priced at $40/document or $800 for a 20-document contract tier with overage rates suddenly makes the value transparent and the expansion path natural. Match the pricing dimension to what the buyer experiences as value, not to what’s administratively convenient for you to track.

    Mistake Three: Neglecting the Free Trial

    AWS Marketplace supports free trials natively. AI agent listings without a trial option face significantly higher purchase friction — particularly for mid-market buyers who can’t justify an enterprise procurement process for a product they’ve never run against their own data. A time-boxed or usage-capped trial that lets buyers experience the agent against their actual documents, queries, or workflows is among the highest-conversion assets you can build. Building it into your submission is a strategic decision, not an optional nicety.

    Mistake Four: Ignoring Keyword Discoverability

    AWS Marketplace’s search works on listing metadata — title, description, category tags, and use case labels. Sellers who write listing descriptions for human readers without considering how enterprise buyers actually search for agents miss early organic discovery. Concrete use case language (“automates Tier-1 customer support ticket routing,” “extracts structured data from unstructured legal documents”) consistently outperforms abstract capability language (“leverages large language model reasoning to…”) in both search ranking and conversion.

    Mistake Five: Not Registering Co-Sell Opportunities Early

    The co-sell motion requires registering opportunities in Partner Central. Sellers who wait until a deal is far advanced — or who don’t register at all — miss the AWS co-sell multiplier effect. AWS account executives cannot help you with deals they don’t know about. Register early, even for deals in early pipeline stages, and you create the opportunity for AWS to surface the relationship from their side.

    Mistake Six: Underestimating Operational Readiness

    An agent that gets approved and starts attracting buyers will generate support requests, integration questions, and usage edge cases that your development team isn’t ready for. Sellers who go live without documented integration guides, a support SLA, and at least basic monitoring on their agent’s availability and response quality often see early subscribers churn before the first renewal. Enterprise buyers who pay for an agent that breaks without clear support channels are not forgiving in their Marketplace reviews.
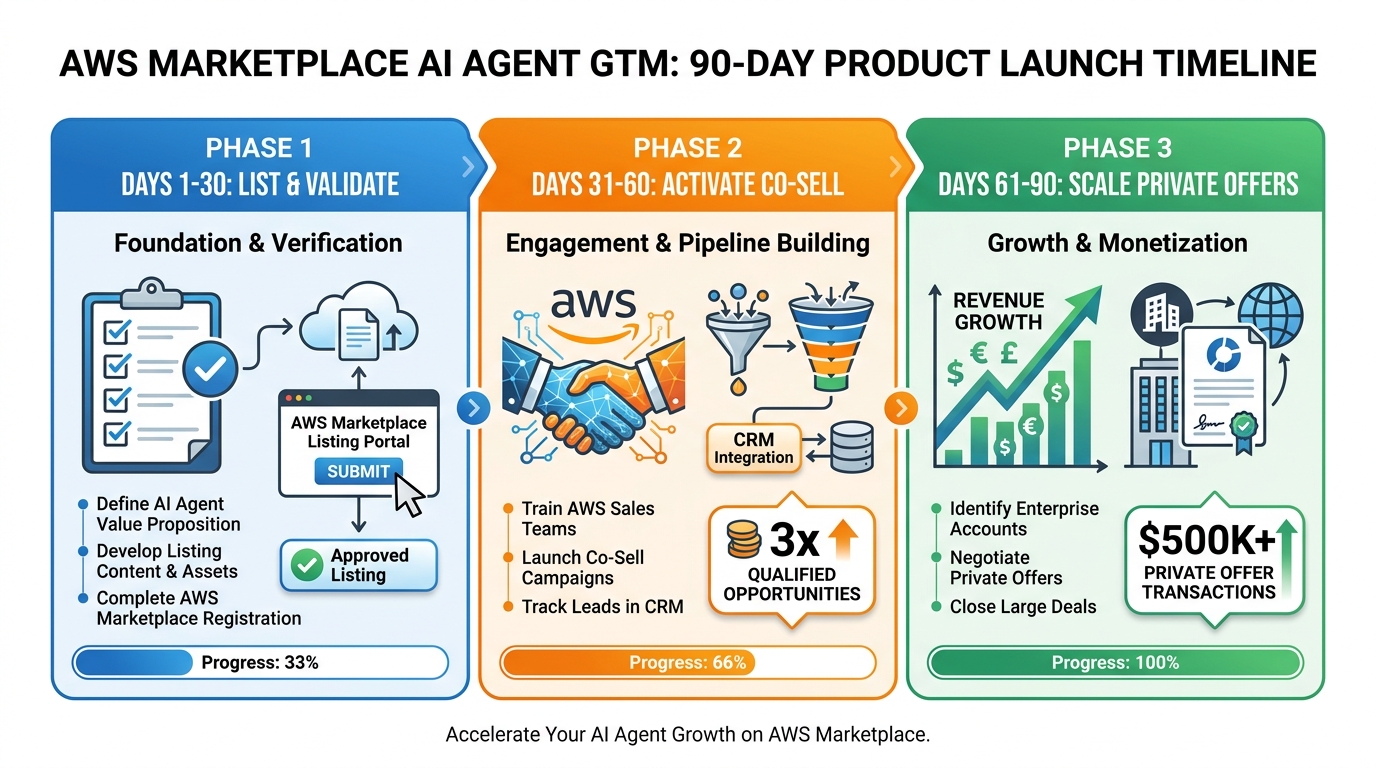
    90-day AWS Marketplace revenue ramp timeline: Days 1-30 list and validate, Days 31-60 activate co-sell, Days 61-90 scale private offers, with 3x qualified opportunities and $500K+ private offer transactions

    The 90-Day Revenue Ramp Framework

    Based on patterns from ISVs who have launched successfully in the AI Agents & Tools category, a realistic 90-day framework looks like this. Note that “revenue” in this context means the framework for creating revenue conditions — not a guarantee that any specific revenue amount materializes, which depends heavily on agent quality, market fit, and seller execution.

    Days 1–30: Technical Readiness and Listing Submission

    The first month is almost entirely technical and administrative. Priority activities:

    • Finalize your listing track decision (SaaS vs. container) and build accordingly.
    • Complete technical requirements: port/protocol specs, agent card, authentication, health check endpoints.
    • Set up your seller account correctly: business entity, IAM roles, billing registration. Do not use a personal or root account.
    • Write and validate listing documentation against the rejection checklist above.
    • Build a free trial environment, even a limited one.
    • Submit for review and be available to respond quickly to reviewer questions — slow response to reviewer queries is a common reason approvals take four to six weeks instead of two to three.

    The goal at the end of Day 30 is a submitted listing with no outstanding technical blockers, not necessarily an approved listing. Approval timing varies and is outside your control; your documentation quality is inside your control.

    Days 31–60: Activation and Early Co-Sell

    Once approved — or while awaiting approval — begin activating the co-sell motion. This phase is about pipeline creation, not revenue collection:

    • Apply for AWS AI Competency validation if you haven’t already. The Agentic AI category validation is the unlock for the $25K incremental MDF.
    • Register your first five pipeline opportunities in Partner Central, even if they’re early-stage.
    • Configure Express Private Offer templates for your most common enterprise deal structures.
    • Run at least one live technical workshop with a prospective enterprise buyer using your trial environment.
    • Submit your MDF application with a concrete demand generation plan.

    Partners who execute this phase thoroughly consistently report three-fold increases in qualified sales opportunities relative to those who list and wait. The pipeline you build in Days 31–60 is what generates revenue in Days 61–90 and beyond.

    Days 61–90: Private Offer Execution and Optimization

    With pipeline established and co-sell motions active, Days 61–90 focus on converting opportunities to transactions:

    • Move qualified co-sell opportunities toward Private Offers for enterprise buyers.
    • Use Express Private Offers to shorten time-to-close on deals where commercial terms are agreed.
    • Analyze trial conversion rates and identify friction points in the free trial experience.
    • Collect and publish the first Marketplace customer review — social proof affects conversion rates for subsequent buyers.
    • Refine your listing keywords and description based on actual search query data from the Marketplace seller dashboard.

    ISV partners who execute all three phases report transaction volumes ranging from a handful of small subscriptions to individual Private Offer transactions exceeding $500,000 in the first 90 days. The range is wide because it depends entirely on the agent’s market fit and the seller’s co-sell execution — not on anything intrinsic to the platform itself.
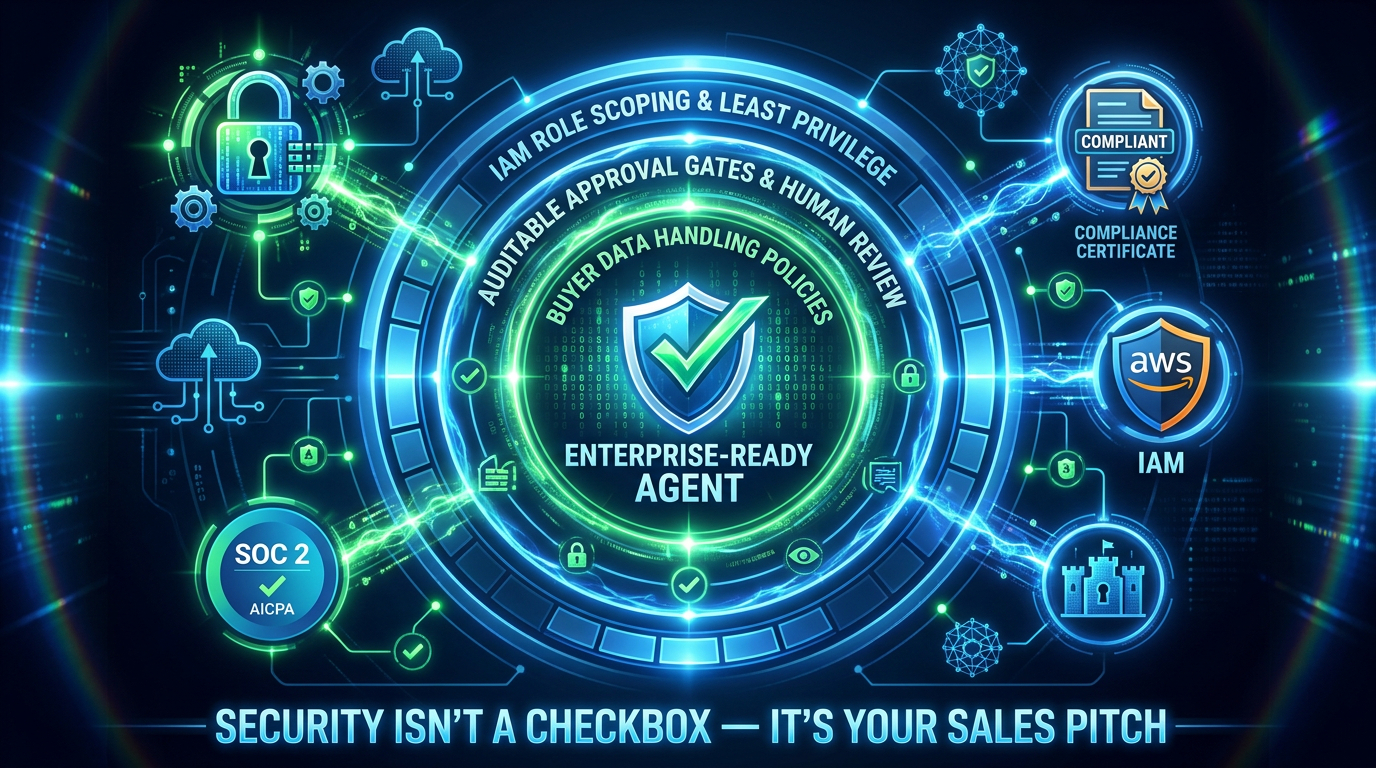
    Enterprise AI agent security architecture: IAM role scoping, auditable approval gates, buyer data handling policies, with security as competitive advantage

    Security and Compliance as a Competitive Sales Advantage

    Most sellers treat security requirements as compliance overhead — a checklist to clear before they can get to the real work of selling. This framing is costly. In the enterprise market for AI agents, security posture is increasingly the primary purchase criterion, and sellers who lead with security evidence rather than burying it in a documentation tab close deals faster and at higher prices.

    What Enterprise Buyers Are Actually Worried About

    The enterprise security concerns around AI agents are distinct from those for traditional SaaS software. Standard software security means protecting data from unauthorized external access. Agents add a new dimension: the risk of the agent itself taking unauthorized actions on behalf of the buyer. An agent that has write access to a production database, for example, poses risks that a read-only analytics dashboard never did. Enterprise security teams are asking questions that didn’t exist two years ago:

    • What actions can the agent take that cannot be undone?
    • How is the agent’s access scope limited (IAM least-privilege, for example) to prevent it from accessing systems it doesn’t need?
    • Is there an audit trail of every action the agent takes, in a format that the buyer’s compliance team can review?
    • Can the buyer revoke the agent’s access without disrupting their production environment?

    Agents that have clear, documented answers to all four questions close faster. Agents that require enterprise security teams to ask these questions during due diligence — and wait for answers — lose deals to competitors who already have the answers ready.

    IAM Scoping: The Non-Negotiable

    Implementing least-privilege IAM roles for your agent’s AWS access is both a Marketplace requirement and a sales enabler. Your listing documentation should explicitly state what IAM permissions your agent requires, why each permission is necessary, and what permissions it explicitly does not require. Many enterprise security architects review this list before the agent ever gets to a demo — agents with unexplained or broad permission scopes often get screened out before the sales team is even engaged.

    Audit Logs as a Product Feature

    Building comprehensive, queryable audit logs into your agent — and making those logs accessible to the buyer through their existing AWS CloudTrail or CloudWatch infrastructure — transforms a security requirement into a product feature. Buyers who can see exactly what their agent did, when, and on what data are far more likely to expand agent usage into sensitive workflows. Buyers who can only see aggregated metrics are cautious about giving agents access to anything critical.

    Compliance Certifications and When They Matter

    SOC 2 Type II is the baseline certification most enterprise buyers require. It does not make your agent secure; it demonstrates that your security practices have been independently audited. For healthcare and life sciences buyers, HIPAA Business Associate Agreement capability is often a requirement. For financial services, SOC 2 plus relevant financial services compliance frameworks matter. Map your certification roadmap to your target buyer profile — not to a generic enterprise standard — to avoid spending compliance budget on certifications your actual buyers don’t require.

    Positioning Your Agent for Discovery in a Crowded Category

    The AI Agents & Tools category is growing fast. AWS’s agentic AI partner base has expanded from 45 to 360 validated partners. Self-service listings are growing faster still. As the category fills, discoverability becomes the scarcest resource. Sellers who think carefully about how their agent is categorized, described, and positioned before day one have a structural advantage that is very difficult to recover later.

    Category Tags and Use Case Labels

    AWS Marketplace allows sellers to select industry vertical and use case tags for their listings. Many sellers select broad tags (“IT & Developer Tools,” “Machine Learning”) because they feel safer. In practice, narrower, more specific tags surface your listing to buyers who are actively looking for exactly what you do — which is far more valuable than broad exposure to buyers who aren’t specifically looking for your capability.

    A document intelligence agent listed as “Legal Tech / Contract Review Automation” will show up for buyers actively searching in that category. The same agent listed as “Machine Learning Tools” competes with every ML tool in the Marketplace. Precision in categorization is a discoverability decision, not a limitation.

    The Role of Marketplace Reviews

    Customer reviews on AWS Marketplace carry significant weight for subsequent buyers, particularly in enterprise procurement contexts where peer validation matters. The first review is the hardest to get — it requires asking satisfied early customers to publish their experience, which many won’t do without a direct request. Build the review ask into your post-deployment customer success motion, ideally after the buyer has had a measurable success experience they can describe specifically. Generic positive reviews (“great product, easy to use”) add credibility but limited detail; specific reviews that describe the use case, the integration experience, and the measurable outcome are the ones that convert skeptical buyers.

    Agent Mode and Conversational Discovery

    AWS Marketplace is evolving toward conversational, agent-driven discovery — where buyers describe what they need in natural language and an AWS agent surfaces relevant listings. This changes the optimization logic for listing copy. Title and description need to match the natural language queries buyers will use when describing their problem to an agent, not just the keyword strings they’d type into a traditional search box. Writing your listing description as if explaining your agent to an intelligent but non-technical enterprise buyer — “this agent automatically reviews incoming vendor contracts for non-standard terms and flags them for legal review” rather than “LLM-powered contract analysis tool with NLP” — prepares you for both traditional search and conversational discovery.

    The Honest Assessment: What This Platform Can and Cannot Do for You

    AWS Marketplace’s AI Agents & Tools category is a genuinely valuable distribution channel for AI agents targeting enterprise buyers. The co-sell program, Private Offer mechanics, and procurement integration are real advantages that reduce the cost of enterprise sales. The MDF incentives are substantial. The buyer pool — enterprises with existing AWS relationships and committed spend — is among the highest-quality enterprise markets available.

    But the platform has real limitations that sellers need to account for. Discovery is not guaranteed by listing. Demand generation is your problem. The platform fee is a permanent line item in your unit economics. Approval is not fast, especially for first-time sellers navigating the requirements for the first time. And the technical requirements for container-based and AgentCore-integrated agents are demanding enough that many agents that work perfectly well as standalone products need significant rearchitecting to meet the AgentCore runtime contract.

    The sellers who thrive here are those who treat AWS Marketplace as one pillar of a broader go-to-market motion — not as a set-it-and-forget-it distribution magic trick. They use the Marketplace for procurement mechanics and buyer credibility, the co-sell program for pipeline development, Private Offers for deal execution, and their own demand generation for awareness. The platform amplifies that motion; it doesn’t replace it.

    The agents that generate the most revenue in the first 12 months share a common pattern: they do one thing very well, they price that one thing in a way that makes the value obvious, and their documentation is good enough that enterprise security teams don’t have to ask basic questions. None of that requires an exotic technical stack. It requires deliberate, systematic execution against requirements that are, to their credit, clearly documented.

    Pre-Launch Checklist: Before You Hit Submit

    Use this consolidated checklist before submitting your AI Agents & Tools listing. It incorporates the most common rejection triggers, the technical requirements for AgentCore-compatible agents, and the GTM setup that determines whether your listing generates revenue or collects dust.

    Technical Requirements

    • ☐ Container images built for ARM64 architecture (if container track)
    • ☐ MCP server listening on 0.0.0.0:8000/mcp with tools/list and tools/call implemented
    • ☐ A2A server listening on 0.0.0.0:9000/ with JSON-RPC 2.0 and GET /ping health check
    • ☐ Agent Card published at /.well-known/agent-card.json
    • ☐ SigV4 or OAuth 2.0 inbound authentication implemented
    • ☐ Session header (X-Amzn-Bedrock-AgentCore-Runtime-Session-Id) handled correctly
    • ☐ IAM roles configured with least-privilege access
    • ☐ Business seller account with proper IAM setup (not personal/root account)

    Listing and Pricing

    • ☐ Listing title names the specific task, not just a capability category
    • ☐ Description explains autonomous operation clearly
    • ☐ Pricing model matches the agent’s delivery architecture and buyer value perception
    • ☐ Metered dimensions map to buyer-observable value units (documents, decisions, tasks)
    • ☐ Free trial configured with sufficient scope for buyers to validate against real data
    • ☐ Data handling practices documented explicitly
    • ☐ Security certifications (SOC 2 Type II minimum) referenced in listing

    Go-to-Market Readiness

    • ☐ Integration guide published (not just API documentation)
    • ☐ Support SLA defined and resourced
    • ☐ Monitoring and alerting active on agent availability and quality
    • ☐ AWS AI Competency validation application initiated or completed
    • ☐ Partner Central account configured for co-sell opportunity registration
    • ☐ Express Private Offer templates configured for common enterprise deal structures
    • ☐ MDF application plan prepared

    Conclusion: The Platform Is Ready. Is Your Agent?

    AWS’s investment in the AI Agents & Tools category is not tentative. The $115 million committed to partner AI development, the formal Agentic AI specialization tracks, the AgentCore Runtime technical infrastructure, and the Express Private Offers automation all point to a platform that AWS is treating as a long-term enterprise distribution channel — not an experiment.

    For builders with genuinely capable agents, this creates a meaningful commercial opportunity. The procurement infrastructure is there. The enterprise buyer pool is there. The co-sell and MDF mechanisms are there. What’s not guaranteed is your share of it.

    The agents that will define this category over the next 12–24 months will not be the most technically complex. They will be the ones that did the unglamorous work — the precise documentation, the security architecture that reduces enterprise friction, the pricing design that makes value tangible, the co-sell engagement that creates qualified pipeline rather than waiting for organic discovery. That work is available to any seller willing to do it. It just requires treating the Marketplace as seriously as you treat the engineering.

    Ship something specific. Price it honestly. Document it thoroughly. Engage the co-sell motion early. The platform will handle the rest of the mechanics — but only if you give it something worth selling.
  • 2026 Image Policy Traps: How to Suppression-Proof Your Entire Amazon Portfolio

    2026 Image Policy Traps: How to Suppression-Proof Your Entire Amazon Portfolio

    Amazon image policy traps 2026 — suppressed listings with red warning stamps and compliance checkmarks across a product catalog

    For most of Amazon’s history, image policy violations were a nuisance. You got a warning, you fixed the image, you moved on. The penalty was a temporary inconvenience — annoying, but contained.

    That dynamic has fundamentally changed in 2026. Amazon’s image enforcement is now faster, more automated, and more sweeping than anything sellers have dealt with before. What used to be a listing-level problem has become a portfolio-level risk — one that can suppress multiple ASINs simultaneously, pause ad delivery across your entire account, erode months of organic rank, and trigger account health flags, all from a batch of images that were perfectly acceptable eighteen months ago.

    The sellers who are getting hurt most aren’t the ones deliberately cutting corners. They’re brands that uploaded compliant imagery, forgot about it, and never realised that retroactive enforcement sweeps can catch old assets that no longer meet tightened standards. They’re growing accounts that used AI image tools without understanding the specific disclosure and accuracy rules Amazon now applies. They’re multi-ASIN operators who treated image compliance as a launch-day checkbox rather than an ongoing operational function.

    This post is not a recap of Amazon’s published image requirements. Those are widely documented elsewhere. Instead, this is a systematic look at the mechanisms by which compliant-seeming portfolios get caught, the cascade of consequences that follows, and the operational systems that actually keep a catalog clean under 2026’s enforcement regime — not just at launch, but over the long run.

    Why Image Policy Has Become a Portfolio-Level Risk, Not a Listing-Level Problem

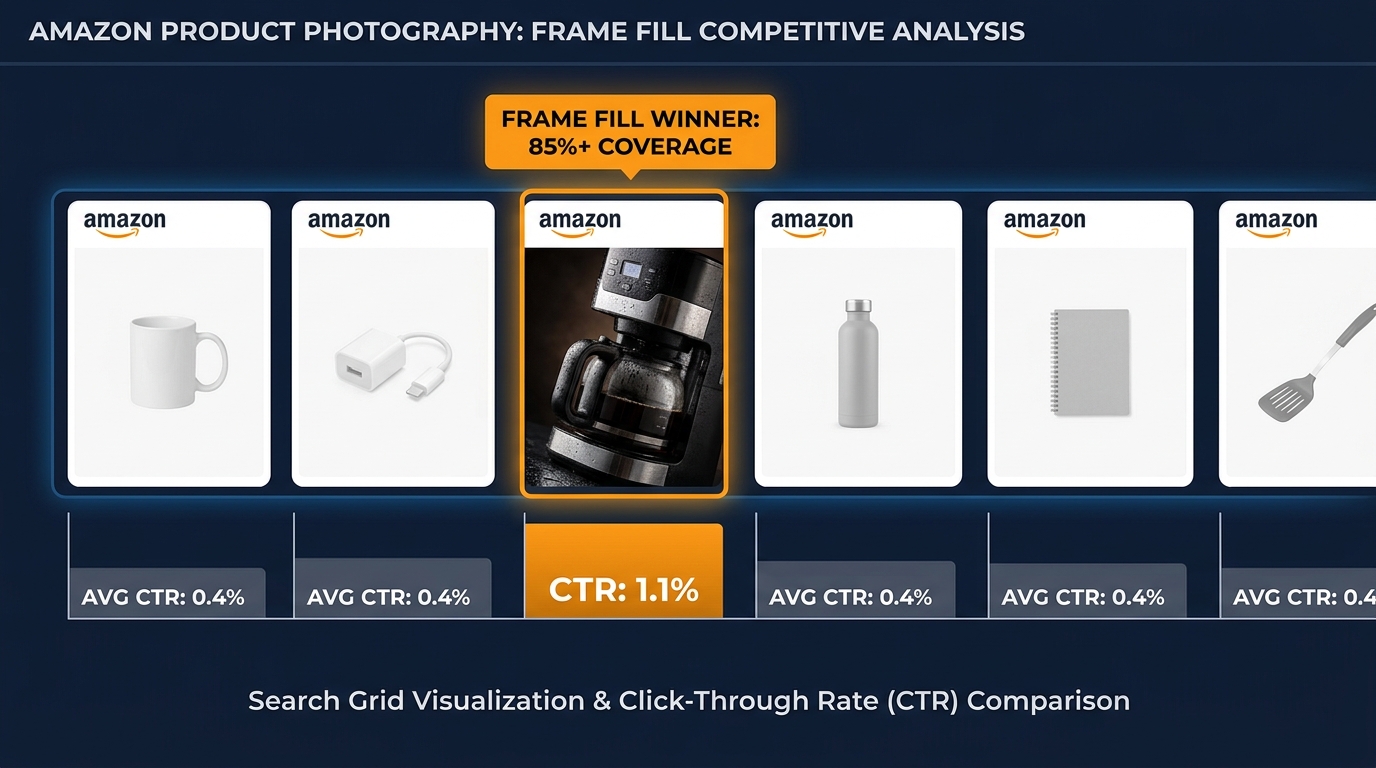
    The shift isn’t in the written policy. Amazon’s core image requirements — pure white main image background at RGB 255,255,255, product filling approximately 85% of the frame, no text or graphic overlays on the main image, no watermarks or logos, accurate representation of the actual item being sold — haven’t dramatically changed in structure. What has changed is how those rules are applied and at what scale.

    Automated Enforcement at Catalog Scale

    Amazon’s image validation systems now operate more like continuous audit loops than one-time upload gatekeepers. In earlier years, an image might pass at upload because the automated check was relatively permissive, only to be flagged later if a human reviewer happened to look at the listing. In 2026, enforcement sweeps are faster, more frequent, and algorithmically driven — meaning an image that passed six months ago can be re-evaluated against updated detection thresholds and suppressed without a new upload or any action on the seller’s part.

    This retroactive enforcement is the trap most sellers don’t see coming. Your catalog isn’t static in Amazon’s eyes, even when you haven’t touched it. Periodic automated re-audits of existing listings mean that compliance isn’t a one-time achievement — it’s a continuous requirement that must be actively maintained.

    From Warning to Suppression Without Gradual Escalation

    The older enforcement model gave sellers a reasonable grace period. A non-compliant image might generate a fix-it notification, remain live during the remediation window, and only disappear from search if the seller ignored the warning repeatedly. The 2026 model, as reported consistently across third-party seller communities and agency analyses, is considerably less forgiving. Listings are being suppressed from search results much more quickly after an image violation is detected — in some cases without a prior warning notification arriving before the suppression takes effect.

    For a single-ASIN account, that’s painful. For a multi-hundred ASIN catalog, a batch enforcement event can create simultaneous suppression across a significant portion of the inventory — with ad campaigns burning impressions on ASINs that are no longer visible in organic search, and sales velocity crashing before the account owner even knows there’s a problem.

    Account Health Is Now Downstream of Image Compliance

    The previously clean separation between “image compliance” and “account health” is blurring. Repeated or severe image violations — particularly those that involve misrepresentation of the actual product — are increasingly feeding into account health scoring mechanisms. A high enough volume of suppressed listings, or violations that Amazon interprets as intentional misrepresentation rather than innocent non-compliance, can generate account-level flags that affect selling privileges well beyond the impacted ASINs.

    This is the portfolio-level risk that demands a portfolio-level response. Treating each ASIN’s image as its own isolated compliance problem is no longer an adequate operating model.

    The Six Hidden Suppression Triggers Amazon’s AI Catches That Sellers Don’t Expect

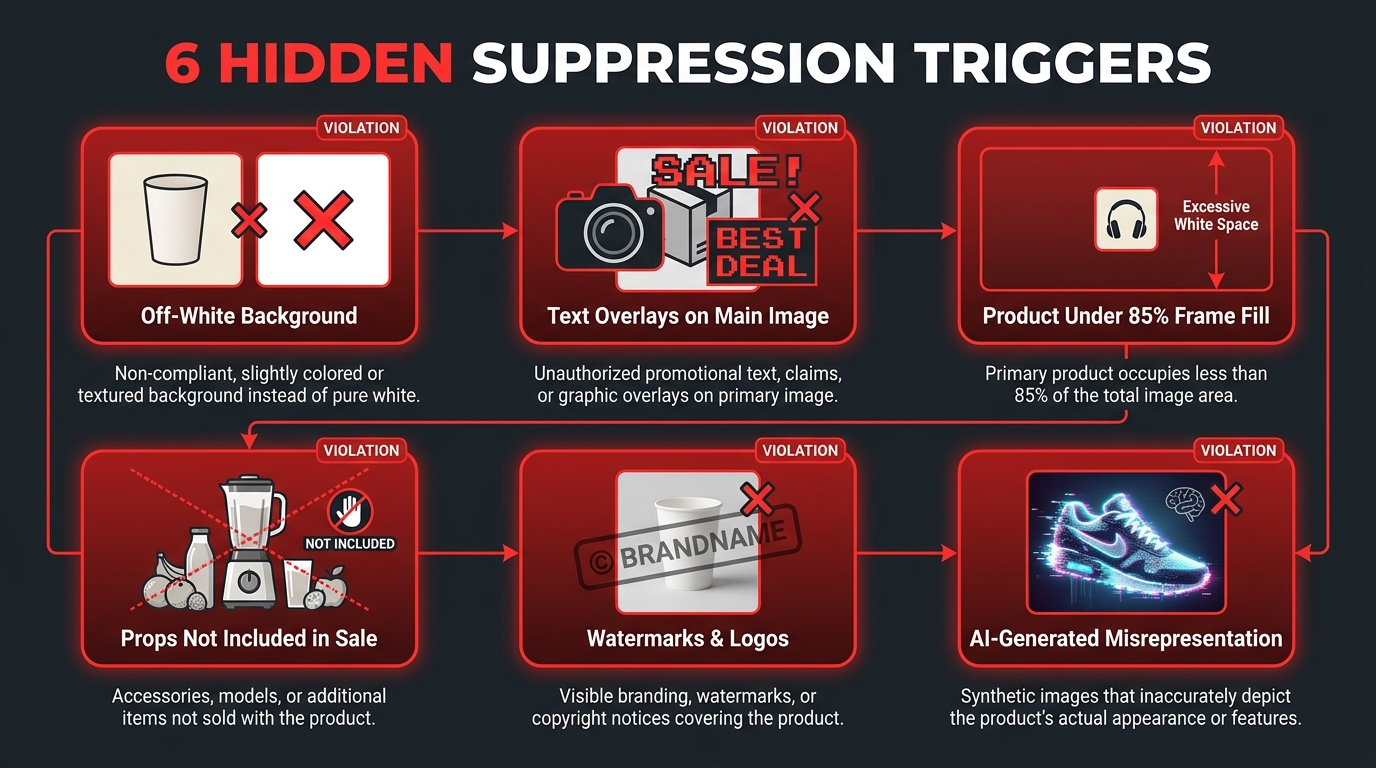
    Six hidden Amazon image suppression triggers in 2026 — infographic showing off-white background, text overlays, frame fill, props, watermarks, and AI misrepresentation violations

    Every seller knows the headline rules. What gets brands into trouble in 2026 isn’t ignorance of the obvious requirements — it’s the subtle violations that look compliant to the human eye but trip the automated detection systems Amazon has built.

    1. Off-White That Doesn’t Look Off-White

    The requirement is RGB 255,255,255. Not 254,254,254. Not 250,250,250. Not a creamy, soft white that looks perfectly clean on your monitor under warm studio lighting. Amazon’s automated detection can distinguish between true white and near-white backgrounds, and the threshold is being applied with increasing precision in 2026. Backgrounds that were accepted without issue at upload are being flagged during re-audit sweeps because the detection sensitivity has been raised.

    The practical source of this problem is often the photography workflow itself. Lightbox setups that use slightly warm-toned LED lighting, paper backdrop materials that have a natural texture or slight color cast, and editing workflows that stop at “looks white” rather than verifying the exact RGB values in post-production can all produce backgrounds that fail the threshold even though they appear compliant to the photographer’s eye.

    2. Shadows and Reflections as Background Violations

    A drop shadow beneath a product, a surface reflection on a glossy table, or a soft gradient created by the product’s own shape against the background — all of these introduce non-white pixels into the main image, and all of them are treated as background violations by Amazon’s image analysis. This is a widely reported trap that catches brands whose product photography is otherwise high quality. A beautiful, professionally lit image with a subtle shadow is still a suppression risk.

    3. Props and Context Objects “Not Included in Sale”

    Amazon’s policy is clear that the main image should show only the item being purchased. Lifestyle elements, complementary products, styling accessories, and contextual props that suggest scale or usage but aren’t included in the box are policy violations for the main image. The trap here is that many sellers use a “hero lifestyle” image as their main image — a decision that was sometimes tolerated historically but that 2026’s enforcement systems are now much more aggressive in flagging.

    Multi-piece sets and bundle products require particular care: the main image must accurately reflect exactly what’s in the box, and the grouping shown must exactly match the purchase. An image that shows a set of four items when the listing is for a set of three — even if it’s a photographic shorthand the seller never intended to be misleading — is a violation.

    4. Faint Watermarks and Edge Logos That Survived Cropping

    Brands that have used third-party image services, stock photography with embedded licensing marks, or photography vendors who added subtle branded watermarks as part of their standard delivery package can find that images contain low-opacity marks that are invisible to casual review but detectable by Amazon’s systems. Similarly, image files that were cropped from larger compositions may contain partial logos or graphic elements near the frame edge that weren’t visible in the pre-upload preview.

    5. Resolution Failures After Platform Compression

    Amazon recommends a minimum of 1,000 pixels on the longest side, with 2,000 pixels or more preferred to enable the zoom function. The trap occurs when sellers upload images that technically meet this threshold but whose effective resolution is degraded by compression artifacts, JPEG quality settings, or platform-side resizing. An image that uploaded at 1,050 pixels may display at a quality level that fails the zoom-enabled clarity standard — and Amazon’s systems can flag this during image quality audits.

    6. Inset Images, Callout Boxes, and Bundled Secondary Visuals in the Main Slot

    A surprisingly common violation involves main images that are actually composites — a primary product shot combined with a smaller inset image showing a detail, a bundled accessory, or a “what’s in the box” visual. From a seller’s perspective, this feels like useful communication. Amazon’s policy treats it as a graphics overlay violation, regardless of whether the inset contains any text. The automated detection for composite images — where the main frame contains a visually distinct embedded sub-image — has become sharper in 2026.

    The Cascade Effect — How One Suppressed ASIN Can Destabilize Your Entire Catalog

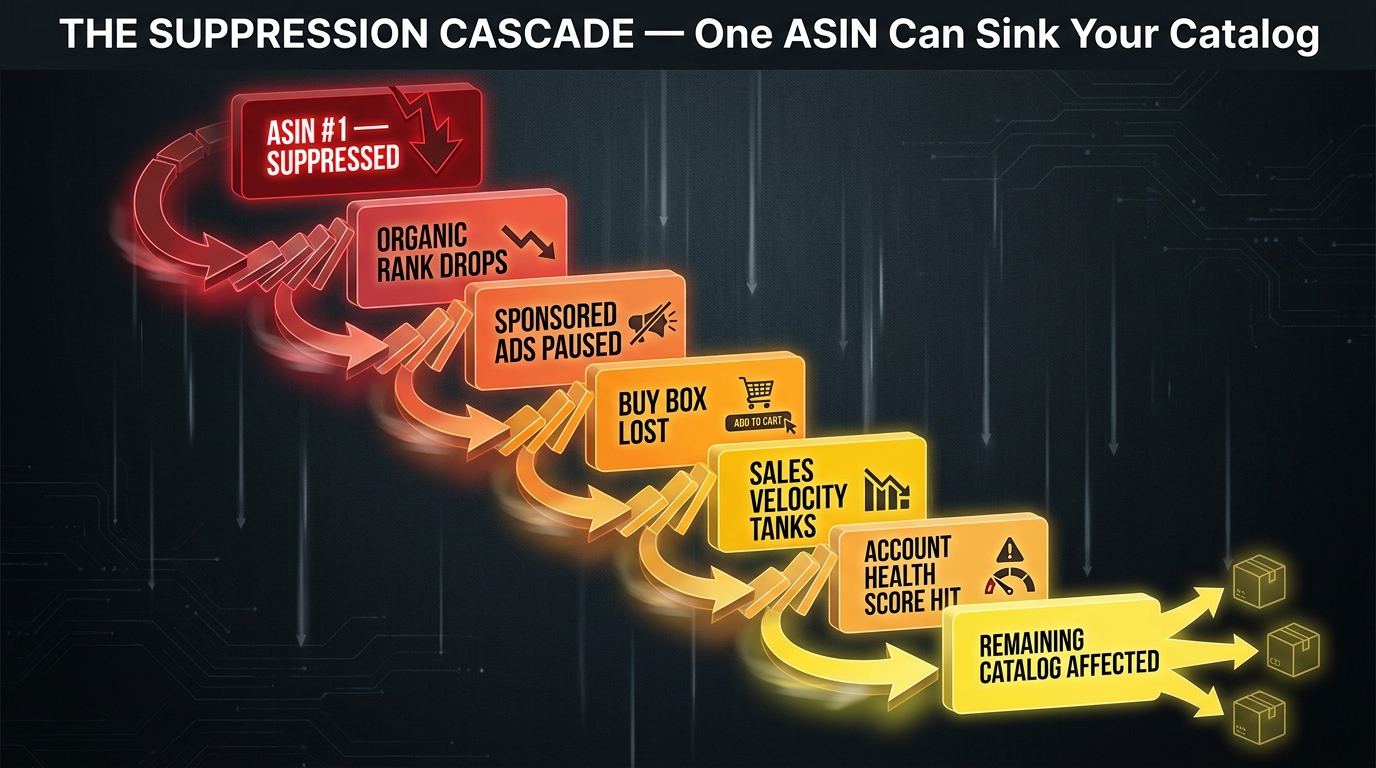
    Amazon suppression cascade diagram showing how one suppressed ASIN triggers organic rank drops, ad pauses, Buy Box loss, and account health deterioration

    Understanding suppression as a cascade rather than an isolated event is the conceptual shift that separates reactive sellers from genuinely protected portfolios. The cascade mechanics are worth understanding in detail because they explain why recovery is so much slower than the initial suppression.

    The Organic Rank Problem

    Amazon’s A10 algorithm uses sales velocity — among other signals — as a core input to organic ranking. A suppressed listing generates zero sales velocity, because it’s no longer appearing in search results for buyers to find and purchase. Depending on how long the suppression lasts before correction, the organic rank for that ASIN will decay. When the listing is restored after a compliant image is submitted, the organic rank doesn’t automatically reset to its previous level. It starts rebuilding from wherever it fell to — which means suppression recovery often involves not just fixing the image but re-earning rank that took months to establish.

    Ad Campaign Disruption

    Sponsored Products campaigns tied to a suppressed ASIN stop delivering impressions. This is straightforward and expected. What sellers often miss is the campaign learning disruption this causes. Advertising algorithms build performance models based on cumulative impression, click, and conversion data. A suppression-caused pause in delivery resets or degrades that accumulated learning, meaning the campaigns that restart after the listing is restored may underperform for days or weeks while the algorithm re-establishes its baseline.

    For accounts running Sponsored Brands or Sponsored Display campaigns that include the suppressed ASIN as part of a broader creative, the ripple extends further — those campaign types may see delivery disruptions or performance anomalies even for the ASINs that weren’t directly suppressed.

    Variation Parent and Child ASIN Interdependencies

    Many Amazon listings operate within variation families — a parent ASIN connected to multiple child ASINs representing different colors, sizes, or configurations. The suppression of a parent ASIN or a high-velocity child ASIN creates visibility and data problems for the entire variation family. Review aggregation, search ranking signals, and Buy Box mechanics at the variation level are all affected when a key node in the family goes dark.

    The reverse also applies: if a variation child is suppressed and its image issue is on the variation-specific image (the photo that shows the specific variant being sold), the brand may not notice as quickly because the parent listing appears to still be live. Meanwhile, customers clicking through to the suppressed variant see an incomplete listing experience, conversion suffers, and the data bleed affects the whole family’s performance signals.

    Inventory and Fulfillment Knock-Ons

    For FBA sellers, a suppressed listing that continues to hold inventory at Amazon fulfillment centers is still incurring storage fees while generating zero revenue. Extended suppression periods create a particularly damaging financial pressure: costs accumulate while the income that was supposed to offset them has stopped. For sellers operating near long-term storage fee thresholds, a suppression event can push inventory into penalty territory faster than expected.

    Category-Specific Traps That Generic Guides Never Cover

    Amazon’s image policy contains category-specific rules that layer on top of the universal requirements. These category rules are the compliance details that generic seller education typically glosses over — and that enforcement systems apply with precision.

    Apparel and Footwear: The Model and Mannequin Rules

    Amazon’s policy for most apparel categories requires that the main image show the garment on a human model or a “clean” invisible mannequin — not flat-lay photography, not folded product shots, and not display on a standard visible clothing form. This creates a compliance trap for brands that use flat-lay as their main image for aesthetic or cost reasons. The enforcement threshold for apparel main images has tightened considerably, and flat-lay images that appeared on detail pages for extended periods without issue have been swept in recent re-audit cycles.

    For footwear, the angle and orientation requirements add further specificity: shoes should generally be shown in a specific angled view that displays the upper, sole profile, and overall silhouette. Main images showing only the sole, only a side view, or only the toe box don’t meet the standard, even if the background and framing are technically perfect.

    Electronics and Technical Products: Accuracy of Included Accessories

    Electronics listings are particularly exposed to the “props not included in sale” violation because product photography in this category routinely includes cables, adapters, cases, and complementary devices for visual context and scale. If the main image shows a pair of headphones next to a smartphone for scale, but the smartphone is not included — that’s technically a violation. If the image shows a charging cable that’s included with one product variant but not another, and the same image is applied to both variants, that’s a misrepresentation violation on the variant that doesn’t include the cable.

    Grocery and Health Products: Label Legibility as Compliance

    For consumable products — supplements, food, beverages, personal care — Amazon’s content accuracy requirements intersect with image compliance in a specific way. The product label shown in the image must match the actual product label. Label updates that change ingredients, warnings, dosage instructions, or net weight create a window where the existing listing images show the old label while the actual product has the new label. This is an image accuracy violation even if the photography itself is otherwise perfectly compliant.

    Toys and Children’s Products: Safety Claim Restrictions

    Secondary images for toys and children’s products that include safety certifications, age-appropriateness badges, or compliance marks (ASTM, CPSC, CE, and similar) run into a specific content restriction: promotional badges and certification marks are prohibited in secondary images in ways that create ambiguity about what is and isn’t a compliance mark versus a promotional badge. The safe approach is to communicate safety certifications in the text content of the listing rather than embedding badges or certification logos in the images themselves.

    AI-Generated Images and the Compliance Grey Zone Sellers Are Walking Into

    Amazon does not ban AI-generated or AI-assisted product images. The policy is output-based, not tool-based — what matters is whether the final image accurately represents the actual product, meets technical specifications, and complies with content restrictions. This permissive-sounding policy is creating a false sense of safety among sellers who are using AI image generation extensively in 2026.

    The Accuracy Problem Is the Core Risk

    AI image generation tools produce images that look like the product being described, not necessarily like the actual product being sold. Generated images may alter proportions, modify colors, simplify details, add or remove design elements, or create a version of the product that is visually appealing but materially different from what the customer will receive. Amazon’s accuracy requirement — that images must truthfully represent the physical item being sold — applies with the same force to AI-generated images as to traditional photography.

    This creates a specific workflow risk: a seller who uses an AI tool to generate a “product image” for a listing that hasn’t been physically photographed, or who uses AI to produce imagery for product variants that differ only slightly from photographed versions, can end up with images that are technically accomplished but fundamentally misrepresent what’s in the box. The enforcement consequence is classification as a misrepresentation violation — a more serious category than a technical spec failure.

    AI Enhancement vs. AI Generation — A Distinction That Matters

    There’s a practical compliance difference between using AI tools to enhance a photograph of the real product (background removal, background replacement with pure white, color correction, upscaling) and using AI to generate a product image without a real photographic source. The former is generally lower risk as long as the enhancement doesn’t alter the product’s appearance in ways that misrepresent it. The latter is inherently higher risk because the output is a synthetic creation rather than a record of the actual product.

    For AI background removal and replacement specifically — a very common use case for achieving the pure white main image standard — sellers need to verify that the removal process didn’t clip the product edges, alter its apparent dimensions, or introduce artifacts that change the perceived product color or finish. These are easily introduced errors in AI-based background tools that human review of the output often misses.

    Disclosure Requirements and Evolving Expectations

    Amazon is moving toward requiring disclosure for AI-generated content in some contexts. The practical advice for 2026 is to treat AI-generated imagery with the same documentation discipline as traditional photography: keep records of what was generated, for which ASINs, using which prompts, and what accuracy verification was performed before upload. If enforcement questions arise, documented verification that the AI output accurately represents the physical product is the strongest defense available.

    Image Hijacking — The Suppression Risk You Didn’t Create But Still Own

    Image hijacking is one of the most underappreciated suppression threats in multi-seller marketplaces, and 2026’s enforcement environment has made it significantly more consequential. The mechanics are specific: in Amazon’s catalog architecture, a product detail page is shared infrastructure. Sellers listing on the same ASIN contribute to a shared content pool, and Amazon’s systems make judgments about which contributed content to display. This creates a vector for unauthorized content substitution.

    How Non-Brand Sellers Replace Your Main Image

    A third-party seller who attaches an offer to your ASIN can contribute content to that ASIN’s detail page — including images. If Amazon’s system evaluates their submitted image as higher quality, more compliant, or simply more recent than yours, it may display their image as the main image on your product detail page. This means a seller offering a counterfeit, grey-market, or materially different version of your product may effectively be showing their image — which may show a different product — as the main image for your ASIN.

    The catastrophic scenario is when the substituted image is non-compliant with Amazon’s policies. Your listing gets suppressed for a policy violation on an image you didn’t upload, didn’t approve, and may not even know exists on your product page. The suppression impact falls on your ASIN, your sales velocity, your organic rank, and potentially your account health.

    Brand Registry and Catalog Lock as Primary Defenses

    Amazon’s Brand Registry provides qualified brand owners with tools to assert control over the content displayed on their branded ASINs. The Catalog Lock feature — available to Brand Registry members — allows restriction of changes to key listing fields including the main image. When catalog lock is applied, only the brand-authenticated account can change the main image, regardless of what other sellers contributing to that ASIN submit.

    Applying catalog lock to high-revenue ASINs is not optional in 2026 — it’s a basic operational requirement. The risk of not doing so is an uncontrolled image substitution event that you may not discover until suppression has already occurred and rank has already started decaying.

    Monitoring for Unauthorized Image Changes

    Catalog lock prevents changes going forward but doesn’t retroactively notify you of changes that have already occurred. A monitoring workflow that checks the main image displayed on each high-value ASIN against a stored reference image on a regular cadence is the mechanism that catches hijacking events before they extend into suppression territory. This can be done manually for small catalogs, but for accounts with dozens or hundreds of ASINs, automated tools that screenshot product pages and compare against a reference library are operationally necessary.

    Building a Suppression-Proof Image QA System Before Launch

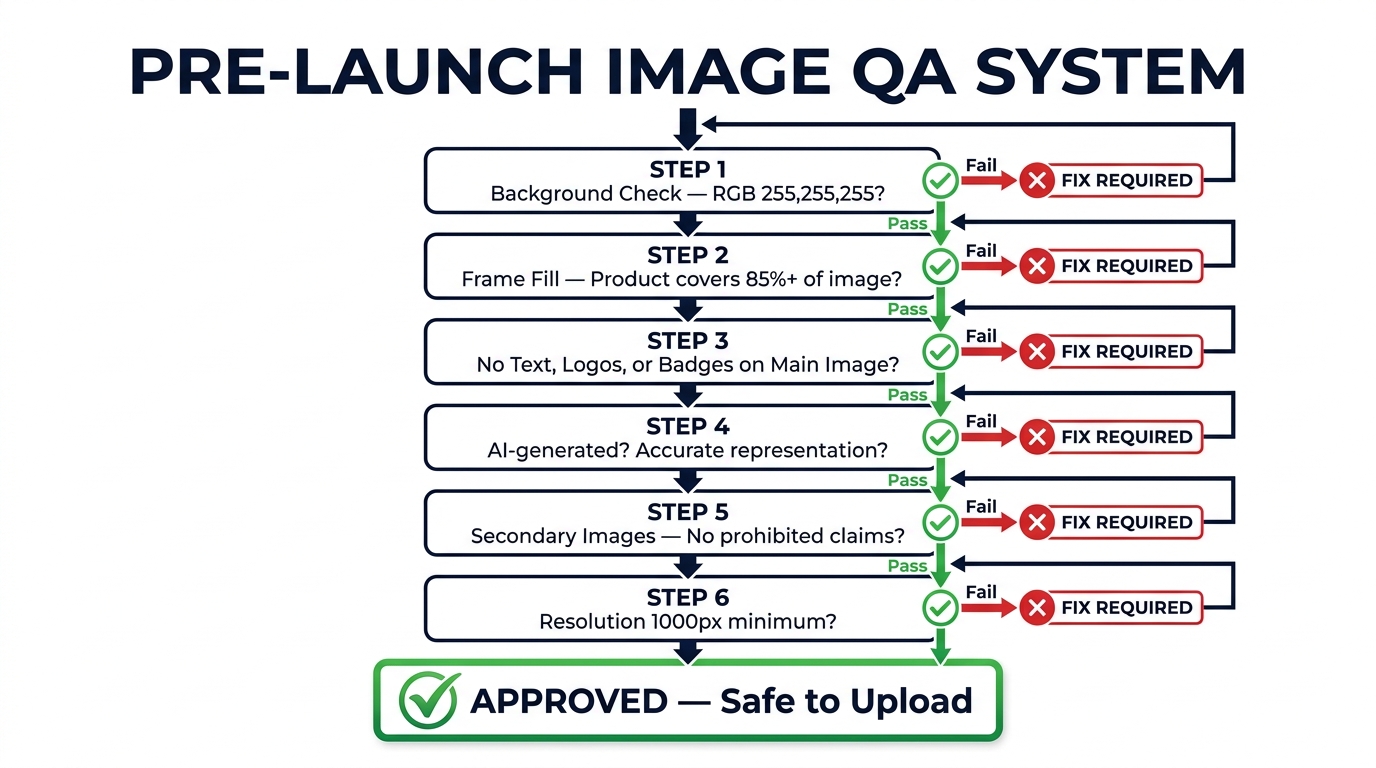
    Pre-launch image QA system flowchart for Amazon 2026 compliance — step-by-step checklist from background verification to upload approval

    Prevention is categorically cheaper than recovery in the Amazon suppression context. A listing that never gets suppressed doesn’t lose rank, doesn’t pause ad delivery, doesn’t trigger account health flags, and doesn’t require the operational scramble of emergency remediation. The investment in a pre-launch QA system pays back every time it prevents a suppression event.

    The Pre-Upload Technical Checklist

    A systematic pre-upload technical check should verify every image before it enters the Amazon catalog. For the main image specifically, this checklist should be non-negotiable:

    • Background verification: Open the image in a color-accurate editing environment and use the eyedropper tool to sample multiple background points. Confirm RGB values of 255,255,255 across the full background area. Pay particular attention to areas near the product edge, which are most likely to show gray fringing from background removal tools.
    • Frame fill measurement: Using a grid overlay or selection tool, verify that the product occupies at least 85% of the image canvas by area. For high-value listings, aiming for 90–95% coverage reduces the risk of failing stricter re-audit thresholds.
    • Element check: Verify absence of text, logos, badges, watermarks, inset images, and graphic overlays. Check at 100% zoom, not at thumbnail scale — violations that are invisible at thumbnail size are still policy violations.
    • Shadow and reflection audit: Zoom into the base of the product and check for ground shadow, cast shadow, or reflective surface elements. These are the most commonly overlooked non-white background elements.
    • Resolution confirmation: Check the actual pixel dimensions of the file, not the upload dialogue — confirm 2,000+ pixels on the longest side and appropriate file size for the format being used.
    • Accuracy verification: Compare the image against the physical product for color accuracy, included accessories, packaging match, and variant-specific details. For AI-enhanced images, this comparison must be done against the actual physical product, not the source image.

    Building a Category-Aware Review Layer

    Generic technical checks aren’t sufficient for category-specific compliance. For each product category you operate in, the QA system should include a category-specific module that checks against the additional requirements that apply to that category. For apparel, this means confirming model or invisible mannequin presentation for the main image. For electronics, this means verifying that every item shown in the image is included in the purchase. For consumables, this means confirming that the label shown matches the current product formulation and packaging.

    This layer of the QA system requires someone who actually knows the category-specific rules — which is itself an argument for centralized image compliance expertise within organizations managing multi-category catalogs, rather than relying on product managers or graphic designers to self-assess compliance.

    Version Control and Asset Management

    Every image that enters the Amazon catalog should have a documented record: the file, the date it was uploaded, the ASIN it was applied to, the slot it occupies (main vs. secondary slot number), who approved it, and any notes about the version history. This documentation serves two functions: it enables fast identification and replacement when an image fails a re-audit, and it enables quick detection of unauthorized image substitutions by comparing the currently displayed image against the documented approved version.

    When You’re Already Suppressed — A Recovery Playbook That Works in 2026

    Despite best prevention efforts, suppression events happen. The recovery process in 2026 has some specific characteristics that sellers need to understand to navigate it efficiently — because the wrong remediation approach can extend the suppression duration significantly.

    Triage by Revenue Impact First

    When a batch suppression event affects multiple ASINs simultaneously, the instinct is to work through a list systematically. The 2026 reality is that speed of recovery is more important for some ASINs than others, and limited internal resources need to be directed at the ASINs where suppression is causing the greatest revenue loss and rank decay. Sort the suppressed ASIN list by average monthly revenue or sales velocity and address the top items first.

    For the highest-revenue ASINs, consider whether you have a compliant backup image already prepared. This is the argument for maintaining a “compliance-ready” version of every main image as part of your asset management system — a pre-verified, technically perfect version that can be uploaded immediately during an emergency without requiring a photography or editing workflow to execute under time pressure.

    Understanding the Suppression Cause Before Fixing the Image

    Uploading a replacement image without first diagnosing why the original image was suppressed is a common and costly mistake. If the replacement has the same underlying issue — off-white background, subtle shadow, wrong frame fill — it will fail again, restarting the suppression clock and potentially triggering escalated enforcement attention. Seller Central’s listing quality dashboard and the suppression notification details (when available) should be reviewed to identify the specific violation category before any replacement image is prepared.

    The Right Way to Submit the Replacement

    Image replacement in 2026 works best when the corrected image is submitted through the most authoritative channel available. For Brand Registry sellers, this means using the Brand content submission tools rather than standard Seller Central image upload — brand-authenticated submissions are typically evaluated faster and carry higher confidence weighting in Amazon’s system. For sellers without Brand Registry, standard image upload through the listing edit interface is the only option, but ensuring the file metadata, filename format, and upload format all meet specifications reduces processing friction.

    Contacting Seller Support in parallel with a replacement upload is advisable for high-revenue ASINs where every day of suppression represents material revenue loss. A support case creates a documented record of the remediation effort and sometimes accelerates the system’s processing of the replacement image. Be specific in the support case about what change was made and why the new image is compliant — generic “please fix my listing” messages generate slower and less useful responses than precise technical explanations.

    Post-Recovery Monitoring

    Lifting a suppression doesn’t mean the underlying system risk is resolved. After a listing is restored, monitor it daily for the following two weeks to confirm that the replacement image is stable, that the listing’s search visibility has been restored, and that ad delivery has resumed and is rebuilding toward pre-suppression performance. Watch the variation family if applicable — sometimes restoring one ASIN reveals a secondary suppression on a sibling ASIN that wasn’t immediately visible.

    Continuous Monitoring — Tools, Cadences, and What to Actually Track

    Compliance is not a one-time achievement. Amazon’s enforcement environment in 2026 requires ongoing monitoring as a permanent operational function — not because the rules change constantly, but because retroactive enforcement sweeps, image hijacking attempts, and catalog drift (where product changes make formerly accurate images inaccurate) create ongoing risk that no initial audit can permanently eliminate.

    Daily Monitoring: Account Health and Suppression Alerts

    The Account Health dashboard in Seller Central is the primary real-time signal for policy violations and enforcement actions. Checking it daily — not weekly — is the baseline for any multi-ASIN operation. Suppression notifications, policy violation alerts, and image removal notices all surface here first. Many third-party tools integrate with Seller Central APIs to send automated alerts when account health metrics change, which reduces the response time from a daily manual check to near-real-time notification.

    Specific metrics to watch daily: account health score, listing quality score changes, new policy violations, and any notifications under the “Listing Issues” section of the inventory management view.

    Weekly Monitoring: Image Integrity Checks

    A weekly check of main images displayed on all active ASINs, compared against the approved reference image in your asset management system, catches hijacking-based substitutions before they have time to generate suppression events. For accounts with large catalogs, this is where automated screenshot comparison tools become necessary rather than optional — manual verification of hundreds of product pages weekly is not a sustainable operational workflow.

    Quarterly Audits: Full Catalog Compliance Review

    Every 90 days, conduct a full catalog compliance review against current Amazon image standards. The purpose of the quarterly cadence is to catch two types of drift: enforcement threshold drift (where Amazon’s automated detection becomes stricter, making previously-accepted images newly vulnerable) and product accuracy drift (where product updates, label changes, or packaging modifications have made existing images inaccurate).

    The quarterly audit should use the same comprehensive checklist as the pre-launch QA process, applied to every image in the active catalog. Prioritize the audit by revenue impact — high-revenue ASINs first — but complete the full catalog review within the quarter. Any images identified as potentially non-compliant during the quarterly audit should be scheduled for replacement before they become active suppression triggers.

    Tools Worth Using in 2026

    Several third-party tools have developed specific capabilities for image compliance monitoring and suppression detection in the Amazon context. Datahawk, SellerApp, and Jungle Scout all offer suppression monitoring features that alert sellers when listing status changes. For image accuracy and consistency verification across large catalogs, tools that can perform pixel-level comparison between reference images and current displayed images are increasingly available within broader catalog management platforms. Amazon’s own Listing Quality Dashboard — available to Brand Registry members — surfaces image-specific quality flags that can serve as early warning indicators before formal suppression occurs.

    The Opportunity Hidden in Compliance — How Strict Policy Creates Competitive Gaps

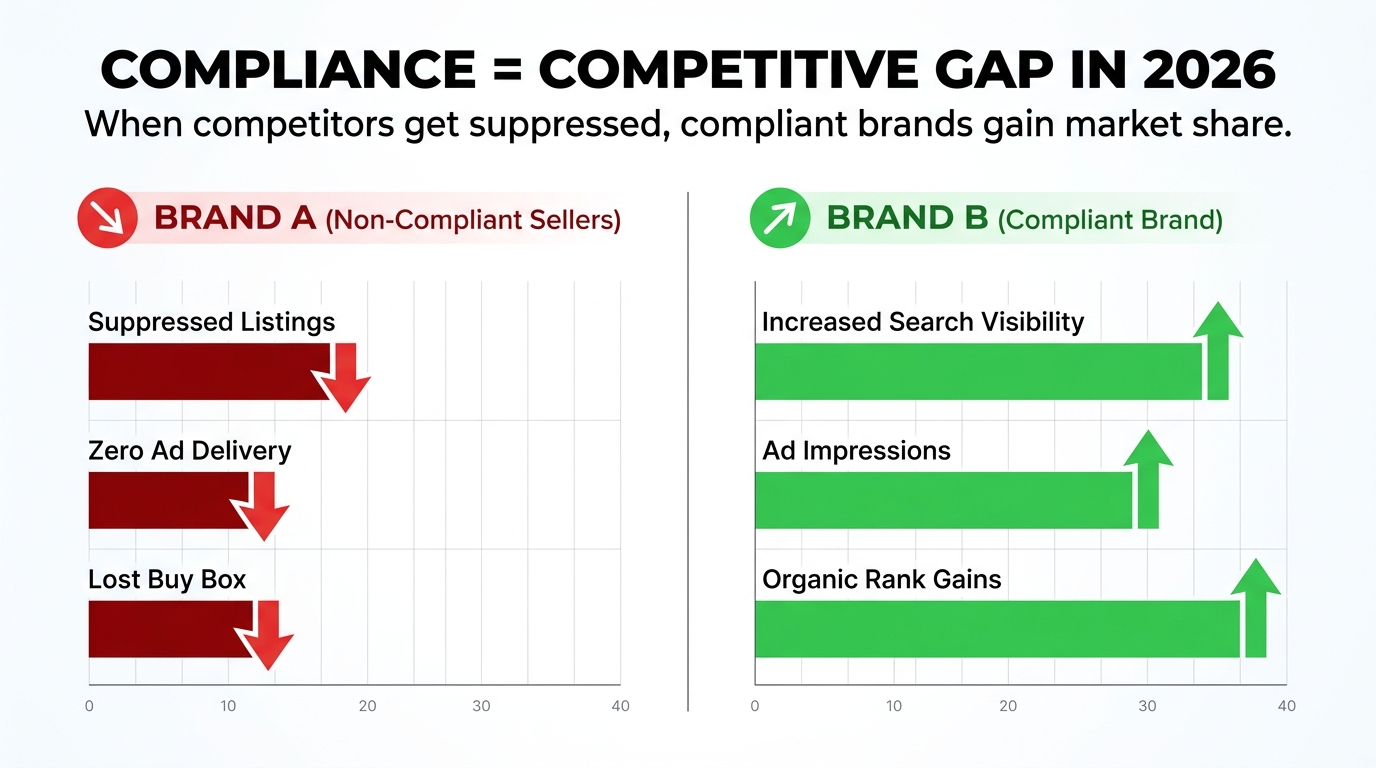
    Competitive advantage bar chart showing compliant brands gaining organic rank and ad impressions while non-compliant sellers face suppression in 2026

    There’s a strategic dimension to Amazon’s stricter image enforcement that most sellers, understandably focused on their own compliance risk, don’t fully consider. When enforcement creates suppression events at scale across a category, it disproportionately affects sellers who are least equipped to manage the operational demands of compliance — and that creates measurable opportunities for brands that maintain clean catalogs.

    Competitive Search Visibility When Rivals Go Dark

    When competing ASINs are suppressed from search results — whether for image violations or any other reason — the search result pages your customers are using don’t disappear. They just become less crowded. Organic rankings that were previously competitive become less contested, and brands with compliant, optimized listings move into visibility positions they couldn’t achieve organically against a full competitive field.

    This is not a minor effect. Category-level suppression events have been associated with measurable increases in organic rank and organic session traffic for remaining visible listings — particularly in competitive product categories where multiple sellers are battling for the same keyword positions. A brand that monitors competitor listing status and has ads pre-positioned to capture increased search traffic during competitor suppression events can generate meaningful incremental revenue from other sellers’ compliance failures.

    Ad Auction Dynamics During Suppression Events

    When competing ASINs are suppressed, their Sponsored Products campaigns stop delivering — because ads can’t drive traffic to suppressed listings. This removes their bidding pressure from the ad auction for shared keywords. For an advertiser with remaining live, compliant listings, the practical effect is lower cost-per-click for the keywords those competitors were previously contesting, at the same or higher impression volume. This is a direct ROAS improvement opportunity that requires no change to your own bidding strategy.

    The brands that capture this opportunity most effectively are those who monitor category-level suppression events as a standard part of their competitive intelligence, and who maintain adequate advertising budgets and bid structures to capitalize on the brief windows when competitor suppression creates more favorable auction conditions.

    Long-Term Brand Quality Signaling

    Amazon’s algorithm evaluates listing quality as an input to organic search ranking. Listings with consistently high image quality scores, stable compliance status, and strong click-through and conversion metrics are treated as higher-quality results and are rewarded with ranking advantages over time. The brands that build and maintain genuinely compliant, high-quality image assets aren’t just avoiding suppression — they’re accumulating a sustained ranking advantage that compounds over time relative to competitors who manage compliance reactively.

    This is the less-discussed dimension of image compliance investment: it’s not purely defensive. Done well, it’s an offensive capability that builds durable organic rank advantages and reduces the cost of maintaining visibility in competitive categories.

    Putting It Together: The 2026 Portfolio Protection Framework

    The operational reality that sellers need to internalize is that image compliance in 2026 is a permanent, ongoing cost of doing business on Amazon — not a one-time setup task. The brands that are building suppression-resilient catalogs are doing so through systems, not through one-off audits. Here’s the framework that holds up:

    Layer 1: Prevention (Pre-Launch QA)

    Every image that enters the catalog passes through a documented, category-aware technical checklist before upload. No exceptions for time pressure, budget constraints, or “this one looks fine.” The checklist covers RGB background verification, frame fill measurement, element audit, shadow check, resolution confirmation, and accuracy verification against the physical product. This layer eliminates preventable suppression events before they happen.

    Layer 2: Protection (Asset Control and Brand Registry)

    Catalog lock is applied to every high-revenue branded ASIN via Brand Registry. Approved images are stored in a version-controlled asset library with documented metadata. Brand Registry’s monitoring tools are configured to alert for unauthorized content changes. This layer eliminates the hijacking-based suppression category.

    Layer 3: Detection (Continuous Monitoring)

    Daily account health checks, weekly image integrity verification for high-value ASINs, and quarterly full-catalog compliance audits form a monitoring cadence that catches enforcement issues as early as possible. Automated alerts from Seller Central integrations reduce detection latency. This layer minimizes the duration of any suppression events that do occur despite prevention and protection efforts.

    Layer 4: Recovery (Rapid Remediation)

    Pre-prepared compliance-ready backup images for all high-revenue ASINs enable same-day replacement when suppression occurs. A documented escalation process — who does what, in what order, using which tools — means the response to a suppression event is a procedure rather than a crisis. This layer minimizes the organic rank and revenue loss from unavoidable suppression events.

    Together, these four layers create a portfolio-level system that doesn’t eliminate suppression risk entirely — Amazon’s enforcement environment is too dynamic for absolute guarantees — but that dramatically reduces both the frequency and the duration of suppression events, and positions compliant brands to capture competitive advantage when the market around them is affected by enforcement actions they’re protected against.

    Key Takeaways

    • Suppression is now retroactive and portfolio-wide. Images that passed upload checks months ago can be re-flagged during automated re-audit sweeps. Treating compliance as a launch-day task is no longer adequate.
    • The six most dangerous non-obvious triggers are off-white backgrounds that look white, product shadows, props not included in the sale, hidden watermarks, post-compression resolution failures, and composite/inset images in the main slot.
    • The cascade from a single suppressed ASIN can destroy organic rank, pause ad delivery, disrupt variation family performance, and generate account health flags — all from one non-compliant image.
    • Category-specific rules are where experienced sellers get surprised. Apparel, electronics, grocery, and children’s products all carry additional image requirements that generic compliance guides don’t fully address.
    • AI-generated images are allowed but not safe by default. The accuracy requirement applies equally to AI-generated imagery — synthetic images that don’t accurately represent the physical product are a misrepresentation violation, not just a technical one.
    • Image hijacking is a suppression risk you didn’t create but are responsible for recovering from. Catalog lock via Brand Registry is the operational control that prevents it.
    • Four-layer portfolio protection — prevention, protection, detection, and recovery — is the operational framework that makes suppression management systematic rather than reactive.
    • Compliance is competitive advantage. Every competitor suppression event is an organic rank and ad auction opportunity for brands that remain visible and compliant.
  • ChatGPT Connectors: What’s Actually Working in Real Workflows Right Now

    ChatGPT Connectors: What’s Actually Working in Real Workflows Right Now

    ChatGPT Connectors workflow automation hub showing multiple app integrations connected to a central ChatGPT interface

    There is a version of ChatGPT Connectors that gets talked about in press releases — a polished story about AI unifying your entire stack, eliminating app-switching, and turning natural language into cross-platform action. Then there is the version that teams are actually using week to week in 2026: messier, more specific, and genuinely more interesting.

    The reality is that Connectors have quietly moved from a novelty to a production layer for a growing slice of knowledge workers. The shift did not happen in a single feature drop. It accumulated — through better deep research integration, the slow expansion of write actions, and the Model Context Protocol (MCP) giving enterprise teams a path to build connectors that can actually touch their own internal systems in ways the native integrations cannot.

    This post is not an explainer on what Connectors are. It is a ground-level account of what is working right now, for which teams, under what conditions, and where the real friction points still live. If you are trying to figure out whether to build or expand a Connectors-based workflow in the next 30 days, this is the article you need to read first.

    We will cover the ecosystem in its current state, the underused combination of Deep Research mode with live connectors, the write actions that finally give the platform some teeth, the MCP architecture layer for teams that need to go beyond native integrations, and the honest limitations that trip up otherwise well-designed workflows. We will also spend time on the governance question — because what data your connected apps expose depends heavily on which plan you are running, and that distinction matters far more than most teams realise until something goes wrong.

    The Connector Ecosystem at Mid-2026: What 500+ Apps Actually Means in Practice

    ChatGPT Connectors ecosystem diagram showing 500+ connected apps organized by category including CRM, cloud storage, email, collaboration tools, and automation platforms

    OpenAI’s connector count crossed 500 integrated applications for ChatGPT 5, spanning cloud storage, email, calendars, CRMs, code repositories, and automation platforms. That headline figure is accurate, but it requires some unpacking before it translates into workflow strategy.

    Coverage is Uneven by Design

    The most battle-tested connectors — the ones that have been in production the longest and carry the fewest edge-case surprises — cluster in a predictable group: Google Workspace (Drive, Gmail, Calendar, Docs), Microsoft 365 (SharePoint, OneDrive, Outlook, Teams), GitHub, Slack, and Notion. These cover the daily surfaces where most knowledge work actually happens, and they are the connectors where the deep research integration and sync/indexing features are most mature.

    CRM connectors occupy a different tier. HubSpot is listed as a native built-in CRM connector in ChatGPT Enterprise’s framework, and it works well for retrieval — pulling contact records, deal stages, and activity history into a chat context without leaving the interface. Salesforce access, by contrast, tends to run through MCP-based or third-party bridges rather than a fully native connector, which changes the setup complexity significantly. If your RevOps team is planning Salesforce workflows assuming native connector simplicity, that gap will surface early.

    The automation platform integrations — Zapier, Make, Microsoft Power Automate — sit in a third category. These are less about data retrieval and more about triggering. When you connect ChatGPT to Zapier, you are not just reading from Zapier; you are using ChatGPT as the reasoning layer that decides what Zapier should execute. This distinction between ChatGPT as a retrieval tool versus ChatGPT as an orchestration layer is the most important conceptual shift for teams designing their first serious connector workflows.

    Search vs. Sync: Two Modes That Teams Confuse

    There are two fundamentally different ways ChatGPT can interact with a connected app: real-time search and pre-synced indexed knowledge. Real-time search pulls current data from the connected app at query time — it is slower and depends on live API access, but the data is always fresh. Pre-synced indexed knowledge uploads a snapshot of your connected content (documents, wikis, knowledge bases) and lets ChatGPT query that index instantly without hitting the live API on every request.

    The choice between these two modes matters for both performance and data freshness. Teams building customer support workflows typically want real-time search so agents always get current ticket status and contact data. Teams building research workflows or internal knowledge assistants often prefer indexed sync for speed, accepting that the data might be hours or days old depending on their sync schedule.

    Getting this wrong — expecting indexed freshness when you have set up real-time search, or expecting live pricing data when you are querying a weekly sync — is one of the most common causes of early frustration with Connectors. It is not a product failure; it is a configuration decision that needs to be deliberate.

    Plan Availability Shapes What You Can Actually Build

    Not all features are available on all plans. The full connector suite, write actions, and MCP custom connector support are concentrated in ChatGPT Team, Business, Enterprise, and Edu plans. Free and Plus users have access to a narrower set of connectors with more restricted capabilities. If you are evaluating Connectors for a team deployment, the feature-to-plan mapping is worth auditing before you build any workflow assumptions around capabilities that may not be available at your current tier.

    Deep Research Mode + Connectors: The Combination Most Teams Are Leaving on the Table

    Before and after comparison showing manual tab-switching workflow versus ChatGPT Connectors deep research mode saving 40-60 minutes per worker per day

    ChatGPT’s Deep Research mode was designed to conduct extended, multi-source research tasks autonomously. When it launched, the primary use case was web-based — pulling together publicly available information on a topic, synthesising it into a structured report, and surfacing citations. That was useful. What is significantly more useful, and less discussed, is running Deep Research across your own connected data.

    What Happens When Deep Research Hits Internal Data Sources

    When you activate Deep Research mode with connectors enabled — particularly Google Drive, SharePoint, or a Notion workspace — the model does not just search one source. It can be instructed to pull from multiple connected repositories simultaneously, cross-reference findings, and synthesise a coherent output that would have required an analyst several hours to assemble manually.

    The practical example that illustrates this well is competitive intelligence preparation. A team preparing for a quarterly business review might need to compile: recent customer feedback from a Notion CRM notes database, product development updates from GitHub commit summaries, and sales deal notes from HubSpot. Before connected Deep Research, that synthesis meant three separate logins, manual copy-paste into a document, and then a drafting session. With connectors configured and Deep Research prompted correctly, a single well-structured query can pull from all three sources and return a formatted briefing document in the time it used to take just to open the tabs.

    Teams running this pattern consistently report time savings in the range of 40 to 60 minutes per worker per day on research-heavy tasks. That figure comes from OpenAI’s own enterprise productivity data and is consistent with independent analyst estimates. On a ten-person team doing daily research tasks, that is the equivalent of recovering a full-time employee’s working hours every week — without headcount change.

    The Prompt Architecture That Makes It Work

    Deep Research across connectors does not work as well with vague prompts as it does with scoped, structured ones. The prompts that produce the most consistent results tend to follow a pattern: specify the data sources explicitly (“from my Google Drive project folder and HubSpot deal notes”), define the output format (“give me a bulleted executive summary with a risk flag section”), and set a time boundary (“for the past 30 days”).

    Vague prompts like “summarise what happened in the business this month” will return something, but it will be inconsistent and harder to act on. The teams getting the most out of Deep Research with connectors have built prompt templates — stored in a shared Notion page or a ChatGPT custom instruction set — that every team member uses as a starting point. Prompt standardisation is not glamorous, but it is the operational practice that separates teams with high connector ROI from teams with mediocre connector ROI.

    Connector-Augmented Research for External Competitive Work

    The combination also works outward. Teams using the web search connector alongside internal data connectors can instruct Deep Research to synthesise internal pipeline data alongside publicly available competitor announcements, industry reports, and pricing pages. The output is a research brief that blends proprietary internal context with external market intelligence — something that previously required a dedicated analyst function to produce at any reasonable frequency.

    Write Actions: Where Connectors Finally Get Some Teeth

    For most of their life, ChatGPT Connectors have been fundamentally about reading data — fetching, searching, and summarising content from connected apps without touching anything on the other side. Write actions change that equation, and they represent the most significant recent evolution in what Connectors can do.

    What Write Actions Currently Cover

    Write actions allow ChatGPT, when connected to supported apps, to take actions rather than just report on them. In practice, the most mature write action implementations in mid-2026 include: drafting and sending emails via Gmail or Outlook (with user confirmation), creating calendar events, creating and updating Notion pages and database entries, creating GitHub issues and pull request comments, and triggering actions in connected automation platforms like Zapier or Power Automate.

    The key qualifier is “with user confirmation.” Most write action implementations include a confirmation step before execution — ChatGPT shows you what it is about to do and asks you to approve. This is not an arbitrary friction point; it is a deliberate design choice that addresses one of the central governance concerns about giving an AI model write access to production systems. Teams that find the confirmation step annoying often have workflows where the write volume is high enough that the confirmation becomes a bottleneck, which is a signal that those workflows should be moved to a fully automated pipeline via Zapier or Make rather than handled interactively in ChatGPT.

    The Workflows Where Write Actions Are Actually Earning Their Keep

    Meeting preparation and follow-up is the workflow category where write actions are delivering the most consistent value in practice. The pattern looks like this: a sales rep finishes a call, opens ChatGPT, prompts it to pull the call notes from their connected CRM, generate a follow-up email summarising next steps, create a calendar event for the agreed follow-on meeting, and update the deal stage in HubSpot. What used to take 20 to 30 minutes of fragmented admin work after every call now takes two to four minutes with connector-enabled write actions.

    Multiply that across a 15-person sales team with four to six customer calls per day per rep, and the arithmetic becomes compelling quickly. One reported outcome from a sales operations team using this pattern was a 23% increase in closed deals — attributed specifically to the elimination of dropped follow-ups that previously fell through the cracks in the manual admin process.

    Content creation workflows are the second area of strong adoption. Marketing teams are using write actions to take a research output produced by Deep Research, have ChatGPT transform it into a draft blog post or email campaign, and push that draft directly to a Google Doc or Notion page for editorial review. The human still edits, approves, and publishes — but the first draft, historically the most time-intensive part of the content production cycle, is handled by the connected workflow.

    Where Write Actions Are Still Immature

    It is worth being direct about the gaps. CRM write-back — the ability for ChatGPT to update deal records, contact properties, and pipeline stages directly in Salesforce or HubSpot based on conversation context — is inconsistent and limited outside of explicitly supported operations. Delete actions remain largely unavailable across the connector ecosystem; ChatGPT will not delete your emails or your files. Bulk write operations (updating 200 records at once rather than one at a time) are not reliable through the native connector interface and require the MCP layer or a separate automation platform for anything at scale.

    Real Workflow Wins: Sales Operations and CRM Pipelines

    Of all the functional areas where Connectors have been adopted in production, sales operations has the most clearly quantified outcomes and the most repeatable workflow patterns. This is partly because RevOps teams tend to have cleaner metrics for measuring impact — deal velocity, follow-up rates, CRM data quality — and partly because the pain points that Connectors address in sales ops are among the most acute across knowledge work.

    Pipeline Hygiene at Scale

    One of the most common and highest-ROI connector use cases in sales is automated pipeline hygiene review. The workflow: connect ChatGPT to the CRM (HubSpot natively, Salesforce via MCP), prompt it weekly to identify all deals past their expected close date, deals with no activity in the past two weeks, and deals missing required data fields. ChatGPT synthesises this into a prioritised cleanup list, flags the highest-risk deals, and drafts outreach messages for each stalled opportunity.

    The manual version of this task — typically performed by a sales manager or RevOps analyst — takes two to four hours per week. The connector-assisted version takes under 20 minutes, including the time to review and approve the drafted outreach. More importantly, it happens consistently. Manual pipeline reviews are the first thing to get skipped when a team is busy. Connector-automated pipeline reviews happen on schedule regardless of how many fires are burning.

    Lead Enrichment and Routing

    A second high-value sales ops workflow combines CRM connectors with web search connectors for lead enrichment. When a new lead arrives in HubSpot, a connected workflow can instruct ChatGPT to research the company (size, funding stage, recent news, tech stack signals from public sources), score the lead against your ideal customer profile, draft a personalised first-touch email, and route the lead to the appropriate sales rep based on territory or vertical rules.

    Teams implementing this workflow report near-zero data entry errors (because the enrichment is automated) and significant improvements in first-touch response quality. The personalised emails drafted by the enrichment workflow outperform generic sequence templates because they reference specific, current company context rather than generic industry messaging.

    Meeting Brief Automation

    Pre-call research is another workflow category where the time savings are immediate and the quality improvement is tangible. A connected brief generation workflow pulls the last three months of deal activity from CRM, any email thread history from Gmail, and recent news about the prospect company from web search, then synthesises a two-page meeting brief with talking points, known objections, and recommended next steps. Reps who use this workflow consistently report feeling more prepared and handling objections more confidently — not because the AI is doing the thinking, but because it is ensuring that relevant context is always surfaced before the call, rather than only when the rep happens to remember to look.

    Real Workflow Wins: Knowledge Work, Documentation, and Internal Comms

    Beyond sales, the second most impactful category of Connector deployment is in organisations with high volumes of internal knowledge work — professional services firms, product teams, research functions, and any operation where people spend significant time either finding information or documenting what they know.

    The Internal Knowledge Base Problem

    Most organisations accumulate knowledge in scattered, poorly organised repositories. Confluence wikis that no one updates. Notion databases where search returns 40 results for any query. SharePoint folders that have been added to for eight years by people who no longer work there. The standard solution — periodic knowledge audits, better tagging taxonomies, dedicated knowledge managers — is expensive and rarely sustained.

    ChatGPT Connectors offer a different approach: rather than organising the knowledge base, you use ChatGPT as an intelligent interface on top of it. Connect ChatGPT to Notion, Confluence, or SharePoint, index the content, and let team members query the accumulated knowledge in natural language rather than through a search interface that requires them to know what to look for. The knowledge base does not get cleaner, but it becomes dramatically more accessible.

    Teams running this pattern report reducing average information-retrieval time from 15 to 20 minutes (digging through docs) to two to three minutes (querying the connected index). Over a week of work, that adds up to context-switching reduction of up to 70% on knowledge-retrieval tasks — a figure consistent with productivity research on the cost of app-switching in knowledge-intensive roles.

    Document Drafting and Iteration Workflows

    The second major knowledge work use case is iterative document drafting. The workflow: retrieve relevant existing documents from Google Drive or SharePoint via connector, use them as context for drafting a new document (proposal, report, policy update, technical spec), and push the resulting draft back to the document store for review. The key here is that the connected context makes the drafts significantly better than prompting ChatGPT without access to internal references. When the model can read your existing proposal templates, client history, and pricing guides before drafting a new proposal, the output is calibrated to your organisation’s standards rather than generic.

    Internal Comms and Status Reporting

    Project status reporting is one of the most universally disliked administrative tasks in knowledge work. It is time-consuming, it is often written by people who would rather be doing the actual work, and it is frequently repetitive — summarising the same data that already exists in project tools. Connected ChatGPT workflows are changing this for teams running their projects in tools like Asana, GitHub, or Notion. A weekly status prompt can pull current task status, blocking issues, and completion metrics from the connected project tool, then draft a formatted status update ready for the team lead to review and send. The time savings per week per project manager run between 45 minutes and two hours depending on project complexity.

    Real Workflow Wins: Engineering Teams and Code Repositories

    Engineering teams were early adopters of AI coding tools via GitHub Copilot, but the ChatGPT Connectors integration with GitHub represents a different use case — less about autocomplete in the IDE and more about connecting code context to broader operational workflows.

    Code Review Summarisation and Context Bridging

    Large pull requests are a well-known productivity bottleneck in engineering organisations. A senior engineer reviewing a 2,000-line PR needs context on what the change is doing, why it was made, what tests cover it, and what risks it introduces. Historically, gathering that context means reading the commit history, the linked issue, the PR description (if one was written), and the diff itself. Connected ChatGPT can pull the GitHub PR, linked issue, and relevant documentation from a connected Confluence or Notion space and produce a structured review brief in under a minute. Reviewers still do the actual code review; they just arrive at it with context already assembled.

    Incident Response and Post-Mortems

    Incident response is another area where cross-system context is critical and time is scarce. When something breaks, engineers need to correlate information from monitoring tools, Slack threads, GitHub commits, and deployment logs simultaneously while also trying to fix the problem. Connected ChatGPT workflows can assist by pulling the recent commit history, the active incident Slack thread, and any linked issues into a single context window, then helping draft the timeline and contributing factors analysis for the post-mortem. Teams that have piloted this report significant reductions in post-mortem documentation time — from four to six hours to under two hours — while improving the accuracy and completeness of root cause analysis.

    Developer Onboarding

    Perhaps the most structurally impactful engineering workflow enabled by Connectors is developer onboarding. New engineers typically spend their first two to four weeks finding information about codebases, internal tools, processes, and conventions — primarily by asking colleagues and searching internal docs. A connected ChatGPT deployment that indexes the GitHub codebase, internal engineering wiki, architecture decision records, and runbooks dramatically compresses this ramp-up. Rather than waiting to find the right person to ask, a new hire can query the connected system directly. Teams report reducing effective onboarding time by 30 to 40% using connected knowledge systems — a significant saving given the cost of engineering talent.

    The MCP Layer: Building Custom Connectors That Can Actually Do Things

    Custom MCP connector architecture diagram for ChatGPT Enterprise showing layered stack from ChatGPT interface through authenticated MCP server to internal CRM, data warehouse, and legacy ERP systems

    The native ChatGPT Connectors catalogue covers a wide range of applications, but it will never cover everything an enterprise uses. Legacy ERP systems. Custom internal databases. Proprietary data warehouses built on Snowflake or Databricks. Industry-specific tools in healthcare, finance, or manufacturing that are not on any SaaS connector list. This is where the Model Context Protocol (MCP) layer becomes essential.

    What MCP Actually Is and Why It Matters

    The Model Context Protocol is an open standard that defines how AI agents fetch data and perform actions through tool servers. In plain terms, it is the technical specification that allows you to expose any internal system — if you can build an HTTPS-authenticated API endpoint for it — as a connector that ChatGPT can read from and, with the right configuration, write back to.

    For enterprises, this resolves the fundamental limitation of native connectors: the dependency on OpenAI to build and maintain an integration with every system you use. With MCP, you build the server layer yourself, you control the scope of what the model can access and do, and you can implement your own authentication, rate limiting, and audit logging in the process. The MCP connector (now formally called an “app” in ChatGPT’s Enterprise developer mode) is registered with your ChatGPT Enterprise deployment and becomes available to your team as if it were a native connector.

    The Architecture in Practice

    A typical enterprise MCP connector architecture for ChatGPT runs in three layers. The top layer is the ChatGPT interface — the Enterprise plan deployment that your team uses. The middle layer is your MCP server: an HTTPS-authenticated endpoint you build and host, which translates ChatGPT’s requests into queries or actions against your underlying systems. The bottom layer is your internal infrastructure — the CRM, the data warehouse, the ERP, the proprietary database — which the MCP server accesses using your existing internal credentials and access controls.

    The middle layer is where most of the engineering effort lives. A well-built MCP server will implement: scoped access controls (so ChatGPT can only access the data the user is authorised to see), input validation (to prevent prompt injection attacks from reaching your internal systems), action confirmation for write operations, and comprehensive audit logging for compliance. A poorly built MCP server — one that passes raw user inputs directly to internal systems without validation — introduces the same prompt injection risks that make native connectors a concern in sensitive data environments.

    What Custom MCP Connectors Enable That Native Connectors Do Not

    The most significant capability gap that MCP connectors close is bidirectional, unrestricted write access. Where native connectors are largely read-only or limited to specific write operations, a custom MCP connector can expose any action your underlying system supports — updating records, triggering workflows, submitting transactions, even calling external APIs — subject only to the constraints you build into your server logic.

    This opens up workflow categories that are simply not accessible through native connectors: procurement workflows that update ERP purchase orders, finance workflows that query and update budget tracking systems, compliance workflows that pull audit trails from multiple internal systems and generate regulatory reports. The build investment is higher than configuring a native connector, but the capability ceiling is also substantially higher.

    The teams getting the most value from custom MCP development in 2026 are those who have identified two to three high-volume internal workflows where the ROI on build time is clear — typically workflows that combine information retrieval with a specific action that runs hundreds or thousands of times per month — and built focused, purpose-specific connectors rather than trying to expose every internal system at once.

    The Limitations Teams Keep Hitting — An Honest Account

    Any assessment of ChatGPT Connectors that does not spend real time on limitations is either a marketing document or a productivity post written before anyone tried to use the feature in anger. Here is where the real friction lives.

    Read-Only Is the Default — and It Bites

    For most native connectors, read-only is not a setting you can turn off — it is the default mode of operation. GitHub, Google Drive, Calendar, and similar integrations are described in OpenAI’s own documentation as essentially read-only in their native form. You can search, fetch, and summarise, but you cannot directly edit a Google Doc through the connector, you cannot delete a GitHub issue, and you cannot update a SharePoint page.

    This surprises teams who assume connector access means full programmatic access. It does not. If your workflow requires write access to these systems natively — outside of the specific write actions that are explicitly supported — you need to route through an automation platform integration (Zapier, Make, Power Automate) or build the write capability into a custom MCP connector.

    Context Window Size and Multi-Connector Queries

    When you query multiple connectors simultaneously, the data returned from each connector competes for space in the model’s context window. For most straightforward queries this is not an issue. For complex deep research prompts that try to pull large volumes of data from three or four connected sources simultaneously, you can hit context limits that cause the model to truncate or miss data from later sources in the retrieval chain. The mitigation is to structure complex multi-connector queries as sequential focused queries — one connector at a time — rather than attempting to pull everything in a single prompt.

    Connector Reliability Varies by Source

    Native connector reliability is not uniform. Connectors for Google Workspace and Microsoft 365 tend to be the most stable and fastest. Third-party and less common connectors can be slower, hit rate limits, or return inconsistent results depending on the source system’s API reliability. Teams building time-sensitive workflows — anything that runs as part of a meeting or a live customer interaction — should test their specific connector configuration under realistic load before relying on it in production.

    Single-Source Search Limitation

    A commonly cited operational frustration is that connector search queries, outside of the Deep Research mode, tend to work best one source at a time rather than simultaneously across all connected sources. The multi-source synthesis that Deep Research mode enables is not the default behaviour in standard chat mode with connectors active. Standard chat with connectors enabled will typically search the most recently active or most contextually relevant connector for a given query, not all connected sources in parallel. Teams that discover this after assuming all queries would span all connectors often need to revisit their workflow design.

    Regional Availability Gaps

    Not all connectors are available in all regions. Enterprise deployments in certain geographies — particularly in parts of the EU, APAC, and the Middle East — may find that specific connectors are unavailable or operate under data residency constraints that affect what can be connected and how data is handled. This is an operational constraint that should be checked early in any regional deployment planning rather than discovered after contracts are signed.

    Data Privacy and Governance: What Your Plan Tier Actually Determines

    Data privacy risk infographic for ChatGPT Connectors showing four key concerns: read-only limitations, prompt injection risk, data training policy by plan tier, and regional availability gaps

    The governance question around ChatGPT Connectors is not abstract. It has concrete implications for whether the data your team feeds through connected apps can end up training OpenAI’s models, who within your organisation can access what through a shared ChatGPT deployment, and how you would demonstrate compliance if a regulator asked you to account for how sensitive data was processed.

    The Plan-Tier Data Policy Split

    OpenAI’s data use policy creates a clear divide by plan. For Business, Enterprise, and Edu plans, data processed through connected apps is not used to train OpenAI’s models. That is a firm commitment that enterprise teams can cite in their data processing agreements and vendor assessments. For Free, Plus, and Pro plans, data may be used to improve models if the user has model improvement enabled in their settings — the default varies and should be checked explicitly.

    This is not a subtle distinction. If your team is running connector workflows on a Pro or Plus plan and model improvement is enabled, information from your connected Google Drive, HubSpot, or Slack workspace is potentially being used as training data. For most personal productivity workflows this is acceptable. For anything touching customer data, proprietary business information, financial data, or regulated personal information, it is likely not acceptable and may violate your obligations under GDPR, CCPA, HIPAA, or sector-specific regulations.

    The practical governance advice is straightforward: use Enterprise or Business plan for any connector deployment that touches business-sensitive data. Document that decision as part of your AI governance framework. Do not allow team members to replicate Enterprise-level workflows on personal Plus accounts to work around the plan cost.

    Prompt Injection: The Risk That Scales With Connector Scope

    Prompt injection — where malicious content in a connected data source attempts to override the model’s instructions — is a real and growing concern as connector scope expands. The attack vector is simple to describe: a bad actor plants a specially crafted instruction in a document, email, or database record that ChatGPT is likely to read through a connector. When the model ingests that content, the injected instruction attempts to alter the model’s behaviour — exfiltrating data to an external URL, generating misleading outputs, or bypassing confirmation steps for write actions.

    Native connectors mitigate this to some degree through content sandboxing, but the risk does not disappear. For custom MCP connectors, input validation in the server layer is the primary defence — never passing raw retrieved content directly into the model context without sanitisation. For native connectors, keeping connector scope narrow (connecting only the specific data sources a workflow needs, not every possible source) reduces the attack surface. Teams with high-sensitivity data environments should treat prompt injection as a genuine threat model, not a theoretical concern.

    Access Control and Least Privilege

    A principle of least privilege applies to connector configuration just as it does to any other access control framework. Connectors should be granted the minimum scope of access required for the specific workflow they support. A connector built to support sales pipeline review does not need access to HR documents or financial records. A connector supporting engineering onboarding documentation does not need write access to the production code repository.

    In practice, teams often connect the broadest available scope during setup (because it is easier) and then leave it wide. This is the connector governance equivalent of giving every employee admin access because it is less work than configuring individual permissions. It creates unnecessary risk and complicates compliance documentation. Building narrow, purpose-specific connector configurations from the outset is more work upfront and significantly better practice.

    ChatGPT Connectors vs. Zapier, Make, and Power Automate: Choosing the Right Layer

    Comparison chart showing ChatGPT Connectors vs Zapier vs Make vs Power Automate with app ecosystem size, best use cases, and AI-native capabilities for 2026

    This comparison comes up in almost every conversation about deploying ChatGPT Connectors at scale, and it is usually framed as a competition — which platform should you use? The more useful framing in 2026 is about layers: these tools are not competing for the same function, and the most effective workflow architectures often use more than one of them simultaneously.

    What Each Platform Is Actually Good At

    Zapier leads the automation platforms on breadth. With over 9,000 connected apps, the fastest setup for non-technical users, and AI-assisted workflow design, Zapier is the right choice when the priority is connecting the widest possible range of tools with minimum engineering effort. If your workflow involves an app that is not in ChatGPT’s native connector catalogue, Zapier probably has it. The limitation is cost at high-volume automation scenarios and the relative complexity of multi-step, conditional logic-heavy workflows.

    Make (formerly Integromat) is the strongest option for complex, high-volume automation with sophisticated conditional logic. Its visual workflow builder handles branching, looping, and error handling more elegantly than Zapier for multi-step workflows, and its pricing model is more favourable for high-operation-count scenarios. Teams with custom, non-standard workflow logic that would require a Zapier “Paths” configuration with multiple nested conditions typically find Make more maintainable.

    Power Automate is the native choice for Microsoft 365-centric enterprises and any organisation with significant governance and compliance requirements. Its deep integration with the Microsoft stack — Teams, SharePoint, Dynamics, Azure — makes it the obvious default for organisations that have standardised on Microsoft. Its AI Builder component is increasingly capable, and its governance controls are more mature than the other options for regulated industries.

    ChatGPT Connectors are not a replacement for any of these. They are the AI reasoning and orchestration layer that sits on top of them. When you connect ChatGPT to Zapier, you are using ChatGPT’s language understanding to decide what Zapier should execute. When you connect ChatGPT to Power Automate, you are adding natural language control and synthesis capability to workflows that Power Automate runs. The most powerful implementations in 2026 use ChatGPT as the intelligent interface layer while relying on dedicated automation platforms for the actual cross-system execution at scale.

    When ChatGPT Connectors Alone Are Sufficient

    There is a class of workflow where ChatGPT Connectors alone — without an underlying automation platform — are the right and sufficient choice. These tend to share three characteristics: they are human-in-the-loop (a person is reviewing and approving at each step), they are moderate volume (not thousands of operations per day), and they benefit significantly from natural language generation in the output (not just data transfer).

    The sales pipeline review, meeting brief generation, and knowledge base query workflows described earlier all fit this profile. They are tasks where a human is present in the workflow, the volume is manageable, and the quality of the synthesised language output matters. Automated lead routing that processes 500 inbound leads per day does not fit this profile — it needs an automation platform underneath it.

    The Layered Architecture That Sophisticated Teams Are Using

    The architecture that is emerging among the most sophisticated connector deployments in 2026 uses three layers: the automation platform (Zapier, Make, or Power Automate) as the backbone that handles trigger logic, conditional routing, and high-volume execution; ChatGPT with Connectors as the reasoning and synthesis layer that generates outputs, makes decisions based on context, and interacts with humans in natural language; and MCP custom connectors as the bridge to internal systems that neither ChatGPT nor the automation platform natively supports.

    Building all three layers is not necessary for every workflow — start with the simplest configuration that solves the problem, and add layers only when you hit a ceiling that a simpler setup cannot clear. But understanding that this three-layer architecture exists, and which layer is responsible for what, saves teams from trying to make ChatGPT Connectors alone do jobs that require an automation platform, or building expensive MCP custom connectors for apps that already have mature native integration.

    The Workflow Wins Worth Prioritising This Week

    The honest conclusion about ChatGPT Connectors in mid-2026 is that the platform is more capable than most teams are using it for, more limited than some promotional coverage suggests, and more strategic in the decisions it requires than a simple feature checklist reveals.

    The wins are real. Teams are saving 40 to 60 minutes per worker per day on search and synthesis tasks. Sales operations teams are recovering deals that used to fall through the cracks and seeing measurable conversion improvements. Engineering teams are compressing onboarding timelines. Knowledge workers are accessing institutional memory that used to be effectively invisible. These are not theoretical gains — they are happening in production, in identifiable workflow categories, through specific connector configurations.

    The limitations are equally real. Read-only by default. Inconsistent multi-source query behaviour in standard chat mode. Plan-tier governance that genuinely matters for sensitive data. Prompt injection as a non-trivial threat surface. Regional availability constraints that affect enterprise deployments in certain geographies.

    The Four Workflows to Start With

    If you are deciding where to begin — or where to expand — these four workflows have the clearest ROI track record and the most manageable setup complexity:

    • Pipeline hygiene review: Connect your CRM (HubSpot natively, Salesforce via MCP) and run a weekly stalled-deal review with automated outreach drafts. Setup time: two to four hours. Time saved: two to four hours per week per ops person.
    • Meeting brief generation: Connect CRM plus Gmail plus web search. Pre-call research brief on demand. Setup time: one to two hours. Time saved: 20 to 40 minutes per call per sales rep.
    • Internal knowledge query: Index your Notion or Confluence workspace via the connector and provide the team with a natural language interface for internal documentation. Setup time: four to six hours including index configuration. Context-switching reduction: significant and immediate for research-heavy roles.
    • Status report drafting: Connect your project management tool (Notion, GitHub, Asana) and automate weekly status update drafts. Setup time: two to three hours. Time saved: 45 minutes to two hours per project manager per week.

    What to Audit Before You Build

    Before deploying any connector workflow that touches business-sensitive data, run through this checklist: confirm your team is on Business or Enterprise plan (not Plus or Pro); review which data sources the connector needs access to and configure the minimum required scope; document the data types being processed and check them against your organisation’s data classification policy; identify any write actions in the workflow and confirm the confirmation/approval step is functioning as expected; and if you are building a custom MCP connector, ensure input validation and audit logging are in place before connecting to production systems.

    The Bigger Picture

    What the Connectors trajectory in 2026 signals is a shift in what ChatGPT is fundamentally for. It is not settling into a role as a writing assistant or a question-answering tool, though it can still do both. It is becoming the intelligent interface layer on top of the applications and data sources that organisations already run — a place where natural language queries produce synthesised, contextualised, actionable outputs that no single source system could generate on its own.

    That is not where it arrived — it is where it is heading, measurably and week over week. The teams positioned to benefit the most from that trajectory are not the ones waiting for the platform to mature further. They are the ones building now, in the workflow categories where the ROI is clear, with governance configurations that will not bite them when the capabilities expand further. The wins this week are real. The infrastructure you build around them is what determines whether those wins compound.

  • Why Your Product Images Are Invisible to Alexa for Shopping — and the Legibility Fixes That Change That

    Why Your Product Images Are Invisible to Alexa for Shopping — and the Legibility Fixes That Change That

    Split-screen comparison showing illegible Amazon product infographic versus AI-readable redesign with bold high-contrast text — IF ALEXA FOR SHOPPING CAN'T READ YOUR IMAGES, YOU'RE INVISIBLE

    There is a peculiar irony running through a large slice of Amazon’s seller base in 2026. Brands spend real money on professional photography, graphic design, and creative direction to build image stacks they believe are doing heavy lifting on their listings. The product looks sharp. The infographic slides look polished. The lifestyle shots look aspirational. And then Alexa for Shopping — Amazon’s AI shopping assistant, which now mediates the discovery experience for hundreds of millions of shoppers — reads approximately none of the text inside those beautiful images.

    Not because the AI is unsophisticated. It is, in fact, highly sophisticated. The problem is that sophistication does not compensate for bad input. When your text overlays use decorative script fonts at 14px, when your callout copy sits in light grey on a white background, when your comparison table is rendered over a busy lifestyle photograph — the OCR layer that feeds the AI assistant fails silently. No error message. No notification in Seller Central. Just a quiet, invisible gap between what your images say and what the AI assistant actually registers.

    Industry practitioner data suggests this affects roughly 40% of seller images currently live on Amazon. That means four out of ten image slides in the average product listing are contributing zero textual signal to the system now ranking and recommending your products. The features you paid to showcase, the benefits you need shoppers to understand, the differentiators your brand spent years developing — they exist in your images, but not in Amazon’s model of your product.

    This article is about fixing that. Specifically, it covers the technical mechanics of how Amazon’s AI stack reads (or fails to read) product images, the design and content decisions that determine OCR success or failure, and the structured approach to rebuilding your image stack so that every slide contributes legible, indexable, AI-useful information.

    From Rufus to Alexa for Shopping — What Actually Changed on May 13, 2026

    For most of 2024 and 2025, Amazon’s AI shopping assistant was called Rufus. It launched as a conversational chatbot embedded in the Amazon app, answering shopper questions about products, comparing options, and surfacing recommendations through natural language queries. Sellers learned to optimize their listings for Rufus, and a cottage industry of “Rufus optimization” guides emerged.

    On May 13, 2026, Amazon retired the Rufus brand and folded its technology into a unified experience called Alexa for Shopping. The rebrand was more than cosmetic. Alexa for Shopping is designed as an agentic assistant — meaning it does not just answer questions, it can take purchasing-adjacent actions, surface recommendations proactively, compare products across multiple attributes simultaneously, and sit inside the search bar, product pages, the Amazon Shopping app, and Echo Show devices simultaneously.

    What This Means Practically for Sellers

    The core capability that sellers need to understand remains consistent from Rufus to Alexa for Shopping: the assistant uses multimodal AI to process product listings. That means it does not just read your title, bullets, and description. It also ingests your images, your A+ content, and your customer reviews, fusing all of those signals together to determine how well your product matches a given shopper’s intent.

    What changed with the May 2026 transition is scope and surface area. Alexa for Shopping is no longer a sidecar chatbot — it is now woven into the core search experience. When a shopper searches for “insulated travel mug that keeps coffee hot for 8 hours,” the AI assistant is not just filtering results by keyword match. It is actively reading product listings — including image content — to determine which products best answer that specific query.

    The implication for image legibility is direct: more shopper queries now flow through an AI layer that reads images. A higher percentage of your organic discovery now depends on whether the AI can extract usable signals from your visual content. The text you buried in a 12px italic font on slide three of your image stack is not a minor design choice. It is a data quality decision that affects how the AI models your product.

    The No-Prime Expansion Factor

    Alexa for Shopping also removed the Prime requirement that previously limited Rufus access. The assistant is now available to all Amazon shoppers regardless of subscription status. That expands the pool of queries running through AI-mediated discovery considerably — and it means the image legibility problem is not an edge case affecting a niche set of searches. It is a mainstream visibility issue for any seller whose products get surfaced through AI-assisted queries.

    How the Multimodal Stack Actually Reads Your Images

    Three-layer technical diagram showing how Amazon Alexa for Shopping reads product images: OCR text extraction, computer vision via Rekognition, and Vision-Language Model fusion into ranking signal

    Understanding why image legibility matters requires understanding the technical pipeline that processes your images before any AI assistant ever “sees” them. Amazon does not use a single model to read product images. It uses a layered stack, and each layer has different failure modes.

    Layer 1: OCR — Optical Character Recognition

    The first pass on any product image is OCR. Amazon uses Amazon Rekognition — its own computer vision service — to extract text from images. Rekognition scans every pixel for character patterns, attempts to reconstruct words and phrases, and hands that extracted text off to downstream systems.

    This is where most legibility failures happen. OCR is not magic. It is a pattern-matching system that performs reliably when the input is clean and degrades predictably when the input is noisy. The primary factors that determine OCR success or failure are: text size relative to image resolution, contrast ratio between text and background, font style complexity, text orientation, and the degree to which text overlaps with busy visual elements.

    When OCR fails to extract your text, the downstream systems — including the ranking models and the AI assistant — receive no information about what that text said. The feature claim you highlighted in slide four simply does not exist in Amazon’s representation of your listing. It is as if you never wrote it.

    Layer 2: Computer Vision via Amazon Rekognition

    Alongside OCR, Amazon Rekognition runs object detection, scene classification, color analysis, and compositional analysis on every product image. This layer answers questions like: What type of product is this? What is the dominant color? Is this a lifestyle shot or a white-background product image? Are there people in this image, and if so, what are they doing?

    This layer is generally more robust than OCR because it does not require text to be present at all — it works on pure visual content. But it interacts with the OCR layer in important ways. An infographic slide where the text fails OCR but the visual context is clear gives the system partial information: it knows the image exists and something about its composition, but it cannot extract the specific claims or features you were trying to communicate.

    Layer 3: Vision-Language Models

    The top of the stack is the Vision-Language Model (VLM) — the component that most closely resembles what we think of when we imagine “AI reading an image.” The VLM takes the outputs from OCR and computer vision as inputs and fuses them with the listing’s structured text data (title, bullets, attributes) and review data to construct a unified model of what the product is, what it does, and which shopper queries it is likely to satisfy.

    This is the model that ultimately informs Alexa for Shopping’s recommendations. When a shopper asks “what’s the best yoga mat for bad knees?” the VLM is drawing on a representation of each relevant product that includes — when the image stack is legible — the text claims from your infographic slides, the visual attributes detected in your product photos, and the structured keywords in your copy.

    When image text fails OCR at Layer 1, the VLM receives an impoverished representation. It can still work with your structured text data, but it has lost a meaningful input channel. In competitive categories where multiple products have similar structured text, the brands whose image text is successfully extracted by OCR have a structural advantage in how richly the AI model represents their product.

    The 40% OCR Failure Rate — What It Is, Why It Happens, and What You’re Losing

    Bar chart showing the 40% OCR failure problem — optimized images at 95% success vs typical seller images at 60%, with the three main failure causes: font too small, low contrast, stylized script font

    The 40% figure is not Amazon’s published statistic — Amazon does not publicly report on image OCR performance. It comes from practitioner analysis of Amazon Rekognition’s behavior across large seller catalogs, and it is consistent enough across multiple independent sources that it represents a reasonable working estimate for the scale of the problem.

    The more important question is not the exact number. It is understanding which specific design decisions cause OCR to fail — because those failures are almost entirely preventable.

    Failure Mode 1: Text That Is Too Small at Upload Resolution

    Amazon recommends uploading product images at a minimum of 1,000 pixels on the longest side, with 2,000 pixels or higher as the recommended standard for zoom functionality. OCR systems work on pixel data. A text label that appears “readable to a human” when viewed at normal zoom can sit at 18px effective height in the raw image file — below the threshold where Rekognition reliably extracts characters.

    The practical threshold from current practitioner guidance is a minimum of 24 pixels of rendered text height at the uploaded image resolution, with 36 pixels or higher as the recommended standard for reliable extraction. On a 2,000px wide image, that means headline text occupying considerably more vertical space than many current listing infographics allow.

    The failure pattern is consistent: sellers design their infographic slides on a 1080px canvas in Photoshop or Canva, viewing it at 100% zoom on a large monitor. The text looks fine. They export and upload. But at the resolution Amazon processes for OCR, the body copy is effectively invisible to character recognition.

    Failure Mode 2: Insufficient Contrast

    OCR systems rely on contrast to distinguish characters from their background. The Web Content Accessibility Guidelines (WCAG) define a minimum contrast ratio of 4.5:1 for normal text legibility — a threshold that also maps closely to the minimum contrast level at which Amazon Rekognition reliably extracts text from images.

    Common contrast failures in Amazon seller images include: light grey text on white backgrounds, white or cream text on pastel-colored panels, text that overlaps with gradient transitions in lifestyle photographs, and brand-colored text where the brand palette was chosen for aesthetic rather than accessibility reasons.

    The contrast problem is compounded by JPEG compression. Amazon re-compresses uploaded images, and compression artifacts reduce effective contrast at character edges — meaning an image that barely passes a contrast threshold at upload may fall below it after Amazon’s processing pipeline.

    Failure Mode 3: Decorative and Script Fonts

    OCR systems are trained on the distribution of fonts that appear in real-world text. They handle common sans-serif and serif typefaces extremely well. They handle script, display, handwritten, and heavily stylized fonts poorly to catastrophically.

    A brand that uses a custom calligraphic font for its headline copy, or a decorative serif with extreme weight variation, is asking the OCR system to solve a character recognition problem it was not optimized for. The system may extract garbled text, partial words, or nothing at all. From the AI’s perspective, that beautifully branded headline callout is noise.

    Failure Mode 4: Text Over Busy Backgrounds

    Placing text on top of lifestyle photography — a product in use, a model, an outdoor scene — creates a highly variable background that makes character segmentation difficult. Even at high contrast on average, the local contrast at individual character edges may be insufficient for reliable extraction. This is why the most OCR-reliable infographic layouts use solid or near-solid color panels behind text rather than relying on drop shadows, glows, or partial transparency to create legibility.

    What You’re Losing When OCR Fails

    When an infographic slide’s text fails OCR, the specific feature claims, benefit statements, and differentiating attributes in that slide do not get added to the AI’s representation of your product. For a product like a protein powder where the critical purchase factors — flavor, protein content per serving, sweetener type, protein source — are typically communicated in infographic slides rather than structured attributes, OCR failure can leave the AI with a materially incomplete picture of what makes your product relevant.

    The downstream consequences include: the AI assistant answering shopper queries without being able to reference information that was in your images; your product failing to surface in intent-based queries that your image text would have satisfied; and in competitive categories, rivals with better OCR compliance getting credited with signals that your listing technically contains but cannot effectively communicate.

    The Main Image Rule: Why Text-Free Remains Non-Negotiable

    Before discussing how to make image text legible, it is worth being precise about where image text belongs at all. Amazon’s product image policy is unambiguous on the main image: it must show the product on a pure white background with no text overlays, no logos in the frame (other than on the product itself), no badges, and no additional props or elements.

    This rule exists for multiple reasons, but from an AI-readability perspective it is actually a feature rather than a constraint. The main image slot is where Amazon’s computer vision system performs its most confident product classification. A clean white-background product shot gives the visual system clear signal about what the product is, its shape, its dominant colors, and its physical form factor. Clutter — including text — degrades that signal.

    Where Text Belongs and Where It Doesn’t

    The hierarchy for Amazon image text placement in 2026 is as follows:

    • Main image: No text. No exceptions. Violations risk listing suppression and lose you the clean visual classification signal.
    • Secondary images (slots 2–7): Text overlays are permitted and, when properly executed, are actively valuable. These are your infographic slides, benefit callouts, comparison images, and use-case demonstrations.
    • A+ Content modules: Text in A+ is processed by the VLM layer and can contribute meaningful signals, particularly in comparison tables and benefit modules. More on this below.
    • Amazon Stores: Image tiles in Stores have specific size specifications (3,000×1,500px for full-width tiles) and text overlay guidance that aligns with general OCR best practices.

    The practical implication is that your text legibility effort should be concentrated in secondary image slots 2–7 and your A+ content. Those are the surfaces where text is both allowed and actively useful for AI indexing — and where most current sellers are failing silently.

    Secondary Images as Structured Data: The New Way to Think About Infographic Slides

    Before and after comparison of Amazon product infographic slide — cluttered illegible design versus clean dark-panel design with bold white benefit callout text readable by AI and shoppers alike

    The most significant mindset shift available to Amazon sellers in 2026 is treating secondary image slots not as design canvases but as structured data entry points. This reframing has practical consequences for every decision you make about what goes in those slides and how it is presented.

    In the old model, a secondary image slide existed to persuade a shopper who had already clicked on your listing. Its job was emotional and visual: make the product look good, make the brand feel premium, communicate aspirational value. Design instincts optimized for these goals produce images that are often beautiful and often OCR-incompatible.

    In the current model, the secondary image slide serves two simultaneous audiences: the human shopper browsing your listing, and the AI system indexing your product. Those two audiences have different but largely compatible requirements. Humans need clarity, hierarchy, and visual appeal. The AI needs extractable text, meaningful semantic content, and consistency with your listing’s other data. Designing well for both is not a compromise — it is a discipline.

    Thinking About Slides as Database Fields

    Consider reframing each secondary image slot as an entry in a structured product database. If you were writing a database record for your product, what fields would you populate? Key ingredients or materials. Primary use cases. Quantified performance claims. Certifications and compliance. Comparison against the product it replaces. Size and dimension data. Compatibility information.

    Each of those “fields” maps directly to a high-value infographic slide. And each slide, if its text is legible, adds that field’s content to the AI’s representation of your product. The AI can then use those fields to match your product to relevant queries it might otherwise have missed.

    A protein powder listing with a legible “26g Protein Per Serving — No Artificial Sweeteners” callout in slide three gives the AI a precise, extractable data point. When a shopper asks Alexa for Shopping “what protein powder has no artificial sweeteners?” the AI has a signal to draw on. If that callout is in a 14px script font on a gradient background, that signal does not exist in the AI’s model of your product — even though you put it there.

    Content Priority for Each Slot

    With six secondary image slots available (and more with enhanced listings), a structured approach to slot allocation produces better AI signals than a purely creative one. A high-performing secondary image stack typically follows this hierarchy:

    1. Slot 2: The single most important purchase factor for your category — the one claim that most directly answers the primary shopper question. Make this the clearest, most legible slide in your entire stack.
    2. Slot 3: The second key purchase factor, or a quantified performance claim that supports slot 2.
    3. Slot 4: Ingredients, materials, certifications, or compliance information — particularly high value for categories where these are active shopper concerns.
    4. Slot 5: Use case or lifestyle context, with a text overlay that states the use case explicitly rather than relying on visual inference alone.
    5. Slot 6: Comparison, either against your own product variants or against the category standard (framed as benefit, not competitive attack, to avoid policy issues).
    6. Slot 7: Social proof anchor or brand story element that reinforces trust signals already present in your reviews.

    This is not a rigid template — category context matters significantly. But the underlying logic — allocating each slot to a specific, meaningful data point rather than a vague benefit statement — is consistent regardless of category.

    The Technical Legibility Stack — Font, Contrast, Size, and Hierarchy

    Typography contrast ratio reference chart for Amazon sellers — showing contrast ratios from 1:1 (invisible to OCR) through 4.5:1+ (WCAG AA compliant and OCR-reliable), with minimum font size guidance of 24px at upload resolution

    Now the specifics. The following technical parameters are derived from Amazon Rekognition’s documented OCR behavior, WCAG accessibility standards (which correlate strongly with OCR reliability), and practitioner testing across large catalog sets. These are not theoretical recommendations — they represent the thresholds at which OCR success rates shift materially.

    Font Selection

    Recommended: Clean sans-serif typefaces. Inter, Helvetica Neue, Montserrat, Source Sans, Open Sans, and their equivalents perform reliably in OCR extraction. These fonts have consistent stroke weights, clear character differentiation, and minimal ambiguity between similar letterforms (e.g., I, l, 1).

    Acceptable with care: Heavier-weight serif typefaces with consistent stroke widths. Fonts like Playfair Display at heavy weights or Georgia Bold can perform adequately, but they introduce more OCR uncertainty than their sans-serif equivalents.

    Avoid: Script fonts, handwritten fonts, ultra-thin weight variants of any typeface, condensed fonts at small sizes, and any custom brand font with unusual letterforms. If your brand guide requires a custom font, use it for hero elements only (large, single-word headlines) and fall back to a standard sans-serif for all substantive content text.

    Weight consideration: Use Medium (500) to ExtraBold (800) weight variants for body copy in infographics. Ultra-light variants (100–300) consistently underperform in OCR extraction regardless of size, because thin stroke widths create insufficient contrast at character edges after JPEG compression.

    Contrast Ratio

    The WCAG AA standard for normal text is a contrast ratio of 4.5:1. For large text (18px+ or 14px+ bold), the minimum is 3:1. These thresholds also represent the practical boundary for reliable Amazon Rekognition OCR extraction.

    In practice, aim higher. A contrast ratio of 7:1 or above — which is the WCAG AAA standard — provides a meaningful buffer against the contrast reduction introduced by Amazon’s image compression. This means:

    • White (#FFFFFF) text on a dark panel (#1A1A2E or similar) is essentially foolproof.
    • Near-black (#1C1C1C) text on pure white (#FFFFFF) is equally reliable.
    • Brand-colored text on white backgrounds should be verified against a contrast checker before use — many brand palettes produce ratios in the 2:1–3:1 range that fail OCR.
    • Text on lifestyle photo backgrounds requires careful placement to achieve consistent contrast. If you cannot guarantee 4.5:1 across the entire text area, use a solid color panel behind the text instead.

    Text Size at Upload Resolution

    The minimum for reliable OCR extraction is approximately 24 pixels of rendered text height at the uploaded image resolution. At the recommended upload size of 2,000 pixels on the longest side, this translates to headline text occupying roughly 3–5% of the image height, and body copy at a scale that would feel “large” by typical infographic design standards.

    Practical recommendations by content type:

    • Main headline / primary claim: Minimum 60–80px at 2,000px image width. This is your primary OCR target — the most important text in the slide should be the most reliably extracted.
    • Supporting callouts and sub-claims: Minimum 36–48px at 2,000px width.
    • Body copy or list items: Minimum 28–32px at 2,000px width. If your content cannot fit comfortably at this size, reduce the amount of text rather than the font size.
    • Fine print, legal disclaimers, certification badges: Anything below 24px is likely to fail OCR. Move critical compliance information into your listing bullets or description where it will be reliably indexed.

    Text Volume and Hierarchy

    A common design failure is treating infographic slides as a place to say everything at once. The more text you cram into a slide, the smaller each element must be, and the lower the average OCR success rate across the slide. OCR systems also struggle with dense text blocks where character boundaries are close together.

    A better approach: one primary claim per slide, expressed in the fewest words possible, at maximum size. Supporting details in a clearly differentiated secondary tier. Three or four bullet points at most per slide. White space is not wasted space — it is contrast buffer, and it gives the OCR system clear character separation to work with.

    Orientation and Angle

    OCR performs best on horizontally oriented text. Rotated, diagonal, or curved text paths reduce OCR accuracy significantly. If your design includes angled text for visual dynamism, assume that text will not be reliably extracted. Reserve it for purely decorative elements and keep all substantive content claims in standard horizontal orientation.

    A+ Content and the Visual Indexing Opportunity Most Sellers Miss

    Annotated Amazon A+ Content module diagram showing AI indexing opportunity zones: module text indexed by VLM, product comparison table, lifestyle image benefit callout, and brand story copy — labeled A+ Content: Your Most Underused AI Indexing Surface

    Most seller conversations about image legibility focus on the main product image stack — the seven slots visible on the product detail page. But Amazon’s multimodal AI system also processes A+ Content, and that content represents one of the most underused AI indexing surfaces in most sellers’ catalogs.

    A+ Content is processed by the VLM layer of Amazon’s system — the layer that fuses visual and textual signals into a unified product representation. Because A+ Content is brand-registered content with a higher quality signal than user-generated material, it gets meaningful weight in how the AI models the product.

    The Comparison Table Opportunity

    A+ Content’s comparison module — which allows you to compare your product against other ASINs in your catalog — is particularly high-value from an AI indexing perspective. The structured tabular format of comparison data is highly legible to both OCR and the VLM layer. Attribute names and values in a clean table format are essentially ideal structured input for the AI system.

    The mistake most sellers make with comparison modules is treating them primarily as upsell tools — designed to push shoppers toward higher-priced variants. They are also indexing tools. Every row in your comparison table is a structured feature attribute that the AI can use to match your product to relevant queries. Populate the comparison table with attributes that directly correspond to the queries your category shoppers actually ask, not just the attributes that make your premium variant look better.

    Image Modules in A+ Content

    Images embedded in A+ Content modules are subject to the same OCR and VLM processing as product listing images. The same legibility rules apply: high contrast, sufficient size, clean fonts, horizontal orientation, solid color panels behind text. The difference is that A+ Content images tend to be displayed at smaller effective sizes in the rendered page view, which means the resolution and text size requirements are even more critical relative to the finished image dimensions.

    A useful heuristic: design A+ Content image modules as if they will be viewed on a mobile screen at 50% zoom. If the text is still legible at that scale, the OCR system will have no trouble with it. If it requires squinting, it needs to be larger.

    Brand Story Modules and Contextual Matching

    The brand story section of A+ Content is often treated as a brand values page — a place to talk about origin story, mission, and craftsmanship. From an AI perspective, it is also a contextual signal that helps the VLM layer understand the broader product ecosystem and shopper intent your brand serves.

    Brand story copy that includes specific, concrete category language — material types, use contexts, performance characteristics — gives the AI additional context for placing your products in relevant discovery paths. Generic mission statements (“we believe in quality you can trust”) contribute nothing to AI indexing. Specific contextual language (“designed for high-altitude hiking, our insulation technology is tested at temperatures down to -20°F”) gives the AI precise signals to work with.

    What to Write in Your Image Text — Content Strategy, Not Just Design Strategy

    Legibility is a necessary but not sufficient condition for effective image text. The text also has to say the right thing. An OCR system that successfully extracts “OUR AMAZING QUALITY DIFFERENCE” has added very little to the AI’s model of your product. The same system successfully extracting “TESTED TO ASTM F1292 — 6-FOOT FALL PROTECTION” has added a precise, searchable, query-matching signal that could directly determine whether your product surfaces for a highly relevant shopper.

    The Query-Answer Framing

    The most useful framework for writing image text content is to ask: what question does this text answer, and is that the question shoppers in my category are actually asking?

    Amazon’s AI shopping assistant surfaces products in response to natural language queries. Those queries have specific information needs. A shopper asking “best air purifier for pet allergies” needs to know: does this purifier capture pet dander and pet-specific allergens? A shopper asking “protein powder for women over 50” needs to know: is this appropriate for that demographic, and what specific formulation decisions reflect that?

    Your image text should be answering these questions directly and explicitly. Not implicitly through lifestyle imagery and brand aesthetic, but explicitly through text that a query-matching AI can extract and use.

    Precision Over Poetry

    Brand copywriting instincts often push toward evocative, aspirational language. “Elevate your morning routine” is evocative. “KEEP HOT 12 HOURS / KEEP COLD 24 HOURS” is extractable. The AI assistant processes both, but only one of them becomes a usable data point when a shopper asks “which travel mug keeps coffee hot longest?”

    This does not mean your images should read like a spec sheet. It means that the primary claim on each slide should be stated in precise, descriptive language before any evocative framing is added. “ULTRA-SOFT BAMBOO JERSEY — TEMPERATURE REGULATING” serves both the human shopper and the AI. “THE SLEEP YOU DESERVE” serves neither particularly well.

    Numerical Specificity as an AI Signal

    Numbers are exceptionally well-handled by OCR systems and are high-value signals for AI query matching. A product that states “400-THREAD COUNT” in a legible slide has given the AI a precise matchable attribute for “high thread count sheets” queries. A product that shows “SPF 50+ / PA++++” in its sunscreen infographic has given the AI classification signals for multiple protection-level queries.

    Wherever your product has a quantifiable performance claim — capacity, duration, weight, dimensions, concentration, protection level, temperature range — that number should appear in your image text, legibly, in a format the OCR system can extract without ambiguity. Numbers with units beat pure superlatives every time in AI-mediated discovery.

    Consistency with Structured Listing Data

    One final content principle: the text in your images should be consistent with and complementary to the text in your structured listing data. The AI system fuses image text and structured text — if they contradict each other, the system may discount both. If your title says “BPA-Free” but your infographic slide says “Made with Food-Grade Stainless Steel Only — Zero Plastic Components,” the more specific image claim reinforces and extends the title claim rather than conflicting with it.

    Conflicts arise when infographic slides make claims that are absent from structured data entirely — a product marketed as “Keto Certified” in images but with no dietary certification data in the structured attributes, for example. These inconsistencies create uncertainty in the AI’s model of the product and can reduce the confidence with which it surfaces your listing for relevant queries.

    Testing and Validating Your Image Legibility

    Knowing the rules for legible images is one thing. Verifying that your actual images pass is another. There are several practical methods for testing before you go live — and for monitoring after you do.

    Pre-Upload OCR Testing

    Amazon Rekognition is available as a standalone API, and you can test your images against it directly before uploading them to Seller Central. Upload your infographic slides to the Rekognition DetectText endpoint and examine the extracted text blocks. Any text that does not appear in the extraction output will not be available to downstream systems including Alexa for Shopping.

    This is the most direct method for identifying OCR failures pre-upload, and it gives you actionable feedback: you can see exactly which text blocks failed to extract, adjust size and contrast accordingly, and re-test until extraction is complete.

    Third-party tools that wrap this functionality in seller-friendly interfaces are also available, and several major Amazon optimization platforms have added image OCR testing modules to their toolsets in 2026 in response to growing seller awareness of the issue.

    Contrast Ratio Checkers

    Before finalizing any infographic slide, run each text element through a contrast ratio checker. Free web tools allow you to input the exact hex values of your text color and background color and return the precise contrast ratio. Check every text element, not just the headline. A slide where the headline passes at 7:1 but the supporting bullet points sit at 2.8:1 is still a partial OCR failure.

    Manage Your Experiments — The Conversion Validation Layer

    Amazon’s Manage Your Experiments tool allows brand-registered sellers to run A/B tests on product images. This is the right mechanism for validating that legibility-optimized images not only improve AI indexing but also maintain or improve human conversion rates.

    The typical pattern for running image legibility tests: create a variant image set that applies the technical legibility standards above, run a 4–6 week test against your current images, and measure the impact on conversion rate, click-through rate from search, and (if available) organic rank position changes over the test period.

    Sellers running these tests in 2026 consistently report that well-executed infographic improvements lift conversion rates in the 10–30% range relative to plain product photography — consistent with the broader data on secondary image impact. The key “well-executed” qualifier includes legibility as a prerequisite: cluttered, low-contrast infographics do not consistently outperform simpler approaches, and in some cases underperform them by creating visual complexity that discourages shoppers.

    Monitoring After Upload

    After uploading optimized images, monitor your organic visibility metrics over the following 4–8 weeks. Amazon’s catalog indexing and AI model updates operate on a crawl cycle that is not instantaneous — changes you make today may not be fully reflected in AI-mediated discovery for several weeks. This lag means that image legibility improvements produce a delayed visibility effect, which sellers sometimes misinterpret as evidence that the changes did not work.

    Track your brand keyword ranking, non-brand keyword ranking, and (if you have access) the category search terms for which you appear in AI-generated responses. Improvements in non-brand keyword visibility are often the clearest signal that image OCR optimization is working, because non-brand queries rely more heavily on feature-matching signals — the kind of signals your infographic text provides when it is successfully extracted.

    The Silent Compounding Effect — What Legible Images Do to Organic Rank Over Time

    Line graph showing the compounding effect of image legibility on Amazon organic rank over 90 days — optimized OCR-compliant image stack trends steeply upward in green versus unoptimized images staying flat in red, with milestone markers at Week 1 image update deployment, Week 3 crawl cycle, and Week 6 rank velocity improvement

    Individual image optimization produces one-time improvements. A consistent commitment to image legibility across your entire catalog produces something different: a compounding structural advantage that accumulates over time and becomes increasingly difficult for competitors to close.

    Here is why it compounds. Every time Amazon’s system re-crawls and re-indexes your listing, it updates its model of your product based on all available inputs — including image text. A catalog where every secondary image and every A+ content module consistently provides high-quality, legible, semantically meaningful text gives the system more to work with on every crawl cycle. The AI’s confidence in its classification of your product increases with each successful extraction cycle.

    The Relevance Score Feedback Loop

    Amazon’s AI systems operate on relevance scores — continuous assessments of how well a product matches a category of queries. High-confidence, consistent signals (including legible image text that consistently confirms the same product attributes) raise the relevance score for specific query types. Higher relevance scores produce better positioning in AI-mediated discovery responses. Better positioning produces more clicks. More clicks produce better conversion data. Better conversion data raises the relevance score further.

    This is a virtuous cycle that begins with the data quality of your image text. Breaking into that cycle requires nothing more exotic than making sure the text in your images is actually readable by the system that determines whether shoppers find you.

    The Competitive Context

    In most Amazon categories, the majority of sellers have not systematically addressed image OCR compliance. This is not an indictment — the problem was not widely understood until the scale of AI-mediated discovery became apparent in 2025 and 2026. But it means that sellers who move now to implement a legibility-first image strategy are doing so in a competitive environment where most rivals are still losing 40% of their image signals.

    The window for a first-mover advantage here is meaningful but not permanent. As awareness of the issue spreads, more sellers will optimize. The sellers who build the compounding relevance score advantage now will be harder to displace later — but the advantage is only durable if the underlying catalog quality is maintained and updated as Amazon’s requirements and AI capabilities evolve.

    New Products vs. Existing Catalog

    For new product launches, building legibility into the image strategy from the start is significantly less costly than retrofitting an existing catalog. New listings start with no crawl history — the AI system builds its initial model of the product from the first crawl. A new product with a fully legible, well-structured image stack gives the AI a high-quality initial model, which tends to produce better early ranking than listings that require iterative improvement to reach legibility compliance.

    For existing catalog items, the retrofit approach — auditing current images, identifying OCR failures, and uploading corrected versions — produces improvements but requires patience for the crawl cycle to reflect the changes. Prioritize high-volume ASINs and categories where AI-mediated discovery is demonstrably active (categories with high rates of conversational queries) for the first wave of optimization.

    Building the Alexa-Ready Image Audit Process

    Turning the principles above into an operational process requires a structured audit methodology. The following framework is designed to be repeatable across a catalog of any size, from a single-ASIN brand to a multi-thousand ASIN catalog operation.

    Step 1: Image Inventory and OCR Baseline

    Pull all current product images from your Seller Central catalog. Run each secondary image through an OCR extraction test (Amazon Rekognition API or a third-party wrapper). For each slide, record: which text blocks were successfully extracted, which failed entirely, and which were partially extracted with errors. This establishes your baseline OCR compliance rate by ASIN and by slide position.

    Step 2: Prioritization by Impact

    Not all ASINs are equal. Prioritize the audit and redesign effort by: organic sales volume (high-volume ASINs benefit most from ranking improvements), competitive intensity (categories with AI-active shopper queries benefit most from legibility optimization), and OCR failure rate (ASINs with the highest failure rates have the most room for improvement).

    Step 3: Brief Creation for Design Teams

    Before sending images to a designer or design agency, create a structured brief for each ASIN that specifies: the primary claim for each slide (one per slide), the exact text to be used (pre-written, query-aligned content, not left to designer judgment), the technical requirements (minimum font size, minimum contrast ratio, approved font families, no text over busy backgrounds), and the image resolution requirement (minimum 2,000px on longest side).

    This brief-driven approach ensures that the design output is optimized for AI legibility from the start, rather than requiring a second round of corrections after design has been completed to human-centered aesthetics standards alone.

    Step 4: Post-Delivery Verification

    Before uploading any new image, verify: OCR extraction test passes for all substantive text elements, contrast ratio check passes at 4.5:1 minimum for all text (7:1 preferred), minimum font sizes met at delivered resolution, no substantive text appears over busy or variable backgrounds. Only images passing all four checks should be uploaded.

    Step 5: Monitoring and Iteration

    After upload, set a 6–8 week monitoring window. Track organic rank position for 3–5 target keywords per ASIN, click-through rate from search, and conversion rate. At the end of the monitoring window, assess whether improvements match expectations and identify any ASINs where the changes did not produce expected results for further investigation.

    Conclusion: The Legibility Gap Is a Data Quality Problem — Treat It Like One

    The framing of this problem as a “design issue” has caused a lot of sellers to underestimate its strategic importance. Adjusting font sizes and contrast ratios sounds like a minor creative concern. In the context of AI-mediated product discovery, it is a data quality problem — and data quality problems at scale have outsized consequences.

    When approximately 40% of the text in your image stack fails to extract, you are operating with a self-inflicted data gap in how Amazon’s AI models your product. The system is doing its best to match your listing to relevant shopper queries — but it is doing so with less information than you intended to provide. The features you highlighted, the benefits you invested in demonstrating, the differentiators that justify your price point: they are present in your images, but absent from the AI’s representation of your product.

    The fix is not complicated. It requires precision, discipline, and a willingness to prioritize AI legibility alongside human aesthetics in design decisions. The technical thresholds are concrete: 4.5:1 minimum contrast ratio, 24px minimum text height at upload resolution, clean sans-serif fonts, horizontal orientation, solid backgrounds behind text, one primary claim per slide expressed in specific and precise language.

    Implementing those standards consistently across your secondary image stack and A+ content does not require a major creative overhaul. It requires treating every image slot as a data entry point as well as a visual communication tool — and verifying, before upload, that the data you intended to enter is actually what the system receives.

    Alexa for Shopping is reading your images. The only question is whether it can actually read them.

    Quick-Reference Checklist

    • ☐ Main image: no text, pure white background, product only
    • ☐ Secondary images: each slide has one primary claim, stated in precise language
    • ☐ Minimum font size: 24px at uploaded image resolution (36px+ recommended)
    • ☐ Minimum contrast ratio: 4.5:1 (7:1+ recommended for body copy)
    • ☐ Font choice: clean sans-serif for all substantive content (no script, no ultra-thin weights)
    • ☐ Text orientation: horizontal only for all extractable content
    • ☐ Background: solid color panels behind text, not lifestyle photos
    • ☐ Image resolution: minimum 2,000px on longest side
    • ☐ OCR pre-test: run Rekognition DetectText before uploading
    • ☐ Contrast pre-test: verify all text elements against a contrast ratio checker
    • ☐ A+ content: apply same legibility standards to all image modules
    • ☐ A+ comparison table: populate with query-aligned attributes, not just upsell positioning
    • ☐ Content consistency: image text claims consistent with structured listing data
    • ☐ Monitor post-upload: track organic rank and CTR over 6–8 week crawl window
  • SBV Budget Rebalancing: When Video Should Eat Search

    SBV Budget Rebalancing: When Video Should Eat Search

    SBV Budget Rebalancing: When Video Should Eat Search — split screen showing fading search ads and a bright product video playing on an Amazon search page

    Most Amazon PPC accounts are built on the same unspoken assumption: Sponsored Products is the engine, and everything else exists to support it. Sponsored Brands Video gets a sliver of budget — enough to say it’s being tested, not enough to actually pressure-test whether it should own a larger share. That assumption made complete sense in 2021. In 2026, it is quietly costing brands significant money every month they leave it unchallenged.

    The economics of Amazon search have shifted. Sponsored Products CPCs have climbed roughly 48% cumulatively since 2019, with competitive categories absorbing 10–15% annual increases that in some verticals reach 25–35% year-over-year. More budget into SP no longer reliably buys more proportional reach or sales. Instead, it increasingly buys position maintenance — defending placements brands already hold against competitors willing to outspend them by a few cents more per click.

    Sponsored Brands Video, meanwhile, has moved from experimental format to dominant Sponsored Brands strategy. Advanced accounts now route 80–95% of their SB spend into SBV, and aggregate data from Q1–Q2 2026 shows SBV delivering approximately 1.6× the click-through rate and 1.3× the conversion rate of static Sponsored Brands. New-to-brand customer acquisition data — which SP campaigns simply cannot surface — reveals an entirely different story about where incremental growth is actually coming from.

    The question in 2026 is not whether video should take more of your search budget. The question is when — and what signals, metrics, and structures should govern that decision. This post works through all of it.

    The CPC Squeeze: What’s Actually Happening to Sponsored Products Economics

    Before you can make a rational case for moving budget out of Sponsored Products, you need to understand exactly what those rising CPCs are buying — and, more importantly, what they are no longer buying at the margin.

    The cost trajectory since 2019

    Amazon’s auction model for Sponsored Products has compressed advertiser efficiency consistently over the past several years. CPCs that averaged under $0.90 in many categories in 2019 now commonly land between $1.05 and $1.65 across mid-competition verticals, with high-competition categories — consumer electronics, supplements, home goods — pushing well beyond $2.00 for top placements on core keywords.

    The cumulative 48% CPC increase across the SP ecosystem since 2019 is not evenly distributed. Branded and category-defining keywords have absorbed the steepest increases, because these are the terms where auction pressure concentrates. Every established brand in a category is bidding on the same short-tail terms. The winner pays more than they did last year for the same position, and the loser goes back to the drawing board to figure out whether to overspend on defensive bidding or accept the erosion.

    What diminishing marginal returns looks like in practice

    Diminishing returns in SP aren’t always visible in the headline ROAS number — which is precisely why they’re dangerous. A Sponsored Products campaign can show a stable 4× ROAS while every additional dollar of budget added to it earns a 2× marginal return. The average looks fine. The marginal reality is quietly terrible.

    The clearest symptom is budget utilization behavior: campaigns that used to run out of budget by 11am now pace through the full day without exhausting their allocation, yet conversion volume hasn’t increased proportionally. This pattern signals that the algorithm is spending more carefully because incremental impression opportunities at acceptable CPCs are genuinely scarce. More budget cannot create more qualified search intent. It can only compete more aggressively for the intent that already exists — which, in a saturated category, means paying more to reach audiences that have already been heavily targeted.

    Position defense is not growth

    There is an important distinction between SP spend that acquires customers and SP spend that defends position. When a brand has established organic rank on its core keywords and runs SP to maintain those placements against competitor conquesting, a significant portion of that budget is effectively insurance rather than acquisition. That’s not inherently wrong — competitive defense has real value. But treating defensive SP spend and growth-oriented SP spend as a single undifferentiated pool is what causes accounts to chronically underinvest in formats that can actually expand the customer base.

    Recognizing the split between defensive and acquisitive SP spend is the first analytical step toward a rational SBV rebalancing conversation.

    Side-by-side comparison of Amazon Sponsored Products vs Sponsored Brands Video — CTR, CVR, new-to-brand reporting, and what each format actually buys

    SBV vs. SP: Understanding What Each Format Is Actually Buying You

    The mistake most advertisers make when comparing Sponsored Brands Video to Sponsored Products is treating them as substitutable formats competing for the same objective. They are not. They operate at different points in the shopping funnel, they deliver different types of value, and they should be evaluated on different metrics. Conflating them in a single ROAS comparison produces misleading conclusions in both directions.

    What Sponsored Products is purpose-built for

    Sponsored Products is, fundamentally, an intent-capture engine. When a shopper types “noise cancelling headphones under $100” into Amazon’s search bar, SP intercepts that expressed, bottom-of-funnel intent and places your product in front of someone who has already decided what category they’re buying from and roughly what they’re willing to spend. The conversion efficiency is high because the qualification work has already been done by the shopper’s own search behavior.

    This is why SP consistently posts higher direct ROAS than SBV in last-click attribution models. It’s not that SP is better at advertising — it’s that SP is fishing in a pond stocked with fish that are already hungry. The format deserves credit for execution, but the underlying demand isn’t being created by the ad. It existed before the ad appeared.

    The ceiling of SP efficiency is therefore largely determined by the volume of existing search intent in your category. Once you’ve captured the efficient portion of that intent, additional SP spend competes for diminishing returns: lower-intent queries, less-qualified audiences, and expensive defensive placements.

    What Sponsored Brands Video is actually doing

    SBV operates differently. It appears in the search results environment — same page, same intent context — but it functions more like an awareness and consideration tool than a pure intent-capture mechanism. The video format interrupts the browsing session in a way that a static text-and-image ad cannot. It communicates product context, brand story, and key differentiators within the first three seconds of autoplay, before the shopper has consciously decided to engage.

    That interruption capability is what produces SBV’s 1.6× CTR advantage over static Sponsored Brands. Shoppers who weren’t specifically looking for your brand get pulled into an evaluation they might otherwise have skipped. And because video conveys more information faster than a static thumbnail, the shoppers who do click arrive at the product detail page better informed — which supports the 1.3× CVR lift relative to static formats.

    Critically, SBV’s impact doesn’t stop at the direct conversion. Amazon’s new-to-brand reporting — available for Sponsored Brands formats but not Sponsored Products — reveals that SBV consistently drives a higher proportion of NTB customers than SP. These are shoppers who had never purchased from your brand in the prior 12 months. They represent genuine incremental growth, not recapture of existing demand.

    The attribution gap that makes SP look better than it is

    Standard Amazon attribution assigns conversion credit to the last-clicked ad before purchase. In a typical multi-touch journey, a shopper might see a Sponsored Brands Video ad that introduces your brand, spend four days considering the purchase, and eventually convert through a Sponsored Products click on a branded keyword. The SP campaign gets the credit. The SBV campaign that initiated the journey shows zero.

    This attribution structure systematically undervalues SBV’s contribution to overall account performance and overvalues SP’s apparent efficiency. Accounts that optimize exclusively on last-click ROAS will perpetually underinvest in the formats that drive top-of-funnel awareness — and then struggle to understand why their SP conversion rates gradually decline as branded search volume stagnates.

    The NTB Advantage: Why Standard ROAS Comparisons Lie

    New-to-brand metrics are one of the most underused data sets in Amazon advertising. They’re available for Sponsored Brands (including SBV) and Sponsored Display but absent from Sponsored Products entirely, which creates a structural information asymmetry that most advertisers never fully reckon with.

    What NTB metrics actually tell you

    Amazon defines a new-to-brand customer as someone who has not purchased from your brand in the previous 12 months. NTB metrics in the SBV reporting dashboard show you the number of NTB orders, NTB order revenue, NTB order rate, and the average NTB order value generated by your SBV campaigns.

    These numbers are important for one specific reason: they represent the only reliable proxy for incremental demand creation in your Amazon advertising account. Existing customers who repurchase would have done so with or without your ad. New-to-brand customers, by contrast, represent expansion of your addressable customer base — growth that almost certainly would not have occurred without the advertising exposure.

    A Sponsored Brands Video campaign showing a 2.5× direct ROAS with a 45% NTB order rate is delivering substantially more business value than its ROAS number suggests. A Sponsored Products campaign showing a 4.5× ROAS with a 12% NTB rate is largely servicing existing demand, not growing it. If you evaluate these two campaigns purely on ROAS, you’ll defund the one actually building your brand.

    Long-Term Sales ROAS and incremental ROAS frameworks

    Amazon has introduced Long-Term Sales ROAS (LTS ROAS) as an additional measurement layer, designed to estimate the incremental sales value of new-to-brand customers over a 12-month horizon after acquisition. The logic is straightforward: a customer acquired through SBV today may make five additional purchases over the next year. Attributing only the first purchase to the acquisition campaign dramatically understates its true economic contribution.

    Advanced advertisers are increasingly building incremental ROAS (iROAS) frameworks that incorporate NTB acquisition rates, estimated customer lifetime value, and downstream organic purchase behavior. When you run this math, SBV’s apparent ROAS disadvantage relative to SP frequently disappears — and in high-repeat categories like consumables, supplements, or pet products, SBV often shows superior iROAS precisely because it acquires customers who hadn’t yet been reached by SP.

    Practical NTB benchmarking

    If you’re running SBV campaigns and haven’t established NTB benchmarks, start there before making any rebalancing decisions. Pull 90-day NTB order rate, NTB order revenue, and NTB customer acquisition cost (NTB ad spend ÷ NTB orders) from your SBV campaigns. Compare NTB CAC to your estimated first-order margin to establish whether SBV is acquiring customers profitably. Then factor repeat purchase rate into a 12-month LTV calculation to determine the true value of each NTB customer generated by SBV.

    This analysis — not a surface-level ROAS comparison — is the analytical foundation for a defensible rebalancing decision.

    Four-quadrant signal dashboard showing the four triggers for rebalancing Amazon advertising budget from Sponsored Products to Sponsored Brands Video

    Four Signals That Mean Video Should Take Search Budget

    The rebalancing decision is not a one-time judgment call. It’s a diagnostic exercise that should be repeated at least quarterly, because the conditions that justify or contra-indicate a budget shift change as your account matures, your category evolves, and the auction dynamics shift. These four signals are the most reliable indicators that SBV deserves a larger share of your total PPC budget.

    Signal 1: SP CPC rising faster than category average

    When your Sponsored Products CPC is climbing 15% or more year-over-year on your core non-branded keywords, you’re experiencing auction pressure that additional budget cannot solve. You can’t bid your way out of a structurally expensive auction. At some threshold — different for every category and margin structure — incremental SP spend crosses from profitable to value-destroying, even if the headline ROAS looks acceptable.

    The diagnostic is simple: calculate your marginal ROAS on SP for the most recent 30 days versus the previous 30-day period, controlling for seasonality. If marginal ROAS is declining while CPC is rising, you’re past the efficient frontier on SP. That’s budget that should be finding a more productive home, and SBV is the logical first candidate.

    Signal 2: ROAS plateau despite sustained budget increases

    If your SP budget has increased by 20% or more over the past 90 days and total account ROAS has stayed flat or declined, the auction has absorbed your incremental spend without delivering proportional output. This is the most visible symptom of SP saturation in a mature account — the algorithm has found the profitable keywords and is now spending more to maintain those positions rather than finding new, efficient opportunities.

    The distinction here matters: ROAS plateauing because of seasonal softness is different from ROAS plateauing because of structural auction saturation. The test is whether your impression share on core keywords is already high (above 70%) even before budget increases. If you’re already capturing the majority of available impressions at your target keywords, adding budget will mostly raise CPCs rather than meaningfully expand volume.

    Signal 3: Branded search volume is stagnant

    Organic branded search — shoppers typing your brand name directly into Amazon — is one of the cleanest leading indicators of brand health and future conversion efficiency. When branded search volume grows, your SP branded campaigns become cheaper and more efficient, and organic conversion rates typically improve alongside. When branded search volume stagnates, it signals that your brand is failing to capture new customers at the top of the funnel who would eventually become high-value branded searchers.

    SBV’s primary mechanism for building branded search volume is exposure at the discovery stage: shoppers who see your SBV ad, don’t click immediately, but remember the brand name well enough to search for it specifically in a later session. This halo effect is real and measurable — brands that add SBV to an SP-only strategy consistently report 10–18% branded search volume increases over 90-day periods, which compounds into long-term organic rank improvements and reduced branded CPC.

    Signal 4: Category keyword saturation with available SBV placements

    Not all categories reach SBV saturation at the same pace. If your category analysis shows that fewer than 30–40% of search results pages in your core keywords display SBV ads — or that the same two or three competitor brands own the SBV slots consistently — there is an immediate placement arbitrage available. SBV CPCs in undersaturated categories frequently run materially lower than SP CPCs for comparable keyword targets, while delivering superior CTR and reaching audiences at a different decision-making stage.

    This asymmetry won’t last. As more advertisers recognize SBV’s efficiency advantage, auction pressure on video placements will increase. The window for low-CPC SBV entry into competitive categories is narrowing — which means accounts that act on this analysis in 2026 will establish creative assets, quality scores, and historical performance data that provide durable advantages before costs normalize.

    The Rebalancing Math: How to Calculate the Right Budget Split

    The portfolio math for SBV allocation in 2026 has crystallized around some fairly consistent benchmarks from advanced accounts. But those benchmarks are outputs of a calculation, not inputs to it. Understanding the calculation is more durable than memorizing the numbers.

    The standard advanced account structure

    Data from well-optimized Amazon PPC accounts in 2026 clusters around a consistent portfolio structure: 60–70% of total ad spend in Sponsored Products, 20–25% in Sponsored Brands, and 10–15% in Sponsored Display. Within the Sponsored Brands allocation, 80–95% flows to Sponsored Brands Video rather than static Sponsored Brands headline ads.

    Working through that math: if SB receives 20–25% of total spend and 90% of that goes to SBV, then SBV is absorbing roughly 18–22% of total PPC budget in advanced accounts. For a brand spending $50,000 per month in Amazon advertising, that’s $9,000–$11,000 per month in SBV — a number that would have seemed aggressive for most advertisers three years ago and is now increasingly treated as the baseline for accounts that take video seriously.

    How to calculate your specific rebalancing threshold

    Rather than adopting aggregate benchmarks wholesale, calculate your account-specific rebalancing ceiling using this structure. First, identify the portion of your current SP spend that is defensive rather than acquisitive — budget spent maintaining top-of-search positions on branded keywords and saturated category keywords where incremental ROAS has demonstrably declined. This is your rebalancing pool: spend that is currently delivering below-marginal returns in SP and could potentially generate higher incremental value in SBV.

    Second, establish your SBV capacity constraint. SBV budget can only be effectively deployed if you have sufficient creative assets and keyword targeting infrastructure to utilize it without quality degradation. Running more budget through a single SBV campaign with one creative asset leads to frequency fatigue and creative decay. The practical rule is that each distinct SBV creative should support no more than $3,000–$5,000 in monthly spend before performance begins to diminish from repetition.

    Third, calculate the incremental NTB acquisition opportunity. Using your current SBV NTB rate and NTB CAC, estimate how many additional new-to-brand customers the rebalanced budget would generate per month. Multiply by your 12-month LTV estimate. If that LTV figure exceeds the marginal ROAS you’re generating from the SP spend you’d be reallocating, the math supports the shift.

    The 5–10% incremental rule

    Whatever the calculation suggests, the execution should be gradual. The consensus among advanced Amazon PPC managers in 2026 is that budget shifts exceeding 10% of total account spend in a single adjustment period create performance instability. Amazon’s campaign algorithms require observation data to optimize new bid levels and placement priorities effectively. Large sudden budget changes can trigger algorithmic recalibration periods — sometimes manifesting as temporary performance dips — that make it impossible to evaluate whether the shift was genuinely beneficial or simply disruptive.

    Move 5–10% of SP budget into SBV over each 30-day period. Observe for 30 days before making the next adjustment. This pacing gives algorithms time to stabilize, gives you clean data to evaluate at each stage, and limits downside exposure if the initial rebalancing reveals unexpected issues with creative quality or keyword targeting in the SBV campaigns.

    Budget allocation pie chart for advanced Amazon PPC accounts in 2026 showing recommended split between Sponsored Products, Sponsored Brands Video, and Sponsored Display

    Creative That Earns the Budget: What SBV Needs to Perform

    Budget rebalancing without creative infrastructure is a money-wasting exercise. SBV is an unforgiving format in one specific respect: the creative asset is the campaign. You can build technically sound targeting, competitive bid levels, and a sensible keyword strategy, and still generate mediocre SBV results if the video asset fails to earn attention in the first three seconds. This is categorically different from SP, where a strong main image and price point do the majority of the conversion work.

    The first three seconds are non-negotiable

    SBV ads autoplay when approximately 50% of the unit is visible on screen, without sound, on mobile and desktop. The shopper did not choose to engage with your ad. The ad appeared in their scroll path, and they have approximately two to three seconds before their thumb continues to the next result. In that window, the video must accomplish one thing: show the product doing something interesting enough that stopping and watching more seems worthwhile.

    This sounds obvious. It is routinely violated. Common first-three-second failures include: opening with a logo or brand name before the product appears; slow-building lifestyle montages that haven’t shown the physical product by second four; text-heavy title cards that require reading rather than watching; and transitions that obscure the product during the critical hook window.

    Amazon’s own research supports the product-first principle: videos that show the core product within the first two to three seconds consistently outperform those that build to the product reveal. The mechanism is practical — a shopper searching for “stainless steel cookware” who immediately sees a gleaming pan being used on a stovetop has received immediate confirmation that this ad is relevant to their intent. A shopper who sees a nature landscape opening sequence has not.

    Design for mute: captions are not optional

    Because SBV autoplays without sound, every video that relies on spoken information to communicate its core message is operating at a structural disadvantage. The shopper who watches a 15-second SBV ad on mute and has no idea what the product does or what makes it different from competitors is not going to tap to enable audio — they’re going to scroll to the next result.

    Bold, high-contrast text overlays that mirror or supplement the visual content are the standard approach for mute-first design. Key benefit statements, differentiators, size/quantity callouts, and pricing signals should all appear as on-screen text at the relevant moment in the video. Captions for spoken content are a secondary measure — effective, but not a substitute for text overlays designed specifically for a sound-off experience.

    Runtime, refresh cadence, and creative volume

    Current SBV best practice benchmarks in 2026 center on videos in the 15–30 second range, with 15–20 seconds outperforming longer formats in most categories where the product benefit can be communicated concisely. Categories with complex products — technical equipment, multi-component systems, software-adjacent products — support slightly longer formats, but even these rarely benefit from videos exceeding 45 seconds in the search results environment.

    Creative decay is one of the most underappreciated performance risks in SBV campaigns. A video that drives strong CTR in month one will typically show meaningfully declining performance by month two or three as the same audiences see it repeatedly. Advanced SBV accounts maintain a minimum of two to three active creative variants per campaign and rotate in new assets at least every 30 days. Some highly scaled accounts run monthly creative production cycles specifically to prevent fatigue-driven performance erosion.

    Amazon’s introduction of its own Video Generator tool for Sponsored Brands campaigns in 2026 has lowered the production barrier for smaller advertisers, enabling basic video creation from existing product images and text. While this tool won’t replace purpose-built video production for established brands, it removes the “we don’t have video assets” constraint for brands that have been deferring SBV entry for creative-cost reasons.

    Multi-ASIN vs. single product SBV strategy

    SBV campaigns can showcase a single product or a curated selection of up to three products in a store spotlight format. The strategic choice between these approaches has meaningful implications for budget efficiency. Single-product SBV is typically more conversion-focused: the ad communicates one clear value proposition, and the click lands on a specific ASIN detail page. Multi-product SBV is more acquisition-focused: it shows category breadth, drives traffic to a custom landing page or brand store, and is more likely to drive NTB exploration across the catalog.

    The general guidance from 2026 account data is to run single-product SBV for your highest-priority ASINs where conversion rate optimization is the objective, and multi-product SBV when the goal is brand building and catalog discovery among new-to-brand audiences. Both have a place in a mature SBV portfolio — but mixing objectives within a single campaign makes it impossible to evaluate performance accurately.

    Attribution Reality: Measuring SBV’s True Contribution

    The measurement challenge for SBV is not technically complex — the tools exist. The challenge is organizational: most Amazon PPC reporting dashboards are built around last-click ROAS, which is the metric most brand managers and finance teams understand and can benchmark against. Introducing incremental ROAS, NTB metrics, and halo effect analysis requires either building new reporting infrastructure or doing a significant amount of educational work with stakeholders who have strong intuitions about what “good” ROAS looks like.

    Building an incrementality baseline

    The first step in accurate SBV measurement is establishing what your account looks like without SBV. If you’ve been running SBV campaigns for six months or more, you can do a retrospective analysis by pulling weekly performance data and identifying periods when SBV budgets were paused or significantly reduced — then examining what happened to SP conversion rates, branded search volume, and overall account ROAS during those periods. If SBV pauses correlate with degraded account-level performance even when SP budgets were held constant, that’s directional evidence of SBV’s incremental contribution.

    For accounts building a prospective incrementality baseline, the cleanest methodology is a geo-based holdout test: run SBV in specific states or regions while suppressing it in matched control regions, with SP budgets held constant across both groups. Comparing sales velocity, branded search growth, and NTB acquisition rates between test and control groups over 30–60 days gives you a reasonably clean incrementality estimate without touching your core SP performance.

    The branded search lift metric

    One of the most practical proxies for SBV’s halo contribution is branded search volume lift. Track your branded keyword impression volume in Sponsored Brands reports before and after SBV campaigns launch or scale. If branded search impressions increase materially — even if your branded SP bids haven’t changed — SBV is generating awareness that converts to intent in later sessions. This metric isn’t available in a single report; it requires pulling SB impression data over time and correlating it with SBV spend levels. But it’s tractable, and it tells a clean story that’s easy to communicate to stakeholders who aren’t fluent in incrementality methodology.

    What to actually report to decision-makers

    For internal reporting purposes, present SBV performance across three distinct metrics tiers: direct performance (CTR, CVR, direct ROAS), new-to-brand performance (NTB order rate, NTB revenue, NTB CAC), and brand health performance (branded search volume trend, branded keyword CPC trend). Showing all three simultaneously makes it impossible to evaluate SBV in purely direct-ROAS terms — which is the framework that leads to chronic SBV underinvestment — and creates a richer, more accurate picture of what the format is delivering to the business.

    How Rufus and Alexa for Shopping Change the Video Equation

    Amazon’s AI-powered shopping assistant — initially launched as Rufus and increasingly integrated across the shopping experience under the Alexa for Shopping umbrella — is adding a new dimension to the SBV value calculation. The precise mechanics of AI-assisted ad placement are still evolving and not fully documented by Amazon, but the directional trends are clear enough to inform 2026 budget strategy.

    Conversational discovery and Sponsored Prompts

    Rufus/Alexa for Shopping processes conversational queries — “What’s the best protein powder for building muscle?” — and generates product recommendations that blend organic results with Sponsored Brands and Sponsored Prompts placements. The AI’s intent-matching capability creates a new discovery surface that is qualitatively different from keyword-triggered search: the shopper is expressing category interest through a conversational format rather than entering a precise search query, which means the discovery mechanism rewards brand awareness and category association more than keyword optimization.

    SBV has a structural advantage in this environment. A brand that has generated meaningful awareness and association with a category through SBV campaigns — impressions, video completions, click-throughs — builds signals that inform the AI’s understanding of brand-category relevance. Brands that exist only as keyword-targeted SP listings have a thinner signal footprint for the AI to work with. As conversational discovery grows as a share of total Amazon shopping sessions, the brands with richer upper-funnel data will have compounding advantages in AI-assisted placement.

    Video surfaces in AI-driven shopping experiences

    Amazon has begun integrating video ad units into AI-assisted discovery surfaces alongside traditional search results. The trajectory suggests increasing video representation in these environments over time, consistent with broader platform trends toward richer media in shopping interfaces. Brands that have established SBV creative assets, performance history, and quality signals in 2026 will be better positioned to occupy these placements as they scale, compared to brands that delay video entry and attempt to build that infrastructure later in a more competitive environment.

    What this means for the rebalancing decision

    The Rufus/Alexa for Shopping trend reinforces the rebalancing case without transforming it. The core argument for shifting budget from SP to SBV — based on CPC economics, NTB acquisition, and incremental ROAS — is already compelling on its own terms. The AI shopping assistant dynamic adds a forward-looking dimension: the investment in SBV creative and performance history being made today is building assets that will compound in value as Amazon’s AI-driven discovery surfaces grow in importance. Brands that treat SBV as an experimental supplement to SP will find themselves starting from scratch in that future environment.

    Common Rebalancing Mistakes (And How to Avoid Them)

    Budget rebalancing decisions are easy to get wrong even when the strategic logic is sound. These are the most consistent failure modes observed in accounts that attempt SBV rebalancing without adequate preparation.

    Moving budget before creative is ready

    The most common and costly mistake is reallocating SP budget into SBV before the SBV creative infrastructure is genuinely ready to absorb it efficiently. Launching a $10,000/month SBV budget against a single 30-second video with mediocre production quality will produce poor results — not because SBV doesn’t work, but because the creative is the limiting factor. Poor SBV results often lead to the incorrect conclusion that “video doesn’t work for our category” and a reversion to SP-heavy allocation, when the actual lesson is that video requires creative investment proportional to the budget behind it.

    The rule of thumb: don’t move more than $3,000–$5,000 per month into SBV per creative asset until you’ve validated CTR and CVR performance on that asset at lower spend levels. Scale budget only behind creative that has demonstrated it can earn attention.

    Evaluating SBV on the same metrics as SP

    Applying SP’s ROAS target to SBV campaigns is analytically incorrect and will systematically prevent SBV from reaching budgets where it can generate its distinctive value. SBV typically shows 15–30% lower direct ROAS than SP in the same account — not because it’s less efficient, but because it’s doing different work. Holding SBV to the same ROAS threshold as SP ensures that every marginal dollar of SBV budget that exceeds that threshold gets cut before the campaign has the scale to generate NTB acquisition at volume.

    Set separate performance targets for SBV based on NTB-adjusted metrics, not direct ROAS. A reasonable starting threshold: SBV ROAS + (NTB order rate × estimated NTB LTV) should exceed SP marginal ROAS. If the combined metric clears the bar, the SBV budget is justified even if the direct ROAS looks weaker in isolation.

    Rebalancing during peak seasons

    Budget structure changes made during Q4, Prime Day, or other high-velocity periods introduce additional variables that make it impossible to evaluate whether performance changes are driven by the rebalancing or by the seasonal dynamics. Always conduct rebalancing tests during stable, predictable demand periods. Use Q1 and Q3 for the bulk of your structural budget experimentation. Apply the learnings from those experiments to your Q2 and Q4 budget configurations, rather than running live experiments during your most consequential trading periods.

    Ignoring keyword strategy in SBV campaigns

    SBV is a keyword-targeted format. The quality of keyword selection in SBV campaigns matters significantly for both performance and cost efficiency. A common mistake is targeting only the same core category keywords in SBV that are already heavily contested in SP — which drives up CPCs, reduces the efficiency advantage of SBV, and limits the format’s reach to audiences the account is already aggressively targeting through SP.

    SBV keyword strategy should include a meaningful proportion of broader, aspirational, or adjacent category keywords that SP campaigns don’t target efficiently. These wider matches reach shoppers earlier in the consideration journey — exactly where SBV’s awareness and video-engagement advantages are most relevant. The CTR from these broader terms will be lower than core keyword CTR, but the NTB acquisition rate will typically be higher, and the CPCs will be more competitive.

    90-day phased Amazon PPC budget rebalancing roadmap: Phase 1 audit and baseline, Phase 2 test 10-15% shift, Phase 3 scale or pause based on incrementality data

    The Phased Rebalancing Framework: A 90-Day Approach

    The following framework provides a structured approach to SBV budget rebalancing that manages risk, preserves account stability, and generates clean data at each stage to support subsequent decisions. It assumes an existing SP-primary account with either no current SBV presence or a small experimental SBV allocation.

    Phase 1 (Days 1–30): Establish baselines and prepare creative

    The first month is entirely analytical and preparatory. Run your existing SP and SBV campaigns without structural changes. Pull 30-day and 90-day performance data across: SP CPC by keyword group, SP marginal ROAS (estimated), SP impression share on core keywords, SBV CTR and CVR by creative asset, SBV NTB order rate and NTB CAC, and branded keyword search volume trends.

    Use this data to identify: (1) which SP campaigns or keyword groups are showing the clearest diminishing marginal returns — these are the rebalancing source pool; (2) which SBV creative assets have demonstrated the strongest CTR and NTB performance at current spend levels — these are the assets worth scaling; and (3) what creative gaps exist if the SBV budget were to double or triple.

    Simultaneously, prepare or commission any additional creative assets needed for Phase 2 scaling. The 30-day Phase 1 window is the production runway for the video assets that Phase 2 will need. Entering Phase 2 without ready creative puts you in the position of scaling budget against an asset before it’s been adequately tested.
    Phase 2 (Days 31–60): Execute the first rebalancing shift

    Move 10–15% of your identified SP rebalancing pool into SBV. If your analysis in Phase 1 suggested $8,000/month in SP spend that is delivering below-marginal returns, shift $800–$1,200 of that into SBV in Phase 2. This is deliberately conservative — the goal is not to maximize the rebalancing speed but to generate clean, observable data on how the shift affects both account-level performance and SBV-specific metrics.

    Configure SBV campaigns with the validated creative assets identified in Phase 1. Separate campaigns by targeting strategy: one campaign targeting your core category keywords, one targeting broader adjacent keywords, and — if you have the budget — one targeting competitor ASINs or branded terms where SBV’s video format can interrupt competitor consideration. Maintain all existing SP campaigns at their current levels minus the reallocated amount; do not simultaneously adjust SP bids, which would introduce additional variables.

    Track weekly: total account ROAS (not just SBV ROAS), SP conversion rate, SBV CTR and CVR, SBV NTB order rate, and branded keyword impression volume. Any significant deterioration in total account ROAS or SP conversion rate should trigger a diagnostic review before Phase 3.

    Phase 3 (Days 61–90): Scale, hold, or pull back based on data

    By Day 61, you have 30 days of clean Phase 2 performance data. The decision tree is straightforward:

    If total account ROAS held or improved: SBV has absorbed the rebalanced budget without degrading overall performance. The data supports further rebalancing. Execute a second 10–15% shift in Phase 3 and extend the framework to a 180-day cycle.
    If total account ROAS declined but SBV NTB metrics are strong: The direct ROAS decline may be offset by NTB acquisition value. Run the iROAS calculation including estimated LTV contribution from NTB customers. If the combined metric supports the shift, hold the current allocation and monitor for 30 more days before deciding whether to scale further or stabilize.

    If both direct ROAS and NTB metrics are weak: The creative or targeting in Phase 2 is the problem, not the rebalancing thesis. Pause the SBV scale, diagnose which elements of creative and targeting underperformed, produce revised assets, and re-run Phase 2 with the improvements before attempting Phase 3 again.

    The structured approach forces each rebalancing decision to be grounded in observed data rather than either blind commitment to the rebalancing thesis or premature retreat at the first sign of performance volatility. Most accounts that fail at SBV rebalancing fail because they either move too fast without adequate measurement infrastructure or abandon the strategy based on direct ROAS data alone without incorporating NTB and iROAS context.

    Conclusion: The Budget Assumption Worth Revisiting

    The SP-primary Amazon advertising account was the right structure for a previous version of the Amazon advertising ecosystem. In that environment — lower SP CPCs, limited SBV placement inventory, fragmented video creative tools — allocating 80–90% of PPC budget to Sponsored Products was a rational, efficient choice. That environment no longer exists in 2026.

    SP CPCs have climbed to levels where incremental spend in many categories generates genuinely poor marginal returns. SBV has matured into a format with documented CTR advantages, measurable NTB acquisition capacity, and a clear place in the full shopping funnel. The analytical tools — NTB metrics, LTS ROAS, incremental ROAS frameworks — to evaluate SBV on appropriate terms are available in Amazon’s own reporting console. The creative production barrier has dropped with Amazon’s Video Generator and widespread access to affordable video production services.

    The remaining barrier is organizational: the habit of evaluating all advertising spend on last-click direct ROAS, which makes SP look more efficient than it is at the margin and makes SBV look less efficient than it is when NTB and halo contributions are included. Changing that measurement framework is the precondition for making rational rebalancing decisions.

    The four signals — rising SP CPCs, ROAS plateaus, stagnant branded search volume, and underutilized SBV placement inventory — are a diagnostic toolkit, not a checklist requiring all four items to be present before action is warranted. Two or three of them appearing simultaneously is sufficient to begin the 90-day rebalancing framework and generate the data that will either confirm or complicate the thesis.

    Video is not eating search because it is a better channel in some abstract sense. It’s earning budget because the economics of search have shifted to a point where video’s incremental contribution — measured honestly and completely — is frequently more valuable than the marginal return on additional search spend. That’s not a creative trend. It’s a math problem with a specific answer that differs for every account and changes every quarter. The job is to run the math, act on what it shows, and keep running it.

    Key Takeaways

    • SP CPCs have risen ~48% cumulatively since 2019; marginal returns on additional SP spend are declining in most competitive categories.
    • SBV delivers approximately 1.6× higher CTR and 1.3× higher CVR than static Sponsored Brands, with new-to-brand reporting that SP cannot provide.
    • Standard last-click ROAS comparisons systematically undervalue SBV; NTB-adjusted and incremental ROAS frameworks are required for accurate evaluation.
    • Advanced accounts in 2026 allocate 80–95% of SB budget to SBV, representing roughly 16–25% of total PPC spend.
    • The four rebalancing signals: rising SP CPC, ROAS plateau, stagnant branded search volume, and available SBV placement inventory.
    • Move budget in 10–15% increments per 30-day period; evaluate with a combined direct ROAS + NTB + iROAS framework.
    • Creative quality is the binding constraint on SBV performance — do not scale budget ahead of creative readiness.
    • Rufus/Alexa for Shopping’s conversational discovery surfaces reward brands with richer upper-funnel data, reinforcing the long-term case for SBV investment.
  • Amazon Ads AI Bidding: The Test-First Framework That Actually Sequences Your Experiments

    Amazon Ads AI Bidding: The Test-First Framework That Actually Sequences Your Experiments

    Amazon Ads AI bidding test-first framework: chaotic random testing vs structured sequenced flowchart

    Here is the mistake most Amazon advertisers are making with AI bidding in 2026: they treat it as a feature to activate, not a system to build. They flip on dynamic bidding, wait a week, see mixed results, then chase the next lever — placement multipliers, a third-party tool, maybe the new Ads Agent — without ever knowing whether the first test actually worked.

    The result is a campaign account that looks increasingly automated but performs no better than it did six months ago. Sometimes worse.

    The core problem is not the tools. Amazon’s native AI bidding infrastructure has matured considerably. The problem is test sequencing. Each bidding layer you add to a campaign interacts with the ones already in place. If you run placement multipliers before you’ve established a stable bid mode, you cannot attribute the outcome to either variable. If you hand off to Ads Agent before you’ve established clean conversion signals, the agent learns from noise. The tests compound — but so do the errors.
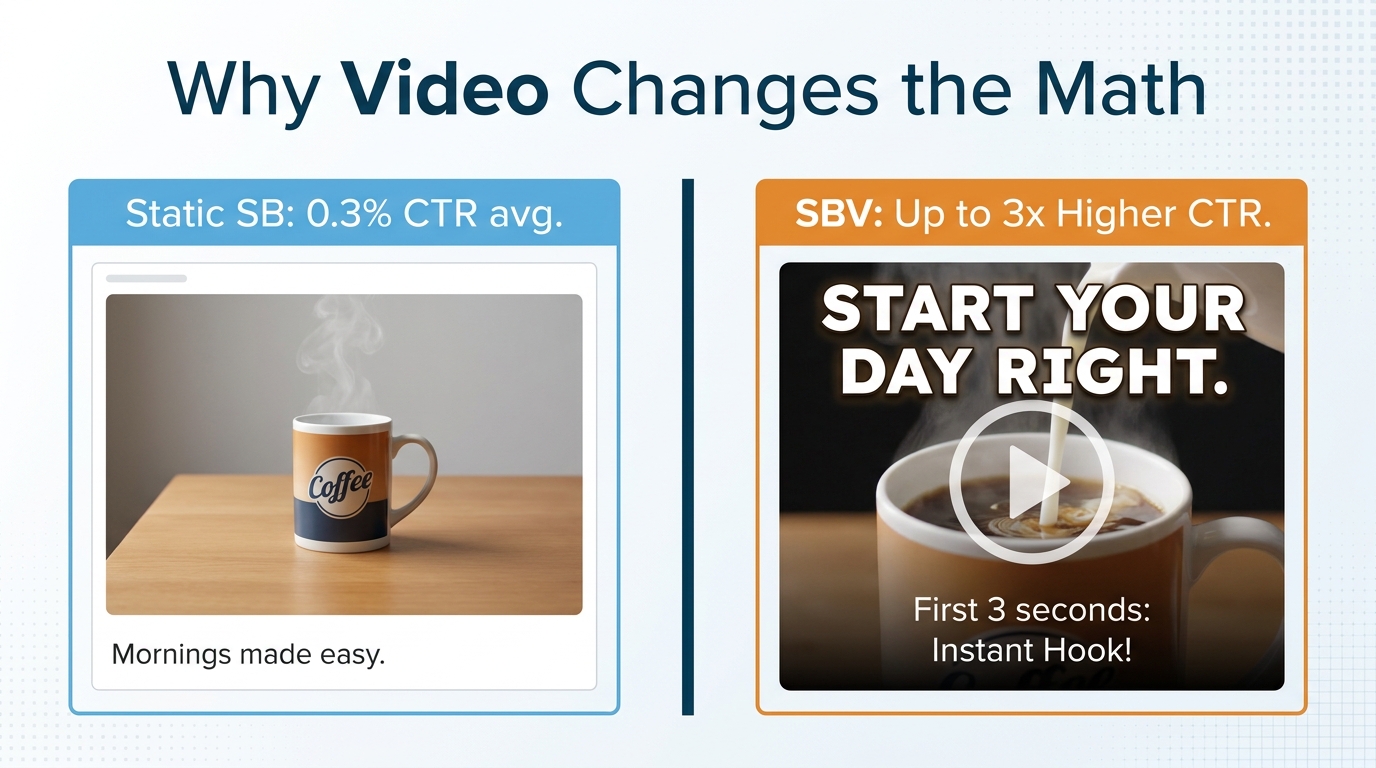
    This article lays out a specific test order: what to run first, what each test actually measures, how long to wait before drawing conclusions, and what failure looks like at each stage. It draws on real campaign data, Amazon’s own documentation, and practitioner analysis from accounts managing thousands of Sponsored Products campaigns in 2026.

    This is not a beginner’s overview of dynamic bidding. It is a sequenced testing framework for advertisers who already understand the basics and want to know how to build on top of them systematically — without breaking what is already working.
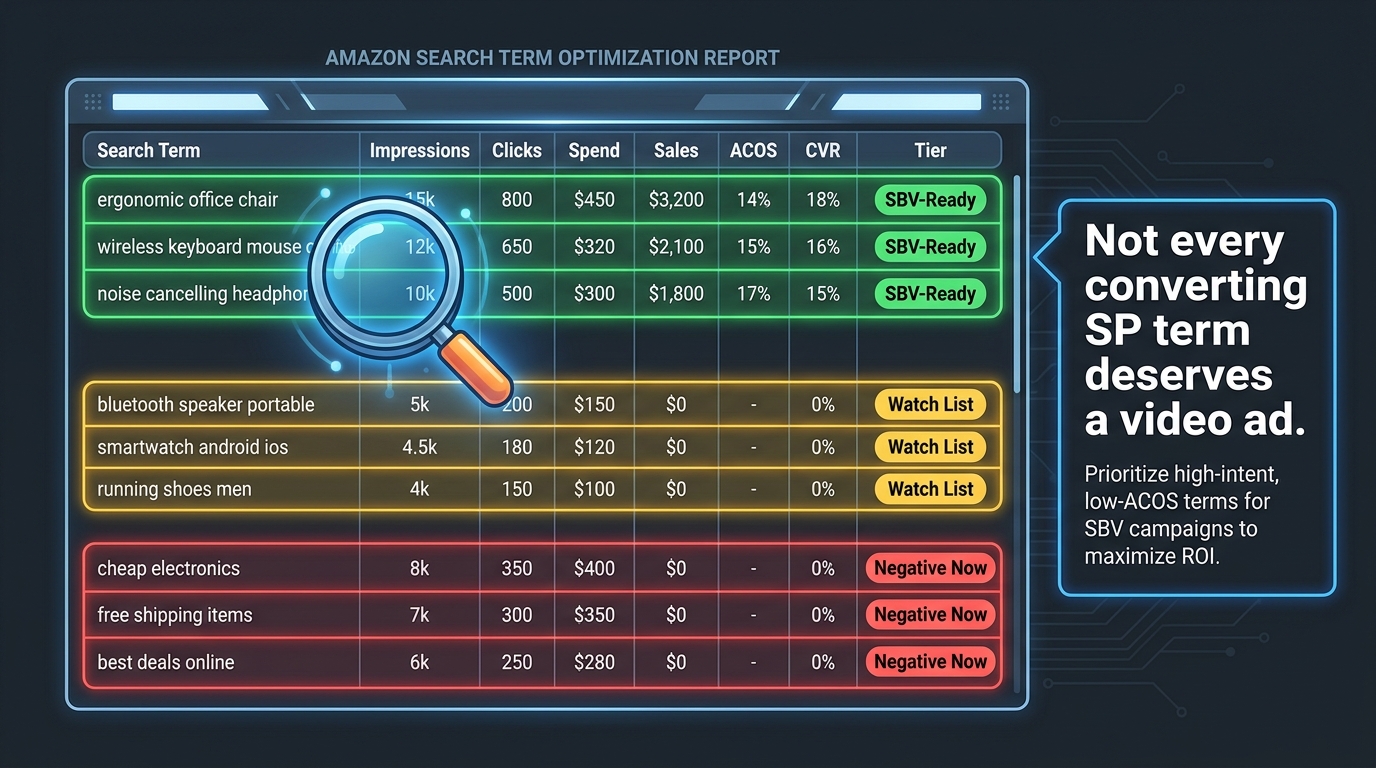
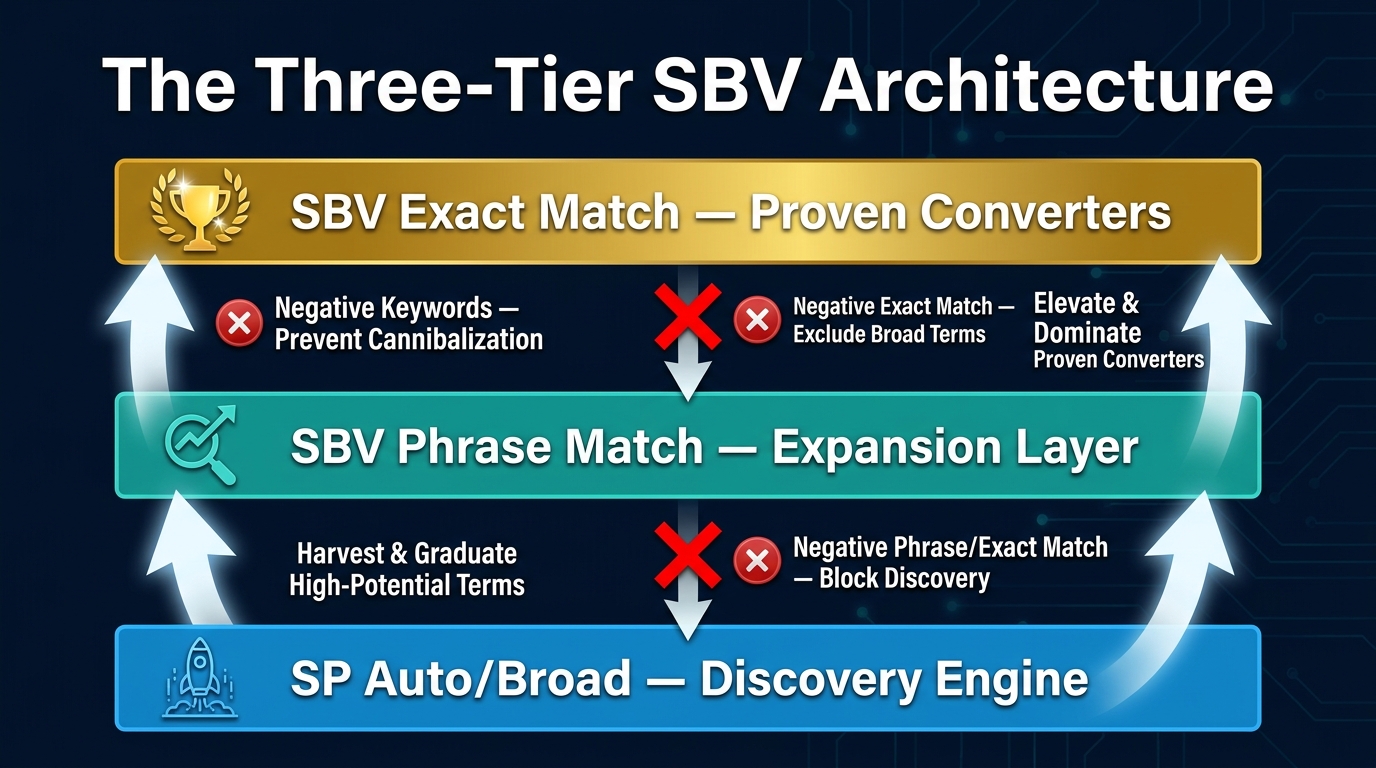
    Why Test Order Matters More Than the Test Itself

    Most Amazon PPC education treats each bidding feature as an independent dial. Turn this one up for volume, turn that one down for efficiency. In practice, these features are interdependent layers in a single auction system, and the order in which you activate them determines what signals each layer receives.

    Consider a simple example. You run a Sponsored Products campaign on dynamic bidding — up and down. Amazon’s algorithm is now adjusting your bids in real time based on its estimate of the probability that any given impression will convert. You then add a 100% Top of Search placement multiplier. The result: on a high-intent search with strong conversion probability, Amazon bids up (say, 30% above your base), and then your multiplier pushes another 100% on top of that. Your effective CPC on top-of-search placements is now 2.6x your stated base bid — a number no efficiency model anticipated.

    You now have two variables interacting in a way you cannot disentangle from a single report. If ACoS spikes, was it the bidding mode or the multiplier? You do not know, and you cannot know, unless you tested them separately in sequence.

    The Compounding Signal Problem

    This sequencing challenge becomes even more critical when AI is involved. Amazon’s bidding algorithms — whether native dynamic bidding or the newer Ads Agent — learn from the conversion data your campaigns generate. That learning is path-dependent: the AI builds a model based on the historical pattern of impressions, clicks, and conversions your campaign has produced. If that history contains periods where two variables changed simultaneously, the model’s understanding of cause and effect is degraded.

    Introduce a third-party AI tool on top of an already-noisy foundation and the problem multiplies. The external tool is now learning from data that Amazon’s system already partially shaped — and both systems may be making competing bid adjustments on the same auction. Practitioner analysis from 2026 accounts consistently flags this as a primary cause of “AI drift,” where automated systems stabilize at a local optimum significantly below what disciplined manual management would have achieved.

    The Right Mental Model: Layers, Not Levers

    Think of Amazon Ads AI bidding as a layer cake. The base layer is your campaign structure and keyword match types. The second layer is your bid mode. The third is your placement modifiers. The fourth is your portfolio or budget controls. The fifth is any AI agent or third-party automation layer on top.

    Each layer should be stable and understood before you add the next one. Stability does not mean perfect — it means you have enough data to have a directional read on performance. This is the foundation of the framework that follows.

    Step One: The Pre-Test Audit — Diagnose Before You Automate

    Before changing any bidding setting, there is a diagnostic step that most advertisers skip entirely. It takes roughly 30 minutes per campaign, but it determines whether AI bidding has any chance of working in the first place.

    AI bidding systems learn from conversion signals. If those signals are weak, infrequent, or contaminated, the algorithm learns the wrong patterns and confidently executes on them. The diagnostic checks four things:

    1. Conversion Volume Sufficiency

    Amazon’s native AI bidding stabilizes with approximately 30 or more conversions over any 30-day window per campaign. Below that threshold, the algorithm does not have enough data to model conversion probability with any reliability. This is not a formal Amazon policy number — the company does not publish a universal minimum — but it reflects consistent practitioner experience and parallels the documented behavior of Amazon DSP Performance+, which officially requires a minimum conversion volume before the learning phase can conclude.

    Check your last 30 days of conversion data at the campaign level. If you are running below 30 orders, AI bidding will not reliably outperform a well-structured manual bid. Fix conversion volume first: tighten match types, eliminate non-converting keywords, and improve listing conversion rate before touching bidding mode.

    2. Attribution Cleanliness

    Amazon’s 14-day attribution window means conversions show up in reports days after the click. If you have recently changed prices, run a coupon, or had a Buy Box loss, the conversion data in your current window is contaminated — it reflects a product state that no longer exists. AI bidding trained on that data will optimize for a context that has passed. Always audit your last 30 days for any external changes before running a bidding test.

    3. Campaign Isolation

    Each campaign you test should contain products with similar economics and conversion rates. Mixing high-margin, fast-selling ASINs with slow-moving commodity SKUs in a single campaign forces the AI to average across wildly different conversion patterns. The result is an algorithm that is perpetually confused and perpetually underperforming. Segment before you test.

    4. Listing Quality Baseline

    Bidding AI cannot fix a listing that does not convert. If your main image, title, price, or review count is meaningfully below category benchmarks, raising bids — automatically or otherwise — generates expensive impressions that do not convert. Document your listing conversion rate (orders divided by sessions from the Brand Analytics or Business Reports page) before starting any bidding test. If it is below 10% in a category where competitors average 15–20%, the problem is the listing, not the bids.

    Step Two: Bidding Mode — Down Only vs Up and Down (The Data You Actually Need)

    Amazon dynamic bidding comparison: Down Only vs Up and Down — ACoS, CPC, and volume trade-offs with 2026 data

    Bid mode is the first real test in the sequence, and the data on it is clearer than most advertisers realize. A BidX analysis of approximately 130,000 campaigns in 2024 found that dynamic bidding — down only produced the lowest average ACoS across the study group, with a click-through rate only 0.02% lower than up and down campaigns. The CTR difference was negligible; the ACoS difference was not.

    In 2026, this picture has sharpened further. Multiple advertisers and agency reports have documented that the up-and-down engine has been retuned by Amazon, with CPCs running approximately 18–27% higher in many categories since late April 2026 compared to historical averages — while conversion rates remained largely flat. That combination is a direct efficiency hit to any campaign using up and down without a deliberate rationale for accepting higher costs.

    When Down Only Is the Right Default

    Down only should be your starting bid mode for the majority of Sponsored Products campaigns. It functions as a cost floor — Amazon can reduce your bid when conversion probability is low, but it cannot inflate your bid above your stated maximum. This gives the AI a real optimization lever (downward adjustment) while preventing the uncapped spend that damages ACoS in high-competition auctions.

    This mode is particularly effective for mature campaigns with established conversion history, campaigns with tight margin constraints, and any ASIN in a category where CPCs have risen significantly in 2026. The algorithm’s downward adjustments can reduce wasted spend on low-intent impressions without requiring you to manually review every keyword bid daily.

    When Up and Down Has a Specific Role

    Up and down is not a universally bad choice — it has a specific, narrow use case: product launches and aggressive share-capture scenarios where you have pre-committed to higher short-term CPC in exchange for velocity and ranking signal. If you are launching a new ASIN and need to build conversion history quickly, or if you are running a time-limited conquest campaign against a key competitor, giving Amazon the ability to bid above your base to win high-intent auctions can be worth the cost.

    The critical discipline is defining an exit condition before you start. Decide: after how many days, or at what ACoS threshold, does this campaign revert to down only? Without a predefined exit, up and down campaigns tend to accumulate cost and never get rationalized.

    How to Run This Test Cleanly

    To test bid mode in isolation, use Amazon’s Campaign Experiments tool (available within the Ads console under “Experiments”). This feature splits your campaign traffic between two configurations — a control and a treatment — and attributes outcomes to each. Run the experiment for a minimum of 28 days to capture enough conversion events for statistical reliability. The single variable to change is bid mode. Keep base bids, keyword lists, match types, and placement modifiers identical across both arms of the experiment.

    Step Three: Placement Multipliers — The Lever Nobody Tests Correctly

    Amazon Top of Search placement multiplier testing diagram showing adjustment ranges and ACoS decision logic

    Placement multipliers are tested in Step Three because they operate on top of your bid mode. If your bid mode is not yet stable and understood, adding placement modifiers creates compounding uncertainty that you cannot resolve. Once you have established a stable bid mode — ideally down only — and have at least 28 days of clean data from that mode, placement multipliers become the next variable to isolate.

    Amazon Sponsored Products allows you to set percentage bid modifiers for two placements: Top of Search (first page) and Product Pages. Rest of Search always uses your base bid with no modifier. Modifiers can go up to +900%, though anything above 150% is almost never justified outside extreme brand-defense scenarios.

    The Stacking Problem

    The most important thing to understand about placement multipliers is how they interact with dynamic bidding. If you are on dynamic bidding — up and down — and you add a 100% Top of Search multiplier, Amazon’s algorithm can bid above your base on a high-intent impression, and then your multiplier adds another 100% on top of that adjusted bid. The CPC you actually pay can reach multiples of your stated base bid, with zero notification from Amazon. This is the stacking risk that inflates spend silently.

    On dynamic bidding — down only, stacking is less dangerous: the multiplier can push above your base for top-of-search placements, but Amazon cannot inflate the base beyond your stated maximum before the multiplier applies. The effective exposure is more predictable. This is one more reason to resolve your bid mode first.

    How to Test Placement Multipliers Correctly

    Start with your placement report, not with a multiplier adjustment. Pull the Placement Report from your campaign’s reports tab, filtered to the last 30 days. This report breaks out ACoS, CPC, conversions, and spend by placement type: Top of Search, Product Pages, and Rest of Search. This data tells you whether Top of Search is currently profitable for your campaigns — before you spend a dollar more amplifying it.

    If your Top of Search ACoS is already below your target, a moderate multiplier (try 25–50% to start) will send more budget to your most profitable placement. Increase in 10-percentage-point increments every 10–14 days, checking placement-level ACoS after each adjustment. Expert consensus in 2026 puts the productive range for most accounts at 50–150% for Top of Search. Above 150%, CPC exposure typically erodes the efficiency gains from better placement.

    If your Top of Search ACoS in the placement report is already above target, a multiplier will not fix that — it will amplify the problem. The issue is either keyword relevance, listing conversion, or a CPC floor set too high for your margin. Fix the underlying conversion issue before applying any positive multiplier.

    Product Pages: The Underused Placement

    Product page placements (your ads appearing on competitor or complementary product detail pages) often convert at lower rates than Top of Search but can deliver profitable scale at lower CPCs. Test product page multipliers separately from Top of Search multipliers using the same placement-report-first process. Many accounts find a moderate product page multiplier (20–40%) expands volume cost-effectively when top-of-search is expensive and competitive.

    Step Four: The Learning Period Protocol — How to Protect the Algorithm’s Work

    Amazon AI bidding learning period 8-week timeline showing optimal intervention points and what not to do in weeks 1 and 2

    Every time you make a meaningful change to a campaign running AI-assisted bidding — bid mode, placement modifier, keyword addition, budget change — the learning period effectively resets. Amazon’s algorithm needs time to rebuild its conversion probability model under the new conditions. This is not unique to Amazon; it mirrors the documented behavior of Google’s Smart Bidding, which carries a formal 2-week learning period designation.

    On Amazon, the learning period is not formally labeled as such in most campaign types (though Amazon DSP Performance+ explicitly documents up to four weeks), but practitioner data consistently shows performance instability in the first two to three weeks after a structural campaign change. The accounts that most commonly report “AI bidding doesn’t work” are the ones making changes every few days.

    The Eight-Week Protocol

    When you activate a new bidding configuration, commit to the following timeline:

    Weeks 1–2 (Learning Zone): Do not change bids, match types, budgets, or placement modifiers. Monitor impressions and spend to confirm the campaign is active and within expected ranges, but resist any optimization impulse. The algorithm is building its baseline model. Any intervention at this stage teaches the system that its early signals were wrong — even if they weren’t.

    Weeks 3–4 (Early Signal Review): Begin reviewing conversion trend data only. You are not yet optimizing — you are assessing whether the trajectory is directionally correct. Is ACoS trending downward compared to the pre-change baseline? Is conversion rate stable or improving? These are the questions to answer. Still no bid or structure changes.

    Weeks 5–6 (First Adjustment Window): If the trajectory is positive, make incremental adjustments — small changes of 10–15% to base bids or placement modifiers, never multiple changes simultaneously. If performance has deteriorated materially from your pre-test baseline, evaluate whether the issue is the bidding configuration or an external factor (seasonality, listing change, inventory constraint).

    Weeks 7–8 (Optimization Phase): You now have approximately 60 days of data under the new configuration. At this point you can make more confident decisions about scaling, restructuring, or moving to the next layer in the framework.

    What Counts as a “Reset” Trigger

    Not every campaign change resets the learning period equally. Minor changes — adding a single negative keyword, adjusting budget by less than 20% — typically do not cause significant disruption. Major changes — switching bid mode, adding or removing large keyword groups, changing campaign structure, enabling or disabling a third-party bidding tool — will reset the model’s confidence in its conversion estimates. Apply the full eight-week protocol after any major change.

    Step Five: Portfolio Bidding and Budget Signals — Teaching the Algorithm What Matters

    Once individual campaigns are stable under a tested bid mode with understood placement behavior, the next layer is portfolio-level optimization. Portfolio bidding on Amazon allows you to set shared budget caps and, for some ad types, target ACoS or ROAS goals at the portfolio level rather than managing each campaign individually.

    This matters in 2026 because Amazon’s bidding engine increasingly looks at portfolio-level signals — not just individual campaign data — when modeling conversion probability. A campaign within a well-structured portfolio with a clear, consistent budget signal performs differently than the same campaign running in isolation. The algorithm uses budget pacing behavior, cross-campaign conversion patterns, and aggregate spend data as inputs alongside the keyword-level signals it has always processed.

    Budget Signals the Algorithm Reads

    Amazon’s AI bidding reads your budget behavior as a quality signal. Campaigns that run out of budget early in the day and go dark for hours create a fragmented performance history — the algorithm sees active-then-inactive patterns and struggles to model consistent conversion probability. Budget depletion events also suppress impression share during high-converting hours (typically mid-morning and early evening), replacing your AI-optimized bids with absence.

    Before adding portfolio-level controls, audit your daily budget utilization. If any campaign is consistently hitting its daily cap before 3 PM, the budget constraint is limiting what the AI can learn. Either raise the budget or reduce it deliberately to a level where the campaign can run all day on its existing allocation. Partial days create partial data.

    Portfolio ACoS Targets vs Campaign-Level ACoS Targets

    A common mistake in 2026 is setting a portfolio-level ACoS target that averages out fundamentally different product economics. A $15 accessory with a 60% margin should not share an ACoS target with a $150 appliance running at 25% margin. The algorithm receives a blended efficiency goal that is wrong for both products.

    Structure portfolios around products with similar margin profiles and similar business goals. Keep launch campaigns — where you deliberately accept higher ACoS to build conversion history — in separate portfolios from mature, efficiency-optimized campaigns. The portfolio’s ACoS target is a signal the AI uses to calibrate bid aggressiveness. A mixed signal produces mixed results.

    The Budget Increase Protocol

    When increasing campaign or portfolio budgets, Amazon’s guidance and practitioner consensus both suggest limiting single-step increases to approximately 20–30% of the current budget. Larger budget jumps can cause the AI to recalibrate its pacing model, temporarily overserving impressions in early-day hours and underserving in peak-conversion windows. Gradual increases preserve the pacing behavior the algorithm has learned and produce more stable performance through growth phases.

    Step Six: Amazon Ads Agent — Where It Actually Helps and Where It Doesn’t

    Amazon Ads Agent launched in early 2026 as an agentic AI campaign management layer built on Amazon’s Bedrock infrastructure. It allows advertisers to describe goals in plain English, receive proposed campaign setups, bid adjustments, keyword suggestions, and budget changes — then approve or reject those proposals before they go live. It is the closest thing Amazon has offered to a fully AI-managed campaign workflow within its native console.

    The key word is “proposed.” Amazon Ads Agent does not make changes autonomously by default — it surfaces recommendations for human review and approval. This is meaningful: it means the agent operates as an informed advisor rather than an autonomous bidder, and it means its effectiveness depends entirely on the quality of the input signals it receives.

    What Ads Agent Does Well

    Ads Agent is genuinely useful for three specific tasks. First, search term harvesting: the agent can identify converting search terms from auto-targeting campaigns and recommend promotion into exact-match manual campaigns, a task that is time-consuming and easy to deprioritize manually. Second, bulk bid adjustments: for accounts with dozens or hundreds of campaigns, reviewing and proposing bid changes at scale is where the agent saves the most time, surfacing the same adjustments that a skilled human manager would make but across a larger surface area faster. Third, campaign creation from briefs: describing a new product launch goal in natural language and receiving a structured campaign draft (with suggested keyword groups, match types, and initial bids) materially reduces the time from product launch to active advertising.

    Where Ads Agent Falls Short

    Ads Agent does not currently understand your product economics, inventory position, or margin structure. It optimizes for the performance metrics it can see inside Amazon Ads — clicks, conversions, ACoS — without any awareness that your ASIN is low on stock, that your margin on this product is 12% rather than 35%, or that this campaign’s goal is new-to-brand acquisition rather than immediate profitability. These strategic inputs still require human specification.

    The agent also performs significantly better when it is working with stable, clean campaign data. This brings us back to sequencing: Ads Agent should be introduced after you have established stable bid modes (Step Two), tested and calibrated placement multipliers (Step Three), and completed at least one full learning period (Step Four) on your primary campaigns. Activating the agent on a campaign that is still in its first 30 days of a new bidding configuration means the agent learns from noise and projects that noise forward into its recommendations.

    A Practical Activation Checklist for Ads Agent

    Before activating Ads Agent on any campaign, confirm: the campaign has at least 60 days of stable performance data; your ACoS target is explicitly documented and can be entered as a goal parameter; you have a human review cadence (minimum weekly) to evaluate proposed changes before approving them; and you have excluded any campaigns in active launch or experimental phases from the agent’s scope. Ads Agent is a force multiplier for stable, mature campaigns — not a replacement for the foundational work that makes those campaigns stable.

    Step Seven: Hourly Bid Scheduling via Amazon Marketing Stream

    Amazon Marketing Stream hourly bid scheduling heatmap showing peak and off-peak conversion windows with Tinuiti case study results

    Hourly bid scheduling is the most operationally advanced layer in the framework — and the one with some of the most dramatic published results. Amazon Marketing Stream provides near-real-time hourly performance data (traffic, conversions, CPC, ACoS, budget consumption) via the Amazon Ads API, updated hourly across Sponsored Products, Sponsored Brands, Sponsored Display, and DSP. Accessing this data requires API integration — either via a third-party tool that has built Marketing Stream integration or via a custom technical build.

    When Tinuiti applied historical hourly Marketing Stream data to identify peak conversion windows for a soda-category campaign and raised bids 40–55% during those windows, the results were notable: share of voice increased 104%, sales increased 273%, and new-to-brand units increased 570% at the account level. The test campaigns directly attributed 120% sales growth to the hourly optimization. These are extreme results in a particular category context, not a universal guarantee — but they illustrate the magnitude of value available when intraday conversion patterns are significant.

    How to Build an Hourly Bid Schedule

    The starting point is data collection, not adjustment. Before modifying any bids, you need at least four to six weeks of hourly Marketing Stream data to establish reliable conversion patterns. Most categories show identifiable peaks — commonly mid-morning (7–9 AM), lunch hours (12–2 PM), and evening windows (7–10 PM) — but these patterns vary significantly by product type, audience demographics, and category. Consumer electronics may peak differently from grocery; home goods may peak differently from automotive.

    Once your hourly conversion data reveals clear high-converting and low-converting windows, structure bid adjustments through a third-party tool (most major Amazon PPC platforms including Perpetua, Intentwise, and Quartile offer Marketing Stream-based dayparting), or via API rules if you have technical resources in-house. A reasonable starting range: reduce bids 15–25% during consistently low-converting hours and increase bids 20–40% during consistently high-converting hours. Adjust in increments, not all at once, and re-evaluate after four weeks as the bid changes may themselves shift which hours generate the most volume.

    When Hourly Scheduling Is Not Worth the Complexity

    Hourly bid scheduling adds meaningful operational complexity. It requires Marketing Stream API access, a technical integration layer, and ongoing monitoring to ensure that bid schedules remain aligned with actual conversion patterns as they evolve. For accounts spending under approximately $500 per day, this complexity is unlikely to generate returns that justify the investment — the conversion volume at that spend level may not be large enough to make hourly patterns statistically significant. At higher spend levels, particularly $1,000 per day and above, the efficiency gains from routing budget away from low-converting hours and toward peak windows can deliver meaningful annual savings.

    The Guardrail Stack: Bid Floors, Ceilings, and Exit Conditions

    No AI bidding system — native or third-party — should operate without a defined guardrail stack. Guardrails are the human-set constraints that prevent automation from optimizing toward local maxima that destroy account health: bids that run to zero and kill impression share, or bids that spike unconstrained during competitive auctions and blow through margin.

    Bid Floor: Your Non-Negotiable Minimum

    A bid floor prevents your AI from bidding so low that you lose impression share entirely. Calculate your floor based on the minimum CPC needed to remain competitive for your top-priority keywords in your category. This is not a fixed number — it varies by category and changes as competitor behavior evolves — but as a starting rule, your bid floor should sit at approximately 70–80% of your current average CPC for high-priority keywords. Below that level, you become invisible in the auction; above it, the AI has meaningful room to optimize downward without eliminating your presence.

    Bid Ceiling: The Protection Against Runaway Spend

    A bid ceiling caps the maximum your AI can bid on any individual keyword or placement. This is most critical when using dynamic bidding — up and down combined with placement multipliers, where effective CPCs can reach multiples of your base bid. Set your ceiling at the maximum CPC that still delivers a profitable conversion given your margin and target ACoS. The formula: bid ceiling = (product price × target ACoS × conversion rate). Any bid above this ceiling cannot, on average, produce a profitable result. Feed this number explicitly into your bidding tool’s cap settings.

    Exit Conditions: Knowing When to Turn It Off

    Every AI bidding experiment needs a predefined exit condition — a specific, quantified threshold at which you stop the test and revert to your control configuration. Without this, poor performers accumulate spend indefinitely while you wait for the algorithm to “figure it out.”

    Define exit conditions before each test, typically: if ACoS exceeds 150% of your target for more than 14 consecutive days after the initial learning period, revert to control; if conversion rate drops more than 30% relative to pre-test baseline and stays there for 7 days, revert; if campaign budget depletes before noon on more than 5 consecutive days, adjust budget before proceeding. These thresholds should be written down and checked systematically, not evaluated subjectively when you feel uncomfortable with the numbers.

    When to Escalate to Third-Party AI Bidding Tools

    Decision tree for choosing native Amazon AI bidding vs third-party tools based on spend level, catalog complexity, and portfolio needs

    Amazon’s native AI bidding infrastructure — dynamic bidding modes, portfolio controls, Ads Agent, and Marketing Stream — covers the majority of optimization needs for most accounts. Third-party AI bidding tools offer incremental capabilities in specific situations, but they are not universally superior to the native stack, and they introduce operational complexity that should be justified by expected returns before adding.

    In 2026, the gap between native Amazon AI and third-party AI tools has narrowed significantly. Amazon’s own algorithms have improved, Ads Agent has added meaningful automation, and Marketing Stream has brought intraday granularity that was previously only available via external integrations. For accounts under approximately $1,000 per day in spend with a catalog of fewer than 50 ASINs, the native stack is the rational starting point.

    Cases Where Third-Party Tools Add Genuine Value

    Third-party tools — platforms like Perpetua, Quartile, Intentwise, and several others — earn their place in three specific scenarios.

    First, cross-campaign portfolio optimization at scale. For accounts managing hundreds of campaigns across dozens of ASINs, native tools require significant manual effort to coordinate budget reallocation across campaigns. Third-party platforms can rebalance spend across the entire portfolio in response to real-time performance signals — moving budget from underperforming campaigns to overperforming ones intraday. Amazon’s native portfolio tools offer some of this, but the external platforms generally operate with more sophistication at high campaign counts.

    Second, margin-aware bidding. Native Amazon bidding optimizes to ACoS, ROAS, or click volume — it does not know your cost of goods, fulfillment fees, or net margin. Third-party tools that integrate product economics data can bid to true profitability rather than proxy metrics. For catalogs with highly variable margins, this distinction matters significantly.

    Third, cross-marketplace coordination. Sellers active across multiple Amazon marketplaces (US, EU, UK, Japan) managing coordinated campaigns benefit from third-party platforms that can apply shared learning and budget coordination across geographies — something native Amazon tools cannot currently do.

    The Overlay Risk

    The most important caution with third-party tools is what happens when their bid adjustments conflict with or layer on top of Amazon’s native AI adjustments. If Amazon’s dynamic bidding algorithm is adjusting bids in real time and your third-party tool is also adjusting bids on a 15-minute cycle, both systems are operating on delayed information about what the other has just done. The result can be erratic effective CPCs and unstable learning data for both systems.

    Best practice in 2026: when using a third-party bidding tool, set Amazon’s native bid mode to “fixed bids” for those campaigns, giving the external tool full control rather than running two competing AI systems simultaneously. Establish which layer has authority, and stick to it.

    What Good Testing Infrastructure Looks Like in Practice

    The framework above is a sequence of decisions. Making those decisions well requires a consistent measurement infrastructure that most Amazon advertisers do not have in place. Here is what that infrastructure needs to include.

    A Documented Pre-Test Baseline

    Before each test in the sequence, document your current performance metrics: average daily spend, ACoS, conversion rate, CPC, and impression share over the prior 30 days at the campaign level. Without this baseline, you cannot assess whether the test delivered an improvement, a degradation, or no measurable change. This sounds obvious, but a significant number of advertisers run tests without recording the starting state and then evaluate outcomes by feel rather than by comparison.

    Consistent Reporting Cadence

    During any active test, pull placement reports, search term reports, and campaign performance reports weekly — not daily. Daily data on Amazon is highly volatile due to attribution delays and normal auction variance. Weekly data provides a smoother, more reliable signal. Monthly data is too infrequent to catch issues before they compound. Weekly is the right cadence during active experiments.

    One Variable at a Time — Enforced as a Rule

    This principle appears in every PPC testing framework ever written, and it is violated in every account examined by every agency that has ever conducted an audit. The pressure to make multiple improvements at once is real — you have a list of things you want to fix, and changing one at a time feels slow. The cost is that you never know what worked, which means you cannot scale what works or avoid what doesn’t.

    In AI bidding specifically, the cost of violating this principle is higher than in manual bidding, because each change resets the algorithm’s learning state. Multiple simultaneous changes do not reset the learning period once — they reset it into a configuration where the algorithm is building a model for a state that may change again before the model has stabilized. The compounding confusion can set performance back months.

    An ACoS Waterfall by Product Lifecycle Stage

    Document your ACoS targets explicitly by product lifecycle stage. Launch-phase ASINs should have a deliberately higher ACoS target (you are paying to build conversion history). Growth-phase ASINs should have a moderate target. Mature, high-volume ASINs should have a tight efficiency target. Each stage implies a different bidding mode, different exit conditions, and different intervention thresholds. Without this documentation, you will inevitably apply efficiency-phase thinking to launch campaigns and kill their velocity, or apply launch-phase thinking to mature campaigns and erode their margin.

    The Sequence Is the Strategy

    Amazon Ads AI bidding in 2026 is genuinely powerful. The algorithms have improved, the data infrastructure has deepened, and the tools — from Ads Agent to Marketing Stream hourly data — provide capabilities that required expensive third-party solutions or custom engineering just two years ago. The frustrating reality, however, is that power does not equal performance. The accounts that are extracting the most from these systems are not the ones with the most advanced tools. They are the ones that built the right foundation in the right order.

    The sequence matters because each layer feeds the next. Clean conversion data makes AI bidding stable. A stable bid mode makes placement testing interpretable. Understood placement behavior makes portfolio ACoS targets accurate. Accurate targets make Ads Agent recommendations trustworthy. Trustworthy recommendations, combined with hourly Marketing Stream data, make intraday bid scheduling genuinely useful rather than just technically possible.

    Running these steps out of order — or running them all at once — collapses the clarity that makes each step work. The accounts that report AI bidding “doesn’t deliver results” have almost universally skipped the audit, changed too many things at once, evaluated outcomes before learning periods completed, or added AI on top of a structurally broken campaign foundation.

    The Practical Starting Point for This Week

    If you are reading this with an active Amazon Ads account and want to know where to start, the answer is the pre-test audit in Step One. Pull your last 30 days of conversion data by campaign, check each campaign for the four diagnostic criteria, and identify which campaigns have the data quality to support AI bidding and which ones need foundational work first. That audit, completed honestly, will tell you more about your account’s current situation than any bidding tool or algorithm setting can.

    From there, the framework gives you a sequence. Follow the sequence. Let each step complete before starting the next. Document your baseline before each change. Set exit conditions before you begin. And resist the pressure to accelerate — in AI bidding, patience at each step is not passivity. It is the mechanism by which the algorithm learns to deliver the results you are trying to measure.

    Key takeaways: Complete your four-point pre-test audit before changing any bid setting. Start with dynamic bidding — down only as your default mode. Test placement multipliers only after bid mode is stable. Protect the learning period from interference for at least 4 weeks after any major change. Build portfolio structures around products with similar margins. Introduce Ads Agent only on mature, stable campaigns. Explore hourly scheduling at scale only after the preceding layers are working. Always define guardrails and exit conditions before starting any test.

  • Search-Term-First SBV Targeting: Mining Your SP Data for Amazon Video Ad Wins

    Search-Term-First SBV Targeting: Mining Your SP Data for Amazon Video Ad Wins

    Search-Term-First SBV Targeting — Turn SP Data Into Amazon Video Ad Wins

    Most Amazon advertisers approach Sponsored Brands Video the wrong way. They start with the creative — picking a product, shooting a video, and then going into the campaign builder to think about keywords as an afterthought. The result is a beautifully produced video ad chasing keywords that have never proven they can convert, burning budget against intent signals it hasn’t earned the right to target yet.

    The smarter path runs in the opposite direction. You start with the data you already have — specifically, the search term report sitting inside your Sponsored Products campaigns right now — and you use it to identify exactly which customer queries have demonstrated the ability to drive purchases before you spend a dollar on video. Then, and only then, do you build your SBV campaigns around those proven terms.

    This is what search-term-first SBV targeting actually means. It is not a creative-led strategy with keywords bolted on at the end. It is a data-led strategy where every video placement you run is anchored to a query that has already passed a conversion test in a lower-cost environment. The creative serves the term. The bid serves the term. The campaign structure serves the term.

    As of 2026, Sponsored Brands Video accounts for roughly 58% of total Sponsored Brands spend across managed Amazon advertising accounts — making it the default format rather than a specialty option. The opportunity is real. But so is the waste for advertisers who haven’t built a systematic way to decide which search terms deserve a video impression in the first place. This post builds that system from the ground up.

    Why SBV Has Earned Its Place at the Top of the Funnel

    Static Sponsored Brands versus Sponsored Brands Video CTR comparison — SBV delivers up to 3x higher click-through rates

    Before getting into the mechanics of mining SP data, it’s worth being precise about what makes SBV different enough to warrant its own keyword strategy — because the answer is more specific than “video performs better than images.”

    The Placement Is the Differentiator

    Sponsored Brands Video occupies a distinct placement that static Sponsored Brands ads and Sponsored Products ads cannot. It appears as an autoplay video strip within the organic search results — not above them, not beside them, but embedded directly inside the page that shoppers are actively reading. That placement creates a fundamentally different interaction dynamic.

    A shopper browsing search results for “stainless steel insulated water bottle” is in a comparison state of mind. They are evaluating products side by side. A static banner above those results asks them to stop and look upward. An SBV placement asks for nothing — it begins playing in their peripheral view as they scroll, and it either earns attention through motion and clarity or it doesn’t. This is why SBV’s click-through rate advantage over static Sponsored Brands is consistently reported in the 1.5x to 3x range.

    An Amazon Science study spanning 15 countries found CTR lifts of 17x for SBV versus static image formats in controlled conditions. Real-world account data is more moderate — most practitioners report 1.5x to 2.5x lift in their actual campaigns — but even the conservative end of that range changes the CPC economics significantly. More clicks at the same CPC means more conversion opportunities, which is why SBV’s conversion rate also runs roughly 10% to 30% above equivalent static Sponsored Brands campaigns for the same terms.

    The Format Rewards Intent, Not Just Awareness

    One of the common misconceptions about video advertising is that it belongs at the awareness stage of the funnel — that it is inherently a brand-building tool rather than a performance tool. SBV demolishes that framing. Because it is keyword-targeted and appears within search results, it reaches shoppers who have already expressed intent through their query. The video format doesn’t move them away from purchase consideration — it accelerates it by delivering richer product information in the moment of search.

    This is the core insight that makes search-term-first SBV targeting so powerful: when you put a video behind a high-intent keyword, you are not trading performance for brand — you are stacking both in the same impression. The term captures the intent. The video converts it.

    SBV Is Now the Default, Not the Exception

    The 58% share-of-Sponsored-Brands-spend figure cited above reflects a structural shift that has been building since 2024. Amazon has progressively made SBV easier to launch — simplifying the creative specifications, lowering the technical bar for video production, and expanding the placement to more device types. In competitive categories like home goods, supplements, pet supplies, and personal care, SBV placements now appear on almost every major search page, which means not running SBV is effectively ceding premium in-search real estate to competitors who are.

    The strategic question is no longer whether to run SBV. It’s which terms to run it on, and how to decide. That answer lives inside your SP data.

    The SP Search Term Report as a Targeting Intelligence Engine

    Amazon search term report with color-coded qualification tiers — SBV-Ready, Watch List, and Negative Now

    Your Sponsored Products campaigns are, functionally, a keyword testing lab. Every day they are running broad match, phrase match, and auto-targeting, they are collecting data on which exact customer queries led to clicks, which of those clicks led to purchases, and at what cost. This data is captured in the search term report, and it represents something genuinely valuable: real shopper behavior, not projected behavior.

    What the Report Actually Contains

    The Amazon Ads search term report shows the actual queries customers typed before clicking your SP ads. For each query, you can see impressions, clicks, click-through rate, spend, attributed orders, attributed sales revenue, and cost-per-click. Critically, you can also see the keyword that matched the query — meaning you can distinguish between a query that your broad match keyword triggered versus one your phrase match keyword triggered, which has implications for confidence in the data.

    Amazon retains up to 65 days of search term data accessible in the native reporting interface, and the Ads Console UI allows export for the past 90 days. For SBV keyword seeding purposes, a 30 to 60-day window is the most actionable — long enough to have statistically meaningful data, recent enough to reflect current demand patterns and seasonal relevance.

    The Data Hierarchy That Matters for SBV

    Not all columns in the search term report are equally important when you are mining for SBV candidates. The metrics that matter most, in order of priority:

    • Orders attributed: This is the bedrock qualifier. A query that has never produced an order has not proven purchase intent, regardless of its click volume. For SBV, where CPCs tend to run higher than SP, only proven converters justify the investment.
    • ACoS (Advertising Cost of Sale): Calculated as spend divided by attributed sales. A term that converts but at an ACoS far above your target is a conversion signal with poor efficiency — it may still qualify for SBV if you believe the creative improvement will reduce CPC, but it needs a tighter bid structure.
    • Click-through rate relative to impressions: High impressions with low CTR can indicate poor listing-page relevance or competitive listing quality. A term with excellent CVR but middling CTR is actually a strong SBV candidate — because better creative (video versus static) is exactly what can close the gap.
    • Conversion rate (CVR): Orders divided by clicks. This is the most reliable signal of query-to-purchase alignment. Terms with CVR significantly above your account average are priority SBV candidates because they demonstrate that shoppers who arrive via that query are predisposed to buy.

    Downloading and Preparing the Report

    To access the data, navigate to Amazon Ads Console → Reports → Create Report → Sponsored Products → Search Term. Set the date range to the past 30 to 60 days, select all available metrics, and export to CSV. From there, the analysis process is the same whether you work in Excel, Google Sheets, or a dedicated PPC tool — filter, sort, and score terms against the qualification criteria detailed in the next section.

    One important note: the report shows customer search terms at the campaign level. If your SP campaigns are not already segmented by product category or match type, your data may be difficult to interpret because high-performing terms from different product categories or intent stages will be mixed together. If your SP campaign architecture is messy, cleaning it up first will make your SBV keyword mining significantly more accurate.

    Setting the Right Filters — What Actually Qualifies a Term for SBV Promotion

    The most common mistake when mining SP data for SBV is using too low a bar. A term that converted twice in 30 days at a borderline ACoS is not an SBV keyword — it’s a keyword that needs more data in SP before it earns a more expensive placement. Being selective at this stage is not cautious; it’s what keeps your SBV campaigns from becoming a vehicle for testing on expensive impressions.

    The Three-Gate Qualification Framework

    Apply these gates sequentially. A term must pass all three to qualify for SBV promotion:

    Gate 1 — Minimum Conversion Activity: The term must have generated at least 3 to 5 orders in the reporting window. Below this threshold, conversion data is too noisy to act on. Some practitioners use a higher threshold of 5 to 10 orders for high-competition categories where CPCs are elevated. The specific number matters less than having a minimum that filters out statistical noise.

    Gate 2 — Acceptable Efficiency: The term’s ACoS must be at or below 150% of your target ACoS. So if your target ACoS is 20%, terms up to 30% ACoS can qualify with the assumption that SBV’s creative improvement may reduce CPC and improve CVR enough to bring it into range. Terms above this threshold need remediation in SP first — fixing bids, improving listing conversion rate, or both — before they deserve a video placement.

    Gate 3 — Volume Adequacy: The term must have generated at least 100 to 200 impressions in the reporting window. Terms with very low impression counts, even if they converted, do not have enough volume to sustain an SBV campaign. SBV CPCs are typically higher than SP CPCs, and low-impression terms often have thin search volume that will not deliver meaningful scale.

    Secondary Scoring for Prioritization

    After applying the three gates, you will typically have a list of qualified terms that is longer than your initial SBV budget can support. Prioritize by scoring each term on a combination of:

    • CVR premium: How much does this term’s conversion rate exceed your SP account average? Higher premium = higher priority.
    • Revenue per click: Attributed sales divided by total clicks. Higher revenue per click terms produce more value per SBV impression regardless of CPC.
    • Competitive sensitivity: Is this a generic category term, a branded competitor term, or your own brand term? Each category has a different priority logic for SBV (covered in more detail in the campaign architecture section below).

    The output of this scoring process is a tiered list: your top-priority SBV exact match candidates, your second-tier phrase match candidates, and a watch list of terms that are close to qualifying but need another 30 days of SP data before promotion.

    Campaign Architecture — Building SBV Campaigns Around Harvested Terms

    Three-tier SBV campaign architecture diagram — Exact Match proven converters, Phrase Match expansion, SP Auto/Broad discovery

    Once you have your qualified, scored list of SBV-ready search terms, the campaign structure you build around them determines whether the system is manageable, measurable, and improvable over time.

    The Three-Campaign Stack

    The cleanest SBV architecture for search-term-first targeting uses three distinct campaign types, each with a defined role:

    Tier 1 — SBV Exact Match (Proven Converters): This is where your highest-priority terms go. Exact match gives you precise control — you know exactly which query triggered the impression, you can set specific bids per keyword, and you can measure performance at the term level with confidence. Budget allocation here should be your heaviest, as these are the terms with demonstrated purchase intent and the highest confidence in their conversion behavior.

    Tier 2 — SBV Phrase Match (Expansion Layer): Your second-tier terms — those that qualified but with lower scores — go here as phrase match keywords. Phrase match allows close variants and additional words around your core term, which creates controlled volume expansion. You will collect new search term data at the SBV level that can feed future exact match promotions or negative keyword additions.

    Tier 3 — SP Auto/Broad (Discovery Engine — not SBV): This is your existing SP infrastructure, continuing to do what it does best: discover new search terms through broad match and auto targeting. This tier feeds qualified new terms upward into the SBV tiers on a regular review cadence (typically every 30 days).

    Ad Group Architecture Within SBV Campaigns

    Within your SBV exact match campaign, resist the temptation to pile all keywords into a single ad group. Segmenting ad groups by intent cluster allows you to align creative more precisely with the shopper’s mindset and, importantly, allows you to run different video creatives for different query types.

    Practical intent clusters that work well for SBV ad group segmentation:

    • Category-generic terms (e.g., “insulated water bottle”) — high volume, competitive, discovery intent
    • Feature-specific terms (e.g., “leak proof water bottle with straw”) — lower volume, higher CVR, feature-match intent
    • Use-case terms (e.g., “hiking water bottle 40oz”) — mid volume, lifestyle intent, strong upsell/lifestyle creative potential
    • Competitor brand terms (e.g., “Hydro Flask alternative”) — high intent, conquest context, requires specific creative framing

    Each cluster gets its own ad group, its own video creative (where budget allows), and its own performance benchmarks. This granularity is what allows you to see not just “does SBV work?” but “which intent context does SBV perform best in?” — which is the question that drives meaningful optimization.

    Budget Allocation Across Tiers

    A practical starting split for accounts new to search-term-first SBV targeting: 70% of SBV budget to Tier 1 exact match, 30% to Tier 2 phrase match. As exact match campaigns accumulate sufficient data and you’ve confirmed performance, you can increase total SBV budget while maintaining this ratio, or shift more toward exact match as phrase match terms graduate.

    Keep SBV campaigns separate from static Sponsored Brands campaigns. Mixing formats within the same campaign prevents clean performance analysis and makes bid management unnecessarily complex. The separation also makes it much easier to track SBV-specific metrics like view rates and the new-to-brand percentage that video tends to generate.

    Match Type Strategy: Why Exact-First Thinking Governs the Whole System

    There is a recurring debate in Amazon PPC circles about whether to launch SBV campaigns broad or narrow. Some practitioners argue for starting broad to collect data quickly. Others argue for starting narrow to control spend. When you’re operating a search-term-first system sourced from SP data, this debate resolves itself: you already have the data. You don’t need broad match to discover what works — you know what works. Exact-first is not caution; it’s precision informed by evidence.

    Why Exact Match Is the Right Starting Point for SBV Candidates

    When you promote a term from SP into SBV exact match, you have a specific piece of knowledge: this exact customer query, typed in this exact way, has driven purchases at an acceptable efficiency in your SP campaigns. Exact match in SBV preserves that precision. You know your ad will appear when shoppers type that query (and close variants), and you can set your bid based on the CVR and revenue-per-click data you already have.

    Launching those same terms as phrase or broad match in SBV introduces variability — the ad may appear for queries that look similar but behave differently. A phrase match on “stainless steel insulated water bottle” will also trigger for “stainless steel insulated water bottle for kids” and “best stainless steel insulated water bottle 2026” — queries you may not have data on. If those variants don’t convert, you are paying SBV CPC rates for impressions that your SP data would have told you to avoid.

    When to Introduce Phrase Match in SBV

    Phrase match becomes appropriate in SBV under two conditions: First, when your exact match campaigns are hitting budget limits regularly, indicating your exact match terms are too restrictive for the available demand. Second, when you want to deliberately expand coverage to related intent variants that you haven’t yet tested in SP — essentially using SBV phrase match as a slightly more expensive version of SP discovery.

    If you use SBV phrase match for discovery, treat the SBV search term reports from those campaigns as a secondary source of exact match candidates — for both SBV and, potentially, for expansion in SP where the CPC will be lower and data collection more cost-efficient.

    Broad Match in SBV: Handle with Care

    Broad match in SBV campaigns is best avoided for terms that haven’t proven their performance in SP first. Amazon’s broad match can trigger for queries with significant semantic distance from your target term, and at SBV CPC rates, that discovery cost is high. If you want to use SBV for pure brand discovery (reaching shoppers with no prior SP data), that is a legitimate strategy — but it should be in a separate campaign with a separate budget, clearly labeled as awareness-stage spend, and measured with different KPIs than your performance SBV campaigns.

    Creative That Actually Converts at the Keyword Level

    15-second SBV video timeline showing the four key segments with muted-viewing design principles — 71% of SBV views are muted

    Search-term-first targeting tells you where to run your video. It doesn’t tell you what the video should say. The creative layer is where the targeting logic and the shopper experience connect — and getting it wrong can negate the advantages of even the most carefully selected keyword set.

    Design for Muted Viewing First

    As of 2026, an estimated 71% of SBV views are played with sound off, up from roughly 64% two years prior. The trend toward muted autoplay viewing is structural — it reflects how people shop on Amazon in real-world environments (offices, public transit, shared spaces). This means your SBV creative must be fully comprehensible without audio. If the primary message of your video relies on a voiceover that a muted viewer will never hear, the video is failing the majority of its audience.

    The practical rule: close-caption every piece of speech in the video, and more importantly, put the core product benefit statement as a large, readable on-screen text element that appears within the first three to four seconds. Don’t treat captions as an accessibility afterthought — treat them as the primary communication layer.

    The 15-Second Timeline That Works

    Amazon allows SBV formats ranging from 6 to 45 seconds, but practitioner data consistently points to 15 to 20 seconds as the sweet spot for search-result placements. Longer videos may perform well on product detail pages, but in the search results context, shorter is better because the format competes with organic listings and the shopper’s primary goal is evaluation, not entertainment.

    A practical 15-second structure that aligns with search-result intent:

    • Seconds 0–3: Product clearly in frame. No logo reveal, no cinematic opening. The product should be recognizable within the first two seconds. This is when most drop-off decisions happen.
    • Seconds 3–8: Primary benefit stated on-screen in readable text. This should answer the implicit question behind the keyword. A shopper who typed “leak proof water bottle” should see “100% Leak Proof, Guaranteed” within the first five seconds.
    • Seconds 8–13: Supporting proof — a quick product demo, a use-case shot, or a secondary benefit. This is where lifestyle context can help without replacing product clarity.
    • Seconds 13–15: Call to action. “Shop Now” is the standard. Consider including a brief differentiation statement here — “Free shipping on Prime orders” or a specific offer — that creates urgency without overpromising.

    Aligning Creative to Keyword Intent

    This is the operational implication of search-term-first targeting that most advertisers miss: if you have segmented your SBV ad groups by intent cluster (as described in the campaign architecture section), you should be running different video creative for different clusters where budget allows.

    A shopper who typed “hiking water bottle 40oz” is in a different mental context than one who typed “stainless steel water bottle office.” The first shopper wants to see outdoor usage context — rugged terrain, a trail, a daypack. The second shopper wants to see clean design, desk compatibility, professional aesthetics. Running the same generic product video against both terms is leaving persuasion efficiency on the table.

    You don’t need an unlimited video production budget to do this. Simple video variants — changing the opening shot, swapping the benefit headline text, showing a different use context in seconds 8 to 13 — can be produced as edits of a core video asset rather than entirely separate productions. The key is matching the opening frames and the benefit headline to the specific shopper intent cluster you’re targeting.

    Amazon’s Autoplay Loop and the Scroll Behavior Problem

    SBV autoplays and loops continuously as shoppers scroll past. This is both an advantage (multiple exposures per page load) and a creative constraint (the video must make sense when entered at any point in the loop, not just from the beginning). Design your creative so the product and primary benefit are visible throughout the video, not just in the final seconds. Treat the loop as a feature, not an afterthought — a shopper who catches the second playthrough should understand your product as well as one who saw it from the start.

    Bidding Logic for SBV — Why SP Benchmarks Don’t Translate Directly

    One of the most common errors in SBV campaign setup is taking the CPC benchmarks from SP campaigns and applying them unchanged to SBV bids. The two formats operate in different auction environments with different competitive dynamics, and treating them as interchangeable will either leave impressions on the table (underbidding) or erode margin (overbidding).

    Why SBV CPCs Are Structurally Different

    SBV ads compete in a separate auction from Sponsored Products. The bidders are fewer — not every advertiser running SP on a given keyword is also running SBV — and the placements are more prominent (in-stream, high-visibility, autoplay). This creates variable CPC dynamics by category:

    • In categories where SBV adoption is high (supplements, beauty, home goods), SBV CPCs can be close to or exceed SP CPCs because competition for the placement is active.
    • In categories where SBV is less adopted, CPCs may be meaningfully lower than SP while delivering significantly higher CTR — an exceptionally favorable efficiency combination.
    • Branded keyword SBV is typically the most efficient placement in terms of CPC-to-conversion ratio, because brand-loyal shoppers click at high rates and competitors are less likely to bid aggressively on your own brand terms.

    Building a Starting Bid Framework from SP Data

    Use your SP data to calculate revenue-per-click for each qualified SBV term: attributed sales divided by total clicks over the reporting period. This gives you the maximum CPC you can afford at breakeven on that specific term, assuming the same conversion rate applies in SBV. Then apply a discount factor to account for the assumption that SBV conversion rates may not exactly match SP conversion rates initially — a common starting factor is 0.7 to 0.85 (bidding 70% to 85% of your calculated maximum CPC).

    As your SBV campaigns accumulate data over the first 30 days, compare actual SBV CVR to the SP CVR assumption. If SBV is converting at a higher rate (common due to the creative improvement), you can increase bids toward the maximum. If it’s converting at a lower rate (sometimes seen when the video creative isn’t well-matched to the keyword intent), investigate the creative alignment before adjusting bids.

    Dayparting and Budget Pacing in SBV

    SBV campaigns tend to perform differently by time of day than SP campaigns, reflecting the different attention states shoppers bring to video content. Late morning and early evening hours typically show the strongest SBV engagement rates — shoppers who are in a more deliberate browsing mode rather than quick mobile searches. Amazon’s own campaign scheduling tools allow budget adjustments by day, though not yet by hour in all markets. Monitor your SBV impression and click data by day of week during the first month to identify any meaningful patterns in your specific category.

    Measuring SBV Performance Beyond ROAS

    SBV measurement dashboard showing ROAS versus New-to-Brand, Branded Search Lift, and Organic Rank — ROAS is only half the story

    ACoS and ROAS are the metrics Amazon advertisers default to because they are familiar, comparable across campaigns, and easy to understand. For SBV, they are also incomplete. Relying on ROAS alone to evaluate SBV performance leads to two systematic errors: undervaluing campaigns that deliver strong brand growth alongside modest direct ROAS, and over-pruning keyword targets that are building brand equity that will show up in organic performance weeks later.

    New-to-Brand Metrics: The Primary Incremental Signal

    Amazon’s new-to-brand (NTB) metric tracks orders from customers who have not purchased from your brand within the past 12 months. This is, in practical terms, a proxy for incremental customer acquisition — the metric that reflects whether your advertising is reaching genuinely new customers or simply recapturing existing ones who would have purchased anyway.

    SBV consistently shows higher NTB percentages than Sponsored Products campaigns for the same keywords. This makes structural sense: SBV’s prominent, autoplay placement is more likely to capture attention from shoppers who are still in evaluation mode versus those who are specifically seeking your brand. A campaign that delivers a 45% NTB rate is doing something different and more valuable than one with a 20% NTB rate, even if their headline ROAS figures are identical.

    Track NTB % per keyword cluster, not just per campaign. This granularity reveals which intent clusters are driving customer acquisition (typically category-generic and feature-specific terms) versus which are capturing repeat purchase intent (often brand terms). Neither pattern is inherently better, but they call for different measurement frameworks and different success benchmarks.

    Branded Search Lift as a Lagging Indicator

    One of SBV’s most economically significant — and least measured — effects is its impact on branded search volume. When shoppers see your brand video in search results for a category term, some portion of them who don’t click immediately will later search specifically for your brand. This creates a halo effect in branded search that shows up as increased impression share on your own branded terms in SP and SBV.

    To measure this, track weekly branded search impression volume in your SP brand campaigns. If you launch SBV on high-volume category terms and branded search impressions begin rising two to four weeks later, that is likely a SBV halo effect. Amazon’s Brand Analytics tool — specifically the Search Query Performance report — can show you branded query growth over time if you are enrolled in the relevant Brand Registry tier.

    Organic Rank Correlation

    A well-structured SBV campaign running on high-volume category terms can indirectly support organic rank by driving increased sales velocity, which is one of the signals Amazon’s ranking algorithm considers. This is not a guaranteed or direct effect, but categories and ASINs where SBV has been running aggressively on category terms for 60 or more days sometimes show organic rank improvements that cannot be fully explained by SP activity alone.

    Measure this by tracking organic rank for your target keywords using a rank tracking tool (or manual search snapshots at consistent intervals) and correlating movements with SBV campaign spend levels. Be cautious about drawing causal conclusions from short time windows — rank data is noisy — but over 60 to 90 days, meaningful patterns do emerge for well-run SBV campaigns.

    View-Through Metrics: What to Track and What to Ignore

    Amazon provides video-specific metrics in SBV campaigns: impressions, video views, view-through rate (VTR), and first quartile, midpoint, and complete view percentages. These metrics are useful for diagnosing creative performance — a video with a very low midpoint completion rate is losing viewers before the core message lands — but they are secondary to conversion metrics for keyword-level optimization decisions. Track VTR at the ad group level to assess creative quality; track CVR and NTB at the keyword level to make targeting decisions.

    Negative Keyword Discipline — The Step Most SBV Builders Skip

    Building a high-quality SBV campaign is half about which terms you target and half about which terms you actively exclude. Negative keyword management in SBV is less discussed than in SP, partly because SBV’s higher CPC makes wasted impressions less tolerable, and partly because the search term data in SBV campaigns provides a second layer of qualification data that requires active management.

    Cross-Campaign Negatives to Prevent Cannibalization

    When you promote a term from SP exact match into SBV exact match, both campaigns are now eligible to show for that query. If both trigger simultaneously, you are bidding against yourself — driving up the CPC you pay in the auction and potentially showing two of your own ads on the same results page (which can look redundant to shoppers and is inefficient from a spend perspective).

    The solution is to add the promoted term as a negative exact match keyword in your SP campaigns when it graduates to SBV. This is the “graduation and negation” principle: promote the term upward, negate it in the originating campaign. The term now lives exclusively in your SBV exact match campaign, where it will receive the video placement, and the SP campaign continues searching for new terms through broader match types.

    SBV Internal Negatives: Managing Phrase and Broad Match Bleed

    If you are running SBV phrase match alongside exact match, add your exact match terms as negative exact keywords in your phrase match campaign to prevent the phrase match campaign from triggering on queries already covered by exact match. Without this, your phrase match campaign will generate impressions on your best-performing terms at a less controlled bid, muddying your performance data and potentially overpaying.

    This cross-campaign negative structure is sometimes called a “waterfall” or “cascading negative” setup. The logic is that each tier only sees queries not already captured by the tier above it. Implementing this properly ensures that each campaign in your SBV stack is doing distinct work: exact match handles proven terms at precise bids, phrase match handles expansion terms at slightly looser bids, and neither overlaps with the other.

    Category-Level Negatives Based on SBV Search Term Reports

    After four to six weeks of running, pull the search term reports from your SBV phrase match campaigns. You will find queries that triggered the ads but showed no conversion — and some that showed very high CPC with very low CTR, indicating poor query relevance. Add these as negative phrase match keywords. This pruning process, repeated monthly, progressively tightens the quality of your SBV targeting and reduces the percentage of spend going to non-converting impressions.

    Pay particular attention to navigational queries (shoppers looking for a specific brand they already know), informational queries (shoppers in research mode, not purchase mode), and unrelated product queries that share surface-level word similarity with your keywords. These three categories are responsible for the majority of wasted SBV spend in accounts without active negative management.

    Scaling the System — When to Expand, When to Hold, When to Kill

    SBV scaling decision matrix — four quadrants based on search volume and conversion efficiency, from Scale Now to Kill

    A search-term-first SBV system is not set-and-forget. It is a living structure that requires periodic review to determine which keywords deserve more investment, which need creative intervention before scaling, and which should be removed entirely to protect budget efficiency.

    The Four-Quadrant Scaling Framework

    Evaluate each keyword cluster in your SBV campaigns against two axes: search volume (the available impression pool) and conversion efficiency (actual CVR relative to your target). This creates four decision quadrants:

    • High volume, high efficiency: Scale immediately. Increase bids toward your maximum CPC (calculated from revenue-per-click), add phrase match variants, and consider additional video creative variants to test different hooks or benefit messages.
    • Low volume, high efficiency: Hold and watch. These terms are performing well but may have a small addressable audience. Don’t cut budget, but don’t dramatically increase it either. Focus instead on ensuring creative is strong so you capture all available impressions efficiently. Monitor for volume growth over time.
    • High volume, low efficiency: Investigate before cutting. High-volume terms with poor efficiency have a diagnosis problem before they have a spend problem. Common causes: bid is too high relative to actual CVR, creative is not aligned to the query intent, or the product listing page has a conversion issue independent of the ad. Fix the diagnosis first, then reassess efficiency.
    • Low volume, low efficiency: Remove and reallocate. These terms are consuming budget at an inefficient rate on a small audience. Return them to SP phrase or broad match for further testing at lower cost and revisit in 60 days.

    The 30-Day Review Cadence

    SBV campaigns need at minimum a monthly review cycle to function efficiently at scale. The review covers three activities: pulling the search term report from phrase match campaigns to find new exact match candidates, auditing bid levels against updated revenue-per-click calculations, and checking creative metrics for signs that video performance is declining (dropping VTR or rising CPC with flat CVR often signals creative fatigue in high-frequency categories).

    Some high-spend advertisers move to bi-weekly review cycles. The right cadence depends on budget scale — a $1,000/month SBV account can afford monthly reviews; a $50,000/month account cannot. In general, review frequency should scale with the dollar amount at risk in the period between reviews.

    Expanding Into New Term Categories

    Once your initial SBV exact match campaigns are performing well, the next expansion opportunity is term categories you haven’t yet targeted. The most systematic way to identify these is to look at your SP auto-targeting campaigns and extract any intent clusters that have not yet been promoted to SBV — use case terms, accessory-related terms, problem-state terms (terms describing the problem your product solves rather than the product itself). Run these through the same three-gate qualification process described earlier. If they qualify, promote them into SBV with appropriate creative.

    Competitor brand terms deserve their own consideration. They typically require specific creative framing — positioning your product as an alternative or comparison rather than simply demonstrating product benefits — and they often show different CVR patterns than generic category terms. If your SP data shows strong conversion on competitor brand terms, they can be viable SBV candidates, but budget them separately and track them with their own benchmarks.

    Common Mistakes That Undermine Search-Term-First SBV Campaigns

    The system described in this post is logical when laid out in sequence, but in practice several failure patterns appear repeatedly in SBV campaigns that claim to be data-driven but aren’t truly operating search-term-first.

    Using SP Impression Data Instead of Conversion Data as the Primary Filter

    High-impression terms in SP are attractive — they suggest there is a large audience for the query. But impressions without conversion data only tell you that the query has volume, not that it converts. SBV built around high-impression, low-conversion terms will generate views but not orders. Always filter on conversion activity first. Volume is a secondary consideration.

    Skipping the Negative Keyword Setup at Launch

    New SBV campaigns are often launched without any negative keywords because the thinking is “we’ll add negatives once we see what’s converting.” This is backwards. At a minimum, you should add known irrelevant terms as negatives at launch — terms that triggered in SP with zero conversions, informational queries, and competitor navigational terms. Waiting until the SBV campaign generates its own wasteful data means paying SBV rates to discover what your SP data already told you.

    Running a Single Video Creative Across All Intent Clusters

    Generic product videos that perform adequately across all keyword types perform excellently for none of them. If your budget only allows for one video initially, accept that constraint and plan for creative variants as the campaign matures. But don’t rationalize one creative as “good enough” — it is a starting point, not an endpoint. Creative alignment to keyword intent is one of the highest-leverage optimization opportunities available in SBV.

    Measuring SBV on the Same Efficiency Target as SP

    Setting the same ACoS target for SBV and SP campaigns systematically undervalues SBV’s contribution. Because SBV drives higher NTB percentages and creates branded search halo effects, its true economic contribution exceeds what last-click ACoS captures. Set SBV efficiency targets at a modest premium — typically 20% to 35% higher ACoS tolerance than your SP target — and evaluate NTB and organic impact alongside ACoS to justify the differential.

    Letting the SP Data Source Go Stale

    The SP search term report that seeded your initial SBV keywords was relevant when you pulled it. Customer search behavior evolves, seasonal demand shifts, and your SP campaigns continue generating new data. A SBV campaign built on a one-time SP data pull will gradually drift out of alignment with current demand. Build the 30-day SP-to-SBV review into your standard operating cadence. Treat it as an ongoing feed, not a one-time setup step.

    Building the Repeatable System — From One-Time Setup to Ongoing Flywheel

    The most durable competitive advantage from search-term-first SBV targeting comes not from the initial setup but from the flywheel effect created when the system runs continuously: SP discovers and tests terms at lower cost, the strongest terms graduate to SBV for higher-visibility placement, SBV generates additional search term data and NTB customers, branded search lift feeds back into brand campaign efficiency, and organic rank improvements from increased sales velocity reduce the reliance on paid placement over time.

    This flywheel only spins consistently if the process is documented, assigned, and repeatable. The practical operational requirements:

    • A monthly SP search term report pull with documented qualification criteria applied consistently
    • A clear handoff process for new terms entering SBV (campaign placement, match type assignment, bid calculation, negative keyword deployment)
    • A performance review template that covers ACoS, CVR, NTB%, view metrics, and bid adjustments for each SBV keyword cluster
    • A creative review process triggered when view-through metrics decline or CPC-to-CVR ratios deteriorate
    • A scaling review that assesses each keyword against the four-quadrant framework monthly

    Teams that treat SBV targeting as a one-time project tend to see initial performance gains followed by gradual degradation as the keyword set becomes stale and creative grows repetitive. Teams that build it as a repeatable system compound their advantage month over month — each review cycle improving keyword precision, creative alignment, and bid accuracy simultaneously.

    The Competitive Reality: What Happens If You Don’t Build This System

    The argument for search-term-first SBV targeting is sometimes framed as an offensive opportunity — a way to take share, build brand awareness, and accelerate growth. But it is equally important to understand the defensive dimension: in competitive categories where your rivals are running SBV on the high-intent keywords you’ve proven, your organic and SP placements are being surrounded by video content from other brands. Shoppers who search for terms where you rank well organically are seeing competitor SBV ads before they ever reach your organic listing.

    The SP data you’re sitting on right now tells you which keywords deserve video defense. It tells you where competitors are most likely building their SBV campaigns, because those are the high-intent terms that every serious advertiser in your category is watching. Acting on that data before competitors fill those placements is the strongest timing argument for urgency in building this system.

    SBV placements are finite — there is typically one video placement per search results page per query. First-mover advantage in SBV targeting for a given keyword cluster is real and meaningful. The brand that occupies the in-stream video position on a high-intent search term consistently, over weeks and months, builds a visual association advantage that is difficult to displace once established.

    Conclusion: Data First, Video Second — Always

    The core argument of search-term-first SBV targeting is simple even if the execution is detailed: video is a powerful format, but format alone doesn’t win. The terms you choose to run video against determine whether that format power is directed at shoppers who are predisposed to purchase or at a broad audience with unclear intent. Your SP search term data is the most reliable tool you have for making that determination — because it is based on actual customer behavior, not projected demographics or estimated demand.

    Build the qualification process before you build the campaign. Build the campaign structure before you build the creative. Set up negatives before you collect waste. Measure NTB and organic halo alongside ROAS. Review the SP data feed every 30 days to keep the keyword set current. And when you’re ready to scale, use the four-quadrant framework to make decisions that are evidence-based rather than instinct-based.

    The advertisers winning in SBV-dominant categories in 2026 are not necessarily the ones with the biggest video production budgets or the most creative teams. They are the ones who have built the most systematic, data-informed approach to deciding which search terms deserve a video impression in the first place. That system starts in your SP search term report. Everything else follows from there.

    Key Takeaways

    • Start with SP data, not creative: Qualify search terms through a three-gate filter (minimum orders, acceptable ACoS, adequate impressions) before committing them to SBV.
    • Use exact match first: Proven SP converters deserve exact match SBV placement. Phrase match is for controlled expansion, not initial targeting.
    • Segment by intent cluster: Different ad groups for category-generic, feature-specific, use-case, and competitor terms — with aligned creative where budget allows.
    • Deploy negatives at launch: Don’t wait for SBV to discover waste your SP data already flagged. Add known non-converters as negatives from day one.
    • Measure NTB alongside ROAS: New-to-brand percentage is the primary signal of SBV’s incremental value beyond last-click attribution.
    • Build the 30-day review cycle: The system compounds when SP data continuously feeds new qualified terms into SBV. One-time setup is not enough.
    • Apply the four-quadrant scaling framework: Scale high-volume, high-efficiency terms; investigate high-volume, low-efficiency terms; remove low-volume, low-efficiency terms.
  • What Your SQP Data Is Actually Telling You About Your Images (And How to Act on It)

    What Your SQP Data Is Actually Telling You About Your Images (And How to Act on It)

    Split-screen showing high impressions vs low clicks on identical Amazon products, with the text YOUR SQP DATA ALREADY KNOWS THE PROBLEM

    Most Amazon sellers treat the Search Query Performance (SQP) report as a keyword discovery tool. They pull it, look at what queries are driving volume, and feed those terms back into their listings and PPC campaigns. That’s not wrong — but it’s only half the job, and it’s the less valuable half.

    The more powerful use of SQP data is as an image diagnostic system. Every query in your SQP report carries a silent verdict about your main image: either shoppers are clicking on it, or they’re not. When your impression share is outpacing your click share on a given query, the market is telling you something very specific — your listing is showing up, but your thumbnail is losing the moment of decision.

    This post is about building a CTR-first methodology around that signal. Not a “make pretty images” philosophy, but a structured workflow where SQP data tells you which queries to fix, your competitive audit tells you why you’re losing them, and your image changes are tested and tracked back to the same dataset that identified the problem in the first place. It’s a closed-loop system — and it’s one that most sellers aren’t running yet, even in 2026 when the tools to do it have never been more accessible.

    The sellers who understand this have a compounding advantage: better CTR drives ranking, better ranking drives more impressions, and more impressions at higher CTR rates drive purchases — all without increasing ad spend. That’s the actual prize here.

    Why SQP Is an Image Diagnostic Tool First

    The conventional framing of SQP is that it answers the question “which keywords should I target?” But SQP’s most precise signal sits one layer deeper: it tells you, at a per-query level, how your listing performs at the moment of comparison against every competing product in those search results.

    Let’s be precise about what SQP actually measures. At the ASIN level, you get five core metrics for each query: impressions, clicks, add-to-carts, purchases, and your percentage share of each relative to the total market for that query. These five numbers describe your complete conversion funnel for every individual search term, not in aggregate, but query by query.

    The Moment SQP Becomes a Visual Feedback Signal

    When you compute your click share as a percentage of your impression share for any given query, you get a ratio that has a very specific meaning. A ratio close to 1.0 means your listing is converting impressions to clicks at roughly the same rate as competitors. A ratio significantly below 1.0 means you are consistently being chosen less often than your share of eyeballs would predict — and at that specific moment on that specific query, the thing differentiating you from every other listing is your thumbnail.

    It’s not your price — shoppers can barely process price in 0.3 seconds of glance time on a search results page. It’s not your reviews — they register as a star rating and a number, which changes very little between listings in competitive categories. It’s primarily your main image. That’s the creative variable that governs whether a shopper’s eye pauses on your listing or slides to the next one.

    This is the insight that makes SQP such a powerful image tool: it’s not showing you abstract engagement metrics — it’s showing you exactly which shopping scenarios your image is failing in, and how severe the failure is.

    What SQP Cannot Tell You Directly

    SQP doesn’t tell you why your image is losing. It doesn’t explain whether your frame fill is too small, your product angle is confusing, your background isn’t clean enough, or your packaging doesn’t match what shoppers expect to see for that query. That diagnosis requires a separate step — the competitive thumbnail audit. But SQP gives you the targeting precision to know exactly where to look. Without it, you’re guessing which images to improve and testing without a hypothesis. With it, you’re following data to the specific queries where image quality is costing you clicks at scale.

    The Impression-Click Gap: Anatomy of a Missed Click

    ICAP funnel diagram showing the gap between impressions and clicks as the image problem, with click share vs impression share callout

    The impression-click gap is the core diagnostic unit of a CTR-first image strategy. Understanding its anatomy — what causes it, what makes it worse, and what conditions it can and cannot diagnose — is essential before you start pulling data.

    Defining the Gap with Precision

    For any given query in SQP, your impression share represents how often your ASIN appeared in search results when someone searched for that term, as a percentage of total appearances across all competitive ASINs. Your click share represents what percentage of all clicks on that query you captured. The gap is simple arithmetic: impression share minus click share. A gap of zero means you’re winning clicks proportionally to your visibility. A gap of 10 percentage points means for every 10 times you appear, you’re capturing 10 fewer clicks than you should be if performance were neutral.

    In practice, most competitive categories see individual ASINs with impression-click gaps of 5 to 20 percentage points, meaning the typical product is significantly underperforming on click capture relative to its visibility. The best-performing listings — the ones with highly optimized thumbnails, strong reviews, and competitive pricing — often show negative gaps, meaning their click share actually exceeds their impression share. These listings are punching above their weight in every impression they receive.

    What the Gap Is Really Measuring

    Think about what happens in a search results page interaction. A shopper types a query, Amazon displays up to 60+ ASINs across multiple pages. But eye-tracking research across e-commerce platforms consistently shows that the vast majority of clicks go to the first handful of results, with position and visual salience being the two dominant variables. Your impression share is largely a function of your ranking and PPC coverage — it tells you how often you’re in the room. Your click share is a function of what happens once you’re in the room.

    The gap, therefore, isolates the creative and pricing performance of your listing from the ranking and advertising performance. A high impression share with low click share tells you that you’ve solved the ranking problem but not the persuasion problem. That’s precisely where image optimization applies.

    The Compounding Cost of a Large Gap

    What makes the impression-click gap worth obsessing over is that it’s self-reinforcing. Amazon’s A10 algorithm factors click-through rate into ranking signals — listings that generate more clicks per impression gradually gain organic rank, which in turn generates more impressions, creating a flywheel. Conversely, listings with persistently low CTR on high-volume queries signal to the algorithm that the listing isn’t what shoppers want for that search, which can suppress organic rank over time even when keyword relevance and sales velocity are strong.

    This means a large impression-click gap isn’t just a revenue problem today — it’s a compounding ranking problem tomorrow. Fixing it through image optimization isn’t just about winning more clicks this week; it’s about building an organic rank trajectory that sustains itself without relentless advertising spend.

    Segmenting Queries by Intent Before You Touch a Single Image

    2x2 query intent segmentation matrix showing high volume/high purchase rate vs low volume/low purchase rate quadrants for image budget prioritization

    One of the most consequential mistakes in SQP-driven image optimization is treating every query the same way. Not all queries with a large impression-click gap deserve the same response — because not all queries represent the same type of shopper, the same conversion potential, or the same type of image requirement.

    Before you commission a single reshooting session or brief a designer, you need to segment your SQP queries into buckets based on intent. This segmentation determines both the priority order of your image work and the creative direction for each set of images.

    Using the Full ICAP Funnel to Classify Intent

    SQP gives you the complete ICAP funnel data (Impressions, Clicks, Add-to-Cart, Purchases) at the query level. The shape of this funnel for each query is your intent signal. Here’s how to read it:

    • High impression share + high purchase rate relative to click rate: These are high-converting queries where every click is valuable. The funnel narrows sharply at clicks but stays wide through to purchases. These are your highest-priority image optimization targets because improving CTR here has an outsized downstream revenue impact.
    • High impression share + high click share but low cart-add rate: Shoppers are clicking but not converting. The image is working — but there’s a disconnect on the product detail page. This is a content and gallery image problem, not a main image problem.
    • High impression share + very low click share + moderate purchase rate: The classic image problem. Shoppers who do click through are buying, but too few are clicking in the first place. This is your primary CTR-first opportunity.
    • Low impression share across the board: This is a ranking or advertising coverage problem, not an image problem. No amount of image optimization will fix an ASIN that isn’t appearing for the query in the first place.

    Building the Segmentation in Practice

    Export your SQP data for the past 90 days. Create a spreadsheet with columns for each of the five ICAP metrics plus the derived ratios: click share ÷ impression share (your “click efficiency ratio”) and purchase share ÷ click share (your “post-click conversion ratio”). These two derived metrics tell you where each query sits on the problem spectrum.

    Queries with a click efficiency ratio below 0.7 and a post-click conversion ratio above 0.5 are your Tier 1 image optimization targets — they have proven buying intent but your image is losing the click competition. Sort by impression volume to find the ones where fixing the image will move the most revenue. These are the queries that deserve your first creative brief and your first Manage Your Experiments test.

    The Intent-to-Image Connection

    Intent segmentation also informs what your image should actually show. A query like “stainless steel french press 34 oz” is a high-specificity, high-intent search — the shopper knows exactly what they want, and your image needs to confirm at a glance that your product matches their mental model. A query like “coffee maker gift” is a browse-intent, low-specificity search — shoppers are evaluating options, and your image might benefit from communicating context and occasion rather than just product specs.

    This distinction matters enormously for creative direction. The same product needs different images to win different types of queries — which is exactly why the Amazon gallery exists. But for main image optimization, you need to understand which intent type represents the majority of your high-gap, high-volume queries, because that’s the shopper your thumbnail needs to convert first.

    The Competitive Thumbnail Audit: Seeing What Shoppers See

    Row of Amazon product thumbnails where one standout image with 85% frame fill dominates CTR compared to generic competitors

    SQP tells you that you’re losing clicks on a specific query. The competitive thumbnail audit tells you why — and more importantly, what winning looks like in that context. This is the step most sellers skip because it feels qualitative, but done systematically, it’s highly actionable.

    How to Run a Query-Level Thumbnail Audit

    For each of your Tier 1 queries from the intent segmentation step, open an incognito browser window (or use Amazon’s mobile app) and perform the actual search. Don’t look at the page as a seller — look at it as a shopper who has 8–10 seconds to scan results and decide where to click. Take a screenshot. Then do the following analysis:

    Step 1: Identify the visual winners. Which three to five thumbnails draw your eye first? Note what they have in common: product scale relative to the frame, background cleanliness, angle, color contrast against the white search results page, and whether any visual element creates a clear differentiation from adjacent listings.

    Step 2: Locate your ASIN. Find your own listing in the results. Does it visually stand out or blend in? Does it appear smaller, lower-contrast, or more generic than the top-performing thumbnails? Be honest about this assessment — what you see is what shoppers see.

    Step 3: Document the gap. List the specific visual differences between your thumbnail and the three most visually compelling listings on that SERP. These differences are your creative brief. Common gaps include: product fills less than 70% of the frame (competitors fill 85%+); product angle shows a less informative face of the product; packaging detail is illegible at thumbnail size; product appears in a shadow or unclean white background; key differentiators (size, color, quantity) are invisible in the thumbnail.

    What Frame Fill Actually Means

    Frame fill is the percentage of the image area that the product itself occupies. Amazon’s own seller guidelines recommend that the product occupy at least 85% of the image. But many sellers interpret this as “the product plus any packaging” — which often results in a thumbnail where the actual product looks small against the full image dimensions.

    At thumbnail size (Amazon displays main images at roughly 160×160 pixels in most grid views), a product filling 65% of the frame looks dramatically smaller than a product filling 85%. In categories where product size is a purchase decision (kitchenware, supplements, tools, outdoor equipment), that size signal can be a decisive factor in the click decision. Shoppers choose what looks bigger and more substantial, all else equal.

    Color Contrast and Category Context

    Every product category has a de facto visual language — a set of image conventions that experienced shoppers in that category have internalized. Beauty products tend to be shot with clean, clinical precision. Outdoor gear tends to use bold angles that suggest durability. Food products use color saturation that triggers appetite appeal. When your thumbnail violates category visual conventions, it registers as slightly “off” to shoppers, even if they can’t articulate why — and that feeling translates to fewer clicks.

    Conversely, when your thumbnail conforms to the best version of category visual conventions but differentiates through one specific element — an angle, a color accent, a size demonstration — you’re working with the shopper’s expectations rather than against them. The audit is your way of mapping those conventions for your specific competitive set.

    Building Your Image Priority Queue from SQP Data

    With your segmented query list and competitive audit complete, you now have enough data to build an image priority queue — a ranked list of image changes, ordered by expected revenue impact. This is where the data work pays off, because it means you’re not spending budget on image redesigns for queries that are already performing well, or for queries where the problem isn’t actually the image.

    The Priority Scoring Framework

    Score each potential image change opportunity using three inputs from your SQP analysis:

    1. Query volume: Higher monthly search volume means more impressions, which means more clicks available to capture. Weight this heavily — a 10% CTR improvement on a 50,000-impression query is worth more than a 30% improvement on a 5,000-impression query.
    2. Impression-click gap magnitude: Larger gaps represent more clicks being left on the table. An impression share of 12% with a click share of 3% is a more urgent problem than impression share of 8% with click share of 6%.
    3. Post-click conversion rate: This is your confidence signal. If the queries where you have a large gap also show strong purchase rates among the clicks you do capture, then every additional click you win is highly likely to convert to revenue.

    A simple priority score: (Query Volume × Impression-Click Gap) × Post-Click Conversion Rate. Sort your query list by this score, descending. The top 10 queries are your first image sprint. Don’t try to fix everything at once — a focused, sequenced approach produces cleaner test data and clearer attribution.

    Single-Image vs Multi-Image Strategy

    An important structural question: are all your top-priority queries being lost by the same image weakness, or are different queries revealing different creative problems?

    If your audit shows that the problem is consistent — say, frame fill is too small across the board — then a single main image redesign will address multiple queries simultaneously, and you should test one new image variant across all affected queries. But if different queries reveal different problems (one query’s SERP is dominated by lifestyle imagery while another’s is dominated by technical specification callouts), you may need to consider whether multiple listing variants, Sponsored Brands imagery, or A+ content can serve as creative solutions for the secondary queries while your main image optimizes for the primary one.

    Respecting Amazon’s Main Image Constraints

    One reality check that every CTR-first strategy must account for: Amazon’s rules for main images are specific and enforced. The main image must show only the product (no additional props, backgrounds, text overlays, or lifestyle elements) on a pure white background (RGB 255,255,255). Amazon has ramped up enforcement of these rules, with AI-based image scanning flagging non-compliant images with increasing accuracy in 2026.

    This means your creative options for the main image are narrower than they might seem: angle, frame fill, lighting, product configuration (assembled vs. components), color variant selection, and shadow treatment are your primary variables. These constraints aren’t limitations — they’re a creative challenge. The best-performing main images in competitive categories win within these rules, not by working around them. Your competitive audit should surface how the winners are doing this.

    What to Change First: Frame Fill, Angle, Overlays, or Color

    Once you have a priority queue and a creative brief from your thumbnail audit, the practical question is sequencing: which change should you make first? Not because you can only make one change, but because you can only test one hypothesis at a time and attribute the result correctly.

    The Four Primary Image Variables

    Frame fill is almost always the first change to test if your audit shows your product appearing smaller than competitors’ at thumbnail size. The mechanics are simple: crop tighter, shoot closer, or remove excess whitespace in post-production. This change is fast, cheap to implement, and often produces the largest single-variable CTR lift because it changes the product’s visual weight on the page.

    The target is 85%+ product coverage within the frame. Test at thumbnail size — not at full image size — because that’s the context in which the change matters. A product that looks perfectly framed at 1000×1000 pixels may still look small at the 160px thumbnail dimension depending on the product’s aspect ratio and shape.

    Product angle is the second variable to test when frame fill is already strong. The question is whether your current angle communicates the product’s most important attribute at thumbnail size. For a multi-tool, a top-down spread of tools might be more informative than a three-quarter view. For a supplement, a front-facing label view with legible branding might outperform an angled glamour shot. The audit tells you what angle the CTR winners in your category are using — test toward that angle if it differs from yours.

    Product configuration applies to items that can be shown assembled or disassembled, packaged or unpackaged, singular or in set quantities. For multi-packs, showing the quantity visually (three bottles arranged together) rather than relying on text to communicate it can significantly improve CTR for queries like “bulk” or “pack of 3” — because the image confirms what the query expects before the shopper has to read anything.

    Shadow and lighting treatment is a subtler variable but meaningful in categories where product quality and premium positioning matter. Hard shadows against white backgrounds can make products look lower-quality or older in photography style. A natural drop shadow or completely shadow-free shot (achieved in editing) can meaningfully shift the perceived value of the product, which affects click behavior particularly for higher-price-point items.

    What Changes to Defer

    If your audit identifies that competitors are winning with lifestyle imagery in the main image slot, don’t try to replicate this by violating Amazon’s content policies. Non-compliant main images can get your listing suppressed — which eliminates all your impressions, not just your clicks. The correct response to a lifestyle-dominated SERP is to make the strongest possible compliant main image while investing in Sponsored Brands creative for that query, where lifestyle imagery is explicitly permitted.

    Running Manage Your Experiments Without Wasting 8 Weeks

    7-step image test cycle flowchart showing the process from pulling SQP data through launching experiments to scaling the winner

    Amazon’s Manage Your Experiments (MYE) tool is the native way to A/B test main images with statistical rigor, and it’s available to brand-registered sellers with sufficient traffic. The challenge most sellers face with MYE isn’t technical — it’s methodological. They run experiments without a clear hypothesis, test too many variables simultaneously, or let tests run indefinitely without acting on the results.

    Designing a Test That Produces Actionable Data

    The single most important principle in MYE testing is one variable at a time. If you change the angle, the frame fill, and the color balance simultaneously in your test image, you cannot attribute a CTR change to any specific element. You’ll know the new image performed better (or worse), but you won’t know why — which means you can’t systematically build on the result.

    Start with the highest-priority change from your creative brief: if the audit showed frame fill is the primary gap, test only a tighter frame fill, keeping all other elements identical. If the test wins, you’ve confirmed the hypothesis and can proceed to the next variable. If it loses, you’ve ruled out frame fill and need to reassess your audit findings.

    Write your hypothesis explicitly before launching: “We believe that increasing frame fill from 65% to 85% on our main image will improve CTR on queries with high impression-click gaps by reducing our visual size disadvantage against the top three competitors on those SERPs.” This forces clarity about what you’re measuring and why, and it gives you a post-test evaluation framework beyond just “did the number go up?”

    The Traffic Threshold Problem

    MYE requires sufficient traffic to reach statistical significance within a reasonable timeframe. Amazon’s own guidance suggests experiments need at least a few hundred clicks per variant to be meaningful. For high-traffic listings, this can happen within two to three weeks. For lower-traffic ASINs, an experiment might require six to eight weeks to reach the traffic threshold — during which time market conditions, pricing, and competitive dynamics can all shift, introducing noise into the results.

    If your ASIN doesn’t have enough organic traffic to run MYE efficiently, there are two workarounds. First, consolidate your experiment to your highest-traffic ASIN in a brand and apply learnings to lower-traffic ASINs without formal testing — directional data from a high-traffic sibling product is better than no data. Second, use Sponsored Products to drive controlled traffic to both variants during the experiment period, accelerating the time to statistical significance. This costs money, but it gets you a result in half the time and significantly reduces the influence of external variables.

    Reading the Results Without Bias

    MYE results show you both statistical confidence and projected annual sales impact. The temptation is to declare a winner as soon as the confidence indicator is high — but confidence in a statistically insignificant positive result can still be misleading. Look for both high confidence (85%+ by Amazon’s indicator) and a meaningful delta in the primary metric before calling the experiment.

    Also watch what MYE measures by default: it typically optimizes for units sold, not CTR specifically. Since CTR improvements cascade through to units sold, this is usually the right metric — but if your test shows improved CTR with flat units sold, the issue may be post-click conversion, not the main image. That’s a useful finding too, and it redirects your optimization effort to the product detail page rather than the thumbnail.

    Tracking CTR Gains Back to SQP: Closing the Loop

    Analytics dashboard showing SQP to image ROI tracker with before and after CTR line graph showing 123% CTR lift after image update

    This is the step that turns a one-time image fix into a repeatable system. Once you’ve made an image change and your MYE test has concluded, you need to return to SQP and measure whether the impression-click gap on your target queries actually narrowed. This closes the feedback loop — and it’s where most sellers drop the thread, walking away after the MYE result without verifying the effect in the source data.

    The 30-Day SQP Pull Protocol

    Pull your SQP data approximately 30 days after your new main image goes live (or after the MYE winner is deployed at 100%). Compare your click share on the Tier 1 queries you targeted against the click share from the 90-day period before the change. Look specifically at:

    • Did your click share increase on the target queries?
    • Did your impression share stay flat or increase (ruling out ranking changes as a confounding variable)?
    • Did your add-to-cart share and purchase share move proportionally with click share, or did click share increase while downstream metrics lagged (suggesting the new image is drawing the wrong shopper intent)?

    The third point is important and often overlooked. An image change that dramatically improves CTR but produces a parallel drop in add-to-cart rate is a warning sign — the new image may be winning clicks from shoppers whose intent doesn’t match the product. This is particularly common when sellers make images more visually dramatic in ways that create expectations the product doesn’t meet. A 40% CTR improvement that comes with a 30% conversion rate drop is a net negative. SQP catches this where MYE’s unit-sales metric might not.

    Building a Query-Level Tracking Sheet

    Maintain a persistent spreadsheet — or automate a pull using Amazon’s Brand Analytics API if your volume justifies it — that tracks, for each of your priority queries, the click efficiency ratio (click share ÷ impression share) across rolling 90-day periods. This gives you a longitudinal view of image performance that no single-point-in-time snapshot can provide.

    Update this tracking sheet every 30 days. Over time, you’ll see which queries have been permanently improved by image changes, which ones drift back toward poor CTR as competitors update their own images, and which new queries have emerged (through keyword expansion or market growth) that have entered your impression profile but are showing early signs of a click gap.

    This tracking discipline is what distinguishes a CTR-first image strategy from a one-time image refresh. The market changes. Competitors improve their thumbnails. New entrants arrive with better creative. Your SQP data will surface these dynamics before they cost you meaningful revenue — but only if you’re actually looking at it on a recurring basis.

    When Better Images Aren’t Enough: The Price, Badge, and Rating Factor

    A rigorous CTR-first strategy requires intellectual honesty about what main image optimization can and cannot fix. There are real scenarios where the impression-click gap is caused by factors that have nothing to do with your thumbnail — and chasing an image solution for a non-image problem wastes time, budget, and creative energy.

    Price as a CTR Variable

    On most Amazon search result pages, price is displayed prominently alongside the thumbnail. At desktop size, shoppers can see price before they click. This means a meaningful portion of your impression-click gap on price-sensitive queries may be attributable to price positioning rather than image quality. The diagnostic test is simple: temporarily narrow the price gap against the top two competitors on your highest-gap queries and monitor the click efficiency ratio in SQP over the subsequent 30-day period. If click share moves meaningfully with the price change while nothing else changes, price was the dominant variable — not the image.

    Review Count and Star Rating

    In some categories, review count and star rating are the primary click-decision variables, particularly for commoditized products where thumbnails are relatively undifferentiated and shoppers are using social proof as a quality shortcut. If your ASIN has significantly fewer reviews or a lower rating than the top CTR performers on your target queries, image optimization alone will not close the gap.

    The practical implication: use your click efficiency ratio as a proxy for competitive health. If your ratio is below 0.7 and you have strong images, competitive pricing, and good reviews, then image refinement is the right lever. If your ratio is below 0.7 and you have 47 reviews versus competitors with 4,700, invest in review acquisition first and revisit image optimization once social proof is no longer the dominant impression-to-click barrier.

    The Amazon Choice Badge and Coupon Flags

    One underappreciated CTR driver is badge visibility. Amazon’s Choice badges, Prime badges, and coupon flags all appear in the search results thumbnail view and demonstrably affect click-through behavior. If your competitors are running 10% or 15% off coupons that appear as bright orange flags on their thumbnails, that visual element competes directly with your image quality for click attention.

    This isn’t an argument to run coupons at all times (the economics may not support it) — but it’s a reminder that your main image doesn’t compete in isolation. Your thumbnail is the sum of the product photo, the price, any badges, the rating and review count, and the Prime eligibility indicator. All of these together constitute what a shopper sees in the 0.3-second glance that determines whether they click. Image optimization addresses one component of that bundle — and an important one — but a truly CTR-first strategy accounts for all of them.

    Scaling the System: From One ASIN to a Full Catalog

    Once you’ve run the SQP-to-image workflow successfully on one or two high-priority ASINs, the question becomes how to scale it across a larger catalog without the analytical workload becoming unmanageable. This is where systematization matters more than sophistication.

    Building the Triage Layer

    At catalog scale, you can’t do a deep competitive thumbnail audit for every ASIN every month. Instead, build a triage system that surfaces which ASINs deserve deep analysis based on their SQP signal. Create a weekly or monthly report that flags any ASIN whose average click efficiency ratio across its top 10 queries has dropped below 0.65 in the current 90-day window, compared to the prior window.

    ASINs flagged by this triage trigger go into the deep analysis queue: competitive audit, creative brief, and MYE experiment. ASINs with stable or improving ratios get a lighter-touch review — no immediate action, just continued monitoring. This approach concentrates your creative investment where the data says it matters, and keeps the system sustainable at scale.

    Building a Creative Asset Library

    As you run image experiments across your catalog, you’ll accumulate institutional knowledge about what works — which angles win in your category, what frame fill level consistently outperforms, whether your brand’s color palette helps or hurts thumbnail differentiation. Document these findings explicitly and build them into a creative brief template that your photographers and designers use for every new ASIN shoot.

    This means your new product launches start with a higher creative baseline informed by performance data from your existing catalog. Instead of launching with an image that will need to be improved after SQP data accumulates, you launch with an image built on the principles that your data has already validated. The result is shorter ramp-up times to optimal CTR and less lost revenue during the critical early weeks of a new ASIN’s life.

    Integrating SQP Review into Operations

    The final piece of scaling is operational: making SQP review a standard, recurring business rhythm rather than an occasional deep-dive. Set a monthly cadence for SQP pulls. Assign clear ownership for the analysis. Build the click efficiency ratio and impression-click gap metrics into whatever reporting dashboard your team reviews regularly. When SQP data is part of weekly business reviews alongside advertising metrics and inventory health, it stops being an advanced tool that only power users access and becomes a standard part of how your team thinks about listing health.

    At that point, the CTR-first image strategy is no longer a project — it’s a process. And that’s when the compounding advantage starts to accumulate: consistent click efficiency improvements quarter over quarter, organic rank gains that reduce dependence on paid traffic, and a visual competitive moat that takes competitors significant time to close.

    Conclusion: The Repeatable SQP-to-Image Workflow

    The core insight of a CTR-first image strategy is disarmingly simple: Amazon already tells you which queries your image is failing on — you just have to know how to read the signal. The SQP report, used as an image diagnostic tool rather than a keyword tool, gives you query-level precision about where the impression-click gap is largest, which queries have the conversion potential to make closing that gap profitable, and whether your changes are actually working.

    The workflow this produces has a clear, repeatable sequence:

    1. Pull SQP data for 90 days at the ASIN level. Compute click efficiency ratios and post-click conversion rates for each query.
    2. Segment queries by intent using the full ICAP funnel shape. Identify Tier 1 targets: high gap, high conversion, high volume.
    3. Run the competitive thumbnail audit for your top 10 priority queries. Document the specific visual differences between your ASIN and the CTR winners.
    4. Build a priority-scored image change list based on expected revenue impact (volume × gap × conversion rate).
    5. Test one change at a time through Manage Your Experiments. Write an explicit hypothesis before launching. Wait for statistical significance before acting.
    6. Close the loop in SQP 30 days post-launch. Verify that click share improved on target queries. Watch for any deterioration in add-to-cart or purchase rates that would indicate the image is attracting the wrong intent.
    7. Systematize and scale. Build triage triggers for catalog-wide monitoring. Compile creative learnings into a brief template. Make SQP review a standing business rhythm.

    What makes this system valuable isn’t any single step — it’s the closed loop. Too many Amazon optimization efforts are one-directional: change something, hope for the best. SQP-driven image optimization is iterative and self-correcting. The data that tells you where to start is the same data that tells you whether you succeeded — and that’s a structural advantage most of your competitors aren’t building yet.

    In a marketplace where the average click-through rate sits between 0.4% and 0.6% and the difference between a 0.4% CTR and a 0.8% CTR represents double the organic traffic at identical advertising spend, the sellers who take image performance seriously — and measure it with the same rigor they apply to their PPC metrics — are the ones building durable, compounding advantages. SQP is your starting point. The image is your lever. The click efficiency ratio is how you know it’s working.

  • From ASIN to Air: How Amazon’s New SBV Template Workflow Actually Works in Practice

    From ASIN to Air: How Amazon’s New SBV Template Workflow Actually Works in Practice

    Amazon SBV Creative Studio dashboard showing ASIN-to-video workflow with product image transforming into polished video ad

    There is a moment every Amazon advertiser hits eventually. You have a great product, a healthy ad budget, and a campaigns manager who keeps saying the same thing: “We should really be running Sponsored Brands Video.” And you agree. Every benchmark you read says SBV outperforms static. The data is unambiguous. But video production is expensive, time-consuming, and your creative agency has a four-week lead time and a five-figure quote for something that might live on Amazon for 15 seconds.

    That’s the wall. And for most brands, it has kept Sponsored Brands Video as a theoretical priority rather than an active strategy. You plan to do it next quarter. Then the next quarter after that.

    Amazon’s new SBV creative tools — most notably the Video Generator inside Creative Studio and the newer Creative Agent workflow — are designed to demolish that wall entirely. In theory, you can now go from a product ASIN to a polished, live Sponsored Brands Video ad in under 30 minutes, at zero production cost, without a camera, an editor, or an agency on the phone.

    But how does it actually work? What does the template system let you control, and what does it decide for you? When should you use the Quick Video path versus the Creative Agent chat workflow? And critically — what are the performance and measurement pitfalls that brands keep tripping over after launch?

    This post answers all of it, from the mechanics of the tool to the testing system you need to build around it, and the new-to-brand metrics that tell you whether any of it is actually working.

    The Creative Toolkit Amazon Has Actually Built

    Before getting into workflow specifics, it helps to understand what Amazon has actually shipped versus what it announced. The distinction matters because there’s been a lot of noise around AI creative tools, and not all of it maps cleanly to what’s available inside your Amazon Ads console today.

    Creative Studio: The Central Hub

    Creative Studio is the unified creative environment within the Amazon Ads console. Think of it as the workspace that houses all of Amazon’s ad production tools under one roof. You access it directly from the Ads console — it does not live in Seller Central. This is a deliberate design choice. Creative Studio is an advertiser tool, not a seller tool, and the distinction affects who in your organization should be managing it.

    Within Creative Studio, you can produce image ads, video ads, audio ads (for streaming), and eventually Streaming TV creatives. For Sponsored Brands Video specifically, you’ll primarily be working with two sub-tools: the Video Generator and the Creative Agent.

    The Video Generator: The Fast Path

    The Video Generator is the quick-production tool. It’s designed for advertisers who want to create SBV-ready assets fast, with minimal decision-making required. You input a product ASIN or product detail page URL, the system pulls your existing product images and copy, applies them to pre-built templates, and outputs six video variations in minutes. These are short — typically 6 to 15 seconds, which aligns with Amazon’s SBV spec requirements.

    The Video Generator was the flagship announcement at Amazon’s unBoxed 2025 event and has been rolling out broadly since. As of 2026, it’s available to most Amazon advertisers in the US and is expanding internationally. It’s free — there’s no production charge. Amazon absorbs the generation cost as part of its advertising ecosystem.

    Creative Agent: The Strategic Path

    The Creative Agent is Amazon’s agentic AI creative workflow. It went into open beta on February 12, 2026, and it works differently from the Video Generator. Instead of a button-click template system, Creative Agent is a conversational interface — you open a chat window inside Creative Studio and brief the tool in natural language.

    You might say something like: “I want to create a Sponsored Brands Video for my collagen supplement. The audience is women 35–55 who are new to supplements. The key message is that this is tasteless and mixes easily into any drink. The tone should be warm and approachable, not clinical.”

    From that brief, Creative Agent generates a concept, a script, a storyboard, and then a finished multi-scene video. It handles voiceover scripting, music selection, text animation, and scene sequencing. The result is significantly more customized than what the Quick Video template path delivers — but it takes longer, and it requires you to engage with the creative process rather than offload it entirely to a template.

    The two tools serve different use cases, and the smartest advertisers are using both in tandem rather than choosing one.

    Split-screen comparison of old traditional video production workflow taking 6-8 weeks versus new Amazon SBV template workflow completing in under 30 minutes

    The Quick Video Template Path: A Practical Walkthrough

    The fastest way to understand the Video Generator template workflow is to walk through it step by step. Here is how it actually functions in practice, not as a marketing description but as a realistic account of what you click, what you input, and what gets produced on the other side.

    Step 1: Access the Video Generator from Within a Campaign

    You start a new Sponsored Brands campaign in the Amazon Ads console. When you reach the creative setup stage — where you’d normally upload your video — you’ll see an option to generate a video instead of uploading one. Clicking this takes you into the Video Generator interface. This entry point is important: unlike Creative Studio, which is accessed independently, the Video Generator is embedded directly in the campaign setup flow. You don’t have to leave your campaign, produce something in a separate tool, and come back. It’s a single continuous workflow.

    Step 2: Input Your ASIN

    You enter the product ASIN you’re advertising. The system then reaches into the product detail page and pulls your existing assets: product images, title, bullet points, and any A+ content images that are available. This is one of the more underrated aspects of the tool. You’re not uploading anything — Amazon already has your assets from the listing. The quality of what gets generated is therefore directly tied to the quality of what’s already on your PDP. Poor main images, dark photographs, inconsistent backgrounds — all of these feed directly into the video output and show up as production problems.

    This is not a bug; it’s the system behaving exactly as intended. But it catches a lot of brands off guard, especially those who haven’t invested heavily in their product photography.

    Step 3: Select a Template and Scene Layout

    The Video Generator offers a selection of template styles. These templates vary in scene sequencing (how many scenes, in what order), text animation style (the way headlines appear, fade, or move), background treatment, and pacing. Some templates are product-forward — the product dominates almost every scene. Others are more narrative, with more text and minimal product visibility in certain frames. The right choice depends heavily on your product category and where the viewer is in their purchase journey.

    For high-consideration products where “what is this?” is still the operative question, product-forward templates perform better. For commoditized categories where the product is familiar but differentiation is the challenge, the more narrative templates give you room to make a case.

    Step 4: Customize Headline, Logo, and Music

    This is where advertisers have more control than many expect. The Video Generator allows you to edit the primary headline text, add your brand logo, and select background music from a licensed library. You can adjust the call to action and make basic edits to the text that appears on-screen in each scene.

    What you cannot do is reorder scenes arbitrarily, add custom footage, change the animation style of a specific template element, or adjust individual scene duration. The templates are structured. You’re customizing within lanes, not redesigning the road. That’s the trade-off: speed and zero technical skill required in exchange for constrained creative control.

    Step 5: Generate Six Variations and Choose

    After inputting your customizations, the system generates six video variations simultaneously. These variations apply your inputs across slightly different executions — different scene emphasis, different text pacing, different background music choices within your selected style. You preview all six, choose the one that best represents the product, and proceed to attach it to your campaign.

    The total elapsed time from starting the campaign to having a video attached is typically 15 to 30 minutes for a first-time user. For advertisers who’ve done it before and know the tool’s interface, it can be under 10 minutes.

    Five-step SBV template workflow flowchart from entering ASIN to generating six video variations in Amazon Creative Studio

    Creative Agent: When the Template Path Isn’t Enough

    The Quick Video template path solves the access problem for SBV. It gets brands into the format who otherwise wouldn’t be running it at all. But there’s a ceiling on what templates can do creatively, and for brands competing in crowded categories — or launching products where storytelling is genuinely part of the conversion argument — the Creative Agent workflow offers meaningfully more.

    The Brief-to-Video Conversation

    Creative Agent operates through a conversational interface. You open chat in Creative Studio and begin with a brief. The more specific that brief, the better the output. Vague prompts like “make me a video for my supplements” produce generic results. Detailed briefs that include audience specifics, the one or two product benefits to emphasize, the tone and register you want, and any messaging to avoid produce output that’s significantly more targeted.

    A well-constructed brief for Creative Agent might include: the target customer (not just a demographic but a behavioral description — “someone who has tried other collagen supplements and been turned off by the taste”), the primary claim to lead with, the emotional register (confident, warm, clinical, playful), the call to action, and any brand voice notes. Amazon has published guidance suggesting that Creative Agent performs best when the brief treats it as you would brief a human creative director — giving it enough context to make good editorial decisions rather than trying to specify every element upfront.

    Storyboard Review and Scene Editing

    After processing the brief, Creative Agent doesn’t immediately produce a finished video. It first presents a storyboard — a scene-by-scene outline of what it intends to produce. This is a deliberate checkpoint. You can review the storyboard, request changes to specific scenes, adjust the script for individual frames, and redirect the concept before any rendering happens. This saves significant iteration time compared to reviewing a fully-rendered video that needs structural changes.

    Once you approve the storyboard, Creative Agent renders the video. Voiceover, if included, is generated by AI voice models. Music is selected from Amazon’s licensed library based on the brief’s tonal guidance. Text animations are applied consistent with the creative direction established in the storyboard review.

    Where Creative Agent Adds Real Value

    The clearest use case for Creative Agent over the Quick Video template is any situation where the product is unfamiliar to the target audience, or where the differentiation story is complex enough that it needs to be told rather than implied. New-category products, products solving non-obvious problems, or brands launching into a category where they’re competing against established names with strong brand recognition — these are the contexts where a structured creative narrative matters more than fast template execution.

    Creative Agent also produces assets that are inherently more differentiated from each other across an ad portfolio, which matters for testing. Template-generated videos, even across variations, share a structural sameness that can limit your ability to learn what messaging element is driving performance differences. Creative Agent output is diverse enough to test genuinely different creative approaches rather than different executions of the same approach.

    What You Can and Cannot Control: The Creative Constraints Map

    One of the most practical things to understand before running SBV through either of these tools is the exact boundary between what you control and what the system controls. Misunderstanding this is the source of most early frustration with the workflow.

    What Advertisers Control

    • Headline text: The primary claim or product descriptor that appears on-screen. This is the single highest-leverage creative element you control, and it deserves significant attention. The headline in the first two seconds of an auto-playing, muted video is effectively your entire message to anyone who doesn’t watch past the opening frame.
    • Brand logo placement: You can upload and position your logo. Getting this right matters for brand recall, particularly for new-to-brand audiences encountering the brand for the first time.
    • Music selection: You choose from a library of licensed tracks within a stylistic category. You cannot upload custom music. For brands with strong sonic identity this is a limitation; for most brands it’s a reasonable constraint.
    • Call to action text: The CTA button or text that appears at the end of the video. The options are templates-bound (e.g., “Shop Now,” “Learn More,” “See Details”) rather than fully custom.
    • ASIN selection: Which product drives the creative. For multi-product brands, this is a meaningful choice — different product images produce materially different video quality depending on photography quality.

    What the System Controls

    • Scene duration and pacing: Each template has fixed scene lengths. You can’t extend a scene to give a particular product feature more screen time.
    • Image selection from your listing: The Video Generator picks which product images to use from your ASIN. It generally selects the main image and the first few secondary images. If your image order on the listing isn’t optimized, the video may pull images that don’t represent the product’s best angles.
    • Animation style: The way text appears, transitions happen, and scenes cut is determined by the template. You’re selecting a template style, not configuring individual animation parameters.
    • Video resolution and format: Amazon generates to its own SBV spec (16:9 aspect ratio, minimum 1080p, typically 1280×720 or 1920×1080). You can’t adjust aspect ratio for a different placement type within the same generation flow.

    The key practical takeaway here: treat the headline as your primary creative lever. It’s what you have the most control over, it has the most direct impact on performance, and it’s the one element where small changes produce measurable differences across test variants.

    The Performance Case for Video: What the Data Actually Says

    The argument for Sponsored Brands Video over static Sponsored Brands has been made many times, but it’s worth grounding it in the specific numbers that are actually available — rather than the vague “video performs better” claims that appear in most generic coverage of the topic.

    Performance benchmark bar chart showing Amazon SBV delivering 507% higher CTR on branded terms, 28-43% higher ROAS, and 38% new-to-brand rate versus static ads

    Click-Through Rate Differentials

    Sponsored Brands Video consistently delivers higher CTR than static Sponsored Brands across both branded and non-branded search. On branded keyword searches, SBV has been cited at approximately 507% higher CTR than other Sponsored Brands ad types — a number that, while striking, makes intuitive sense. A searcher looking for your brand by name, encountering a video auto-playing your product, is in an extremely receptive moment. The video reinforces the brand recognition that already drove the search.

    On non-branded keyword searches, the CTR advantage is cited at approximately 703% higher — even more significant, because these are discovery-mode shoppers who had no prior intent to find you specifically. Stopping their scroll with a video format rather than a static image is a meaningful edge in a genuinely competitive context.

    ROAS and Conversion Rate

    SBV’s ROAS advantage over static Sponsored Brands is documented at approximately 28–43% higher, depending on category and campaign structure, based on Amazon’s own published benchmark data cited by third-party research firms including Perpetua. The average ROAS for a Sponsored Brands campaign across all formats sits around $5.66 with an ACOS of roughly 17.68% per Amazon’s own benchmark materials — but SBV-specifically tends to land at the higher end of that range when campaigns are properly structured.

    It’s worth noting what drives this ROAS premium. SBV doesn’t inherently produce better conversions on the click — the conversion rate difference comes in part from the quality of the audience clicking. A shopper who watches 10+ seconds of an auto-playing video and then clicks has demonstrated significantly higher intent than one who clicks a static image. The self-selection of engaged viewers is built into the format.

    New-to-Brand Acquisition

    The most compelling data point for brands investing in SBV is the new-to-brand customer rate. Sponsored Brands Video campaigns have shown a new-to-brand purchase rate of approximately 38%, compared to roughly 22% for Sponsored Products. This gap — nearly 16 percentage points — is not incidental. It reflects that SBV does actual brand awareness work in a way that Sponsored Products fundamentally cannot. SP ads appear to people already searching; SBV stops people who weren’t necessarily looking and makes them look. That’s a different customer acquisition mechanic entirely, and it justifies running SBV as part of a customer acquisition strategy rather than purely as a bottom-funnel conversion tool.

    Where SBV Ads Actually Appear — And Why Placement Matters

    Amazon has been actively expanding the placement inventory for Sponsored Brands Video, and understanding the placement landscape affects how you structure your creative. The video that works at the top of search results does not necessarily work the same way on a product detail page.

    Amazon search results page diagram showing three SBV ad placement zones: Top of Search, Inline/Mid-Search, and Product Detail Page placements

    Top of Search: The Premium Placement

    The top of search placement — the very first position on a search results page, above any organic listings — is the highest-visibility placement in the SBV inventory. It auto-plays as soon as it’s 50% visible on screen, and because it’s the first thing the searcher sees, the first 2–3 seconds of your video are doing an enormous amount of work. This placement rewards videos that lead with the product identity immediately. The viewer has no context about your brand; they just entered a search query and the first thing they see is your video. The creative has to orient them instantly.

    Videos that open with brand-forward content (a logo, a tagline, a lifestyle scene that doesn’t show the product quickly) tend to underperform at this placement compared to videos that start with the product itself in the first frame. The Top of Search viewer is in discovery mode and impatient.

    Inline Search Results: The Volume Placement

    Inline search placements appear between rows of organic product listings as the shopper scrolls. This placement captures a viewer who has already begun their search journey — they’ve seen multiple products and are evaluating. Creative that works here tends to be more differentiating: leading with a specific product advantage, addressing a concern (“mixes clear — no clumping”), or calling out a comparison point. The viewer is already in comparison mode; meet them there.

    Product Detail Pages: The Consideration Placement

    PDP placement is the most recently expanded placement type for SBV, and it operates differently from search placements. The viewer is already on a competitor’s product page. They’ve shown purchase intent for the category; they just haven’t committed to a specific product. SBV appearing here is competing for a high-intent shopper in the middle of a consideration phase. Creative for PDP placement benefits from being benefit-dense — making a specific, credible product claim that gives the viewer a reason to click away from the page they’re already on.

    Amazon lets you apply placement bid adjustments — modifiers that increase or decrease how much you bid on each placement type. Use placement reporting to understand which placement is delivering your strongest ROAS and adjust bids accordingly rather than leaving them flat across placements.

    Building a Creative Testing System Around SBV Templates

    The biggest operational advantage of the new SBV template workflow isn’t the zero cost or the speed — it’s the volume. When producing a single SBV used to cost $5,000–$15,000 and take six weeks, most brands ran one video per campaign and hoped it worked. When producing six variations takes 15 minutes and costs nothing, you can test aggressively. But testing aggressively without a system produces noise, not signal.

    SBV creative A/B testing system showing four video variants running simultaneously with CTR comparison bars identifying the winning creative

    The One-Variable Rule

    The core discipline of SBV creative testing is changing one variable at a time. If you generate four video variations with different headlines, different template styles, different music, and different CTAs simultaneously, you cannot determine what drove any performance difference between them. You’ll know which video won; you won’t know why. And why is what lets you compound learnings across future creative cycles.

    For your first testing sprint, choose the variable you’re least certain about and hold everything else constant. For most brands new to SBV, that variable is the headline. Generate six videos with the same template and music, varying only the headline text across them. After sufficient data has accumulated — typically at least 500 impressions per variant, though more is better — pause the underperformers and move the winning headline into the next round of testing where you vary the template style or CTA.

    Campaign Structure for Testing

    The cleanest testing structure is to run each video variation as a separate ad within the same campaign. This keeps targeting, bidding, and placement identical across all variants, ensuring that performance differences are attributable to the creative rather than any campaign-level variable. Amazon’s campaign manager allows multiple ad creatives within a single Sponsored Brands campaign; use this feature deliberately rather than running separate campaigns per variant, which introduces budget allocation and bid competitiveness variables that contaminate the creative signal.

    Setting a Decision Timeline

    Many brands make the mistake of pausing underperforming ads too early — pulling a video after 200 impressions when the data is still statistically noisy. The right decision timeline depends on your daily ad spend and how quickly you accumulate impressions. A campaign spending $100/day will reach meaningful sample sizes faster than one spending $20/day. As a general operating rule: don’t make pause decisions in the first 7 days of a new creative test regardless of what the numbers appear to be saying. Amazon’s ad delivery system needs time to calibrate placement and bidding for new creative; early results often don’t reflect steady-state performance.

    What to Learn, Not Just What to Test

    Each testing round should be generating a transferable insight. “Test C won” is not an insight. “Test C won, and its headline led with a specific product claim (‘melts in 45 seconds’) rather than a brand benefit (‘premium quality’), which suggests our audience at this placement responds to functional specificity over aspiration” — that’s an insight. Document every round at this level and you’ll accumulate a creative intelligence asset that pays dividends well beyond any individual campaign.

    The Common Template Mistakes That Kill Performance Before a Click

    The availability of fast, low-cost SBV production creates a new failure mode: brands are now making creative errors at scale, quickly, where before those errors were rare because production was prohibitively expensive. Understanding the most common template mistakes helps you avoid distributing bad creative efficiently.

    Relying on Product Images That Weren’t Built for Video

    The Video Generator pulls from your existing product images. These images were almost certainly photographed for a static context — designed to look good as a thumbnail in a listing grid, on a white background, isolated and clear. When those images are animated and sequenced in a 15-second video, the result often looks like a slideshow rather than a video. It’s technically compliant, but it lacks the visual momentum that makes video effective.

    The solution is to ensure your product image library includes at least a few lifestyle images — products in use, in context, against non-white backgrounds — before generating template videos. These images translate into far more compelling video frames than isolated white-background hero shots. This is a listing preparation task, not a video production task, and many brands overlook it entirely when they think about SBV readiness.

    Writing Headlines That Are Too Long

    The headline in an SBV plays over a moving image, often against a background that isn’t perfectly controlled for legibility. Long headlines — anything over 7–8 words — become difficult to read in the screen time available and compete with the visual for attention. The best-performing SBV headlines are short, specific, and instantly comprehensible. “Zero Sugar. Full Flavor.” beats “Our award-winning sports drink now comes in sugar-free formulations.” The former lands in one second. The latter requires three seconds of reading that most viewers won’t give you.

    Using the Same Video Everywhere

    Because production is now cheap, there’s no reason to run a single SBV across all placements, all keyword groups, and all stages of your funnel. A brand-awareness-mode video (looser, lifestyle-forward, emotional) is not the right creative for a shopping-mode placement against high-intent keywords. A direct-response video with a tight product claim and a “Shop Now” CTA is not the right creative for a PDP placement where the shopper needs more convincing. The template workflow makes it cheap to produce placement-specific and intent-specific creative; use that capability.

    Not Accounting for the Muted Autoplay Context

    SBV ads autoplay muted. The viewer has not chosen to engage with your ad; it simply started playing in their field of view. Every creative element that assumes audio — voiceover, sound effects, music that creates emotional context — is invisible to the majority of initial viewers. Your video must communicate its primary message through visuals and text alone. If the headline disappears and only the product remains on screen, can the viewer still understand what this product does and why they might want it? If the answer is no, the creative needs revision.

    Measuring SBV Template ROI: The Metrics That Actually Matter

    The new SBV creative tools solve a production problem, but they create a measurement responsibility. When creative was expensive, brands were careful about what they produced and watched performance obsessively. When creative is free and fast, it’s easy to keep generating videos without establishing a clear success definition. Don’t fall into this trap.

    New-to-Brand Metrics Are Non-Negotiable

    Amazon now exposes new-to-brand (NTB) metrics directly in Sponsored Brands reporting. These include: new-to-brand orders, new-to-brand order rate, new-to-brand sales, and new-to-brand orders as a percentage of total orders. These metrics use a 12-month lookback window — a customer counts as new-to-brand if they haven’t purchased from your brand in the prior 12 months.

    For any SBV campaign, NTB rate should be a primary KPI alongside ROAS. A campaign delivering strong ROAS but 100% to existing customers is doing remarketing work, not customer acquisition. That’s still valuable — but if your goal is growth, it’s a different strategic contribution than you think you’re making. SBV running a 38% NTB rate is growing your customer base; a campaign running 12% NTB is largely selling to people who would have bought from you anyway.

    Branded Search Lift as a Halo Signal

    One of the most underutilized measurements for SBV is tracking branded search volume before and after campaign launch. When SBV campaigns generate genuine brand awareness among new audiences, branded search volume typically rises — people who encountered the brand through video then search directly for it. This is a real signal that’s systematically excluded from ROAS calculations, because the branded SP campaign that captures that search gets credit rather than the SBV that created the intent.

    Monitor your branded search impression share and branded keyword conversion rates in parallel with SBV campaign performance. If both rise in the weeks after an SBV scale-up, you’re capturing brand equity that ROAS doesn’t show you. This matters enormously for justifying SBV budget at the senior level, where ROAS-only storytelling undervalues the format’s contribution.

    Video Engagement Metrics Inside Creative Studio

    Amazon provides video-specific performance metrics within Creative Studio, including video completion rate (what percentage of viewers watched to the end), average watch time, and impression-to-click ratios. These are leading indicators of creative quality. A video with a 12% completion rate is losing most viewers before they’ve received your message. A video with a 55% completion rate is generating extended brand exposure across every impression.

    Benchmarks vary by category and placement, but as a general orientation: below 20% completion rate suggests a first-scene problem (the opening frame isn’t holding attention); between 20–40% suggests a mid-video pacing or relevance problem; above 40% is solid and suggests the creative is genuinely engaging the audience it reaches.

    What’s Coming: The SBV Creative Roadmap

    Amazon’s investment in AI-assisted creative tools is accelerating, and the current Video Generator and Creative Agent workflows are early iterations rather than finished products. Understanding the direction of travel helps you build a creative infrastructure now that will adapt well to capabilities arriving in the next 6–18 months.

    Vertical Video for Mobile-First Placements

    The current SBV spec is 16:9 horizontal, which aligns with desktop viewing and traditional video production. But Amazon’s mobile traffic has been growing consistently, and social-platform mobile behavior — where vertical video is the default — is reshaping viewer expectations. Amazon has been signaling a move toward supporting vertical (9:16) video formats for mobile placements, similar to how Meta and TikTok have built mobile-native ad environments. Brands that begin thinking about their SBV creative in a mobile-first vertical format now will have an advantage when Amazon officially opens those placements.

    ASIN-to-Video Personalization at Scale

    The next maturity stage for the Video Generator is likely dynamic creative optimization at the ASIN level — where large catalog brands can generate video assets for dozens or hundreds of products simultaneously, with product-specific assets auto-generated from each ASIN’s unique images and copy. For brands with broad catalogs, this would represent a step-change in SBV coverage that currently requires significant manual work. Early agentic features in Creative Agent already hint at this direction.

    Streaming TV and the Full-Funnel Creative Stack

    Amazon’s broader creative strategy, as outlined at unBoxed 2025, is a full-funnel video stack that runs from Streaming TV and Prime Video ads (upper funnel, large-format) down through SBV (mid-funnel, search intent) to Sponsored Products Video (lower funnel, conversion intent). Creative Studio is being built to serve all of these formats from a single creative workspace. Brands that get efficient with SBV template production now are building institutional knowledge that will transfer directly to the broader video formats as Amazon’s programmatic video inventory expands.

    From Tool to Strategy: Putting the Workflow to Work

    The most important reframe for brands approaching the new SBV creative tools is this: the bottleneck has moved. It used to be production — getting video made was the hard part. That bottleneck is now effectively gone. The new bottleneck is strategy: knowing which products to prioritize, which creative angles to test, which placements to target, and how to read the measurement data to make better decisions in the next cycle.

    Brands that treat the Video Generator as a “set it and generate” solution will produce video ads they’re mildly satisfied with and wonder why performance doesn’t match the benchmarks. Brands that use the speed of the template workflow to run structured, systematic creative tests will accumulate learnings that compound over time — getting better at SBV with every iteration in a way that was simply not possible when each video cost $10,000 to produce.

    The tools are genuinely useful. But they’re the beginning of the work, not the end of it.

    Conclusion: 5 Actionable Takeaways

    Amazon’s new SBV creative tools represent a real shift in who can run Sponsored Brands Video effectively. The production barrier — the one that kept most small and mid-size brands from competing in the format — is functionally gone. But removing a barrier doesn’t guarantee results. Here is what to actually do with this new capability:

    1. Audit your product images before touching Creative Studio. The Video Generator is only as good as the assets on your listing. Lifestyle images, in-use photography, and diverse angles produce far better video output than white-background hero shots. Fix the inputs before generating the output.
    2. Use the Quick Video template path for testing volume and Creative Agent for narrative-driven launch creative. They’re complementary tools, not competing ones. Let the template path generate your testing variants cheaply; use Creative Agent when you need a truly differentiated hero creative for a major campaign.
    3. Make the headline your primary creative variable. It’s what you control most, it’s what viewers read first, and it’s where small changes produce measurable performance differences. Test it systematically and document what you learn.
    4. Add new-to-brand metrics to every SBV campaign report. ROAS alone misrepresents SBV’s contribution. NTB rate tells you whether the campaign is growing your customer base or recycling it. Both matter; neither tells the whole story without the other.
    5. Start building the habit now. The brands that will have durable advantage in SBV over the next 12–24 months are the ones building creative testing data, NTB benchmarks, and placement performance intelligence today. The tools are early. The learning curve is real. Get on it ahead of your competitors rather than after them.

    The template workflow makes SBV accessible. What you do with that access is still a strategic choice. Make it deliberately.

  • When Agents Work Together: The Engineering Reality of Robust Multi-Agent Pipelines

    When Agents Work Together: The Engineering Reality of Robust Multi-Agent Pipelines

    Multi-agent pipeline architecture diagram showing orchestrator, researcher, validator, executor, and review agents connected by directed handoff edges with status indicators

    There is a moment every team hits, usually around their third or fourth agent in production, when the system stops behaving like software and starts behaving like a group of colleagues who haven’t been properly briefed. An agent hands off a half-baked result. Another agent accepts it without checking. A third goes quietly off-script. By the time anyone notices, the pipeline has produced something technically complete and factually wrong — and nobody can explain how.

    This is the coordination tax. It doesn’t show up in demos. It doesn’t appear in benchmark scores. It surfaces in production, at scale, after you’ve already committed to the architecture.

    The shift to multi-agent systems was supposed to solve problems that single agents couldn’t: parallelism, specialization, long-horizon task decomposition. And it does solve those things — when the orchestration layer is designed as carefully as the agents themselves. The trouble is that most teams spend 90% of their effort on the agents and about 10% on what happens between them.

    This post is about that 10%. It covers the topology choices that determine how failure propagates, the state management patterns that make pipelines recoverable, the protocol stack that is rapidly becoming the enterprise standard for agent coordination, the six failure modes that quietly destroy multi-agent pipelines in production, and the observability and security work that most teams skip until something breaks badly enough to force them back to first principles.

    If you’ve already deployed agentic workflows and found the complexity growing faster than the value, this is the engineering perspective you were missing at the start.

    What “Post-Agentic” Actually Means — and Why the Terminology Matters

    The phrase “post-agentic orchestration” is doing real conceptual work, not just following a naming trend. It marks a specific inflection point in how teams think about AI systems.

    The first wave of agentic AI — roughly 2023 to mid-2025 — was characterized by what might charitably be called optimistic autonomy. Teams built agents and let them route their own decisions. The LLM chose the next tool. The LLM chose when to stop. The LLM decided which result was good enough to pass downstream. Frameworks like early LangChain made this easy to set up and very hard to reason about in production.

    Post-agentic orchestration rejects that premise. It treats agents as specialized components inside a larger, explicitly governed workflow — not as autonomous actors that happen to share a pipeline. The LLM is still doing the hard cognitive work, but the control flow, the handoff logic, and the state transitions are defined in code, not inferred at runtime by a model.

    The Distinction That Actually Changes Your Architecture

    Anthropic’s engineering team captured this distinction cleanly in their work on building effective agents: workflows are systems where LLMs and tools are orchestrated through predefined code paths, while agents are systems where LLMs dynamically direct their own processes. Both are valid. The question is which one you need for a given task — and most teams reach for the autonomous agent when a well-structured workflow would be more reliable, cheaper to run, and easier to debug.

    Post-agentic orchestration is the recognition that in most enterprise contexts, you want agents to be excellent at their specific tasks while the orchestrator — not the agent — decides what happens next. This isn’t a step backward from agentic AI. It’s what agentic AI looks like when it grows up.

    Why the Terminology Matters Beyond Semantics

    When you call something an “agent,” there’s an implicit expectation of autonomy and self-direction. When you frame it as a “component in an orchestrated pipeline,” the design questions change immediately: What inputs does this component require? What outputs does it guarantee? How does it signal failure? What authority does it have to make side effects?

    These are not LLM questions. They are distributed systems questions — and that’s exactly the lens that 2026’s most reliable multi-agent pipelines are being built with. Production teams in 2026 are increasingly treating multi-agent pipelines less like prompt chains and more like distributed microservice architectures, applying the same engineering rigor around contracts, state, retries, and observability.

    The Four Topology Choices — and When Each One Breaks

    Comparison diagram of four multi-agent topology patterns: linear chain, hierarchical orchestrator-worker, peer-to-peer mesh, and directed acyclic graph

    Before you write a single line of orchestration code, the most consequential decision you’ll make is your topology. How agents are connected determines how errors propagate, how context flows, how parallelism works, and ultimately how much you can recover when something goes wrong.

    There are four dominant topologies in production multi-agent systems, and each has a specific failure profile that’s worth understanding before you commit.

    Linear Chains: Simple to Build, Brittle to Operate

    A linear chain is the default topology most teams reach for first. Agent A passes output to Agent B, which passes to Agent C, and so on. It’s intuitive, easy to reason about, and maps cleanly to sequential tasks like “research, then draft, then review.”

    The problem is error propagation. In a linear chain, a degraded output from Agent B doesn’t just produce a worse result at step C — it actively misdirects Agent C, which may then produce a confident but incorrect output that propagates to D. Research from fault-injection studies on MetaGPT-style linear architectures shows near-total cascade collapse under certain failure modes, because there is no mechanism to intercept an error mid-chain without discarding all downstream work.

    Linear chains are appropriate for tasks that decompose cleanly into sequential steps where each step is deterministic and the output of each step is easy to validate programmatically. When steps involve LLM judgment calls, you need gates — explicit programmatic checks that validate intermediate outputs before passing them downstream. Without gates, a linear chain is a cascade-failure machine waiting to be triggered.

    Hierarchical Orchestrator-Worker: The Production Workhorse

    The hierarchical pattern puts a dedicated orchestrator agent at the top of the stack. The orchestrator plans, routes, and assembles — but doesn’t execute domain tasks. Worker agents below it handle specialized execution: a research agent, a calculation agent, a writing agent, a validation agent. Results flow back up to the orchestrator, which decides what to do next.

    This topology is the most widely adopted in enterprise production deployments in 2026 for a simple reason: it localizes failure. When the research agent fails, the orchestrator knows it, can retry with a different strategy, and the writing agent never sees a degraded input it wasn’t designed to handle.

    The orchestrator-worker pattern’s weakness is the orchestrator itself becoming a bottleneck — both in terms of latency (everything passes through it) and in terms of cognitive load (the orchestrator’s context window fills with accumulated task state across long workflows). Teams address this with sub-orchestrators: smaller orchestrators that manage subsections of the workflow and report aggregated results upward, creating a two-level or three-level hierarchy.

    Peer-to-Peer Mesh: Theoretically Flexible, Practically Dangerous

    In a mesh topology, agents can communicate directly with each other without routing through a central orchestrator. An agent can request help from any peer, delegate subtasks laterally, and receive results from multiple sources simultaneously.

    The appeal is flexibility and low latency for certain coordination patterns. The reality in production is complexity explosion. Debugging a failure in a mesh is extremely difficult because you lose the single path of execution that you could trace. Circular delegation — where Agent A asks Agent B, which asks Agent C, which asks Agent A — becomes possible and is surprisingly hard to prevent without explicit cycle detection. Trust boundaries become ambiguous because any agent can communicate with any other.

    Mesh topologies remain mostly in research contexts or in tightly scoped, well-instrumented production deployments. Most teams who start with mesh architecture migrate toward hierarchical or graph-based designs after their first significant production incident.

    Graph (DAG) Topologies: The Most Resilient, the Hardest to Design

    Directed Acyclic Graph (DAG) topologies model the workflow as an explicit graph of nodes and edges, where each node is an agent or tool invocation and each edge represents a data dependency or control flow transition. Branches, merges, conditional routing, and parallel execution are all native to the model.

    Iterative, closed-loop designs built on DAG principles neutralize over 40% of faults that cause catastrophic collapse in linear workflows, according to recent fault-injection research. The reason is structural: a DAG forces you to design explicit merge points, where outputs from parallel branches are combined and validated before proceeding, and explicit conditional branches, where the next node is chosen based on structured evaluation of the previous result.

    The cost is design complexity upfront. Building a good DAG requires you to model your workflow as a proper state machine before you build it — which is uncomfortable for teams that want to iterate rapidly. The payoff at scale is substantial. Frameworks like LangGraph have emerged specifically to make DAG-based multi-agent pipelines manageable, offering graph-based workflow definition with built-in checkpointing and state management.

    State Management: The Hidden Load-Bearing Wall

    Diagram showing multi-agent shared state management with schema-enforced state store, color-coded successful and failed state transitions, and rollback mechanism

    If topology determines how failure propagates, state management determines whether you can recover from it. And in most multi-agent systems built in 2024 and early 2025, state was an afterthought — which is why so many of those systems are being rewritten in 2026.

    State in a multi-agent pipeline has three distinct layers, and conflating them is one of the most common architectural mistakes teams make.

    Layer 1: Conversational Context

    This is the in-context memory each agent carries — the accumulated messages, tool results, and instructions that fit within its context window. Conversational context is ephemeral: it dies when the agent call ends, and it doesn’t survive restarts, retries, or handoffs unless you explicitly pass it forward.

    Many teams treat conversational context as if it were workflow state, passing the full conversation history as a handoff payload from agent to agent. This creates two problems. First, context windows fill up — a five-hop agent pipeline passing full history at each step is burning tokens on information most downstream agents don’t need. Second, the receiving agent has no structured way to identify which parts of the history are relevant to its task.

    The production pattern is to summarize or extract structured outputs at each hop, passing only the typed data the next agent actually requires, not the full conversational trace. This requires more upfront schema design but dramatically improves reliability and cost efficiency.

    Layer 2: Workflow State

    Workflow state is the persistent, typed record of what has happened in the pipeline so far — completed steps, intermediate results, branching decisions, and retry counts. This is the layer that makes recovery possible.

    The non-negotiable property of production workflow state is durability. If a worker agent crashes mid-execution, the orchestrator needs to know what was completed, what was not, and what inputs the failed step received — so it can retry without re-running everything from scratch. Without durable workflow state, any failure resets the entire pipeline.

    The 2026 production standard is schema-enforced shared state with explicit write semantics. Every state mutation is typed, validated, and logged. Agents don’t write arbitrary key-value data to a shared store — they emit structured state transitions that the orchestrator validates before they’re committed. This is the same pattern used in event sourcing and CQRS architectures, and it maps directly onto multi-agent pipelines because the fundamental problem — distributed components modifying shared state — is identical.

    Layer 3: External Side Effects

    Side effects — database writes, API calls, emails sent, files written — are the most dangerous category of state because they cannot be easily rolled back. A multi-agent pipeline that makes an external write halfway through and then fails faces a partial commitment problem that’s familiar to anyone who has debugged a distributed transaction.

    The pattern that works is treating all external side effects as idempotent operations with explicit rollback plans. Every tool call that touches external state should have an idempotency key, a confirmation step before execution, and a logged record of what was written. Agents should not be given open-ended write access to external systems — they should have scoped, validated, reversible write capabilities that the orchestrator controls. This isn’t overcaution; it’s the baseline requirement for operating any distributed system reliably.

    MCP and A2A: How the Protocol Stack Changes Your Design Decisions

    Split-screen diagram showing MCP protocol for agent-to-tool connections versus A2A protocol for agent-to-agent coordination, labeled as complementary standards

    Through the first half of 2026, the multi-agent protocol landscape consolidated faster than most analysts expected. Two standards now dominate, and understanding exactly what each one does — and what it doesn’t do — is essential for designing systems that will survive vendor changes and ecosystem shifts.

    MCP: The Tool Access Layer

    The Model Context Protocol (MCP), originally released by Anthropic and now stewarded by the Linux Foundation’s Agentic AI Foundation (AAIF), standardizes how agents access external tools and data sources. An MCP server exposes capabilities — search, code execution, database queries, file operations — in a structured, discoverable format. An MCP client (the agent) can query which tools are available, understand their input/output contracts, and invoke them without bespoke integration code for each tool.

    The practical impact is significant. Before MCP, every new tool integration required custom code in every agent framework that wanted to use it. With MCP, a tool server is written once and consumed by any MCP-compatible agent. This dramatically reduces the integration tax when adding new capabilities to a multi-agent pipeline.

    What MCP does not do is handle coordination between agents. It’s a tool access layer, not a coordination layer. An agent using MCP is still making its own decisions about which tools to call and in what order — MCP just makes those tools universally accessible.

    A2A: The Agent Coordination Layer

    The Agent-to-Agent (A2A) protocol, which hit v1.0 and formal AAIF governance in mid-2026, addresses exactly the coordination gap that MCP leaves open. A2A defines how agents discover each other, delegate tasks, communicate progress, and exchange results — across vendor boundaries, across cloud environments, and across different underlying model providers.

    With A2A, an orchestrator agent can discover available worker agents, query their capabilities in a structured format, delegate a task with a typed payload, receive streaming progress updates, and get a structured result back — all without needing to know which framework the worker agent was built on, which model it’s running, or which cloud it’s deployed to.

    This interoperability matters enormously as enterprise multi-agent systems grow larger. Without a standard, every agent-to-agent interaction requires bespoke integration. With A2A, a financial services firm can compose a multi-agent pipeline that includes agents from multiple vendors without building custom coordination logic for each pair.

    As of mid-2026, over 150 organizations are actively supporting A2A as a standard, and the protocol is in production use across financial services, supply chain, healthcare, and IT operations. All major cloud providers have announced or deployed A2A support.

    The Design Decision the Standards Create

    The practical implication for architects is that the 2026 enterprise multi-agent stack uses MCP for tool access and A2A for agent coordination. These are not competing choices — they operate at different layers. An agent might use MCP to call a web search tool while using A2A to delegate a research subtask to a specialized research agent that happens to be running in a different environment.

    The key design implication is that both protocols push you toward explicit interface contracts. MCP requires you to define tool schemas. A2A requires you to define agent capability cards and task schemas. This overhead in the design phase pays dividends when you need to swap out a component, debug a failure, or audit what happened in a pipeline run.

    The Six Failure Modes That Kill Multi-Agent Pipelines in Production

    Production data from 2025 and early 2026 has produced much cleaner taxonomies of multi-agent failure than were available when these architectures first emerged. The picture that emerges is that model quality accounts for a relatively small share of failures. The dominant causes are architectural and operational — which means they’re preventable with better design.

    Failure Mode 1: Specification Drift

    Specification drift happens when agents are given instructions that are underspecified, internally inconsistent, or that conflict with each other’s goals. In a single-agent system, this produces a confused output. In a multi-agent system, it produces a pipeline where each agent is confidently executing a subtask that doesn’t align with what the other agents are doing.

    The symptom is pipeline outputs that are technically complete but systematically wrong in ways that are hard to pinpoint. Each agent’s output, evaluated individually, looks reasonable. The failure is in the gap between individual correctness and collective coherence.

    Prevention requires treating agent specifications as a system-level design artifact, not as individual prompt engineering. Every agent’s role, scope, inputs, outputs, and success criteria should be designed in relation to every other agent in the pipeline. Contradictions should be resolved before deployment, not discovered in production.

    Failure Mode 2: Context Starvation

    A downstream agent produces a degraded output not because its instructions are wrong, but because it received insufficient context to work with. The handoff payload from the upstream agent was too sparse — either because the upstream agent summarized too aggressively, or because the pipeline architecture never defined what a complete handoff payload looks like.

    Context starvation is insidious because it looks like a quality problem, not a coordination problem. Teams typically respond by improving the model or the prompts on the receiving agent, when the actual fix is in the handoff contract between agents.

    Failure Mode 3: Hallucination Amplification

    Single-agent hallucinations are well understood and manageable with appropriate retrieval and verification. Multi-agent hallucinations compound in ways that are much harder to intercept. A factual error produced by Agent A is accepted by Agent B, which builds analysis on top of it. Agent C receives the compounded error as an established fact and generates confident conclusions from it. By the time the hallucination reaches the end of the pipeline, it has the authority of several independent confirmations — none of which were actually independent.

    The mitigation is explicit verification gates at each pipeline stage. Outputs that will be passed as inputs to downstream agents should be validated against source data or external checks before handoff. This adds latency but substantially reduces the probability of compounded error. Some teams run a dedicated “skeptic agent” whose only job is to challenge and verify upstream outputs before they propagate.

    Failure Mode 4: Runaway Delegation

    This failure mode is unique to multi-agent systems. An orchestrator delegates a task to a worker. The worker, lacking clear boundaries, delegates subtasks to other workers. Those workers spawn additional subtasks. The result is an exponentially growing tree of agent invocations consuming tokens and API calls without producing a useful result, and without any mechanism for the original orchestrator to recognize or interrupt the runaway.

    Prevention requires explicit delegation budgets enforced at the orchestration layer: maximum depth of delegation, maximum number of total agent invocations per workflow, and timeout mechanisms that escalate to human review rather than silently consuming resources.

    Failure Mode 5: Coordination Deadlock

    Two or more agents that depend on each other’s outputs can enter a state where neither can proceed — a classic distributed systems deadlock translated into the agent context. This is particularly common in peer-to-peer topologies where agents have been given bidirectional communication channels without explicit sequencing rules.

    The solution is the same one distributed systems engineers have applied for decades: define dependency graphs explicitly before execution, detect circular dependencies at design time, and use timeout-with-escalation rather than indefinite waiting.

    Failure Mode 6: Silent Tool Failure

    A tool called by an agent returns an error or a malformed result. The agent, not designed with robust error handling, either proceeds with the bad data or silently produces a null-equivalent response. The orchestrator has no signal that anything went wrong. The pipeline completes. The output is garbage.

    Every tool invocation in a production multi-agent pipeline needs explicit success/failure semantics: structured error returns, retry policies with backoff, and escalation paths that surface failures to the orchestrator rather than burying them inside agent context. This is basic defensive programming applied to tool calls — but it’s absent in a surprising proportion of production agent implementations.

    Fault Tolerance Without Drama: Circuit Breakers, Dead Letters, and Checkpoints

    Recognizing failure modes is the diagnosis. Circuit breakers, dead letter handling, and checkpointing are the treatment — the engineering patterns that transform a fragile chain of agents into a system that fails gracefully and recovers predictably.

    Circuit Breakers for Agent Calls

    Borrowed from distributed systems engineering, a circuit breaker monitors the failure rate of a downstream component. When failures exceed a threshold, the circuit “opens” — calls to that component are rejected immediately rather than allowed to block and consume resources. After a cooldown period, the circuit enters a half-open state where limited calls are allowed to test recovery.

    Applied to multi-agent pipelines, this means the orchestrator maintains health metrics for each worker agent: failure rate, latency, and error types. A worker agent that is consistently failing, slow, or producing malformed outputs triggers the circuit breaker, routing those tasks to a fallback agent or escalating to human review. This prevents a single degraded component from consuming the entire pipeline’s resources and producing corrupted outputs that contaminate downstream processing.

    Dead Letter Handling

    In message queue architectures, a dead letter queue captures messages that couldn’t be successfully processed after a configured number of retries. The equivalent in multi-agent pipelines is a dead letter store for tasks that have exhausted their retry budget without producing a valid output.

    Dead letter handling requires you to design your pipeline with three things: explicit retry limits per task, a structured failure payload that captures what was attempted and why it failed, and a process for handling dead-lettered tasks — whether that’s human review, an alternative agent path, or graceful degradation of the final output.

    Teams that omit dead letter handling typically discover this gap when a task quietly disappears from their pipeline — consumed by retries, never completed, and never surfaced as a failure because there was no mechanism to surface it.

    Checkpointing and Durable Execution

    A checkpoint is a persisted snapshot of workflow state at a specific point in pipeline execution. If the pipeline fails after a checkpoint, recovery resumes from the checkpoint rather than from the beginning. In long-running multi-agent workflows — which can span minutes to hours and may involve dozens of API calls and LLM invocations — the economics of checkpointing are straightforward: the cost of persisting state at each major step is a fraction of the cost of re-running the entire workflow on failure.

    The engineering implementation requires idempotent step execution: each step, if re-run from a checkpoint, should produce the same result it produced the first time. This means tool calls need idempotency keys, and LLM calls that depend on non-deterministic results need to have their outputs captured in state rather than re-generated on retry.

    Production frameworks including LangGraph and Temporal are seeing adoption specifically because they provide built-in checkpointing, durable state persistence, and replay semantics — effectively bringing durable execution patterns from workflow orchestration systems into the agent layer.

    Observability Is Not Optional: Tracing Handoffs Across Agent Boundaries

    Multi-agent observability dashboard showing hierarchical trace waterfall with orchestrator parent span, child agent spans, tool call details, error highlighting, and key metrics

    The phrase “observability” in the context of single-agent systems typically means logging LLM calls and tracking token usage. In multi-agent systems, this is wildly insufficient — because the failures that matter most happen at the boundaries between agents, not inside them.

    What Handoff-Aware Tracing Actually Requires

    Standard distributed tracing concepts apply directly to multi-agent pipelines, with some necessary extensions. A trace represents a complete pipeline execution from the initial task trigger to the final output. Spans within that trace represent individual agent invocations, tool calls, and handoffs. The critical requirement is that the trace ID propagates across every handoff — so you can reconstruct the complete causal chain of what happened and in what order, even when agents are running in parallel across different compute resources.

    Handoff-aware tracing needs to capture more than just timing: it needs the structured payload that was passed at each handoff (what data moved between agents), the decision logic that triggered the handoff (what condition in the orchestrator caused it to route to this agent), and the success/failure status of each agent’s execution. Without this, debugging a multi-agent pipeline failure is guesswork.

    OpenTelemetry is emerging as the baseline for multi-agent tracing in 2026, with GenAI-specific semantic conventions being standardized to cover LLM calls, tool invocations, and agent spans. Major APM vendors including Datadog, Honeycomb, and New Relic have shipped first-class multi-agent trace views — hierarchical UIs that show the full tree of agent invocations, collapsed by agent type, with drill-down into individual LLM calls and tool results.

    Evaluation in the Trace Loop

    The most sophisticated production teams in 2026 are coupling observability with automated evaluation — running quality assessments on agent outputs as part of the trace pipeline, not as an offline batch process. This means every agent handoff can be scored against defined quality criteria in near-real time, with quality regressions surfaced as trace annotations rather than discovered hours later through downstream complaints.

    The practical implementation is an evaluation span inserted after each significant agent output: a lightweight LLM call or rule-based check that scores the output and appends the score to the trace. When quality drops below a threshold, the orchestrator is notified immediately and can route to a fallback strategy rather than propagating a degraded result.

    What “57%” Means in Practice

    As of 2026, 57% of organizations report using AI agents in production — up from 51% the prior year. But the same surveys show that detailed multi-agent tracing and production-grade guardrails remain significant gaps in most deployments. The gap between “we have agents running” and “we can see what they’re doing and respond to problems” is where the majority of multi-agent production failures originate. Organizations that treat observability as a day-one requirement rather than a future iteration consistently report fewer production incidents and faster time-to-resolution when incidents do occur.

    Security at the Seams: Trust Boundaries in Multi-Agent Systems

    Security architecture diagram for multi-agent systems showing zero-trust trust boundaries, agent identity tokens, least-privilege tool access, and prompt injection threat blocked at perimeter

    Multi-agent systems introduce security risks that simply don’t exist in single-agent architectures. The most significant of these is cross-agent prompt injection — and it’s rapidly becoming the primary security concern for enterprise AI deployments in 2026.

    Cross-Agent Prompt Injection: Why It’s Worse Than You Think

    A prompt injection attack in a single-agent system involves a malicious instruction embedded in external data — a document, a webpage, a user message — that overrides the agent’s intended behavior. The blast radius is limited to that single agent’s actions.

    In a multi-agent system, prompt injection can cascade. Malicious instructions injected into one agent’s context can be passed forward as legitimate task data to downstream agents, which execute the injected instructions with the full authority of their role in the pipeline. An instruction injected into a research agent can travel downstream to an executor agent that has write access to production systems — bypassing every security control that was applied only at the entry point.

    The security community’s consensus in 2026 is to treat every inter-agent message as potentially untrusted data, regardless of its source. This is a zero-trust model applied to agent communication: the fact that a message came from another agent in your pipeline is not sufficient authorization to execute instructions it contains without validation.

    Agent Identity and Least-Privilege Access

    A2A v1.0 addresses the identity problem directly. Under the A2A model, agents have structured identity credentials — capability cards that define what they are authorized to do. Orchestrators can verify agent identity before delegating tasks, and agents can verify the identity and authority of the orchestrators directing them.

    The least-privilege principle applies to both tool access and inter-agent delegation. A research agent should have read access to the data sources it needs and nothing else. An executor agent should have the minimum write permissions necessary for its specific tasks, scoped to specific resources rather than broad categories. An agent should never be granted the authority to delegate to other agents with broader permissions than its own.

    These principles are straightforward to state and non-trivial to implement — particularly in systems that were built before these security requirements became clear. Retrofitting zero-trust agent identity into an existing multi-agent pipeline is substantially harder than designing it in from the start, which is why security architecture needs to be a first-class consideration before the first agent is deployed.

    Audit Logging as a Security Requirement

    Every inter-agent handoff, every tool invocation, every delegation decision, and every external side effect should be logged in an immutable audit trail. This is not just an observability requirement — it’s a security requirement. When a multi-agent pipeline is used as an attack vector (or when internal misuse needs to be investigated), the audit log is the primary forensic artifact.

    Audit logs for multi-agent systems should include the agent identity at each step, the authority chain (which agent authorized which action), the inputs and outputs at each boundary, and timestamps with sufficient resolution to reconstruct the sequence of events. Teams that have invested in this infrastructure consistently find it invaluable when incidents occur — and worth the engineering cost several times over in the first incident it helps resolve.

    Governance, Human-in-the-Loop, and the Autonomy Dial

    One of the harder design decisions in any multi-agent system is calibrating how much autonomy to grant the pipeline — and where to insert human judgment into the loop. This isn’t primarily a safety question (though it is that too). It’s a reliability question.

    Designing the Autonomy Spectrum

    Think of pipeline autonomy as a dial with five settings:

    • Fully Supervised: Human approves every agent action before execution. Maximum control, zero throughput at scale.
    • Step-Gated: Human approves outputs at defined checkpoints — before a task moves to the next major phase. Appropriate for high-stakes workflows.
    • Exception-Based: Pipeline runs autonomously unless a predefined condition (confidence below threshold, cost above budget, novel situation detected) triggers human escalation. The production-grade default for most enterprise workflows.
    • Audit-Only: Pipeline runs fully autonomously; humans review logs after the fact. Appropriate for low-stakes, high-volume, reversible tasks.
    • Fully Autonomous: No human in the loop. Appropriate only for tasks where errors are easily detected and corrected automatically, and where the cost of human review exceeds the cost of occasional errors.

    Most production multi-agent pipelines in 2026 operate at the exception-based level for routine tasks, with step-gating for high-stakes actions and a clear escalation path to human review. The fully autonomous setting is deployed cautiously and usually for well-understood, high-volume, low-consequence tasks where the pipeline has demonstrated sustained reliability over thousands of runs.

    What Good Human-in-the-Loop Design Looks Like

    Human-in-the-loop is often implemented as a checkbox — “we’ll add a review step before final output.” This is better than nothing but misses the point of where human judgment actually adds value in a multi-agent pipeline.

    Effective HITL design identifies the specific decision points where human judgment has a comparative advantage over the pipeline’s automated judgment. These tend to be: decisions involving novel situations the pipeline hasn’t encountered before, decisions with large, hard-to-reverse consequences, decisions involving stakeholder relationships that require human context, and decisions where the pipeline’s confidence is genuinely uncertain rather than falsely confident.

    At these specific points, the human reviewer should be given a structured interface that surfaces the relevant context, the pipeline’s proposed action, the confidence level, and the alternatives considered — not a raw dump of agent logs. The quality of human-in-the-loop oversight depends almost entirely on the quality of the interface that surfaces the decision to the reviewer.

    Governance Frameworks Are Becoming Mandatory

    As multi-agent systems grow in scope and consequence, governance is transitioning from best practice to regulatory requirement. Financial services, healthcare, and government deployments in particular are seeing explicit requirements around audit trails, decision explainability, and human oversight for consequential AI-driven actions.

    The architectures that handle this well are those that built governance in from the beginning — where audit logs are complete, where the authority chain for every action is traceable, and where human escalation paths exist and are tested regularly. The architectures that handle this poorly are those that treated governance as documentation work to be done after the pipeline was built, only to discover that the system’s decisions cannot be adequately explained or audited after the fact.

    Building Your First Production-Grade Pipeline: A Decision Framework

    Translating the above into practical guidance requires answering a specific sequence of questions before a single agent is instantiated. The following framework is designed for teams moving from prototype to production.

    Step 1: Justify the Multi-Agent Architecture

    Start with the hardest question: does this task actually require multiple agents? Anthropic’s engineering team observed that the most successful implementations they worked with started with the simplest possible architecture and added complexity only when clearly needed. A single well-designed LLM call with good retrieval will outperform a fragile multi-agent pipeline for tasks that are genuinely sequential and don’t require parallelism or specialization.

    Multi-agent architectures add justified value when: the task requires genuine specialization that would degrade under a single generalist agent, when parallelism would materially reduce latency, when the workflow is too long to fit in a single context window, or when different parts of the task have different reliability requirements that require different validation strategies.

    Step 2: Choose Your Topology Before Writing Code

    Map the task’s dependency structure. If steps are sequential and deterministic, a chain with gates may be sufficient. If steps require parallelism and a single coordination point, hierarchical orchestrator-worker is your default. If the workflow has conditional branching, merging parallel results, and loop-back conditions, design a DAG from the start — even if the initial implementation is simpler.

    Step 3: Define Your State Schema

    Write the typed schema for your workflow state before writing any agent code. What fields does the pipeline state contain? What are their types? Which agents can read which fields? Which agents can write which fields? What constitutes a valid state transition? This schema is your contract — it will surface conflicts in your design before they become runtime failures.

    Step 4: Define Handoff Contracts for Every Agent Boundary

    For every agent-to-agent transition in your pipeline, define: what structured data is passed in the handoff payload, what the receiving agent is expected to do with it, and what a valid output from the receiving agent looks like. These contracts should be validated programmatically at runtime, not just described in documentation.

    Step 5: Design Failure Handling Before You Design Happy Path

    For each agent and each tool call in your pipeline, define: what happens when it fails once, when it fails repeatedly, when it times out, and when it produces a result that fails quality validation. Build the retry policies, circuit breakers, dead letter handlers, and escalation paths before you build the primary execution logic. This inversion feels counter-intuitive but prevents the most common production failures in multi-agent systems.

    Step 6: Instrument Everything Before Deployment

    Define your trace structure, your key metrics (latency per agent hop, token cost per workflow run, failure rate per agent type), and your quality evaluation hooks before the pipeline goes to production. The cost of adding observability after the fact — especially in a system already handling production traffic — is substantially higher than building it in during initial development.

    The Shift Happening Underneath the Surface

    The most important development in multi-agent AI through 2026 isn’t any specific protocol, framework, or model capability. It’s an epistemological shift in how engineering teams think about these systems.

    The first generation of multi-agent builders asked: “What can this agent do?” The post-agentic generation asks: “How does this pipeline behave as a system?” The first question leads to impressive demos. The second question leads to reliable production systems.

    This shift is visible in how organizations are staffing these efforts. Teams that are succeeding with multi-agent pipelines in production have deliberately mixed profiles: AI engineers who understand model behavior, infrastructure engineers who understand distributed systems reliability, and platform engineers who understand tooling, observability, and developer experience. Teams staffed entirely with AI specialists consistently hit the same distributed systems problems from scratch — not because those problems are novel, but because they weren’t expecting to encounter them in an AI project.

    The systems that will define the standard for reliable multi-agent AI in the years ahead are being built right now by teams who are applying that mixed perspective — treating agent orchestration as a serious engineering discipline, not as an extension of prompt engineering. The design decisions they’re making today around topology, state management, protocols, fault tolerance, observability, and security will determine which systems are still running reliably two years from now.

    Conclusion: What Robust Actually Means for Multi-Agent Pipelines

    The word “robust” is overloaded in AI conversations. In the multi-agent context, it has a specific, testable meaning: a pipeline is robust if it produces correct outputs reliably, fails gracefully when components degrade, recovers predictably from failures without human intervention, surfaces the information needed to diagnose and fix problems when they occur, and does not create new security exposures through the coordination mechanisms it relies on.

    None of those properties emerge from building good agents. They emerge from designing good systems — systems built on explicit topologies, durable state management, standardized protocols, comprehensive fault handling, first-class observability, and zero-trust security boundaries.

    The coordination tax is real. But it is not fixed. It shrinks dramatically when the orchestration layer receives the same engineering attention that the agents themselves receive. The teams who have internalized this are building something qualitatively different from the teams still treating orchestration as plumbing — and the gap between them will only widen as multi-agent systems take on more consequential tasks.

    Actionable Takeaways

    • Audit your current topology. If you’re running linear chains without programmatic gates, you have latent cascade failure risks. Map your dependency graph explicitly.
    • Define your state schema before your next agent. Every field, every type, every write permission. This single artifact will prevent more runtime failures than any amount of prompt engineering.
    • Implement MCP for tools, A2A for agents. The protocol stack is stable enough to build on. Bespoke integrations are now technical debt.
    • Build failure handling before happy path. Retry policies, circuit breakers, dead letter handlers, and escalation paths are not optional features — they’re what separates a demo from a production system.
    • Add handoff-aware tracing on day one. The cost of retroactive instrumentation is three to five times higher than building it in during initial development.
    • Treat every inter-agent message as untrusted. Zero-trust agent identity is not paranoia — it is the appropriate security posture for systems that accept external data at any point in their pipeline.
    • Calibrate your autonomy dial deliberately. Exception-based human escalation is the production-grade default for most enterprise workflows. Fully autonomous should be earned through demonstrated reliability, not assumed.