Author: algofuse

  • When Bots Break: The Real Economics of Replacing Static Workflow Automation with Agentic AI

    When Bots Break: The Real Economics of Replacing Static Workflow Automation with Agentic AI

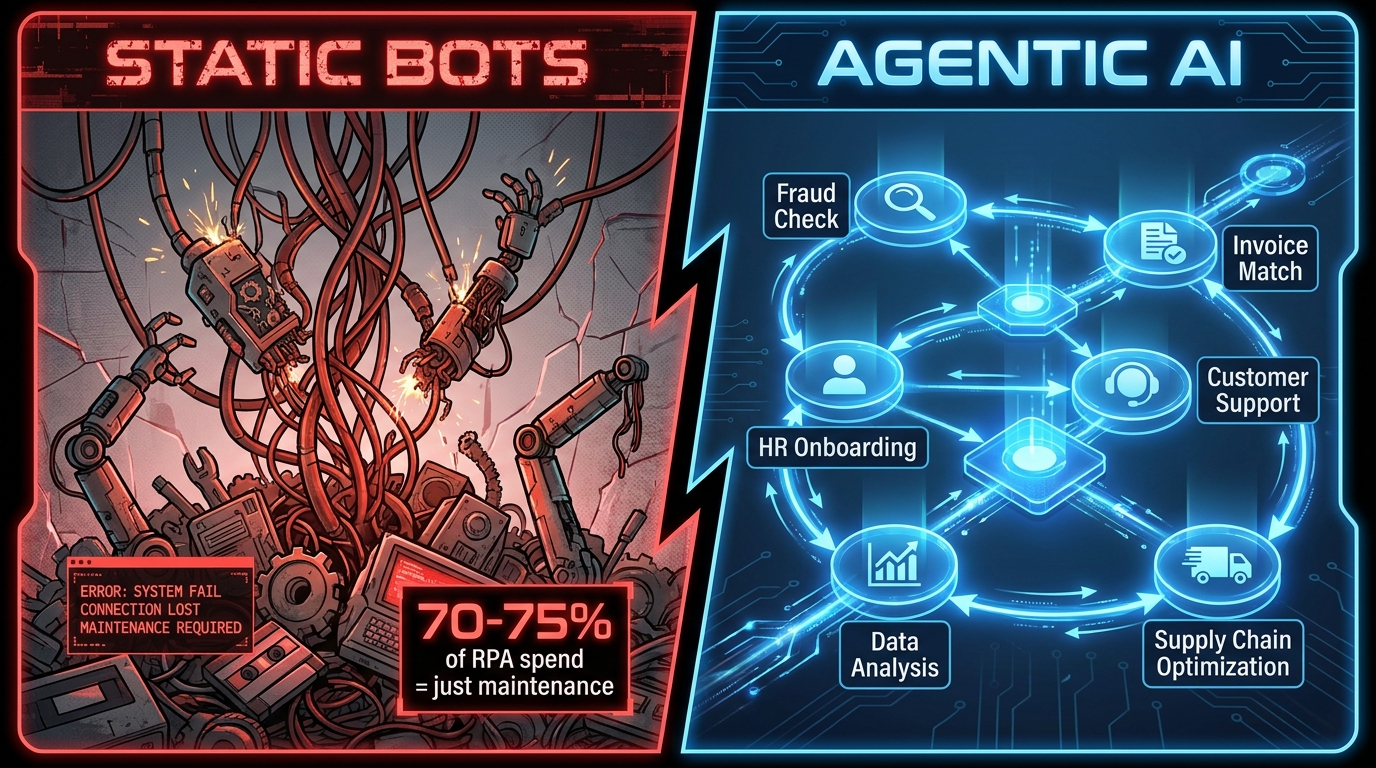
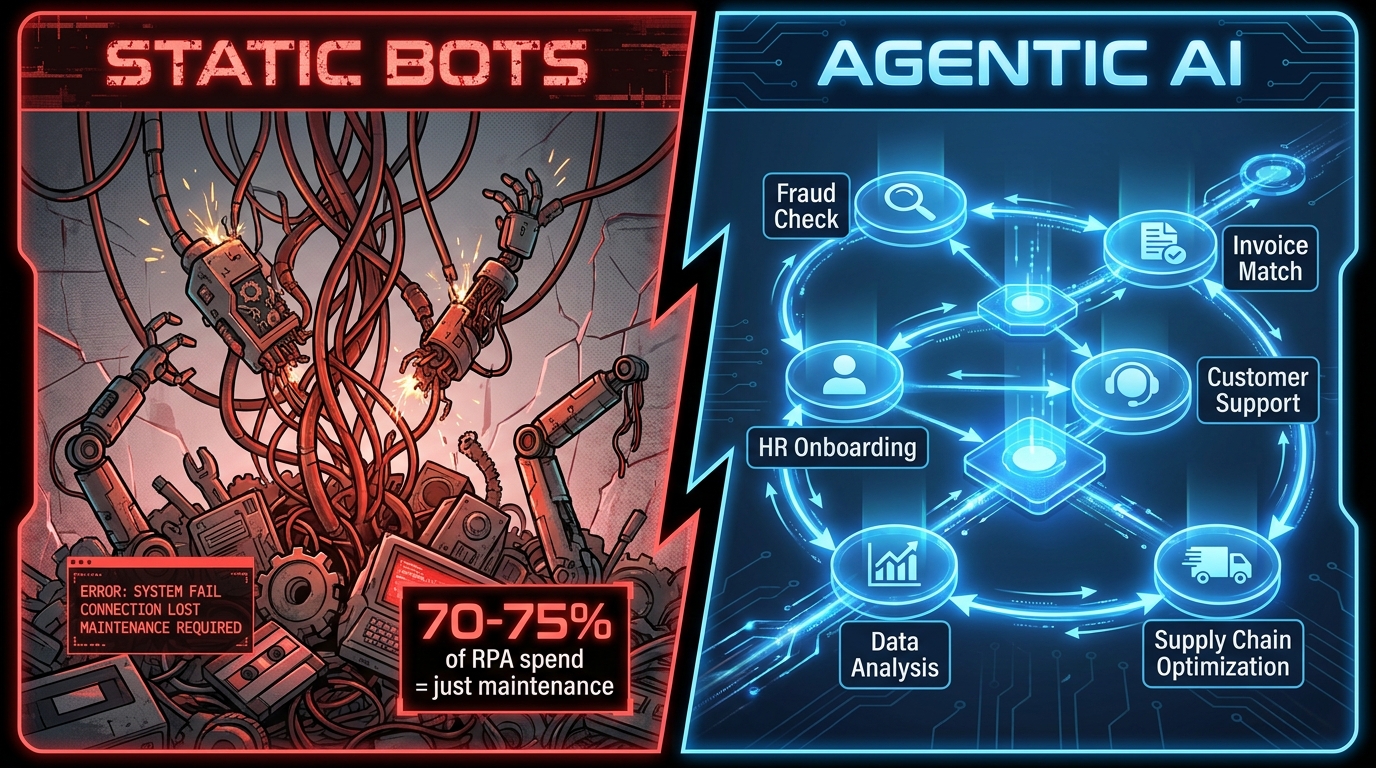
    Split scene showing broken static RPA bots on the left versus a connected agentic AI network on the right, illustrating the shift from brittle automation to intelligent agents

    Somewhere in your organization, there is probably a bot that nobody talks about anymore. It was built two years ago to handle a specific process — invoice matching, maybe, or new-hire account provisioning. It worked for about eight months. Then a vendor upgraded their portal, a browser extension changed, or someone restructured a spreadsheet column, and the bot quietly started failing.

    Now it lives on a server that three different teams claim ownership of, costs a developer four hours a month to patch, and handles maybe 60% of what it was originally designed to do. The remaining 40% gets kicked to a human queue that never quite empties.

    This is not a technology failure story. It is an economics story — and the economics of static workflow automation are quietly collapsing under the weight of their own maintenance burden. Enterprises built RPA estates on the assumption that “automate once, benefit forever” was a realistic proposition. It rarely is. What most organizations actually built was a fleet of fragile scripts that require constant tending just to maintain the status quo.

    Agentic AI is entering this space not as a flashy upgrade but as a structural solution to a problem that the industry has been reluctant to name clearly: static bots are not a solved problem. They are a recurring cost center dressed up as a capital investment. The question for 2026 is not whether agentic AI is better in a demo. The question is whether the transition economics actually work — and for which workflows, in what order, with what governance in place.

    This article breaks down the real cost of the bot status quo, explains what makes agentic architectures structurally different, and lays out the transition strategy that separates the 23% of enterprises successfully scaling agents from the majority still running on brittle scripts.

    The Bot Graveyard: Why RPA Promised More Than It Could Deliver
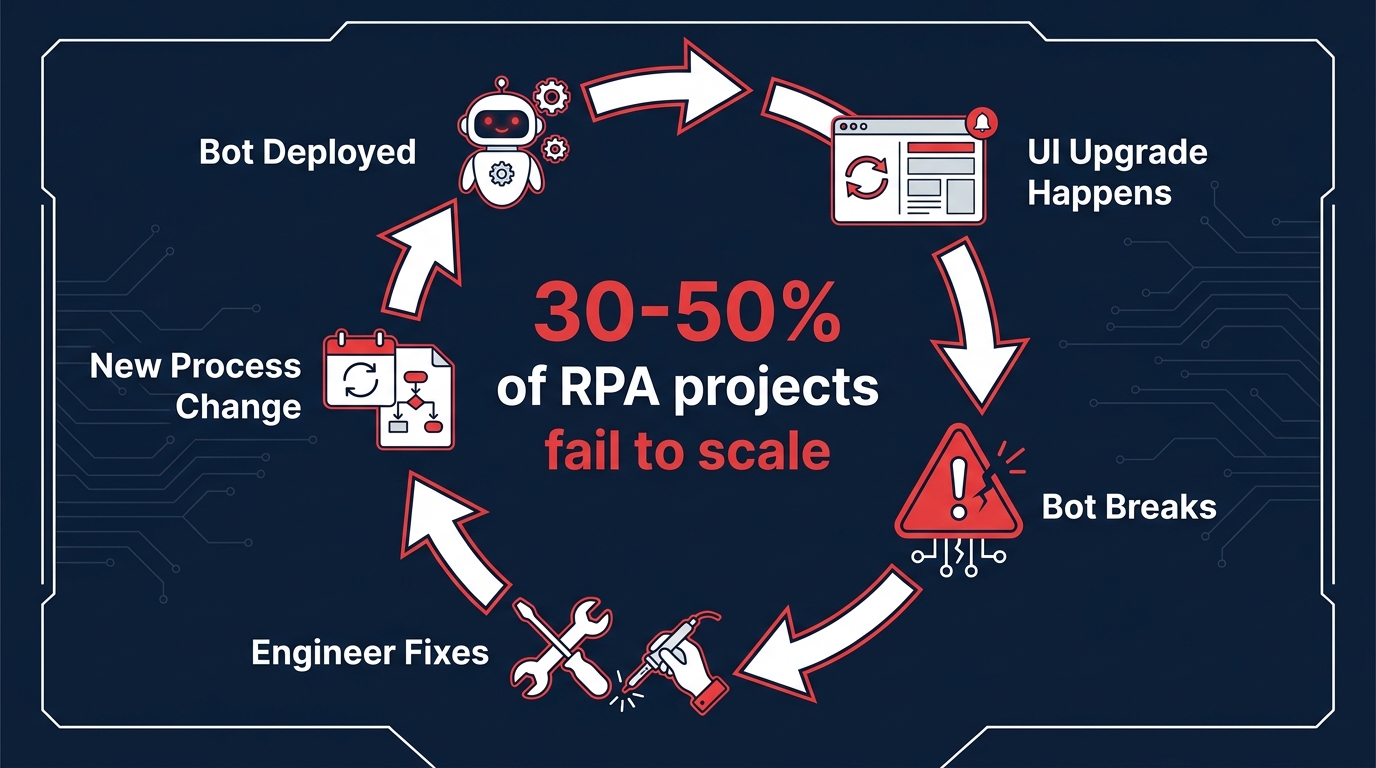
    Circular diagram showing the failure cycle of a static RPA bot: deployed, UI changes, bot breaks, engineer fixes, repeat — with stat showing 30-50% of RPA projects fail to scale

    Robotic Process Automation arrived in enterprise technology circles with a compelling pitch: mimic human keystrokes and mouse movements to automate rule-based tasks, without needing to integrate directly with underlying systems. No API required. No custom development. Just record the steps and let the bot run.

    For a certain category of task, it worked. Copying data between legacy systems that lacked APIs, running end-of-month reconciliations on fixed formats, generating standard reports from predictable data sources — these were genuine wins, and many organizations correctly captured ROI from them.

    But the assumption embedded in the RPA model was quietly catastrophic: that the processes being automated would stay stable. They almost never do.

    The Three Failure Modes That Eat RPA Estates Alive

    UI dependency. Traditional RPA bots operate by interacting with screen elements — buttons, fields, dropdown menus — identified by their position, label, or selector. When the application is updated, rebranded, or restructured, the bot can no longer find what it is looking for. This is not an edge case. It is a near-certainty over any 12-to-18-month horizon, and it means every application upgrade on every system your bots touch generates a wave of break-fix work.

    Exception intolerance. Static bots follow predetermined decision trees. When reality deviates from the expected path — an invoice arrives in a non-standard format, a field is missing, an approval is pending from someone out of office — the bot has no mechanism to adapt. It either fails silently, errors out, or, in the worst case, processes the exception incorrectly. The resulting human exception queues often grow larger than the process the bot was supposed to eliminate.

    Unstructured data blindness. The majority of enterprise information does not arrive in neat, structured formats. Emails, PDFs, scanned documents, free-text fields, voice memos — these are the connective tissue of real business processes. Traditional RPA has almost no ability to interpret unstructured content without pairing it with additional OCR or NLP tools, and even then, the integration is brittle and version-sensitive.

    The Scale of the Problem

    The failure statistics are not soft industry rumors. Research consistently puts the share of RPA projects that fail to scale or are abandoned within approximately two years at 30 to 50 percent. That is a remarkably high failure rate for technology that has been positioned as proven and mature.

    More instructively, organizations that do successfully deploy RPA at scale often find that the ongoing maintenance burden reshapes their ROI calculation in ways the original business case never anticipated. Industry data puts total RPA maintenance and support costs — including engineering labor, monitoring, incident response, and break-fix cycles — at 70 to 75 percent of total program spend. Licensing, the line item that dominates procurement discussions, typically represents only 20 to 25 percent of what enterprises actually pay to keep RPA running.

    The result is a fleet of bots that requires roughly 15 to 25 percent of initial development cost, per bot, per year, just to maintain at current capability — with no improvement in scope, no expansion of coverage, and no ability to handle the exceptions that the bot was never designed to manage.

    “The real problem with our RPA estate wasn’t the bots that failed loudly. It was the ones that were technically running but only handling 55% of the volume they were supposed to, and nobody had noticed.”
    — Enterprise automation lead, financial services sector (2026)

    That silent underperformance is the most insidious aspect of the static bot model. Failures are visible and generate tickets. Quiet coverage erosion — where a bot handles fewer and fewer cases as the process drifts from the original design — accumulates invisibly until someone runs the numbers.

    What Makes Agentic AI Structurally Different
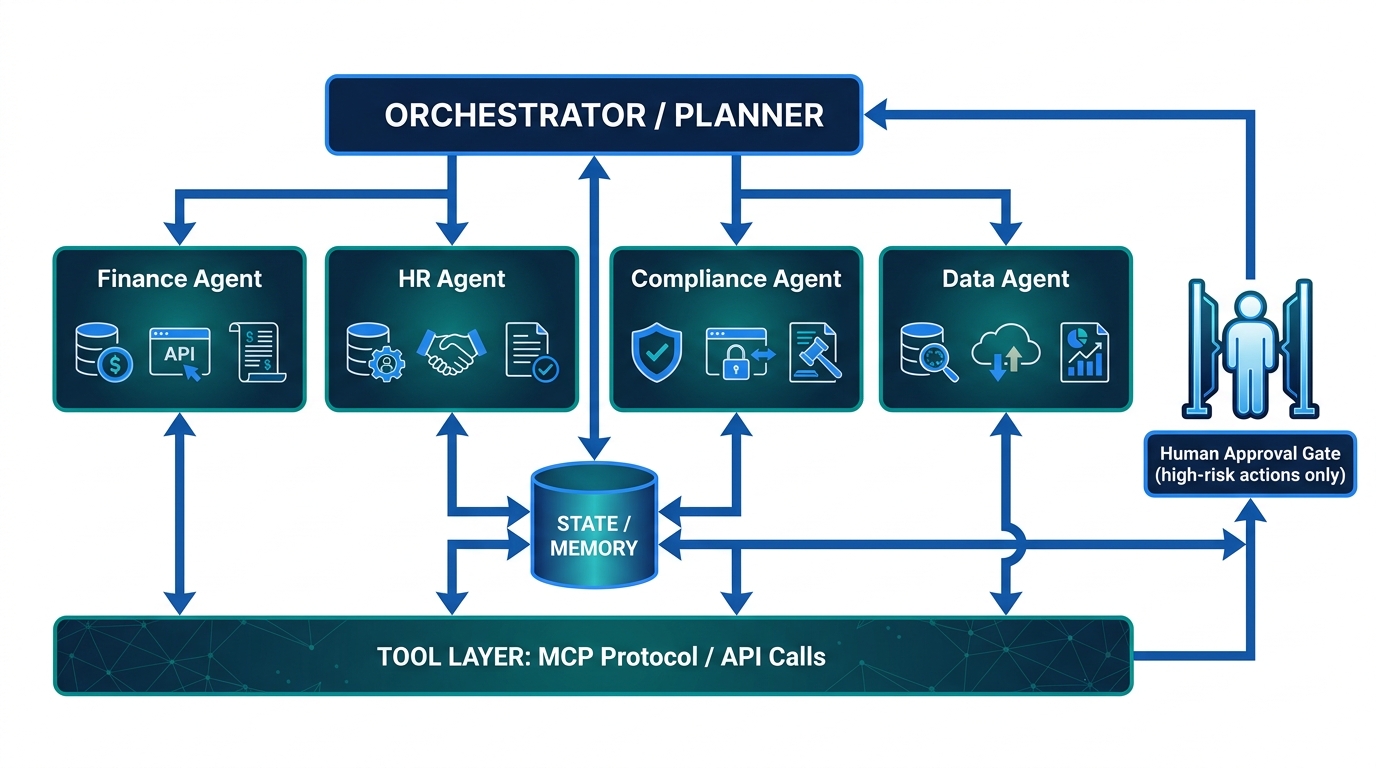
    Architecture diagram of a multi-agent agentic AI system showing an orchestrator directing specialist agents through a tool layer with a human approval gate for high-risk actions

    The term “agentic AI” has accrued enough marketing gloss that it risks meaning nothing. Before examining where it beats static bots, it is worth being precise about what the architecture actually is and why that architecture behaves differently when processes change.

    The Core Architecture: Orchestrator Plus Specialists

    A production agentic AI system in 2026 is not a single model running a single task. It is typically a layered architecture with three functional components working in concert.

    At the top sits an orchestrator or planner — a model or controller that receives a high-level goal, decomposes it into subtasks, determines the sequence and routing of those tasks, and manages shared state across the workflow. The orchestrator does not execute actions directly. It decides what happens next, tracks what has happened, and handles failures by retrying, rerouting, or escalating.

    Below the orchestrator sit specialist agents — purpose-built for specific domains or task types. A finance agent might be configured with access to ERP APIs, trained on invoice formats, and constrained to specific approval thresholds. An HR agent might have access to HRIS systems and knowledge of onboarding checklists. Each specialist operates within a defined scope, receives only the context it needs for its task, and returns a structured result to the orchestrator.

    The third layer is the tool and execution layer — the APIs, databases, and external systems that agents actually interact with. In 2026, the Model Context Protocol (MCP) has emerged as the dominant standard for tool discovery and invocation, allowing agents to dynamically identify and call tools without hard-coded integration logic. This is a meaningful shift from RPA: rather than scripting exact UI interactions, agents query a tool catalog, select the appropriate interface, and make structured API calls that are far more resilient to application-layer changes.

    Why This Architecture Handles Change Differently

    The critical behavioral difference between a static bot and an agentic system is not intelligence per se. It is adaptability at the exception boundary.

    When a static bot encounters a situation outside its decision tree, it stops. When an agentic system encounters an unexpected input — a missing field, a format variation, an ambiguous approval state — it can reason about the situation, consult additional context, attempt alternative paths, or escalate to a human with a structured summary of what it found and what decision is needed. The human approval gate becomes a feature rather than a failure mode.

    This is also why agentic systems handle unstructured data categorically better than their RPA predecessors. A large language model underlying an agent can read a PDF invoice, extract the relevant fields, reconcile them against a purchase order, identify a discrepancy in line item 7, draft a query to the vendor, and route the whole package to an accounts payable manager — without requiring the document to arrive in a specific template or format.

    State and Memory: The Feature Nobody Talks About Enough

    One underappreciated structural advantage of agentic architectures is persistent state management. Static bots are typically stateless — each execution is independent, and context does not carry across sessions. Agentic systems maintain working memory and can track a multi-day workflow across multiple interactions, handoffs, and system calls.

    For enterprise processes that span days or involve multiple approval stages — supplier onboarding, compliance reviews, contract negotiations — this is not a minor improvement. It is the difference between a system that handles a single transaction and one that owns a business process end to end.

    The Maintenance Trap: Why 70–75% of RPA Spend Is Just Keeping Bots Alive
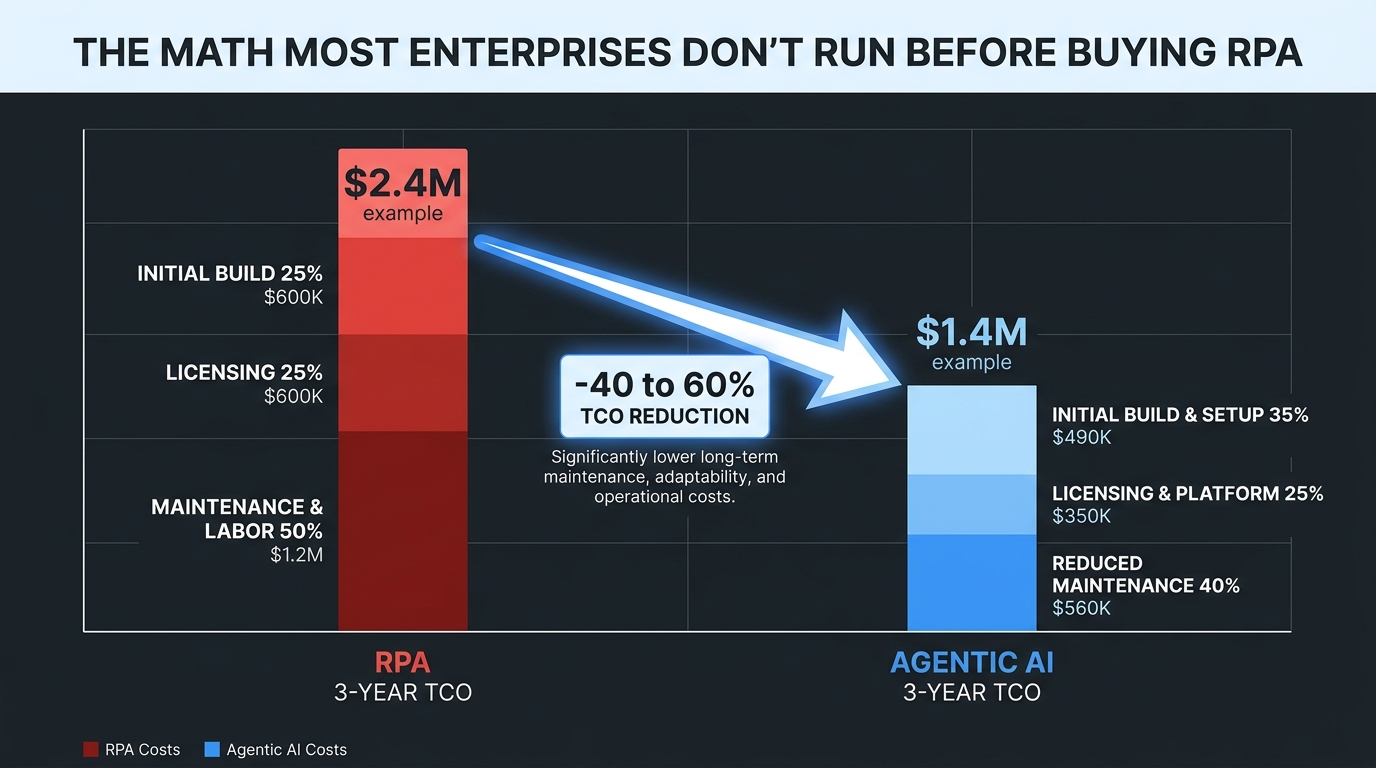
    Bar chart comparing 3-year total cost of ownership for RPA versus agentic AI, showing 40-60% TCO reduction potential from lower maintenance costs

    If there is a single data point that should reset how enterprises think about automation economics, it is this: in most mature RPA programs, the majority of total spend goes not toward creating new capability, but toward maintaining existing capability at its current level.

    This is an extraordinary misallocation of engineering talent, and it compounds over time in ways that are structurally difficult to escape.

    How the Maintenance Spiral Works

    The dynamic plays out in a predictable pattern. An enterprise builds a bot fleet of, say, 80 automations over two years. Each bot is tested against the current state of the application it interacts with. Initial performance is strong. The business case closes. The automation team receives approval for further expansion.

    Twelve months later, application upgrades, process changes, and organizational restructuring have introduced break points across a significant share of the bot estate. Developers who should be building new automations are instead triaging failures. The bot estate has become its own maintenance backlog, competing for the same engineering resources as the expansion pipeline.

    By year three, many organizations find that their automation team is effectively a bot maintenance operation with a small new-build function on the side. The original value proposition — continuous delivery of new efficiency — has stalled. The estate is stable enough to justify its existence on cost-per-transaction metrics, but it is not growing, and its ability to handle modern process complexity is visibly limited.

    Running the Real Numbers

    The standard benchmark for annual RPA maintenance is 15 to 25 percent of initial development cost, per bot, per year. For a bot that cost $40,000 to build, that represents $6,000 to $10,000 in annual upkeep. Across an estate of 80 bots with an average build cost of $35,000, the annual maintenance bill runs to roughly $420,000 to $700,000 — before accounting for the opportunity cost of the developer hours consumed.

    Add licensing (typically 20 to 25 percent of total spend), infrastructure, and the labor associated with monitoring and incident response, and the total cost of ownership for a mature RPA estate regularly exceeds twice the initial capital investment over a three-year period — often without any net expansion of automation coverage.

    The three-year TCO comparison with agentic AI is not simple, and any vendor claiming a clean apples-to-apples figure should be viewed skeptically. But the structural case is credible: agentic systems that interact with systems via APIs rather than UI scripts are substantially less sensitive to application-layer changes, meaning the maintenance burden for stable, well-governed agent workflows is materially lower than equivalent RPA automations in dynamic environments. Enterprises that have made selective migrations report total cost reductions in the 40 to 60 percent range over three years for the specific workflows transitioned.

    The Hidden Cost: Developer Talent Drain

    There is a softer but real cost that the spreadsheet rarely captures: what experienced automation engineers actually want to work on. In a tight market for technical talent, assigning developers to an endless cycle of bot patching is an attrition risk. The organizations that are successfully scaling agentic AI are, without exception, organizations where automation engineers have been retasked from maintenance to architecture — and that shift in work quality is having a measurable effect on retention.

    Where Agentic AI Actually Wins Today: Use Cases With Real Production Data

    The temptation when discussing agentic AI is to list every possible application domain and gesture toward future potential. The more useful exercise in 2026 is to identify specifically where agents are in production, performing reliably, and delivering measurable results — rather than where they might eventually work.

    Three enterprise functions have emerged as the clearest early wins: finance operations, HR administration, and customer-facing service workflows.

    Finance Operations: Invoice-to-Pay and Exception Handling

    Accounts payable is one of the most thoroughly documented agentic AI success stories in enterprise operations, and for good reason: it is a workflow that combines structured requirements (match invoice to PO, validate line items, post to ERP) with a high volume of real-world variation (different invoice formats, missing fields, quantity discrepancies, vendor query handling).

    A static bot can handle the straight-through cases reliably. But in most AP operations, the straight-through rate for complex invoices sits below 70 percent, meaning more than 30 percent of invoices require some form of human intervention. The traditional bot either fails on these or routes them immediately to a human queue — defeating much of the automation value.

    An agentic AP system changes the equation substantially. The agent reads invoices in any format via document understanding models, matches them against PO records, flags specific discrepancies with structured reasoning (not just “error — unmatched field” but “line item 3 shows $4,200 against PO value of $3,800 — likely partial delivery, querying vendor”), routes exception-ready summaries to approvers, and updates ERP records once approved. Enterprises deploying agentic AP report straight-through rates climbing to 85 to 90 percent for previously exception-heavy invoice streams.

    HR Administration: Onboarding and Service Desk

    Employee onboarding is a process that looks deceptively simple from a workflow chart but consistently breaks static automation in practice. New hires join with varied backgrounds, role variations trigger different system access requirements, start dates shift, and onboarding steps that appear sequential often have implicit dependencies on actions from multiple parties.

    HR agents in 2026 handle the full onboarding sequence — provisioning accounts across IT systems, coordinating training assignments, managing document collection, triggering payroll setup, and routing background check steps — while tracking completion status and managing exceptions when steps are delayed or incomplete. The agent does not just execute tasks; it manages the state of the process, proactively identifying blockers and escalating them before they delay the new hire’s start date.

    For the HR service desk specifically, agentic AI has reduced average ticket resolution time by 40 to 60 percent in documented enterprise deployments, largely by resolving the long tail of questions that are too contextual for a static FAQ bot but too routine to warrant full human handling — policy queries with specific personal circumstances, benefit calculation questions that require pulling data from multiple systems, and leave request scenarios that involve overlapping approvals.

    Customer-Facing Operations: The Klarna Data Point

    Klarna’s much-cited deployment of an AI-powered customer service agent provides the clearest large-scale evidence of what happens when agentic AI replaces a combination of static chatbots and human agents. The system handled 2.3 million customer conversations in its first operational month — roughly two-thirds of all support volume — with average resolution time dropping from 11 minutes to under 2 minutes, and repeat inquiry rates falling 25 percent.

    The more instructive detail from Klarna’s experience is what happened next. After achieving those headline results, the company moved toward a hybrid human-AI model after identifying that the fully automated system underperformed on complex, emotionally charged cases — disputes, fraud claims, and situations requiring nuanced judgment about customer circumstances. The lesson is not that agentic AI failed. It is that the optimal architecture is not zero humans. It is the right humans, handling the right cases, with AI handling everything else.

    That is a fundamentally different labor model than either “humans do everything” or “bots do everything” — and it is the model that is actually working at scale in 2026.

    The Transition Playbook: Augment First, Then Replace
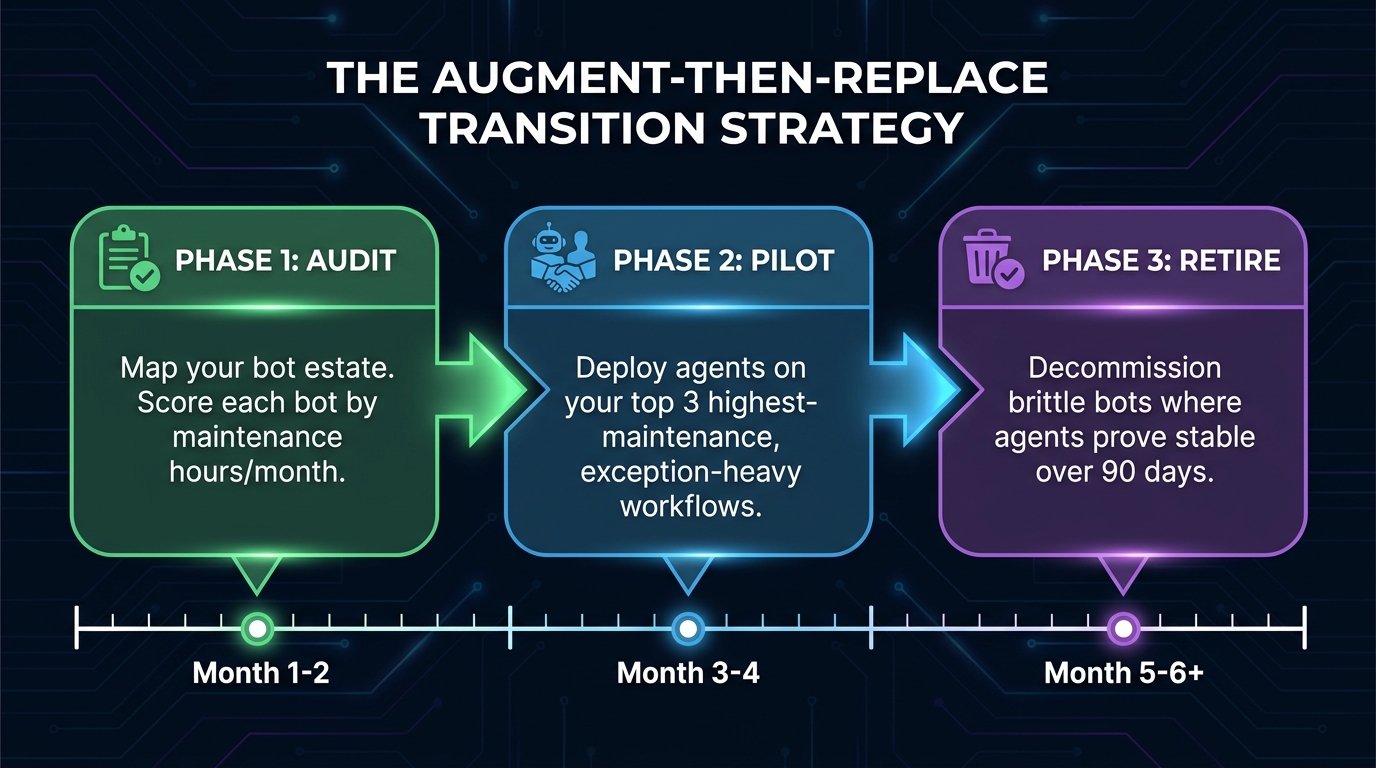
    Three-phase transition roadmap from static RPA bots to agentic AI: Audit your bot estate, Pilot on high-maintenance workflows, Retire brittle bots once agents prove stable

    The dominant enterprise pattern in 2026 is not ripping out RPA and replacing it wholesale with agents. Organizations that attempted aggressive rip-and-replace strategies in 2024 and 2025 largely found that the disruption cost exceeded the efficiency gain, at least in the short term. The strategy that is actually working is more deliberate: augment existing automation where agents can add immediate value, then selectively retire the bots that agents demonstrably outperform.

    Phase 1: Audit and Score Your Bot Estate

    The transition starts not with technology selection but with honest accounting of the existing automation portfolio. Every bot in the estate should be scored against two dimensions: maintenance cost (engineer hours per month, incident frequency, average time to restore after failures) and exception rate (the percentage of cases the bot cannot handle and routes to humans).

    This scoring exercise typically reveals a clear distribution. A minority of bots — often 20 to 30 percent of the estate — account for the majority of maintenance effort and exception volume. These are the bots that are the highest-fit candidates for agentic replacement: they are expensive to maintain, they handle a shrinking share of their intended volume, and they sit on processes that require the kind of contextual reasoning that agents handle well.

    A second tier — often the largest category — consists of bots that are stable, low-maintenance, and handling structured, predictable processes. These are the bots that RPA was designed for. There is no economic case for replacing them with agents unless the underlying process is scheduled to change. Leave them alone.

    A third tier consists of bots that are marginal performers — low volume, unclear ownership, uncertain ROI. These warrant decommissioning regardless of what replaces them, because they are consuming infrastructure and monitoring resources without meaningful output.

    Phase 2: Pilot on Your Highest-Pain Workflows

    With the audit complete, the transition team can identify the two or three workflows that represent the best case for an agent pilot. The selection criteria should be explicit: high exception rate, high monthly maintenance hours, business-critical enough to have executive attention, but not so operationally central that a failed pilot causes significant disruption.

    The pilot should be structured as a parallel run. The existing bot continues to handle the workflow while the agent runs alongside, processing the same volume independently. At the end of 60 to 90 days, the comparison is straightforward: straight-through rate, exception handling accuracy, cycle time, and total engineer hours consumed by each system.

    Parallel running is critical for two reasons. First, it generates clean side-by-side evidence for the business case, which matters when requesting budget for expansion. Second, it allows the team to discover the governance and guardrail requirements specific to that workflow before the agent is operating without a safety net.

    Phase 3: Retire Brittle Bots Where Agents Prove Stable

    Once an agent has run in parallel for 90 days with consistently better metrics, the decommissioning decision becomes a data-driven one rather than a technology opinion. The bot is retired, the agent takes full ownership of the workflow, and the maintenance budget previously allocated to that bot is freed up for the next phase of expansion.

    This cycle — audit, pilot, retire, expand — typically delivers measurable ROI from the first workflow transition within six to nine months, generating both financial returns and organizational confidence for subsequent phases. The enterprises that are now scaling agents enterprise-wide started with exactly this methodical approach. They did not begin by declaring RPA dead. They began by finding the bots that were already dying and replacing them with something better.

    The Governance Gap: Why Autonomy Without Guardrails Is a Risk Category of Its Own
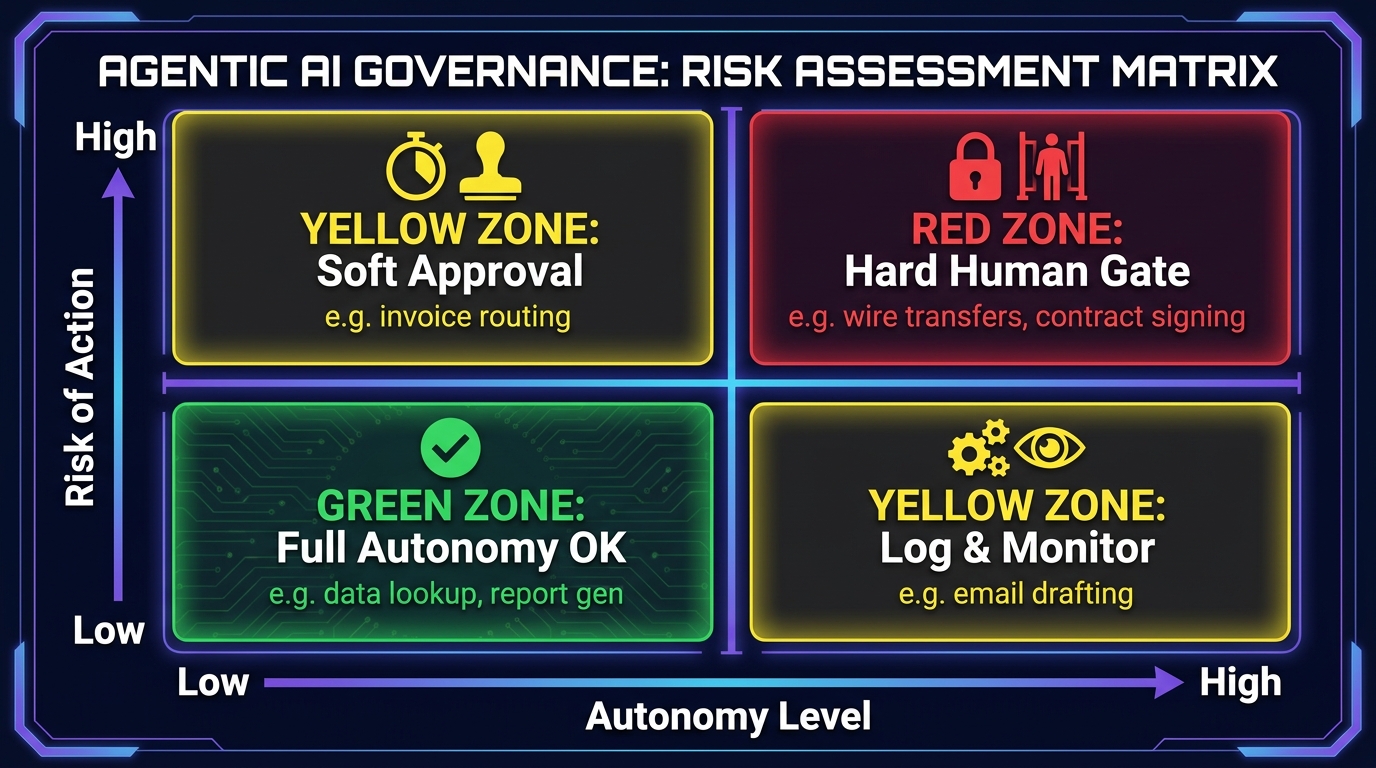
    Risk assessment matrix for agentic AI governance showing four quadrants from full autonomy permitted to mandatory human approval gate based on autonomy level and action risk

    Static bots fail loudly and predictably. They error out on recognizable failure modes. Agentic AI introduces a different risk profile: the risk of confident, well-reasoned wrong actions — decisions that look correct at each individual step but compound into significant errors at the workflow level.

    This is not a hypothetical. Organizations that deployed agents without adequate guardrails in 2024 and 2025 reported incidents where agents completed multi-step actions — routing payments, modifying records, triggering external communications — based on ambiguous inputs that a human would have flagged for clarification. The agents were not malfunctioning. They were behaving exactly as designed: completing the task as efficiently as possible. The problem was that “completing the task” in ambiguous situations required judgment calls that the governance framework had not anticipated.

    The Risk-Tiered Approval Framework

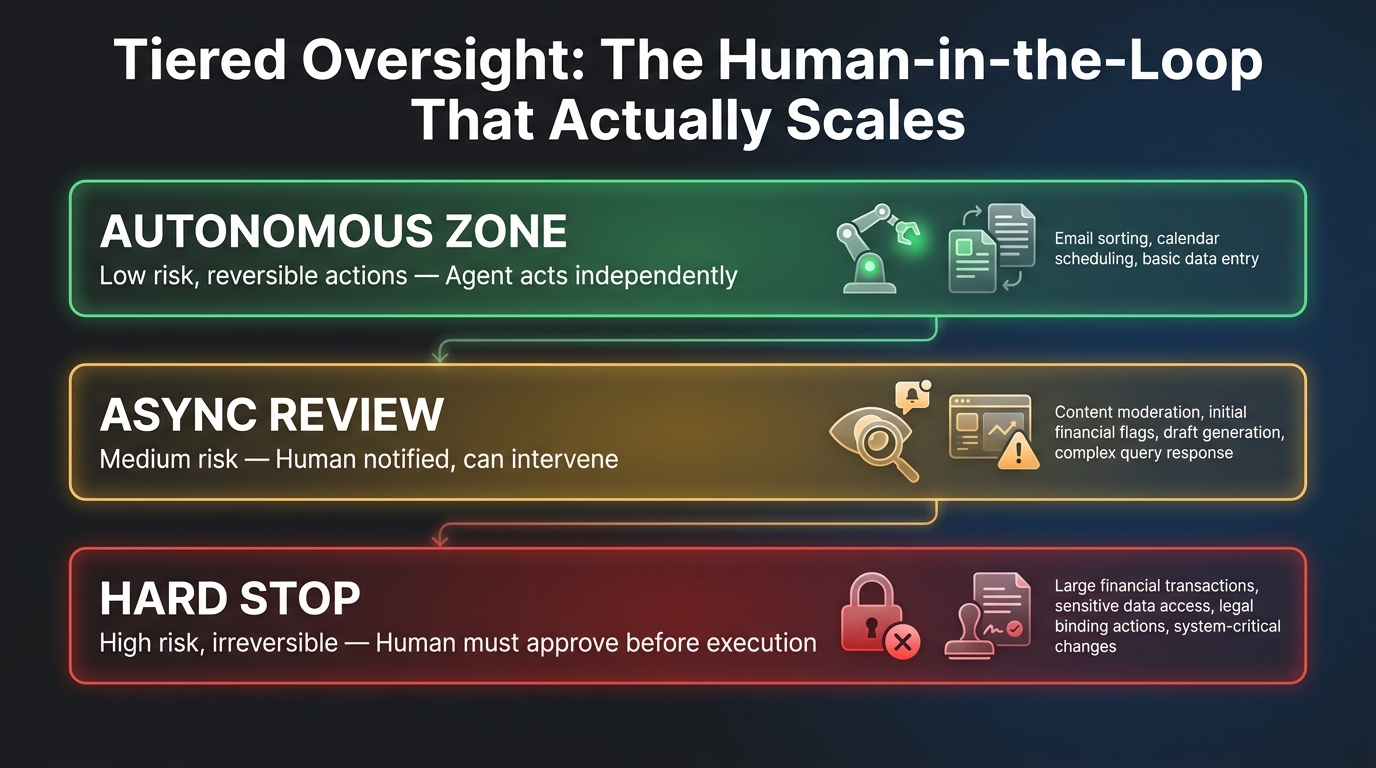
    The governance pattern that is emerging as best practice in 2026 is not “human in the loop for everything” — that destroys the efficiency case — nor is it “full autonomy for everything.” It is a risk-tiered framework that calibrates human involvement to the reversibility and consequence of the action being taken.

    Low-risk, reversible actions — data lookups, report generation, drafting communications for human review, reading and summarizing documents — can operate with full autonomy. The consequence of an error is limited and easily corrected.

    Medium-risk actions — sending external communications, routing items for approval, updating internal records — operate with logging and monitoring. No human approval is required before execution, but every action is recorded in an immutable audit trail, and anomaly detection flags patterns that deviate from expected behavior.

    High-risk, potentially irreversible actions — wire transfers, contract execution, payroll modifications, external commitments above defined thresholds — require an explicit human approval gate before execution. The agent prepares the action completely and presents it for sign-off. It does not proceed until approval is recorded.

    This tiered model allows agents to operate at speed on the 80 to 90 percent of workflow steps that are low-risk, while maintaining appropriate control over the minority of actions that require human judgment.

    Identity, Least Privilege, and Auditability

    Beyond approval gates, effective agentic governance requires treating agents as distinct identities within the enterprise security perimeter. Each agent should have its own credential set with narrowly defined permissions — access only to the systems and data required for its specific task scope. This “least privilege by default” approach limits the blast radius of any individual agent failure or security incident.

    Equally important is auditability. Every agent action — every tool call, every decision branch, every data access — should be logged in a form that supports incident investigation and regulatory review. In regulated industries (financial services, healthcare, insurance), auditability is not a best practice. It is a prerequisite for deployment.

    Organizations that have governance infrastructure in place before deploying agents at scale report significantly fewer incidents and faster recovery times when issues do occur. Organizations that deploy agents quickly and retrofit governance afterward tend to face a much harder remediation process — particularly if an agent has taken consequential actions that are difficult to reverse.

    Reading the 2026 Vendor Landscape: Who Is Building What

    The vendor landscape for enterprise automation in 2026 reflects the hybrid reality of the market. Traditional RPA vendors — UiPath, Automation Anywhere, Blue Prism — have all repositioned their products to incorporate agentic capabilities, framing their platforms as the orchestration layer that connects existing bot estates with new AI-native workflows. The pitch is continuity: extend your existing investment rather than replace it.

    AI-native platforms — including frameworks like LangGraph, CrewAI, Microsoft AutoGen (now AG2), and Google’s ADK — approach the space from the opposite direction: building orchestration-first architectures with AI reasoning at the core and plugging into execution systems via API. These platforms require more architectural work to implement but offer substantially more flexibility for complex, multi-system workflows.

    The Cloud Hyperscaler Play

    AWS, Microsoft Azure, and Google Cloud have all entered the agentic orchestration market with managed services — AWS Bedrock AgentCore, Azure AI Foundry, and Google Vertex AI Agent Builder, respectively. These managed runtimes lower the operational burden of running multi-agent architectures at scale, handling state persistence, retry logic, monitoring, and scaling infrastructure.

    For enterprises already committed to a primary cloud provider, the managed agent runtime from that provider will often be the path of least resistance — particularly for teams that do not have deep MLOps capability in-house. The trade-off is vendor lock-in at the orchestration layer, which can limit flexibility as the market continues to evolve rapidly.

    The MCP Standardization Shift

    One development that deserves more enterprise attention than it currently receives is the emergence of the Model Context Protocol as a de facto standard for agent-to-tool communication. MCP allows agents to discover and invoke tools through a standardized interface, meaning a well-designed agentic system can add new tool integrations without rebuilding the agent logic.

    For procurement and architecture teams, this matters because it reduces the switching costs associated with agentic infrastructure. An agent built on MCP-compliant tooling is substantially more portable across platforms than one built on vendor-specific integration layers — a lesson that RPA buyers learned the hard way when they found their bot estates locked to specific vendors.

    Point Solutions vs. Platform Bets

    A growing category of vertical-specific agentic AI vendors — targeting specific functions like AP automation, legal document review, IT service management, or compliance monitoring — offers a middle path between DIY agent frameworks and broad platform commitments. These point solutions deliver faster time-to-value for specific workflows but require careful integration planning when the goal is enterprise-wide orchestration.

    The selection principle that is proving durable in 2026: evaluate vendors on the quality of their audit trails and governance tooling first, their agent reasoning quality second, and their roadmap claims last. The organizations that are struggling with agentic deployments are almost universally struggling with observability and control, not with the intelligence of the underlying models.

    The 3-Year TCO Calculation Nobody Does Before Buying RPA

    The economics of automation technology selection deserve more rigorous treatment than most procurement processes provide. The standard approach is to compare licensing costs and implementation fees — the visible, contractual numbers — and largely ignore the ongoing operational cost profile. This is the calculation error that has trapped many enterprises in expensive, underperforming RPA estates.

    Building a Realistic Total Cost of Ownership Model

    A defensible 3-year TCO model for any automation investment — RPA or agentic — should include the following cost categories:

    • Initial implementation cost: vendor fees, internal developer time, integration work, testing, documentation. For RPA, this typically runs $25,000 to $80,000 per bot depending on complexity. For agentic workflows, the range is wider and depends heavily on the integration surface and the maturity of the tool layer.
    • Annual licensing: typically 20 to 25 percent of RPA spend. Agent platform costs vary significantly; managed cloud runtimes often price on consumption rather than fixed licenses, which can work favorably or unfavorably depending on volume patterns.
    • Annual maintenance labor: the line item that most TCO models underestimate. For RPA, budget 15 to 25 percent of initial development cost per bot per year for maintenance alone, excluding new development. For agentic systems, this number is lower for workflows where the API layer is stable, but should not be assumed to be zero — model updates, prompt drift, and tool API changes all require ongoing attention.
    • Exception handling labor: the human cost of managing the cases the automation cannot handle. This should be measured at current state for the process being automated, then modeled against the expected exception rate of the proposed automation technology.
    • Governance and compliance overhead: audit trail management, policy reviews, incident response. Often omitted from initial TCO models. For agentic systems in regulated industries, this can be a significant line item.

    What the Model Reveals

    When enterprises run this model honestly — before selecting a technology, not after — the result often significantly shifts the relative attractiveness of agentic AI for exception-heavy workflows. The higher upfront implementation cost of an agentic system is frequently offset within 18 to 24 months by lower maintenance labor costs and higher straight-through processing rates, which reduce the ongoing human exception handling cost.

    For simple, stable, structured processes, RPA still wins on this model. The implementation is faster, the predictability is higher, and the governance requirements are lower. This is why the recommendation from practitioners who have worked through these calculations is consistently hybrid: keep RPA where it works, replace it where it doesn’t.

    The organizations that regret their RPA investments are not organizations that deployed RPA on the wrong technology. They are organizations that deployed RPA on the wrong processes — specifically, processes that were complex enough to generate persistent exceptions but not complex enough to justify the upfront investment in a more capable system. They chose the path of least resistance at implementation time and discovered the true cost at maintenance time.

    What the 23% Scaling Agents Are Doing Differently

    Enterprise data from 2026 shows a clear adoption split: approximately 72 percent of enterprises have AI agents in production or pilot in some form, but only around 23 percent have scaled an agentic system enterprise-wide. The gap between “we have a pilot” and “we have a scaled program” is where most organizations are currently stuck — and the practices of the organizations that have crossed that gap are instructive.

    They Started With Operations, Not Innovation

    Organizations that are successfully scaling agents almost universally started in back-office operations rather than in customer-facing or revenue-generating contexts. Finance, HR, IT service management, and compliance were the entry points, not sales, marketing, or product development. The reason is straightforward: operational workflows have clearer definitions of success, more predictable volumes, better-documented exception handling requirements, and lower brand risk if something goes wrong.

    This sequencing also generates the financial results that fund expansion. A successful AP automation agent that demonstrably reduces processing costs and exception volume creates an internal ROI narrative that procurement and finance leadership can audit. That narrative unlocks budget for the next deployment. Organizations that started with ambitious customer-facing or analytical use cases often found the value harder to measure and the organizational support harder to sustain.

    They Invested in Observability Before They Invested in Capability

    The 23% that are scaling treat observability — the ability to see what every agent is doing, why, and with what result — as infrastructure, not an afterthought. Before a new agent workflow goes live, they have dashboards showing throughput, exception rates, decision rationale, and anomaly alerts. Before they scale an agent to a new business unit, they verify that the audit trail for that agent meets the regulatory and operational requirements of that unit.

    This approach slows initial deployment timelines but dramatically reduces incident rates and remediation costs. It also builds organizational trust at a pace that supports continued expansion, rather than triggering the risk committee review that tends to freeze programs after a highly visible failure.

    They Treat the Agent Portfolio Like an Engineering Product, Not an IT Project

    The most consistent organizational difference between enterprises that scale agents and those that plateau at pilot is whether the agent program is run like an engineering product — with dedicated ownership, a roadmap, a feedback loop, and ongoing iteration — or like an IT project that gets handed off after implementation.

    Agents are not static. The processes they operate in change. The tools they access change. The models they run on are updated. Organizations that assign permanent product ownership to their agent portfolio — with engineers responsible for monitoring performance and iterating on prompt logic, tool configuration, and exception handling — sustain performance over time. Organizations that treat agent deployment as a one-time implementation event find their systems degrading in ways that mirror the RPA maintenance trap they were trying to escape.

    They Measured Process Coverage, Not Just Task Accuracy

    A subtle but important measurement distinction separates organizations that scale agents effectively from those that plateau. The less effective organizations measure agent performance on task accuracy — does the agent complete the task correctly when it accepts it? The more effective organizations measure process coverage — what percentage of the total incoming volume does the agent handle end-to-end, including the cases it routes out?

    A 98 percent task accuracy rate sounds excellent. But if the agent only accepts 60 percent of incoming cases and routes the other 40 percent to humans, the net automation rate is 59 percent — which may not be materially better than the bot it replaced. Organizations that optimize for process coverage rather than task accuracy consistently achieve higher net efficiency gains and more defensible business cases for expansion.

    From Automation to Orchestration: The Shift That Changes Everything

    There is a conceptual frame shift embedded in the transition from static bots to agentic AI that deserves explicit attention, because it changes not just the technology but the way organizations should think about what automation can do.

    Static bots automate tasks. Agentic AI orchestrates processes. These are not the same thing, and the distinction matters for how organizations scope, fund, and measure their automation investments.

    A task is a discrete, bounded action: extract these fields, compare these values, update this record. A process is a sequence of decisions, actions, and handoffs that collectively achieve a business outcome: a new employee is hired and fully onboarded, a supplier invoice is validated and paid, a customer complaint is resolved and documented.

    RPA programs have always been implicitly measured at the task level, because that is the unit of work a static bot can reliably own. The resulting metrics — tasks automated, FTE equivalents saved, process steps touched — are real but limited. They capture what happened within the automation boundary, not what happened to the process overall.

    Agentic systems, because they can own multi-step processes with decision logic and exception handling, invite measurement at the process level: end-to-end cycle time, straight-through rate for the full process, cost per completed outcome, and compliance accuracy across the entire workflow. These are metrics that business leaders understand and care about in a way that “number of tasks automated” never quite achieved.

    This reframing is why the transition from static bots to agentic AI is less of an upgrade and more of a repositioning of what automation is for. The goal shifts from “automating steps that humans used to do” to “owning processes that humans used to manage.” The scope is larger, the governance requirements are higher, and the business impact is proportionally greater when done well.

    Conclusion: The Decision Framework for 2026

    The question facing automation leaders in 2026 is not whether agentic AI is better than static bots in the abstract. In exception-heavy, unstructured, multi-step workflows, it demonstrably is. The practical question is which workflows to transition, in what sequence, with what investment, and with what governance infrastructure in place.

    The framework that the data supports is not complicated, but it requires honesty about the current state of the bot estate and discipline about the order of operations:

    1. Audit first. Score every bot in the estate by maintenance burden and exception rate. This is not a lengthy exercise — most automation teams can complete it in two to three weeks — but it is essential for making transition decisions based on evidence rather than vendor enthusiasm.
    2. Target the high-maintenance, high-exception bots first. These are the cases where the economic case for transition is clearest and where the improvement in performance will be most visible. Do not start with the easy bots that are already working well.
    3. Build governance before scale. Audit trails, approval gates, and monitoring dashboards are not optional extras. They are the infrastructure that allows agentic systems to operate in enterprise environments without generating the kind of incidents that freeze programs. Build them into the first pilot, not as a retrofit after scale.
    4. Measure process coverage, not just task accuracy. The metric that matters is what percentage of total incoming volume the agent handles end-to-end. A highly accurate agent that handles a small fraction of volume is not a successful automation.
    5. Treat the portfolio as a product. Assign permanent ownership. Build an iteration cadence. Expect agent workflows to require ongoing attention as processes, models, and tools evolve.

    The enterprises that invested in RPA as a durable solution discovered that durable automation requires a different architecture than scripts running against static UIs. The enterprises investing in agentic AI today are, in the best cases, building with that lesson in mind — governing carefully, measuring honestly, and transitioning methodically from the systems that are already failing toward ones that are structurally better suited to the complexity of real enterprise processes.

    The bots are not dead yet. But the ones in your estate that are expensive to maintain, slow to recover, and handling a shrinking fraction of their intended volume? Those are already dying. The decision is simply whether to replace them intentionally, on your terms, or to wait until the maintenance burden makes the decision for you.
  • What Actually Breaks When You Scale a Voice Agent Past the Pilot Stage

    What Actually Breaks When You Scale a Voice Agent Past the Pilot Stage

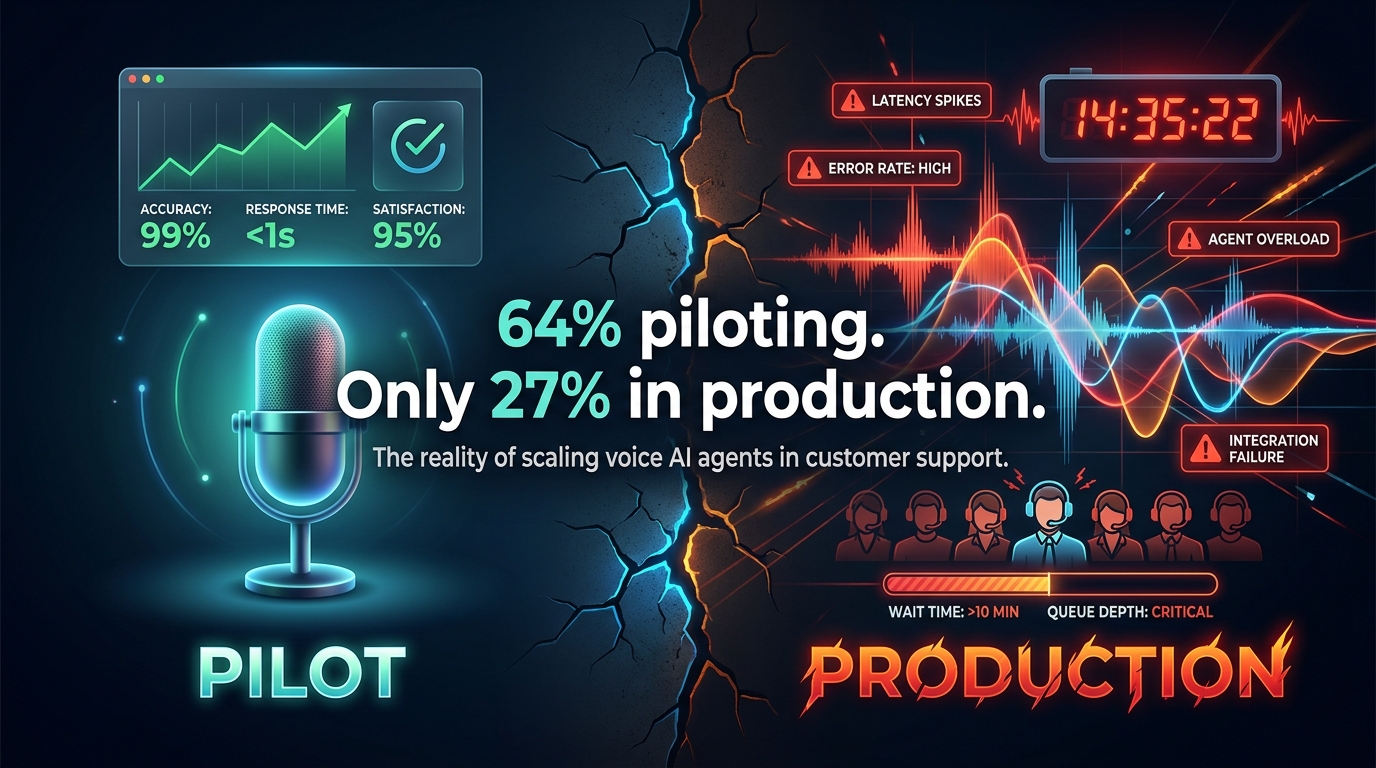
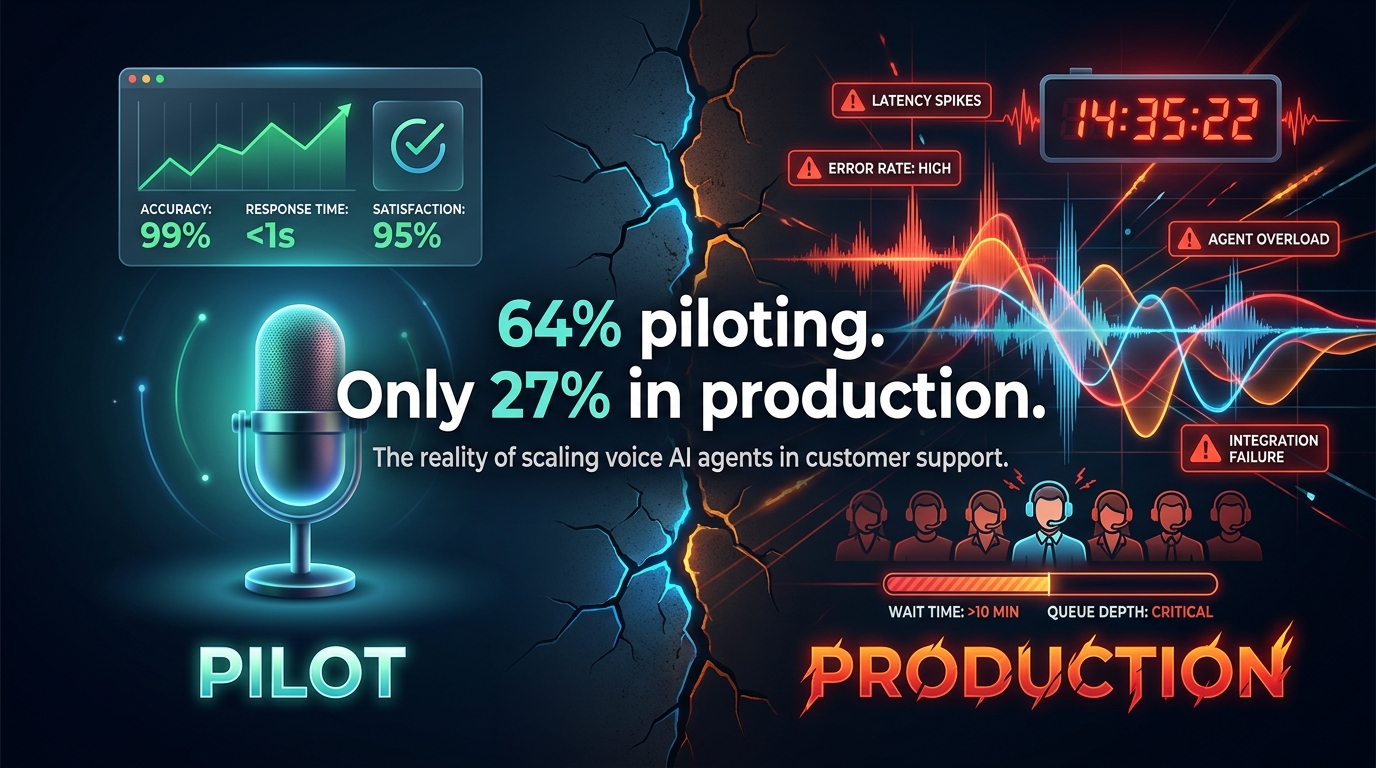
    Voice AI agent pilot vs production gap — 64% piloting, only 27% in full production

    There is a number that should make every CX leader pause before celebrating a successful voice agent pilot: 64% of enterprise customer experience teams ran an agentic AI or voice agent pilot in 2026. Only 27% have at least one channel in full production.

    That gap is not a technology gap. The tools work. The vendors have improved dramatically. Latency has come down, LLM accuracy has gone up, and the economics of per-interaction cost are genuinely compelling. The gap is an execution gap — a systematic series of things that break or get underestimated the moment you move from a controlled demo environment into the messy, high-variance reality of a live production call queue.

    About 18% of programs that started pilots in 2025 are still stuck there after twelve months. They are not failing; they are not succeeding. They are in a holding pattern, perpetually finding new reasons the timing is not right for a broader rollout.

    This article is for the teams that do not want to end up there. It examines what actually breaks at scale — the architectural assumptions, the measurement frameworks, the workforce dynamics, and the compliance realities that pilots conveniently sidestep — and what the teams that do reach full production do differently.

    This is not a technology overview. It is a post-pilot survival guide.

    The Pilot Illusion: Why Demo Numbers Don’t Survive First Contact with Real Calls

    Pilot conditions are, by design, favorable. Teams typically select a narrow call type with high-volume, low-variance intent — something like “check my balance” or “what is the status of my order.” They curate the test dataset, brief the evaluators, and measure against metrics that the system has essentially been tuned to pass.

    None of those conditions survive real production deployment.

    The variance problem

    Real callers do not read the system prompt. They call with compound problems, mid-sentence topic switches, strong accents, background noise, and emotional states the system was never trained to handle. Where a pilot might process 500 carefully selected interactions, a production system handles thousands per day, and the long tail of unusual cases is far longer than any pilot team anticipated.

    In production, LLM hallucination rates can increase three to five times compared with controlled demos as call content deviates from the training distribution. That is not a model problem — it is a scope problem. Pilots succeed precisely because they exclude the variance that production cannot.

    The latency gap

    Humans tolerate conversational silence differently on the phone than in any other medium. Research consistently shows that users find delays above approximately 1,000 milliseconds noticeably robotic and uncomfortable. Delays above 1.5 seconds begin to feel like the system has crashed.

    In a pilot, the team might accept 1.2 seconds of mouth-to-ear latency because it “mostly works.” In production at scale, with concurrent sessions competing for GPU resources, network variability, and edge cases that require longer LLM reasoning chains, that 1.2-second average can degrade to 2.0 seconds under peak load. The customer experience deteriorates precisely when call volume is highest — the worst possible time.

    The integration gap

    Pilots often connect to a staging version of the CRM, a sandbox API, and a simplified knowledge base. Production connects to the real systems, which have undocumented edge cases, rate limits, authentication timeouts, and data quality issues that nobody documented because human agents worked around them intuitively.

    When the voice agent hits a CRM record with unexpected null fields, it either fails silently, invents data, or crashes the interaction. Human agents know to ask a clarifying question and keep moving. The system does not — unless someone built that recovery logic, which pilot teams rarely have time to do.

    What this means for your team

    A successful pilot is a necessary condition for production deployment, but it is not a sufficient one. Before declaring a pilot a success, the team should deliberately stress-test against production-variance conditions: unscripted callers, real system integrations, peak concurrent load, and the specific failure modes the agent will encounter at 2 AM on a Sunday when nobody is watching. If it cannot handle those conditions in staging, it is not ready for the rollout conversation.

    The Architecture That Has to Work at Scale

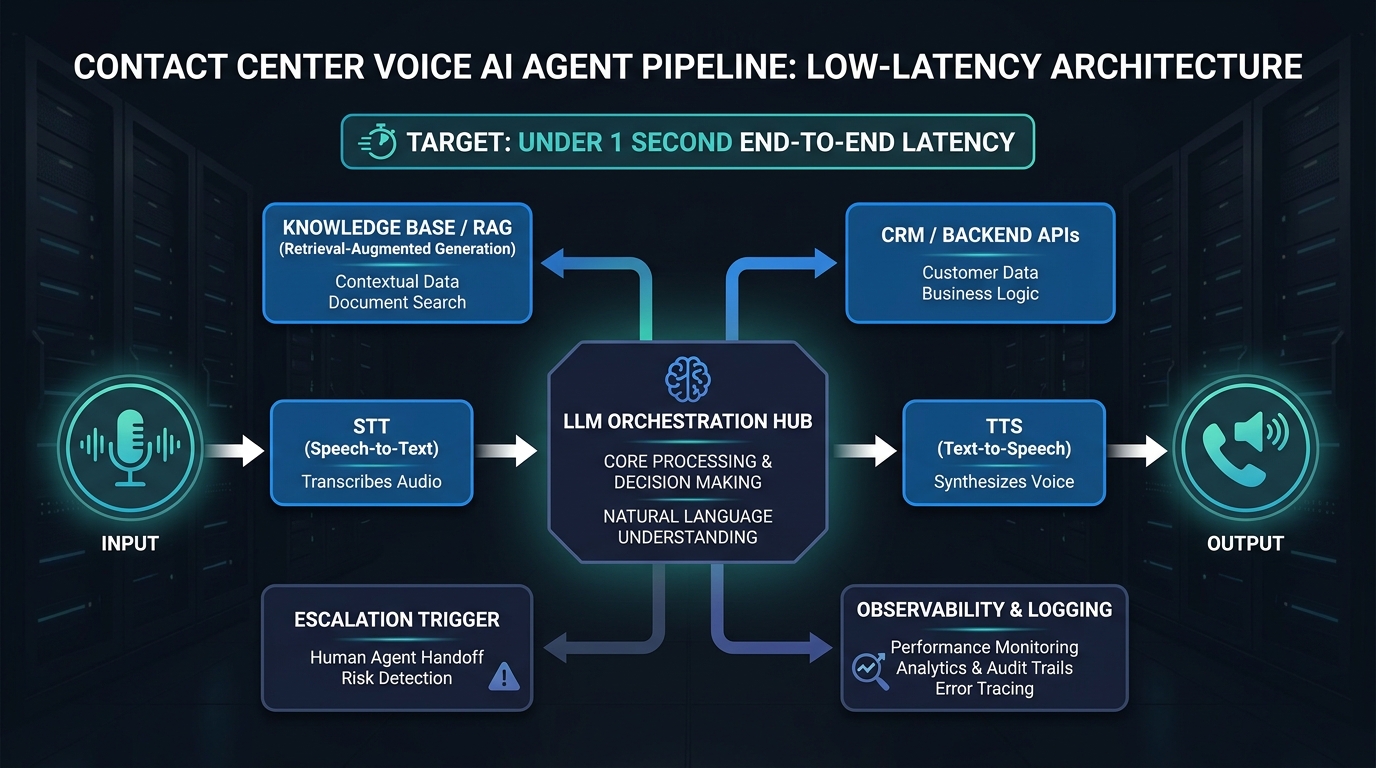
    Voice AI agent production pipeline: STT to LLM orchestration to TTS with CRM and escalation integrations

    Production voice agents in 2026 converge on a specific architectural pattern. Understanding it is important because the failure modes are not random — they are predictable, and they cluster around specific points in the pipeline.

    The cascaded STT → LLM → TTS pipeline

    The dominant architecture flows like this: a Speech-to-Text (STT) engine converts the caller’s audio to text in real time, often using streaming transcription to reduce perceived latency. That transcription passes to a large language model, which reasons about the intent, queries relevant tools or knowledge stores, and generates a response. A Text-to-Speech (TTS) engine converts that response back to audio and plays it to the caller.

    Each stage introduces latency, and those latencies are multiplicative. An STT engine adding 150ms, an LLM taking 400ms to generate a response, and a TTS engine taking 200ms means roughly 750ms before audio starts playing — and that does not account for network transit, authentication calls to the CRM, or RAG retrieval from a knowledge base. Production systems targeting sub-one-second end-to-end latency have to be engineered deliberately at every stage.

    The orchestration layer — the real production system

    The part that is consistently underinvested in pilots is the orchestration layer. This is not glue code. It is the component responsible for: managing conversation state across turns, handling barge-in (when the caller talks over the agent), deciding when to call backend tools versus when to respond from context, triggering escalation logic, managing retry and recovery when an API call times out, and writing structured logs that feed the observability stack.

    In production, the orchestration layer processes thousands of concurrent, stateful conversations simultaneously. It needs to handle failure gracefully — if the CRM API returns a 503, the agent should acknowledge the issue, offer alternatives, or escalate. It should not confuse the caller or pretend the problem does not exist.

    Teams that treat orchestration as an afterthought discover it in the worst way: an agent that silently drops state between turns, gives contradictory answers within a single call, or fails to escalate when it clearly should.

    Emerging speech-to-speech architectures

    A newer pattern gaining traction in 2026 is the speech-to-speech (S2S) multimodal model, which collapses the cascaded pipeline into a single end-to-end model that processes audio input and produces audio output without a separate STT or TTS stage. The primary benefit is latency reduction — eliminating transcription and synthesis steps can bring mouth-to-ear latency below 500ms. The drawback is maturity: S2S models are harder to audit, harder to integrate with structured backend tools, and have fewer production references than cascaded architectures.

    For most enterprise deployments in 2026, the cascaded streaming pipeline with a well-engineered orchestration layer remains the safer production choice. S2S architectures are worth piloting in narrow scenarios, particularly where latency is the primary constraint, but treating them as a production default is premature for most organizations.

    Observability is not optional

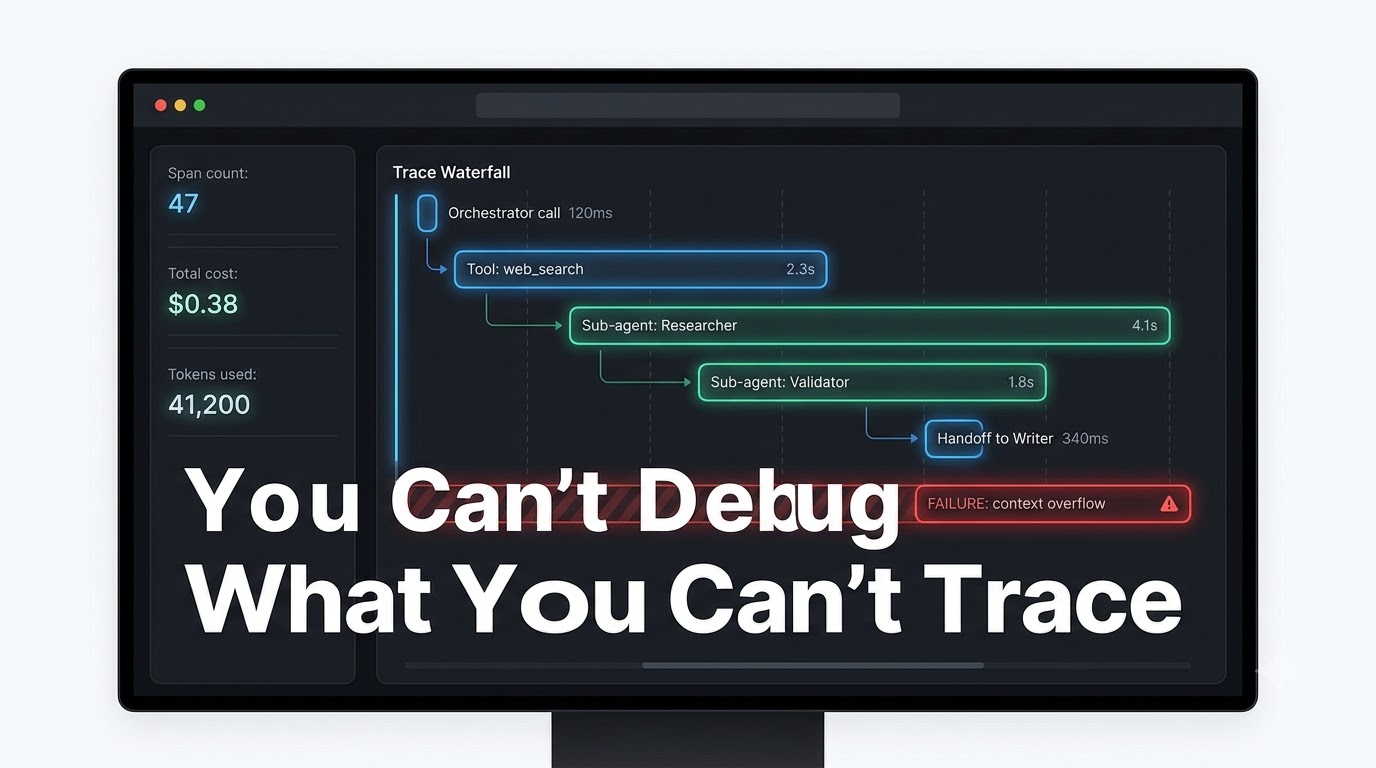
    Production voice agents need trace-level logging of every turn: what the caller said (as transcribed), what the model received, what tools were called and what they returned, what the model generated, and what the TTS spoke. Without this, diagnosing failures is guesswork, and improving containment rates is essentially impossible.

    Leading teams in 2026 treat observability as a first-class architectural requirement rather than a post-launch add-on. They instrument latency at each pipeline stage, track per-intent error rates, and run automated quality sampling on a random percentage of calls daily.

    Scoping Your First Production Use Case: The Narrow-Before-Wide Rule

    The single most consistent factor separating teams that reach production from teams stuck in pilot purgatory is use case discipline. Teams that try to automate everything at once automate nothing at scale. Teams that pick one narrow, high-volume, well-bounded call type and build it to production quality first create the organizational confidence and technical foundation to expand.

    What “narrow” actually means

    A production-ready use case has several properties. First, the intent distribution is predictable: if you pull 1,000 calls of this type, the vast majority follow a recognizable pattern and the variance is manageable. Second, the backend integrations are finite and documented: the agent needs to call two or three APIs, not fifteen. Third, the failure mode is recoverable: if the agent fails, the escalation path to a human agent is smooth and the customer experience is not damaged. Fourth, the volume justifies the investment: automating a call type that accounts for 200 calls a month does not move any meaningful metric.

    Classic first use cases that meet these criteria include: order status and shipping inquiries, account balance and transaction history, appointment scheduling and cancellation, password reset and basic account authentication, and FAQ deflection for common policy questions.

    The temptation to over-scope

    CX leaders face constant pressure to demonstrate transformational impact quickly. This pressure often drives over-scoping — trying to automate complex, multi-intent call types that require judgment, empathy, or access to a dozen backend systems. These use cases have real ROI potential, but they require a production foundation that does not exist yet.

    A banking organization that tries to deploy a voice agent capable of handling loan applications, dispute resolution, and product advisory conversations simultaneously is designing for failure. The same organization that starts with balance inquiries and account verification — achieving 70%+ containment on those narrow intents — builds the observability infrastructure, the integration patterns, the escalation protocols, and the team confidence to tackle complex use cases in phase two.

    Mapping intents before you build

    Before finalizing use case selection, the best teams do a structured intent audit: pulling three to six months of call recordings, transcribing them, and clustering by intent. This reveals which call types are genuinely high-volume and low-variance versus which ones look simple from the outside but are actually filled with exceptions. It also provides the training and evaluation data the model needs — not synthetic examples, but real caller language with all its messiness.

    Teams that skip the intent audit and build from assumed call types consistently discover, post-launch, that the distribution does not match their assumptions. The agent is tuned for calls that rarely happen and struggles with calls that are extremely common.

    The Escalation Handoff: Designing the Moment That Defines Trust

    Voice AI agent warm handoff to human agent with structured context brief — not a blind transfer

    If there is one design decision that defines whether customers trust a voice agent program, it is the escalation handoff. Get it right and customers feel the system is working as intended. Get it wrong and customers feel trapped, deceived, or disrespected — and they call back angry, sometimes multiple times.

    The multi-signal escalation trigger

    Escalation should never be driven by a single confidence threshold. Production-grade systems in 2026 use composite trigger logic that weighs multiple signals simultaneously: the model’s internal confidence score, detected customer sentiment (frustration signals in tone or word choice), conversation loop detection (the customer has stated the same need more than twice without resolution), explicit human agent requests, and policy-based rules (certain transaction types or compliance-sensitive topics should always involve a human).

    Composite triggers reduce both under-escalation (the agent confidently handles something it should not) and over-escalation (the agent transfers too easily, undermining the value of the system). The thresholds for each signal should be defined before deployment as explicit policy, not tuned reactively after complaints.

    Context transfer, not transcript dumping

    The single most common failure in production escalation is what happens after the transfer decision. Teams often configure the system to send the human agent a raw transcript of the conversation — which is typically 500-1,500 words of dialogue that the agent has no time to read while the caller is on hold waiting.

    Leading teams instead generate a structured context brief at the point of escalation: a 4-6 line summary that tells the human agent the customer’s name, their authenticated account status, the intent they called about, the steps the voice agent already took, the specific failure point, and the recommended next action. A human agent can absorb this in 8-10 seconds while the customer is in the transfer queue, meaning the conversation resumes intelligently rather than forcing the customer to repeat everything from the beginning.

    Forcing customers to repeat themselves after an AI transfer is one of the top-cited frustration points in post-deployment CSAT surveys. It signals that the AI portion of the interaction produced zero value. The structured brief eliminates this entirely.

    Warm transfer versus cold drop

    A warm transfer connects the caller to a human agent and provides a brief verbal summary before completing the handoff — something like “I’m connecting you with a specialist now. I’ve let them know you’ve been waiting and what you need.” A cold drop simply routes the call and leaves the human agent to figure it out from the incoming call.

    Warm transfers require slightly more engineering — the system needs to handle the three-party moment between the voice agent, the caller, and the incoming human agent — but the CSAT impact is substantial. Production teams that measure post-escalation CSAT consistently find warm transfers outperform cold drops by 15-25 points.

    Durable state for human-in-the-loop workflows

    An underappreciated design requirement for complex call types is durable conversation state — the ability for a human agent to review what the AI did, make a decision, and then hand back to the AI for completion. This is particularly valuable in regulated industries where certain steps require human authorization but others can be automated.

    Without durable state, every human intervention effectively terminates the automated portion of the workflow. With it, the human acts as a checkpoint rather than a replacement, dramatically improving the economics of complex, partially-automated interactions.

    Governance, Compliance, and the Regulatory Layer That Pilots Skip

    Compliance is where many enterprise pilots stall when they try to scale. The pilot ran on a test dataset that excluded sensitive interactions. Production cannot. Voice agents in 2026 operate under a thickening web of regulatory obligations that were either absent or unenforced when most pilot architectures were designed.

    PCI DSS 4.0.1 and voice payments

    PCI DSS 4.0.1 — which reached full mandatory compliance in 2026 — explicitly addresses AI systems that handle payment card data in contact center environments. Voice agents that capture card numbers, expiry dates, or CVVs are now required to implement scope-reduction controls, maintain audit trails of AI-mediated transactions, and ensure the LLM and TTS systems do not retain sensitive data between interactions.

    Many pilot architectures log full conversation transcripts for quality review without redacting payment data. This is a compliance violation at production scale. Teams need to implement real-time redaction pipelines that scrub card data from transcripts before storage, and they need to audit every component in the voice pipeline to confirm it does not cache sensitive audio or text.

    HIPAA and healthcare voice agents

    Healthcare organizations deploying voice agents in patient-facing support roles face HIPAA obligations that extend to every component in the AI pipeline — including the LLM provider, the STT engine, the TTS provider, and the observability platform. Each of these vendors typically needs a Business Associate Agreement (BAA). The LLM provider’s standard enterprise agreement may not include BAA terms, which means the legal team needs to negotiate customized contracts before the voice agent can handle any interaction involving protected health information.

    This is not a theoretical risk. HIPAA enforcement against AI-mediated healthcare interactions has intensified since late 2025, with investigators specifically examining whether organizations applied the same rigor to AI systems that they would apply to human agents.

    EU AI Act Article 50 and disclosure requirements

    For organizations serving EU customers, the EU AI Act’s Article 50 transparency obligations — now enforceable — require that customers interacting with an AI system be clearly informed that they are speaking with an AI, not a human. This means voice agents cannot use names, voices, or conversational patterns designed to create the impression of human interaction without disclosure.

    The practical implication is that the introductory script — “Hi, this is Aria, our virtual assistant” — is not optional branding copy. It is a compliance requirement. And it needs to be reinforced at the point of escalation, when customers are sometimes uncertain whether they have been transferred to a human. Failing to disclose this explicitly is an enforceable violation.

    TCPA and outbound voice AI

    Organizations using voice agents for outbound calls — proactive notifications, collections, appointment reminders — face Telephone Consumer Protection Act obligations that have become significantly more stringent. Updated consent requirements now require explicit, documented, revocable consent for AI-initiated outbound voice calls, and consent obtained for one purpose (marketing, for example) does not transfer to another (collections).

    Compliance teams need to audit every outbound use case before production deployment, verify the consent basis for every contact list, and implement real-time opt-out handling so the voice agent immediately stops calling a customer who requests it — including recognizing verbal opt-out requests in natural language.

    The Metrics That Actually Matter — Beyond Containment Rate

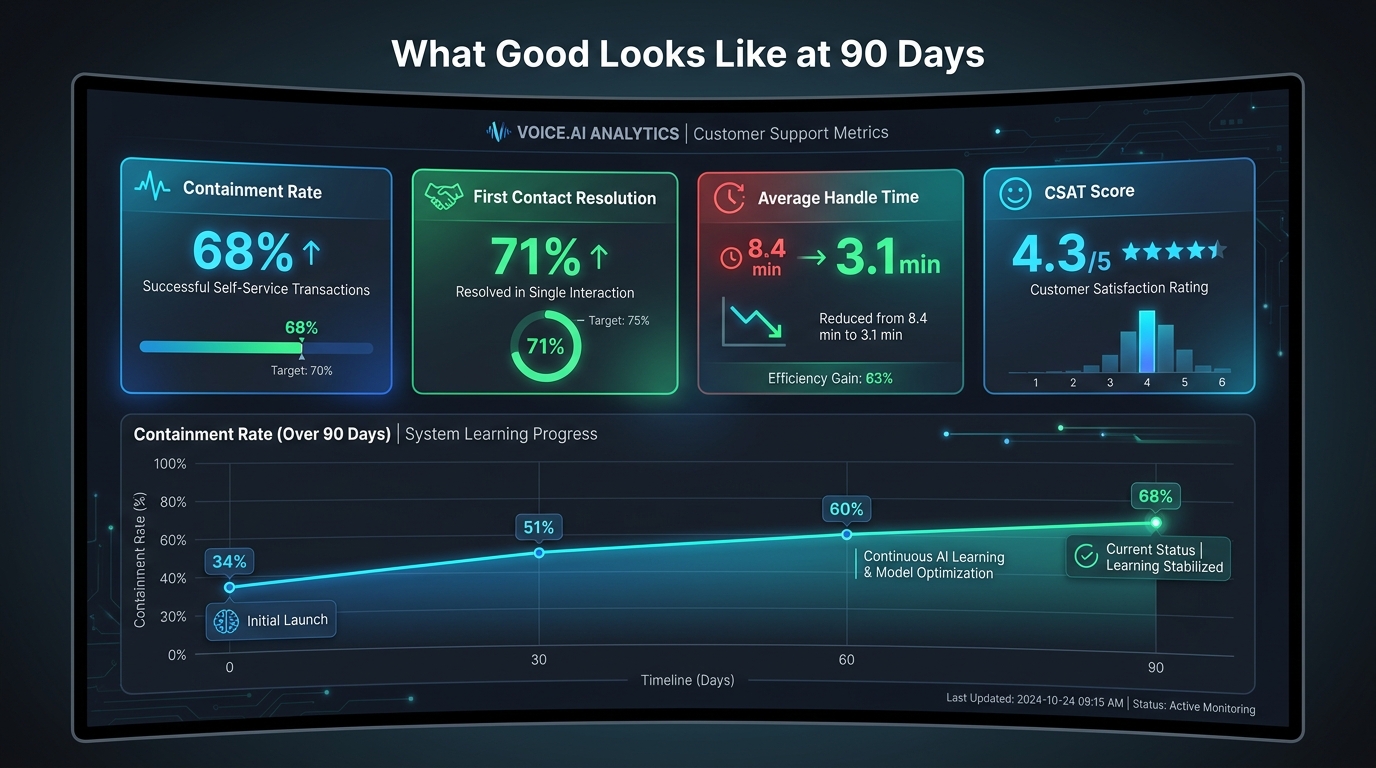
    Voice AI support metrics dashboard showing containment rate 68%, FCR 71%, AHT reduction, and CSAT 4.3 after 90 days

    Containment rate — the percentage of calls the voice agent handles end-to-end without escalation — has been the headline metric for voice AI deployments since the technology emerged. It is also one of the most misleading metrics in production if it is the only metric being tracked.

    Why containment rate lies to you

    A containment rate measures calls completed without human escalation. It does not measure whether those calls were actually resolved. A caller who asks about a billing dispute, receives an unhelpful response, and hangs up in frustration counts as a “contained” interaction by most definitions. That caller will call back — often immediately, now irate — and the repeat contact represents a cost that the containment metric invisibilized.

    The shift in leading contact centers in 2026 is from containment rate to true resolution rate — a metric that measures whether the customer’s issue was actually solved, typically validated by checking whether the same customer with the same intent contacts support again within a defined window (usually 24-72 hours). A voice agent that truly resolves an issue at 65% containment is dramatically more valuable than one that “contains” at 80% but resolves at 40%.

    The metric stack for mature deployments

    Teams operating in full production track a five-metric stack that gives a complete picture of voice agent performance:

    • True resolution rate (TRR): The percentage of handled interactions where the issue was resolved without repeat contact. This is the primary performance metric.
    • Post-escalation resolution time: How long it takes human agents to resolve calls that were escalated from the voice agent. A rising post-escalation time indicates the agent is handling the wrong calls — passing the most complex cases through — or that context transfer is failing.
    • CSAT delta by channel: Customer satisfaction scores for AI-handled versus human-handled calls on the same intent type. This should narrow as the agent matures, but a persistent gap signals a quality ceiling.
    • Escalation trigger precision: What percentage of escalations were genuinely necessary versus cases where the agent escalated unnecessarily. High unnecessary escalation rates indicate over-cautious thresholds; low unnecessary escalation rates with high post-escalation CSAT scores indicate the trigger logic is well-calibrated.
    • Cost per resolved contact: The total operational cost (infrastructure, staffing, oversight, vendor fees) divided by the number of contacts where the issue was fully resolved. This grounds the business case in outcomes, not activity.

    The 90-day learning curve

    Production voice agents rarely hit their operational targets in the first few weeks. Mature deployments in 2026 typically show a pattern of containment starting in the 30-40% range at launch and climbing to 55-70% over a 60-90 day ramp period, as the team tunes intent recognition, expands the knowledge base, fixes integration edge cases, and refines escalation thresholds based on real call data.

    Teams that measure success at day 14 and conclude the program is underperforming are measuring at the wrong point on the curve. The appropriate target-setting conversation should be about 90-day benchmarks, not launch-week performance.

    The Workforce Conversation Nobody Wants to Have

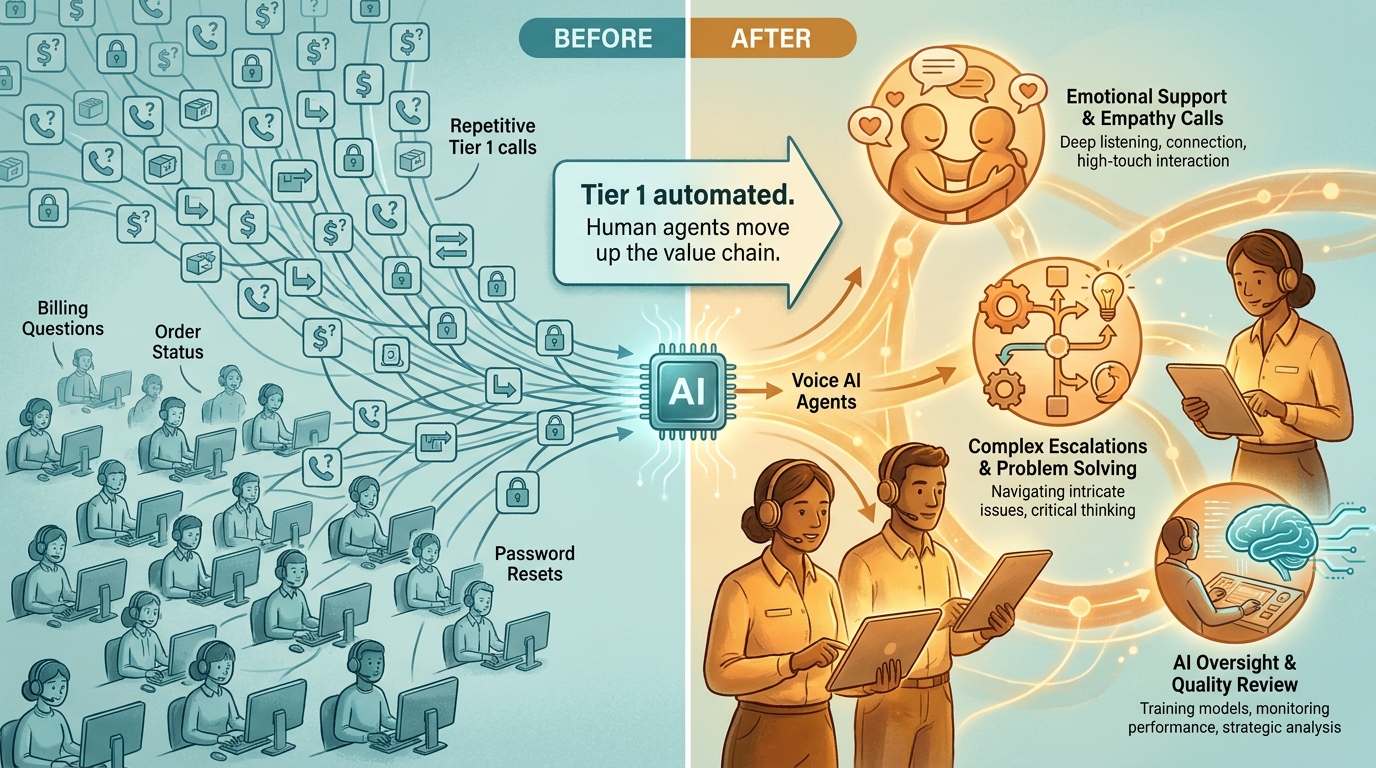
    Contact center workforce transformation — agents moving from repetitive Tier 1 calls to complex escalations and AI oversight roles

    There is no version of a successful full-production voice agent rollout that does not affect the workforce. Approximately 2 million call center jobs were eliminated globally between mid-2024 and mid-2026 as voice AI deployed at scale. That is not a statistic to be celebrated or minimized — it is a fact that every CX leader planning a rollout needs to address explicitly with their teams.

    What agents are actually afraid of

    Frontline customer support agents in 2026 report that their primary concern is not immediate job loss — it is work intensification. As voice agents handle routine Tier 1 interactions, the calls that reach human agents are, by definition, the harder ones: frustrated customers, complex multi-issue interactions, emotionally charged escalations, and edge cases the AI cannot resolve. Agents report that their jobs are becoming more cognitively demanding and emotionally taxing without a corresponding change in compensation, title, or support infrastructure.

    This is the dynamic that, left unaddressed, drives the highest-quality agents to leave. And losing experienced agents who know how to handle complex calls is exactly the wrong outcome when the voice agent is supposed to be freeing humans for higher-value work.

    The role redesign problem

    Many organizations announce a voice agent rollout with messaging that emphasizes “augmentation” and “freeing agents for meaningful work,” without actually redesigning the work. The agent queue changes in volume and composition, but the job descriptions, performance metrics, compensation structures, and support resources stay the same.

    Effective rollouts treat workforce redesign as a parallel workstream, not a follow-on task. This means: redefining performance metrics to reflect the harder nature of the remaining call mix, creating explicit AI oversight and quality review roles that skilled agents can grow into, providing training on handling emotionally escalated calls (which will make up a larger share of the queue), and establishing clear communication about headcount changes — whether through attrition management, redeployment, or reduction in force.

    The change management minimum viable commitment

    The minimum change management commitment for a full production rollout includes: a pre-launch briefing with frontline agents that is honest about what the system does and how it affects their role; a feedback channel where agents can report voice agent failures or inappropriate escalations; regular sessions where agent insights about common failure patterns inform model improvement; and a visible internal sponsor — ideally a CX executive — who communicates regularly about the program’s direction.

    Teams that skip this and simply launch tend to encounter passive resistance — agents who recommend that callers “ask to speak to a real person” or who flag every AI interaction as a complaint regardless of outcome. This is not malicious; it is what happens when the people closest to the customer feel excluded from a process that fundamentally changes their work.

    Where Voice Agents Are Delivering Real Numbers: Sector Evidence

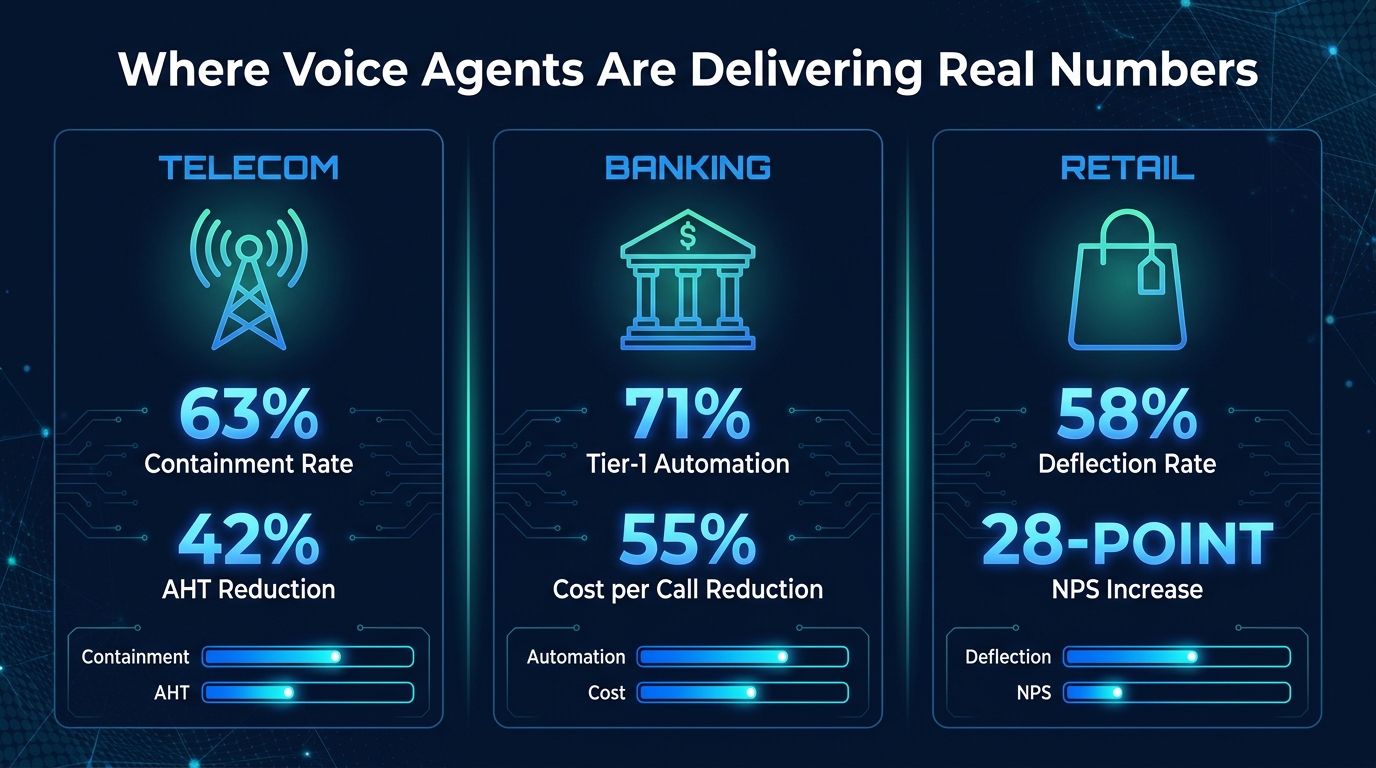
    Voice AI agent results by sector — Telecom 63% containment, Banking 71% Tier-1 automation, Retail 58% deflection

    The gap between pilot enthusiasm and production reality does not mean voice agents are not working. In specific sectors, with specific use cases, they are delivering substantial, measurable results. The pattern is consistent: results are best where call volume is high, intent distribution is predictable, and backend integrations are manageable.

    Telecom: High volume, high ROI

    Telecommunications is the sector with the most mature voice agent deployments in 2026. Tier-1 telcos typically handle hundreds of thousands of inbound calls per day, with a significant portion concentrated in a handful of common intents: billing inquiries, data usage checks, outage status, SIM card issues, and plan changes.

    Production deployments in this sector report containment rates of 55-70% for these defined use cases, with average handle time reductions of 35-50% on the calls that do reach human agents (because the AI has already authenticated the customer and captured the intent). Cost per resolved contact has dropped by 40-60% in mature telco deployments. Vodafone’s published results with its generative AI speech agent for first-level customer service illustrate the pattern: SIM activation and billing query automation at scale, with the human agent queue refocused on complex and commercial calls.

    Banking: Trust-intensive, but the numbers work

    Banking presents higher compliance complexity than telecom — authentication requirements are stricter, error costs are higher, and customer trust in AI handling financial matters starts from a lower baseline. But mature banking deployments are achieving 65-75% Tier-1 automation rates for self-service account management use cases, with 50-60% cost reductions per interaction.

    The key differentiator in successful banking deployments is authentication architecture. Voice agents that use voice biometrics combined with knowledge-based authentication (rather than relying solely on knowledge-based verification, which is increasingly vulnerable to social engineering) achieve higher containment rates because they resolve authentication faster, and customers feel the security is appropriate for the channel.

    Outbound use cases in banking — proactive balance alerts, payment due reminders, and collections follow-ups — are also generating measurable results, with collection rates on AI-handled outbound campaigns running 15-25% higher than equivalent email campaigns, primarily because the voice medium achieves higher engagement rates.

    Retail: Seasonal scaling and multilingual support

    Retail’s primary voice AI value proposition is different from telco and banking: it is less about permanent cost reduction and more about elastic capacity. Retail call volume spikes dramatically during peak periods — Black Friday, holiday shipping windows, major sale events — and the traditional approach of hiring seasonal agents creates quality and training challenges.

    Voice agents scale to handle those peaks without hiring, without training lag, and without the quality variance that comes with seasonal agents who have been onboarded in two days. Retailers with production voice agent deployments report 55-65% deflection rates for order status, returns initiation, and store information queries during peak periods, with CSAT scores that hold within 10 points of the off-peak baseline — a meaningful improvement over seasonal agent quality metrics.

    Multilingual support is a secondary but significant advantage in retail. A voice agent can be deployed in 15 languages simultaneously at no marginal cost per language, while adding a human agent for each language requires separate hiring markets and training infrastructure. For retailers with geographically diverse customer bases, this capability alone can justify the deployment investment.

    The 90-Day Rollout Cadence That Actually Works

    Across the deployments that have successfully moved from pilot to full production, a repeatable 90-day cadence emerges. It is not universal — sector, team size, and technical complexity create variations — but the broad structure holds.

    Days 1-30: Production foundation, not feature expansion

    The first month of production is not the time to add use cases. It is the time to confirm that the initial use case is functioning reliably under real load, that the observability stack is capturing everything needed for diagnosis, and that the escalation pathway is smooth. Teams should be reviewing a random sample of calls daily — not just metrics, but actual transcripts and audio — to identify failure patterns that aggregate metrics obscure.

    Key targets for day 30: containment rate of at least 35% on the target use case (the system is handling something meaningful), escalation CSAT above 3.8 on a 5-point scale (the handoff experience is not damaging customer relationships), and zero compliance findings from legal and compliance review of the call logs.

    Days 31-60: Systematic improvement, intent expansion

    With the foundation confirmed, days 31-60 focus on improving performance on the existing use case while beginning the readiness assessment for the next. The improvement work is data-driven: categorizing containment failures by root cause (transcription error, intent misclassification, missing knowledge, integration failure, or appropriate escalation), then prioritizing fixes by frequency and impact.

    The intent expansion readiness assessment follows the same criteria as the original use case selection: intent distribution analysis, backend integration inventory, failure mode mapping, and compliance review. The goal is to have the next use case ready to launch in month three, not to start the architecture work in month three.

    Days 61-90: Scale and second use case launch

    By day 60, a well-executed deployment should show containment rates in the 55-68% range on the initial use case and be ready to launch the second. Days 61-90 run both use cases simultaneously, with careful monitoring to ensure that adding volume and complexity to the system does not degrade performance on the established use case.

    The 90-day mark is also the appropriate point for the first formal business case review: comparing actual cost per resolved contact, agent time savings, and customer satisfaction metrics against the pre-launch projections. This review serves two purposes: it validates (or challenges) the ongoing investment, and it builds the organizational evidence base for the next phase of expansion.

    What Full Production Actually Looks Like — and How You Know You’re There

    There is no universally agreed definition of “full production” for a voice agent program. But the characteristics of teams that consider themselves there — as opposed to teams still in an extended pilot — are fairly consistent.

    Volume thresholds

    A program is in full production when the voice agent is handling a material percentage of the total call volume for its defined use cases — not a gated subset, not a test cohort, but the default path for those calls. This typically means 20-40% of total inbound call volume for the combined set of automated intents, with the expectation that this will grow as more use cases are added.

    Programs where the voice agent is still handling less than 10% of relevant call volume, or where human agents retain a parallel path for the same call types, are not in full production. They are in supervised expansion — which is a legitimate stage, but it is not the same thing.

    Operational independence

    A production program runs without requiring dedicated attention from the AI/ML team for routine operations. The contact center operations team can adjust thresholds, update knowledge base content, configure new routing rules, and review performance dashboards without developer involvement. The development team handles structural changes and new use case launches, but the day-to-day operation is genuinely owned by operations.

    This is frequently the last milestone reached. Teams that built voice agents on architectures that require engineering intervention for every content update or threshold adjustment are operationally dependent on the technical team indefinitely. Full production requires sufficient no-code or low-code configurability that operational staff can manage the system they are accountable for.

    Continuous improvement infrastructure

    A production program has a functioning feedback loop: call samples are reviewed regularly, failure categories are tracked and prioritized, model updates are deployed on a cadenced schedule (not reactively), and performance metrics are reviewed in monthly operational reviews that include both technical and business stakeholders.

    The distinction between a mature production program and a deployed-but-stagnant one is this continuous improvement infrastructure. Without it, a system that achieves 60% containment at launch will still be at 60% eighteen months later, and the business case for expansion deteriorates.

    Escalation as a designed system, not an exception path

    Finally, a production program treats escalation not as a failure mode but as a designed workflow. The system knows which calls to escalate, when to escalate them, how to transfer context, and how to route to the right human agent tier. Post-escalation performance is measured and reviewed. The human agent queue is staffed appropriately for the escalation volume. And escalation rate itself is used as a leading indicator — a rising escalation rate signals something has changed in the call mix or the system’s performance, and that signal triggers investigation before it becomes a customer satisfaction problem.

    Conclusion: The Gap Is Executable

    The 37-point gap between the 64% of enterprises piloting voice agents and the 27% that have reached production is not a reflection of the technology’s limits. It is a reflection of execution complexity that pilots are specifically designed to avoid confronting.

    The teams that close that gap share a specific set of behaviors: they scope narrowly and build to quality before expanding, they invest in orchestration and observability as first-class concerns rather than afterthoughts, they design escalation as a user experience rather than a technical fallback, they address compliance proactively rather than reactively, and they treat the workforce impact as a change management challenge that requires as much attention as the technical architecture.

    The median time from pilot to production is four to five months. That is not a long time. But it requires that the months be spent on the right problems — the variance handling, the integration depth, the escalation design, the governance framework, and the operational tooling that pilot conditions happily obscure.

    Voice agents are not difficult to demo. They are difficult to run well at scale in a production support environment where the calls are harder, the callers are real, and the consequences of failure — a frustrated customer, a compliance finding, a lost agent — are concrete.

    The teams in the 27% know this. They built for those conditions from the start. That is what separates a production rollout from a pilot that never ends.

    Key Takeaways

    • Stress-test for real conditions before launch: Unscripted callers, real integrations, peak load, and edge cases. Pilot conditions are favorable by design.
    • Treat orchestration as the production system: State management, retry logic, observability, and escalation triggers belong in the architecture from day one.
    • Start with one narrow, high-volume, well-bounded use case. Over-scoping is the most common path to pilot stagnation.
    • Design escalation as a UX, not a fallback: Multi-signal triggers, structured context briefs, and warm transfers are non-negotiable in production.
    • Audit compliance before launch, not after: PCI DSS 4.0.1, HIPAA, EU AI Act Article 50, and TCPA requirements apply to production systems — and enforcement has intensified.
    • Measure resolution, not containment: A call the AI “contained” but did not resolve is a repeat contact waiting to happen.
    • The workforce conversation is not optional: Agents whose work changes without explanation or redesign become the program’s loudest critics.
    • 90 days is the right measurement window: Systems that look underwhelming at day 14 often hit targets by day 60-90 as tuning and data accumulate.
  • When Amazon’s Compliance Bot Gets It Wrong: The Hidden Cost of False Positives in 2026 Image Enforcement

    When Amazon’s Compliance Bot Gets It Wrong: The Hidden Cost of False Positives in 2026 Image Enforcement

    Your listing is live. Sales are running. And then — without a warning email, without a phone call, without a human ever looking at your product photo — Amazon’s automated system decides your image is non-compliant. Your ASIN disappears from search. Your ad spend continues burning. Your organic rank starts eroding. You find out because sales stopped.

    This is the reality of Amazon image compliance enforcement in 2026, and the conversation around it has been dominated by one question: what are the rules? That question has been answered, repeatedly. There are comprehensive rule lists everywhere. But the rules are almost not the point anymore.

    The real story in 2026 is what happens when those rules are enforced by an AI system operating at a scale no human team could match — scanning over 300 million product images per month, suppressing 3.1 million listings in a single quarter, and generating a non-trivial rate of false positives that fall entirely on sellers to identify, dispute, and remediate. Meanwhile, new legal obligations around AI-generated imagery and synthetic performers have layered fresh complexity onto an already dense compliance landscape.

    This article isn’t a rule recap. It’s an operational analysis of what Amazon’s image compliance system actually looks like from the inside of the enforcement pipeline — how the detection works, where it breaks down, what suppression really costs, how to navigate the appeals process when you’re wrongly flagged, and what a genuine compliance operation looks like for sellers who are serious about protecting their catalog in 2026.

    Amazon image compliance enforcement 2026 — compliant vs suppressed listing split comparison with 3.1 million listings suppressed stat

    The Scale of the Problem: 3.1 Million Listings in One Quarter

    To understand why image compliance has moved from a background operational concern to a top-line business risk, you need to start with the numbers. According to Marketplace Pulse reporting cited across multiple 2026 industry analyses, Amazon removed more than 3.1 million listings in a single quarter for image policy violations. That is not a typo, and it is not a cumulative figure. That is one quarter.

    Put that in context. Amazon hosts hundreds of millions of active product listings. The enforcement action in a single quarter represents a meaningful percentage of active catalog, and every one of those suppressions represents a seller losing organic search visibility, potentially losing their rank position, and in some cases losing weeks or months of sales velocity data that feeds into the A10 algorithm’s ranking signals.

    What Changed to Produce This Scale

    The enforcement shift didn’t happen overnight. Amazon has been building toward automated, algorithmic image compliance for several years, but 2026 is when the infrastructure became genuinely capable of acting at catalog scale without meaningful human review in the loop.

    Several specific changes converged to produce the current environment:

    • Main image minimum resolution raised: The standard moved from 1,600×1,600 pixels to 2,000×2,000 pixels effective April 15, 2026. Listings that had technically passed before suddenly became non-compliant under the new threshold.
    • Product fill requirement tightened: The product must now occupy at least 85% of the image frame, a specification that is now being checked algorithmically rather than through spot audits.
    • Pixel-level background enforcement: Amazon’s systems now check that backgrounds are pure white at the pixel level — specifically RGB 255, 255, 255. An off-white that is barely distinguishable to the human eye can be flagged and trigger suppression.
    • Auto-suppression without warning: Previously, sellers might receive a notification to fix a non-compliant image within a grace period. In 2026, the default for many violation types is immediate suppression, with sellers discovering the issue only after the fact.

    Who Bears the Risk Asymmetrically

    The 3.1 million figure obscures an important distribution. Most of those suppressions are concentrated among smaller and mid-sized sellers who lack the dedicated compliance infrastructure to catch issues before Amazon’s system does. Large brand-registered sellers with professional catalog teams and automated pre-submission checks are largely insulated. The sellers most likely to be hurt are those with large catalogs and limited operations bandwidth — exactly the sellers who can least afford to have revenue interrupted without warning.

    The concentration of enforcement impact among smaller sellers is not a feature of the policy — it is a structural consequence of who has the resources to operate compliant catalog management systems at scale. A well-resourced brand can afford the tooling, the dedicated staff, and the pre-submission verification workflows that effectively insulate them from the automated system’s error rate. A growing seller running a lean operation is far more exposed to both genuine violations and false positives.

    How Amazon’s AI Actually Scans Your Images

    Most coverage of Amazon’s image compliance discusses the rules in isolation without explaining the mechanism by which they’re enforced. Understanding the technical architecture of Amazon’s detection system matters — both because it tells you what the system is actually looking for, and because it explains why false positives happen.

    Amazon AI image scanning pipeline 2026 — Rekognition detection modules, background check, synthetic person detector, resolution validator

    The Core Infrastructure: Amazon Rekognition and Custom Classifiers

    Amazon’s retail image compliance system is built primarily on Amazon Rekognition, the company’s commercial computer vision service, combined with proprietary compliance classifiers that sit on top of it. Rekognition itself handles the broad moderation tasks — detecting unsafe, explicit, or potentially misleading content. On top of that foundation, Amazon has developed specialized classifiers tuned specifically for marketplace compliance contexts.

    These custom classifiers handle tasks that Rekognition’s general model wasn’t designed for: identifying whether a product is filling the required percentage of frame, detecting non-white background pixels, flagging watermarks or overlaid text, and — increasingly — identifying images that appear to be AI-generated or digitally altered in ways that misrepresent the product.

    The Multi-Stage Review Pipeline

    When you upload an image to Amazon, it doesn’t flow directly to your live listing. It moves through a multi-stage review pipeline that operates roughly as follows:

    1. Technical metadata check: File format, color space (sRGB required), and minimum resolution are verified immediately. Failures here stop the image before it reaches more expensive computer vision processing.
    2. Computer vision moderation pass: The image is run through Rekognition-style models to flag unsafe or prohibited content. This happens at scale, using batch processing infrastructure.
    3. Compliance classifier pass: Purpose-built models check for background compliance, product fill percentage, presence of text or logos, and whether the image appears to represent the actual product being sold.
    4. Hash similarity check: The image is compared against a database of previously flagged or removed images. Resubmitting a non-compliant image with minimal changes will typically be caught here.
    5. Synthetic image classifier: A relatively new addition to the pipeline, this checks whether images appear to be substantially AI-generated — a determination that matters under both Amazon’s internal policy and new legal requirements around synthetic performers.

    For most images, this entire pipeline runs automatically without any human involvement. Human review enters the picture primarily when sellers appeal a suppression, and even then, the initial appeal review is frequently handled by a combination of automated scoring and low-level review teams working from standardized decision frameworks.

    What the System Isn’t Good At

    The system described above is genuinely impressive in scale. Analyzing 300 million images per month would be impossible any other way. But it is important to understand the limitations of these systems, because those limitations translate directly into false positives that damage seller revenue.

    Computer vision models that identify pixel-level background deviations are sensitive enough to flag shadows, compression artifacts, and minor color profile inconsistencies that are invisible to the human eye and irrelevant to the customer experience. Models trained to detect AI-generated images are not perfect — they produce false positives on high-quality product photography that uses certain editing techniques. The compliance classifiers have to operate on simplified rules rather than contextual judgment, which means they will always produce a certain percentage of incorrect determinations.

    The system is also not static. Amazon regularly retrains its classifiers and adjusts enforcement thresholds. When this happens, images that have been live and compliant for months can be retroactively flagged under the new model — not because anything about the image changed, but because the detection standard was updated. Sellers have no advance notice of these retrains and no way to pre-emptively verify compliance against a model that doesn’t exist yet.

    The False Positive Problem Nobody Is Talking About Loudly Enough

    The 3.1 million listing suppressions in one quarter are reported as evidence of enforcement strength. But embedded within that figure is a subset of suppressions that should never have happened — listings suppressed for alleged violations that, on any reasonable human examination, were compliant.

    Amazon AI image compliance false positive problem — robot stamping compliant product image with violation detected, 62% of AI-generated photos flagged stat

    The Numbers Behind the False Positives

    Amazon has not published false positive rates for its image compliance system. The company doesn’t acknowledge the category in its public communications. But industry-level signals are telling. Analysis from 2026 marketplace specialists indicates that approximately 62% of fully AI-generated product photos submitted to Amazon’s catalog were flagged in automated review — a number that suggests a detection system calibrated toward over-sensitivity. That statistic applies specifically to AI-generated images, but the same underlying detection systems produce false positives across other violation categories as well.

    Sellers in specialized forums and agency reports have documented cases where:

    • Perfectly compliant product photography on pure white backgrounds was flagged because compression during upload introduced background artifacts below perceptible threshold.
    • Images that had been live and compliant for months were retroactively suppressed when Amazon’s models were retrained and applied to the existing catalog.
    • High-quality lifestyle images submitted for secondary image slots were flagged as main image violations despite being uploaded to different positions.
    • Products on white backgrounds with minimal product shadows were rejected for “non-white background” when the shadow constituted a small fraction of the image’s total pixel space.
    • Heavily edited conventional photography was detected as AI-generated — and therefore non-disclosed — by classifiers that couldn’t distinguish between aggressive photo retouching and generative AI output.

    The Structural Problem: No Accountability Loop

    What makes false positives especially damaging in Amazon’s enforcement system is the absence of a feedback mechanism that creates accountability. When Amazon’s system incorrectly suppresses a listing, there is no automatic review triggered. There is no internal metric at Amazon that tracks false positive rates and incentivizes the team to reduce them. The burden of identifying the suppression, investigating whether it’s legitimate, and pursuing an appeal falls entirely on the seller.

    During the time it takes a seller to notice the suppression, investigate the cause, prepare a response, and navigate the appeals process, revenue is lost. Rank position deteriorates. Ad campaigns targeting the suppressed ASIN continue spending with zero conversions. And in categories with seasonal peaks, a false positive at the wrong moment can cost a seller their window entirely.

    Why Amazon’s Incentives Don’t Point Toward Fixing This

    Amazon’s published rationale for aggressive image compliance enforcement is customer experience — ensuring that product photos accurately represent what’s being sold, meet quality standards, and don’t deceive buyers. That’s a legitimate goal. But it doesn’t create pressure to reduce false positives, because false positives don’t hurt customers. They only hurt sellers.

    From Amazon’s internal perspective, over-enforcement is less costly than under-enforcement. A false positive produces a complaint through the appeals channel; a missed violation potentially produces a customer complaint, a return, and a negative review. The asymmetric consequences of errors mean the system will, by design, err on the side of over-suppression. Sellers absorb the cost of that design choice without any mechanism to recover it from Amazon when the suppression was the system’s error rather than theirs.

    The Technical Spec Minefield: Where Most Sellers Actually Get Tripped Up

    Understanding the compliance landscape requires a clear-eyed look at the specific technical requirements that generate the most suppression events in 2026. These aren’t the obvious violations — nobody is intentionally submitting images with visible watermarks or explicit content. The volume comes from technically subtle requirements that are easy to get subtly wrong.

    The White Background Problem

    The requirement for a pure white background — specifically RGB 255, 255, 255 / HEX #FFFFFF — sounds simple. In practice, it is one of the most common sources of suppression in 2026. Here’s why:

    Professional product photographers typically shoot on white seamless paper or white surfaces that look white to the eye but photograph in the range of RGB 245–252 depending on lighting conditions. Post-production editing can bring these into full compliance, but imprecise editing, JPEG compression artifacts during upload, and color profile mismatches between sRGB and other profiles can all introduce sub-visible deviations that Amazon’s pixel-level checker flags.

    The specific failure modes sellers encounter include:

    • Compression artifacts: JPEG compression at any quality setting below 100% introduces color variation at edge boundaries. A product image that passes a background check before compression may fail it after upload processing.
    • Color profile mismatches: Images saved in Adobe RGB or ProPhoto RGB color spaces and converted to sRGB during upload can shift background values slightly. Amazon’s system checks the uploaded file as-is.
    • Ambient shadows: Even diffuse, soft shadows cast by a three-dimensional product onto a white background can produce pixel values in the 240–254 range, technically violating the pure white standard.
    • Edge processing artifacts: When products are clipped from a photography background and composited onto a white canvas, the anti-aliasing at the edge can create semi-transparent pixels that blend with off-white values.

    Resolution and Frame Fill

    The 2,000×2,000 pixel minimum is straightforward, but sellers running older photography workflows may not have been producing images at this resolution historically. The 85% frame fill requirement is more nuanced — it applies to the longest edge of the product in the image, meaning a product like a flat cable or a narrow pen that is oriented vertically needs to nearly fill the frame in that dimension.

    Sellers with large catalogs who produced compliant images under the previous 1,600×1,600 minimum now face the task of auditing and re-shooting entire product lines. Those who haven’t completed that transition have listings quietly sitting under the threshold, vulnerable to suppression under the new standard whenever Amazon’s system runs a compliance pass against those ASINs.

    What’s Prohibited in Secondary Images

    While main image compliance gets most of the attention, secondary images have their own set of requirements that sellers frequently miss. Infographic images, lifestyle shots, and feature call-outs used in secondary positions are permitted — but they must not contain false claims, must not show elements not included with the product, and must represent the specific variation being viewed, not a different color or size.

    In categories with variation listings, Amazon’s system is increasingly checking whether secondary images accurately correspond to the selected variation. A parent listing that shows lifestyle images featuring the blue version of a product when the customer has selected the red variation can be flagged for misrepresentation, even if each color ASIN technically exists in the catalog. This check is subtle enough that sellers with large variation catalogs may have numerous technically non-compliant image associations without realizing it.

    The AI-Generated Image Rulebook: New Legal Terrain in 2026

    The most significant new development in Amazon’s image compliance landscape in 2026 isn’t a change to the white background specification. It’s the emergence of legally-backed disclosure requirements for AI-generated images — particularly those depicting synthetic human beings.

    Amazon AI-generated image disclosure requirements 2026 — synthetic performer disclosure badge, New York S.8420-A law, Amazon upload checkbox requirement

    The New York Synthetic Performer Law and Its Reach

    New York State Senate Bill S.8420-A — commonly referred to as the synthetic performer law — took effect June 9, 2026. The legislation requires that any commercial use of a digitally created or AI-generated likeness of a performer include explicit disclosure. While this law applies to New York specifically, Amazon’s response has been to implement a disclosure requirement across its entire marketplace rather than attempt to apply state-specific rules to a global platform.

    The practical implication: any seller or brand using AI-generated product imagery that includes photorealistic human models — a practice that had been growing rapidly as a cost-efficient alternative to model photography — is now required to tag those images during the upload process. Amazon has added a checkbox to the image submission workflow specifically for this declaration.

    What “Synthetic Performer” Means in Practice

    The definition matters because it affects a broader range of content than sellers initially realize. A synthetic performer under Amazon’s current policy interpretation includes:

    • Fully AI-generated human models wearing or using the product
    • Photorealistic human faces created by generative AI, even if only partially visible in the frame
    • AI-generated hands, arms, or other body parts used in product demonstration imagery where the human element is photorealistic and central to the image composition

    What it does not necessarily include — though this area remains interpretively gray — is highly stylized illustrations or clearly non-photorealistic representations of humans. The “photorealistic” threshold is doing a lot of work in the policy language, and Amazon’s automated classifiers aren’t perfectly calibrated on that boundary. Sellers operating in that gray zone should err on the side of disclosure rather than risk an enforcement action for non-disclosure.

    The Disclosure Requirement vs. The Detection Problem

    Here is where the situation becomes operationally complicated. Amazon requires disclosure for AI-generated images. Amazon also runs an automated AI image detection system to identify undisclosed AI-generated content. But the detector is imperfect — it produces false positives on human photography and false negatives on high-quality AI-generated imagery that successfully mimics photographic characteristics.

    And the penalties for failing to disclose are more severe than for failing to meet technical specifications. Non-compliant technical specifications typically result in listing suppression pending correction. Failure to disclose AI-generated synthetic performers can result in listing removal, Account Health violations, and in cases involving repeated or deliberately deceptive non-disclosure, account-level consequences. The stakes are asymmetric, and sellers using generative AI tools in their creative workflows need to have explicit disclosure protocols in their production process — not as an afterthought, but as a documented, mandatory step.

    What About Non-Human AI-Generated Elements?

    The current disclosure requirement specifically targets AI-generated people. AI-generated product backgrounds, AI-enhanced product imagery where the product itself is photographed conventionally, and AI-generated graphic design elements in secondary images are not currently subject to the same explicit disclosure mandate. However, Amazon’s compliance classifiers are increasingly sensitive to imagery that appears AI-generated broadly — and flagging rates are elevated for images with certain generative AI visual signatures, disclosure or not.

    The practical guidance for 2026 is to disclose anything involving photorealistic AI-generated humans, document your disclosure decisions as part of your production workflow, and remain aware that even non-human AI-generated content is under heightened automated scrutiny that may intensify as the regulatory landscape around synthetic media continues to evolve.

    Category-Specific Traps: Apparel, Electronics, and Regulated Products

    Amazon’s baseline image requirements apply universally, but each major category carries additional specifications and, importantly, different enforcement patterns. Three categories are responsible for a disproportionate share of compliance issues in 2026.

    Apparel: The Model Photography Complexity

    Apparel is the most complex category from an image compliance standpoint. The main image rules for apparel include category-specific exceptions: items must be shown on a human model for certain garment types, with the model standing upright (not seated), facing forward, against a pure white background. Flat-lay photography is permitted for some subcategories but not others, and the rules about which approach is acceptable have been a moving target.

    In 2026, the intersection of apparel image requirements and AI-generated model policies has created a particularly fraught environment. Brands that were using AI-generated models to reduce photography costs — a widespread practice given the significant expense of professional model photography — now face both the technical requirements for compliant apparel imagery and the disclosure requirements for synthetic performers. Many are simultaneously navigating suppression risk on both fronts while determining what compliant AI-model disclosure looks like at catalog scale.

    Additionally, variation images in apparel listings must accurately represent the specific color and style variation being displayed. A parent listing with 12 color variations requires 12 sets of compliant, variation-specific images. Sellers who have been using a single set of images across variations — or who have orphaned images from discontinued colors still attached to the listing — are particularly vulnerable to automated flagging under the current enforcement environment.

    Electronics: Technical Accuracy Requirements

    Electronics listings face a different set of traps. Amazon’s compliance systems increasingly check whether product images for electronics accurately represent what’s included in the box. Images showing accessories, cables, or companion products that are not included in the specific ASIN are flagged for misleading representation — an issue that has always existed in the policy but is now being enforced algorithmically rather than through complaint-based review.

    The challenge for electronics sellers is that product images frequently need to convey scale, connection type, or compatibility context — information that’s genuinely useful to buyers but which may require showing the product in a context that suggests inclusion of items not actually in the box. Navigating this requires careful attention to how secondary images are framed, using contextual imagery that communicates feature information without implying product scope that doesn’t match the specific ASIN’s contents.

    Regulated Products: The Packaging Compliance Layer

    Perhaps the most underappreciated compliance requirement in 2026 is the packaging image requirement for regulated product categories. Products in categories including dietary supplements, topical products, over-the-counter health items, and certain food products must now include images that show all sides of the packaging with visible safety warnings, ingredient lists, usage instructions, and regulatory compliance information.

    This requirement exists not just as a listing policy but as a verification mechanism — Amazon uses packaging images to confirm that the product as listed matches regulatory standards. Missing or obscured packaging information can trigger a compliance review that goes beyond image suppression into product authenticity and regulatory compliance territory. For sellers in these categories, the packaging image isn’t just a sales asset; it’s part of the compliance documentation record that Amazon can reference in any regulatory inquiry about the product.

    What Suppression Actually Costs: The Revenue Math

    The business case for investing in proactive image compliance rests on understanding what suppression actually costs. The numbers are sobering, and they scale in ways that many sellers don’t fully model until they’ve experienced a suppression event firsthand.

    Amazon listing suppression revenue impact 2026 — daily revenue chart dropping post-suppression, 30-50% visibility drop, 25-30% conversion loss, up to $5,000 per image fine

    Direct Revenue Loss During Suppression

    When an ASIN is suppressed, it disappears from organic search results. Customers searching for the product won’t find it through search — only through direct URL access, which accounts for a small fraction of product discovery on Amazon. Industry data from 2026 marketplace analyses suggests that suppressed listings experience visibility drops of 30–50% depending on the category and the product’s typical traffic mix between organic search, browse, and advertising.

    With 30–50% less visibility comes corresponding revenue loss. For a product generating $5,000 per month in organic revenue, a week-long suppression represents $875–$1,250 in direct lost sales. For high-velocity products generating $50,000 or more monthly, a seven-day suppression can cost $8,750–$12,500 in revenue alone. Documented industry cases show six-figure revenue impacts from suppression events affecting a small number of top-performing ASINs at peak season timing.

    The Conversion Rate Damage That Persists After Reinstatement

    Beyond the direct revenue loss during suppression, there is a secondary impact that persists after the listing is reinstated. Amazon’s A10 algorithm uses recent sales velocity as a ranking signal. A suppression event reduces sales velocity to zero (or near-zero) for the duration, which depresses the ranking signal for weeks after the listing is reinstated. The visibility loss compounds: you lose rank while suppressed, and rebuilding that rank after reinstatement requires sustained sales performance that is harder to achieve from a degraded position.

    Additionally, listings returning from suppression experience a temporary decline in conversion because any review and sales momentum that accumulated during the suppression period has less weight in the algorithm’s freshness calculations. The total effective revenue impact of a suppression event — accounting for both direct lost sales and the post-reinstatement rank recovery period — is typically 1.5–2x the direct revenue figure alone.

    The $5,000 Per-Image Fine Exposure

    For AI-generated image compliance specifically, the financial risk extends beyond revenue loss to actual fines. Amazon’s enforcement framework for AI-generated image violations — particularly non-disclosed synthetic performers — includes per-image financial penalties of up to $5,000. A seller with even a modest catalog who has been using AI-generated model imagery without proper disclosure could face fines that dwarf the production cost savings that motivated the AI approach in the first place.

    The practical risk depends on the severity and repetition of violations — a first-time, self-reported disclosure miss handled proactively through the appeals channel is unlikely to result in a maximum fine. A pattern of non-disclosure across a large catalog, or a case where non-disclosure appears intentional rather than inadvertent, is a different matter entirely. The financial exposure is real and worth taking seriously in the design of your creative production process.

    Ad Spend Waste During Suppression

    One cost that sellers frequently overlook in their suppression calculus is advertising spend. If you’re running Sponsored Products campaigns targeting a suppressed ASIN, those campaigns can continue running in some configurations even when the listing is suppressed from organic search. Ad impressions may decline along with organic visibility, but campaigns can remain active and continue consuming budget against an ASIN that cannot convert. Depending on your campaign structure and monitoring cadence, a suppression event you don’t catch for 48–72 hours can burn a meaningful portion of your advertising budget with zero return — adding to the total cost of the suppression event before you’ve even begun the remediation process.

    The Appeals Maze: Navigating the Account Health Flow in 2026

    When your listing is suppressed, the path to reinstatement runs through Amazon’s Account Health system. Understanding this process before you need it — rather than learning it under the pressure of an ongoing suppression event — dramatically improves outcomes and reduces the time your listing is out of commission.

    Where Suppressed Listings Show Up

    Image-related suppressions appear in Seller Central under two different locations, and which one you see first depends on the nature and severity of the violation:

    • Manage Inventory → Suppressed: The Suppressed tab in Manage Inventory shows listings that are not appearing in search due to policy violations, including image issues. This is often where sellers first discover a suppression, particularly for technical specification failures.
    • Performance → Account Health → Product Policy Compliance: More serious image violations — particularly those involving AI disclosure requirements, deceptive imagery, or repeat violations — appear in Account Health as formal policy issues requiring a structured Plan of Action rather than simple image correction.

    The distinction matters because the remediation path differs substantially. An image suppressed in Manage Inventory can often be resolved by uploading a corrected image and waiting for the system to re-scan. A formal Account Health policy violation requires a structured appeal with documentation, and failure to respond adequately can escalate the account health impact.

    The Plan of Action Structure That Actually Works

    For Account Health violations, sellers need to submit a Plan of Action (POA). The POA that succeeds in 2026 has three specific components that Amazon’s review system is calibrated to look for:

    1. Root cause acknowledgment: A specific, technical description of why the image was non-compliant — not a vague statement that you’re committed to compliance, but a precise statement of what was wrong. “The background had a shadow that measured RGB 242, 242, 242 rather than 255, 255, 255 due to studio lighting technique” is substantially more effective than “we failed to follow your guidelines.”
    2. Corrective action taken: Confirmation that the compliant image has already been uploaded, with specifics — file dimensions, background specification, how it was verified. Include a direct image URL if you can reference it from within the Seller Central environment.
    3. Preventive measures: A description of the process change you have made to prevent recurrence — whether that’s a pre-upload pixel-level background check, a new photography standard operating procedure, or a compliance review step added to your image production workflow. This section matters more than most sellers realize; Amazon’s reviewers are looking for evidence that you’ve changed your process, not just fixed this individual image.

    Timelines and Realistic Expectations

    Image suppression appeals that require only a technical correction and re-upload — where the issue is clearly a specification failure rather than a policy violation — typically resolve within 24–72 hours once the corrected image is submitted and rescanned. Account Health formal violations require human review and can take 7–14 days for a first response, with follow-up rounds potentially adding additional time to the resolution timeline.

    Amazon’s appeal system is not designed to fast-track cases where sellers believe they have been wrongly suppressed by a false positive. There is no escalation path that guarantees faster review for incorrect determinations. The practical implication: if you believe you’re experiencing a false positive, submit the appeal with your original image plus documentation that it meets the stated specifications (pixel-level background measurement, resolution confirmation, frame fill verification), then simultaneously prepare a corrected image that definitively meets spec. The fastest path to reinstatement is often to provide both — the appeal evidence and a definitively compliant alternative — rather than waiting for Amazon to reverse the false positive determination.

    When to Use the Brand Registry Advantage

    Sellers with Brand Registry status have access to additional escalation channels that general seller accounts do not. Brand Registry members can submit urgent image compliance issues through the Brand Registry support channel, which typically receives faster first response than the standard Account Health queue. If you’re experiencing a suppression on a high-revenue ASIN during a peak period, this channel — while not guaranteed to produce faster resolution — is worth using in parallel with the standard appeal process. Every hour of reinstatement time you can recover has direct revenue value at peak season.

    Building a Proactive Compliance Operation

    The sellers who minimize suppression risk in 2026 are not those who know the rules best — rule knowledge is table stakes. They are the sellers who have built operational systems that catch compliance issues before Amazon’s automated scanner does.

    Proactive Amazon image compliance audit workflow 2026 — five-step circular process from catalog export through remediation and evidence archiving

    Proactive Amazon image compliance audit workflow 2026 — five-step circular process from catalog export through remediation and evidence archiving

    The Audit Cadence That Matches Your Catalog Risk Profile

    Not every ASIN in your catalog carries equal risk or equal consequence from suppression. A compliance audit cadence should be calibrated to both the probability of violation and the revenue cost of suppression:

    • Weekly audit: Top 20% of ASINs by revenue. These are the listings where a suppression causes the most financial damage and where you want the shortest detection gap between a potential suppression and your response.
    • Monthly audit: Full catalog review for technical specification compliance — resolution, background pixel values, frame fill percentage. This catches images that may have been compliant under previous standards but are now vulnerable under updated enforcement thresholds.
    • Triggered audit: Any time Amazon announces a policy change or specification update, run an immediate targeted audit on the affected specification across the full catalog. The April 2026 resolution change, for example, should have triggered an immediate audit of all existing main images against the new 2,000×2,000 minimum. Many sellers who experienced suppression in that period had compliant images under the old standard and were caught by the transition.

    Pre-Upload Verification Tools

    Several third-party tools have emerged specifically to provide pre-submission Amazon image compliance checking. These tools simulate Amazon’s compliance checks — background pixel values, frame fill measurement, resolution, text/watermark detection — before you upload, allowing you to catch failures that would otherwise only surface after suppression has already occurred.

    The most effective implementations integrate these checks into the image production workflow itself, rather than as a final-step gate review. An image that fails a background check after a photographer has delivered it requires expensive and time-consuming rework. An image where the compliance check is part of the post-production specification — informing how the photographer lights, retouches, and exports — is far less likely to require remediation. The cost savings from preventing even a single suppression event on a high-revenue ASIN typically cover the cost of pre-upload verification tooling for the entire year.

    Documentation as Compliance Infrastructure

    In an environment where false positives occur and appeals require evidence, image documentation is a compliance asset. For every ASIN image you submit to Amazon, maintain an evidence record that includes:

    • The original image file (pre-compression, pre-upload processing)
    • Background pixel value measurements (screenshot of eyedropper reading from multiple background sample points)
    • Resolution confirmation from image metadata
    • Date of submission and submission status result
    • For AI-generated content: documentation of the generative tool used, the disclosure checkbox status at upload, and whether the image contains elements that qualify as synthetic performers

    This documentation takes perhaps two minutes per ASIN to create and maintain. In a false positive appeal scenario, it can mean the difference between reinstatement in 48 hours versus a multi-week appeals process. It is essentially an insurance premium with a near-certain payout whenever you need it.

    AI-Generated Content Governance

    If your creative workflow incorporates AI-generated imagery — whether for main images, secondary images, A+ content, or advertising materials — you need a formal governance process that tracks which images contain AI-generated elements and which specifically contain synthetic performers. This doesn’t need to be complex, but it needs to be systematic and auditable.

    A simple tracking system that logs ASIN, image type, AI generation status, presence of synthetic people, and disclosure submission confirmation is sufficient for most seller operations. Larger catalog operations may want this integrated with their product information management system or catalog database. The goal is to ensure that no AI-generated image containing photorealistic people reaches Amazon’s upload system without a documented disclosure decision attached to it — not because Amazon’s system will always catch it, but because the consequences of undisclosed synthetic performers are severe enough to warrant systematic rather than ad-hoc governance.

    The Asymmetry of Enforcement — and What Sellers Can Do About It

    It is worth naming directly what the current Amazon image compliance environment represents structurally: a significant asymmetry of power and accountability between Amazon’s enforcement system and the sellers it acts upon.

    Amazon Enforces; Sellers Respond

    Amazon’s automated system can suppress millions of listings in a quarter without human review, without prior warning, and without accountability for false positives. Sellers have no equivalent recourse. You cannot pre-audit your listing before Amazon’s system does. You cannot request a human review of your images before suppression. You cannot opt out of automated enforcement even if you have a strong historical compliance record.

    This is not an argument that image compliance standards are wrong — maintaining product image quality standards benefits the customer experience and the marketplace broadly. It is an observation that the current enforcement architecture imposes costs on sellers that include the error rate of the automated system, and that sellers have no mechanism to recover those costs from Amazon when the errors are on Amazon’s side. The design places all the risk of automated error on the seller population.

    Collective Pattern Recognition

    One practical response available to sellers is collective intelligence — tracking suppression patterns across the seller community to identify when Amazon’s enforcement algorithms appear to be misfiring systematically. Seller forums, agency networks, and marketplace analytics providers increasingly serve this function. When multiple sellers in the same category report simultaneous suppressions on images that appear compliant, it signals a potential algorithm update or classifier retrain that may be generating elevated false positive rates across a specific image type or category.

    Identifying these patterns quickly means sellers can escalate their appeals collectively — not as a formal organized action, but as a body of evidence that Amazon’s seller support teams can use to escalate internally. Amazon’s enforcement teams have responded to pattern-based reports in the past, particularly when a false positive appears to affect a broad category rather than individual listings.

    Build Compliance Margin Into Your Production Standards

    The sellers best positioned for the 2026 enforcement environment have built compliance costs explicitly into their production standards. Photography specifications that exceed Amazon’s minimums — targeting 2,500×2,500 images rather than 2,000×2,000, using background RGB values verified at 255,255,255 with multiple readings rather than approximate, retaining pre-submission pixel verification as a standard production step — cost more upfront but reduce suppression risk to near zero by providing buffer against the enforcement system’s sensitivity.

    The investment is a known, predictable cost. The alternative — running to minimum specification and absorbing occasional suppression events — is an unpredictable cost with a tail risk that, at the wrong moment, can exceed the entire compliance investment for a year. For high-velocity sellers generating meaningful monthly revenue from their catalog, this math strongly favors investing in compliance margin rather than operating at minimum specification and hoping the automated system’s error rate doesn’t catch you.

    Conclusion: Treating Compliance as a Catalog Asset

    Amazon’s image compliance enforcement in 2026 operates at a scale and speed that fundamentally changes what it means to manage a product catalog on the platform. The automated systems are genuinely powerful — and genuinely imperfect. They protect customers from misleading or low-quality product imagery while simultaneously suppressing compliant listings at a non-trivial error rate. The new legal requirements around AI-generated content have added a layer of complexity that will only grow as synthetic media regulation develops further.

    Understanding this environment clearly is the first step to operating within it safely. The sellers who are managing it well have made a fundamental mental shift: they no longer think of image compliance as a rules-following exercise. They think of it as catalog infrastructure — a permanent, managed operational discipline with defined specifications, verification records, documented audit histories, and governance processes for emerging content types.

    The specific actions that matter most in 2026:

    • Verify at the pixel level. Background compliance is not “looks white.” It is RGB 255,255,255, measured with tooling, verified with evidence, and maintained across the upload and compression process.
    • Update your resolution standard. 2,000×2,000 pixels is the new minimum effective April 2026. If your photography workflow isn’t producing at this resolution consistently, you’re accumulating suppression risk with every image in your catalog.
    • Build AI disclosure into your creative workflow. If your team uses generative AI tools to produce any imagery that includes photorealistic human elements, disclosure is not optional and not an afterthought. Make it a documented, mandatory step in your production process with a paper trail.
    • Audit proactively, not reactively. The sellers who discover compliance gaps before Amazon’s system acts on them have a fundamentally different risk profile than those who discover suppression events after revenue has already dropped.
    • Maintain evidence for every image. Pre-upload verification records reduce a potentially weeks-long false positive appeal to a 48-hour resolution. The documentation cost is trivial; the insurance value is substantial.
    • Know the appeals process before you need it. When suppression happens, the sellers who know exactly where to look, what to write, and what evidence to provide get reinstated faster than those learning the system under the financial pressure of an ongoing suppression.

    Amazon’s enforcement will continue to tighten. The automated systems will become more sensitive as the models are retrained and the specifications evolve. The penalty structures for AI-related violations will expand as legal frameworks around synthetic content develop across additional jurisdictions beyond New York. The sellers who build compliance into the DNA of their catalog operations now — rather than treating it as a periodic cleanup task — will be the ones still running strong when the next round of enforcement changes arrives.

  • The Seller’s Scientific Method: How to Run Image A/B Tests in Manage Your Experiments That Actually Mean Something

    The Seller’s Scientific Method: How to Run Image A/B Tests in Manage Your Experiments That Actually Mean Something

    Split-screen Amazon product image A/B test showing Version A white-background vs Version B lifestyle photo with conversion rate comparison bar chart

    Most Amazon sellers who run image experiments through Manage Your Experiments believe they’re doing science. They pick two photos, set a duration, watch the dashboard, and declare a winner. What they’re actually doing, in the vast majority of cases, is running an expensive opinion poll dressed up in data clothing.

    The difference between a test that produces a reliable, actionable insight and one that produces noise you act on anyway comes down to a handful of decisions made before the experiment launches. Hypothesis structure, variable isolation, traffic thresholds, duration discipline, and result interpretation — get those right, and a single image test can deliver a 10–25% conversion lift that holds. Get them wrong, and you’ll publish a “winner” that quietly underperforms for the next twelve months while you wonder what happened.

    This post is not a basic walkthrough of the Manage Your Experiments interface. It’s a discipline guide for using it correctly. We’re going to cover how the tool actually works under the hood, what eligibility really means in practice, how to design experiments that isolate signal from noise, how to read results without fooling yourself, and how to build a testing cadence that compounds over time. By the end, you’ll have a framework for turning image testing from a one-off tactic into a permanent, measurable competitive advantage.

    What Manage Your Experiments Actually Does Under the Hood

    Infographic showing Amazon Manage Your Experiments dashboard anatomy with 50/50 traffic split, conversion rate metrics, and statistical significance progress bar

    Understanding how the tool operates mechanically changes how you design and interpret tests. Manage Your Experiments (MYE) is Amazon’s native content experimentation platform, available exclusively to Brand Registry brand owners through Seller Central. When you launch an experiment, Amazon splits your eligible ASIN’s shopper traffic approximately 50/50 between two versions of a listing element — in the case of image tests, that means Version A shoppers see your current main image, and Version B shoppers see your challenger image.

    This split is applied at the session level, not the account or device level, meaning individual shoppers are randomly assigned to one variant for their session. Amazon does not publicly document the exact randomization algorithm, but expert consensus is that the split is consistent enough to be reliable across high-traffic ASINs over the recommended duration window.

    The Metrics MYE Reports

    The results dashboard surfaces the following metrics per variant: sample size (unique shoppers who saw each version), conversion rate, units ordered, total sales revenue, and units sold per visitor. For image tests specifically, click-through rate from search results is arguably the most critical upstream metric — a stronger main image drives more clicks, which flows into the rest of the funnel. However, CTR as a standalone metric in MYE is less prominently reported than conversion rate, which measures what happens after the shopper lands on the detail page.

    This is an important nuance. A main image change that lifts CTR but doesn’t lift conversion may still be a net positive from a traffic-acquisition standpoint, particularly if your organic rank benefits from improved click velocity. But MYE’s primary lens is conversion rate and units sold. Keep that in mind when framing your success criteria before you launch.

    How Statistical Significance Is Determined

    Amazon reports a probability score — essentially a confidence level that one version is genuinely outperforming the other, rather than the difference being random variation. The tool’s internal threshold for flagging a winner appears to sit around 66–70% confidence, which is substantially lower than the 90–95% confidence standard used in rigorous statistical practice. This matters enormously. Amazon may signal a result as meaningful while the actual evidence would not meet the standard applied in an academic or enterprise CRO context.

    If you’re treating the tool’s built-in significance flag as gospel, you’re operating on a lower evidentiary threshold than you probably realize. Experienced sellers add their own filter: they look for probability scores above 90% before acting on a result, and they treat anything below that as directional — interesting information that warrants a follow-up test, not a publishing decision.

    MYE also offers a “Run to Significance” setting, where Amazon automatically ends the test once it judges enough data has been collected. This is convenient, but it puts the significance threshold decision in Amazon’s hands rather than yours. More on that later.

    Eligibility Reality Check: Who Can Actually Run These Tests

    Before designing your first experiment, you need to confirm you’re eligible — and eligibility is more restrictive than Amazon’s marketing language implies. The two hard requirements are Brand Registry enrollment and sufficient ASIN traffic. Meeting one without the other means no experiments.

    Brand Registry Requirements

    You must be the brand owner enrolled in Amazon Brand Registry with an active registered trademark in the marketplace where you want to experiment. Generic resellers, wholesale accounts, and arbitrage sellers are categorically excluded. The brand owner designation must be tied to the selling account running the experiment — you cannot run experiments on behalf of a brand through an unaffiliated account. A Professional selling plan is also required; individual plan accounts cannot access MYE.

    If you manage multiple brands or brand entities, each requires its own Brand Registry enrollment. Experiments are brand-specific and cannot be run across brands in the same account without separate enrollments.

    Traffic Thresholds: The Number Amazon Won’t Officially State

    Amazon does not publish a precise minimum traffic threshold for MYE eligibility, but the practical consensus among sellers and tools teams in 2026 is approximately 1,000 detail page views in the last 30 days as the floor. Some sellers report eligibility at slightly lower volumes; others report ineligibility well above that number depending on category and order velocity.

    The reason traffic matters isn’t just eligibility — it’s result reliability. An ASIN with 500 monthly sessions will take significantly longer to accumulate the sample size needed for a statistically valid result, often far exceeding Amazon’s maximum experiment duration. The tool will technically run the experiment, but the result will be inconclusive. In practice, ASINs with fewer than 1,000–1,500 monthly detail page views should not be prioritized for MYE image testing. Your effort is better spent on traffic acquisition first.

    What Happens When You’re Not Eligible

    If an ASIN doesn’t appear in your MYE experiment setup, it’s almost always a traffic issue rather than a product category restriction. The solution isn’t to try to force the experiment — it’s to run sponsored ads to build sufficient organic and paid session volume, then revisit eligibility in 60–90 days. Running experiments on artificially traffic-boosted ASINs introduces its own confounds (paid traffic behaves differently than organic), so the target should be consistent organic session velocity before you test.

    Building a Real Hypothesis Before You Touch Seller Central

    Scientific hypothesis framework diagram showing IF-THEN-BECAUSE structure for Amazon product image A/B testing

    The single most common reason image tests produce ambiguous results is that they begin with a vague question rather than a falsifiable hypothesis. “Let’s see if the lifestyle photo does better” is not a hypothesis. It’s a guess. A real hypothesis specifies what you’re changing, what you expect to happen, why you expect it, and how you’ll measure it.

    The IF-THEN-BECAUSE Framework

    The most practical hypothesis structure for image testing follows a three-part format:

    • IF we change [specific image element] from [Version A description] to [Version B description]
    • THEN we expect [specific metric] to [increase/decrease] by [approximate magnitude]
    • BECAUSE [the mechanism — why this change should produce this effect]

    For example: “If we change the main hero image from a white-background studio shot to a lifestyle image showing the product in use in a kitchen, then we expect click-through rate and conversion rate to increase by 10–20%, because shoppers searching for this type of product respond to contextual use-case imagery that helps them visualize the product in their own environment.”

    That’s a testable, documented hypothesis. You’ve committed to a mechanism, a metric, and an approximate magnitude before seeing any data. This matters because it prevents you from retroactively reframing results to fit whatever the data shows.

    One Variable Per Experiment, Without Exception

    The temptation to “improve” a challenger image by also adjusting the background, changing the angle, and updating the props is constant — and must be resisted. Every element you change in Version B beyond the one variable you’re testing becomes a potential explanation for any difference in results. If you change three things and Version B wins by 15%, you don’t know which of the three things drove the lift. You can’t replicate it. You can’t learn from it. You’ve wasted 8–10 weeks of live traffic.

    The practical rule: Version B should differ from Version A in exactly one meaningful way. If you’re testing white background versus lifestyle context, every other element — product size in frame, lighting quality, image resolution, angle — should be as consistent as possible. This is harder than it sounds. It requires briefing your photographer or AI image tool with precision, and it requires reviewing the two variants side by side with a checklist before launching.

    Defining Success Before You Start

    You should also define your minimum meaningful effect size — the smallest lift that would make publishing the winning variant worthwhile — before the experiment runs. This prevents the common mistake of declaring a 1.5% conversion lift as a meaningful win when the test-to-action cost (photography, setup time, opportunity cost) required a 5% lift to justify the effort. Document it. Lock it in. Don’t move it.

    Which Image Variables to Test First — and In What Order

    Image Testing Priority Pyramid showing main hero image at top with high CTR impact down through secondary images, infographic callouts, and lifestyle shots

    Not all image variables carry equal weight, and testing them in the wrong order wastes testing cycles. The priority sequence should follow the shopper’s decision path — from the first impression in search results to the deeper-dive content on the detail page.

    Tier 1: The Main Hero Image

    The main image is the highest-leverage test you can run, and it should almost always be first. It’s the only image shoppers see in search results, on category browse pages, and in sponsored ad placements. A stronger main image lifts CTR from every entry point, and CTR feeds into organic ranking velocity. The downstream effect of a better main image compounds far beyond the conversion rate lift measured in MYE alone.

    The most productive main image tests in 2026 fall into these categories:

    • Background context: Pure white background vs. a subtle environmental context (kitchen counter, desk surface, outdoor terrain — appropriate to the product’s use case)
    • Product scale: Full product visible vs. cropped to show detail; product filling 75% of frame vs. 85% of frame
    • Product orientation: Front-facing vs. slight 3/4 angle to show dimensionality
    • Packaging vs. product: Showing the retail packaging vs. the bare product — relevant for supplement, cosmetic, and food categories
    • Use-in-hand vs. standalone: Product held by a hand or in use vs. floating on its own

    Documented results from main image tests vary widely depending on the quality of the original image, but typical conversion lifts range from 8–25%, with well-designed tests on weak originals occasionally reaching 30% or more. A case study from the UK marketplace showed a main image change lifting conversion from 21% to 24% — a 14% relative improvement — driving a 35.5% month-over-month sales increase and a 67% net profit gain on that ASIN.

    Tier 2: Secondary Images and Their Role in Conversion

    Once your main image is optimized, secondary images (image slots 2–7) become the primary lever for the on-page conversion rate — what happens after the shopper arrives. Secondary images serve a different function than the main image: they answer questions, overcome objections, demonstrate scale and use, and build purchase confidence.

    Testable secondary image variables include:

    • Feature infographic vs. lifestyle photo in position 2 — does the shopper want to see features annotated on the product, or do they want to see it in use?
    • Size/scale comparison image (product next to a common object) vs. a dimensions diagram
    • Social proof image (star rating callout, review count banner) vs. a materials/ingredients breakdown
    • Before/after or use-case sequence vs. a single use-case lifestyle shot

    Secondary image tests tend to produce smaller lift magnitudes than main image tests — typically 5–15% conversion improvement — but they’re still highly valuable, particularly for complex products where shoppers need information before converting.

    Tier 3: A+ Content Images

    MYE also allows testing of A+ Content, which includes the module-based enhanced content images below the fold. These tests are best run after main and secondary image optimization is complete, since A+ content is seen by fewer shoppers (those who scroll far enough to reach it) and has a lower per-impression impact than above-the-fold elements. However, for high-involvement purchase decisions — electronics, furniture, fitness equipment, health products — A+ content images can meaningfully influence the final conversion decision and are worth testing systematically.

    Sample Size, Duration, and the Traffic Threshold You Cannot Ignore

    Graph showing statistical confidence building over experiment weeks with danger zone in weeks 1-4 and safe decision zone in weeks 7-10 for Amazon A/B testing

    The duration and sample size question is where most seller-run experiments fail silently. The test completes, a result appears on the dashboard, and a decision is made — but the data underlying that decision was never sufficient to produce a reliable result in the first place.

    Why 8–10 Weeks Is the Standard

    Amazon’s own guidance for MYE experiment duration is 8–10 weeks for most tests. This is not arbitrary. Several statistical realities make shorter durations unreliable for most Amazon ASINs:

    Day-of-week variance: Amazon shopper behavior varies systematically by day of the week. Weekend browsers behave differently from weekday buyers. A test that runs for only 2–3 weeks may have disproportionate exposure to certain days depending on when it launched, skewing results. A full 8-week run captures approximately 8 complete weekly cycles, washing out day-of-week noise.

    Novelty effects: A new image variant may receive an initial boost (or drag) from algorithm freshness effects. Running long enough allows novelty to dissipate and genuine performance to emerge.

    Sample size accumulation: Statistical reliability requires a minimum sample size per variant. The rule of thumb for Amazon image tests is approximately 1,000 sessions per variant per week. An ASIN generating 2,000 total weekly sessions (1,000 per variant) needs a full 8–10 weeks to accumulate 8,000–10,000 sessions per variant — a robust sample for conversion rate testing. Lower-traffic ASINs need proportionally longer, but since Amazon caps experiment duration, low-traffic tests may end before reaching adequate sample size.

    The “Run to Significance” Setting: Convenient, But Not Risk-Free

    Amazon’s “Run to Significance” option automatically ends the experiment when it judges sufficient data has been collected. This is useful for sellers who don’t want to monitor duration manually, but it comes with one significant caveat: Amazon’s internal significance threshold is lower than best-practice standards. The tool may end a test and call a winner at 66–70% confidence, which means there’s a 30–34% probability the declared winner is actually a false positive.

    For sellers running high-stakes tests on their primary revenue ASINs, the recommendation is to set a fixed 8–10 week duration rather than relying on “Run to Significance,” and to apply your own 90%+ confidence filter when reviewing results. For lower-stakes exploratory tests, “Run to Significance” is an acceptable shortcut.

    What Happens When Your ASIN Doesn’t Have Enough Traffic

    If your ASIN generates fewer than 1,000 sessions per week, you have a few options. First, you can drive additional paid traffic during the test period through Sponsored Products campaigns — but this introduces a confound, since paid traffic converts differently than organic traffic. The results from a traffic-boosted test should be interpreted with caution and validated post-publication. Second, you can wait until the ASIN has built more organic velocity before testing. Third, you can run the test knowing that the result will be directional rather than definitive, and plan a follow-up confirmatory test once traffic has grown. The worst option is to run the test, see any result, and treat it as ground truth regardless of sample size.

    Reading MYE Results Without Fooling Yourself

    Dashboard showing three common Amazon MYE result misinterpretations: the peeking problem, seasonality confound, and projected impact trap

    The results dashboard in MYE is designed to be readable by sellers with no statistical training. That’s both its strength and its primary failure point. The simplification required to make results accessible also strips away the nuance needed to interpret them correctly.

    The Peeking Problem: Why Early Results Are Almost Always Wrong

    The most destructive habit in experiment management is checking results while the test is running and acting on what you see. Early data in any A/B test is inherently volatile. With small accumulated sample sizes, random variation produces dramatic-looking differences that smooth out as more data accumulates. Version B might appear to be winning by 20% at week 2 and be statistically indistinguishable from Version A by week 6.

    The statistical term for the distortion caused by monitoring and potentially stopping tests early is “peeking,” and it’s one of the most well-documented sources of false positives in experimentation science. Amazon’s own documentation warns against ending tests early, but the visual of an apparent “winner” on the dashboard is compelling enough that many sellers can’t resist.

    The practical discipline: set your experiment, lock your review date for the day it completes, and do not look at interim results with intent to act on them. Check that the experiment is running (not paused), and that’s the extent of your mid-experiment engagement.

    The Confidence Score: What Each Level Actually Tells You

    When reviewing results, the confidence score (probability that one version is better) should be your first filter, applied before you consider any of the headline metrics:

    • Below 70%: No meaningful signal. The result is effectively a coin flip. Do not publish based on this result. Either extend the test or treat it as inconclusive.
    • 70–89%: Directional signal only. One version appears to be performing better, but the evidence isn’t strong enough for a high-confidence publishing decision. Consider this informative for future hypothesis design, not actionable as a standalone result.
    • 90–95%+: Reliable enough to act on for most business decisions. Publish the winner with reasonable confidence that the lift is real. Validate performance in the 4–6 weeks post-publication.
    • 95%+: Strong evidence. Act on this result with confidence. Document it as a high-quality data point for your testing knowledge base.

    Which Metrics to Prioritize in Image Tests

    Not all metrics reported in MYE carry equal weight for image experiments. Here’s how to prioritize them:

    Primary: Units ordered and conversion rate. These are the most direct measures of whether your image change influenced purchase behavior. Units ordered accounts for volume differences; conversion rate accounts for traffic differences between variants.

    Secondary: Sales revenue. Revenue is useful for understanding dollar impact, but it can be skewed by price variation, promotional discounts applied during the test period, or add-on item purchases. Weight it less heavily than units ordered.

    Tertiary: Units per visitor. This metric captures whether a single session tends to result in a multi-unit purchase, which is relevant for consumable and bundled products but less meaningful for single-unit durables.

    Return rate and review velocity are not directly reported in MYE but should be monitored in your broader analytics for the 60 days following a winning image publication. A new image that increases conversions but also increases return rates (because the product doesn’t match what the image implied) is a net negative that MYE’s dashboard won’t flag.

    The “Projected One-Year Impact” Number: What It Means and What It Doesn’t

    When an experiment completes with a clear winner, MYE displays a “Projected one-year impact” figure — a Most Likely, Best Case, and Worst Case estimate of how much additional annual revenue and units you’d gain by publishing the winning version. This number is frequently misunderstood, and that misunderstanding leads to poor business decisions.

    How the Number Is Calculated

    The projected one-year impact is not a demand forecast. It’s a mechanical extrapolation: Amazon takes the average daily difference in units sold between the winning and losing variant during the test period, multiplies it by 365, and presents that as the annual impact under various scenarios. There is no seasonality modeling, no accounting for pricing changes, no adjustment for competitive dynamics, and no consideration of whether the test-period traffic is representative of annual traffic patterns.

    If your test ran during Q4 — when most categories see peak demand — the extrapolation will wildly overestimate annual impact. If it ran during a slow period, it will underestimate. The number is directionally useful as an order-of-magnitude sense check, but it should never be used for financial planning, board presentations, or resource allocation decisions without significant manual adjustment.

    Applying the Number Correctly

    The right way to use the projected impact figure: treat it as a rough signal for prioritizing which winning variants to publish first when you have multiple concluded tests waiting for action. A test showing a projected impact of $180,000 should generally be published before one showing $12,000, all else being equal. The relative ranking of tests by projected impact is more meaningful than any individual number’s absolute value.

    Also note: the Best Case scenario in MYE’s projected impact display tends to assume conditions that are rarely sustained. Use the Most Likely figure, apply your own seasonality discount or premium based on when the test ran, and treat the result as a directional indicator rather than a precise forecast.

    Confounds That Corrupt Your Experiment — and How to Avoid Them

    Even a well-designed experiment can produce unreliable results if external factors create asymmetric conditions for the two variants during the test period. These confounds are the second most common reason image tests fail to deliver usable insights.

    Pricing Changes Mid-Test

    Any price change applied to your ASIN during an active experiment contaminates the results. Price is the most powerful conversion lever on Amazon — a 10% price reduction will almost always produce a conversion lift that dwarfs any image-driven effect. If you change price mid-test, stop the experiment, discard the data, and restart once price has stabilized for at least two weeks.

    Similarly, coupons, deals, and lightning deal activations during the test period introduce conversion spikes that are impossible to disentangle from image effects. Schedule experiments to avoid planned promotional periods, and if an unplanned promotion runs during your experiment window, note it explicitly and discount the result accordingly.

    Inventory and Buy Box Disruptions

    Going out of stock for even a day during a test period corrupts the data for the variant that was running when the stockout hit. Likewise, losing the Buy Box to a competitor for any portion of the test window means a fraction of your “sessions” during that period saw a different purchasing experience than usual. Monitor inventory and Buy Box ownership daily during active experiments and pause the experiment immediately if either condition occurs.

    Seasonal Demand Shifts

    Avoid starting image tests within 3 weeks of major shopping events (Prime Day, Black Friday, Cyber Monday, back-to-school peaks, holiday ramp-up). The traffic composition, intent level, and conversion propensity of shoppers during these periods is substantially different from typical weeks. If an experiment straddles a seasonal event, the data from those weeks should be weighted down when interpreting results — or the experiment should simply be extended to ensure an equal amount of non-peak data on both sides of the event.

    Concurrent Listing Changes

    This is the most commonly violated discipline in real-world testing. During an active image experiment, do not change your title, bullet points, description, A+ content, back-end keywords, pricing, or any other listing element. Any concurrent change creates a new confound that prevents you from attributing result differences to the image variable under test. If you need to make a critical listing change during an active experiment, pause the experiment first, make the change, allow the listing to stabilize for one week, then restart — resetting the clock.

    What to Do After a Winner: The Iteration Roadmap

    Post-experiment iteration roadmap showing five milestones from publishing winner through validating lift, documenting learnings, forming next hypothesis, and testing next ASIN

    Declaring a winner and hitting publish is the halfway point of a useful experiment, not the finish line. The real value of systematic image testing accrues over multiple test iterations, as each experiment generates learnings that sharpen the next hypothesis and raise the hit rate of future tests.

    Step 1: Publish and Validate

    When you have a high-confidence winner (90%+ confidence score, positive result on units ordered), publish the winning variant immediately. Then monitor real-world performance for the next 4–6 weeks without running another image experiment on the same ASIN. Look at: conversion rate in your Business Reports, session-to-order ratio, return rate, and any change in organic ranking position. If the published winner produces the expected lift in organic data, the result is validated. If performance reverts or deteriorates, you may be seeing a novelty effect wearing off, or the test result may have been a false positive — both of which are actionable learnings.

    Step 2: Document the Why

    The most underused practice in seller-run experimentation is documentation. After publishing a winner, write down: what you tested, what the hypothesis was, what the result was (including the confidence score and magnitude), and your interpretation of why the winner performed better. This doesn’t need to be elaborate — a shared spreadsheet with six fields per test is sufficient. Over time, this knowledge base becomes one of your brand’s most valuable assets: a proprietary library of what works for your specific customers in your specific category.

    Patterns emerge from documented experiments that aren’t visible from individual tests. You may find that lifestyle images consistently outperform white-background shots in your category, but only when the lifestyle context matches your primary customer’s age demographic. You may find that infographic-style images with text callouts lift conversion for male shoppers but underperform for female shoppers browsing the same ASIN. These insights require multiple tests and good documentation to surface.

    Step 3: Form the Next Hypothesis

    A completed test — win or loss — always generates a next question. If lifestyle beat white-background, the next question is: which lifestyle context works best? Indoor vs. outdoor? Solo use vs. group use? Morning vs. evening context? If the challenger lost, ask why: was the image quality technically inferior? Did the lifestyle context not match the customer’s self-image? Did the product look smaller or less premium in context?

    Each answered hypothesis narrows the search space for future tests. Within 3–4 image test cycles on a single high-traffic ASIN, you’ll typically find that your original main image was leaving somewhere between 15% and 40% of conversion performance on the table — and that the gains from systematic testing accumulate to a meaningfully different business outcome than you started with.

    Research indicates that sellers who run deliberate, well-structured image tests over 12 months on their core ASINs see cumulative conversion improvements of 30–80% relative to where they started. That’s not a single test result — it’s the compounded effect of sequential hypothesis-driven experiments, each building on the last.

    Step 4: Expand to the Next ASIN or Element

    Once your primary ASIN’s main image is optimized and you’ve documented the learnings, the playbook branches in two directions. First, apply what you’ve learned about image type preferences to your next highest-traffic ASINs — often the winning insight from ASIN 1 translates well enough to ASIN 2 and 3 that you can launch with a higher-confidence hypothesis and see faster results. Second, move to the next listing element on your primary ASIN: secondary images, then A+ content, then title. Each element has its own optimization ceiling, and working through them systematically compounds the total listing performance improvement.

    Building a Testing Cadence Across Your Catalog

    Individual tests are tactical. A testing cadence is strategic. The brands that make image testing a genuine competitive advantage aren’t running one experiment per quarter — they’re running three to six simultaneous experiments across their catalog, with a structured pipeline of hypotheses queued up, and a review rhythm that keeps the organization learning continuously.

    Building the Experiment Pipeline

    A practical cadence for a mid-sized brand with 20–50 active ASINs looks like this: at any given time, 3–5 ASINs are in active experiments. Another 5–8 ASINs are in the hypothesis development phase (images being designed or ordered). Another 3–5 ASINs are in the post-experiment validation window. The rest are either ineligible (insufficient traffic) or in a maintenance phase where they’ve been tested and optimized to a sufficient degree.

    This means roughly one new experiment launching per week, one concluding per week, and continuous data flowing into your testing knowledge base. At that cadence, a brand with 30 eligible ASINs can run 4–5 complete test cycles per year on its primary products — enough to produce a substantial cumulative optimization effect.

    Prioritizing Which ASINs to Test First

    Not all ASINs deserve equal testing attention. Prioritize using a simple matrix:

    1. Revenue contribution: ASINs that generate the most revenue have the highest upside from conversion improvement. A 15% lift on a $500,000/year ASIN is worth more than a 15% lift on a $20,000/year ASIN.
    2. Traffic volume: High-traffic ASINs generate reliable results faster, reducing the cost of experimentation in time and opportunity cost.
    3. Current conversion rate: An ASIN converting at 8% when the category average is 12% is a high-priority target — there’s a clear gap suggesting the current image may be underperforming relative to opportunity.
    4. Image quality baseline: ASINs with visibly dated, technically poor, or unoptimized main images have the most headroom for improvement and tend to produce the strongest test wins.

    When to Stop Testing a Specific Variable

    Testing has diminishing returns. After 3–4 rounds of main image testing on a single ASIN where results have been inconclusive or where marginal differences are shrinking, it’s reasonable to conclude that the current main image is near its optimization ceiling for this variable type and shift testing attention to other elements or other ASINs. The signal that you’ve reached this point: multiple consecutive tests showing no statistically significant difference between variants that are meaningfully different from each other.

    This is actually a useful result. Knowing that your main image is well-optimized for your category allows you to invest creative resources elsewhere with confidence that you’re not leaving easy wins behind.

    Integrating MYE Data with Your Broader Analytics Stack

    MYE results are most valuable when cross-referenced with data from Brand Analytics, your advertising console, and third-party tools that track organic ranking and search visibility. A main image that lifts MYE-measured conversion rate should also produce measurable downstream effects: improved organic ranking (as higher click-through signals to Amazon’s algorithm), lower ACoS on Sponsored Products (as the same ad spend converts at a higher rate on the improved listing), and improved return on ad spend overall.

    If a winning MYE experiment doesn’t produce observable downstream improvements in these broader metrics within 60 days of publication, treat the result with additional skepticism. Either the lift was a false positive, or other factors (pricing, competition, seasonality) are suppressing the gains. Either way, that’s a signal to investigate further rather than simply accepting the MYE result at face value.

    Making Scientific Testing a Permanent Competitive Edge

    Image testing through Manage Your Experiments is one of the few areas of Amazon seller optimization where disciplined process and rigorous methodology produce substantially better outcomes than intuition alone. The tool is available to every eligible brand. The traffic is already flowing. The data is already being generated. The only question is whether you capture it systematically or let it pass unused.

    The brands that win with image testing don’t have better creative instincts than everyone else — though strong creative judgment helps. They win because they’ve built a process that converts every test, win or loss, into a piece of organizational knowledge that makes the next test faster, better-calibrated, and more likely to produce a meaningful result. Over time, that compounding effect creates a catalog that’s demonstrably better optimized than competitors who are still changing images based on opinion and gut feel.

    The core discipline is straightforward, even if execution requires consistency:

    • Write a falsifiable hypothesis before every test
    • Change one variable per experiment, no exceptions
    • Run every test for a minimum of 8 weeks with adequate traffic
    • Apply a 90%+ confidence filter before acting on any result
    • Document wins, losses, and the reasoning behind each
    • Never change other listing elements during an active experiment
    • Validate real-world performance for 4–6 weeks after publishing a winner
    • Use each result to sharpen the next hypothesis, not just to justify a publishing decision

    Run that process consistently across your catalog for twelve months, and the cumulative effect — 30–80% improvement in conversion rate on optimized ASINs, stronger organic ranking driven by improved click signals, lower cost per acquisition across paid campaigns — will be visible in your P&L in ways that no single test could achieve on its own.

    The test is not the strategy. The testing system is the strategy.

  • ChatGPT Work and Claude Managed Agents: How Two Competing Visions of the AI Coworker Are Playing Out in Production

    ChatGPT Work and Claude Managed Agents: How Two Competing Visions of the AI Coworker Are Playing Out in Production

    ChatGPT Work vs Claude Managed Agents: two competing visions of the AI coworker in 2026

    When OpenAI launched ChatGPT Work on July 9, 2026, it crystallised a question that enterprise teams had been quietly wrestling with for months: what does it actually mean for an AI to do your work, rather than just assist with it?

    The distinction sounds semantic. It isn’t. “Assistance” means a human-in-the-loop at every decision. “Work” means the agent takes a goal, figures out the steps, gathers the data from across your connected apps, and hands you a finished output — a report, a spreadsheet, a slide deck, a web app. The human re-enters at the end to review, not at every juncture to steer.

    That shift from assistant to executor is what both OpenAI and Anthropic have been racing toward in 2026. And while their public messaging occasionally sounds interchangeable — “autonomous agents,” “orchestrated workflows,” “AI coworkers” — the two platforms are making fundamentally different architectural bets. ChatGPT Work is a cloud-native, cross-SaaS output machine. Claude Managed Agents are evolving into a hosted control plane for memory, evaluation, and multi-agent delegation.

    Neither is universally better. But they are genuinely different, and choosing between them (or combining them) without understanding those differences is how organisations end up with expensive pilots that don’t survive contact with real workflows.

    This article unpacks both platforms in detail — what they are, how they’re built, where the production evidence is strongest, and what your team needs to get right before trusting either with consequential work.

    What ChatGPT Work Actually Is (And What It Isn’t)

    ChatGPT Work is not a new model. It is a new mode — a third interface surface inside ChatGPT alongside Chat and Codex, powered by GPT-5.6 and designed specifically for outcome-driven execution rather than turn-by-turn conversation.

    The operative word in OpenAI’s positioning is “finished.” You give Work a goal — “prepare a competitive analysis of our three main rivals using our internal sales data, our CRM, and recent news sources” — and it comes back with a finished artifact: a formatted document, a populated spreadsheet, a set of slides, or a small web application. It is not asking you which rival to start with. It is not checking in after every paragraph. It is doing the work.

    How the App Connection Layer Works

    The engine behind this is ChatGPT’s connector ecosystem, which by mid-2026 had extended to Microsoft 365, Google Workspace (Drive, Docs, Sheets, Gmail, Calendar), Slack, Notion, GitHub, and a growing set of third-party integrations. Work pulls from these sources, synthesises across them, and writes back to them as appropriate.

    That cross-app reach is what separates Work from a simple document generator. A typical multi-step task might involve pulling a brief from Notion, finding relevant past research in Google Drive, cross-referencing recent email threads in Gmail, running analysis code via Codex, and assembling the output into a Google Doc — all without a human directing each handoff.

    Workspace Agents: The Team-Level Layer

    Alongside Work, OpenAI simultaneously moved Workspace Agents to general availability in Business, Enterprise, and Edu plans. Workspace Agents are reusable, shareable agents that an admin configures once and teams can invoke repeatedly. Where Work is user-level and ad hoc, Workspace Agents are org-level and repeatable.

    Think of the difference this way: a user spinning up Work to draft a one-off competitive brief is using Work. A sales team that has a standing “weekly account intelligence” agent that runs every Monday morning, pulls from the CRM and LinkedIn, and drops a formatted summary into Slack — that is a Workspace Agent.

    The two tiers are complementary, and most enterprise deployments will end up using both: Work for complex, varied, individual tasks, and Workspace Agents for high-frequency, standardised workflow automation.

    What It Isn’t

    ChatGPT Work is not a persistent-memory system in the Anthropic sense (more on that shortly). It does not have a native mechanism for an agent to review its own past sessions and get smarter over time. It does not natively support hierarchical multi-agent delegation — a coordinator agent spinning up specialist subagents for different parts of a complex task. And it is not currently the strongest tool for heavily regulated, compliance-sensitive environments where auditability of each reasoning step matters as much as the quality of the output.

    ChatGPT Work architecture: cloud-native app-connected orchestration across SaaS tools

    Claude Managed Agents: A Different Architectural Bet

    Anthropic’s approach to managed agents reflects a different theory of what makes AI work at enterprise scale. Where OpenAI is betting on breadth of integration and output quality, Anthropic is betting on what you might call agent continuity — the idea that the most valuable thing a managed agent can develop is memory, evaluation capability, and the ability to improve through repetition.

    Claude Managed Agents as they stand in mid-2026 are a bundle of four distinct capabilities: a hosted execution runtime, persistent cross-session memory, an outcomes-based evaluation layer, and multi-agent orchestration with subagent delegation. Each of these deserves unpacking separately because they solve different problems.

    The Hosted Runtime

    The foundation is a managed execution environment that handles the infrastructure complexity of running long-lived agents — state persistence, retry logic, timeout handling, tool-call tracking — so development teams do not have to build that themselves. This is what “managed” actually means in the product name. You are not deploying an agent on your own servers; you are running it on Anthropic’s control plane, with the platform handling durability and observability.

    For enterprise teams that previously had to stitch together LangChain, a custom memory store, a monitoring layer, and their own orchestration logic, this is a significant consolidation. The separate vendors that used to sell those infrastructure layers individually are now competing against a bundled platform — a dynamic that is reshaping the agent infrastructure market in real time.

    Persistent Memory: What Changed in April 2026

    On April 23, 2026, Anthropic moved persistent memory for Managed Agents into public beta. The feature does something that sounds simple but has substantial operational implications: it gives agents a cross-session state layer, meaning an agent can store structured memories from one session and access them in the next.

    In practice, this means an agent working on a long-running project — say, a multi-week legal document review or a rolling software build — does not start from scratch each session. It carries forward what it learned about the codebase, the client’s preferences, the recurring error types, the output standards that passed review. The agent gets demonstrably better at the specific job it is doing, without requiring a human to re-brief it every time.

    The production results attached to this feature are striking. Rakuten’s deployment of Claude Managed Agents reported 97% fewer first-pass critical errors compared to baseline — a number that becomes plausible once you understand that persistent memory eliminates entire categories of repeated mistakes. Wisedocs, which uses Claude agents for medical document processing, reported a 30% increase in errors caught and a 50% reduction in audit time.

    Dreaming, Outcomes, and the Self-Improving Agent

    The most conceptually ambitious feature in Claude’s managed agent stack is what Anthropic calls Dreaming — and it deserves more attention than the AI press has given it.

    What Dreaming Actually Does

    Dreaming is a scheduled, asynchronous background process that runs between agent sessions. After a session concludes, Dreaming reviews the session logs and the existing memory store, extracts recurring patterns (common error types, successful reasoning paths, preferred output formats), and rewrites memory to reflect those learnings before the next session begins.

    The metaphor to the human experience of sleep-consolidating memories is intentional and reasonably apt. The agent is not learning during the task. It is processing what happened after the task, in a dedicated consolidation cycle, and arriving at the next session with a refined understanding of how to do the work better.

    At launch, Dreaming is in research preview, meaning it is available to a subset of developers and enterprise accounts experimenting with it under Anthropic supervision. But early production data is hard to ignore: Harvey, the legal-AI platform that uses Claude Managed Agents for complex document workflows, reported a roughly 6× lift in agent task completion rates after enabling Dreaming. That is not a marginal improvement. It is the difference between a system that finishes complex multi-step tasks reliably and one that stalls out.

    Outcomes: Measuring Whether Agents Are Actually Working

    Alongside persistent memory, Anthropic introduced an Outcomes evaluation layer — a rubric-driven scoring system that lets teams define what “good” looks like for a given agent workflow and then measure whether the agent is consistently hitting that bar.

    This addresses one of the most persistent problems in enterprise AI deployment: the gap between “it seems to be working in testing” and “we can prove it is working in production against measurable criteria.” Outcomes allows teams to specify success criteria in natural language (or structured rubrics), run the agent against those criteria at scale, and surface systematic failure patterns.

    The business value is not just quality assurance — it is the ability to have a defensible answer when a compliance team, a board, or a regulator asks how you know the agent is doing what you say it is doing. That kind of measurability is increasingly non-negotiable in regulated industries.

    Claude Managed Agents multi-agent orchestration: lead agent coordinating specialist subagents with persistent memory and Dreaming

    Multi-Agent Orchestration: How Lead Agents and Subagents Actually Work

    The most architecturally significant development in Claude’s platform in 2026 is multi-agent orchestration, which moved to public beta at Anthropic’s Code with Claude developer event in May 2026. This is not a chatbot feature or a UX improvement — it is a fundamental change to how Claude-based systems decompose and execute complex work.

    The Lead Agent / Subagent Pattern

    In Claude’s multi-agent architecture, a lead (or orchestrator) agent receives a high-level task and decomposes it into subtasks, each of which is delegated to a specialist subagent. Each subagent has its own model configuration, its own system prompt, its own tool access, and its own context window. The lead agent coordinates their work, aggregates their outputs, and assembles the final result.

    The practical implication is that complex tasks can now be parallelised in ways that a single-context agent cannot manage. Consider a workflow like “conduct a comprehensive due diligence report on a target company before an acquisition.” A single agent would work through this sequentially, hit context limits, and potentially lose coherence across a long chain of reasoning. A multi-agent system running parallel subagents — one on financial history, one on legal exposure, one on market position, one on regulatory compliance — can work breadth-first and then integrate findings, completing the same work faster and more completely.

    Shared Filesystem and Coordination

    The subagents in Claude’s orchestration system operate on a shared filesystem, which is the coordination mechanism that allows them to hand off information without routing everything through the lead agent’s context window. One subagent’s research output becomes another subagent’s input, without the lead agent needing to hold all of it in memory simultaneously.

    This design choice reflects an architectural philosophy: Claude’s multi-agent system is built around breadth-first decomposition, with a shared state layer for inter-agent communication. It is a different approach to multi-agent coordination than systems that route all communication through a central context or message bus, and it has real implications for the kinds of tasks it handles well — particularly tasks where the scope is wide and the subtasks are relatively independent.

    Fountain: A Real-World Multi-Agent Case Study

    Anthropic’s 2026 Agentic Coding Trends Report highlighted Fountain, a frontline workforce management platform, as a flagship example of multi-agent orchestration in production. Fountain’s system uses a hierarchical agent architecture to handle complex hiring workflow automation — ingesting applicant data, running screening evaluations against configurable criteria, routing decisions to appropriate reviewers, and generating structured candidate summaries for hiring managers.

    The key insight from Fountain’s deployment is not just that agents automated tasks, but that the multi-agent structure allowed them to handle scale and variance simultaneously. A single monolithic agent would struggle with the volume and diversity of inputs. The orchestrated system, with specialist subagents for different workflow stages, handled both without the quality degradation that single-context systems typically show under load.

    Governance, Admin Controls, and the Approval Gate Problem

    Any serious discussion of managed agents in enterprise contexts has to grapple with governance — not as a compliance checkbox, but as a genuine operational challenge. When an AI agent can take actions across your connected systems (sending emails, creating calendar entries, writing to databases, submitting code), the question of what it is allowed to do without human review becomes existential for risk teams.

    ChatGPT’s Governance Model

    OpenAI has built a suite of admin controls into ChatGPT Enterprise and Business that operate at the organisation level. Admins can configure which apps a Workspace Agent can access, what data it can read versus write, which users can create or invoke agents, and what actions require explicit approval before execution.

    The emerging best practice in ChatGPT Work deployments is to treat each agent as a distinct non-human identity — not as an extension of the user who created it. This distinction matters for access control (agents get scoped permissions, not inherited user permissions), for audit trails (each agent action is logged under its own identity, not attributed to the user), and for compliance (you can demonstrate what the agent did and why, independently of any human actor).

    The approval gate mechanism allows admins to designate high-risk action categories that require explicit human sign-off before execution. Sending a mass email to customers, submitting a PR to a production codebase, or modifying a pricing record in the CRM — these can be configured to pause and present for human review rather than executing autonomously. The agent’s chain of reasoning and proposed action is surfaced to the reviewer, who can approve, modify, or reject before anything happens.

    Claude’s Governance Architecture

    Claude Managed Agents take a somewhat different approach to governance, shaped in part by Anthropic’s Constitutional AI research lineage. The platform has built-in policy enforcement at the agent level — you configure what a given agent is allowed to do at the system-prompt level, and those constraints are evaluated against Anthropic’s own safety policies before execution.

    The Outcomes evaluation layer doubles as a governance tool: teams can define rubrics that explicitly test for policy compliance, harmful outputs, or inappropriate actions, and surface violations systematically. This is particularly relevant for regulated industries where the compliance team needs ongoing evidence that the agent is behaving within defined boundaries — not just an assurance from the AI team that it was set up correctly.

    Claude Opus 4.8, the model underpinning the most capable Claude agents as of mid-2026, achieved 88.8% task completion and only 2.5% unintended harmful actions on Anthropic’s WorkBench benchmark in June 2026. Those numbers represent meaningful progress on the safety-capability frontier, though “2.5% unintended harmful actions at scale” still requires serious governance infrastructure to be acceptable in high-stakes environments.

    Enterprise governance checklist for AI managed agents: six essentials before going live

    The Pricing Reality Check: Credits, Seats, and What You’ll Actually Pay

    One of the more significant mid-2026 developments in this space is the shift from flat per-seat pricing toward credit-based, token-metered pricing for agent workloads — a change with real implications for how enterprises budget AI at scale.

    ChatGPT Work’s Credit Model

    Workspace Agents moved to credit-based pricing on May 6, 2026. The architecture is a hybrid: organisations continue to pay per-seat subscriptions for ChatGPT Business or Enterprise (broadly in the $25–$75 per user per month range), but agent-executed workloads draw down from a shared credit pool, with additional credits purchasable as usage scales.

    Codex, which powers Work’s code generation and code-execution capabilities, is now available as a pay-as-you-go seat with no fixed monthly fee — you pay purely on token consumption. This makes it economically viable to add Codex access for a handful of power users or specific automations without buying full Enterprise seats for every developer.

    OpenAI has also made significant cuts to API/credit costs, with GPT-5.6 Luna and Terra pricing reduced by up to 80% from initial rates. The effective result is that the cost per “unit of AI work” has dropped substantially since early 2026, which is materially improving the ROI calculus for enterprise deployments moving from pilots to at-scale production.

    Claude’s Pricing Architecture

    Claude Managed Agents pricing is more closely tied to API token consumption, with managed infrastructure costs layered on top. The persistent memory and Dreaming features carry their own cost structures, as they require storage and compute for the background consolidation processes.

    The practical consideration for teams evaluating cost is not the headline per-token rate but the total cost of ownership versus building equivalent infrastructure independently. Before Managed Agents, a team that wanted persistent memory, evaluation, and orchestration for Claude-based workflows had to build and maintain those systems themselves — or buy them from separate vendors. The bundled platform changes that build-vs-buy equation significantly.

    The ROI Signal From Early Adopters

    Early enterprise adopters of both platforms are reporting productivity gains in the 10–20% range for broad workforce deployment, with significantly higher numbers in specific high-frequency workflow automations. The RingCentral case — where ChatGPT Work’s automation of a monthly launch-check workflow allowed one person to effectively support approximately 50 product managers — represents the high end of what targeted automation can achieve when the workflow is well-defined and the agent is deeply connected to relevant data sources.

    The pattern that emerges from the production data is consistent: the ROI is highest where the workflow is repetitive, the inputs are structured, and the agent has access to all the context it needs. The ROI is lowest where the workflow is genuinely novel each time, the inputs are ambiguous, or the agent has to work around data it cannot access.

    Production Case Studies: What the Evidence Actually Shows

    Rather than relying on vendor claims, it is worth examining the documented production results from actual deployments of both platforms — along with what those results reveal about the conditions under which each platform performs best.

    Production results from AI managed agents: RingCentral, Rakuten, Harvey, and Wisedocs results in 2026

    RingCentral: Scaling Across Product Teams With ChatGPT Work

    RingCentral’s R&D Efficiency team deployed ChatGPT Work to automate a monthly launch readiness workflow that previously required significant manual effort across multiple product and go-to-market teams. The agent was configured to pull launch criteria from Notion, cross-reference product status in the team’s project management system, surface blockers from Slack threads, and assemble a formatted readiness report.

    The headline result — one person supporting approximately 50 product managers through automated workflow — is a function of Work’s ability to operate across connected apps at scale, without requiring the human coordinator to touch each instance. The human’s role shifted from assembling information to reviewing the assembled output and making judgment calls on the blockers the agent surfaced.

    The lesson from RingCentral is that ChatGPT Work’s value compounds when the workflow involves aggregating information from multiple heterogeneous sources into a structured output. That is precisely the task profile where the cloud-native app connector architecture pays off.

    Rakuten: Error Reduction With Claude Managed Agents

    Rakuten’s Claude Managed Agents deployment was structured around code review and quality assurance workflows. Using persistent memory and the Outcomes evaluation layer, the agent retained context about Rakuten’s codebase standards, common error patterns in their environment, and the specific rubrics their engineering team used for code review.

    The result: 97% fewer first-pass critical errors compared to pre-agent baseline, alongside a 27% reduction in cost and 34% reduction in latency. These numbers become interpretable when you understand the mechanism — the agent was not getting smarter in an abstract sense; it was retaining specific institutional knowledge (this codebase, these standards, these common failure modes) that a stateless agent would have to re-derive from scratch in every session.

    The lesson from Rakuten is that Claude’s persistent memory architecture delivers its biggest gains in workflows where institutional context accumulates over time. Code review is an ideal fit: the standards are relatively stable, the error patterns are recurring, and the value of “remembering what we learned last time” is concrete and measurable.

    Harvey: Legal AI With Dreaming Enabled

    Harvey, which uses Claude Managed Agents for complex legal drafting and document review workflows, is the most dramatic case study for the Dreaming feature specifically. Harvey’s agents work on long-horizon legal tasks — multi-document analysis, drafting complex agreements, reviewing regulatory submissions — where task completion rate (finishing the task without stalling or degrading) is the primary quality signal.

    After enabling Dreaming, Harvey reported a roughly 6× increase in agent task completion rates. The mechanism is straightforward in retrospect: legal workflows have many recurring patterns (contract clauses, citation formats, regulatory requirements specific to a jurisdiction), and an agent that has reviewed its past sessions and consolidated those patterns arrives at each new task with a significantly richer foundation for handling its specific challenges.

    Wisedocs: Medical Document Processing

    Wisedocs processes medical documentation at scale — a domain where both accuracy and auditability are non-negotiable. Their Claude Managed Agents deployment combined persistent memory with the Outcomes evaluation layer, with rubrics calibrated to medical documentation standards and compliance requirements.

    Results: 30% more errors caught (the agent learned from accumulated examples of what “correct” looks like in their specific document types) and 50% faster audits (because the Outcomes layer provides structured, queryable evidence of the agent’s decisions, rather than requiring auditors to review raw outputs). The auditability improvement is particularly notable — it speaks directly to the compliance value of the Outcomes architecture, not just the quality value.

    Where Each Platform Clearly Wins — And Where It Struggles

    Based on the architecture, the pricing model, and the production evidence, some clear patterns emerge about where each platform outperforms the other. Understanding these is essential for teams making build decisions in mid-to-late 2026.

    ChatGPT Work vs Claude Managed Agents: enterprise capability comparison by use case

    ChatGPT Work: Where It Wins

    Cloud-native, cross-SaaS output workflows. If the task requires pulling from multiple cloud apps and producing a finished office deliverable — document, presentation, spreadsheet, web app — ChatGPT Work’s connector architecture is the strongest option available in 2026. No other platform matches its breadth of native integrations with the leading SaaS productivity tools.

    Teams already embedded in the Microsoft 365 or Google Workspace ecosystems. Work’s connectors are deep and bidirectional, meaning it does not just read from these systems — it can write back to them, update records, create documents in the right folders, and trigger downstream workflows. The friction of working within an existing SaaS stack is minimal.

    Broad, varied task portfolios. For teams where no two tasks look the same — marketing teams that move between competitive analysis, campaign briefs, and audience research — Work’s ad hoc, outcome-driven model fits better than a memory-augmented specialist agent.

    ChatGPT Work: Where It Struggles

    Highly regulated industries with strict auditability requirements. Work’s outputs are excellent; Work’s reasoning trails are less granular than Claude’s Outcomes evaluation layer. If a compliance team needs to audit why the agent made a specific decision, not just what it produced, the current ChatGPT Work architecture is less equipped to answer that question.

    Long-running, repetitive workflows where institutional learning matters. Without native persistent memory in the Claude sense, Work treats each task as largely independent. For workflows where the agent should get measurably better over time at the specific job, that is a meaningful limitation.

    Claude Managed Agents: Where It Wins

    Repetitive, domain-specific workflows where memory compounds. Code review, legal document processing, medical records management, financial analysis — anywhere the agent is doing essentially the same type of work repeatedly, with institutional knowledge that accumulates — Claude’s persistent memory architecture delivers outsized gains.

    Regulated industries where auditability is a first-order requirement. The Outcomes evaluation layer, combined with the structured logs from Managed Agents, provides the kind of documented evidence trail that compliance teams in healthcare, financial services, and legal services need.

    Complex tasks that benefit from parallel breadth-first decomposition. The multi-agent orchestration architecture, with specialist subagents operating on a shared filesystem, outperforms single-context approaches for tasks that are wide in scope and have relatively independent subtask dimensions.

    Claude Managed Agents: Where It Struggles

    Cross-SaaS connector breadth. Claude’s integration ecosystem is narrower than ChatGPT Work’s, particularly for cloud-native productivity app workflows. Teams that need deep, bidirectional integration with the full Google or Microsoft stack will find Work better positioned today.

    Ad hoc, general-purpose task variety. Claude Managed Agents shine on specific, repeatable workflows. For the unpredictable breadth of requests that a general knowledge-worker brings to an AI tool, the overhead of Managed Agent configuration adds friction that Work’s more free-form approach avoids.

    What Operators Need to Actually Get Right Before Going Live

    Both platforms have moved past the “is this real?” stage of enterprise adoption. The question in mid-2026 is not whether managed agents can do consequential work — the production evidence confirms they can. The question is what the organisational and technical prerequisites are for that work to be trustworthy and sustainable.

    Define the Agent’s Identity Before You Define Its Tasks

    The most consistent recommendation from enterprise teams that have deployed either platform successfully is to treat each agent as a distinct non-human identity, not as an extension of a user or a power tool. This matters for several reasons.

    First, it determines access control. Agents should have scoped, least-privilege permissions — access to exactly the data and tools they need for their specific function, and nothing more. Inheriting broad user permissions from the account that created the agent is a governance anti-pattern that most teams discover the hard way.

    Second, it determines accountability. When an agent takes an action — sends an email, modifies a record, submits code — that action needs to be attributable to the agent identity, not to a human user. This is what makes audit trails defensible: you can reconstruct exactly what the agent did and when, separate from any human actor’s activity log.

    Build Approval Gates Around Action Risk, Not Action Frequency

    A common mistake in early agent deployments is configuring approval gates around action frequency — requiring human review of every nth action, or limiting agents to a fixed number of actions per session. This creates approval fatigue without actually catching the high-risk actions that matter.

    The more effective pattern is to classify actions by risk level and require approval for the high-risk category regardless of frequency. Sending a read receipt is low risk. Sending a mass external communication is high risk. Modifying a read-only record in a compliance system is high risk. Approving a customer refund above a threshold is high risk. Build your approval gates around the risk taxonomy, not the volume.

    Instrument for Failure Modes, Not Just Successes

    The standard approach to evaluating AI outputs — reviewing what the agent produced and deciding whether it is good — does not scale to production agent deployments. You cannot manually review every output when the agent is running thousands of tasks per week.

    What scales is instrumenting for specific, known failure modes. Define the ways the agent could fail that would matter most — producing outputs with factual errors in a regulated context, taking actions outside its scoped permissions, stalling on a task that should complete — and build automated checks for those failure modes. The Claude Outcomes layer is specifically designed to support this; ChatGPT Work’s admin analytics provide aggregate visibility that can support similar monitoring with appropriate instrumentation.

    Run a Shadow Period Before Autonomous Execution

    Before giving any managed agent autonomous execution rights, run it in “shadow mode” — configured to produce its planned actions for human review, without actually executing them. This gives you a production-quality view of what the agent would do in real conditions, without any of the real consequences.

    Most teams that skip this step report a predictable experience: the agent performs well on the tasks they tested, and then encounters an edge case they did not anticipate, and does something plausible but wrong. Shadow periods expose the edge cases before they have consequences.

    Tie Evaluation Criteria to Business Outcomes, Not AI Quality Signals

    The most common evaluation mistake is optimising for AI quality metrics — BLEU scores, human preference ratings, benchmark performance — rather than business outcomes. A document that scores highly on a generic quality rubric may still be wrong in the specific context of your business, your compliance requirements, or your customer relationship.

    Define success criteria in terms of the business outcome you are trying to achieve, then work backwards to what the agent output needs to look like to achieve it. Rakuten’s rubrics were calibrated to their specific codebase standards. Wisedocs’s rubrics were calibrated to their specific documentation compliance requirements. That specificity is what made the metrics meaningful.

    The Bigger Picture: Two Bets That Are Both Paying Off

    It would be convenient — and wrong — to declare a winner between ChatGPT Work and Claude Managed Agents at this stage of development. Both are producing measurable value in production. Both are moving fast. And both have genuine architectural strengths that the other does not yet match.

    What the 2026 production evidence actually shows is that the “AI coworker” concept has bifurcated into two meaningfully different product philosophies. OpenAI is building toward a universal output machine — an agent that can do finished work across any connected system, for anyone, on any task. Anthropic is building toward a persistent, learning agent runtime — a platform where agents develop institutional knowledge, get evaluated against measurable criteria, and improve through experience.

    These are not competing visions in the sense that one will make the other irrelevant. They are complementary in the sense that different workflows call for different architectures. The organisations that will get the most out of managed agents in 2026 and beyond are the ones that understand this distinction clearly enough to match platform to task rather than defaulting to whichever vendor they already have a relationship with.

    The shift from “AI that assists with work” to “AI that does work” is already underway. The production numbers make that clear. What remains genuinely hard — and what will separate the organisations that get lasting value from those that get impressive demos — is the governance infrastructure, the evaluation discipline, and the operational maturity to run AI agents at scale without letting the autonomy outrun the oversight.

    That gap is where most of the real work still needs to happen. And it is, notably, a human problem rather than a technology problem.

    Takeaways for Teams Making Decisions Now

    If your team is actively evaluating ChatGPT Work or Claude Managed Agents for production deployment, the following points represent the most actionable synthesis of the 2026 evidence:

    • Choose ChatGPT Work if your priority is breadth of SaaS integration, finished office-document outputs, or a low-friction tool for teams with highly varied, ad hoc task profiles.
    • Choose Claude Managed Agents if your priority is domain-specific, repetitive workflows where memory compounds value, regulated environments where Outcomes-based auditability is required, or complex tasks that benefit from parallel multi-agent decomposition.
    • Consider using both — the platforms are not mutually exclusive, and a growing number of enterprise teams are running Work for broad knowledge-worker productivity while running Claude Managed Agents for specific high-stakes automated workflows.
    • Do not skip shadow mode. Run every agent in a non-executing review period before granting autonomous action rights. The edge cases you discover will justify the time investment.
    • Instrument for failure modes. Define the specific ways your agent could fail in ways that matter, and build automated detection for those scenarios — don’t rely on sampling outputs manually at production scale.
    • Treat credit costs as a variable, not a fixed line item. Both platforms’ token-based pricing means agent costs scale directly with usage. Model your credit consumption against your expected workflow volume before committing to at-scale deployment.
    • The governance infrastructure is not optional. Scoped permissions, agent identity management, approval gates for high-risk actions, and queryable audit trails are prerequisites for production deployment in any environment where consequential actions are involved — not features to add later.

    The managed agent era is not coming. It arrived. The organisations figuring out how to govern these systems well, not just how to deploy them, are the ones that will be ahead of this curve twelve months from now.

  • Supervision Is Expensive: How to Design Human-in-the-Loop That Scales Without Breaking Your Budget

    Supervision Is Expensive: How to Design Human-in-the-Loop That Scales Without Breaking Your Budget

    Split-screen infographic: human reviewer overwhelmed by AI approval requests on the left vs. a clean three-tier oversight architecture on the right — illustrating the core challenge of scaling human-in-the-loop supervision

    There is a number buried inside almost every enterprise AI budget that nobody wants to talk about. It is not the GPU bill. It is not the licensing fee for the model. It is the cost of the people who watch the model work — the reviewers, approvers, auditors, and escalation handlers whose labor turns an AI system into a production-grade, accountable operation. In 2026, that number has a name: human-in-the-loop overhead, and in many organizations it has quietly grown to represent 15–25% of total AI program spend.

    At low volumes, this overhead is manageable — a few reviewers, a shared Slack channel, a spreadsheet of edge cases. But as AI systems scale from hundreds to thousands to tens of thousands of decisions per day, the math changes completely. A single knowledge-worker review costs $0.58–$0.83 per decision at fully loaded labor rates. A comparable LLM inference call costs roughly $0.003. At 5,000 decisions a day, that differential is not academic: it is a $1.4 million annual gap between a fully supervised workflow and a fully autonomous one.

    The uncomfortable reality is that most enterprises are running neither. They have built HITL systems that are too expensive to sustain at volume and too poorly designed to actually catch the errors they were supposed to prevent. This article is about how to fix that — not by removing humans from the loop, but by engineering their participation so that every hour of human attention is doing real work, not theater.

    The Unit Economics of Human Attention — A Number That Should Be on Every AI Dashboard

    Bar chart infographic showing where AI total cost of ownership actually goes — human review labor as the tallest bar at 15–25% of spend, with the $0.58–$0.83 per human review vs. $0.003 per LLM call comparison highlighted

    The conversation about AI costs almost always starts in the wrong place. Procurement teams negotiate model contracts. Engineers benchmark inference latency. CTOs study cloud spend dashboards. But the largest variable cost in a mature AI deployment is often none of these things — it is the fully loaded hourly cost of the humans who review, correct, approve, and escalate its outputs.

    Breaking Down the True Cost of a Single Review

    When you calculate the true cost of a human review event, you need to account for more than the reviewer’s salary. The full picture includes:

    • Direct labor: The reviewer’s time at fully loaded rates (salary plus benefits plus overhead) — typically $35–$50/hour for knowledge workers in 2026
    • Context-switching cost: Shifting attention from one task to a review queue and back degrades both activities. Research on task interruption consistently shows 15–25 minutes of productivity loss per context switch
    • Queue management overhead: Someone has to route work, handle backlogs, and manage SLA compliance — that is typically 10–15% additional headcount on top of raw reviewer capacity
    • Tooling and infrastructure: Review interfaces, audit log systems, escalation workflows, and integrations with the AI system itself
    • Rework from missed errors: When reviewers do miss something — and they will — the downstream cost of correcting that error is often 3–10x the original review cost

    Putting these together, the $0.58–$0.83 per-decision estimate cited in enterprise governance analyses is likely conservative for anything requiring genuine domain expertise. In regulated industries like healthcare, finance, or legal — where the reviewer needs professional credentials and carries personal liability — the cost per reviewed decision can easily reach $3–8.

    The Volume Inflection Point

    At 100 decisions per day, a two-person review team is manageable. At 1,000 decisions per day, you need to hire a team. At 10,000 decisions per day, you are looking at a 20–30 person operation whose annual budget rivals the entire model deployment cost. This is the volume inflection point — the moment when HITL stops being a governance safeguard and starts being a business model problem.

    The critical design question is not “do we need humans in the loop?” The answer is almost always yes, at least partially. The real question is: at exactly which decisions does human attention change the outcome, and how do we ensure humans are only spending time on those ones? Everything else is an engineering problem masquerading as a governance question.

    Computing the Opportunity Cost of Latency

    Human review does not just cost money — it costs time, and time has economic value in automated workflows. A synchronous review gate that adds 4 hours of latency to a decision chain is not just a user experience problem. In workflows where AI decisions trigger downstream processes — fulfillment, pricing, clinical triage, fraud alerts — that latency translates directly into delayed outcomes, missed SLAs, and in some cases, material business loss. Any honest accounting of HITL cost must include this latency overhead as a direct line item.

    Why “Review Everything” Is Already Broken at Scale

    The “review everything” model was the safe default when AI systems were new, confidence was low, and volumes were small enough that a small team could keep up. In 2026, it is neither safe nor sustainable — and for a counterintuitive reason: universal review does not actually produce better oversight. It produces the illusion of oversight while introducing its own failure modes.

    Reviewer Capacity Has a Hard Ceiling

    Human reviewers process decisions at a finite rate. A knowledge worker reviewing AI-generated content at a comfortable pace can typically evaluate 50–70 items per hour before quality begins to degrade. Push beyond that, and something measurable happens: review time per item compresses, approval rates climb, and error detection rates fall. This is not a character flaw in the reviewer — it is basic cognitive science. Working memory, sustained attention, and critical evaluation all have per-hour limits that cannot be overridden by urgency or good intentions.

    The practical consequence: if your AI system generates 500 decisions per hour and your reviewer can genuinely evaluate 60 per hour, you have one of three outcomes. Either you hire 8+ reviewers (expensive), allow a queue backlog to build (latency), or the reviewer starts rubber-stamping to keep up (failure mode). Most organizations, under time and budget pressure, drift toward the third option without ever formally deciding to do so.

    Queue Volume Predicts Review Quality Better Than Reviewer Skill

    This is one of the most important and underappreciated findings from recent enterprise AI governance research. Reviewer quality in high-volume queues is not primarily a function of training, expertise, or motivation. It is a function of queue depth at time of review. When reviewers can see that they are 200+ items behind, cognitive shortcuts kick in automatically. The brain shifts from analytical processing to pattern-matching based on the most recent approved items — a dynamic that creates systematic blind spots to anything that falls outside recent patterns.

    This means that a well-designed, lightly loaded review workflow staffed by moderately experienced reviewers will consistently outperform an overloaded review workflow staffed by domain experts. The implication for HITL architecture is stark: if you cannot guarantee queue depth stays below your reviewers’ cognitive overload threshold, you do not have a review process — you have an approval process, and those are very different things.

    The False Security of High Approval Rates

    Many organizations measure HITL health using approval rate as a proxy for review quality. If reviewers are approving 98% of items, the thinking goes, the AI must be doing well. This is exactly backwards. High approval rates in high-volume queues are one of the clearest signals of approval fatigue, not AI accuracy. When the approval rate for a review queue approaches 95–99%, the next question should not be “great, our AI is performing well” — it should be “is our review process still adding value, or have we built an expensive rubber-stamp?”

    Genuine review processes in well-designed HITL systems typically show approval rates between 75–90%. If yours is higher than that consistently, either the escalation threshold is set too low (sending easy cases to human review unnecessarily) or the reviewers have cognitively checked out. Both are design problems, not operational ones.

    The Automation Bias Trap: When Oversight Becomes Performance

    Illustration of automation bias: a fatigued human reviewer rubber-stamping AI outputs on a conveyor belt without reading them, with the warning 'When Human-in-the-Loop Becomes Human-on-the-Loop'

    Automation bias is the tendency of humans to over-trust automated systems, defer to their outputs even when those outputs are wrong, and reduce independent verification over time. It has been documented in aviation, radiology, financial trading, and now systematically in AI oversight workflows. Understanding it is not optional for anyone designing human-in-the-loop systems at scale — it is the single most important failure mode to engineer against.

    How Automation Bias Develops in Review Workflows

    The mechanism is well-understood. When a reviewer first starts working with an AI system, they are appropriately skeptical. They check outputs carefully, catch errors, occasionally override, and develop a mental model of where the system is strong and where it fails. Over time, however, if the AI’s accuracy is reasonably high — say 87–93% — the reviewer experiences hundreds of validations for every override. The brain’s reinforcement learning system does what it is designed to do: it updates toward trusting the frequent pattern.

    Within weeks, reviewers who were carefully verifying AI outputs are spending a fraction of their original review time per item. Within months, many have effectively delegated their judgment to the system and are primarily performing confirmation — checking that the AI produced something plausible rather than something correct. This transition happens gradually and often without the reviewer being consciously aware of it.

    The “Human-on-the-Loop” Failure Mode

    Enterprise AI governance analysts now distinguish between two functionally different states that can both be labeled “human-in-the-loop”:

    • Human-in-the-loop (genuine): The human is making an independent judgment that could plausibly differ from the AI’s output. They are applying domain expertise, contextual knowledge, and critical evaluation that adds information to the decision.
    • Human-on-the-loop (theater): The human is present in the workflow and technically approves outputs, but their approval is not adding information — it is ratifying whatever the AI produced with a human’s signature, creating a liability shield while providing no actual error-catching value.

    The dangerous thing about human-on-the-loop is that it combines the worst properties of both oversight approaches. It preserves the latency cost of human review (since a human is still in the decision chain), while providing essentially none of the quality benefit. Worse, it creates a false audit trail: documentation records that a human reviewed and approved each output, which may satisfy a compliance checkbox while the actual error rate is no different from full automation.

    Detecting Automation Bias in Your Current Workflow

    There are several operational signals that automation bias has taken hold in a HITL workflow:

    • Approval rate consistently above 95% in queues with more than 50 items/hour throughput
    • Review time per item trending down over weeks without a corresponding improvement in AI accuracy or reviewer experience
    • Override rate clustering near zero for a specific reviewer while remaining healthy for others
    • Calibration drift: periodic re-injection of known errors fails to be caught at the expected rate
    • Reviewer unable to articulate decision reasoning when spot-audited: they approved the item but cannot say why

    The practical fix is not to admonish reviewers for becoming efficient — it is to redesign the workflow so that genuinely difficult cases are the only cases reaching human reviewers, keeping their cognitive load within a range where real evaluation is possible.

    Risk-Stratified Architecture: The Framework That Makes Scaling Viable

    Three-tier risk stratification architecture diagram: Tier 1 auto-execute at 80% volume in green, Tier 2 human review at 15% in yellow, Tier 3 expert escalation at 5% in red — the foundational model for scalable AI oversight

    The solution to expensive, degrading universal review is not less oversight — it is tiered oversight calibrated to actual risk. Risk stratification is the core architectural pattern that allows organizations to scale AI decision volume by an order of magnitude without proportionally scaling reviewer headcount, while maintaining or improving genuine quality control.

    The Three-Tier Model

    The most robust HITL architectures in 2026 organize oversight into three tiers, each with different routing criteria, reviewer profiles, SLAs, and tooling:

    Tier 1 — Autonomous Execution: High-confidence, low-stakes decisions that execute without human review. These cases meet a high confidence threshold (typically above 85–90%), fall within well-defined action scope limits, and have low error cost — meaning if the AI is wrong, the downstream impact is easily correctable. In a well-calibrated system, this tier should handle 75–85% of total decision volume.

    Tier 2 — Standard Human Review: Medium-confidence or medium-risk decisions that require a trained reviewer to evaluate before execution. Cases land here either because model confidence falls in a middle band (typically 65–90%), because contextual risk flags are present, or because the decision type carries inherent risk regardless of model confidence. Target volume for this tier is 10–20%, with reviewers working at a sustainable pace that allows genuine evaluation — typically no more than 30–40 items per hour in complex domains.

    Tier 3 — Expert Escalation: Low-confidence, high-stakes, or novel cases that require domain expert judgment or formal approval authority. These cases cannot be resolved by Tier 2 reviewers alone because they require specialized expertise, carry significant consequence, or represent a genuinely new pattern the model has not encountered. This tier should represent 3–8% of volume. It should never be allowed to grow significantly above that — if it does, it signals either a model performance problem or miscalibrated routing logic.

    What Makes Routing Logic Actually Work

    The routing logic that assigns decisions to tiers is the most technically demanding component of risk-stratified HITL. Naive implementations route solely on model confidence score, which is a reasonable starting point but insufficient on its own. Confidence scores are poorly calibrated for many production models — they tell you how certain the model is, not how much the model’s certainty correlates with actual accuracy.

    More robust routing combines multiple signals:

    • Model confidence score — necessary but not sufficient
    • Domain risk classification — some decision types carry inherent stakes that require human review regardless of confidence
    • Entity-level risk profile — decisions about high-value customers, large transactions, or flagged accounts escalate by default
    • Novelty detection — inputs that fall significantly outside the distribution of training data trigger escalation even if model confidence is superficially high
    • Historical accuracy by context — if the model has a documented performance weakness in specific input categories, those categories route to Tier 2 automatically

    Organizations that invest in multi-signal routing typically achieve escalation rates 30–50% lower than those using confidence-only routing, while maintaining equivalent or better defect detection rates. The engineering cost is real but pays back quickly at production volumes.

    Confidence Thresholds and the Double-Gate Pattern

    One of the most consequential decisions in HITL system design is choosing where to place confidence thresholds — the numerical cutoffs that determine whether a decision goes to Tier 1, Tier 2, or Tier 3. Get this wrong in either direction and the economics collapse: too conservative and you overload reviewers with easy cases; too aggressive and you automate decisions that should have had oversight.

    Why Single-Threshold Systems Fail

    The obvious approach — set one confidence threshold and auto-approve everything above it — has a structural flaw. It conflates two very different categories of output: cases where the model is genuinely high-confidence because the input is clear and within training distribution, and cases where the model is superficially high-confidence because it has learned to produce high confidence scores on a certain input type regardless of actual accuracy. These look identical to a single-threshold filter but have very different real-world error rates.

    A single threshold also creates a fragile cliff: cases just above the threshold are treated identically to cases far above it, even though their risk profiles are meaningfully different. And when model performance drifts over time — as it always does in production — the threshold calibration becomes stale without triggering any alert, silently increasing error rates in the autonomous tier.

    The Double-Gate Pattern

    The design pattern that has emerged as best practice in 2026 uses two confidence thresholds rather than one, creating three zones:

    • Above upper gate (e.g., 90%): Auto-execute. High confidence + acceptable action scope = autonomous.
    • Between gates (e.g., 70–90%): Route to human review. Genuine uncertainty zone where human judgment is most likely to add information.
    • Below lower gate (e.g., below 70%): Route to expert escalation or automatic rejection. Confidence is too low to trust even with human review — the model does not know what it does not know.

    The key insight behind the double-gate pattern is that different failure modes require different responses. Cases in the middle zone are genuinely uncertain — a human reviewer working with the right context can meaningfully improve the outcome. Cases below the lower gate are not uncertain in the sense of being close calls: they represent situations where the model is operating outside its competence boundary, and sending them to a standard reviewer who may not have the context to recognize that is actually more dangerous than routing them to expert escalation or rejection.

    Threshold Calibration Is Not Set-and-Forget

    Both thresholds should be treated as live operational parameters, not deployment-time configurations. Optimal threshold placement shifts as model performance evolves, as input distributions change with business growth, and as reviewer capacity fluctuates. Organizations running well-instrumented HITL systems in 2026 are recalibrating thresholds on a monthly cadence at minimum, using metrics from their review queues — actual human override rates by confidence band — to adjust where the gates sit.

    A practical rule of thumb: if the human override rate for decisions just above your upper gate is higher than the override rate for decisions well above it, your upper gate is too low. If the override rate is essentially zero for decisions just below your upper gate, your gate is too high. The goal is a threshold placement where the human override rate in the review zone is meaningfully above zero and stable — typically 8–25% — indicating that reviewers are genuinely making different calls than the model would have made autonomously.

    Asynchronous vs. Synchronous Review: Choosing the Right Mode for Each Tier

    One of the most consequential and least-discussed design decisions in HITL architecture is whether human review happens synchronously (the AI waits for human approval before proceeding) or asynchronously (the AI proceeds while the review occurs in parallel, with correction capability if needed). The choice has profound implications for latency, throughput, reviewer experience, and the types of errors that can be caught.

    Synchronous Review: When Waiting Is Worth It

    Synchronous review — sometimes called “human-in-the-loop” in the strict sense — requires the AI workflow to pause and wait for human approval before the decision executes. This is the right architecture when:

    • The decision is irreversible. If the AI’s action cannot be undone — a financial transaction, a patient medication order, a legal filing — the cost of getting it wrong before execution is higher than the cost of latency. Synchronous review is the correct default for all irreversible decisions above a materiality threshold.
    • The decision has immediate external consequences. Actions that immediately affect external parties (customers, counterparties, regulators) before any correction window closes require synchronous oversight.
    • The organization is in a calibration phase. Early in deployment when the model’s accuracy in a new domain is not yet well-characterized, synchronous review provides the most reliable signal about where the model is failing.

    The critical constraint for synchronous review is SLA management. If you commit to synchronous oversight, you are committing to a human response time that must fit within your workflow’s acceptable latency budget. A synchronous review SLA of 4 hours is fine for a nightly contract analysis workflow. It is catastrophic for a real-time fraud detection system. Matching review mode to workflow latency requirements is not optional.

    Asynchronous Review: The Overlooked Scaling Mechanism

    Asynchronous review — where the AI executes the decision while human review happens concurrently, with rollback or correction capability — is significantly underused in enterprise AI deployments. Its underuse stems from a misunderstanding: organizations conflate “asynchronous review” with “no review,” when it is actually a different timing contract rather than a lesser one.

    In an asynchronous model, the human reviewer examines outputs after execution but within a defined correction window. If they identify an error, there is a defined remediation path — a reversal, a correction notice, an override that applies to subsequent similar decisions. This architecture is genuinely appropriate for a wide range of business decisions where the consequences of a wrong output are material but not catastrophic, and where a short correction window is available.

    The throughput advantages are significant. Asynchronous review decouples reviewer capacity from workflow throughput — the AI system runs at its natural speed, and reviewers work through the output queue at a pace that allows genuine evaluation. Cognitive overload drops because reviewers are not being driven by the real-time pace of AI output generation. And because corrections apply prospectively, a single reviewer catching a systematic error in asynchronous review can prevent hundreds of identical future errors, multiplying the value of each review event.

    Making the Reversibility Assessment

    The practical decision framework for choosing between synchronous and asynchronous review comes down to a reversibility and window assessment for each decision category:

    • Can the decision be reversed within an acceptable time window if wrong? → Asynchronous is viable
    • Is there a correction window between execution and material consequence? → Asynchronous is viable
    • Does the decision immediately affect a third party in a way that cannot be corrected? → Synchronous required
    • Is the error cost of a wrong decision roughly proportional to cost of delay? → Synchronous vs. async is a cost-optimization decision

    Sampling Strategies That Preserve Quality Without Draining Capacity

    Statistical quality control sampling visualization: AI decisions on a production line with spot-check spotlights at 5% intervals — showing targeted sampling achieves 94% equivalent defect detection at a fraction of the review cost

    For the autonomous tier (Tier 1) of a risk-stratified HITL architecture, “no human review” does not mean “no oversight.” It means moving from pre-execution gating to post-execution sampling — a statistically governed audit process that detects systematic errors and model drift without reviewing every single output.

    The Statistical Logic of Sampling-Based Oversight

    Statistical sampling for quality control has a well-understood mathematics. For detecting a defect rate of 5% or higher, a random sample of 59 items provides 95% probability of detecting at least one defect. For detecting a defect rate of 1%, you need roughly 299 samples. These numbers hold regardless of the total population size — which is counterintuitive but accurate and has significant implications for HITL economics.

    In practice: if your AI system processes 10,000 decisions per day in the autonomous tier, you need to review approximately 200–400 of them to maintain robust quality assurance with standard statistical confidence. That is a 2–4% sampling rate that provides detection power equivalent to reviewing far larger fractions of output. The cost difference — reviewing 300 items vs. reviewing 10,000 items — is the entire economic case for sampling-based oversight.

    Stratified vs. Simple Random Sampling

    Simple random sampling — randomly selecting items from the autonomous-tier queue — works well for detecting uniformly distributed errors. But most AI errors are not uniformly distributed. They cluster around specific input types, edge cases, data quality issues, or distribution shift in particular customer segments. Simple random sampling will systematically under-sample exactly these high-risk clusters.

    Stratified sampling addresses this by drawing samples proportional to risk within defined strata:

    • Confidence distribution sampling: Over-sample decisions near the upper confidence gate, where the model’s error rate is highest within the autonomous tier
    • Novel input sampling: Flag and sample decisions where input features are unusual relative to historical distributions — these are where unreported model weaknesses most often surface
    • Output distribution sampling: Sample outputs at the tails of the output distribution — unusually high or low values, unusual classifications — which are more likely to represent genuine edge cases than outputs clustering near the mean
    • Time-stratified sampling: Ensure samples are drawn across all time periods, not just recent output — this catches gradual model drift that simple recent-window sampling misses

    Sentinel Cases: The Underused Quality Signal

    One of the most effective and underused tools in sampling-based HITL oversight is the sentinel case — a deliberately injected known-answer item that is routed through the autonomous tier and caught by sampling. Sentinel cases serve two purposes: they validate that your sampling infrastructure is actually catching items from the autonomous tier (not just routing everything to review), and they provide a direct measurement of model accuracy on known cases over time.

    Well-designed sentinel programs use a library of cases with known correct answers, injected at a rate of roughly 1–2% of autonomous-tier volume. If sentinel error rates climb above a defined threshold, it triggers an escalation — either to recalibrate the confidence thresholds or to pull the autonomous tier offline for revalidation. This is the closest equivalent to a circuit breaker for AI quality, and it works without requiring human review of every output.

    Building the Oversight Stack: Roles, Tooling, and SLAs

    Organizational chart of the specialized HITL oversight team: Workflow Architect, Tier-2 Domain Reviewers, Oversight Engineer, and Escalation Authority with SLA badges — showing supervision as a structured system, not an ad-hoc task

    The most persistent mistake in enterprise HITL design is treating oversight as a task that gets appended to existing job descriptions rather than as a function that requires purpose-built roles, tooling, and service-level agreements. When oversight is bolted onto other responsibilities, it consistently loses to those responsibilities under time pressure — which is precisely when oversight is most needed.

    The Specialized Roles Emerging in Production HITL Teams

    Mature HITL deployments in 2026 have begun to formalize oversight into distinct roles with explicit decision authority. The emerging structure includes four core functions:

    Oversight Engineer: Owns the technical infrastructure of the HITL system — routing logic, confidence calibration, monitoring dashboards, sampling systems, and integration between the AI pipeline and review tooling. This is a hybrid role sitting between ML engineering and operations, with accountability for whether the HITL system is functioning as designed. Not every organization has the headcount for a dedicated Oversight Engineer at launch, but someone needs to own these responsibilities explicitly — assigning them implicitly to whoever is available is how systems drift toward the “theater” failure mode.

    Workflow Architect: Designs the decision taxonomy (what types of decisions go where), defines the routing rules, and maintains the tier-assignment logic as the AI system and business context evolve. This role bridges the technical system and the business requirements, translating risk tolerance and compliance requirements into concrete routing specifications. In regulated industries, this role often sits at the intersection of AI engineering and risk management functions.

    Domain Reviewers (Tier 2): The people doing the actual work of human review. The critical shift in 2026 is treating these as specialist roles rather than generalist ones. Effective Tier 2 reviewers are domain experts with calibrated judgment in the AI system’s application area — not general-purpose employees asked to evaluate outputs in a domain they do not deeply understand. Reviewer specialization is strongly correlated with both review quality and sustainable reviewer satisfaction; generalist reviewers tend toward automation bias faster because they lack the domain knowledge to efficiently identify what is worth scrutinizing.

    Escalation Authority: A named individual or panel with the decision rights and accountability to resolve Tier 3 escalations — novel cases, edge cases, and high-stakes decisions that Tier 2 cannot resolve. Escalation Authority is not a team of full-time reviewers; it is a defined governance structure that ensures escalated cases have a clear resolution path with a defined SLA, rather than disappearing into a scheduling queue.

    Tooling Requirements That Most Teams Underestimate

    The tooling surface for a production HITL system is larger than it appears at design time. The minimum viable oversight stack includes:

    • Reviewable decision interface: A structured UI that presents the AI’s input, proposed output, confidence score, routing reason, and any relevant context in a single view — without requiring the reviewer to navigate between multiple systems. Cognitive load in the review interface directly affects review quality; every extra click is a judgment degrader.
    • Override recording with rationale capture: Not just the fact of an override, but a structured record of why. Rationale data from overrides is the primary raw material for model improvement and threshold recalibration — organizations that capture only “approved/rejected” lose the most valuable training signal.
    • Queue management with real-time depth visibility: Reviewers and queue managers need to see queue depth, age of oldest item, and throughput rate in real time. This is the instrumentation that allows workload adjustments before cognitive overload sets in, not after.
    • Audit log with tamper evidence: A complete, chronologically ordered record of every decision, its routing tier, the reviewing identity, the outcome, and the timestamp. In regulated environments, this needs to be tamper-evident and accessible to compliance functions without requiring access to the operational system.
    • Monitoring dashboard with leading indicators: Not just output metrics (accuracy, error rate) but leading indicators of HITL system health: review time per item trends, approval rate trends, queue depth over time, override rate by reviewer and by model confidence band.

    SLAs Are Not Optional

    Without defined SLAs, HITL systems develop informal norms about response time that are almost always too slow, inconsistently applied, and impossible to audit. Every tier in a risk-stratified architecture needs a defined maximum response time that is owned by a named function:

    • Tier 2 reviews: typically 15 minutes to 4 hours depending on workflow latency budget
    • Tier 3 escalations: typically 4–48 hours depending on decision urgency
    • Sampling audits: completed within defined cycles (daily, weekly) with escalation triggers for detected anomalies

    When SLAs are breached, there should be a defined response: automated alerts, escalation to the next authority, or temporary workflow modification (e.g., hold autonomous-tier execution until backlog clears). Treating SLA breaches as operational data rather than operational failures allows the system to self-correct rather than quietly degrade.

    Measuring Whether Your HITL Is Actually Working

    Most HITL programs are measured on the wrong things. They track volume (how many items were reviewed), time (how long reviews took), and cost (what reviewers were paid). These are operational hygiene metrics. They tell you the system is running — not whether it is working. A genuinely effective HITL measurement framework centers on a different set of questions.

    The Metrics That Signal Real Oversight Quality

    Human Override Rate by Confidence Band: The most important single signal of HITL system health. Measures the fraction of reviewed items where the human reviewer reaches a different conclusion than the AI’s output. Healthy override rates are typically 8–25% within the review tier, and they should be higher for items near the lower confidence gate and lower for items near the upper gate. A flat override rate across the confidence spectrum suggests reviewers are not responding to model uncertainty signals — a calibration problem.

    Downstream Error Rate by Tier: Of decisions that passed through each tier and executed, what fraction were later identified as wrong — through customer complaints, outcome tracking, audit findings, or sentinel re-injection? This is the ground-truth measure of whether each tier’s oversight level is appropriate. If Tier 1 autonomous decisions show a materially higher downstream error rate than Tier 2 reviewed decisions, the upper confidence gate is set too low (letting too many uncertain decisions through to autonomous execution).

    Review Time Trend: Average time per review item over rolling weekly periods. A declining trend in review time, absent a deliberate change in workflow complexity or reviewer experience, is a leading indicator of automation bias taking hold. Flag it before it becomes a quality problem.

    Queue Age Distribution: Not just how many items are in the queue, but how old they are. Items sitting in a review queue for more than twice the target SLA are an operational failure that most queue-depth metrics will not surface unless you specifically track age distribution. Old items tend to get bulk-approved under time pressure — exactly the wrong outcome.

    Escalation Rate Stability: The fraction of Tier 2 reviews that escalate to Tier 3 over time. An escalating trend means either model performance is degrading (more items require expert judgment) or reviewer confidence is declining (reviewers are escalating items they could resolve themselves). A declining trend is healthy — until it reaches zero, at which point reviewers have likely stopped escalating anything and the Tier 3 path is functionally dead.

    Building a HITL Health Score

    The most operationally effective teams in 2026 are building composite HITL health scores — single numbers synthesizing the above metrics into a weekly or daily readout. The construction is simple: define green/yellow/red ranges for each metric, assign weights based on consequence (override rate and downstream error rate typically weighted highest), and combine into a dashboard indicator that any stakeholder can read without navigating five separate dashboards.

    The health score does not need to be statistically sophisticated to be useful. Its primary value is creating a shared, visible signal that HITL system quality is tracked and owned — not assumed to be fine until something breaks.

    What the Economics Look Like at 10x Volume

    Break-even economics graph: Full HITL Review Cost line rising steeply vs. flat Error Cost of Full Automation — crossing at approximately 1,200 decisions/day, with green 'Autonomous wins' zone to the right

    Here is the scenario most HITL design decisions need to be stress-tested against: your AI system is working. The business case held up. Volume is growing. What happens to your oversight costs and quality at 5x, 10x current volume?

    The Three Scenarios

    Consider an organization processing 1,000 AI decisions per day today, with a universal review model (every decision reviewed). At that volume, 3 reviewers can keep up with a sustainable workload at roughly 60 reviews per hour each.

    Scenario A — Scale without redesign (universal review at 10x): At 10,000 decisions per day, the same universal review model requires 30 reviewers. At fully loaded cost of $75,000–$90,000 per reviewer per year, that is $2.25M–$2.7M in reviewer salaries alone — before tooling, management, training, and overhead. The review queue’s throughput ceiling also means that unless all 30 reviewers are on the same shift, peak-hour decision volumes will exceed reviewer capacity and queue age will grow. This scenario is what most organizations are sliding toward, usually without explicitly deciding to.

    Scenario B — Risk-stratified architecture at 10x: The same 10,000 decisions per day, but routed through a three-tier system with 80% autonomous, 15% Tier 2 review, 5% Tier 3 escalation. At 1,500 decisions per day reaching human review (combined Tier 2 and Tier 3), you need 5–6 reviewers plus 2–3 domain experts for Tier 3, at a total headcount of 8–9 FTEs. Cost: approximately $600,000–$750,000 per year in reviewer labor. The saving vs. Scenario A is $1.5M–$2M annually at 10x volume.

    Scenario C — Sampling-augmented hybrid at 10x: Risk-stratified architecture plus sampling-based audit for the autonomous tier. Human review touches roughly 15% of total decisions pre-execution (Tier 2) and 5% post-execution (sampling audit). Total human decision-touching rate: 20%. Total reviewer headcount: 6–7 FTEs. Annual cost: $450,000–$525,000. The saving vs. Scenario A is $1.8M–$2.25M annually.

    The Quality Trade-off Is Smaller Than You Think

    The natural concern about reducing review coverage is error rate. Will catching fewer decisions per unit time mean more errors slip through? In well-designed systems, the answer is counterintuitive: not necessarily. The key insight is that quality in universal review systems is already seriously degraded by overload — the 30 reviewers in Scenario A are rubber-stamping most of what they see. Meanwhile, the 8 reviewers in Scenario B are evaluating genuine borderline cases and bringing real domain expertise to the decisions that need it most.

    Multiple enterprise deployments comparing pre- and post-stratification error rates have found that risk-stratified systems with 15–20% human review coverage achieve roughly equivalent downstream error rates to overloaded universal review systems at 100% coverage — and in several cases actually outperform them, because reviewers are no longer cognitively depleted by the time they encounter genuinely difficult cases.

    When the Break-Even Math Flips

    There is a volume threshold below which full HITL review is economically rational — roughly when the expected cost of undetected errors (error rate × average error cost × daily volume) exceeds the daily cost of universal review. This threshold is highly domain-dependent: in high-stakes decisions (medical, financial, legal), the error cost is so high that full review may remain justified at significant volumes. In lower-stakes automation (content moderation, recommendation generation, routine data classification), the break-even point is typically reached much sooner — often before 500–1,000 decisions per day.

    The discipline of explicitly computing this break-even for each decision category in your AI system is one of the most valuable exercises an oversight architect can run. It transforms the debate from “how much oversight is enough?” (an unanswerable philosophical question) to “at what volume does the expected value of this review tier go negative?” (a quantifiable engineering question with a specific number answer).

    The Regulatory Dimension: Compliance Requirements Without Compliance Theater

    No treatment of human-in-the-loop design in 2026 is complete without addressing the regulatory environment, which has become a significant driver of HITL architecture decisions — particularly for organizations operating under the EU AI Act, sector-specific AI guidance from financial regulators, and evolving healthcare AI oversight frameworks.

    What Regulators Actually Require

    The common misconception is that regulation requires “a human reviewed every decision.” In practice, most current regulatory frameworks require something considerably more nuanced: meaningful human oversight calibrated to the risk level of the application. The EU AI Act’s requirements for high-risk AI systems, for instance, mandate that systems be designed to allow human oversight, that humans be capable of intervening, and that appropriate measures are taken to ensure oversight is effective — not that every decision is manually reviewed.

    This distinction matters enormously. A well-designed risk-stratified HITL system with documented routing logic, defined escalation paths, maintained audit trails, and evidence-based calibration of tier thresholds typically satisfies regulatory oversight requirements far better than an overloaded universal review process in which reviewers are rubber-stamping at speed. Regulators increasingly understand the difference, and compliance teams that conflate “any human touchpoint” with “meaningful oversight” are creating both unnecessary cost and false compliance confidence.

    What Documentation Actually Needs to Exist

    For organizations in regulated industries, the documentation requirements for HITL systems are specific and non-trivial. At minimum, production HITL systems should maintain:

    • A decision taxonomy classifying each AI action type by risk tier with documented rationale
    • Threshold calibration records showing the basis for confidence gates and evidence of their effectiveness
    • Reviewer competence records linking each review authority to the qualifications required for their tier
    • Audit logs sufficient to reconstruct any individual decision’s routing path, review outcome, and reviewer identity
    • Monitoring records showing HITL system health metrics over time, with evidence that anomalies triggered appropriate responses

    Organizations that build this documentation infrastructure during initial deployment rather than retrofitting it at audit time avoid both the compliance panic and the significant cost of post-hoc documentation reconstruction.

    Designing for the Next Order of Magnitude

    The organizations getting HITL right in 2026 are not thinking about their current volume — they are designing for where they will be in 18 months. The architectural decisions made at low volume create path dependencies that are expensive to unwind later. A universal review system that was “good enough” at 500 decisions per day becomes a $2M annual problem at 5,000 decisions per day, and redesigning it under production pressure is a significantly worse option than designing it for scale from the start.

    The Architectural Decisions That Compound

    Several early HITL design decisions have outsized impact on scalability:

    Routing logic location: If your routing logic is embedded in the AI model output pipeline rather than in a dedicated routing service, recalibrating thresholds requires a pipeline change rather than a configuration change. This means threshold recalibration happens infrequently (because it’s costly) rather than continuously (because the system makes it easy). Build routing as a separate, configurable service from day one.

    Review interface design: Review interfaces built for small teams quickly become unusable at scale. The design decisions that matter — how much context is surfaced per item, how overrides are captured, how queue management works — are much easier to get right at the beginning than to retrofit into a production system with an established user base of reviewers who have adapted their workflows to whatever the interface currently does.

    Audit log schema: Audit logs that record only approved/rejected status are worthless for calibration, improvement, and compliance. Audit logs that record input features, confidence scores, routing reasons, reviewer identity, override rationales, and downstream outcomes are extraordinarily valuable. The difference in storage and implementation cost is small. The difference in downstream utility is immense.

    The AI-Assisted Review Transition

    The next frontier in scalable HITL — already in early production deployment at several large technology and financial services organizations — is AI-assisted review, where a second AI system helps the human reviewer by surfacing relevant precedents, flagging specific features of the input that drove the model’s decision, and predicting which aspects of the output are most likely to contain errors based on historical override patterns.

    This is not the same as using AI to replace human review. The human remains the decision authority. But the cognitive burden on the reviewer shifts from “evaluate this output from scratch” to “assess whether this AI-flagged concern is genuinely a concern.” Early results suggest this hybrid approach can reduce review time per item by 30–50% without reducing — and in some cases while improving — override rate and downstream error detection. As this pattern matures, it represents a plausible path to sustaining meaningful human oversight at volumes that would otherwise be unmanageable.

    Supervision as Infrastructure: The Closing Argument for Investing in HITL Design

    The frame of “human-in-the-loop as cost center” is ultimately the wrong frame, even though cost is real. The more useful frame is supervision as infrastructure — a foundational capability that enables the organization to deploy AI at scale with confidence, that provides the quality signal needed for continuous model improvement, that satisfies regulatory requirements without creating compliance theater, and that preserves institutional accountability in automated decision systems.

    Infrastructure investment decisions are made differently than operational expense decisions. When you build a payment processing system, you do not try to minimize the cost of fraud detection to zero — you invest in fraud detection as a capability that makes the entire payments system trustworthy and scalable. HITL oversight deserves the same framing: not “how little can we spend on this?” but “what is the oversight capability worth to our ability to deploy AI at scale and stand behind its outputs?”

    Actionable Takeaways for Teams Designing or Redesigning HITL Today

    1. Compute your per-decision review cost at current and projected volume before any other architectural decision. Know the number. It is almost always larger than teams assume when they include fully loaded labor costs, tooling overhead, and latency cost.
    2. Audit your current approval rates. If Tier 2 approval rates are consistently above 93–95%, you do not have a review process — you have an approval process. Diagnose whether the threshold is miscalibrated or automation bias has taken hold.
    3. Map your decision taxonomy by reversibility and error cost before choosing synchronous vs. asynchronous review mode. Not every AI decision needs pre-execution approval.
    4. Build routing logic as a standalone, reconfigurable service rather than embedding it in the model pipeline. Threshold recalibration should be a configuration operation, not a deployment event.
    5. Define explicit SLAs for each tier and assign ownership for SLA compliance. Unowned SLAs are advisory documents that will be violated as soon as volume pressure arrives.
    6. Invest in override rationale capture. The qualitative signal in reviewer overrides is the highest-ROI input to model improvement, and most HITL systems throw it away by capturing only binary outcomes.
    7. Run your HITL architecture through a 10x volume stress test before committing to a design. If it requires proportional headcount scaling, it will fail at scale. Redesign it now while the decision is cheap.

    Supervision is expensive. But poorly designed supervision is far more expensive — it costs all the money of proper oversight and delivers none of the quality. The difference between HITL as a liability and HITL as a strategic capability is almost entirely an architectural and operational design question. The organizations that figure this out early will be the ones running AI systems at the next order of magnitude without rebuilding their oversight stack from scratch every time the volume doubles.

  • Silent-First SBV Hooks: How to Build a System That Converts When No One Is Listening

    Silent-First SBV Hooks: How to Build a System That Converts When No One Is Listening

    Smartphone showing a muted video ad with bold text overlay 'SOUND OFF. Still Watching.' — illustrating silent-first SBV hook design with stat: 85% of social video plays on mute

    Here is the uncomfortable truth about your Sponsored Brands Video ads: the majority of shoppers who see them will never hear a single word you say. No voiceover. No product jingle. No carefully crafted audio cue. The sound is off, the scroll is on, and your ad has roughly three seconds to say something — visually — before the shopper moves on forever.

    This is not a niche edge case. Across major social and shopping platforms, between 70% and 85% of video impressions begin autoplayed and muted. On Amazon specifically, Sponsored Brands Video (SBV) autoplays without sound by default; audio only kicks in if a shopper actively taps. Most never do. The format is, by design, a silent medium.

    Yet most SBV creatives are still built the other way around. Teams spend budget on professional voiceovers, write scripts that depend on spoken narrative, and treat captions as an afterthought — a box to check for accessibility rather than the primary communication layer. The result is an ad that works fine in a quiet living room and is essentially invisible everywhere else.

    This post is about fixing that at a systems level. Not just adding captions. Not just putting text on screen. Building an end-to-end production and testing framework — a hook library, a modular shoot structure, a variant testing protocol, and a feedback loop — that treats silence as the baseline condition your creative must survive before anything else.

    The numbers make a compelling case for getting this right. SBV currently delivers a click-through rate of approximately 0.89%–1.0%, which is roughly 2.6 times higher than static Sponsored Brands headline ads. Conversion rates sit around 11%. Those are category-level averages, which means the gap between a well-built silent hook and a poorly built one is considerably wider than those benchmarks suggest. This post is about closing that gap systematically.

    Why SBV Lives and Dies in the First 3 Seconds (and Sound Has Nothing to Do With It)

    Infographic showing the 3-second hook zone on a video timeline, with split-screen comparison of a logo-first intro (SKIP) versus a product-first text hook (WATCH), with stat: 2.6x higher CTR with strong silent hook

    The three-second window is not a metaphor. It is a measurable, documented behavioral boundary that determines whether a video ad gets a click or disappears into the feed without a trace. Understanding exactly why that window exists — and what is happening inside it — is the foundation of building a reliable hook system.

    The Cognitive Economics of Muted Autoplay

    When a shopper is scrolling through Amazon search results or a social feed, they are operating in a high-decision-velocity environment. Every impression is evaluated in a fraction of a second. The brain’s first question is not “do I want this product?” It is a much simpler, more primitive question: “Is this worth a moment of my attention?”

    Sound does not get to participate in that question. By the time the brain has processed the first frame visually and made a preliminary continue/scroll decision, the audio — even if it were playing — would not have had enough time to deliver a meaningful signal. The visual channel is simply faster. This is why the silent-first constraint is not a bug in SBV. It is a clarifying design brief: make the first frame carry the entire initial value proposition, because nothing else will.

    The practical implication is that your opening frame is functioning more like a print ad than a video ad. It needs to communicate a clear benefit, show the right subject, and create a reason to keep watching — all before motion, music, or voice have contributed anything. Teams that internalize this distinction build fundamentally better hooks.

    What the Data Says About the Drop-Off Curve

    Video retention data consistently shows a steep drop-off in the first two to three seconds, followed by a much flatter curve for viewers who make it past that initial window. This pattern holds across SBV, TikTok, Reels, and YouTube Shorts. The implication is binary: either your hook is strong enough to clear the initial threshold, or the video’s quality beyond that point is irrelevant to most of your audience.

    For SBV specifically, the 6-to-45-second allowed duration creates an interesting strategic tension. The format supports longer storytelling. But the vast majority of viewers will never experience the second half of even a 15-second ad unless the first three seconds earned their continued attention. Completion rates for well-optimized 15-to-30-second SBV creatives run around 60%, which sounds respectable until you factor in that the hook was the gatekeeper who let those viewers in.

    The Sound-On Minority Is Not Your Primary Design Constraint

    This is a point that needs to be stated plainly because it runs counter to how most video production teams are trained to think. Sound-on viewers are a minority, and they are not the constraint that determines your ad’s scalable performance. Design for the muted majority first. If your hook works silently, sound-on viewers get a bonus layer of information. If your hook only works with sound, you have already lost the majority of your impressions before a word is spoken.

    This does not mean audio is unimportant — far from it. But in the hook-building context, audio is a reinforcement layer, not a primary communication channel. Build the visual and text layer to carry the full weight first, then layer audio on top to enhance the experience for those who choose to engage with it.

    The Four Hook Archetypes That Drive SBV Performance

    Four SBV hook archetypes shown in a 2x2 grid: Problem-Solution, Product-First, Outcome/Proof, and Curiosity/Intrigue — each with a distinct visual style and labeled with when to use each type

    Not all hooks work the same way or for the same products. Before you can build a systematic hook library, you need to understand the structural vocabulary of hook types — what each one does mechanically, which product categories and buying stages they serve, and how they translate into a silent visual format.

    There are four archetypes that dominate high-performing SBV creative, and the best hook libraries contain examples of all four.

    Archetype 1: Problem-Solution

    The problem-solution hook opens with the pain, not the product. Frame one names or visualizes a frustration that the target shopper actually experiences, then — within two to three seconds — positions the product as the resolution. The silent version of this typically works as a two-panel or before/after visual with a short text overlay naming the problem explicitly: “Cord tangling driving you insane?” or a visual of the problem state itself with zero text needed because the problem is instantly legible.

    This archetype works especially well for products solving practical, familiar frustrations: kitchen organization, back pain, pet mess, sleep quality, time waste. The emotional recognition is instantaneous and requires no audio explanation. The viewer sees their own problem reflected back at them, which creates a micro-moment of identification that earns continued attention.

    The critical execution risk with problem-solution hooks is dwelling too long on the problem. In a silent-first context, you have approximately one second to establish the problem before the viewer’s pattern recognition kicks in and they want to see the solution. Two seconds on the problem, one second on the resolution reveal — that is the cadence to aim for.

    Archetype 2: Product-First

    The product-first hook opens with the hero product in a visually strong, immediately recognizable shot — ideally in motion or showing its defining characteristic. There is no setup, no context-building, no narrative preamble. The product appears on screen within half a second, accompanied by a single bold text overlay naming the primary benefit or differentiator.

    This archetype works best for products with strong visual identity — items where the product itself is the hook because it looks different from what the shopper expected to find. Premium kitchenware, distinctive gadgets, visually bold apparel, and unique packaging are natural fits. It also performs well in lower-funnel retargeting contexts where the shopper already knows the category and needs only to be reminded of this specific product’s standout quality.

    The execution discipline required here is ruthless simplicity. One product, one dominant feature, one text claim, all delivered before the first second is complete. Any additional visual information in frame one competes with the primary message and weakens the hook.

    Archetype 3: Outcome-Proof

    The outcome-proof hook leads with a result, not a product feature. The opening frame shows a demonstrable outcome — a before/after transformation, a completed result, a testimonial screenshot with a specific data point — and the product is introduced as the mechanism that produced it. In the silent format, this typically manifests as a results visual (a clean organized space, a fitness transformation, a completed project) with a text overlay quantifying the outcome: “Assembled in 8 minutes flat” or “From zero to 4.8 stars in 60 days.”

    This archetype is particularly effective for products where skepticism is a purchase barrier. When a shopper has been disappointed by similar products before, leading with the outcome bypasses their defensive filters more effectively than leading with the product or the problem. It answers the question “but does it actually work?” before the question is even formed.

    Archetype 4: Curiosity-Intrigue

    The curiosity hook opens with an incomplete visual or a text overlay that raises a question without immediately answering it. It leverages the brain’s natural discomfort with informational gaps — the Zeigarnik effect — to compel continued watching. “You’ve never seen a [product category] do this” or a close-up of an unusual product application where the product itself is not yet identifiable both create the kind of cognitive itch that keeps the scroll finger still.

    This archetype requires the most careful execution in a silent context because it depends entirely on visual intrigue, not audio storytelling. The reveal must come within two to three seconds or the viewer disengages. It works best for genuinely novel products or for demonstrating unexpected product capabilities that the shopper would not anticipate from the category.

    First-Frame Engineering: What Your Opening Shot Must Accomplish

    If there is a single discipline that separates brands running mediocre SBV from those running high-performing SBV, it is first-frame engineering — the deliberate, systematic design of the opening shot as a standalone communication unit capable of doing its entire job in isolation.

    The Five-Element Framework for Frame One

    Every opening frame of a well-built silent-first hook needs to accomplish five things simultaneously. These are not sequential steps — they must all be present in a single frame:

    1. Subject clarity. The viewer must immediately understand what they are looking at. Ambiguity in the subject kills hooks faster than almost any other error. If your product is in the frame, it must be identifiable. If the problem is in the frame, it must be recognizable. A blurry, tight, or confusingly composed opening shot fails this test even if the text overlay is perfect.

    2. Motion or tension. A static frame is harder to hold attention on than one that contains motion or visual tension. Even a subtle move — a product rotating, a hand entering the frame, a reveal beginning — gives the visual cortex something to track and creates a forward-pulling momentum that earns the second second of watch time.

    3. A dominant text element. In a silent context, text in frame one is not optional. It is the primary spoken voice of the ad. This element should be large enough to read at a glance on a mobile screen, short enough to process in under two seconds (five to seven words maximum for the primary hook), and positioned in a zone that does not get obscured by UI elements on the platform.

    4. Contrast and legibility. Bold text on a low-contrast background is invisible to a scanning eye. The text layer in your hook needs to be designed for the worst-case viewing conditions: small screen, bright ambient light, sub-second attention. This typically means a semi-transparent dark background bar behind white text, or large enough type that it creates its own contrast against any background.

    5. An implicit question. The strongest opening frames leave one thing unanswered — a visual thread that only continuing to watch will resolve. This creates the micro-commitment that converts passive scrollers into active viewers, even if only for five more seconds.

    What to Eliminate From Frame One

    Equally important is understanding what frame one must not contain. Brand logos in the opening frame have been consistently shown to reduce hook performance — they signal “advertisement” before a value proposition has been established, triggering the mental skip reflex. Save the logo for the end card. Similarly, text-heavy information dumps in the opening frame — three bullet points, a feature list, competing headlines — create cognitive overload that causes the viewer to make a negative decision simply because processing costs too much in a fast-scroll environment.

    The opening frame is not a brochure. It is a door. Its only job is to get the viewer to step through it.

    Building Your Text Overlay Layer: Rules, Hierarchy, and Rhythm

    Technical annotation diagram of text overlay hierarchy for a silent-first video frame, showing three layers: Primary Hook Text (large, high contrast), Benefit Subtext (medium), and Caption/CTA (bottom), with size and contrast specifications

    Text overlays in a silent-first video are not subtitles. They are not a transcript of the voiceover. They are an independent communication layer with its own hierarchy, pacing, and design logic — and treating them like subtitles is one of the most common and costly mistakes in SBV production.

    The Three-Layer Text Architecture

    Effective silent-first text overlay design uses a three-layer architecture that maps to the viewer’s cognitive journey through the ad:

    Layer 1: The Hook Line (0–2 seconds). This is the largest, most prominent text in the video. It appears in frame one and its job is to stop the scroll. Five to seven words maximum. It communicates the primary hook — the problem, the claim, the question, or the differentiator. Typography should be bold, minimum 72pt equivalent at export resolution, and positioned in the upper or center zone of the frame.

    Layer 2: The Benefit Statement (2–8 seconds). This layer expands on the hook line with a secondary piece of information — typically a specific benefit, a product name, or a key differentiating detail. It appears after the hook line has had a moment to land, and it is smaller than Layer 1 but still clearly readable on mobile. Think of this as the body copy in a print ad: it exists for the viewer who engaged with the headline and wants to know more.

    Layer 3: Caption Track (throughout). Auto-captions or burned-in captions that transcribe spoken audio are essential for accessibility and for the subset of viewers who want full context without turning on sound. These should be styled to match the ad’s visual tone — not the default auto-caption box, which is often visually jarring — and positioned at the lower third in a way that does not overlap with the product or the first two layers.

    Text Pacing and On-Screen Timing

    One of the least-discussed variables in silent video hook design is the timing of text appearance. Text that appears and disappears too fast creates anxiety and prevents reading. Text that stays on screen too long becomes background noise and loses emphasis. The working rule is: if a viewer at average reading speed cannot comfortably read the text twice during the time it is on screen, the timing is too fast. For a five-word hook line, that means a minimum of 1.5 to 2 seconds on screen.

    There is also a pacing rhythm to consider across the full 15-to-20-second SBV window. Text that appears at regular intervals — roughly every three to four seconds — maintains reading engagement throughout the ad. Extended visual segments with no text in a muted context create dead zones where viewers who entered silently have nothing to parse.

    Typography and Font Choices

    For SBV and short-form video, sans-serif fonts with high stroke contrast — bold weights of geometric typefaces — read fastest and clearest on mobile screens at the small sizes at which these ads are typically viewed. Decorative fonts, thin weights, and all-italic text all reduce legibility under scrolling conditions. If your brand font does not meet these criteria for the hook layer, use it only for the end card branding and choose a legible system font for the primary text overlays.

    The Hook Library: Treating Creative as an Asset, Not a One-Off

    Workflow diagram: One master shoot feeding a Hook Variant Factory producing 10 different hooks, flowing into a Winning Hooks Bank ranked by Hook Rate, 3-Sec View, and CTR metrics. Header: One Shoot → 10 Hooks

    Most brands approach SBV as a project: a one-time creative effort that produces a video, runs until performance degrades, and then requires a new project to replace it. This project mindset is the structural reason most SBV underperforms. High-performing advertisers treat SBV as a system: a continuously evolving library of tested, categorized hook assets that can be recombined, updated, and replaced without starting from scratch.

    What a Hook Library Actually Contains

    A mature hook library is not just a folder of video files. It is a structured asset database with each hook catalogued by archetype, product category, target audience segment, test status, and performance data. At minimum, each entry should include:

    • The hook clip (the first 3–5 seconds of the video, as a standalone file)
    • The hook type (problem-solution, product-first, outcome-proof, curiosity-intrigue)
    • The primary text overlay copy (the exact words on screen)
    • The body content it was paired with (so you can distinguish hook performance from body performance)
    • Test date and campaign context
    • Performance data: hook rate, 3-second view rate, CTR, CVR
    • Status: untested, in test, winner, retired

    This structure allows your team to answer questions that a folder of videos cannot: “Which hook archetype performs best for this product category?” “Which text overlay formulas have we never tried?” “What does our fastest-growing segment respond to that our main audience doesn’t?”

    The Modular Hook Architecture

    The production efficiency of a hook library depends on building hooks as modular, interchangeable components. The standard approach is to create a single strong “body” for each SBV campaign — the product demonstration, benefit explanation, and CTA that form the core of the ad — and then produce multiple hook variants that can be swapped onto the front of that body without re-editing the rest of the ad.

    This modular structure means that a single two-hour shoot can produce enough raw material to build 8–12 distinct hook variants, each testing a different archetype, text overlay, or opening visual. The edit time per variant drops significantly because only the first three to five seconds changes between versions. Testing becomes faster. Iteration cycles compress from weeks to days.

    Seeding the Library: How Many Hooks to Start With

    For a new product or campaign, the minimum viable hook library for meaningful testing is three variants representing at least two different archetypes. With fewer than three variants, you do not have enough data range to draw conclusions about which direction to invest in further. With more than six variants live simultaneously, most teams do not have the budget distribution to reach statistical significance on individual variants quickly enough to act on the data.

    The practical starting point is four hooks: two problem-solution variants with different opening visuals, one product-first variant, and one outcome-proof variant. Let them run for a minimum of seven to ten days before drawing conclusions. The winners from that initial test become the seeds of your next production batch.

    Production Ops for Silent-First Video: A Practical Workflow

    The gap between understanding silent-first principles and consistently producing creatives that apply them is almost always an operational gap, not a knowledge gap. Teams know what good looks like. The friction is in translating that knowledge into a repeatable production workflow that does not depend on remembering to do things differently each time.

    The Pre-Production Brief Template

    Every SBV shoot should begin with a pre-production brief that includes a silent-first design section as a mandatory component. This section should specify:

    • The planned opening frame: what is visible, what motion occurs, and the exact text overlay copy for Layer 1
    • Hook archetype for each planned variant
    • Product visibility timing: at what second the hero product is first clearly visible
    • Text overlay timing plan: when each text layer appears and disappears
    • Sound-off watchability score: a mandatory pre-shoot question — “If we mute this ad completely, does the core benefit story still land?”

    Making this section mandatory in the brief — not optional or aspirational — is the operational intervention that changes production behavior. It forces the creative team to solve the silent-first problem before the camera rolls, rather than trying to fix it in post.

    Shoot Day: Capturing Hook-Specific Raw Material

    A silent-first shoot requires specific raw material that a standard product video shoot does not prioritize. Beyond the standard product beauty shots and demonstrations, the hook-optimized shoot list should include:

    Problem visualization shots — visual representations of the problem the product solves, without the product present. These are often neglected on standard shoots but are essential for problem-solution hooks.

    Extreme close-ups of defining product features — the detail that makes this product visually distinctive. These fuel product-first hooks and curiosity-intrigue hooks.

    Result/outcome shots — the after state, the completed result, the transformed environment. These power outcome-proof hooks and are frequently left off shoot lists because they require imagining the ad structure in advance.

    Multiple opening motion options — at least three different ways to begin the video, captured as separate takes. This gives the editor genuine options when building hook variants rather than forcing a single direction.

    Post-Production: The Hook-First Edit Review

    In most video production workflows, the edit review process evaluates the complete ad from beginning to end. The hook-first workflow adds a mandatory first review step: watch only the first three seconds of each variant, with sound muted, and evaluate whether the hook communicates value independently. If it does not pass this three-second muted test, the edit goes back before the full review is completed.

    This sounds simple. In practice, it requires deliberately breaking the habitual video review process, which naturally tends toward watching the full ad and then evaluating the opening in the context of the whole. The hook-first review inverts this — the opening is evaluated in isolation because that is how shoppers experience it.

    A/B Testing Hooks at Scale: The Metrics That Actually Matter

    A/B testing dashboard comparing two SBV hook variants: Variant A showing Hook Rate 22%, CTR 0.4%, CVR 7% versus Variant B showing Hook Rate 61%, CTR 1.1%, CVR 13%, with callout noting text overlay added to frame 1 produced 2.75x higher CTR

    Testing hooks without a clear measurement framework produces data that looks comprehensive but cannot actually tell you what to do next. The key is identifying which metrics measure hook performance specifically — as distinct from body content performance, product-market fit, or pricing — and building your test structure around those metrics.

    The Metrics Hierarchy for Silent Hook Testing

    Hook Rate (primary hook metric). Hook rate measures the percentage of people who watched past the first two to three seconds out of those who had the video in view. This is the most direct measure of hook effectiveness because it captures the binary continue/scroll decision. A hook rate above 50% is generally considered strong for SBV. Below 30% is a signal to change the hook before drawing conclusions from any other metric.

    3-Second View Rate (platform hook metric). On Amazon and most social platforms, a “view” is counted at three seconds. The three-second view rate — views divided by impressions — is the platform’s own hook quality signal. It also determines how your ad gets distributed algorithmically on platforms that use engagement signals for pacing. Low three-second view rates mean you are effectively paying for impressions that never register as views.

    CTR (post-hook engagement metric). Click-through rate measures what happens after the hook has done its job. It reflects the quality of the full ad experience, not just the hook, which means CTR alone cannot diagnose a hook problem. A low CTR with a high hook rate means the problem is in the body or the CTA, not the hook. A low CTR with a low hook rate means you have not yet solved the opening.

    CVR (conversion metric). Conversion rate — the percentage of clicks that result in a purchase — is largely determined by factors outside the ad itself: product-market fit, pricing, listing quality, reviews. Include it in your testing dashboard but do not use it as the primary metric for hook evaluation. Hook changes rarely move conversion rate significantly. They move CTR volume, which moves total conversions.

    Test Structure: Isolating the Hook Variable

    The cardinal rule of hook testing is to change only the hook and keep everything else constant. Same body content, same CTA, same targeting, same budget allocation. This sounds obvious, but it breaks down frequently in practice when teams want to also test a new lifestyle shot or a different offer in the same test round. Resist the temptation. When multiple variables change simultaneously, you cannot attribute performance differences to the hook specifically.

    The recommended test structure for a new product SBV campaign is:

    1. Set a minimum impression threshold before making decisions — typically 10,000–15,000 impressions per variant at minimum, to avoid drawing conclusions from statistically thin data.
    2. Run variants with equal budget allocation for the first seven to ten days.
    3. After the threshold is reached, pause the bottom 50% of variants by hook rate.
    4. Increase budget on the top performers and introduce one new hook variant to replace each paused variant.
    5. Repeat the cycle every two to three weeks.

    This iterative cycle — test, measure by hook rate, rotate out losers, introduce new challengers — is the engine that drives continuous hook library improvement. Teams that run one round of testing and declare a winner are leaving significant optimization on the table.

    Reading Failure Signals

    Hook data tells specific, actionable stories when you know how to read it. Low hook rate combined with normal impressions means the opening frame is failing — the subject, motion, or text is not stopping the scroll. High hook rate combined with low CTR means the hook is interesting but the product promise is not compelling enough to drive a click. High CTR combined with low CVR points to a listing problem, not a creative problem. Mapping these signal patterns to their root causes is what allows teams to make precise interventions rather than rebuilding everything when performance dips.

    Platform-Specific Adaptations: Amazon SBV vs. Reels vs. TikTok

    The silent-first principle applies across platforms, but the execution details differ meaningfully by platform context. A hook that works on Amazon SBV does not automatically transfer to TikTok Reels without adaptation, and understanding the behavioral and technical differences between platforms is essential for teams running multi-platform video creative.

    Amazon SBV: The Shopping-Intent Context

    Amazon SBV appears on search results pages and product detail pages — environments where the shopper already has purchase intent. They searched for something. They are actively evaluating options. This changes the hook calculus significantly compared to social platforms.

    On Amazon, the hook does not need to create desire from scratch. It needs to differentiate from the other results on the page and answer the question “why this one over the alternatives?” The most effective SBV hooks in a shopping-intent context are therefore product-first and outcome-proof hooks that speak directly to the decision being made, not curiosity-intrigue hooks that try to manufacture interest in an unfamiliar product.

    Amazon’s technical specs add additional constraints: SBV must be 6–45 seconds, with specific aspect ratio and file format requirements. The ad also runs in a placement that is often partially visible before being scrolled into view, which makes the very first frame — the thumbnail frame — critical. Many teams overlook the thumbnail as a hook element, treating it as a default first frame rather than a deliberately designed entry point.

    Instagram Reels and TikTok: The Discovery Context

    On social discovery platforms, the viewer has no declared purchase intent. The hook has a harder job: it must first earn attention in a competitive feed, then create product awareness, and only then guide toward intent. This shifts the optimal hook archetype away from product-first toward problem-solution and curiosity-intrigue — approaches that engage the viewer emotionally or intellectually before asking them to care about a specific product.

    The text overlay conventions also differ. On TikTok, large full-screen text overlays in the style of native TikTok content — bold, centered, with the TikTok aesthetic — dramatically outperform text styles that read as clearly branded advertising. Matching the platform’s native visual language in the silent text layer reduces the “ad detection” response that causes viewers to disengage before evaluating the content.

    YouTube Shorts: The Middle Ground

    YouTube Shorts occupies a behavioral middle ground — some viewers are in discovery mode, others are in search-and-evaluate mode. For SBV-style creatives repurposed to Shorts, a hybrid approach tends to work best: open with the problem or intrigue (discovery mode) and transition quickly to the product and outcome (evaluation mode) within the first three to five seconds.

    YouTube Shorts also allows for slightly longer text overlays to remain on screen, because the viewing context is somewhat more patient than TikTok’s fast-scroll environment. This gives slightly more room for the benefit statement layer to communicate before disappearing.

    Common Silent Hook Failures (and How to Diagnose Them Fast)

    Understanding what failure looks like in silent-first hooks is just as valuable as understanding what success looks like. Most hook failures fall into one of five recognizable patterns, and each pattern points to a specific fix rather than requiring a complete creative rebuild.

    Failure Pattern 1: The Logo-First Trap

    Opening with a brand logo or title card is the most common SBV hook failure pattern, and it is persistent because it feels professional and brand-safe. The logic seems reasonable: establish the brand, then make the pitch. The data consistently shows the opposite result. Logo-first opens signal “advertisement” to the viewer’s pattern-recognition system before any value has been established, triggering the mental skip reflex even in viewers who cannot articulate why they disengaged.

    Fix: Move the brand element to the end card. Open with the product, the problem, or the outcome. Earn the brand impression by delivering value first.

    Failure Pattern 2: Text That Cannot Be Read

    Small text, low-contrast text, decorative fonts, text placed in the lower third where it competes with platform UI, and text that appears and disappears too quickly are all common variations of this failure. In a silent context where text is the primary communication channel, illegible text is equivalent to muted audio — the message simply does not land.

    Fix: QA every SBV creative on an actual mobile device at arm’s length, in normal ambient lighting. If you cannot read the hook text in under one second without squinting, it is too small, too light, or too brief on screen.

    Failure Pattern 3: The Late Product Reveal

    Some SBV creatives open with atmospheric B-roll, lifestyle footage, or contextual scenes before showing the product. This is a narrative storytelling convention borrowed from longer-form video content. In a three-second decision window, it is a fatal pacing error. If the viewer cannot identify what is being advertised within the first two seconds, they have no reason to continue watching.

    Fix: The product — or the clearly recognizable problem the product solves — must be visible or directly implied by frame one. Context can follow. Establishment cannot precede the core communication.

    Failure Pattern 4: The Generic Benefit Statement

    Text overlays that say “High Quality” or “The Best [Category] You’ll Find” or “Perfect for Any Occasion” are functionally invisible. They communicate nothing that distinguishes the product and they do not create any reason to continue watching. In a silent context where text is the only voice, generic benefit language is worse than no text — it actively undermines credibility.

    Fix: Replace generic benefit statements with specific, concrete claims: “Charges 3 devices simultaneously,” “Fits under a standard door — no gap tape needed,” “Rated #1 by independent lab testing.” Specific claims pass the silent hook test; generic claims do not.

    Failure Pattern 5: The Sound-Dependent Payoff

    This failure is less visible but highly damaging: ads where the emotional or informational payoff of the hook is delivered through audio — a punchline, a surprising stat, a compelling endorsement — that muted viewers will never receive. The visual portion of the hook creates curiosity, but the resolution of that curiosity requires sound. This structure punishes the 70–85% majority of muted viewers by leaving their cognitive loop open.

    Fix: Map the full emotional and informational arc of the hook in text and visual form before adding audio. Every payoff, every resolution, every key claim should be readable and viewable. Audio then amplifies an already complete experience.

    From One Master Shoot to Ten Hook Variants: A Step-by-Step System

    The practical question most teams face when adopting a hook library approach is: how do we actually produce this volume of variants without proportionally increasing production costs? The answer is a structured extraction workflow that turns a single well-planned master shoot into a full library of testable hooks.

    Step 1: The Hook-First Shoot Planning Session

    Before any production planning begins, convene a one-hour hook planning session. The output of this session is a hook matrix: a grid with hook archetypes across the top (problem-solution, product-first, outcome-proof, curiosity-intrigue) and hook variants down the side (variant A, B, C, D for each archetype). For each cell in the matrix, the team agrees on the opening visual and the Layer 1 text overlay copy.

    This session should produce a list of 10–15 planned hook variants, each specified precisely enough that the videographer knows exactly what raw material needs to be captured to make each one possible. Many teams skip this step and plan the shoot around the product narrative, then attempt to extract hooks in post. The extraction is always more constrained and less varied than hooks planned at the source.

    Step 2: The Double-Shoot Protocol

    For each scene in the standard product shoot, capture a second take specifically designed for the hook version. The hook take is typically a tighter framing, earlier motion start, or more exaggerated visual that creates the stop-scroll impact the full-ad version does not need. This double-take protocol adds approximately 20–30% to shoot time but produces raw material that cannot be created any other way in post-production.

    Step 3: The Modular Edit Structure

    Build the master edit as three distinct, exportable components: the hook segment (0–4 seconds), the body segment (4–12 seconds), and the end card (12–20 seconds). Structure the project file so that any hook segment can be swapped onto the front of the body/end card combination and exported as a complete ad without restructuring the timeline. This modular architecture makes producing variant ten as fast as producing variant two, rather than requiring an increasingly complex edit with each new variant.

    Step 4: Text Overlay Variations Without Re-Shooting

    One of the fastest ways to expand hook variant count without additional shooting is to create multiple text overlay versions of the same opening visual. The same three-second product-first clip can support three distinct hook lines: a problem-oriented overlay (“Still dealing with [pain point]?”), a benefit-oriented overlay (“Charges in 45 minutes flat”), and a curiosity-oriented overlay (“Engineers called this impossible”). These three versions test fundamentally different hook strategies using the same visual raw material, at near-zero marginal production cost.

    Step 5: The Weekly Hook Review Cadence

    The system only functions as a system if there is a regular cadence for reviewing hook performance data and making production decisions. A weekly thirty-minute hook review meeting — attended by whoever manages campaigns, whoever manages creative, and whoever manages production scheduling — is the minimum viable cadence for keeping the hook library current. The agenda is simple: review hook rate and three-second view rate for all live variants, pause underperformers, identify what new variants to introduce, and confirm production timeline for the next batch.

    Teams that run this cadence consistently build compounding advantages. Each iteration cycle produces a slightly better average hook rate, because losing hooks are replaced by new challengers informed by what the data revealed about what works. After three to six months of consistent iteration, the performance gap between these teams and teams running static SBV creative becomes very difficult to close.

    Conclusion: The Silent Majority Is Your Most Important Audience

    The central shift that silent-first thinking requires is not technical — it is strategic. It asks teams to stop designing for the ideal viewing condition (headphones in, full attention, quiet room) and start designing for the modal viewing condition (muted, distracted, three seconds of patience). Most shoppers experiencing your SBV creative live in the modal condition, not the ideal one. Building for them is not lowering your standards. It is accepting reality and designing to meet it.

    The four archetypes give your hook library its vocabulary. First-frame engineering gives each hook its structure. The text overlay layer gives it its voice when audio is not available. The modular production workflow makes the system affordable to run at volume. The A/B testing framework tells you which direction to go next. And the weekly cadence keeps it all moving.

    None of these pieces is individually novel. The discipline is in connecting them into a functioning system rather than treating each element as a separate creative decision. When they work together, SBV stops being a format you occasionally publish content in and starts being a measurable, iterative performance channel.

    Actionable Takeaways:

    • Audit your existing SBV creative: mute every ad and watch only the first three seconds. If the core value proposition does not land, it needs a hook rebuild before any other optimization.
    • Build your first hook matrix before the next shoot. Specify at least four hook variants across two archetypes before the camera rolls.
    • Add hook rate and three-second view rate to your SBV reporting dashboard as primary metrics, above CTR.
    • Structure your project files modularly — hook segment, body, end card — so variant production is a minutes-long task, not a days-long edit.
    • Run a minimum weekly review of hook performance data and make rotation decisions based on those metrics, not on how long the ad has been live.
    • Test text overlay copy variations against the same visual hook before spending on additional raw production — many meaningful lifts are available without a single new shoot day.

    The majority of shoppers watching your ads right now are doing so in silence. The ones who stay are the ones you reached through what they could see. Building a system to reach more of them — systematically, testably, repeatably — is one of the highest-leverage investments available to SBV advertisers in 2026.

  • When Multi-Agent AI Breaks: The Operator’s Field Manual for Coordination, Control, and Cost

    When Multi-Agent AI Breaks: The Operator’s Field Manual for Coordination, Control, and Cost

    Multi-agent AI workflow control room with interconnected agent nodes and red warning indicators showing coordination failures

    The Coordination Gap That’s Quietly Killing AI Projects

    There’s a statistic that should give every operator pause before they architect their next AI system: UC Berkeley’s MAST study, analyzing over 1,600 execution traces across seven production multi-agent frameworks, found failure rates ranging from 41% to 87%. Not prototype failures. Not edge-case failures. Production failures, in live systems, on real workloads.

    What makes these numbers more troubling is why they fail. The dominant assumption in most AI teams is that failures are model failures — the LLM misunderstood the prompt, hallucinated a fact, or produced malformed output. The data tells a different story. The primary failure categories are system design issues, inter-agent misalignment, and verification gaps — all coordination-layer problems that have nothing to do with the quality of the underlying model.

    This means that how you architect the space between agents matters more than which model you put inside them.

    This guide is written for operators: the engineers, technical leads, and AI platform owners who are responsible for building systems that actually run in production, not just pass demos. We’ll cover the architectural decisions that determine whether your multi-agent system is controllable and observable, the cost dynamics that compound in ways most teams don’t anticipate, the security risks that live at every agent handoff, and the human oversight patterns that let you scale autonomy without losing control.

    This isn’t a framework tutorial. It’s a field manual for the problems that surface after you’ve deployed.

    The Architecture Decision You Have to Make Before You Write Any Code

    Side-by-side diagram comparing deterministic workflow chains versus dynamic agent decision loops

    Before selecting a framework, choosing a model, or designing a single agent role, operators need to answer a foundational question that most teams skip: Are you building a workflow or an agent system?

    Anthropic’s engineering team, which has worked with dozens of teams building production systems, draws a distinction that matters operationally: workflows are systems where LLMs and tools are orchestrated through predefined code paths, while agents are systems where LLMs dynamically direct their own processes and tool usage, maintaining control over how they accomplish tasks. Both are valuable. Confusing them is where projects go wrong.

    When Workflows Are the Right Answer

    Workflows are defined by predictability. Each step is explicitly sequenced, the flow is determined by code rather than by model reasoning, and the output of each stage is the input to the next in a known, testable manner. If your task can be decomposed into fixed subtasks — generate a draft, then check it against a policy, then format it for output — you almost certainly want a workflow, not an agent.

    The operational advantages are significant. Workflows are easier to test because each node has a defined contract. They’re easier to debug because failures localize to specific steps. They’re more cost-predictable because you can enumerate the calls in advance. And they’re more compliant with governance requirements because the decision path is deterministic and auditable.

    Common production-proven workflow patterns include:

    • Sequential pipeline: Fixed step-by-step chains where each agent’s output feeds the next. Ideal for repeatable business processes like document processing, content generation pipelines, or data enrichment flows.
    • Prompt chaining with gates: A variant of sequential pipelines where programmatic checks validate intermediate outputs before proceeding, preventing downstream errors from compounding.
    • Parallelization: Multiple agents process different aspects of the same input simultaneously, with results aggregated. Useful when tasks are independent — running competitive analysis, legal review, and technical validation on a contract at the same time rather than sequentially.

    When You Actually Need Agent Autonomy

    Agents are appropriate when the task space is genuinely open-ended: when the path to completion can’t be known in advance, when decisions need to be made based on intermediate results, or when the workflow itself needs to adapt based on what the system discovers. Research tasks, complex multi-step problem-solving, and scenarios requiring tool use conditioned on real-time feedback are legitimate use cases for dynamic agent behavior.

    The tradeoff is real and should be stated plainly in your architecture document: agents trade latency and cost for flexibility. Every time an LLM decides what to do next rather than following a predetermined code path, you’re accepting variability in behavior, increased token consumption, and more complex observability requirements.

    The Production Pattern That Works Most Often

    In practice, the most reliable production multi-agent systems use a supervisor/planner-worker pattern: a central orchestrator agent that plans and routes tasks, delegating to specialized sub-agents that are essentially stateless workers with narrow, well-defined responsibilities. This hybrid gives you the flexibility of agent reasoning at the planning layer while preserving workflow-like predictability at the execution layer.

    Anthropic’s guidance on this is direct: start with the simplest solution possible, and only increase complexity when needed. Many teams fail not because they built too little but because they built agent systems for problems that a simple three-step prompt chain would have solved more reliably and cheaply.

    State Is the Hard Part: Why Most Agent Handoffs Fail

    If you survey teams running multi-agent systems in production and ask them where they spend most of their debugging time, the answer is overwhelmingly consistent: state management and agent handoffs. Not prompt quality, not model selection, not tool reliability. The space between agents.

    The root cause is a deceptively simple architectural habit: treating state as implicit conversation history rather than as an explicit, typed data structure that is actively managed. When Agent A passes its entire message history to Agent B, you’re not doing state management — you’re doing context dumping. The receiving agent has to infer what actually matters from an unstructured blob of text, which introduces ambiguity, context window pressure, and compounding errors as the workflow progresses.

    Explicit State Models Are the Production Default

    Production systems in 2026 have converged on treating shared state as a first-class architectural object. This means defining a typed schema — a structured data model — that represents the canonical workflow state. Each agent reads from this shared state store, performs its task, and writes back structured results. Handoffs are not “send everything to the next agent.” They are typed transitions: “here is the specific subset of state this agent needs to receive, and here is the contract for what it must write back.”

    LangGraph formalizes this with its StateGraph model, where every node receives a typed state object and returns a typed state update. This design makes the state transitions explicit, testable, and inspectable at every step — which is foundational for debugging and for building replay and recovery capabilities.

    The Three State Failure Patterns to Watch For

    Understanding the most common failure modes helps teams build defenses before they encounter them in production:

    • State bloat: The shared state object grows unbounded as agents add context without pruning it. This drives up token costs on every subsequent agent call (since each agent loads the full state into its context window) and can eventually exceed context limits, causing silent truncation or hard failures. The fix is explicit state pruning policies — define what gets archived versus what stays in the active state object.
    • Conflicting writes: When multiple agents run in parallel and can both write to the same state fields, you get race conditions and overwrites. In distributed systems, this is a classic problem solved by transactions and locks. In multi-agent systems, it’s often ignored until it produces corrupted state. Design your state schema so that parallel agents write to distinct fields, with a merge step that explicitly resolves conflicts.
    • Semantic drift: The meaning of a state field changes as it passes through agent hands. Agent A writes summary as a technical overview; Agent C expects summary to be a customer-facing description. The type system doesn’t catch this — both are strings. The fix is documentation-first state schemas, where every field has a semantic contract, not just a type.

    Checkpointing and Recovery

    Long-running multi-agent workflows need durable state checkpointing. If an agent fails at step seven of a fifteen-step workflow, you need to be able to resume from step seven — not restart from step one. This requires a workflow engine that persists state snapshots at defined intervals, with replay capabilities that can reconstruct the workflow from any checkpoint.

    LangGraph’s persistence layer and durable workflow engines like Temporal address this directly. Teams building on raw API calls without this infrastructure typically discover the need for it the hard way, after a long-running task fails in the final stages for the third time and they’re paying for the retry from scratch.

    The Framework Tradeoffs Nobody Tells You

    The three dominant multi-agent orchestration frameworks in 2026 — LangGraph, CrewAI, and AutoGen/AG2 — are genuinely different products for different operator needs. Most framework comparisons focus on feature lists. Operators need to understand the operational tradeoffs: what each framework makes easy, what it makes hard, and what that means for your maintenance burden over a 12-month horizon.

    LangGraph: Maximum Control, Maximum Responsibility

    LangGraph is the choice for teams that need deterministic, production-grade orchestration where the control flow cannot be left to model interpretation. Its core mental model is an explicit state graph: you define nodes, edges, and a typed shared state schema. The LLM reasons within nodes; it does not control the graph structure.

    The operational advantage is significant: LangGraph gives you the most inspectable, debuggable, and controllable multi-agent architecture available. Every state transition is auditable. The graph structure is readable by a human. Integration with LangSmith provides distributed tracing out of the box.

    The tradeoff is that LangGraph requires more upfront investment. You need to model your workflow as an explicit graph, define your state schema in advance, and write the routing logic explicitly. For teams with a clear, stable workflow that needs to run reliably at scale, this investment pays back. For teams prototyping in a fast-changing environment, it can feel like over-engineering in the early stages.

    CrewAI: Fast Role-Based Workflows with a Governance Ceiling

    CrewAI’s mental model is a team of agents with defined roles, goals, and tools. You describe what each agent does and who coordinates them; the framework handles much of the orchestration mechanics. This makes it the fastest path to a working multi-agent prototype, particularly for business workflow automation where the “team” metaphor maps naturally to the task — a research agent, a writing agent, a fact-check agent.

    The governance ceiling appears at scale. Because CrewAI abstracts much of the orchestration, operators have less visibility into and control over exactly how tasks are decomposed, delegated, and resolved. For regulated industries, complex compliance requirements, or systems where you need to audit every decision, this abstraction becomes a liability. CrewAI works well when you need speed-to-prototype and your governance requirements are modest. It struggles when you need to explain exactly what happened and why.

    AutoGen/AG2: Conversational Collaboration for Code-Heavy Workloads

    AutoGen’s paradigm is agent-to-agent conversation: agents exchange messages with each other to collaborate on a task, with the conversation driving the workflow. This makes it exceptionally well-suited for research-style tasks and software development workflows where agents need to iteratively refine outputs through dialogue — a coder agent produces code, a critic agent reviews it, the coder revises based on feedback.

    The operational challenge with AutoGen is conversation length management. When agents converse, context windows fill up fast, and the longer the conversation, the more prone the system is to losing coherence or looping. Teams running AutoGen in production need explicit conversation management policies: when to summarize, when to reset context, and how to prevent unbounded conversation depth.

    The Rule No Framework Can Override

    Anthropic’s engineering team states this plainly: frameworks simplify standard low-level tasks but often create extra layers of abstraction that obscure the underlying prompts and responses, making them harder to debug. Their recommendation — start by using LLM APIs directly, and only adopt a framework when the manual implementation overhead genuinely justifies it — is worth taking seriously.

    The best operators know their framework’s internals well enough to step outside it when needed. Incorrect assumptions about what’s happening under the hood are among the most common sources of production failures.

    Cost Compounds Faster Than Your Team Expects

    Bar chart showing token cost multipliers for multi-agent AI architectures from single agent baseline to 30x for complex spawning hierarchies

    Single-agent AI has a predictable cost profile: you make a call, you pay for the tokens. Multi-agent AI has a multiplication problem that most operators don’t model until they see their first month’s API bill.

    Current data puts the token overhead for multi-agent systems at 5x to 30x a comparable single-agent setup, depending on architecture. A simple three-to-five agent pipeline typically runs at 5x the token cost of a direct single-agent approach. Parallel fan-out architectures with multiple concurrent agents can reach 15x. Complex hierarchical systems with spawning sub-agents — where a planner agent creates new agents to handle sub-tasks — can reach 30x or higher on complex inputs.

    Per-task costs in the $4 to $30 range for moderate workflows and $25 to $100+ for complex architectures are well-documented in production environments. At low volume, this is manageable. At the scale where multi-agent systems become interesting, this arithmetic demands deliberate cost architecture.

    The Four Cost Drivers to Engineer Against

    Understanding the mechanisms of cost multiplication helps operators address them at the design stage rather than after deployment:

    • Repeated context loading: Every agent call that loads the full shared state or conversation history into its context window pays for every prior token, again. A 10-agent sequential pipeline where each agent loads the full prior context doesn’t just cost 10x a single call — it costs 1 + 2 + 3 + … + 10 times the base call cost. The fix is selective context passing: give each agent only the state fields it needs, not the entire history.
    • Verification and retry loops: When agents validate each other’s outputs and request revisions, you pay for multiple model calls to accomplish what a single well-designed prompt might handle. Excessive retry loops are both a cost signal and a quality signal — they usually indicate that the upstream agent’s output specification or the validation agent’s criteria are insufficiently precise.
    • Spawning without bounds: Planner agents that can dynamically create sub-agents are powerful but dangerous from a cost perspective. Without hard limits on spawning depth and agent count, a complex input can trigger an exponential expansion of the agent graph, each leg consuming tokens. Set hard limits — both on the number of agents that can be created and on the maximum nesting depth of sub-agent hierarchies.
    • Model misallocation: Using frontier models for every agent in a workflow is the most common, most avoidable cost waste. Routing tasks — deciding which agent handles what — doesn’t require GPT-4 class reasoning. Formatting agents, summarization agents, and classification agents can often run on smaller, cheaper models with no meaningful quality loss. Model routing by task complexity is a cost governance primitive, not an optimization afterthought.

    Hard Budgets and Circuit Breakers

    Effective cost governance in multi-agent systems treats token budgets as financial controls, not soft suggestions. This means implementing hard per-task, per-agent, and per-workflow token caps at the orchestration layer — not as prompt instructions (agents don’t reliably enforce their own token consumption) but as platform-level enforcement. If a workflow exceeds its token budget, it fails gracefully with an informative error rather than running to completion at five times the projected cost.

    Circuit breakers extend this further: they detect anomalous cost patterns — a workflow consuming 10x its typical token volume, or an agent retry count exceeding threshold — and pause execution for human review. This is especially important during the first weeks after deploying a new workflow in production, when edge cases that weren’t covered in testing can trigger expensive runaway loops.

    Prompt and context caching — where identical or near-identical context passed to multiple agents in the same session can be served from cache rather than recalculated — provides meaningful savings on workflows with shared system context or background information. Most major model providers now support this; it’s worth verifying your framework passes cache-eligible context correctly.

    Observability or Blindness: You Cannot Debug What You Cannot Trace

    Multi-agent AI observability dashboard showing trace waterfall diagram with agent steps, timing, costs, and a red failure indicator

    A single-agent system fails in a visible way: you made a call, you got a bad response, you know exactly what the model received and what it returned. A multi-agent system fails in a distributed way: by the time the final output is wrong, the root cause may have originated three or four agent calls earlier, been silently amplified by each subsequent agent, and arrived at the output layer looking like a model quality problem when it was actually a context contamination problem in step two.

    This is why the expert consensus in 2026 is categorical: observability is not optional infrastructure for multi-agent systems. It is foundational architecture. Teams that treat tracing and monitoring as a later concern — something to add after the system is working — spend months debugging in the dark.

    What Production Tracing Actually Requires

    Effective observability for multi-agent workflows requires tracing at a different granularity than standard application monitoring. You need to capture, at minimum:

    • Span-level traces per agent call: Each agent invocation is a span, with a parent span for the overall workflow. The trace tree shows you the full execution graph — which agents ran, in what order, for how long, with what cost.
    • Full input/output logging per agent: Not just “Agent B ran.” What exact input did Agent B receive? What exact output did it return? What tools did it call, with what arguments, and what did those tools return? Without this, you cannot reconstruct failure scenarios.
    • Token and cost attribution per span: Which agent in a workflow consumed what proportion of the total tokens? This both supports cost optimization and surfaces agents whose token consumption is anomalously high — often a signal of poorly scoped instructions or state bloat.
    • State snapshots at key checkpoints: Capturing the shared state object at the beginning and end of each major stage gives you the ability to replay workflows from any point, test modified agents against historical state snapshots, and conduct post-mortems on failed runs without needing to reproduce the input conditions.

    The OpenTelemetry Layer

    The emerging standard is OpenTelemetry-based tracing applied to multi-agent workflows, with LLM-specific instrumentation libraries extending standard OTEL spans to capture model-specific metadata: token counts, model IDs, temperature settings, prompt templates, and evaluation scores. Tooling in this space has matured significantly — platforms like LangSmith, Arize Phoenix, and Weights & Biases now offer purpose-built multi-agent trace visualization that shows the full agent interaction graph as a single coherent trace, rather than disconnected individual model calls.

    Honeycomb’s Agent Timeline product takes this further by allowing operators to annotate traces with business context — correlating a trace showing a failed agent handoff with the downstream business outcome it affected, which closes the loop between technical observability and business impact measurement.

    Eval-Driven Debugging

    The most sophisticated teams are building evaluation pipelines that run automatically against production traces. When a workflow produces an output that scores below threshold on a quality metric, the system automatically captures the full trace, the input, the output, and the intermediate state at each step — creating a labeled failure case that can be added to a regression test suite and used to identify the exact agent and step where quality degraded.

    This “trace to eval” pipeline turns production failures from debugging emergencies into structured data. Over time, it builds an empirical map of which agent interactions are most fragile under which input conditions — the kind of knowledge that turns reactive firefighting into proactive system improvement.

    Trust Boundaries and the Security Risk Hidden in Every Handoff

    Multi-agent AI security diagram showing prompt injection point at Agent B with contamination spreading downstream through agent chain

    Multi-agent systems have a security property that single-agent systems do not: the output of one agent becomes the input of another. If an attacker can influence the output of Agent B, they have an indirect channel into every downstream agent that receives Agent B’s output as input. This is not a hypothetical attack surface. It is the dominant production AI security risk in 2026, sitting at the top of the OWASP Top 10 for LLM applications.

    Audits of production multi-agent systems in 2026 found prompt injection vulnerabilities present in approximately 73% of systems reviewed. The attack vector is straightforward: content that an agent processes as data — a web page it scrapes, a document it analyzes, a database record it reads — contains embedded instructions that hijack the agent’s behavior. In a single-agent system, this affects that one call. In a multi-agent system, the hijacked agent’s output flows downstream, and any agent that trusts that output without validation is now operating under attacker influence.

    The Zero-Trust Mindset for Agent Architecture

    The expert consensus has moved clearly in one direction: treat every agent handoff as a trust boundary. The receiving agent should not assume that the context it receives from a prior agent is clean. This doesn’t mean every agent runs full adversarial validation on every input — that would be prohibitively expensive and create latency problems. It means designing the system architecture to contain the blast radius of a compromised agent.

    Practical zero-trust principles for multi-agent systems:

    • Principle of least privilege for tools: Each agent should only have access to the tools and external systems it specifically needs for its task. An agent that reads from a database should not also have write access unless that is explicitly required by its role. Over-permissioned tools turn a compromised agent into a much larger incident.
    • Input validation at handoff boundaries: Define a typed schema for each agent’s expected inputs and validate incoming messages against it before the agent processes them. Inputs that don’t conform to the schema should be rejected, not silently coerced. This catches both injection attempts and upstream agent errors.
    • Privileged action separation: High-blast-radius actions — writing to databases, sending external communications, modifying files, making API calls with side effects — should be executed by a dedicated action-execution layer that sits outside the agent reasoning chain. Agent reasoning produces a structured action proposal; a separate, more rigidly controlled layer executes it after validation.
    • Sentinel agents for governance: The most mature deployments include dedicated security or governance agents that review the outputs of reasoning agents before those outputs are passed downstream or executed. The sentinel doesn’t have tools or write access — its only job is to evaluate whether an output contains policy violations, injection signatures, or anomalous instructions.

    Identity and Auditability for Multi-Agent Systems

    As agent systems take consequential actions — sending emails, submitting transactions, modifying records — the question of “which agent did this, on whose authorization” becomes both a security question and a compliance question. Production systems need cryptographically signed agent identities and an immutable audit trail that records not just what was done, but which agent proposed it, which agent or human authorized it, and which agent executed it.

    This is not just a governance formality. When an incident occurs, the audit trail is how you reconstruct the causal chain, identify the point of failure or compromise, and demonstrate to regulators or customers what happened and why. Multi-agent systems without this infrastructure cannot meet compliance requirements in regulated industries, full stop.

    Human-in-the-Loop Oversight That Scales Without Becoming a Bottleneck

    Three-tier human oversight model for AI agents showing autonomous zone, async review tier, and hard stop tier with example actions

    About 70% of organizations running AI agents in 2026 operate a model where the agent recommends and a human approves before any irreversible or external-facing action is executed. This is the right instinct. The problem is that naive human-in-the-loop implementation doesn’t scale — it turns into a queue of agent outputs that a human must review and approve, becoming a bottleneck that negates the speed and automation value the multi-agent system was supposed to provide.

    The shift that’s happening across enterprise deployments is from “human in the loop on every step” to “human on the loop for exceptions.” Agents operate autonomously within defined boundaries; humans are notified and can intervene when the system detects that those boundaries have been exceeded. This is a governance design problem, and solving it well is one of the characteristics that distinguishes teams that get value from multi-agent AI from teams that get a slow, expensive, human-bottlenecked process.

    Tiered Risk Classification: The Foundation of Scalable Oversight

    Scalable human oversight starts with classifying every action type your multi-agent system might take into three risk tiers:

    • Tier 1 — Autonomous: Low-risk, reversible, internal actions where the cost of an error is low and correctable. Reading data, generating drafts for human review, updating internal notes, running analyses. Agents act without human approval; the action log is available for retrospective review.
    • Tier 2 — Async review: Medium-risk actions with moderate consequences or moderate reversibility. Sending internal communications, creating external-facing drafts, updating customer records, scheduling actions with a future execution window. The agent proposes the action and proceeds, but the responsible human receives a notification with a review window — if the human takes no action within the window, the action proceeds; if they flag it, execution is paused.
    • Tier 3 — Hard stop: High-risk, irreversible, or policy-sensitive actions. Sending external communications to customers or partners, executing financial transactions, deploying to production, deleting records, changing access permissions. Execution is blocked until a human explicitly approves the proposed action.

    The specific actions that belong in each tier will vary by organization and domain, but the structure is consistent across most production deployments. Importantly, the tier assignment should be enforced at the platform level, not by prompting the agent to self-assess its risk. Agents are not reliable risk classifiers for their own actions. The platform decides; the agent executes.

    Escalation Routing and Approval Latency

    Tier 3 approvals create a latency problem: the workflow is blocked waiting for a human. Designing this well means minimizing both the frequency of Tier 3 triggers (by scoping agent authorities appropriately) and the time-to-approve when they do trigger (by routing approvals to the right person with the right context).

    Smart approval routing sends the approval request to the human most likely to be able to evaluate it quickly — the product owner for content approvals, the finance lead for transaction approvals — with a pre-formatted summary of the proposed action, the context that led to it, and the options available (approve, reject, edit, escalate). The goal is to give the approver everything they need to decide in under 30 seconds, not a raw dump of agent conversation history.

    Timeout policies matter too. If an approval request goes unresponded for a defined window, the workflow should fail safely — not proceed without approval, not silently abandon the task, but surface explicitly as a timed-out approval with the relevant human notified of the pending item in their queue.

    The Audit Trail as Organizational Memory

    Every approval gate interaction — the proposed action, the human decision, the timestamp, the reviewer identity, the context at the time of decision — is valuable organizational data. Over time, approval gate logs reveal patterns: which action types are most frequently rejected (signal that the agent’s judgment needs recalibration), which approval requests take the longest to process (signal that routing or context presentation needs improvement), and which reviewers are approving at rates significantly higher or lower than peers (signal for calibration discussions).

    Teams that review approval gate telemetry monthly consistently find opportunities to either expand autonomous operation (moving frequently-approved action types to Tier 2 or Tier 1) or tighten agent authority (recognizing that certain action types are being rejected more than anticipated). This continuous calibration is what allows human oversight to remain meaningful as the agent system scales, rather than degrading into rubber-stamping.

    When to Flatten Your Hierarchy: The Over-Engineering Trap

    Multi-agent architecture has an aesthetic pull. Hierarchical systems with specialist agents, orchestrators, validators, and governance layers look sophisticated in architecture diagrams. Teams that build them feel like they’re doing serious AI engineering. This aesthetic pull is one of the most reliable predictors of project failure.

    The failure mode is architectural over-complexity: building a six-agent hierarchical system for a problem that a two-step prompt chain would solve more reliably, more cheaply, and with less operational overhead. Every additional agent you add is a coordination cost, a potential failure point, an additional source of context window consumption, and another moving piece to monitor and debug.

    The Simplest System That Solves the Problem

    Anthropic’s engineering guidance is blunt on this point: for many applications, optimizing a single LLM call with retrieval and in-context examples is sufficient. Most teams building agentic systems should regularly ask: does this actually require agent autonomy, or would a well-designed prompt chain with a few tool calls accomplish the same thing?

    The signals that a system is over-architected for its problem:

    • Most agent handoffs carry the same context forward unchanged. If Agent C mostly passes Agent B’s output to Agent D with minor formatting changes, Agent C is probably unnecessary.
    • Failure rates are higher than a single-agent equivalent. Each agent you add to a chain multiplies the failure probability. If a sequential five-agent pipeline each have a 95% success rate, the end-to-end success rate is 0.95^5 ≈ 77%. A simpler system with two agents might achieve higher end-to-end reliability even if each individual step is slightly lower quality.
    • The system requires constant human intervention to stay on track. If operators frequently need to restart workflows, manually correct intermediate outputs, or override agent decisions, the system’s autonomous capability is largely theoretical. Simplifying the architecture often produces better actual autonomy than adding more agents to compensate for coordination failures.
    • Development time is dominated by framework configuration rather than task logic. When the team spends more time wiring agents together than improving the actual task performance, the framework is adding complexity without adding value.

    Hierarchical Systems Are Earned, Not Designed In Advance

    The most reliable path to a well-architected multi-agent system is iterative expansion rather than upfront comprehensive design. Start with the simplest system that could plausibly work — often a single agent with several tools, or a two-agent planner/executor pattern. Identify the specific bottlenecks and failure modes in that system. Add architectural complexity only in response to specific observed problems, not in anticipation of problems you might encounter later.

    Teams that start simple and evolve their architecture based on empirical feedback consistently build more reliable systems than teams that begin with elaborate multi-agent designs. The former are adapting to reality; the latter are adapting reality to their design — a much harder problem.

    The Operator’s Pre-Production Checklist

    Before a multi-agent workflow ships to production, there’s a set of questions that experienced operators have learned — usually the hard way — to answer explicitly rather than assume. This checklist is not exhaustive, but covering these points will prevent the majority of production failures documented in the MAST study and in incident postmortems from the past year.

    Architecture and State

    • Is shared state defined as an explicit typed schema, or are agents passing raw conversation history?
    • Are state mutation rules defined — which agents can write to which state fields, and in what order?
    • Is there a checkpointing mechanism that enables workflow recovery without full restart?
    • Have you defined a maximum state size and a pruning policy for state fields no longer needed by downstream agents?

    Cost Governance

    • Is there a documented per-task cost estimate, based on a realistic token count across all agents in the workflow?
    • Are hard token budgets enforced at the platform level, not as prompt instructions?
    • Are agent tool permissions scoped to minimum necessary access?
    • Is model routing configured so that low-complexity tasks use smaller, cheaper models?
    • Are circuit breakers in place to pause execution when cost anomalies are detected?

    Observability

    • Are span-level traces implemented for every agent call, with parent spans capturing the full workflow trace?
    • Is full input/output logging in place for each agent, including tool calls and tool responses?
    • Is there a cost attribution mechanism that shows token usage per agent per workflow run?
    • Are state snapshots captured at key checkpoints for replay and post-mortem capability?
    • Is there an alerting policy for trace anomalies — unusually high token consumption, excessive retry counts, or abnormal failure rates?

    Security

    • Has each agent’s tool access been reviewed against the principle of least privilege?
    • Are there input validation schemas enforced at agent handoff boundaries?
    • Is privileged action execution separated from agent reasoning, with a validation layer between proposal and execution?
    • Is there an immutable audit trail for all consequential actions, including which agent proposed, who authorized, and what was executed?
    • Has the system been evaluated for prompt injection attack surfaces, particularly in agents that process external content?

    Human Oversight

    • Have all action types been classified into the three risk tiers (autonomous, async review, hard stop)?
    • Are Tier 3 approvals enforced at the platform level, not by agent self-assessment?
    • Is approval routing configured to reach the appropriate reviewer with sufficient context to decide quickly?
    • Is there a timeout policy for unresponded approval requests, with safe-failure behavior?
    • Is there a regular cadence for reviewing approval gate telemetry to calibrate tier assignments?

    What Separates the Systems That Work From the Rest

    The MAST study’s 41–87% failure rates are not an argument against multi-agent AI. They’re a map of where the complexity actually lives — and it lives in coordination, governance, and state management, not in model quality or framework selection.

    The teams running multi-agent systems that deliver reliable, sustainable production value share a consistent set of operating principles. They’re not using the newest or most powerful frameworks; they’re using the most appropriate ones with a deep understanding of the tradeoffs. They treat state as a first-class architectural concern, not an afterthought. They enforce cost governance and security at the platform layer, not by trusting agents to manage themselves. They build observability before they build complexity. They start simple and earn their way toward more sophisticated architectures through empirical evidence, not architectural ambition.

    Most importantly, they’re honest about what agents are good at and what they’re not. Agents are extraordinarily capable at handling open-ended tasks with complex decision trees in a way that would be impractical to code explicitly. They’re poor at reliably enforcing their own resource limits, security boundaries, and quality standards — those need to be built into the surrounding system.

    The operator’s job is to build that surrounding system: the state model, the observability layer, the cost governance, the security architecture, the human oversight tiers. Do that work well, and the multi-agent system inside it has a real chance to perform. Skip it, and you’ll spend months debugging coordination failures in the dark, wondering why the model keeps making mistakes that have nothing to do with the model.

    The coordination gap is real. It’s also closed by design, not by accident.

  • The Weekly SBV Signal Stack: A Lightweight Analytics Routine That Actually Moves the Needle

    The Weekly SBV Signal Stack: A Lightweight Analytics Routine That Actually Moves the Needle

    A clean dark-mode SBV Signal Stack analytics dashboard showing three layers of metrics: Traffic Efficiency, Creative Health, and Revenue Quality, with a 45-minute weekly clock.

    Sponsored Brands Video now accounts for roughly 58% of total Sponsored Brands spend across managed Amazon accounts as of Q1 2026. It delivers CTR benchmarks around 0.9–1.0% — more than double the static Sponsored Brands average of 0.4%. Its conversion rate sits near 11%, and its ROAS range, depending on how it’s managed, stretches from 3x on the low end to 8x or more on well-optimized branded defense campaigns.

    SBV is, without question, the dominant Sponsored Brands format right now. Which makes it genuinely strange that most brands reviewing their SBV performance each week are essentially flying blind — pulling whatever metrics the Ads console happens to surface first, comparing them to last week’s numbers, and calling it done.

    That is not an analytics routine. That’s reactive data consumption. And the difference matters more in 2026 than it ever has, because SBV performance is now shaped by layers of signals — creative quality, keyword relevance, audience composition, impression share, brand lift, and multi-touch attribution — that don’t all point in the same direction at the same time.

    This post is about building a signal stack: a deliberately ordered, tightly scoped set of nine core metrics organized into three functional layers, reviewed on a fixed weekly schedule in under an hour. Not a spreadsheet empire. Not a BI platform project. A lightweight, repeatable routine that turns data into decisions — every single week.

    If you’re spending meaningfully on SBV and you’re not running a structured weekly review against a defined signal hierarchy, you’re probably leaving both performance and insight on the table. Here’s how to fix that.

    Why Most SBV Analytics Routines Fail Before Friday

    Split-screen infographic comparing analytics overload with 40+ metrics versus a clean 9-metric signal stack, with headline: 9 Signals Beat 40 Metrics Every Time.

    Most SBV analytics routines don’t fail because of bad data. They fail because of a structural problem that starts well before anyone opens a report: too many metrics, no defined hierarchy, and no time-bounded review discipline.

    The Metric Sprawl Problem

    Amazon’s Ads reporting console, as of 2026, surfaces more than 40 reportable metrics for a Sponsored Brands Video campaign — impressions, viewable impressions, clicks, orders, spend, ACOS, ROAS, CTR, CVR, video starts, 5-second views, first-quartile views, midpoint views, third-quartile views, completes, unmutes, view-through rate, new-to-brand orders, new-to-brand sales, new-to-brand units, brand impression share, and more. That’s not a signal stack. That’s a signal swamp.

    When every metric looks equally important, the brain defaults to checking the most emotionally salient numbers — usually total spend, ACOS, and ROAS — and ignoring everything else. Creative signals go unread. Brand lift data stays untouched. Search term impression share never gets pulled. The review becomes a financial audit rather than a performance diagnostic.

    The “Once a Month” Trap

    Another common failure mode is review cadence mismatch. Many Amazon advertisers review SBV performance monthly — often as part of a broader account review — which is far too infrequent for a format that responds quickly to creative fatigue, bid pressure, and keyword drift.

    SBV creative assets can exhaust their novelty effect within two to three weeks in competitive categories. A video that opened the month at 1.0% CTR may be sitting at 0.55% by week three as Amazon’s algorithm deprioritizes repeatedly-seen creative. If you only check monthly, you’ve already lost two weeks of opportunity to either refresh creative or reallocate budget to a better-performing variant.

    No Defined Action Layer

    The third failure mode — and arguably the most common — is running a review that generates observations but not decisions. It’s easy to spend an hour looking at charts and thinking “CTR is down a bit this week, ROAS looks okay, completion rate seems fine.” Nothing in that review is false. But nothing in it produces a Monday-morning action either.

    A signal stack solves all three of these problems at once. It defines which metrics to look at (eliminating sprawl), mandates a weekly cadence (eliminating the monthly trap), and closes every review with a defined action log (eliminating the observation-without-decision cycle).

    Why SBV Specifically Demands a Stack Approach

    Static Sponsored Brands ads have a relatively simple performance story: you can mostly diagnose them with CTR, CVR, ACOS, and maybe impression share. SBV is categorically more complex because it adds an entire layer of creative engagement signals — video-specific metrics that sit upstream of click behavior — that static ads simply don’t have.

    With SBV, a campaign can have a healthy ROAS but a collapsing completion rate, which tells you the creative is burning out fast and ROAS is about to deteriorate. Or it can have a strong completion rate but weak CTR, which tells you the video is holding attention but failing to trigger product interest. These are different diagnoses requiring different fixes. Without a structured stack that looks at both creative signals and revenue signals together, you can’t tell which problem you’re actually dealing with.

    The Three-Layer Signal Stack Architecture

    The SBV Signal Stack is organized into three functional layers, each answering a different diagnostic question. Reviewing them in order — top to bottom — creates a natural diagnostic flow from upstream attention signals to downstream revenue outcomes.

    Layer One: Traffic Efficiency

    This layer answers the question: Is SBV getting the right eyeballs and converting them to clicks efficiently? It covers the metrics that sit between impression and click — the first expression of creative-market fit. The core signals here are CTR, 5-Second View Rate, and Search Term Impression Share.

    Layer Two: Creative Health

    This layer answers: Is the video creative doing its job? It’s the layer most advertisers neglect because the metrics feel less “financial” — but they’re actually leading indicators for future ROAS deterioration. Core signals: Completion Rate, Unmute Rate, and View-Through Rate (VTR).

    Layer Three: Revenue Quality

    This layer answers: Are the clicks we’re getting worth paying for? It connects ad-attributed conversions to business outcomes, with particular emphasis on customer acquisition quality (New-to-Brand Rate), cost efficiency (ACOS), and blended return (ROAS). Core signals: New-to-Brand (NTB) Order Rate, ACOS, and CVR.

    Why the Ordering Matters

    The three-layer ordering is not arbitrary. Traffic Efficiency signals often reveal the root cause of Revenue Quality problems — and they’re faster to change than revenue outcomes, which take a full attribution window to update. If you always start with ROAS and work backwards, you’ll frequently chase the wrong fix. Starting with traffic signals and reading downward forces proper causal reasoning: attention → engagement → conversion.

    Nine signals. Three questions. One weekly hour. That’s the architecture. Now let’s go deep on each layer.

    Layer One — Traffic Efficiency Signals

    Traffic efficiency is about the relationship between SBV’s placement in search results and its ability to earn the click. These are your fastest-moving signals — they update daily and respond quickly to bid changes, keyword additions, and creative rotations.

    Signal 1: Click-Through Rate (CTR)

    CTR is the most direct measure of whether your video creative is compelling enough to earn a click against competing search results. For SBV in 2026, the cross-category benchmark sits at 0.9–1.0%. That’s the range you’re aiming for on competitive keywords. If you’re running branded keywords (where the searcher already knows your brand), CTR benchmarks are higher — 1.2–1.5% is achievable on strong branded campaigns.

    The important thing about CTR in a signal stack context is not just its absolute value but its direction over time. A CTR decline of 10–15% week-over-week, sustained across two consecutive weeks, is a strong creative fatigue signal — especially on campaigns where the same video creative has been running for three weeks or longer. This is when the Layer Two creative signals become critical context.

    What CTR doesn’t tell you: whether the traffic you’re attracting is relevant, whether those clicks are converting, or whether your impression share is high or low. CTR is a ratio — it measures the quality of clicks per impression, not the volume or quality of the impressions themselves. That’s why it never stands alone in the stack.

    Signal 2: 5-Second View Rate

    This metric is unique to video formats. Amazon defines it as the percentage of video starts that reach the 5-second mark — which, given that SBV plays as autoplay and can be scrolled past at any moment, is a direct measure of how effectively your creative hooks attention in the first few seconds.

    The first 2 seconds of an SBV ad are the most critical creative real estate on Amazon’s search results page. Best-practice guidance from Amazon and third-party agencies in 2026 converges on a consistent recommendation: show the product in the first 2 seconds, communicate its primary function or benefit by the 5-second mark. Ads that front-load brand logos, animations, or ambient footage before showing the product consistently underperform on 5-second view rate.

    A healthy 5-second view rate for SBV sits at 35% or higher. Rates below 25% indicate the opening sequence is failing to create enough visual interest to overcome the passive scroll. This is a creative fix, not a bid fix — increasing bids on a video with a weak hook just means you’re paying more to show a creative that isn’t working.

    Signal 3: Search Term Impression Share (SIS)

    Impression share is the metric most Amazon advertisers have heard of but fewest actually track systematically. Amazon provides Search Term Impression Share in the Sponsored Brands reporting tab — it shows what percentage of available top-of-search impressions on a given query your brand is capturing versus the total available impressions across all competing advertisers.

    For branded keywords (queries that include your brand name), impression share should be your most-watched competitive signal. An impression share below 80% on your own branded terms is a meaningful warning sign — it means competitors are actively bidding on your brand name and capturing a fifth or more of the searches where buyers are explicitly looking for you.
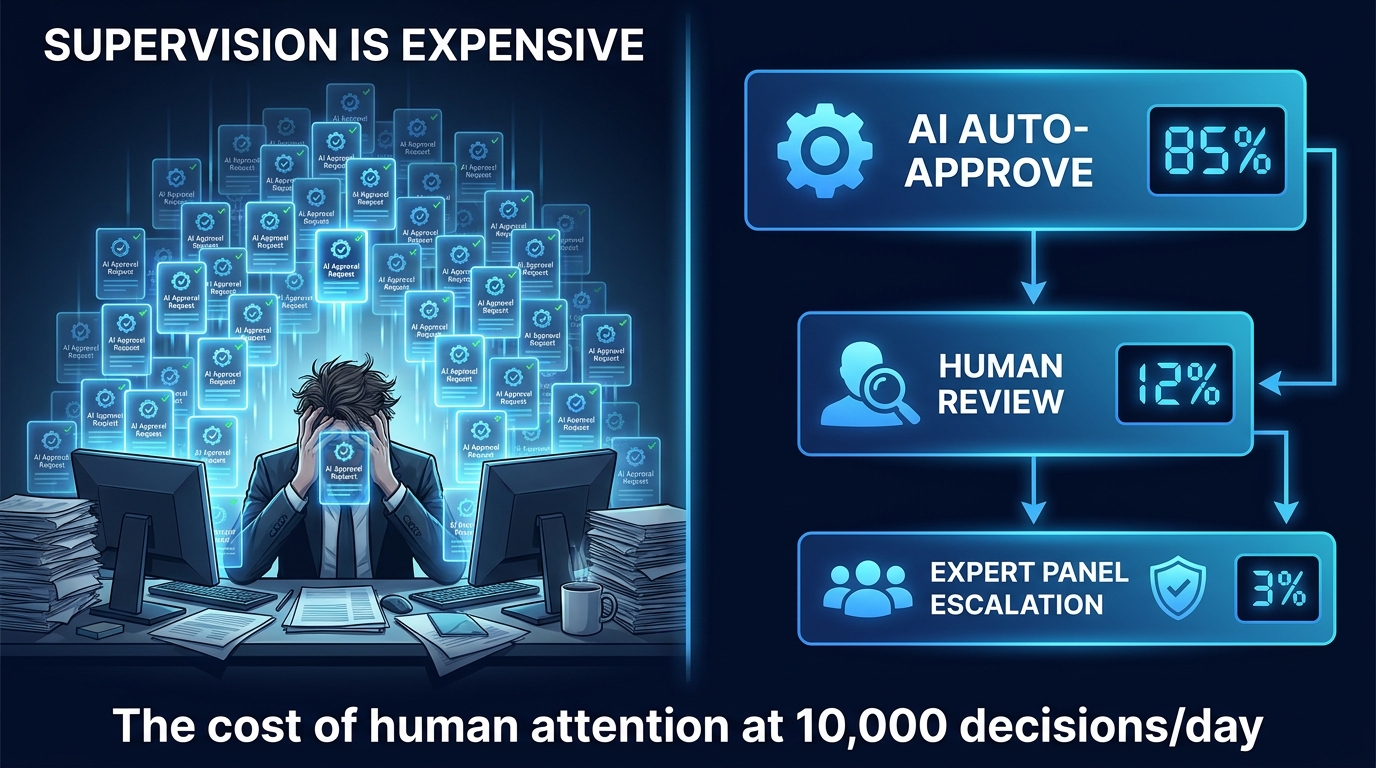
    For category keywords, impression share benchmarks vary significantly by category, but a weekly review should flag any week-over-week decline of 5 percentage points or more, which typically indicates either a competitor has increased their bids aggressively or your Quality Score has slipped (often tied to product detail page freshness).

    Building a running SIS time series is the key habit. Export the Search Term report every Monday, paste the relevant rows into a master tracking spreadsheet, and create a rolling chart. After four weeks, you have a baseline. After eight weeks, you can see trends. After twelve weeks, you have a competitive intelligence signal that no single-week view can provide.

    Layer Two — Creative Health Signals

    Funnel infographic showing the SBV Creative Diagnostic Stack: Hook at top with 2-second product appearance, Hold in the middle with 35%+ 5-second view rate, Convert at the bottom with 0.8-1.0% CTR and 11% CVR.

    Creative health signals are the layer most likely to be skipped in a time-pressured weekly review — and the layer most likely to give you advance warning of impending ROAS deterioration. A video creative doesn’t break overnight. It decays gradually, and the decay shows up in creative engagement metrics weeks before it shows up in revenue numbers.

    Signal 4: Video Completion Rate

    Completion rate measures the percentage of video starts that reach the end of the video. For SBV, which typically runs at 15–30 seconds in autoplay, completion rate is a measure of the video’s hold power — its ability to keep a viewer engaged through to the end.

    The 2026 benchmark range for healthy SBV completion rates is 40–55% on well-performing campaigns. Rates below 30% indicate the middle portion of the video is losing viewers — often because the creative lingers too long on product features rather than maintaining visual momentum or communicating a clear benefit progression.

    Critically, completion rate should be read alongside CTR, not independently. A video with high completion rate (say, 52%) but low CTR (0.4%) tells you viewers are watching to the end but not clicking through — meaning the creative is engaging but the call-to-action or product-market connection is weak. A video with high CTR but low completion rate (18%) tells you the hook is working but viewers who don’t click are bailing early — often a sign of poor creative-keyword alignment.

    One nuance for the weekly review: completion rate naturally varies with video length. A 15-second video will almost always have a higher completion rate than a 30-second video, all else equal. When comparing creatives, always compare within the same length tier.

    Signal 5: Unmute Rate

    SBV plays silently by default on Amazon’s search results page. Viewers who actively tap or click to unmute are signaling a measurably higher level of interest in the creative than those who watch silently. That makes unmute rate a highly sensitive engagement quality signal — it’s not just measuring whether people watched, but whether they wanted to hear what you were saying.

    Amazon provides unmute data in the Campaign Manager video metrics tab. Average unmute rates across SBV campaigns are low — typically 5–10% across all viewers — but the metric’s value is comparative: a video with 12% unmute rate versus another with 3% unmute rate tells you something significant about relative engagement quality, even if the absolute numbers seem small.

    For brands running multiple SBV creative variants simultaneously, unmute rate is one of the better early signals to identify which variant is generating genuine audience interest versus passive scroll exposure. In a creative testing rotation, the variant with the highest unmute rate often (not always, but often) has the best long-term CVR trajectory.

    Signal 6: View-Through Rate (VTR)

    VTR measures the percentage of viewable impressions (where at least 50% of the ad was visible for 2+ seconds) that resulted in a video start. It’s a metric that sits between impression and engagement — it captures how many people who could see the video actually let it begin playing.

    VTR is particularly useful for diagnosing placement quality issues. If your VTR is declining week-over-week on a campaign with stable creative, it often indicates your SBV is winning more impressions in lower-visibility placements — below the fold, in less-engaged browsing contexts, or in categories where search intent is lower. This doesn’t necessarily mean your bids are wrong, but it does mean your impression volume growth is coming from lower-quality inventory.

    A healthy weekly check: if VTR drops more than 8–10% week-over-week without a corresponding creative change, investigate whether your campaign’s keyword portfolio has expanded into lower-intent queries that are winning impressions but generating low-quality viewing contexts.

    Layer Three — Revenue Quality Signals

    Revenue quality signals are what most advertisers track exclusively — which is precisely the problem. ROAS and ACOS are lagging indicators. By the time they deteriorate meaningfully, the upstream cause has usually been brewing for two to three weeks in the creative and traffic layers. Reading this layer in isolation is like checking your engine temperature after your car has already overheated.

    That said, revenue quality signals remain the most financially consequential metrics in the stack, and reading them correctly — especially NTB Rate — creates decision-making clarity that pure efficiency metrics don’t provide.

    Signal 7: New-to-Brand (NTB) Order Rate

    New-to-Brand is Amazon’s metric for identifying buyers who have not purchased from your brand in the prior 12 months. For SBV, NTB rate is arguably the most strategically important revenue metric — more important, in many cases, than ROAS — because it measures whether your advertising is building your customer base or merely re-converting existing customers.

    SBV is inherently an upper-funnel format. Its placement at the top of search results, its autoplay behavior, and its visual storytelling format make it particularly effective at capturing category-level shoppers who are aware of a problem but haven’t yet committed to a brand. The expected NTB rate target for SBV campaigns on non-branded keywords is 50% or higher on a 28-day attribution window. Rates consistently below 35% suggest SBV spend is disproportionately recapturing existing buyers — a role better suited to Sponsored Products retargeting than to SBV.

    On branded keywords, the NTB expectation flips. Here, you want a lower NTB rate — you’re defending against competitors targeting your brand name, and many of those clicks should convert existing or highly-aware customers. A branded SBV campaign showing 70% NTB rate might actually indicate keyword bleed into non-branded category terms.

    The weekly action rule for NTB: if NTB rate on category campaigns drops below 40% for two consecutive weeks, audit your targeting to check for keyword overlap with branded or retargeting campaigns. Use Amazon Marketing Cloud’s audience overlap queries if you have AMC access — the visual confirmation that your SBV audience and your Sponsored Products retargeting audience are heavily overlapping is usually enough to prompt an immediate segmentation fix.

    Signal 8: Advertising Cost of Sales (ACOS)

    ACOS — ad spend divided by ad-attributed sales — is the most commonly tracked SBV metric and also the most commonly misread. The mistake isn’t tracking ACOS; it’s applying a single ACOS target to campaigns with fundamentally different strategic purposes.

    A branded defense SBV campaign should have a very different ACOS target than a category acquisition campaign. Branded defense campaigns are competing against rivals bidding on your brand name — the cost of allowing competitor SBV to appear on branded searches is customer attrition, not a financial metric. Many advertisers correctly run branded SBV at a deliberately high ACOS (30–40%) because the alternative — losing branded search visibility — is costlier than the ad spend.

    Category acquisition SBV campaigns, by contrast, should be held to tighter efficiency targets, typically ACOS in the 15–25% range depending on category margins. If a category acquisition campaign has drifted above 30% ACOS for three consecutive weeks, it’s a signal to investigate either keyword relevance (targeting queries too far from purchase intent) or landing page quality (product detail page not converting SBV traffic effectively).

    ACOS targets should be documented in your weekly scorecard, not improvised during each review. Knowing the target before you check the number is what separates a diagnostic review from an anxious one.

    Signal 9: Conversion Rate (CVR)

    CVR — orders divided by clicks — is the signal that bridges creative performance and listing quality. A platform-wide SBV CVR benchmark sits around 11%, and campaigns achieving 13% or above are generally well-optimized across both creative and landing page dimensions.

    CVR drops are one of the clearest diagnostic triggers in the entire stack. A sustained CVR decline (two or more weeks, 15%+ decline) on a campaign where CTR remains stable almost always points to a product detail page issue: price increase, review count or rating decline, competitor content improvement, or a listing image change that weakened perceived value. It’s rarely a campaign structure problem — by the time someone clicks your SBV ad, the campaign has already done its job. What happens after the click is the listing’s responsibility.

    This is why CVR belongs in the signal stack: it’s the handoff metric between advertising and merchandising. Watching it weekly creates accountability for both the ad team and the content/listing team simultaneously.

    The Brand Metrics Bridge: Connecting Upper-Funnel Signals to Downstream Purchase

    The nine signals above cover what happens inside your SBV campaigns. But SBV’s full impact extends beyond what any campaign-level report can show — and that’s where Amazon Brand Metrics becomes an essential companion to the signal stack.

    What Brand Metrics Actually Measures

    Amazon Brand Metrics is a separate reporting module (available in Seller Central and the Ads console for enrolled brands) that quantifies the shopper funnel at the brand level: awareness, consideration, and purchase. Unlike campaign reports, which only capture ad-attributed events, Brand Metrics captures all on-Amazon shopper behavior associated with your brand — including organic branded searches, product detail page views from non-ad sources, and purchase events that occurred without ad exposure.

    This matters enormously for SBV because SBV’s primary job is often to generate awareness and consideration, not just last-click conversion. An SBV impression that doesn’t result in an ad-attributed purchase might still trigger a branded search three days later — which shows up in Brand Metrics’ awareness index but never in your campaign ROAS.

    How to Use Brand Metrics in the Weekly Stack

    Brand Metrics data refreshes on a three-month rolling basis, which means it’s not a daily-monitoring tool. But adding a monthly Brand Metrics check as a companion to the weekly signal stack creates a crucial upper-funnel perspective that pure campaign metrics miss.

    The most actionable weekly bridge between Brand Metrics and your signal stack is branded search volume. If your SBV campaigns are running at scale and your brand-level branded search volume (visible in Brand Metrics under “awareness”) is flat or declining over a multi-week period, that’s a meaningful signal that SBV impressions are not translating into brand recall. It warrants a creative diagnostic: are your videos clearly brand-stamping from the first second? Is your logo placement and brand name prominent in the first 5 seconds of the autoplay?

    Consideration Index as a Creative Quality Check

    The consideration metric in Brand Metrics — which Amazon builds from detail page views, add-to-carts, and brand-search-to-detail-page navigation patterns — serves as a slow-moving but high-signal indicator of whether your SBV is reaching genuinely interested shoppers or just generating passive impressions.

    If you’re running SBV at meaningful scale (say, $5,000+ per month in Sponsored Brands spend) and your consideration index is stagnant while your impression volume grows, the SBV reach expansion is landing on low-intent audiences. This is the moment to tighten keyword targeting, exclude low-quality search terms aggressively, or shift bid weight toward tighter match types that reach shoppers further down the purchase funnel.

    Search Term Impression Share: Your Weekly Competitive Pulse Check

    Search Term Impression Share (SIS) deserves its own section because it’s the one weekly signal that directly tells you what your competitors are doing — not just what your own campaigns are doing. It’s the closest thing Amazon Advertising offers to a weekly competitive intelligence brief.

    Building Your SIS Time Series

    Amazon’s SIS report provides a snapshot of your impression share and rank for each search term in your campaigns, with up to a 90-day lookback. The trap is treating this as a static reference document rather than a time series. Your SIS on a given keyword last week means almost nothing in isolation. Your SIS on that keyword across the last 12 consecutive weeks tells you whether you’re gaining ground, holding steady, or losing share — and at what rate.

    The mechanical process for building this time series is simple but requires discipline: download the Search Term Impression Share report every Monday morning (or whatever day you designate as your review day), paste the relevant rows into a master tracking spreadsheet, and create a rolling chart. After four to six weeks, patterns emerge. After three months, you have a genuine competitive intelligence asset.

    What SIS Declines Actually Tell You

    A declining impression share on a given search term can mean three different things, and the right response depends on correctly diagnosing which one it is:

    • Competitor increased bids: Your impression share is declining because a competitor is outbidding you. Response: evaluate whether the term’s conversion rate justifies a bid increase, or accept a smaller share on that term and redirect budget elsewhere.
    • Your Quality Score declined: Amazon’s algorithm assigns a Quality Score to SBV ads that incorporates creative relevance, keyword-to-landing-page alignment, and historical engagement metrics. A declining Quality Score can reduce impression share even at the same bid level. Response: audit keyword-to-creative alignment and check whether recent listing changes reduced relevance signals.
    • New competitor entered the keyword: A new brand has started bidding aggressively on a term where you previously had minimal competition. This is identifiable because the SIS decline is sudden (one week) rather than gradual. Response: investigate the competitor’s creative and consider whether a bid defense is strategically warranted.

    Branded Impression Share: The Number That Must Stay Above 80%

    Brand impression share — Amazon’s specific metric for your share of top-of-search impressions on queries containing your brand name — is a metric you should never let fall below 80% without active monitoring and a decision. Below 80% means competitors are consistently appearing above or alongside your brand in searches where buyers are explicitly looking for you. Every percentage point of branded impression share lost to competitors represents a measurable leak in brand equity.
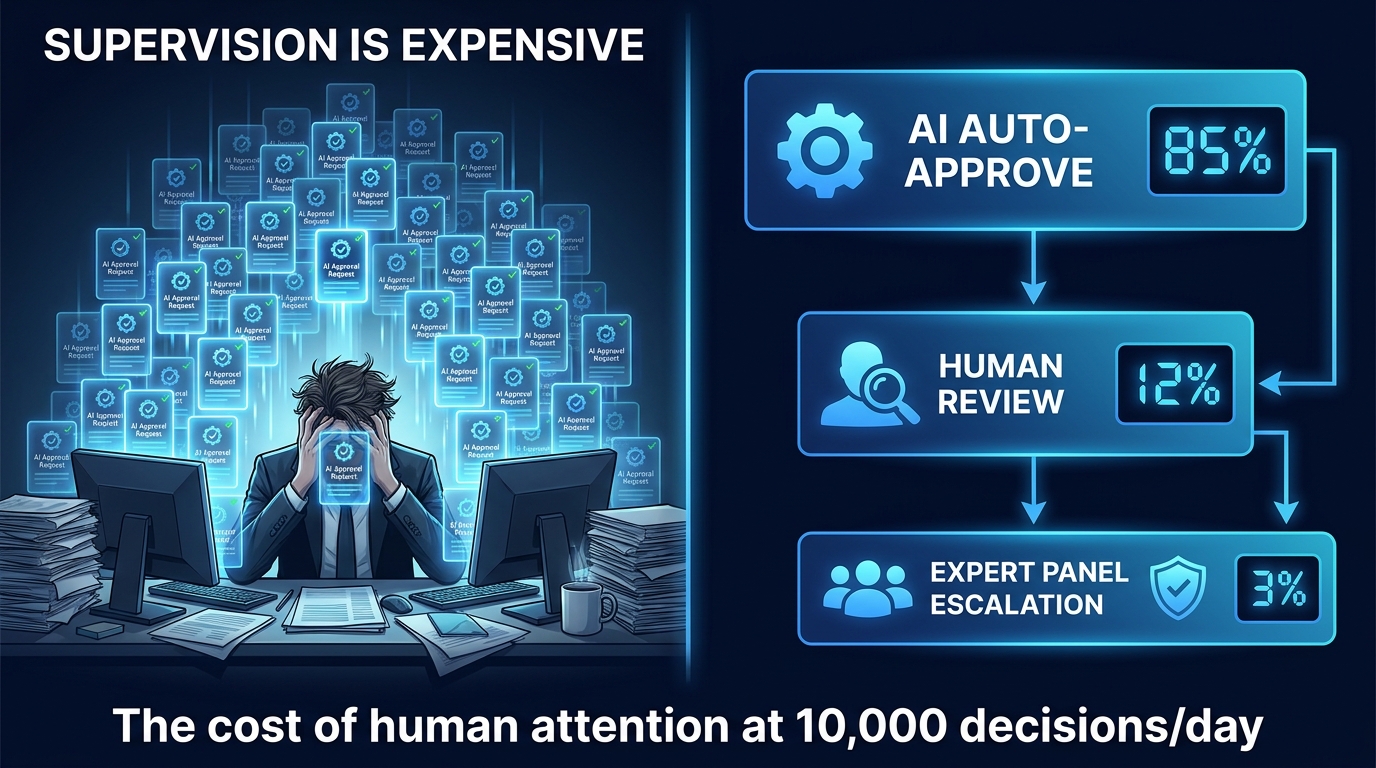
    The good news: branded SBV is typically lower CPC than category SBV because your Quality Score on your own branded terms tends to be high. Maintaining 85–90%+ branded impression share is usually achievable at a reasonable cost — and the NTB rate on branded campaigns, as discussed earlier, acts as a check on whether that spend is drawing in genuinely new customers or recapturing existing ones.

    AMC as a Weekly Sanity Layer (and When You Actually Need It)

    Amazon Marketing Cloud (AMC) is the privacy-safe clean room environment where Amazon joins event-level data from Sponsored Products, Sponsored Brands, DSP, and Streaming TV into a single queryable dataset. It’s genuinely powerful — and genuinely over-prescribed for small-to-mid SBV advertisers who don’t yet need it.

    Who Actually Needs AMC Weekly

    If your total Amazon Ads monthly spend is below $15,000, AMC’s incremental value over a well-executed signal stack routine is marginal. The signal stack covers the actionable decisions you need to make at that scale. If you’re running $15,000–$50,000+ per month, AMC starts delivering unique insights that the signal stack can’t replicate — specifically around multi-touch attribution and audience overlap.

    The most valuable AMC query for SBV advertisers at the $15K+ level is the SBV-to-Sponsored Products path analysis: identifying buyers whose purchase path started with an SBV impression and converted later via a Sponsored Products click. This is the exact path that last-click ROAS attribution systematically undercredits SBV for — and AMC is the only way to surface it.

    The Overlap Query: Your Audience Cannibalization Check

    The second high-value AMC use case for weekly SBV analysis is audience overlap: checking whether the audience exposed to your SBV campaigns is substantially overlapping with the audience you’re retargeting via Sponsored Products or DSP. If it is, you have an attribution problem — conversions are being counted in multiple campaigns, and your true incremental impact of SBV is lower than your ROAS suggests.

    Amazon’s AMC Audience Overlap query, run monthly (not weekly), takes roughly 30 minutes to set up and run for the first time, and about 10 minutes on subsequent runs. It outputs an audience overlap percentage between two campaigns or campaign groups. An overlap above 40% between SBV and retargeting campaigns typically warrants an audience exclusion fix — adding an audience exclusion to either the SBV campaign (excluding recent purchasers) or the retargeting campaign (excluding users who saw SBV in the last 7 days, to avoid double-counting).

    When to Keep AMC Out of the Weekly Routine

    AMC runs SQL queries against a cloud dataset. It has a learning curve, and it produces outputs that require interpretation. For weekly reviews, resist the temptation to use AMC as a primary diagnostic tool — it’s too slow and too complex for the 45-minute weekly cadence. Instead, use it monthly as a validation layer: confirming that what your signal stack has been showing you over the past four weeks is consistent with AMC’s multi-touch view of the same period.

    The signal stack gives you speed and decision velocity. AMC gives you depth and attribution confidence. They serve different purposes, and conflating them leads to either analysis paralysis (trying to run AMC queries every week) or strategic blindness (never running AMC at all).

    Building Your 45-Minute Weekly Review Ritual

    Timeline infographic showing the 45-minute weekly SBV review ritual with five stops: Pull Reports, Traffic Efficiency Check, Creative Health Audit, Revenue Quality Review, and 3 Actions Logged. Overlay text: Same Day. Same Time. Every Week.

    The signal stack is only useful if it’s actually reviewed. The review is only useful if it’s time-boxed, consistent, and action-generating. Here’s the exact routine structure to implement this week.

    The Non-Negotiable Anchor: Same Day, Same Time

    Pick a day and time for your weekly SBV review and treat it as non-negotiable. Monday mornings work well for most teams because Amazon campaign data from the prior week is fully settled by Sunday evening and Monday’s review can inform the week’s optimization priorities. Tuesday mornings are also popular for teams that run a Monday standup and want fresh data for that discussion.

    The specific day matters less than the consistency. Irregular reviews — “whenever I get to it” — are almost always deprioritized during busy weeks and end up happening monthly at best. The habit of a fixed weekly slot is itself a competitive advantage, because most of your competitors are doing it inconsistently.

    Minutes 0–5: Report Pull

    Before your review session begins, set up a standing report schedule in Amazon Ads so the reports you need are waiting in your inbox when you sit down. The three reports to schedule:

    • Sponsored Brands Video Campaign Report — weekly, including CTR, CVR, ACOS, ROAS, NTB metrics
    • Sponsored Brands Video Creative Report — weekly, including video starts, 5-second views, completions, unmutes
    • Search Term Impression Share Report — weekly, for all Sponsored Brands campaigns

    Scheduled reports eliminate the 10–15 minutes that manual report pulling typically consumes and ensure your data is consistent week-over-week. Spend minutes 0–5 downloading these three reports and pasting the relevant rows into your tracking scorecard.

    Minutes 5–15: Traffic Efficiency Layer

    Review CTR, 5-Second View Rate, and Search Term Impression Share against your established baselines. Flag any metric that has moved more than 10% in either direction compared to the prior week. Green flags (improvements) are worth noting but don’t require immediate action. Red flags (declines) get logged with a hypothesis: Is this a creative issue, a keyword issue, or a competitive pressure issue?

    Minutes 15–25: Creative Health Layer

    Check completion rate, unmute rate, and VTR. For any video creative that has been running three weeks or more, check whether completion rate has declined 5+ percentage points from its first-week baseline. If it has, this is a creative refresh trigger — note it explicitly in the action log. This is not something to debate in the review; if the signal is there, the action is queued.

    Minutes 25–35: Revenue Quality Layer

    Review NTB Rate, ACOS, and CVR against campaign-specific targets (not universal benchmarks). Note the delta from last week and from the four-week rolling average. Any metric outside its target range for two or more consecutive weeks gets a root cause entry in the action log — one sentence identifying the most likely cause based on what you saw in Layers 1 and 2.

    Minutes 35–45: Action Log

    Write three to five concrete actions that emerge from the review. Each action should be specific enough that someone else could execute it without asking for clarification. Examples of good action log entries:

    • “Campaign X — Video Creative A has declined from 48% to 29% completion rate over 3 weeks. Initiate Creative B rotation test on 50% of budget this Monday.”
    • “Branded keywords — impression share down from 87% to 71% over 2 weeks. Increase branded SBV bid floor by 20% effective today.”
    • “Category campaign — CVR down 14% week-over-week with stable CTR. Review product detail page for price or review changes in last 7 days.”

    The action log is the most important output of the weekly review. The signal stack tells you what’s happening. The action log decides what to do about it.

    When Your Signals Disagree: Conflict Patterns and What They Mean

    A 2x2 conflict pattern matrix showing four SBV signal disagreement scenarios: CTR Up/CVR Down equals Landing Page Mismatch; High Completion/Low CTR equals Weak Product Introduction; High NTB/Low ROAS equals Audience Too Broad; All Green Signals/Plateau equals Impression Share Ceiling.

    Real SBV campaigns rarely present with all signals pointing in the same direction. The most valuable analytical skill in the weekly routine is not reading healthy signal patterns — it’s correctly diagnosing the four most common conflict patterns, where different layers tell contradictory stories.

    Conflict Pattern 1: CTR Up, CVR Down

    What it looks like: Week-over-week CTR is improving (often after a creative refresh), but CVR is declining simultaneously.

    The diagnosis: Landing page mismatch. The new creative is attracting a different audience — one that’s responding to the visual hook but finding that the product detail page doesn’t match what the video implied. This is common when SBV creative is updated to emphasize a use case or lifestyle context that the listing imagery doesn’t reinforce.

    The fix: Audit the product detail page images and A+ content for alignment with the new creative’s messaging. The creative and the listing need to tell the same story — if the SBV shows the product in an outdoor fitness context but the listing imagery is entirely studio white-background shots, the emotional handoff breaks at the click.

    Conflict Pattern 2: High Completion Rate, Low CTR

    What it looks like: Completion rate is healthy (45%+), viewers are watching the whole video, but CTR sits below 0.6%.

    The diagnosis: The video is entertaining or informative but failing to generate purchase intent. This often happens with videos that lead with lifestyle storytelling, problem-framing, or brand narrative before the product appears — viewers watch to the end but don’t click because the video didn’t make them want the product specifically.

    The fix: Test a variant that brings the product and its primary benefit into the first 2 seconds. The goal of SBV creative is not to be watched; it’s to generate clicks from buyers who see the product and want it. High completion with low CTR is watchable content that’s failing at commerce.

    Conflict Pattern 3: High NTB Rate, Low ROAS

    What it looks like: 60%+ of SBV-attributed orders are new-to-brand customers, but ROAS is below target (say, 2x on a campaign targeting 4x).

    The diagnosis: The campaign is reaching genuinely new audiences but converting them inefficiently — typically because keyword targeting is too broad and pulling in low-intent search queries that result in expensive-to-win clicks with poor conversion rates.

    The fix: A search term audit of the SBV campaign. Isolate the 20% of terms generating 80% of spend, check their individual CVR and ACOS, and aggressively negative-match any term with CTR above 0.8% but CVR below 5%. High NTB rate with low ROAS is not a brand awareness investment — it’s a targeting efficiency problem.

    Conflict Pattern 4: All Signals Green, But Performance Plateau

    What it looks like: CTR, completion rate, NTB rate, ACOS, and CVR are all at or above benchmark — but revenue growth from the campaign has flatlined.

    The diagnosis: Impression share ceiling. The campaign has optimized itself into a state where it’s performing well within its current scale but can’t grow because it’s already captured most of the available impressions on its keyword set.

    The fix: Check Search Term Impression Share. If branded keywords are at 85%+ and category keywords are at 40%+, the campaign is close to its organic growth ceiling on the current keyword set. The path forward is keyword expansion — adding related category terms, complementary product queries, and competitor brand terms (with careful ROAS monitoring) — rather than bid increases, which will yield diminishing returns at high impression share levels.

    Signal Stack Benchmarks: What Good Actually Looks Like in 2026

    Horizontal bar chart infographic showing 2026 SBV benchmarks: CTR 0.9-1.0% versus static SB 0.4%, Completion Rate 40-55% good range, New-to-Brand Rate 50%+ target, and ROAS range from 3x to 8x+.

    Benchmarks without context are dangerous — but benchmarks with context are genuinely useful calibration tools. The following ranges reflect 2026 cross-category SBV performance data and should be treated as orientation points, not pass/fail thresholds. Your specific category, margin structure, and competitive density will shift your targets in either direction.

    Traffic Efficiency Benchmarks

    Signal Underperforming On Track Strong
    CTR (Category Keywords) Below 0.55% 0.55–0.85% 0.85%+
    CTR (Branded Keywords) Below 0.9% 0.9–1.2% 1.2%+
    5-Second View Rate Below 25% 25–35% 35%+
    Branded Impression Share Below 70% 70–84% 85%+

    Creative Health Benchmarks

    Signal Underperforming On Track Strong
    Completion Rate Below 28% 28–42% 42%+
    Unmute Rate Below 4% 4–8% 8%+
    Creative Freshness (weeks since last test) 6+ weeks 3–5 weeks 1–2 weeks

    Revenue Quality Benchmarks

    Signal Underperforming On Track Strong
    NTB Order Rate (Category SBV) Below 35% 35–50% 50%+
    CVR Below 7% 7–10% 10%+
    ACOS (Category Acquisition) Above 35% 25–35% Below 25%
    ROAS (Blended SBV) Below 2.5x 2.5–4x 4x+

    One important caveat on benchmarks: category margin structure changes everything. A brand with 65% gross margins can sustain a 30% ACOS profitably. A brand with 28% gross margins cannot. Always back-calculate your ROAS floor from your margin structure before setting campaign targets, and don’t use cross-category benchmarks as hard performance thresholds without accounting for your own unit economics.

    From Data Collector to Signal Reader: A Closing Framework

    The difference between an Amazon advertiser who’s drowning in dashboards and one who’s decisively managing their SBV performance isn’t access to better data. It’s a different relationship with data itself.

    Data collection is reactive — you open the console and read whatever it shows you. Signal reading is proactive — you review a defined set of metrics in a defined order, looking for specific patterns against established baselines, and generating a specific list of actions before you close the tab.
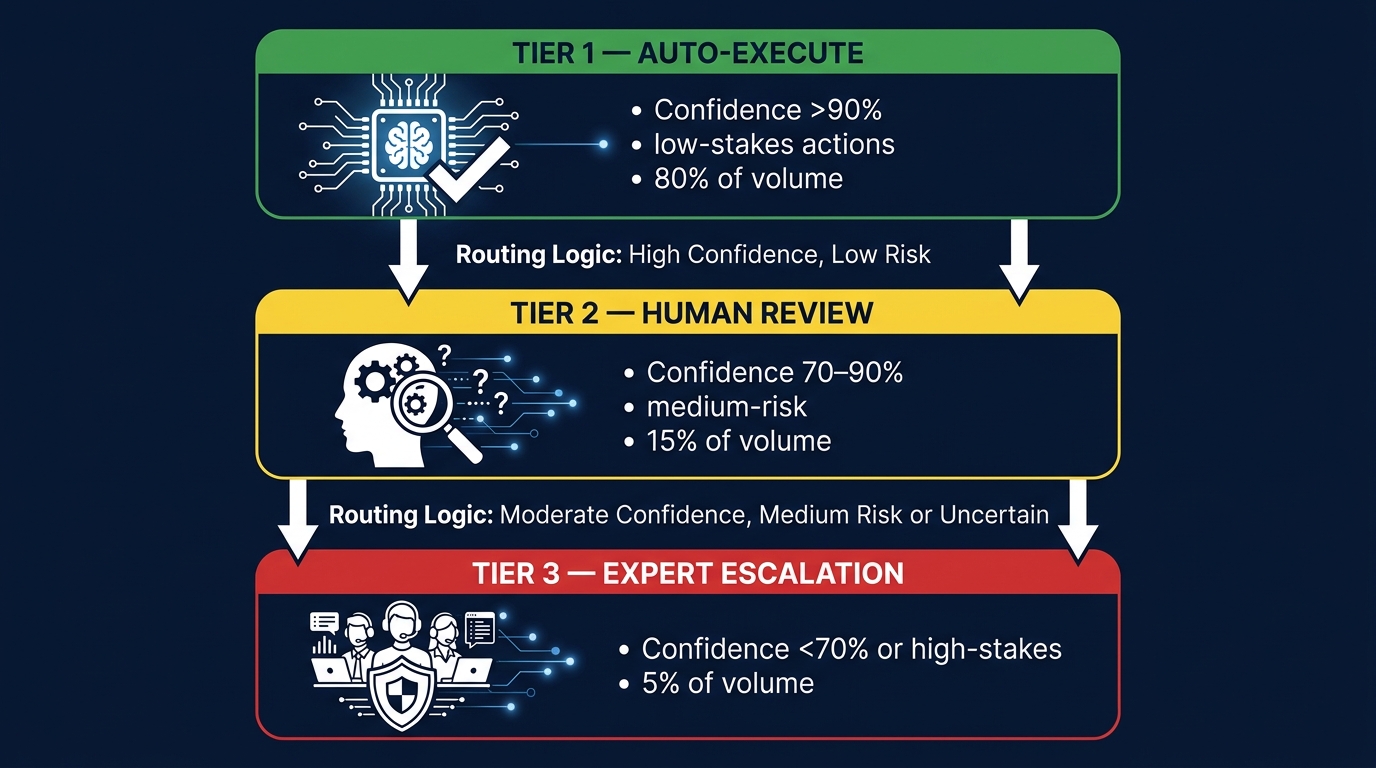
    The SBV Signal Stack described in this post is deliberately narrow: nine signals, three layers, four conflict patterns to watch for, one 45-minute weekly block. That narrowness is not a limitation. It’s the design. Because the goal isn’t to maximize the amount of data you consume each week. It’s to maximize the quality of decisions you make from the data you review.

    The Three Habits That Sustain the Routine

    Implementing the signal stack is straightforward. Sustaining it past the first month requires three habits:

    1. Document your baselines explicitly. Your first four weeks of running the signal stack establish your baselines. Write them down. A 0.78% CTR that looks “low” against industry benchmarks might actually be strong for your specific category and keyword mix. Without your own documented baseline, every week’s review is floating against abstract benchmarks rather than your actual performance trajectory.
    2. Keep the action log honest. The easiest corruption of the weekly review ritual is a vague action log: “Monitor CTR,” “Adjust bids,” “Look at creative.” These are not actions. Each entry in the action log should have a specific metric, a specific campaign, a specific decision, and a specific date for implementation or follow-up.
    3. Treat creative refresh as a scheduled maintenance item, not a reactive fix. The data will tell you when completion rate is declining. But waiting for the signal to arrive means you’ve already lost two or three weeks of optimal performance. Best practice is to plan a creative refresh cycle proactively — typically every 4–6 weeks for high-spend campaigns — and use the signal stack to confirm whether to accelerate or delay the planned refresh based on the actual performance trajectory.

    What This Routine Makes Possible Over Time

    Run this routine for twelve weeks and you’ll have something most Amazon advertisers don’t: a structured, annotated performance history for your SBV campaigns that shows exactly which creative changes produced which signal improvements, which keyword decisions moved impression share in which direction, and which targeting refinements correlated with NTB rate recovery.

    That history is compounding intellectual capital. Every week of consistent signal reading adds to a body of brand-specific knowledge that no benchmark report and no external audit can fully replace. The brands that will be managing SBV most effectively in the next 12–18 months are the ones building this institutional knowledge now — not because the analytics are complicated, but because the discipline of building them consistently is rare.

    Nine signals. Forty-five minutes. Every week. That’s the whole routine. Start this Monday.

  • High-Velocity SBV Creative Sprints: How to Engineer 10 Winning Video Variations in 7 Days

    High-Velocity SBV Creative Sprints: How to Engineer 10 Winning Video Variations in 7 Days

    High-velocity SBV creative sprint — 10 video variations in 7 days sprint board with countdown timer

    Most Amazon advertisers treat Sponsored Brands Video the way they treat a TV commercial: months of planning, one big production, one polished asset, and then hope. They spend weeks refining a single concept, film it once, launch it carefully, and then watch it slowly plateau. When the CTR starts sliding three months later, they circle back to the creative discussion — and the cycle restarts.

    That model is not wrong because it values quality. It is wrong because it confuses quality with singularity. The assumption buried inside it — that one great video is better than ten testable ones — is exactly backwards from how Amazon’s ad auction actually rewards creative.

    The brands quietly outperforming their categories in 2026 are not making one great SBV. They are running creative sprints: structured, repeatable, seven-day workflows that produce ten distinct video variations from a single asset bank, launch them simultaneously, read the performance signal, and use it to inform the next sprint. They are treating Sponsored Brands Video as a data-generating machine, not a finished product.

    This post lays out precisely how that works — the sprint structure, the ten variation angles worth testing, the variable isolation logic that keeps your data readable, and the team setup that makes this repeatable rather than a one-time scramble. If you have ever felt like your SBV program was stuck, this is why, and here is what to do about it.

    What Makes SBV the Highest-Leverage Ad Format on Amazon Right Now

    SBV CTR benchmark comparison chart showing 2.6x higher CTR versus static Sponsored Brands in 2026

    Before designing a sprint, it helps to understand why Sponsored Brands Video commands this level of attention in the first place. The format earns it on the data alone.

    Across 2026 benchmark aggregations, SBV is delivering CTRs in the range of 0.6% to 1.0%, with well-optimized creatives frequently hitting 1.0% or above. Compare that to static Sponsored Brands, which typically sits between 0.20% and 0.40%. The gap — roughly 1.6x to 2.6x — is not a rounding error. At that magnitude, the format difference alone can determine whether your product lands on a shopper’s shortlist or gets scrolled past entirely.

    Why the Gap Exists

    Amazon’s search results pages are dense. Dozens of products compete for attention in static grids of images and price points. SBV breaks that pattern at the placement level. It moves. It occupies screen real estate differently. And critically, it communicates product value within the first few seconds in a way that a hero image — however optimized — simply cannot replicate.

    A customer scrolling for a portable blender can see a product image and infer roughly what it is. A well-executed SBV shows the blender in action, communicates noise level through a visual metaphor, demonstrates cleanup in three seconds, and delivers a headline message — all before a shopper has consciously decided whether to engage. That compression of information is why the CTR delta exists.

    The Conversion Signal Matters Too

    CTR is the attention metric, but the downstream signal is just as compelling. SBV campaigns in 2026 are associated with conversion rates in the range of 6% to 11% depending on category — noticeably higher than formats that send shoppers to a detail page cold. The video pre-qualifies intent. Shoppers who click through after watching even a few seconds of SBV tend to have a clearer idea of what they are buying, which reduces abandonment.

    For high-consideration products — anything with a learning curve, a specific use case, or a strong size/fit dimension — this pre-qualification effect is especially significant. The video does part of the detail page’s job before the shopper even arrives.

    SBV in the Auction Context

    There is also an auction-level advantage worth noting. Amazon’s ad auction rewards relevance, and CTR is one of the signals used to assess it. A creative that consistently earns a higher click-through rate effectively lowers your cost per click over time, because the algorithm interprets high CTR as a relevance signal and adjusts accordingly. Running SBV is not just a creative decision — it compounds into a structural cost efficiency advantage for brands that run it well.

    None of this matters, however, if you are running one video and hoping it holds. The real leverage is in velocity: getting to the right creative faster than your competitors by running more experiments per unit of time.

    The Problem With “Perfect” Video — And Why Velocity Beats Perfection

    The instinct to perfect a video before launching it is deeply intuitive. Nobody wants to put out creative that looks rough, that misses the brief, or that wastes budget on a bad concept. This instinct is not wrong in principle — execution quality does matter for SBV, more than it might for some other formats. But it becomes a liability when it causes teams to collapse ten potential creative hypotheses into one final choice before they have any performance data.

    The core problem is this: you cannot predict which creative angle will resonate with your audience until your audience tells you. Seasoned creative directors get this wrong. Research panels get this wrong. Internal stakeholders get this wrong with impressive consistency. The only reliable oracle is live performance data — and you can only gather that by shipping creative and reading the signal.
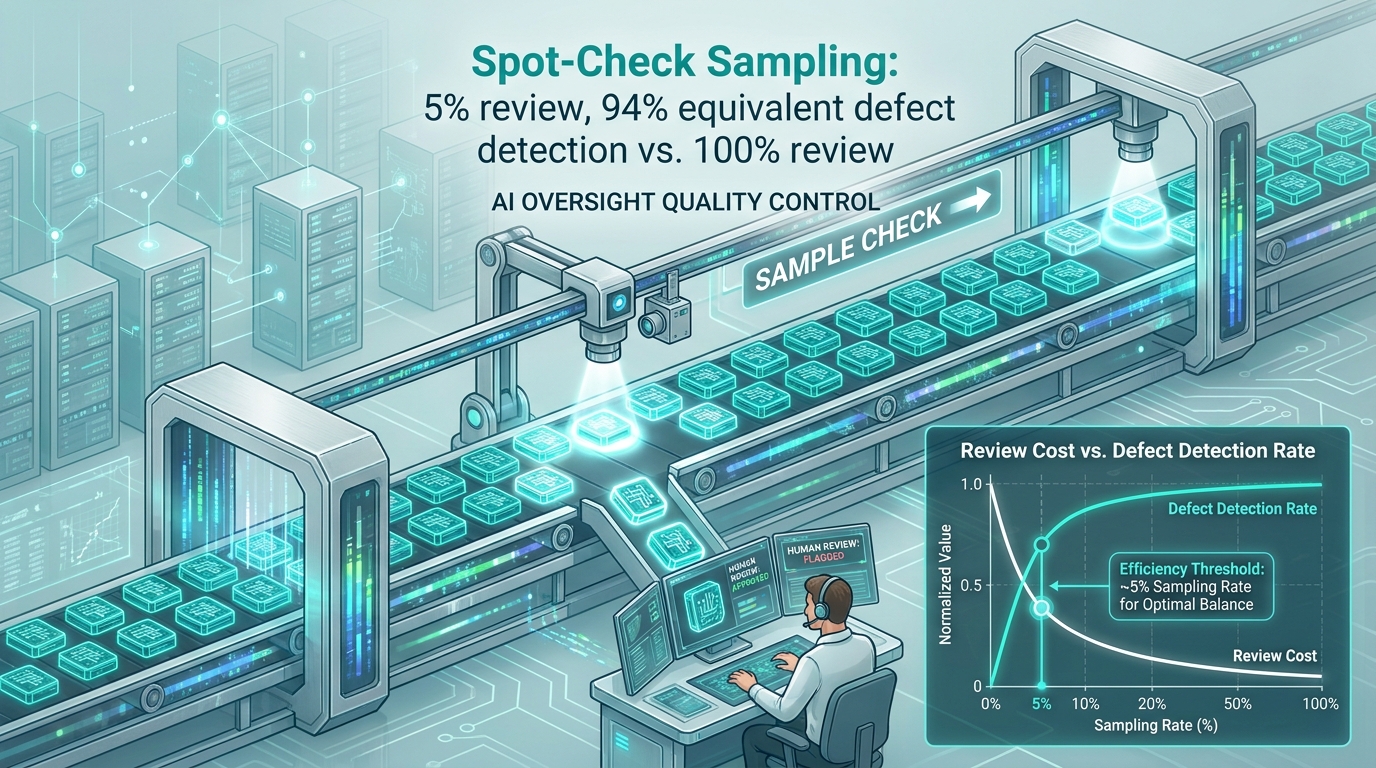
    The Cost of Waiting

    A brand that spends six weeks developing one SBV, launches it, and watches it fatigue over 45 days has run approximately 1.5 creative experiments in a quarter. A brand running weekly sprints that each produce 10 variations has potentially run 130 distinct creative experiments in the same period. The creative learning curve those two programs are on is not comparable.

    This is not a theoretical argument. It describes the actual divergence happening between top-performing brands and mid-tier performers on Amazon right now. The gap is rarely in budget — it is in creative throughput and the learning that velocity generates.

    What “Good Enough to Test” Actually Looks Like

    High-velocity creative does not mean low-quality creative. There is an important distinction between rough and lean. A lean SBV is tightly conceived, well-lit, clearly audio-designed for muted playback, and hits its key visual moment in the first two to three seconds. It does not need a $50,000 production budget to do any of those things. Many of the highest-CTR SBV creatives in 2026 have been produced by teams running a smartphone, a white paper background, and a clear script.

    The threshold is not “polished.” The threshold is “clear, credible, and hypothesis-testable.” If a video communicates its intended message clearly to a cold shopper and isolates a single variable from its companion videos in the sprint, it is ready to run.

    The Hidden Tax of the Perfection Mindset

    There is also an organizational cost to prolonged creative development cycles that rarely gets measured: the opportunity cost of the budget you are spending on a fatigued creative while your next sprint sits in review. Every week a single SBV continues running past its peak CTR is a week of ad spend subsidizing a declining asset instead of generating fresh learning. The perfection mindset does not just slow iteration — it actively extends the decay window.

    Anatomy of a High-Velocity SBV Sprint (The 7-Day Structure)

    7-day SBV creative sprint calendar showing day-by-day production workflow from brief to launch

    A seven-day creative sprint is not seven days of chaos. It is a highly structured sequence of discrete phases, each with a specific deliverable. The goal is to collapse the distance between “we have a hypothesis” and “we have live performance data” to one week. Here is how the days break down.

    Day 1: Brief and Hypothesis Set

    The sprint begins not with cameras but with clarity. On Day 1, the team assembles (or a lead strategist works alone) to define the sprint brief. This document answers five questions: What is the one product or offer being featured? What is the specific performance goal — CTR threshold, ROAS target, or conversion rate lift? What are the 10 creative hypotheses being tested? Which single variable will differ across each variation? And what will constitute a “winner” at the end of the sprint’s data window?

    The 10 hypotheses are the most important output of Day 1. Each one should be phrased as a testable statement: “A hook that leads with the customer’s pain point will outperform a hook that leads with the product feature.” That framing keeps the team honest during production and makes the results interpretable.

    Day 2: Shot List, Scripting, and Storyboards

    Day 2 converts the 10 hypotheses into a production plan. The critical insight here is that the 10 variations are not 10 separate shoots — they share a common “body” section (the 10-20 seconds that follow the hook) and a common CTA. Only the hooks vary in the first sprint’s hook-testing phase, or only the body angles vary if you are testing messaging, or only the CTAs vary if you are testing conversion triggers.

    The shot list therefore has two distinct sections: shared assets (everything that appears in the common body across all 10 variations) and variation-specific assets (the 10 different hooks, each scripted to a maximum of 5 seconds). This modularity is what makes one shoot day viable. You are not shooting 10 full videos — you are shooting the building blocks of 10 videos.

    Day 3: Shoot Day

    This is the only full production day in the sprint. For most SBV use cases, a 6-8 hour shoot is sufficient to capture all shared assets plus 10 distinct hook variations. The order matters: capture the shared body content first while energy is high and the setup is fresh, then work through each hook variation systematically.

    Capture extras of everything. Multiple takes of each hook, alternative camera angles on the body content, product close-ups from different perspectives. The time spent overshooting on Day 3 pays dividends in editing flexibility on Day 4 and 5, and it prevents costly reshoot requests from derailing the sprint.

    Day 4: Modular Editing — Parts, Not Films

    Day 4 is where the editor works on components, not complete videos. Each hook is cut to its cleanest version (typically 3-5 seconds). The shared body is assembled into a master segment. Each CTA variant is rendered. These are stored as labeled, reusable modules — not assembled into final videos yet. This modular approach is what enables the speed of Day 5.

    Day 5: Assembly — 10 Variations From One Set of Parts

    With all modules ready, Day 5 is assembly. The editor sequences Hook A + Body + CTA to produce Variation 1, then Hook B + Body + CTA to produce Variation 2, and so on. Captions, text overlays, and any format-required elements (SBV requires silence-first legibility, so all key messages should be readable without audio) are added at this stage. The 10 final files are exported, named with a consistent convention, and handed off for QA.

    Day 6: QA, Spec Check, and Upload

    Amazon’s SBV specs are non-negotiable: video must be between 6 and 45 seconds, no letterboxing or black bars, minimum 1280 x 720 resolution, and no pricing information in the creative. Day 6 is for verifying every variation against these requirements, uploading to Amazon Ads, configuring each variation in its own campaign structure (more on why this matters in the testing section), and setting baseline tracking parameters.

    Day 7: Launch and Baseline

    All 10 variations go live on Day 7. The first 72 hours of data are directional, not definitive — but they establish the baseline from which all future decisions are made. Budget is distributed evenly across variations at launch. Nothing is scaled or paused until you have at least 200-300 impressions per variation with meaningful click data. Day 7 is also when you document your hypotheses against the live assets so that analysis does not require archaeology later.

    The Modular Asset Bank — How to Shoot Once and Edit Into 10+ Variations

    The sprint model only works because of modular production logic. Understanding this deeply is what separates teams that pull off one sprint from teams that build a repeatable creative program.

    Think of every SBV as having three structural zones: the Hook (seconds 0-5), the Body (seconds 5-25), and the Close (seconds 25-30 or to end). Each zone carries a different functional weight in the viewer’s journey, and each zone can be varied independently.

    Building the Hook Library

    The hook is the highest-value creative real estate in any SBV. It determines whether the shopper pauses or scrolls. It sets the emotional frame. And because it can be swapped without changing anything else, it is the ideal starting point for your first sprint’s variable.

    A well-built hook library for one sprint captures 10 distinct opening sequences, each targeting a different angle — problem-first, product-first, lifestyle-first, social proof-first, and so on (detailed in the next section). Each hook is filmed in the same visual style as the body, so the edit does not feel jarring. The hook and body share lighting, location, and talent so continuity is seamless even when they are assembled from different clips.

    Building the Body and Close Templates

    The body is your product demonstration zone. This is where you show the product in action, communicate the primary benefit, and build the rational case for clicking. Because the body is shared across all 10 variations in a hook-testing sprint, it gets the most production attention. It should be tight (10-18 seconds), visually clear for muted playback, and deliberately structured: show the product, demonstrate the key benefit, surface the use case.

    The Close is the CTA zone. Like the hook, it can be independently varied. In a hook-testing sprint, you will likely hold the CTA constant. But a subsequent sprint — after you have identified your best hook — might swap the CTA across 10 variations to identify the most conversion-efficient closing message.

    Naming Conventions and Asset Management

    Modular production creates an asset management challenge if you do not solve it from the start. Every raw clip, every rendered module, and every assembled variation should follow a consistent naming convention from the moment it is captured. A format like [BRAND]_[PRODUCT]_[SPRINT#]_[ZONE]_[VARIANT_LETTER] (e.g., APEX_BLENDER_S01_HOOK_B) takes 30 seconds to apply and saves hours of archaeology when you are scaling into Sprint 3, Sprint 4, and Sprint 5 with an expanding library of reusable assets.

    Reusing Across Sprints

    One of the compounding advantages of the modular approach is that assets do not expire after one sprint. A body segment that performed well in Sprint 1 can be paired with entirely new hooks in Sprint 3. A hook that won a hook test can become the permanent opening of a hero SBV that runs for 60 days. The asset bank grows with each sprint, and so does your creative optionality.

    10 Creative Variation Angles to Test in Your First Sprint

    10 SBV creative variation angles shown as labeled cards: Pain Point, Product Demo, Before/After, Lifestyle, Social Proof, Competitive Contrast, Problem-Agitate-Solve, Curiosity Gap, UGC-Style, CTA-First

    Your first sprint is most valuable when it tests fundamentally different angles — not minor execution tweaks. The goal is to surface which creative category your audience responds to, so subsequent sprints can drill deeper into the winner. Here are the 10 angles structured for maximum signal value.

    Variation 1: The Pain Point Hook

    Opens with the customer’s problem, stated directly or shown viscerally. No product in the first frame — just the frustration, the inconvenience, or the failure state the product solves. This angle works exceptionally well for products in categories where shoppers are actively looking for relief: cleaning tools, health aids, organizational products, and kitchen items. The viewer self-selects by recognizing their own problem.

    Example opening: A closeup of a cluttered drawer. Text overlay: “Tired of digging through this every morning?” Cut to product at second 3.

    Variation 2: The Product Demo Hook

    The product appears in the very first frame, doing the thing it is best at. No preamble. No setup. Just the action. This angle assumes the shopper already has category intent and rewards them with immediate relevance. It tends to perform well on high-purchase-frequency categories where the audience is efficient and knows what they are looking for.

    Example opening: Product in hand, demonstrating primary function in one clean motion. Text overlay: the primary feature claim. No narration needed.

    Variation 3: The Before/After Reveal

    A two-frame contrast — the state before the product, then the transformed state after. This is one of the most intuitive creative structures for human brains, because it delivers a narrative arc in under five seconds. For transformation-oriented categories (skincare, fitness equipment, home improvement, organization), this angle consistently generates strong click-through because it makes the product’s value immediately tangible.

    Variation 4: The Lifestyle In-Use Hook

    Opens with a real-world scene showing the product being used in context — a morning kitchen routine, a camping setup, a home office desk. The product is secondary to the setting; the viewer is drawn in by the lifestyle aspiration or relatability first. This angle performs especially well when the product’s appeal is partly aspirational or identity-based rather than purely functional.

    Variation 5: The Social Proof Hook

    Opens with a customer-voice element: a review excerpt overlaid on screen, a star rating, a testimonial quote, or a “verified purchase” callout. In a marketplace environment where trust is a primary purchase barrier, leading with evidence that other customers have already made the decision can dramatically lower resistance. This angle often outperforms in lower-awareness categories where the brand name carries less inherent credibility.

    Variation 6: The Competitive Contrast Hook

    Opens by implying or showing what competitors’ solutions look like — without naming competitors — then pivoting immediately to your product’s differentiated approach. “Most [product category items] require [frustrating process]. This one doesn’t.” This angle works when your product has a genuine structural advantage that can be visualized quickly. It is particularly effective in crowded categories where the differentiation story is the primary purchase driver.

    Variation 7: The Problem-Agitate-Solve Structure

    The classic persuasion sequence compressed into five seconds. The hook names the problem (one second), amplifies it briefly (one to two seconds), then introduces the product as the specific solution (one to two seconds). PAS works across nearly every category because it aligns with how shoppers arrive at a purchase decision: they feel the problem first, then search for relief. Starting your hook at that emotional starting point creates immediate alignment.

    Variation 8: The Curiosity Gap Hook

    Opens with a statement or visual that creates an information gap the viewer needs to close. “We tested 47 versions of this before getting the formula right.” “Most people who try this once never go back to [old method].” “This is not what it looks like.” These hooks exploit the brain’s drive for completion — the viewer clicks because they need to resolve the open question. Curiosity gap hooks require more specific knowledge of your category to execute well, but when they land, they often produce outsized CTR.

    Variation 9: The UGC-Style Authenticity Hook

    Deliberately shot to look like organic user content rather than an ad: handheld camera, natural lighting, conversational tone, relatable setting. This angle can perform exceptionally well because it disrupts the visual language of typical ad creative. Shoppers who have developed ad-blindness from constant exposure to polished commercial formats respond to the perceived authenticity. The key is to make it look organic without crossing into deception — the product should be the genuine subject of the content.

    Variation 10: The CTA-First Urgency Hook

    Opens with the action you want the viewer to take, combined with a reason to act now. “Click before we run out — we’re down to 200 units.” “This deal ends Sunday.” “Shop the #1 rated [category] on Amazon.” This is a directional hook that works best when paired with a genuine scarcity or urgency signal. It tends to attract high-intent shoppers who are close to the purchase decision already and just need a trigger. Do not use it with fabricated urgency — sophisticated shoppers see through it quickly and it will suppress credibility.

    Hypothesis-Driven Testing: The Variable Isolation Framework

    Variable isolation testing framework for SBV showing what to change, hold constant, and measure in creative tests

    Ten variations only generate useful data if they are set up to be readable. The most common mistake teams make in creative testing is changing multiple things simultaneously and then trying to draw conclusions from the result. That is not a test — it is noise with a budget attached.

    The One Variable Rule

    Each sprint should test exactly one variable category. If you are testing hooks, every variation must have the same body, the same CTA, the same text overlay style, and the same music. If you are testing CTAs, every variation must have the same hook and body. If you are testing messaging angles in the body, every variation must have the same hook and the same CTA.

    The discipline this requires is uncomfortable. Teams will want to also “fix” the CTA while they are in there, or “improve” the text overlay on a few variations. Resist this completely. Any change that is not the designated test variable is contamination. It makes the results uninterpretable, which wastes the entire sprint’s data value.

    Writing the Hypothesis Statement

    Every variation should have a pre-written hypothesis statement before it goes live. The format is simple: “IF we lead with [specific creative approach], THEN we expect [specific metric] to increase by [estimated magnitude] BECAUSE [customer behavior rationale].“

    This is not bureaucracy. Writing out the “because” forces the team to articulate why they believe a creative choice will work — and that articulation is what gets smarter over sprints. When Variation 4 (Lifestyle Hook) beats Variation 2 (Product Demo Hook) and your hypothesis had predicted the opposite, the gap between prediction and reality is where the most valuable learning lives.

    Campaign Structure for Isolated Testing

    On Amazon Ads, variable isolation requires a specific campaign structure. Each SBV variation should run in its own campaign — not as different ads within the same campaign. This ensures that each variation receives its own impression allocation and that Amazon’s delivery algorithm does not internally optimize toward one variation and starve the others of data before you have had a chance to read the results.

    Keep the following variables constant across all 10 campaigns: keyword targeting (same keyword list), match types, bid strategy, daily budget (equal across all), placement settings, start and end dates. The only thing that should differ is the video creative asset. Everything else is locked.

    Minimum Data Thresholds Before Declaring a Winner

    Calling a winner too early is one of the most expensive testing mistakes in PPC. A variation that generates 30 clicks in the first 48 hours may look like a strong performer — but with that sample size, the confidence interval is too wide to act on. A general minimum threshold before making pause/scale decisions on SBV creative tests is:

    • Impressions: At least 1,000 per variation
    • Clicks: At least 30-50 per variation for CTR decisions
    • Time: At least 7-10 days of live running to smooth out day-of-week patterns
    • Orders: At least 10-15 per variation before making ROAS-based decisions

    For lower-volume products or smaller budgets, these thresholds may take longer to hit — which is a reason to prioritize CTR as the primary sorting metric, since it accumulates faster than purchase data.

    Reading Your Results: The Metrics That Tell You What to Keep, Kill, or Scale

    Data without a reading framework is just noise in a spreadsheet. Here is the decision logic for interpreting SBV sprint results.

    Primary Metric: CTR (Click-Through Rate)

    CTR is the attention signal. It tells you whether the hook captured intent. In the context of a hook-testing sprint where everything except the first five seconds is identical, a material CTR difference between variations is almost entirely attributable to the hook. This is the cleanest creative signal available in Amazon Ads.

    What “material” means depends on your category baseline. If your current SBV is running at 0.65% CTR and a new variation hits 0.95%, that is a 46% lift — clearly meaningful. If the range across your 10 variations spans 0.60% to 0.70%, the signal is weak and no single variation has a definitive edge; in that case, run a follow-up sprint with more extreme hook differences.

    Secondary Metric: CVR (Conversion Rate) and ROAS

    A variation that wins on CTR but loses on CVR is generating curiosity it cannot convert. This is possible — a hook that overpromises or sets the wrong expectation can attract clicks from shoppers who then land on the detail page and feel misled. Always layer CVR analysis on top of CTR analysis before declaring a winner.

    The ideal creative is one that wins on both — high CTR indicating strong hook performance, and a CVR that matches or exceeds your campaign baseline, indicating that the shopper the hook attracted was the right shopper. When you find that combination, that is your winner, and it deserves to be scaled.

    The Keep/Kill/Scale Framework

    • Scale: Top 2-3 CTR performers with CVR at or above baseline. Increase budget, move to a hero campaign.
    • Keep/Monitor: Variations with middle-tier CTR but strong CVR — these may be attracting lower volume but higher-quality intent.
    • Kill: Bottom-quartile CTR with no compensating CVR signal after reaching data thresholds. Pause and do not rerun without a fundamental creative change.
    • Investigate: High CTR but below-baseline CVR. This indicates a hook-to-page alignment problem. The hook may be conceptually sound but setting an expectation the listing cannot fulfill. Fix the landing page, or revise the hook’s specific promise.

    Feeding Results Into the Next Sprint

    The output of every sprint is not just a winner — it is a brief for the next sprint. If Variation 3 (Before/After) won the hook test, the next sprint brief starts from that insight and drills deeper: what specific before state resonates most? What after state matters most to this shopper? Does the transformation moment need to appear earlier or later? Sprint 2 does not start from zero — it starts from Sprint 1’s winning hypothesis and refines it.

    This is the compound effect of sprint-based creative development. Each cycle generates learning that makes the next cycle faster, more targeted, and more likely to produce a lift rather than a wash.

    Creative Fatigue and the 60-90 Day Refresh Cycle

    SBV creative fatigue decay curve showing CTR declining from Day 45 to Day 90 with refresh window annotation

    Even a winning creative has a shelf life. The data on SBV creative fatigue in 2026 is fairly consistent: measurable CTR decay typically begins around Day 45 of continuous serving, with significant degradation visible by Day 75. By Day 90, a creative that launched at 0.90% CTR may be running at 0.55% or lower — a decline that is quietly eroding both performance and ad efficiency without triggering any obvious alert.

    Why Fatigue Happens in Amazon’s Environment

    Amazon’s search audience is not a static pool. But for any given keyword set, the overlap between repeat visitors is higher than most advertisers assume. A shopper who searches for “stainless steel travel mug” multiple times in a month will see the same SBV repeatedly. After three or four exposures, the hook that originally stopped their scroll becomes familiar — and familiarity kills the pattern interrupt effect that generates CTR.

    This is not a failing of your creative. It is physics. Even the best TV spots become wallpaper after enough exposures. The answer is rotation frequency, not hoping your winner lasts longer than it will.

    The Proactive Refresh Approach

    The sprint model is specifically designed to solve this problem at the root. Rather than waiting for fatigue to register in the data and then scrambling to produce new creative, the sprint cadence means you always have the next creative wave in development before the current one starts declining.

    A practical schedule for a brand running consistent SBV looks like this:

    • Weeks 1-2: Sprint 1 launches. 10 variations running. Data accumulating.
    • Weeks 3-4: Sprint 1 winner identified and scaled to hero campaign. Sprint 2 brief being developed.
    • Weeks 5-6: Sprint 2 runs. New 10 variations tested. Sprint 1 hero creative approaching Day 45.
    • Weeks 7-8: Sprint 2 winner identified. Sprint 1 hero creative rotated or refreshed based on fatigue data.

    This staggered cadence means you are never in the position of running a fatigued creative because nothing new is ready. The pipeline always has something in production, something in testing, and something scaling.

    Leading Indicators of Fatigue

    Do not wait for ROAS to decline before investigating creative fatigue. The earlier signal is almost always in CTR. If your SBV CTR drops more than 15-20% from its running average over any 7-day window, treat it as a fatigue signal and move the scheduled refresh forward. Catching the decline early means you can rotate in a fresh variation before the conversion impact becomes material.

    Amazon’s Ads console now surfaces video-specific metrics — completion rate, mute/unmute interactions, and engagement rate — that can provide early warning signals before CTR visibly drops. Monitor these weekly, not monthly.

    Team Structure and Tooling for a Repeatable Sprint Machine

    The sprint model described above is achievable for a lean team. It does not require a full creative studio. But it does require clear role definition and the right tooling to prevent the workflow from collapsing under its own volume.

    The Minimum Viable Sprint Team

    A functional sprint team needs five roles covered. Those roles can be distributed across fewer people — a brand with a strategic marketer, a videographer, and an editor can run this — but each function must be owned by someone:

    • Sprint Lead / Strategist: Owns the brief, the hypotheses, the testing framework, and the results analysis. This person understands the data and translates it into creative direction.
    • Scriptwriter / Creative Director: Converts the hypotheses into specific, shootable concepts. Writes each hook script. Ensures the body and close are tight and on-brief.
    • Videographer / Producer: Executes the shoot day. Manages lighting, shot list, talent (if any), and asset capture. Overshoots systematically.
    • Video Editor: Builds the modular parts and assembles the 10 variations. Manages the asset library and naming convention.
    • Ads Manager / Campaign Operator: Sets up the campaign structure, uploads assets, configures targeting and bids, monitors data, and runs the keep/kill/scale framework.

    Tooling Stack for Sprint Operations

    The tools required are not exotic, but they do need to be configured before Sprint 1 launches:

    • Project management: Notion, Asana, or ClickUp with a dedicated sprint template that tracks each variation’s hypothesis, status, and performance
    • Asset storage: Google Drive or Dropbox with a consistent folder structure (Sprint > Modules > Final Variations)
    • Video editing: DaVinci Resolve, Premiere Pro, or CapCut for Business — the key is that your editor is fluent in whichever tool and can work fast on Day 4 and 5
    • Performance tracking: Amazon Ads console supplemented by a custom data pull into Google Sheets or a third-party tool like Perpetua, Pacvue, or Helium 10 Adtomic for cross-campaign comparison
    • Sprint log: A running document (Google Sheets or Notion database) that records every sprint’s hypotheses, results, and key learnings — this becomes your institutional creative memory

    AI-Assisted Speed Boosts

    In 2026, AI tooling has entered the sprint workflow at several specific points without replacing human judgment:

    • Hook scripting: AI can generate 20-30 hook script drafts from a brief in minutes, which the creative lead then culls and refines to 10 production-ready options
    • Caption and text overlay generation: Auto-captioning tools dramatically reduce the time required to make SBV legible for muted playback
    • Background music selection: AI music tools can match tempo and mood to brief specs without licensing concerns
    • Data analysis: AI can summarize comparative performance across 10 campaigns and flag statistical outliers faster than manual spreadsheet review

    These tools shave hours off Days 2, 4, and 5 without changing the fundamental creative logic of the sprint. The human decisions — which hypotheses to test, what constitutes a meaningful lift, how to brief the next sprint — remain firmly in the hands of the strategist.

    Common Sprint Mistakes That Quietly Sabotage Results

    Even teams that understand the sprint model conceptually tend to make a set of predictable mistakes on first execution. These are the ones worth specifically guarding against.

    Mistake 1: Testing Variations That Are Too Similar

    If your 10 hook variations are all minor wording changes to essentially the same concept, the sprint will produce tight, undifferentiated results that cannot guide creative direction. The variations need to represent genuinely different creative hypotheses — different emotional entry points, different visual approaches, different audience assumptions. If you look at your 10 scripts and they all feel like versions of the same thing, the brief needs to go wider before production starts.

    Mistake 2: Treating CTR as the Only Metric

    CTR measures attention. It does not measure purchase intent quality. A hook that generates 2.0% CTR by being sensationalist or ambiguous is not a winner if the conversion rate on those clicks is 1%. Always layer CVR and, where you have sufficient data, ROAS before declaring a creative the champion.

    Mistake 3: Inconsistent Campaign Setup Across Variations

    This is a mechanical error, but it is surprisingly common. If one campaign has exact match targeting and another has broad match, or if budgets differ, or if bid strategies differ, the performance differences between variations are no longer interpretable as creative signals. The campaign setup discipline has to be enforced without exception, every sprint.

    Mistake 4: Pausing Too Early Based on Early Data

    The urge to pause underperforming variations within the first 48-72 hours is understandable — it feels like responsible budget management. But SBV campaigns on Amazon often need 5-7 days to exit the learning period and reach statistically meaningful impression volumes. Variations that look weak on Day 2 sometimes emerge as strong performers by Day 7. Hold the discipline of the minimum data threshold before making any pause decisions.

    Mistake 5: Not Documenting the Learning

    The sprint log is not optional. Teams that run sprints without documenting their hypotheses and results tend to rediscover the same learnings repeatedly — testing similar angles, finding similar results, and not building on them. The sprint log is the mechanism that converts testing activity into institutional knowledge. Without it, velocity without learning is just expensive noise.

    Mistake 6: Shooting for One Sprint and Stopping

    The value of the sprint model is cumulative. One sprint gives you data. Two sprints give you a directional hypothesis. Five sprints give you a creative thesis that has been tested and refined through multiple iterations. Brands that run one sprint, find a winner, and then stop testing have captured only the first layer of the model’s value. The competitive advantage is in maintaining the cadence, not completing a single cycle.

    Building a Creative Velocity Advantage That Compounds

    The sprint model is not just a production technique — it is a compounding investment in creative intelligence. Every sprint that runs adds to a growing body of performance knowledge about your specific audience, your specific category, and your specific product’s strongest creative angles. That knowledge narrows the gap between concept and winner with each iteration.

    By Sprint 5, a team running this model will know: which hook categories outperform for their audience (emotional vs. rational vs. social proof), which body structure converts best (demo-forward vs. benefit-forward vs. use-case-forward), which CTA framing drives action most efficiently, and approximately how long each winning creative sustains before fatigue requires a refresh. That is not anecdotal — it is empirically derived from live data across 50 tested variations.

    That knowledge is not available to competitors who are still treating SBV as a one-and-done production project. And it does not transfer easily — it lives in your sprint log, in your team’s accumulated pattern recognition, and in the asset bank that gets richer with every sprint.

    The Practical Starting Point

    If you have never run a sprint, the immediate action is not to redesign your entire creative program. It is simpler: take your next planned SBV production and instead of making one video, commit to making 10 variations from the same shoot. Pick 10 hooks from the angle library above. Write 10 hypotheses. Set up 10 campaigns with identical targeting and budget. Launch them, read the data for 10 days, and apply the keep/kill/scale framework to what you find.

    That single sprint will generate more actionable creative insight than most brands gather from three months of running a single SBV. It will also give you a winner that you can be confident in — because it earned the title against nine alternatives, not by being the only entry in the race.

    What Changes at Scale

    As the sprint cadence matures, the scope of testing expands. Later sprints can test body structures, CTA language, music choices, text overlay placements, caption styles, and talent presentation styles. The variable isolation discipline means each of these tests remains readable. The asset bank means later sprints get cheaper per variation because more modular parts are already built and reusable.

    Eventually, a mature sprint program starts to feel less like a creative process and more like a research function — one that continuously generates signal about what your audience responds to, and continuously converts that signal into better-performing SBV. That is precisely what it is. And it is the kind of structural creative advantage that compounds quietly while competitors are still asking which video to make next.

    Final Takeaways

    • SBV delivers 1.6-2.6x higher CTR than static Sponsored Brands — but only if the creative is continuously tested and refreshed.
    • The 7-day sprint structure turns one shoot day into 10 live variations by separating production into modular zones: hook, body, and close.
    • Variable isolation is non-negotiable. Test one thing per sprint or your data is unreadable.
    • CTR is the primary signal; CVR is the filter. A winner must clear both metrics before scaling.
    • Creative fatigue begins around Day 45. Start your next sprint before it arrives, not after you notice the decay.
    • The sprint log is the most underrated asset in this entire system. Document every hypothesis and every result without exception.
    • The compounding value is in the cadence, not the single sprint. Build the machine, then let it run.