Category: Uncategorized

  • The Department-by-Department ChatGPT Work Deployment Map: What’s Actually Happening on the Ground in 2026

    The Department-by-Department ChatGPT Work Deployment Map: What’s Actually Happening on the Ground in 2026

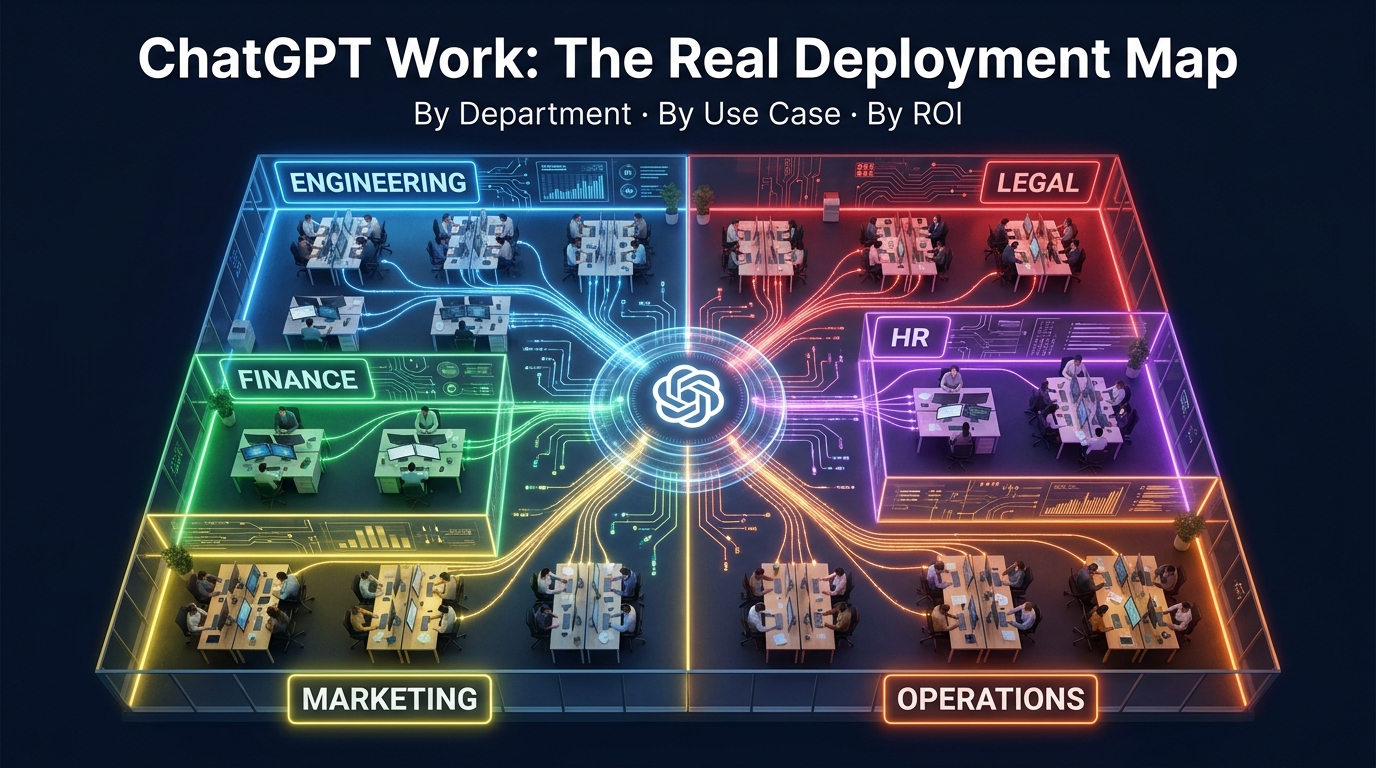
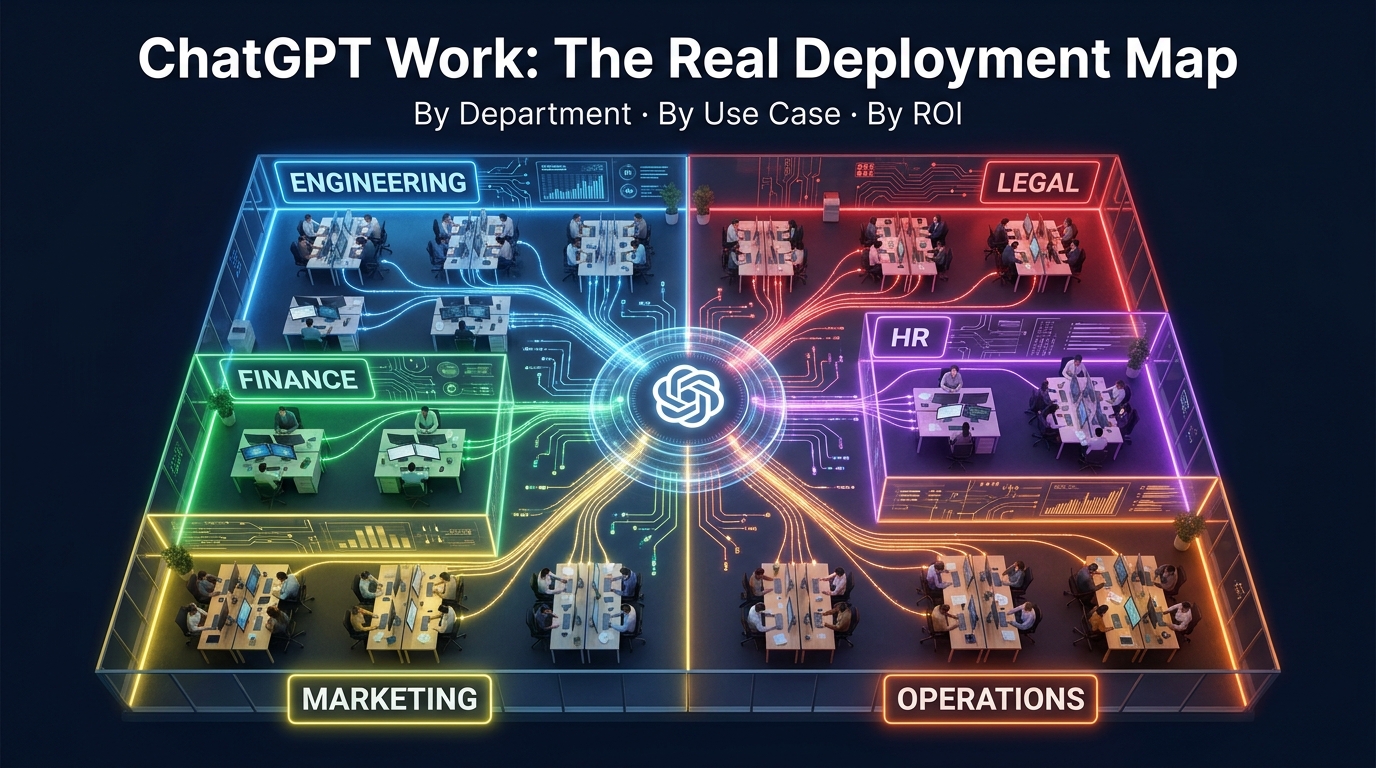
    ChatGPT Work deployment map across departments: Engineering, Finance, Marketing, Legal, HR, Operations

    Ask any executive in mid-2026 whether their company is “using AI,” and you’ll almost certainly get a yes. Ask them which teams are getting results, which are spinning their wheels, and what separates the two — and the answers get a lot murkier.

    This is the real challenge with ChatGPT in the workplace right now. The technology is broadly available. The motivation to deploy it is strong. But the outcomes are wildly uneven — and the gap has almost nothing to do with the model itself.

    What separates companies hitting 200–350% first-year ROI from those sitting on a pile of unused Enterprise licenses comes down to a set of deployment decisions that are almost never discussed in the product launch announcements: which department goes first, what specific workflows get targeted, how prompts are governed, and how human review is built into the process before a single output leaves the building.

    This article is not about whether ChatGPT is worth deploying. That debate is over. It’s about how the organizations that are actually succeeding are doing it — department by department, workflow by workflow, decision by decision. We’ll map what’s working in engineering, finance, marketing, legal, HR, and operations, look at the governance architecture that makes or breaks deployments at scale, and give you a practical prompt-library framework you can build from this week.

    If you’ve already deployed ChatGPT and wonder why adoption is flatlining, or if you’re planning a rollout and want to skip the expensive mistakes, this is the map you need.

    From Chatbot to Autonomous Agent: What ChatGPT Work Actually Is in 2026
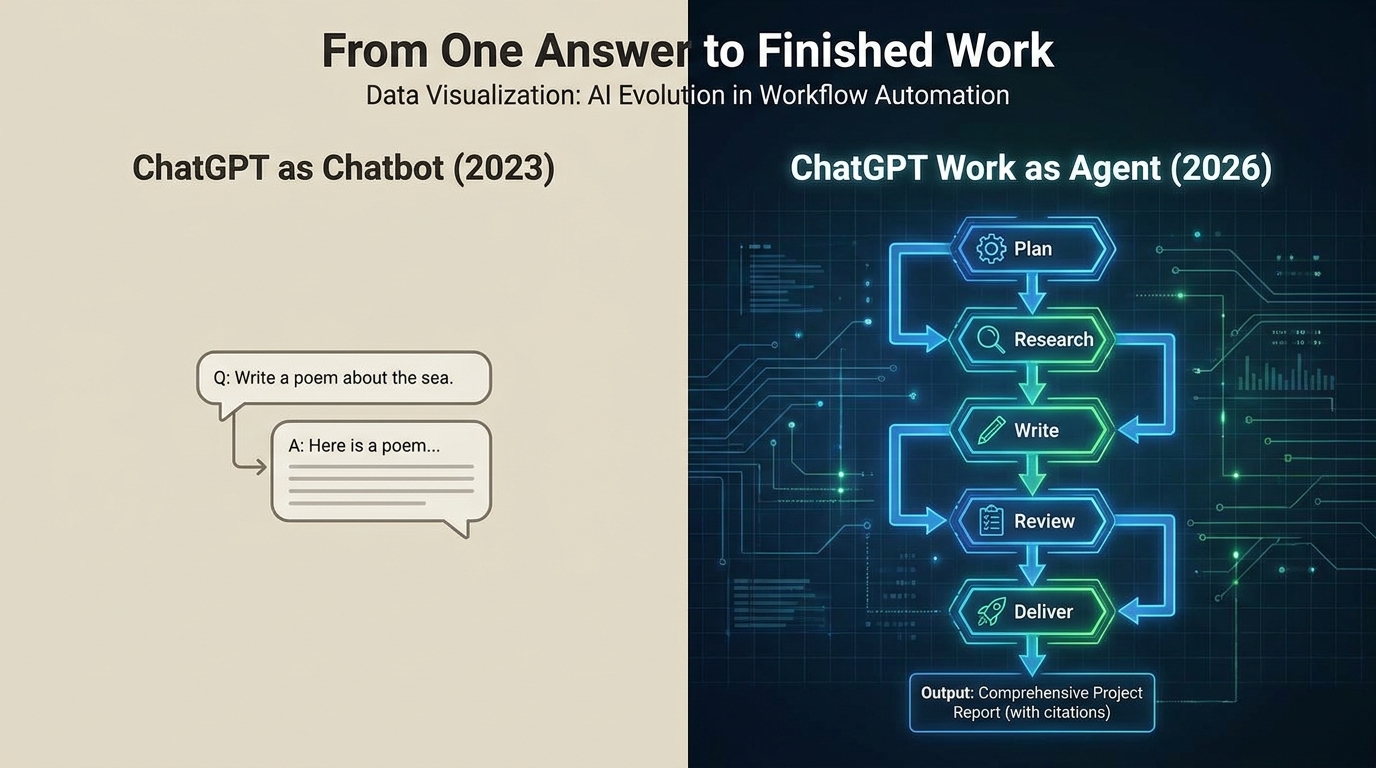
    Split-screen comparison: ChatGPT as a single-turn chatbot in 2023 vs. ChatGPT Work as a multi-step autonomous agent in 2026

    The term “ChatGPT” still conjures images of a text box where you type a question and get an answer. That model of the tool is now several generations out of date, and organizations that are still treating it that way are leaving the majority of its value on the table.

    ChatGPT Work — OpenAI’s enterprise-oriented agentic feature set — can accept a high-level business goal, plan the steps required to achieve it, execute those steps across connected apps and files, and deliver a finished work artifact. Not a draft. Not raw output. A finished deliverable: a spreadsheet, a slide deck, a forecasting model, a PR-ready code change, an updated campaign readout.

    What “Agentic” Means in Practice

    When practitioners use the word “agentic” to describe ChatGPT Work, they mean something specific. The system doesn’t just respond to a prompt — it reasons about a goal, assembles a plan, uses tools (web search, code execution, file access, connected SaaS integrations), executes steps in sequence, checks its own output, and iterates until the task is complete. This can run for minutes or, in complex cases, hours, with minimal human intervention during execution.

    The practical implication is significant. In a traditional deployment, a knowledge worker might use ChatGPT as a drafting assistant — paste in content, get improved content back, copy it somewhere else. That’s a productivity enhancer. ChatGPT Work operating agentically is closer to a digital coworker: it connects to your project management system, pulls the relevant data, synthesizes it with context from recent messages, builds the status deck, and flags the blockers. The worker reviews and approves the output rather than building it from scratch.

    The Three Modes of Current Deployment

    Across organizations deploying ChatGPT in 2026, three distinct modes have emerged based on how deeply agentic the use case is:

    • Assisted mode: ChatGPT helps a human produce better output — editing, summarizing, drafting, translating. The human drives every step. This is the most common mode and the easiest to deploy safely.
    • Directed mode: ChatGPT executes defined multi-step tasks under human supervision — it runs a research workflow, generates a report structure, populates a template from connected data. The human reviews before anything goes external.
    • Autonomous mode: ChatGPT Work runs background tasks, scheduled workflows, or cross-system processes with limited human input during execution. This is where the highest productivity gains live — and where governance becomes non-negotiable.

    Most organizations are currently operating in a mix of assisted and directed modes, with selective autonomous deployments for well-defined, lower-risk workflows. The shape of that mix by department tells you a lot about where the real ROI is being captured.

    The Four Deployment Tiers: Choosing the Right Seat Structure Before You Start

    One of the most consequential decisions organizations make before deploying ChatGPT at work is also one of the least discussed: which plan tier to use, and how to structure seats across teams. Getting this wrong creates both security exposure and budget waste.

    ChatGPT Team (2–149 users)

    Designed for small to mid-size departments or early-stage pilots. ChatGPT Team provides shared workspaces, basic admin controls, and strong default data privacy (conversations are not used to train OpenAI’s models). It’s the right tier for a department of 20–30 people testing a focused workflow before broader rollout.

    The limitation is scale and governance depth. Team doesn’t include SSO/SCIM provisioning, audit logs, or the kind of centralized analytics you need to manage adoption across dozens of departments. Organizations that try to scale Team-tier deployments to 500+ users typically hit friction fast.

    ChatGPT Enterprise

    Enterprise is purpose-built for company-wide deployments in regulated or security-conscious environments. It adds SSO/SCIM integration, audit logs, data residency controls, compliance API visibility for conversations and agent activity, and advanced workspace analytics. It also includes full access to ChatGPT Work’s agentic capabilities and Codex for engineering teams.

    OpenAI’s own case studies show that companies who move to Enterprise typically see significantly higher adoption rates. In one reported deployment, 83% weekly active users and 98% employee preference over competing tools were measured — metrics that reflect both product quality and the organizational momentum that comes from a properly governed rollout.

    The Pilot-to-Enterprise Bridge

    The most common and costly deployment mistake organizations make is running a Team-tier pilot for three months, seeing positive results, and then trying to scale company-wide without upgrading their governance architecture. The pilot worked because it was small, well-managed, and involved early adopters. The company-wide rollout fails because governance, training, and integration weren’t designed to scale with it.

    The better path: use Team-tier for genuine experimentation with 20–50 users, document what works, build the governance framework, and move to Enterprise for the production rollout. Don’t try to scale the pilot — industrialize the lessons from it.

    Engineering and Dev Teams: The Fastest Adopters — and the Most Instructive Case
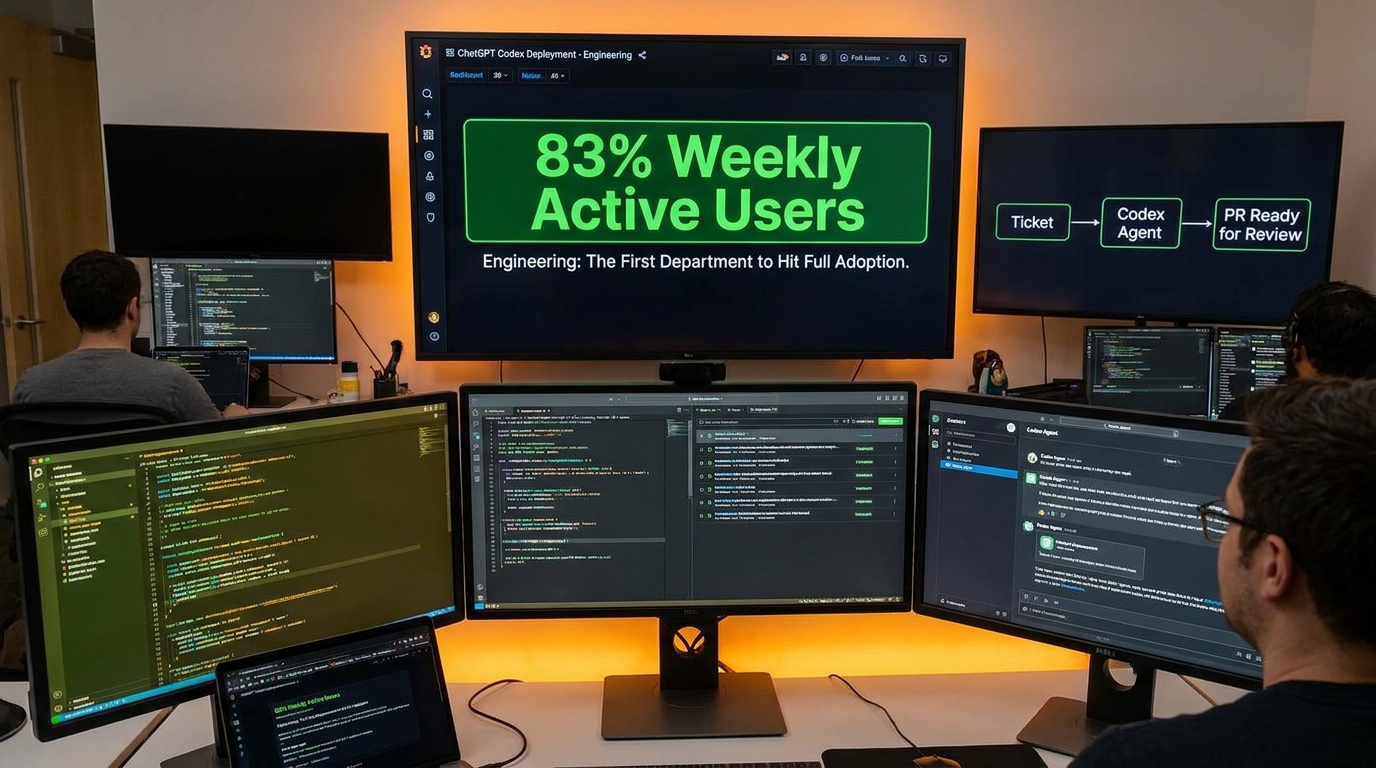
    Engineering team ChatGPT Codex deployment showing ticket-to-PR workflow with 83% weekly active user stat

    Engineering teams are, consistently, the fastest adopters of ChatGPT at work — and not just because developers are more comfortable with AI tools. The deeper reason is structural: software development already has the workflow discipline, review processes, and measurement infrastructure that successful AI deployment requires. Engineers don’t ship code without review. They have version control. They have test suites. These habits translate directly into responsible AI use.

    The Codex Workflow: Ticket to PR Without Manual Coordination

    The flagship engineering use case for ChatGPT Enterprise in 2026 is Codex-powered PR generation. The workflow runs like this: a developer receives a ticket, opens it in a Codex-connected environment, and instructs the agent to understand the task, inspect the relevant codebase, propose a solution, implement the change, run the test suite, validate the experience, and prepare the PR for team review — all in a single flow.

    This isn’t theoretical. Organizations running this workflow are reporting measurable reductions in cycle time from ticket to review-ready PR. The human work shifts from writing code from scratch to reviewing, approving, and refining AI-generated work — a change that experienced developers often describe as qualitatively different rather than just faster.

    What the 60–80% Adoption Figure Actually Means

    Current estimates put ChatGPT adoption in engineering and IT departments at 60–80%+ across organizations that have deployed Enterprise. That number is significantly higher than marketing (40–60%) or HR (15–30%), and it reflects a few things beyond developer enthusiasm:

    • Clear output verifiability: Code either compiles and passes tests or it doesn’t. Engineers can assess AI output quality rapidly and with confidence, which reduces anxiety about using the tool.
    • Existing workflow integration: GitHub, Jira, and linear development workflows already have integration points. Slotting Codex into a PR review process requires less organizational change management than, say, introducing AI to a legal review process.
    • Culture of experimentation: Engineering culture typically treats new tools as hypotheses to test rather than threats to resist. This lowers the adoption friction that kills rollouts in more risk-averse departments.

    The Engineering Playbook: What Successful Teams Do

    The teams getting the most out of ChatGPT in engineering are following a consistent pattern. They start with code documentation and explanation tasks — low-risk use cases where AI output quality is easy to verify. They build confidence, refine their prompting practices, and then move to more complex tasks like test generation, code review assistance, and eventually full Codex-driven PR workflows.

    They also treat AI-generated code the same way they’d treat code from a junior developer: it gets reviewed, it goes through the test suite, and nothing ships without human signoff. That discipline — not the tool itself — is what separates teams that succeed from those that introduce bugs at scale.

    Finance Teams: The Workflow That Pays Back Fastest
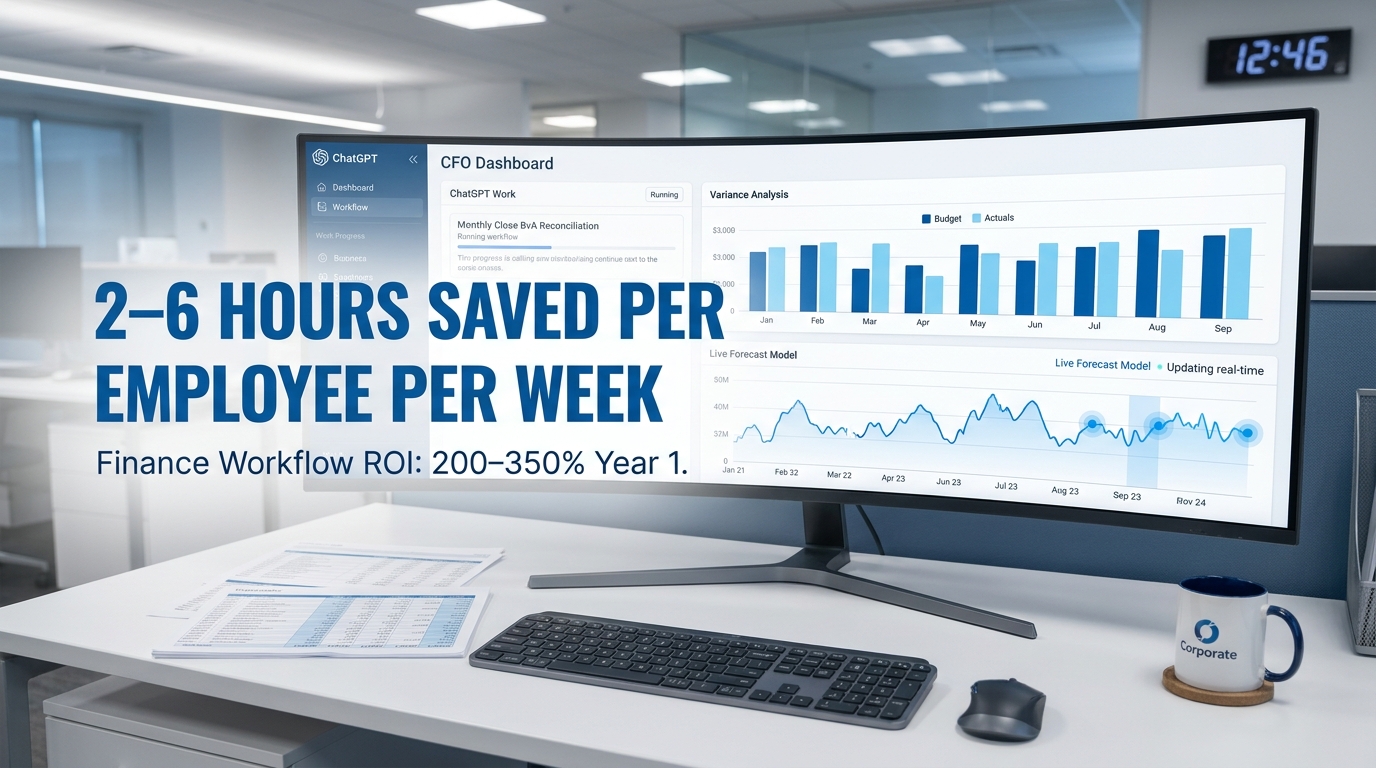
    Finance team ChatGPT Work dashboard showing monthly close BvA reconciliation workflow with ROI statistics

    Finance is not the department most people imagine when they think about ChatGPT deployment. But in terms of raw time-savings, measurable ROI, and payback speed, it is consistently one of the top performers — because finance work is exactly the kind of high-volume, structured, data-intensive workflow that ChatGPT Work handles well.

    The Monthly Close Problem

    Every finance team that runs a monthly close knows the pain: stitching together data from multiple systems, reconciling variances, building BvA (budget vs. actual) comparisons, adjusting forecasts, and preparing leadership presentations — all under time pressure, all with a high tolerance for error.

    ChatGPT Work’s finance workflow addresses this directly. As described in OpenAI’s own Enterprise documentation, a fully connected deployment can reconcile variances across systems, assess the quality of results against targets, model risk-weighted scenarios, build a live dashboard, and refresh the forecast model — in a fraction of the time a manual process requires.

    This is the archetype of a workflow where ChatGPT delivers not just convenience but structural time savings that compound month over month. Finance teams running this workflow are reporting reductions in monthly close cycle time, with some organizations cutting the process by 30–40% in the first quarter of deployment.

    Ad Hoc Analysis vs. Guided Decision Support

    The second major finance use case — and one that’s significantly underdeployed — is moving from reactive ad hoc analysis to proactive decision support. In a traditional setup, a finance analyst spends much of their time answering the same five questions from business partners: what was revenue last month, what’s driving the variance, how are we tracking against plan? These are valuable questions, but the analysis to answer them is repetitive and time-consuming.

    ChatGPT Work connected to a data warehouse and CRM can run a standing analysis on these questions before they’re asked, combining financial results with business context, identifying anomalies, and building an interactive report that explains changes and recommends where to focus. The analyst’s time shifts from data assembly to interpretation and strategic guidance — a meaningfully different job.

    The Finance Guardrails Non-Negotiable

    Finance deployments require the strictest data governance of any department. Financial data connected to a ChatGPT workspace must be governed through role-based access controls — not every team member should be able to query every dataset. Audit trails for AI-generated analyses need to exist for regulatory compliance. And outputs used in external communications or regulatory filings must go through human review and sign-off before use.

    Organizations that have had the most success in finance treat the AI as a skilled analyst who still requires a senior reviewer’s sign-off before anything leaves the department. That mental model gets the governance right without stifling the productivity gains.

    Marketing and Content: Where Volume Wins — and Where It Backfires
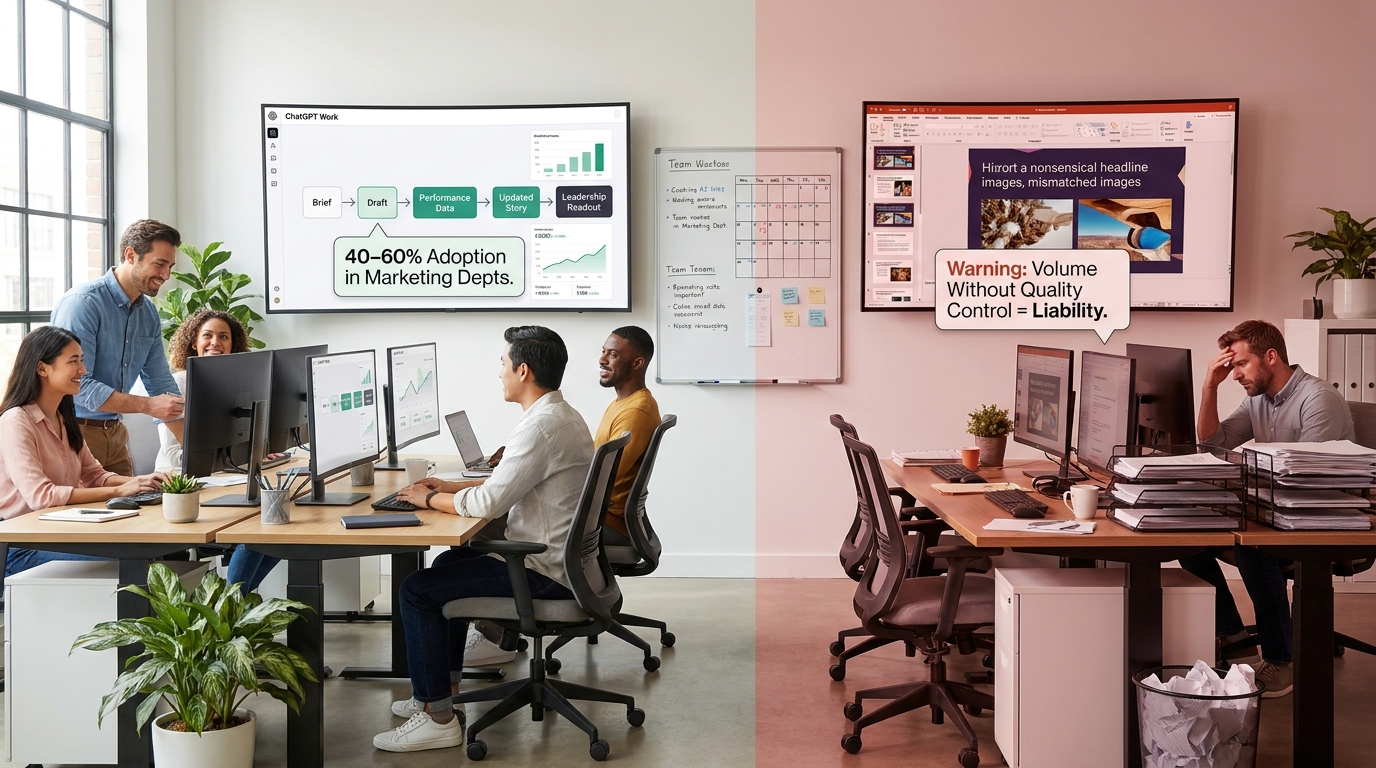
    Marketing team ChatGPT Work campaign workflow showing brief to leadership readout flow with adoption statistics and quality control warning

    Marketing is where ChatGPT deployment is simultaneously most enthusiastic and most prone to failure. Adoption rates in marketing and content departments run 40–60% across organizations with Enterprise access — high relative to HR and finance, but below engineering. The gap reflects a fundamental tension: marketing needs AI to produce more volume, but volume without quality control is a liability, not an asset.

    The High-ROI Marketing Use Cases

    The marketing workflows where ChatGPT consistently delivers strong returns are those that involve structured transformation of existing content or data — not open-ended creation from scratch.

    • Campaign reporting: Turning raw performance data into structured leadership readouts with clear narrative and recommendations. ChatGPT Work can ingest campaign metrics, compare against benchmarks, identify what’s working and what isn’t, and build a presentation-ready analysis. This used to take a skilled analyst four to six hours. It now takes under an hour with human review.
    • Brief-to-draft: Converting a structured creative brief into a first-draft long-form asset — blog post, white paper, case study. The AI does the scaffolding and research assembly; the human refines the voice, adds proprietary insight, and ensures factual accuracy.
    • Multi-channel adaptation: Taking a single piece of approved content and adapting it to five different formats and platforms. This is pure volume work that AI handles efficiently and correctly when the source content is solid.
    • Competitive research summaries: Using ChatGPT’s research mode to monitor competitor messaging, product updates, and market positioning — and synthesizing it into a weekly briefing that marketers actually read.

    Where Volume Without Governance Breaks Down

    The marketing failures in 2026 deployments follow a consistent pattern. A team gets access to ChatGPT Enterprise, starts using it for all content production, ships AI-generated copy without systematic review, and eventually publishes something factually incorrect, tonally off-brand, or legally problematic. The damage isn’t always dramatic — sometimes it’s subtle brand drift, sometimes it’s a compliance issue, sometimes it’s simply content that doesn’t sound like the company.

    The root cause is almost always the same: the team deployed the tool before establishing the review process. They were focused on output volume rather than output quality standards. The lesson isn’t that AI shouldn’t produce marketing content — it’s that every AI-produced piece needs a review step that is explicitly designed for AI-generated material, not repurposed from the editorial review process for human-written content. AI makes different kinds of errors than humans, and the review process needs to check for them specifically.

    Building the Marketing Prompt Library That Holds Up

    The marketing teams with sustained high performance from ChatGPT have one thing in common: a maintained prompt library that is treated as a living document, not a one-time setup. This library contains tested prompts for each major content type, with version history so that when a prompt is refined, the old version doesn’t disappear. It includes brand voice guidelines embedded directly in the system prompts for each Custom GPT. And it has explicit instructions about what the AI should not do — facts to avoid asserting without verification, claims that require legal review, brand positioning statements that require sign-off before publication.

    This kind of prompt library takes two to three weeks to build properly. Organizations that build it before full deployment see dramatically better sustained performance than those who deploy first and iterate under fire.

    Legal, Compliance, and HR: The Governance-First Departments

    Legal, compliance, and HR teams share a characteristic that shapes their ChatGPT deployment: every output carries real-world consequences for real people. A contract clause that’s wrong exposes the company to liability. A benefits policy FAQ that’s misleading creates legal obligations. A job description that uses the wrong language creates discrimination exposure. These stakes mean that governance isn’t a nice-to-have for these departments — it’s the precondition for any deployment at all.

    Legal: Where ChatGPT Earns Its Keep in Document-Heavy Work

    Contract review, NDA drafting, policy summarization, and regulatory research are the legal workflows that ChatGPT handles best. These are tasks where the AI’s ability to process large volumes of text rapidly, identify relevant clauses, flag potential issues, and generate structured summaries provides genuine time savings for legal teams that are perpetually under-resourced relative to their workload.

    The key governance principle for legal is clear and consistent: ChatGPT output is a first draft or a research assist, never a final work product. Every AI-generated contract clause, policy summary, or regulatory analysis must be reviewed and signed off by a qualified legal professional before it is used. This isn’t just a governance policy — it needs to be a technical constraint built into the deployment, making it impossible for AI-generated legal content to leave the system without a documented human review step.

    Organizations that have implemented this properly report that their legal teams are handling significantly higher document volumes without proportional headcount increases. The AI handles the first pass; the lawyer handles judgment, strategy, and client relationships.

    HR: The Use Cases That Scale and the Ones That Create Risk

    HR adoption of ChatGPT runs at the lower end of the department spectrum — typically 15–30% in most organizations — and for understandable reasons. HR work involves sensitive personal data, employment law compliance, and decisions that directly affect people’s livelihoods. But there is a set of HR use cases where ChatGPT delivers clear value with manageable risk.

    Job description drafting is the canonical example. ChatGPT can take a role brief and a set of requirements and generate a structured, inclusive-language job description quickly. HR reviews for compliance and brand voice, then posts. The AI saves the initial drafting time; the human ensures legal and organizational alignment.

    Onboarding material creation, policy FAQ generation, and benefits communication drafting follow the same model — AI handles the templated, document-heavy work, human experts review for accuracy and compliance before distribution.

    Where HR must be careful: using AI in any part of the actual hiring decision process. Resume screening, candidate assessment, or interview evaluation that involves AI without rigorous bias auditing and legal review creates significant legal exposure. The current guidance from employment law specialists is consistent: AI can assist HR with documentation and communication workflows, but should not be in the decisional loop for employment outcomes without explicit, audited safeguards.

    Compliance: AI as a Research and Monitoring Layer

    Compliance teams are finding ChatGPT most useful as a regulatory research and change-monitoring layer. Keeping up with regulatory changes across jurisdictions is a volume problem — there is simply more regulatory output than small compliance teams can read, synthesize, and act on. ChatGPT’s research mode can monitor regulatory feeds, summarize relevant changes, flag potential impacts on specific policies or processes, and generate preliminary impact assessments for human review.

    This is the kind of consistent background work that AI handles well and that frees compliance professionals for the higher-stakes judgment work that actually requires their expertise.

    Operations: The Unsung ROI Engine of ChatGPT Deployment

    Operations is consistently underrepresented in discussions of ChatGPT deployment, which is strange given that operations teams tend to have the highest density of the workflows where AI delivers the clearest ROI: structured, high-volume, data-intensive processes that need consistent execution across distributed teams.

    The Weekly Review Problem — and How ChatGPT Solves It

    Ask any operations leader what they spend most of their meeting preparation time on, and “chasing updates to rebuild the status deck” is a near-universal answer. Before a weekly review, someone needs to pull data from the project management system, the initiative tracker, the planning documents, and recent team messages. They need to reconcile them, identify what’s on track and what’s at risk, and build a deck that makes sense of it all.

    This is precisely the task that ChatGPT Work’s agentic capabilities are designed for. Connected to the relevant systems, it can pull current data, identify risks and blockers, synthesize recent signals, and prepare the review deck — with each owner and their current status already mapped. The operations manager walks into the meeting having reviewed the output rather than having spent hours preparing it.

    Early adopters of this workflow are reporting that operations team members are reclaiming three to five hours per week that were previously consumed by status reporting and deck preparation. That time is being redirected to actual problem-solving — the work that operations leaders are most qualified to do.

    Cross-System Data Synthesis: Where Ops Gets Asymmetric Value

    Operations teams typically work across more systems than any other department — project management tools, ERP systems, logistics platforms, customer success dashboards, HR systems, finance data. The data they need to do their job is fragmented across these systems, and assembling a coherent operational picture manually takes significant time.

    ChatGPT Work connected to these systems can synthesize cross-system data on demand, building operational dashboards that would otherwise require a data analyst and a day of work. This capability is available today for organizations with Enterprise accounts and the right integrations, and it’s delivering outsized ROI for operations teams willing to invest in the integration layer.

    The Governance Architecture That Separates Successes from Failures
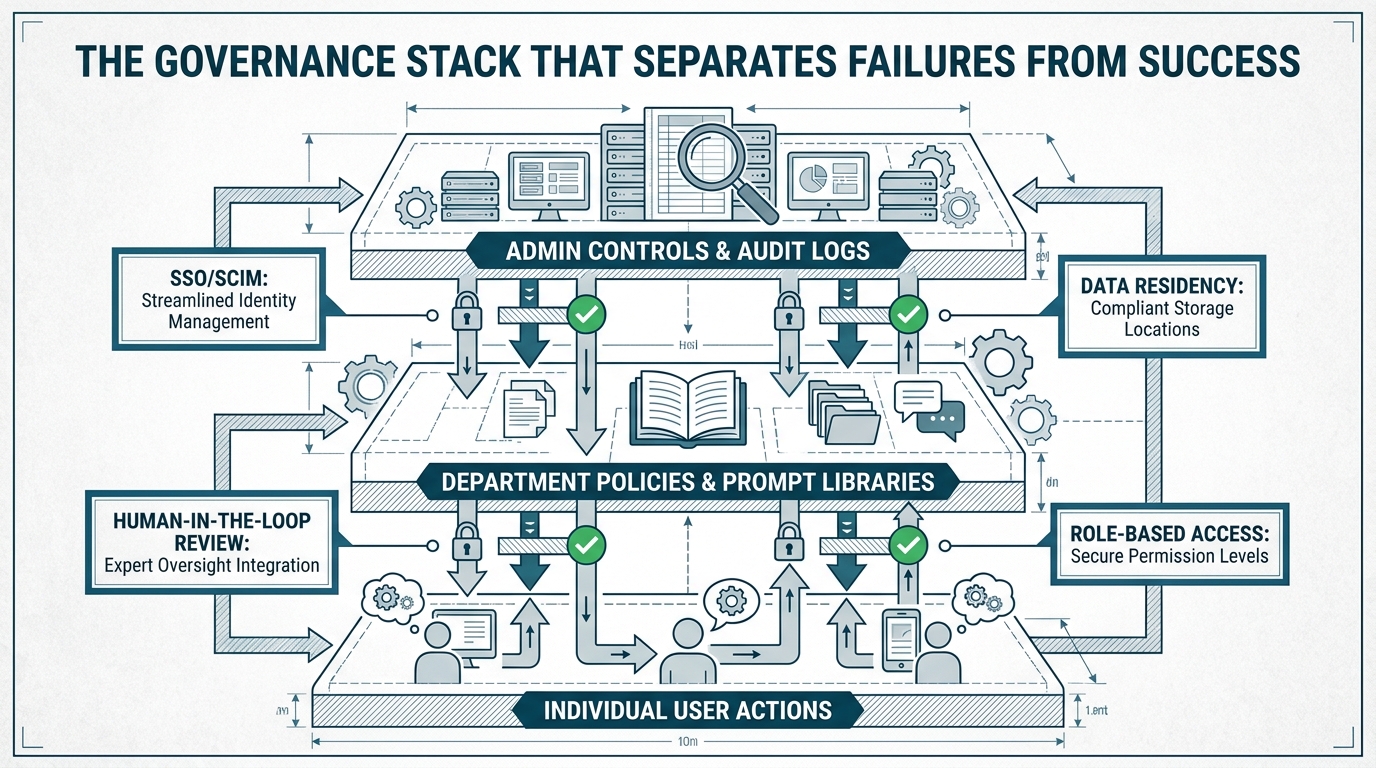
    Enterprise AI governance architecture diagram showing layered admin controls, department policies, and human-in-the-loop review gates

    Every organization that has successfully scaled ChatGPT across departments has one thing in common: they built the governance layer before they needed it, not after something went wrong. Governance is not a compliance checkbox — it’s the technical and organizational infrastructure that allows the tool to be used broadly and confidently rather than cautiously and narrowly.

    The Three-Layer Governance Model

    The governance architecture that works in practice has three layers, each serving a distinct function:

    Layer 1: Admin Controls and Audit Infrastructure. At the enterprise level, IT and security teams control who has access to ChatGPT, which tools and integrations each workspace can use, and what data the system can see. Audit logs capture all agent activity, conversation data, and file access. Compliance API visibility ensures that every action taken by ChatGPT Work on behalf of a user is traceable. This layer is non-negotiable for any organization operating in a regulated industry or managing sensitive customer data.

    Layer 2: Department Policies and Prompt Libraries. Each department operates under its own set of approved use cases, standardized prompts, data access rules, and output review requirements. These are documented, versioned, and maintained by a departmental AI lead or governance owner. The marketing department’s policy is different from the legal department’s — and both are different from the engineering team’s. Trying to govern all departments with a single blanket policy consistently fails because the risk profiles and workflow patterns are too different.

    Layer 3: Individual User Training and Practice Standards. Individual users need to understand not just how to use ChatGPT, but how to use it responsibly in the context of their specific role. This means role-based training (not generic AI literacy training) that covers the approved use cases for their department, the prompt templates they should use, and the review process they need to follow before using AI output externally.

    The Failure Modes That Governance Prevents

    The deployment failures that made the most news in 2025–26 were almost all governance failures rather than technology failures. The pattern is consistent: a team deploys ChatGPT without clear use-case boundaries, an employee uses it for a task it wasn’t designed or approved for, the output goes external without review, and the consequences range from embarrassing to legally problematic.

    Model behavior changes compound this risk. When OpenAI updates its models — and updates happen regularly — prompts that worked reliably on one model version may behave differently on the next. Organizations without version-controlled prompt libraries and systematic output monitoring won’t notice this drift until something goes wrong. Organizations with proper governance will catch it in the review layer before it causes damage.

    Building the AI Working Group: Who Needs to Be in the Room

    Successful governance programs consistently start with a cross-functional AI working group that meets before deployment begins and maintains oversight throughout the rollout. The minimum viable working group includes:

    • IT/Security: For technical controls, data governance, and integration architecture.
    • Legal/Compliance: For acceptable use policies, data privacy compliance, and liability review.
    • HR: For acceptable use communications, training program design, and employment policy alignment.
    • Finance: For cost controls, seat allocation strategy, and ROI measurement.
    • Business unit leads: For use-case prioritization, workflow design, and department-level adoption.

    This group doesn’t need to meet weekly forever. But it needs to exist before rollout, actively during the first 90 days, and on a quarterly basis thereafter to review usage patterns, address emerging issues, and manage model update cycles.

    Building Your Department Prompt Library: The Practical Framework

    A prompt library is not a collection of clever prompts — it’s a governed, versioned system of templates that standardizes how your organization interacts with ChatGPT for specific, defined tasks. Building it correctly is one of the highest-leverage investments you can make in your deployment.

    The Anatomy of a Deployment-Grade Prompt

    A prompt that’s ready for organizational deployment has several components that a casual prompt doesn’t:

    • System context: A clear statement of the AI’s role in this task, the output format it should produce, and the audience it’s writing for. This is usually embedded in the Custom GPT’s system prompt rather than the user prompt.
    • Constraint instructions: Explicit statements of what the AI should NOT do — claims it shouldn’t assert, content it shouldn’t produce without human verification, formatting it should avoid.
    • Output scaffolding: For structured tasks (reports, analyses, communications), a template that the AI populates. This dramatically improves output consistency and review efficiency.
    • Review checklist reference: A pointer to the review process the output should go through before use. This makes the review step a part of the prompt workflow, not an afterthought.

    How to Build the Library Without Spending Six Months on It

    The mistake organizations make is trying to build a comprehensive prompt library from scratch before they’ve actually deployed the tool. They end up with a library built on theoretical use cases that doesn’t reflect how the tool is actually being used.

    The better approach is a two-week sprint after a limited pilot:

    1. Week 1: Run a limited pilot with 20–30 users in one department. Have each user document every prompt they use that produces a useful output. Collect these prompts centrally at the end of the week.
    2. Week 2: A small team reviews collected prompts, identifies the highest-value use cases, refines the top 10–15 prompts using the anatomy framework above, and creates the initial library. Governance owners review and approve.
    3. Ongoing: The library is a living document. A designated maintainer reviews usage analytics monthly, identifies prompts that need refinement (especially after model updates), and adds new approved prompts as use cases expand.

    This approach produces a library that reflects real workflows rather than theoretical ones, takes weeks rather than months, and starts generating value immediately.

    The Custom GPT Layer

    For Enterprise deployments, prompt libraries should be implemented not just as document repositories but as Custom GPTs — configured AI assistants that have the governance constraints built into their system prompts. This means that when a marketing team member opens the “Campaign Report Builder” Custom GPT, they’re automatically working with the approved system context, constraints, and output format — without needing to remember or correctly apply a complex prompt each time.

    This approach dramatically reduces user error, improves output consistency, and makes governance auditable. Every output from the “Legal NDA Reviewer” Custom GPT is traceable to that specific configuration, and changes to the configuration require an approval process.

    Measuring Real ROI: The Metrics That Actually Matter
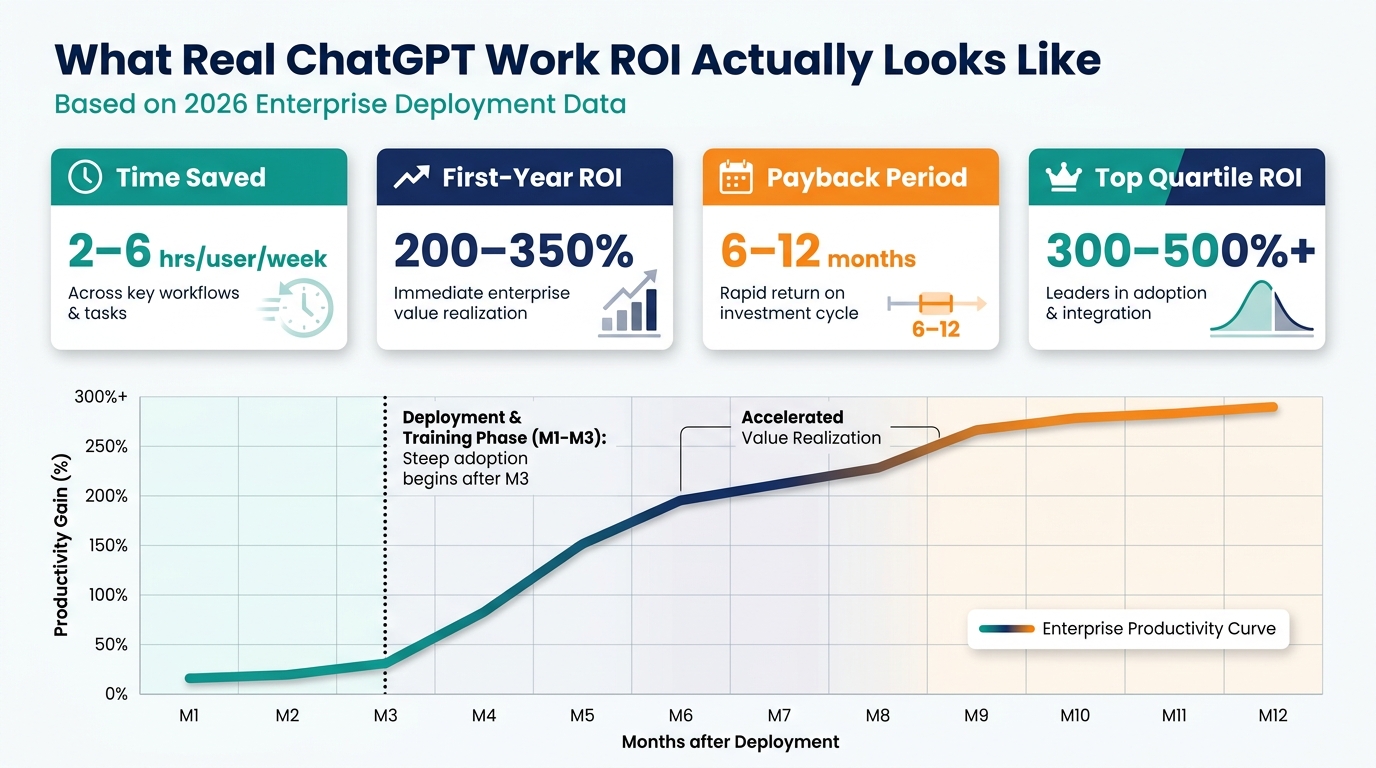
    ChatGPT Work ROI measurement dashboard showing 2–6 hours saved per week, 200–350% first-year ROI, 6–12 month payback, and 300–500%+ top-quartile ROI

    The organizations measuring ChatGPT ROI correctly aren’t looking at message volume, query counts, or user satisfaction surveys. They’re measuring business outcomes — and the numbers from properly governed deployments in 2026 are consistent and credible enough to act on.

    The Core Productivity Numbers

    Across enterprise deployments with strong governance and workflow focus, the consistent reported productivity gain is 2–6 hours saved per knowledge worker per week. That range reflects the difference between assistive use cases (lower end) and fully integrated agentic workflows (higher end). For a team of 50 knowledge workers, even the low end of this range represents 100+ hours per week of recovered capacity — the equivalent of two to three additional full-time employees.

    First-year ROI for well-implemented deployments runs in the 200–350% range, with a payback period of 6–12 months. Top-quartile programs with deep workflow integration and strong adoption are reporting 300–500%+ ROI within the first year. These numbers are consistent across multiple independent enterprise deployments and reflect time savings, quality improvements, and reduced need for certain categories of external vendor work.

    The Metrics Worth Tracking vs. the Ones That Distract

    The metrics that predict successful long-term deployment are behavioral, not volume-based:

    • Weekly active users as a percentage of licensed seats: Below 50% after 60 days of deployment signals an adoption problem. Above 70% suggests the tool is genuinely embedded in workflow. (The OpenAI-reported figure of 83% weekly active users in high-success deployments is a benchmark worth aspiring to.)
    • Workflow completion rate: For agentic use cases, the percentage of initiated workflows that produce a usable output without requiring a restart. Low completion rates indicate prompt quality, integration, or model performance issues.
    • Review escalation rate: The percentage of AI outputs that require significant human revision before use. High escalation rates indicate that prompts, system context, or use-case selection need adjustment — not that the tool doesn’t work.
    • Time-on-task before/after: For defined, measurable workflows (monthly close, contract review, report generation), direct measurement of time taken before and after AI deployment. This is the most defensible ROI metric for internal business cases.

    The 30/60/90 Day Measurement Cadence

    The teams that sustain ROI over time are measuring at three defined checkpoints:

    30 days: Adoption rate, early productivity signals, top user pain points. The goal is to identify and fix friction before it calcifies into habit. If adoption is below 40% at 30 days, there is a training or workflow-fit problem that needs immediate attention.

    60 days: Workflow completion rates, review escalation patterns, and the first pass at time-on-task comparison. This is when you identify which use cases are working well (expand them), which are underperforming (diagnose and adjust), and which prompt library gaps need to be filled.

    90 days: Full ROI calculation, user satisfaction, and recommendation for scale or scope adjustment. The 90-day review should produce a documented business case for the next phase of deployment — whether that means expanding to new departments, moving to Enterprise tier, or building additional Custom GPTs for the use cases that have proven out.

    Why Most Deployments Stall at 30%: The Organizational Dynamics Nobody Talks About

    The technical deployment of ChatGPT is rarely what causes rollouts to underperform. The technology works. The organizational dynamics around it frequently don’t — and they follow patterns that are predictable enough to plan for.

    The Early Adopter Cliff

    Most ChatGPT deployments show a characteristic adoption curve: rapid uptake by the 15–20% of employees who are naturally enthusiastic about new technology, followed by a plateau as the tool fails to penetrate the majority who are waiting to see whether it’s genuinely useful in their specific job. This plateau — often around 30–35% adoption — is the most common failure mode in enterprise AI rollouts.

    Breaking through it requires a different approach than the one that drove early adoption. Early adopters self-served. The majority needs demonstration, not documentation — they need to see a colleague in their specific role doing a specific task faster and better with ChatGPT before they’ll commit to changing their workflow. Peer demonstrations and internal case studies from within the organization are far more effective at this stage than vendor-produced materials or executive mandates.

    The Manager Multiplier Effect

    One of the strongest predictors of departmental ChatGPT adoption is whether the department’s manager uses it visibly and talks about it openly. Teams with actively AI-using managers hit adoption rates 2–3x higher than comparable teams with AI-skeptical or passive managers. This isn’t about mandating use — it’s about the signal that a manager sends by demonstrating the tool in team settings, referencing AI-assisted work in meetings, and creating space for experimentation without fear of judgment.

    Organizations that identify this dynamic early and specifically train managers to be visible AI adopters consistently see stronger rollout performance than those that focus all their enablement energy on individual contributors.

    The “Productivity Theatre” Trap

    A specific failure mode that has become more visible in 2026: teams that adopt ChatGPT enthusiastically but use it in ways that look productive without creating real business value — generating more reports that nobody reads, producing longer documents that contain less useful information, or automating the production of deliverables that shouldn’t exist in the first place.

    This is the “productivity theatre” trap, and it’s surprisingly common. The fix is simple but requires discipline: before deploying AI to a workflow, ask whether the workflow itself is creating genuine value. If the answer is uncertain, the right intervention is workflow redesign, not AI automation of an existing but questionable process.

    The 90-Day Deployment Checklist: From Decision to Measurable ROI

    Everything above distills into a practical sequence of decisions and actions. Here is the checklist that the best-performing ChatGPT work deployments have in common — not as an abstract framework, but as a concrete sequence you can act on.

    Weeks 1–2: Foundation

    • Form the AI working group (IT, Legal, HR, Finance, business leads).
    • Define the specific use case for the pilot — one workflow, one department, 20–50 users.
    • Select and configure the deployment tier (Team for pilots under 50 users, Enterprise for broader rollout).
    • Draft the acceptable use policy for the pilot department.
    • Identify the department AI lead who will own the prompt library and training.

    Weeks 3–6: Pilot and Learn

    • Deploy to pilot users with role-specific training focused on the target workflow.
    • Establish the baseline time-on-task metric for the targeted workflow.
    • Collect prompts and use patterns from pilot users daily.
    • Run a weekly 30-minute retrospective to surface friction and early wins.
    • Document the review process that AI output must go through before external use.

    Weeks 7–8: Governance and Library

    • Build the initial prompt library from pilot learnings (target: 10–15 well-governed prompts).
    • Create the department Custom GPT with governance constraints built into system prompts.
    • Define the 30/60/90 day metrics and assign measurement ownership.
    • Run the first adoption audit and address any users who have not engaged with the tool.

    Weeks 9–12: Scale and Measure

    • Expand to additional use cases within the pilot department.
    • Conduct peer demonstration sessions to drive adoption past the early-adopter plateau.
    • Train department managers to be visible AI users.
    • Conduct the 90-day ROI review and build the business case for the next phase.
    • Present findings to the AI working group and define the next department for rollout.

    This sequence is not theoretical — it’s a distillation of what the organizations reporting 200–350% first-year ROI actually did in their first 90 days. It is notably un-glamorous. There is no “big launch moment,” no all-hands announcement with slick videos, no promise of immediate transformation. There is instead careful problem selection, disciplined governance, persistent measurement, and the organizational patience to build something that actually works before declaring victory.

    What 2026 Has Made Clear: The Deployment Decisions That Define the Outcome

    Eighteen months into widespread ChatGPT Work deployment, the organizational evidence is clear enough to draw some firm conclusions — not about the technology, but about the decisions that determine whether it delivers on its potential.

    The organizations seeing real, sustained returns share a profile: they started narrow and specific rather than broad and aspirational. They built governance before they needed it. They invested in department-level prompt libraries rather than hoping individuals would figure out effective prompting on their own. They measured outcomes rather than activity. And they treated the organizational change management as the hard part — not the technology setup.

    The organizations that are disappointed — sitting on expensive Enterprise licenses with low adoption and unclear ROI — made the opposite choices. They launched broadly without sufficient preparation. They invested in access without investing in enablement. They measured the wrong things and missed the signals that something was going wrong until it was expensive to fix.

    ChatGPT Work is, in 2026, genuinely capable of changing how knowledge work gets done. The engineering team that moves from ticket to PR-ready code without manual coordination is working differently, not just faster. The finance team running a live, always-current operating model is doing a different job than the one that spent three days assembling a monthly close. The operations leader walking into a review with a current, AI-synthesized risk register is having a different conversation than the one who spent hours rebuilding the deck from scratch.

    That kind of change is available. Whether your organization captures it comes down to the deployment decisions you make in the next 90 days — and whether you’re willing to do the unglamorous work of building governance, measuring outcomes, and earning adoption one department at a time.

    Key takeaway: The difference between ChatGPT deployments that deliver 300%+ ROI and those that stall is not the technology. It’s the specificity of the use cases targeted, the quality of the governance architecture, the investment in department-level prompt libraries, and the organizational patience to measure real outcomes rather than activity metrics. Start with one workflow. Govern it properly. Measure the results. Then scale.

  • The New Attention Gatekeeper: How ChatGPT Ads Are Rewiring the Economics of AI Media

    ChatGPT ads replacing traditional web advertising as the new attention gatekeeper in AI media

    For thirty years, the economics of digital media ran on a simple but fragile contract: publishers produced content, search engines sent traffic, and advertisers paid for the eyeballs in between. It worked — until it didn’t. And now, in 2026, a new party has arrived at the table with a fundamentally different offer.

    OpenAI launched ads inside ChatGPT in February 2026, and within six weeks the program had crossed $100 million in annualized revenue. The internal target for the full year sits around $2.4–$2.5 billion. By 2029, OpenAI’s own projections put ad revenue at $25 billion. To put that in context: that would make ChatGPT one of the largest advertising businesses on earth within three years of its first commercial impression.

    But the numbers alone are not the story. What matters is where that money comes from, who loses it, and what kind of media economy takes shape on the other side of this transition. This is not simply a new ad channel layered on top of existing ones. ChatGPT advertising represents a structural reconfiguration of how attention is captured, how intent is read, and how value flows between users, brands, and content creators. It is, in a very real sense, the first fully AI-native ad market — and it is being built in real time.

    This piece digs into what is actually happening: how the format works, what the early numbers mean, what it does to publishers, and what media businesses need to understand right now before the architecture solidifies around them.

    From Subscription to Hybrid: OpenAI’s Monetization Pivot

    OpenAI ChatGPT three-tier monetization model showing ad-supported free tier and ad-free premium subscriptions

    When OpenAI first launched ChatGPT, the business model was purely subscription-driven. Pay a monthly fee, get access to more powerful models, better speed, priority during peak hours. It was clean, simple, and easy to communicate — and for a product in its early growth phase, it made sense. Subscriptions build a direct relationship with users and generate predictable revenue without the complexity of an ad stack.

    But subscriptions have a ceiling. The free tier of ChatGPT has hundreds of millions of users. The paid conversion rate, as with most freemium products, captures only a fraction of that base. To build the kind of revenue engine that can justify the compute costs of running frontier AI models at scale — and fund the next generation of model development — OpenAI needed a second lever. Advertising is that lever.

    The Three-Tier Architecture

    OpenAI has structured its monetization around three distinct tiers, each with a different value exchange. The Free tier is ad-supported — users who do not pay see sponsored placements embedded in their conversations. The ChatGPT Go tier, a low-cost entry-level subscription, also carries ads. Above those sits the premium stack: Plus, Pro, Business, Enterprise, and Education plans, all of which remain entirely ad-free.

    This is a deliberate design. The ad-free premium tier is not just a product feature — it is a statement about the relationship between payment and privacy. It positions OpenAI as a company that respects its paying users enough not to monetize their conversations, while also giving the free tier a genuine reason to exist for the company financially. It mirrors, structurally, what Spotify and YouTube have both built: the free user funds the product through ads, and the premium user buys their way out.

    Why This Pivot Is Strategically Necessary

    Running large language models is extraordinarily expensive. Inference costs — the compute required to generate each response — scale directly with usage. As ChatGPT’s user base has grown into the hundreds of millions, the cost per user on the free tier has remained a real drain. Advertising changes that equation entirely: the free user becomes a revenue source rather than a cost center.

    There is also a competitive dimension. Google, Meta, and Amazon are all building AI assistants and AI-native search experiences. If those products are free and ad-supported, ChatGPT cannot remain the only major AI assistant charging everyone or serving no one on the free side. The ad-supported tier is partly a competitive response to the reality that the AI assistant market will largely be free at the point of use — with attention as the currency.

    OpenAI’s monetization pivot is not a departure from its original model. It is a maturation of it — the recognition that a company building at this scale, in this market, needs multiple revenue streams to be durable.

    What the ChatGPT Ad Format Actually Looks Like — And Why It’s Different

    Understanding the ChatGPT ad format requires letting go of almost every assumption built up over two decades of web advertising. There are no banner slots. No pre-roll video. No retargeted display ads following users around the open web. The format is genuinely new — and its newness is both its strength and its current limitation.

    Sponsored Cards, Clearly Labeled

    Ads appear as visually distinct, tinted boxes — commonly called “sponsored cards” — positioned at the bottom of a ChatGPT response or inline within the conversational thread. Each card carries a visible “Sponsored” badge, a brand name, a headline, a short description, and a call-to-action link or button. The card is visually separated from the organic AI-generated answer above it. Users cannot mistake the ad for part of the model’s response.

    OpenAI has been emphatic on one design principle: the answer itself is never influenced by the ad. The model generates its response independently. The sponsored card is a separate layer, appended after the fact based on the conversation’s detected intent. This separation is not just a UX choice — it is a trust promise, and OpenAI is betting that maintaining it strictly is what allows the format to survive long-term.

    Why the Placement Matters More Than It Looks

    In traditional search advertising, a sponsored result sits at the top of a results page, above organic listings. Users have to actively scroll past it to reach organic content. In ChatGPT, the opposite is true: the organic AI response comes first, and the sponsored card arrives after. The user has already received their answer before they see any commercial message.

    This is a significant inversion of the traditional attention model. The user is not being asked to notice the ad on their way to getting information — they have already gotten the information, and the ad appears as a potentially relevant next step. The implicit message is: here’s what you need to know — and here’s a product or service that might help you act on it. That is a fundamentally different psychological context than a banner ad, a pre-roll video, or even a top-of-page search result.

    Dismissibility and Feedback

    Users can dismiss ads and provide feedback, signaling that a placement was irrelevant or unwanted. OpenAI uses these signals to refine targeting. This feedback loop is important — it distinguishes the ChatGPT ad system from static ad formats and builds in a mechanism for quality control that benefits advertisers (irrelevant ads waste budget) and users (bad ads get filtered) simultaneously.

    The Intent Signal Advantage — Contextual Targeting Without Cookies

    Comparison of ChatGPT contextual ad targeting versus traditional cookie-based ad tracking

    The most commercially interesting thing about ChatGPT ads is not the format — it is the targeting methodology. And the most important thing to understand about that methodology is what it does not use.

    ChatGPT does not rely on third-party cookies. It does not build cross-site behavioral profiles. It does not use retargeting pixels or off-site identifiers of the kind that power Google Display Network or Meta’s audience targeting. In a post-cookie digital advertising landscape — where the industry has spent five years scrambling for alternatives — ChatGPT has arrived with a model that never needed cookies to begin with.

    How Conversational Intent Targeting Works

    The ChatGPT targeting system operates on what might be called real-time conversational intent. When a user asks “What are the best standing desks for a home office under $500?” — the model detects that intent in the conversation and matches it to relevant advertiser categories. A furniture brand, an ergonomics company, or a home office retailer might be surfaced as a sponsored card below the response.

    This is contextual advertising, but at a depth that traditional contextual systems — which read page-level metadata or article topics — have never achieved. The system is reading the actual expressed need of the user in real time, at the level of a specific sentence, not a broad topic category. The intent signal is extraordinarily precise because the user has, in effect, stated their intent explicitly in natural language.

    The Privacy Trade-Off That Still Exists

    OpenAI’s model avoids cookies and cross-site tracking, but it creates a different kind of data relationship: one where the ad system has access to the full conversational context in which a user is seeking information. That context can be highly personal. Users ask ChatGPT about medical symptoms, financial situations, relationship problems, and career crises — exactly the kinds of sensitive topics that privacy advocates have long argued should be off-limits for commercial targeting.

    OpenAI says conversations are not shared with advertisers and that ads are matched to the detected commercial intent of a conversation, not to its sensitive content. The system is designed to recognize when a conversation involves sensitive topics — health, politics, relationships — and exclude those threads from ad eligibility. Whether that exclusion holds at scale, and how regulators in the EU and elsewhere will evaluate it, remains an open and consequential question.

    The Contextual Advertising Renaissance

    ChatGPT’s targeting model is, in a sense, the fullest realization of what contextual advertising always promised but never quite delivered. Traditional contextual systems matched ads to page topics. ChatGPT matches ads to real-time user intent expressed in natural language. The gap between those two things is the difference between knowing someone is reading a travel magazine and knowing they just asked for a hotel recommendation in Barcelona for next month.

    For advertisers who have been building toward a privacy-safe, cookie-free future, that distinction is commercially significant. It points to a targeting model that does not require surveillance infrastructure to deliver relevance — and that may, in fact, deliver better relevance than cookie-based systems ever did, precisely because the user has voluntarily expressed their need in their own words.

    The Numbers So Far: $100M ARR, Softening CPMs, and the Road to $25B

    ChatGPT advertising revenue trajectory infographic showing $100M ARR at launch to $25B projected by 2029

    The revenue numbers attached to ChatGPT’s ad rollout have drawn attention partly because of their scale and partly because of how quickly they arrived. But reading the numbers carefully reveals a more nuanced picture than the headline figures suggest.

    The $100M ARR Milestone in Context

    OpenAI confirmed in March 2026 that its advertising program had crossed $100 million in annualized revenue — within roughly six weeks of the formal ad launch in February. That figure was reached while fewer than 20% of eligible Free and Go users in the U.S. were seeing ads daily. It was, in other words, a partial rollout number, not a full-deployment run rate.

    Investor projections published in April put the full-year ad revenue figure closer to $2.4–$2.5 billion, assuming continued rollout and scaling. The internal long-range forecast, widely reported in industry sources, targets $25 billion in ad revenue by 2029. If achieved, that would place OpenAI’s ad business in a similar tier to major publisher and platform conglomerates — above the entire podcast advertising market and larger than many broadcast television networks.

    CPM Compression and Pricing Reality

    At launch, ChatGPT ads carried CPMs in the range of $60 — positioning the product as premium inventory with a price point above most programmatic display and competitive with premium publisher direct deals. Within approximately nine to ten weeks, as inventory scaled and performance data accumulated, CPMs fell to around $25. CPC bidding, added alongside the CPM model, has been clustering at $3–$5 per click for early advertisers.

    This CPM compression is entirely normal for a new ad format finding its market. Google’s search CPCs were trivial in their early years. Facebook’s CPMs were a fraction of their current level during the social network’s initial commercial buildout. The compression reflects inventory expanding faster than advertiser demand at launch — a supply-demand dynamic that typically stabilizes as advertisers gain confidence in performance data and increase their allocations.

    What Performance Data Actually Shows

    Official, published performance benchmarks from OpenAI remain limited. What exists in the market is a combination of early advertiser reports, industry analyst estimates, and directional data points. The emerging picture suggests:

    • High-intent verticals are outperforming. B2B software, financial services, and high-consideration consumer categories — where users are explicitly researching before purchasing — are showing above-average conversion rates relative to display and social formats. The conversational context creates a natural alignment between ad appearance and purchase intent.
    • Click-through rates are variable. CTRs across early campaigns vary significantly by category and creative approach, and lag Google Search’s click-through rates at comparable price points. The format is still new enough that users have not yet established a learned behavior around clicking ChatGPT sponsored cards.
    • ROI is strongest for considered purchases. Categories where users spend significant time researching — home office equipment, software tools, insurance, travel — see stronger ROI signals than impulse-purchase categories, because the conversational context captures mid-to-late funnel intent naturally.

    The data picture will sharpen considerably over the next two quarters as OpenAI publishes more measurement tools and advertisers accumulate enough campaign history to draw reliable conclusions.

    The Zero-Click Trap: What ChatGPT Ads Mean for Publishers

    Publishers losing traffic to AI zero-click search as ChatGPT intercepts user queries before they reach websites

    For digital media publishers, the arrival of ChatGPT ads is not a separate event from the zero-click crisis — it is its acceleration. Understanding that connection requires stepping back from the ad product itself and looking at what ChatGPT’s growth is doing to the underlying traffic ecosystem.

    The Zero-Click Reality

    Zero-click behavior — where users receive an answer from an AI assistant or search overview without clicking through to any external website — now accounts for approximately 60% of searches. That figure, cited consistently across industry research in 2026, represents a structural drain on the referral traffic that has underpinned digital publishing economics for two decades.

    When a user asks ChatGPT “What are the side effects of metformin?” and receives a comprehensive, accurate answer, they have no reason to click through to a WebMD article or a pharmacy blog. The information they needed was delivered inside the conversation. The publisher that wrote the underlying content gets nothing — no pageview, no ad impression, no referral relationship.

    For publishers dependent on search-driven traffic to sell programmatic display advertising, this is not a headwind. It is a structural revenue removal. Multiple industry sources report double-digit declines in referral traffic for content categories most vulnerable to AI summarization — health, finance, how-to guides, product reviews, and news explainers.

    The Compounding Effect of ChatGPT Ads

    ChatGPT’s ad rollout adds a particularly sharp edge to this dynamic. Previously, the zero-click problem was about traffic loss — users staying inside the AI and not clicking out. Now, ChatGPT is monetizing that captured attention through its own ad system, rather than leaving it as a cost center.

    This creates a compounding effect for publishers. Traffic declines cut into their programmatic revenue. And now, the attention that would have generated that revenue is being actively monetized by the AI platform that captured it — with ad dollars that might otherwise have gone to publisher inventory. The zero-click era is not just a traffic problem anymore. It is a competition for the same ad budgets, fought on terrain that publishers do not control.

    Licensing as a Partial Lifeline

    Some publishers have responded by negotiating content licensing deals with OpenAI and other AI platforms. Under these arrangements, publishers license their archives and ongoing content production to AI companies in exchange for direct payments. Early deals have been reported across news organizations, academic publishers, and magazine groups.

    These deals are real revenue, but they are not a replacement for what is being lost. Licensing payments are typically one-time or annual flat fees, not usage-based revenue that scales with how frequently the content is used inside AI conversations. They also do not restore the audience relationship — the direct connection between publisher and reader — that referral traffic created. A publisher that licenses its content to ChatGPT has been paid for its archive, but has not necessarily secured its future audience.

    Publishers That Are Adapting

    The publishers navigating this transition most effectively are those treating AI-mediated discovery not as an enemy but as a new distribution channel with its own logic. That means optimizing content for AI citation — the equivalent of SEO for an answer-engine world — by producing highly structured, authoritative, cite-worthy content that AI systems consistently surface in their responses. It also means building direct audience relationships through newsletters, events, communities, and subscription products that do not depend on search referral to exist.

    The publishers that are struggling are those that built their entire model on high-volume, search-optimized content designed to capture programmatic display impressions. That model is not just facing pressure — it is facing a structural endpoint.

    How the Ad Buying Experience Works — Self-Serve Manager, CPC, and Conversion Tracking

    For advertisers considering ChatGPT as a channel, the practical question is: how does the buying experience actually work? OpenAI has moved quickly from a closed, high-minimum pilot to a self-serve infrastructure — and the platform’s capabilities have matured significantly in just a few months.

    From Closed Pilot to Open Self-Serve

    The initial ChatGPT ads launch required a minimum spend of $50,000 and was limited to a small cohort of managed advertisers working directly with OpenAI teams. That minimum was subsequently removed as the self-serve Ads Manager moved into beta. The platform is now accessible to U.S. advertisers without a managed account requirement, with standard credit-card billing and budget controls similar to a simplified version of Google Ads or Meta Ads Manager.

    The self-serve interface allows advertisers to set budgets, choose between CPM and CPC bidding, define campaign objectives, upload creative assets, and monitor performance through a dashboard. The experience is deliberately simplified compared to the mature complexity of Google or Meta’s advertising platforms — reflecting both the early stage of the product and OpenAI’s apparent strategy of making the entry threshold as low as possible during the growth phase.

    Targeting Controls and Campaign Structure

    Targeting in the ChatGPT Ads Manager is, by design, limited. Advertisers cannot target by demographic, geographic detail below national level (initially), or interest category in the behavioral advertising sense. What they can do is define their campaign’s contextual intent categories — essentially telling the system what types of conversations should trigger their ads.

    This is a meaningful difference from Google’s keyword bidding model, where advertisers bid on specific terms. In ChatGPT, the system interprets conversational intent and matches it to advertiser categories, with OpenAI’s model doing the semantic matching work rather than the advertiser providing explicit keywords. For advertisers accustomed to granular keyword control, this requires a different mental model — trusting the AI to make the relevance match rather than specifying it themselves.

    Measurement: Pixel, Conversions API, and Aggregated Insights

    OpenAI has added two measurement mechanisms: a pixel-based tracking option for post-click events (purchases, sign-ups, leads) and a Conversions API for server-side attribution that is more durable in a privacy-constrained environment. Both tools allow advertisers to measure outcomes beyond the click — understanding whether the traffic from ChatGPT ads is converting into actual business results.

    The Conversions API approach, in particular, signals OpenAI’s awareness that modern performance advertising needs to connect impression and click data to downstream outcomes. Advertisers spending on any channel in 2026 want to see cost-per-acquisition data, not just click-through rates. Building that measurement infrastructure early, before advertiser expectations are set, is strategically smart — it positions ChatGPT ads as a performance channel, not just an awareness one.

    Performance reporting currently offers aggregated insights rather than individual-level data, consistent with the platform’s privacy positioning. This creates some measurement friction for advertisers accustomed to more granular reporting, but aligns with regulatory trends pushing all major ad platforms toward privacy-safe measurement approaches regardless.

    User Trust and the Privacy Paradox of Conversational Targeting

    No analysis of ChatGPT advertising would be complete without confronting the deepest tension in the model: the fact that the targeting system that makes it valuable is also the targeting system that makes it uniquely sensitive.

    Why Conversational Data Is Different

    Traditional web advertising targets users based on what they have browsed, clicked, searched, and purchased. That data is behavioral — reconstructed from digital footprints across multiple platforms and sessions. It tells advertisers about what users have done.

    Conversational data in ChatGPT is different in kind, not just degree. Users are not leaving behavioral traces — they are actively disclosing their needs, concerns, and intentions in natural language. The same session might contain a question about a medical symptom, a question about family finances, a question about a career change, and a question about a vacation destination. The AI system that powers the ad matching can theoretically read all of it.

    OpenAI has stated explicitly that conversations are not shared with advertisers and that sensitive topics are excluded from ad eligibility. But “excluded from ad eligibility” does not mean “not processed by the system” — the detection of sensitive content requires the system to read the content. The question of whether that processing constitutes a privacy risk is not a theoretical one. It is the question that regulators in Europe, the United Kingdom, and several U.S. states are actively examining.

    The Trust Cost of Getting It Wrong

    ChatGPT’s value as a product rests entirely on user willingness to share genuine needs and questions. The moment users begin self-censoring their queries because they fear commercial targeting — or worse, begin to feel that the AI’s responses are colored by commercial considerations — the product’s core utility degrades.

    OpenAI’s strict design principle of keeping ad content visually and algorithmically separated from model responses is a recognition of this risk. But design principles are not the same as technical guarantees, and they are not the same as regulatory compliance. The long-term sustainability of the ChatGPT ads model depends on OpenAI maintaining user trust at a depth that no previous advertising platform has ever had to manage, because no previous advertising platform has ever had access to users’ genuine, unfiltered expressed needs in real time.

    What Advertisers Need to Think About

    For advertisers, the privacy question is not just an ethical consideration — it is a brand risk management one. Showing up in sensitive conversational contexts, even inadvertently, creates reputational exposure that does not exist in traditional search or display advertising. A financial services brand whose ad appears after a user has been discussing debt anxiety, or a pharmaceutical brand appearing after a mental health query, faces a context problem that can damage consumer relationships in ways that a misplaced banner ad never could.

    The early best practice emerging from campaign managers is to define clear exclusion contexts — categories of conversations where the brand should never appear — and to treat the contextual definition of ChatGPT campaigns with the same care given to brand safety settings on programmatic platforms. The tools for doing this precisely are still being built. Advertisers who assume the defaults are sufficient may find out the hard way that they are not.

    Where ChatGPT Ads Fit in the Media Mix vs. Google, Meta, and Retail Media

    Media mix comparison chart showing ChatGPT conversational ads versus Google Search, Meta Social, and Amazon Retail Media in 2026

    ChatGPT ads will not replace Google or Meta advertising in 2026. They probably will not in 2027 either. But that framing misses the more important question: what does ChatGPT actually do well, and where does it belong in a well-constructed media mix?

    Google Search: Intent at Scale vs. Intent at Depth

    Google Search advertising remains the largest and most mature performance channel in digital advertising, with annual revenue comfortably above $200 billion. Its strength is scale: billions of queries per day, across virtually every category, with decades of auction optimization and performance data behind every bid.

    ChatGPT’s advantage is not scale — not yet — but intent depth. A Google search query is typically a few words: “standing desk under 500.” A ChatGPT query is a conversation: “I’ve been working from home for three years and my back is killing me. I’m thinking about getting a standing desk. What should I look for, and are there good options under $500?” The latter contains dramatically more context about the user’s situation, their decision stage, their price sensitivity, and their motivation. That context is commercially valuable in ways that keyword matching cannot replicate.

    For advertisers, this suggests ChatGPT is not a replacement for Google Search but a complement — potentially most valuable for capturing the highest-consideration, most researched purchase decisions where users are self-educating through extended conversations before buying.

    Meta and Social: Audience vs. Intent

    Meta’s advertising model is built on audience targeting: detailed demographic and interest-based segments constructed from behavioral data across Facebook and Instagram. It excels at discovery — surfacing products to users who have not yet expressed a purchase intent but match a profile associated with likely interest.

    ChatGPT’s model is the opposite: it captures declared intent from users who are actively seeking information. This makes the two systems genuinely complementary for brands that think in terms of the full funnel. Meta discovers potential customers. ChatGPT captures the moment they are actively researching. Google Search captures the moment they are ready to buy. The three channels serve three distinct stages of the consideration journey.

    Retail Media: The Closest Structural Parallel

    Of all the existing advertising categories, retail media — where Amazon, Walmart, and others sell ad placements based on purchasing data and shopping intent — is probably the closest structural parallel to ChatGPT ads. Both are built on high-intent contexts: a user browsing Amazon is likely to buy; a user asking ChatGPT for a product recommendation is also in a decision mode. Both operate on contextual relevance rather than demographic inference.

    The key difference is that retail media is tied to a transaction environment: the ad appears alongside a product that can be purchased in the same session. ChatGPT’s ad environment is pre-transactional — the user is in research mode, and clicking a sponsored card moves them toward an external site where the purchase will happen. That adds a conversion step that retail media does not have, which partly explains why early ChatGPT CPCs are running at a discount to Amazon’s sponsored product rates.

    The Portfolio Approach

    For most advertisers in 2026, ChatGPT ads make most sense as a test-and-learn allocation rather than a primary channel. Given the early stage of measurement infrastructure, the limited historical performance data, and the ongoing evolution of the ad format, allocating 5–15% of a performance budget to ChatGPT while maintaining primary spend on proven channels is a reasonable posture. The goal is to build performance benchmarks and audience insights now, before the platform scales and CPMs rise as competition for inventory intensifies.

    What AI Media Businesses Must Do Right Now to Survive the Shift

    The ChatGPT advertising era does not present a single threat that can be responded to with a single countermeasure. It is a structural reorganization of how attention is captured and monetized online — and it demands a structural response from every business that operates in the media and content economy.

    Audit Your Traffic Dependency

    The first step is honest measurement: what percentage of your audience, your pageviews, and your advertising revenue depends on search referral traffic? For many digital media businesses, that number is uncomfortably high — in some cases above 60 or 70% of total traffic. If those referrals are being eroded by zero-click AI behavior, the financial exposure is immediate and concrete.

    This audit is not about generating alarm — it is about creating a clear picture of which parts of the business are structurally vulnerable and which are not. A newsletter-driven media business with strong subscriber retention is largely insulated from search referral decline. A programmatic display business dependent on high-volume, search-optimized page views is not. Knowing which situation you are in is the prerequisite for every strategic decision that follows.

    Build for AI Citation, Not Just SEO

    Search engine optimization and AI citation optimization are related disciplines, but they are not the same. Traditional SEO targets ranking algorithms based on links, authority, and keyword relevance. AI citation optimization is about producing content that AI systems consider authoritative enough to surface in their responses — and that users trust enough to follow the citation link when it is provided.

    The practical implications differ: AI systems favor content that is highly structured, factually dense, clearly attributed, and demonstrably expert. The listicle-and-keyword-stuffing approach that worked for search traffic optimization is actively penalized by the kinds of AI systems now mediating information access. Content strategies built for AI citation need to invest in genuine subject matter expertise, primary research, and authoritative sourcing — which is, coincidentally, exactly what builds long-term reader trust as well.

    Monetize the Direct Relationship

    Every media business needs to be building revenue streams that do not depend on third-party platforms as intermediaries. Subscription products, premium newsletters, events, memberships, branded content, and community offerings all create direct relationships that platform algorithm changes — whether from Google or OpenAI — cannot disrupt.

    The businesses that will navigate the ChatGPT ads era most successfully are not those that find a way to capture more AI-driven traffic. They are those that build audiences loyal enough to seek them out directly, independent of whatever discovery mechanism is currently dominant. That has always been the durable media business model. It is simply more urgently necessary now than it has been in two decades.

    Engage the Licensing Conversation Proactively

    If your content is being used to train AI systems or generate AI responses — which, for most substantive publishers, it is — the licensing question deserves proactive attention rather than reactive litigation. Early licensing deals with AI platforms have set precedents, both for what is possible and for what is being left on the table.

    The publishers best positioned to negotiate favorable terms are those with demonstrably unique, high-quality content that AI systems need and cannot replicate: original reporting, proprietary data, specialist expert voices, and primary research. Generic content that can be freely replicated by AI has minimal licensing value. Genuinely differentiated content has real bargaining power — but only if that bargaining power is exercised before the negotiating window closes.

    Experiment on the New Channel

    For media businesses that sell advertising to clients, ChatGPT’s ad platform is a new inventory source that deserves exploration — not blind enthusiasm, but genuine test-and-learn investment. Understanding how audiences that come from ChatGPT conversational ads behave, how they convert, and how they compare to audiences from other channels is commercially valuable information. Building that knowledge now, when the platform is still early and CPMs are relatively low, is better than trying to catch up when the market has matured and competition has driven prices up.

    Conclusion: The New Rules of Attention in an AI-Mediated World

    The ChatGPT advertising era is not arriving slowly. It arrived in February 2026 with $100 million in annualized revenue and a self-serve ad platform. It is scaling toward a projected $2.5 billion by year’s end and a $25 billion target within three years. And it is doing so while simultaneously reshaping the traffic, attention, and monetization economics that have sustained digital media for a generation.

    The structural shift this represents is real, and it is worth stating clearly: we are moving from an open-web attention economy — where value flowed through search engines, clicks, pageviews, and display impressions — to an AI-mediated attention economy, where value increasingly flows through conversations, contextual responses, and sponsored placements inside closed AI environments. That transition does not happen overnight, but its direction is not in question.

    What is in question is who captures the value on the other side of it. OpenAI is building the infrastructure to capture it at the platform layer. Advertisers who experiment now will build the institutional knowledge to use that infrastructure effectively. Publishers and media businesses that adapt their models — toward direct audience relationships, AI-citation-optimized content, and diversified revenue — will find sustainable footing. Those that do not will find that the audience they built on search-referral sand has been washed away by a tide they could see coming.

    The rules of the new attention economy are still being written. The ChatGPT ads launch is the opening chapter — not the whole story. But the chapter is already defining the terms. The businesses that read it carefully now are the ones that will have a voice in how the rest gets written.

    Key Takeaways

    • ChatGPT ads crossed $100M ARR within six weeks and are targeting $2.5B by end of 2026 — this is a real revenue program, not an experiment.
    • The contextual, cookie-free targeting model is genuinely novel — and genuinely valuable for high-intent, considered-purchase advertising categories.
    • Zero-click behavior at approximately 60% of searches is actively eroding publisher referral traffic. ChatGPT’s ad monetization of captured attention compounds that damage.
    • CPMs fell from $60 to roughly $25 within nine weeks — typical for a new format finding its market. Now is the low-cost window for advertisers to build performance benchmarks.
    • The self-serve Ads Manager with CPC bidding and Conversions API signals a performance-channel ambition, not just a branding play.
    • Privacy and user trust are the existential risks to the model. OpenAI’s ability to maintain the integrity of its answer quality — independent of ad influence — will determine long-term viability.
    • Media businesses need three parallel strategies: audit traffic vulnerability, build for AI citation, and monetize direct audience relationships.
  • Where Agentic Ends and Deterministic Begins: An Operator’s Decision Map for 2026

    Where Agentic Ends and Deterministic Begins: An Operator’s Decision Map for 2026

    Split-screen diagram showing deterministic vs agentic workflow pipelines with an operator decision boundary in the center

    The question almost every operations team is wrestling with right now is not whether to use agentic AI. That debate is over. The real question — the one with actual money and operational risk attached to it — is where agentic AI stops and deterministic systems take back over.

    Most guidance on this topic falls into two camps: vendor marketing that wants everything to be agentic, and risk-averse IT governance docs that want nothing to be agentic. Neither is useful to an operator trying to run a production system in 2026.

    This guide is written from the operator’s perspective — the person or team responsible for making decisions about system architecture, process design, and live workflow reliability. It gives you a concrete decision map: which processes belong in the agentic layer, which belong in a deterministic layer, what lives at the boundary between them, how the handoffs fail, and how you measure the whole thing once it’s running.

    Across the material covered here, one finding from 2026 enterprise survey data frames the stakes clearly: roughly 79% of enterprises have adopted agentic AI in some form, but only about 11% are running agents in true production at scale. The gap between those two numbers is not a technology gap. It is an operator gap — the absence of clear frameworks for deciding what the mix should be and how to manage it safely.
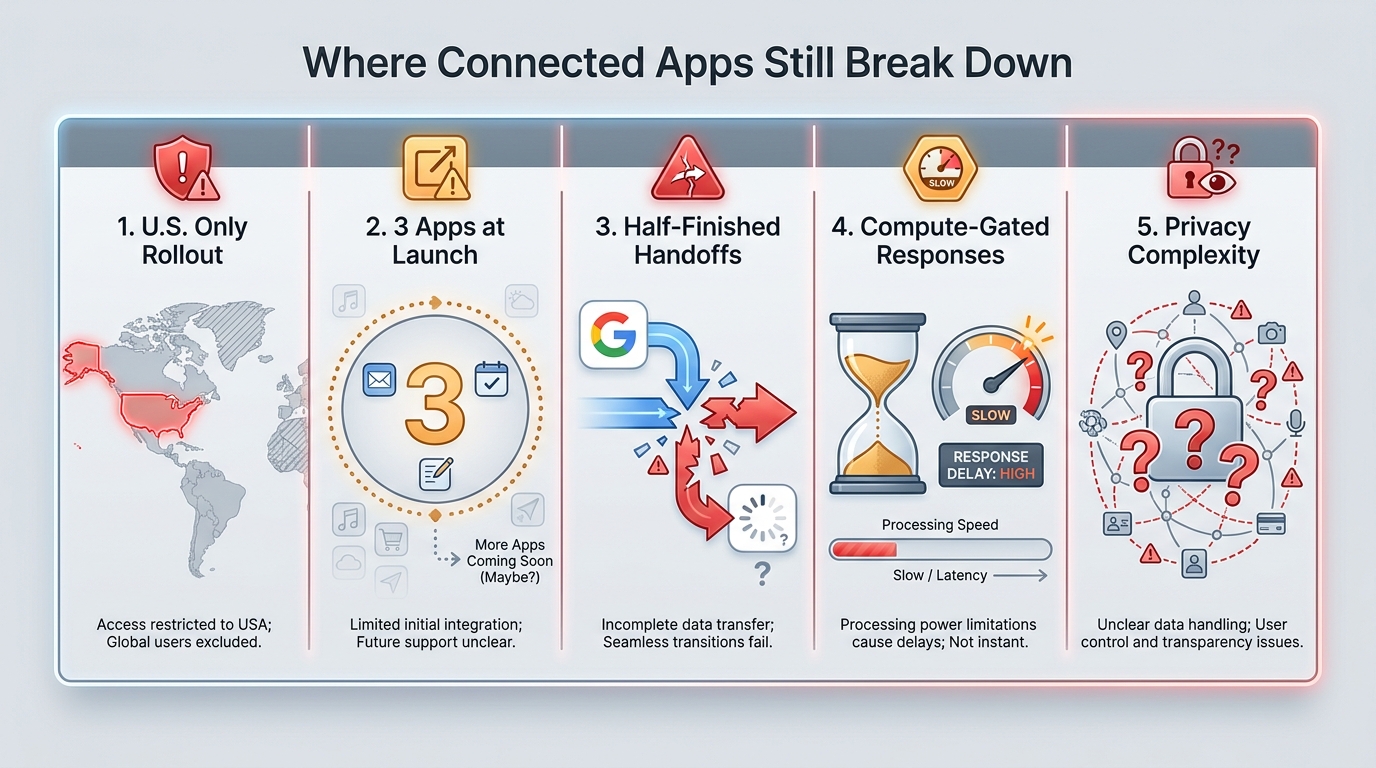
    This is that framework.

    Two Modes, Precisely Defined

    Before you can make a good decision about the mix, you need precise definitions. The terms “agentic” and “deterministic” get used loosely, and the looseness is expensive when you’re designing live systems.

    What deterministic actually means in a workflow context

    A deterministic system produces the same output every time it receives the same input, following a pre-specified execution path. The logic is fully enumerated before the system runs. Given input A, the system executes steps 1, 2, and 3, then produces output B — without variation, without interpretation, and without consulting any external reasoning process to decide which step comes next.

    Deterministic systems include: traditional business process management (BPM) engines, robotic process automation (RPA) bots executing scripted workflows, rule-based fraud detection systems, hardcoded approval routing, compliance policy engines, and any conditional logic expressed as explicit decision trees. The key signature is that a human being, in advance, specified what happens in every case the system will encounter.

    This is the system’s strength, not its limitation. Deterministic logic is auditable, reproducible, debuggable, and legally defensible. When a compliance auditor asks why a payment was blocked, the system can show them the exact rule that fired. That is not something a probabilistic model can reliably provide.

    What agentic actually means in a workflow context

    An agentic AI system pursues a stated goal by selecting its own actions at runtime. The execution path is not pre-specified — the agent reasons about the current state of the world, decides what to do next, executes a tool or takes an action, observes the result, and iterates. The same goal, given to the agent twice with slightly different context, may produce a different action sequence.

    This is the system’s strength. It handles situations that weren’t anticipated when the workflow was designed. It interprets ambiguous inputs. It adapts when the environment changes mid-task. It can coordinate across multiple tools or systems without a human scripting each step of that coordination. The cost is that it introduces probabilistic behavior — and probabilistic behavior is not compatible with every step in every workflow.

    The spectrum between them

    Most real systems are not purely one or the other. They exist on a spectrum from “fully scripted” to “fully autonomous.” The operator’s job is to decide, for each step in each process, where on that spectrum the step should sit — and then engineer the boundaries between steps accordingly.

    In practice, the most resilient 2026 architectures treat the spectrum as a deliberate design choice, not a default. You are not asking “how agentic can we make this?” You are asking “what is the minimum level of determinism we can safely remove from each step, and why?”

    The Workflow Classification Test: Four Axes That Determine the Right Mode

    2x2 process classification matrix for agentic vs deterministic workflow decisions showing four quadrants based on input variability and failure cost

    Not all processes are created equal. Before assigning a workflow to an agentic or deterministic layer, every operator needs a consistent test. The following four-axis classification gives you a structured way to evaluate any process and arrive at a defensible, documented decision.

    Axis 1: Input variability

    How structured and predictable are the inputs to this process? At one end of the scale, a payroll run has highly structured inputs — employee IDs, hours worked, tax codes, all in defined schemas. At the other end, a customer complaint intake process receives free-text emails, voice transcripts, chat logs, photos, and PDF attachments, each containing different information arranged differently.

    Low variability inputs → deterministic systems can handle them cleanly. High variability inputs → deterministic systems struggle because you cannot enumerate handling rules for every possible form the input might take. This is where agentic systems have a genuine advantage: they interpret, classify, and extract structured meaning from messy, variable inputs before handing off to downstream processes.

    Axis 2: Failure cost

    What is the cost if this step produces a wrong output? This has two dimensions: reversibility and magnitude. A step that sends an automated price update to an internal spreadsheet has low failure cost — the error is easy to catch and reverse. A step that triggers a wire transfer, submits a regulatory filing, or sends a mass customer communication has high failure cost — the error may be irreversible, financially significant, or legally consequential.

    High failure cost → maintain deterministic control over the final execution step, even if agentic reasoning contributes to the decision. The failure cost axis is where operators most consistently underestimate risk. Agents are excellent at reasoning, but they should rarely be the last actor before a high-consequence, hard-to-reverse action fires.

    Axis 3: Rule completeness

    Can you completely enumerate, in advance, all the rules needed to handle every case this process will encounter? This is the crux of the agentic vs. deterministic decision. If the answer is yes — if you can write a decision tree that covers every meaningful case — then a deterministic system will outperform an agentic one on speed, cost, and auditability. If the answer is no — if there are too many edge cases, exception types, or context-dependent variations to script — then a deterministic system will break constantly, and an agentic system will handle the variability better.

    Most mature, stable processes are closer to rule-complete than operators think. The honest exercise is: have someone actually try to write the decision tree. If they get 85% of the way there and then hit a wall, that remaining 15% of edge cases may be exactly where agentic reasoning belongs — not at the whole process level.

    Axis 4: Auditability requirements

    Does this process need to produce a clear, human-readable audit trail that explains every decision? Financial services, healthcare, legal, and regulated industries typically require this. Audit requirements favor deterministic systems because a rules engine can explain exactly why it did what it did. Agentic systems can log their actions, but “the model reasoned that…” is not the same as “rule 47(b) applied because condition X was true.”

    Where auditability requirements are strict, the recommended pattern is: let the agentic layer classify, draft, or recommend, but enforce the actual decision through a deterministic policy engine that writes the audit record. The agent contributes reasoning; the deterministic layer makes the final call and owns the log.

    Applying the four axes: a quick scoring approach

    Score each axis from 1 (low) to 3 (high). Add the scores for input variability and subtract the scores for failure cost and auditability requirements. Processes with a positive net score lean toward agentic; processes with a negative or zero net score lean toward deterministic. Rule completeness acts as a veto: if you can fully enumerate the rules and the process is stable, go deterministic regardless of the other scores. This is not a perfect algorithm — it’s a conversation starter that ensures your team is evaluating the right dimensions before making the call.

    Trust Zones: How to Draw Boundaries Inside Your Architecture

    Concentric rings architecture diagram showing deterministic enforcement zone, supervised agentic zone, and fully agentic core as trust zones in a hybrid AI system

    Once you’ve classified your processes, you need a way to represent the results architecturally. Trust zones are the mechanism. A trust zone is a defined area of your system within which a particular type of AI behavior is permitted to operate, bounded by explicit controls at its edges.

    Zone 1: The deterministic enforcement layer

    This is the outermost and most tightly controlled zone. It contains your policy engine, your rate limiters, your blocklists, your compliance rules, and your authorization checks. Nothing that reaches this layer is evaluated by a language model. The logic here is fully codified, versioned, and auditable. It is the last line of defense before an action becomes permanent or externally visible.

    Every hybrid system needs this zone, regardless of how sophisticated the agentic layers above it are. The deterministic enforcement layer does not negotiate. If a request fails a rule, it fails — no override, no re-reasoning, no “but the agent thinks it’s fine.” This is where operators set hard limits on spend, access scope, customer-facing action types, and irreversible state changes.

    Zone 2: The supervised agentic layer

    Inside the deterministic enforcement layer sits a supervised agentic zone. This is where agents operate, but with human checkpoints wired into the workflow at defined confidence thresholds or action types. An agent in this zone can classify a customer complaint, draft a resolution, look up account history, and propose a refund amount — but before the refund is issued, a human reviews and approves the action, or the request is routed to the deterministic enforcement layer for a rule-based approval check.

    Supervision can be human-in-the-loop (a person reviews before action), human-on-the-loop (a person monitors in real time with override capability but doesn’t review every action), or automated policy check (a deterministic rule evaluates the agent’s proposed action before it executes). The choice depends on volume, risk, and the maturity of your confidence measurement for that agent’s output.

    Zone 3: The fully agentic core

    At the center of the architecture, fully agentic behavior is appropriate for a specific, usually limited, class of tasks. These are typically: internal, reversible, low-consequence actions like drafting, summarizing, classifying, or retrieving information; tasks with no external side effects until explicitly committed; and reasoning steps that contribute to decisions rather than executing them.

    The common mistake is letting the fully agentic core expand over time as the team gets comfortable with the agent’s output quality. Zone boundaries should be reviewed on a schedule, but they should never drift because of familiarity. Comfort with a system’s usual behavior is not the same as confirmed safety of its full behavior distribution. The boundary between Zone 2 and Zone 3 should be a formal governance decision, not an informal cultural shift.

    Zone transitions: the permission model

    Each zone transition needs an explicit permission model. What is the agent’s identity at each boundary? What tools can it call inside each zone? What data can it read, write, and delete? The 2026 consensus from security-focused practitioners is to apply a zero-trust model at zone transitions: the agent must explicitly authenticate its identity and have its requested action authorized against a policy at each boundary crossing. Not “we trust agents in Zone 2 generally,” but “this specific agent, executing this specific action class, with this specific confidence score, has authorization to cross this boundary right now.”

    The Boundary Layer: Engineering the Seam Between Agentic and Deterministic

    The boundary between your agentic and deterministic systems is the most important piece of engineering in a hybrid architecture. It is also the piece that gets the least deliberate design attention. Most teams build the agents, build the deterministic rules, and then treat the connection between them as “just an API call.” That is where systems break.

    What the boundary layer needs to do

    The boundary layer has four distinct responsibilities: translation, validation, routing, and logging.

    Translation means converting between the agent’s natural-language or semi-structured output and the typed, schematized inputs that deterministic systems require. An agent might output “approve the refund for $47 and send the customer an apology email.” The boundary layer must parse that intent, validate that the customer ID is valid, confirm the refund amount is within policy limits, and format the request as a structured payload that the downstream refund system can process without interpretation.

    Validation means checking the agent’s output against a set of deterministic rules before it passes downstream. This is the boundary’s own enforcement step — not the full policy engine (that lives in Zone 1), but a lighter-weight check for structural validity, range violations, obvious inconsistencies, and missing required fields. If the agent’s output fails validation, it is returned to the agent with an error description, or escalated to a human, rather than passed forward with bad data.

    Routing means directing the validated output to the correct downstream system or approval workflow based on its content. Not all validated agent outputs go to the same place. A routing layer that is itself agentic is a common and dangerous anti-pattern — you want deterministic routing at the boundary, so that the path an action takes is predictable and auditable.

    Logging means creating an immutable record of every agent output, every validation result, every routing decision, and every downstream action triggered. This record is your audit trail and your incident reconstruction capability. It must be separate from the agent’s own memory or context — agents should not be able to read or modify the boundary log.

    The structured output contract

    The most practical tool for managing the boundary layer is a structured output contract: a schema that defines exactly what the agentic layer is required to produce before its output can cross into the deterministic layer. The contract defines required fields, data types, valid value ranges, confidence thresholds (where the agent is required to report its own uncertainty), and the action classification that determines routing.

    Teams that implement strict output contracts reduce boundary-layer failure rates substantially because they catch format and validity errors at the source rather than downstream. The contract also creates a versioning discipline — when the agent’s capabilities change, the contract version changes, downstream systems can be tested against the new contract before it reaches production, and the change is fully documented.

    Failure Modes at the Handoff: What Goes Wrong Specifically at the Seam

    Five-panel infographic showing the most dangerous failure modes at the agentic-to-deterministic handoff including goal drift, context bleed, privilege escalation, silent misbehavior, and prompt injection

    The 2026 field literature on hybrid agentic systems has converged on a clear finding: most production failures do not happen within the agentic layer or within the deterministic layer. They happen at the boundary between them. Understanding the taxonomy of these failures is essential before you can design against them.

    Failure mode 1: Goal drift across long-running contexts

    In long-running agentic workflows — ones that persist over hours, days, or multiple user sessions — the agent’s effective goal can drift from its original specification. This happens through context window accumulation, where earlier instructions get pushed out by newer inputs. It also happens through adversarial prompt injection, where a malicious payload embedded in data the agent processes (an email body, a document, a web page) redirects the agent’s behavior.

    The deterministic defense against goal drift is periodic context reset combined with goal anchoring: at defined intervals, or before each boundary crossing, the agent’s active goal is re-validated against the original specification stored in a deterministic, immutable system. If the agent’s stated goal no longer matches the original, the workflow is paused and escalated.

    Failure mode 2: Context bleed between sessions

    When agents share memory systems or when session isolation is improperly implemented, information from one workflow can contaminate another. An agent helping with a customer refund request might carry context from a previous session involving a different customer’s data. In multi-tenant environments, context bleed is not just a reliability problem — it is a data privacy and regulatory compliance failure.

    The deterministic enforcement layer must include hard session isolation at the boundary: before any agentic output is processed, the boundary layer validates that the session identifiers, customer identifiers, and data references in the agent’s output all belong to the same authorized context as the current workflow instance.

    Failure mode 3: Privilege escalation through tool chaining

    Agentic systems with access to multiple tools can, in certain configurations, chain tool calls in ways that produce capabilities the system was not authorized to have. An agent authorized to read a database and send emails might combine those two capabilities to exfiltrate data in a way that neither capability would allow in isolation. This is particularly dangerous in multi-agent architectures where sub-agents may have different permission levels than the orchestrating agent.

    The countermeasure is task-scoped identity: each agent and sub-agent is issued credentials that are valid only for the specific task scope of the current workflow instance, and those credentials expire when the workflow completes. The agent cannot accumulate permissions across tasks, and cross-task tool chaining is structurally prevented by the permission model rather than relying on the agent’s judgment not to do it.

    Failure mode 4: Silent misbehavior

    Silent misbehavior is the failure mode that most often goes undetected longest. The agent produces outputs that are technically valid — they pass validation, they route correctly, they execute without errors — but they are subtly wrong in ways that don’t trigger any alert. The refund amount is slightly off. The summary omits a key clause. The classification is in the right category but the wrong subcategory. Each individual error is small enough to be within the system’s tolerance, but they compound over volume into significant financial or operational damage.

    The only reliable defense against silent misbehavior is statistical monitoring at the boundary layer. Track the distribution of agent outputs over time, not just individual output validity. A sudden shift in the distribution — even if every individual output passes validation — is a signal that the agent’s behavior has changed in ways that should be investigated before they compound.

    Failure mode 5: Boundary layer brittleness on model updates

    When the model powering the agentic layer is updated — new version, fine-tuned weights, updated system prompt — the output format, confidence calibration, and reasoning style can all shift. If the boundary layer was calibrated to the previous model’s behavior, the update can cause a spike in validation failures, misrouting, or silent behavior changes that aren’t caught by the previous threshold settings.

    Best practice is to treat model updates as infrastructure deployments: run the new model in shadow mode behind the boundary layer, compare its outputs against the current model on live traffic for a defined validation period, and only switch traffic when the statistical comparison meets a defined equivalence threshold. This is operational discipline, not a product feature — it requires policy and process, not just tooling.

    Orchestration Patterns: Where Each One Belongs in the Agentic/Deterministic Mix

    Comparison chart of 5 orchestration patterns for hybrid agentic and deterministic systems including sequential pipeline, router/handoff, planner-worker, hierarchical, and parallel/swarm

    The orchestration pattern you choose determines how agentic and deterministic components interact — and the right pattern depends on your process type, failure tolerance, and the volume and variety of work flowing through the system. The 2026 production landscape has consolidated around five primary patterns.

    Sequential pipeline

    The simplest pattern: the workflow moves through a defined sequence of steps, some of which are agentic and some of which are deterministic. An agentic step might classify an inbound document; the next step, a deterministic router, sends it to the appropriate downstream system; a second agentic step might draft a response; the final step, a deterministic policy check, approves and queues it for sending.

    Sequential pipelines are the easiest to audit, the easiest to debug, and the easiest to modify. They are best for processes with a clear start and end, defined handoff points, and moderate rather than high variability. The limitation is that they handle exceptions poorly — if a step receives something it wasn’t designed for, the pipeline either fails or routes everything to a catch-all that becomes a human queue backlog.

    Router / handoff pattern

    A central routing step — ideally deterministic, potentially agentic for the classification that feeds it — receives work and distributes it to specialized handlers based on type. Some handlers are fully deterministic (standard order processing). Others are agentic (complex complaint resolution). The router itself must be deterministic or its behavior must be very tightly bounded, because a misbehaving router propagates errors to every downstream handler simultaneously.

    This pattern excels when work arrives with high variety but natural categorization: customer service queues, document intake, IT ticket routing. The key design rule is to make the classification step as deterministic as possible. Where classification requires AI, use a classifier with a confidence threshold and a deterministic fallback for low-confidence cases — route those to human review rather than letting an uncertain classification cascade into a handler that will act on it.

    Planner-worker pattern

    An agentic planning component receives a goal and decomposes it into a sequence of subtasks. Those subtasks are then executed by worker components, which can be agentic or deterministic depending on their nature. A planning agent might receive “reconcile this month’s vendor invoices” and produce a structured plan: retrieve invoices, match against POs, flag discrepancies, escalate unmatched items. The retrieval and matching steps execute deterministically; the discrepancy escalation step might be agentic (drafting a message) or deterministic (routing to a workflow).

    The planner-worker pattern is powerful for complex, multi-step processes that can’t be fully pre-scripted but need to complete reliably. The risk concentration is in the planning step: if the planner produces a bad plan, all the workers faithfully execute it. This is why the plan output should be validated by a deterministic schema check — and for high-stakes workflows, by a human reviewer — before execution begins.

    Hierarchical / manager-worker pattern

    A managing agent coordinates multiple specialized sub-agents, each of which may have its own agentic or deterministic behavior. The manager handles goal decomposition, context passing, and result aggregation; the workers specialize in specific task types. This is the pattern underlying most enterprise “agent teams” or “digital workforce” deployments.

    The governance challenge with hierarchical patterns is permission inheritance. When the manager agent passes a task to a sub-agent, what permissions does the sub-agent receive? The conservative answer is: only the permissions explicitly required for that specific subtask, issued fresh for that task, not inherited from the manager’s broader permission set. Hierarchical systems that pass permissions down through the hierarchy without re-scoping them are the most common source of privilege escalation failures in multi-agent deployments.

    Parallel / swarm pattern

    Multiple agents execute simultaneously on different aspects of the same problem, with a deterministic aggregator collecting and reconciling their outputs. This is best for high-throughput tasks where different inputs can be processed independently — document batch processing, large-scale data enrichment, parallel research tasks. The deterministic aggregator is critical: it must reconcile potentially inconsistent outputs from different agents and produce a single, validated result.

    Parallel patterns are operationally the most complex to monitor because failures can occur in any of the parallel branches simultaneously, and the aggregator must be designed to handle partial failures gracefully — completing the run on available outputs, flagging which branches failed, and not letting one branch’s failure corrupt the others’ valid results.

    The Operator’s Daily Job in a Hybrid System

    When agentic and deterministic systems are running in production together, the operator’s role changes in specific, concrete ways. This is worth spelling out because most teams don’t update their operational model when they add an agentic layer, and then are surprised when the agentic system produces problems that their existing operational practices weren’t designed to catch.

    Shifting from step monitoring to outcome monitoring

    In a purely deterministic system, you monitor steps: did step 3 execute? Did step 4 receive the correct input? Did the workflow complete? In a hybrid system, step monitoring is still necessary, but it is insufficient. You must also monitor outcomes: are the agent’s outputs producing the expected downstream results? Is the distribution of outputs consistent with expected behavior? Are edge cases being handled the way the design intended?

    Outcome monitoring requires logging at a higher level of abstraction than step logging. The agent might execute all its steps without error and produce an output that passes all boundary validations — and still produce a wrong result. The only way to catch this is to track what the output caused downstream and compare it against a defined success distribution.

    Managing the exception queue

    Every hybrid system produces an exception queue: cases that the agentic layer flagged as uncertain, that failed boundary validation, that the router couldn’t classify, or that were escalated by the deterministic enforcement layer. The operator’s daily job includes reviewing this queue, categorizing the exceptions, and deciding whether they represent system failure (a bug to fix), edge cases (patterns to add to training or rules), or expected human territory (cases that should always go to a person).

    Exception queue management is intelligence gathering for the system. A well-run exception review process is how operators know when their agentic/deterministic mix is wrong: if the queue is dominated by a specific type of case, either the agentic layer needs improvement for those cases or more of them need to be routed to the deterministic layer (or to humans) upfront.

    Governance of the boundary over time

    The agentic/deterministic split is not a one-time decision. It requires periodic review as the agent’s capabilities improve, as the process changes, and as the organization’s risk tolerance shifts. Operators need a formal governance calendar for boundary reviews — not a standing meeting, but a scheduled audit cycle tied to model update events, significant process changes, and defined time intervals (quarterly is a reasonable default for most production systems).

    The governance decision at each review is specific: which process steps, currently handled deterministically, could now safely be handed to the agentic layer? Which steps, currently agentic, have shown enough reliability issues that they should be brought back under deterministic control? Both directions of change should be on the table. The goal is the right mix for current conditions, not a constant expansion of agentic scope.

    Measuring the Mix: Observability and the KPIs That Actually Matter

    Dashboard-style observability panel for hybrid agentic and deterministic systems showing agentic intervention rate, deterministic override count, handoff latency, and human escalation rate metrics

    You cannot manage a hybrid system without measuring it. The problem is that most teams inherit monitoring frameworks built for purely deterministic systems and add a few model-specific metrics on top. This gives an incomplete picture because it misses the boundary-layer dynamics that determine whether the hybrid architecture is actually working.

    Boundary health metrics

    Agentic intervention rate: the proportion of workflow instances in which the agentic layer materially influenced the outcome (as opposed to being bypassed or overridden). A very high rate suggests the deterministic rules may be too narrow. A very low rate suggests the agentic layer may not be contributing meaningfully and its cost may not be justified.

    Boundary validation failure rate: the proportion of agent outputs that fail the boundary layer’s structural and validity checks. A rising trend here indicates the agent’s output quality is degrading, possibly due to a model update, context drift, or a shift in input distribution. A spike after a model update is normal; a persistent rise without a trigger event is a red flag.

    Deterministic override count: how often the deterministic enforcement layer blocks or reroutes an action that the agentic layer intended to execute. This is distinct from validation failures — an override means the agent proposed a valid-format action that was blocked by policy. Overrides are not failures; they are the system working as designed. But a sustained high override rate means the agent is consistently proposing things the policy engine won’t allow, which suggests either the agent needs better grounding in the policy constraints or the policy constraints need review.

    Handoff latency: the time elapsed between an agent producing an output and that output completing its boundary-layer processing and reaching the downstream deterministic system. Boundary layer bottlenecks show up here. High handoff latency at volume can negate the efficiency gains from agentic processing.

    Trust and reliability metrics

    Human escalation rate: the proportion of cases that exit the automated system (either agentic or deterministic) for human review. Monitoring this by case type tells you which parts of your process are not yet reliably automated. A declining escalation rate over time is a positive signal. A sustained flat or rising escalation rate despite continued investment in the agent suggests the process itself may not be a good fit for the current agentic architecture.

    Output distribution consistency: statistical tracking of the agent’s output distribution over time — the mix of action types recommended, confidence score distribution, and routing decisions. Major shifts in this distribution without a corresponding shift in input distribution are a signal that the agent’s behavior has changed. This metric requires baseline measurement from a stable production period and ongoing comparison against that baseline.

    Error amplification factor: in systems where the agentic layer’s output feeds into downstream automated systems (rather than humans), a single error can trigger a cascade. The error amplification factor measures how many downstream actions were affected by a single upstream agent error. High amplification factors in specific workflow paths indicate those paths need additional validation or a human check before the agentic output fans out to downstream systems.

    Ten Mistakes Operators Make When Setting the Agentic/Deterministic Ratio

    Most of the patterns that cause hybrid systems to underperform or fail are predictable. They appear consistently across different industries and different technical implementations. Understanding them before you encounter them is cheaper than fixing them in production.

    1. Treating the ratio as a one-time architectural decision

    The right mix changes over time — as the agent matures, as processes evolve, and as the organization’s regulatory environment shifts. Teams that lock in a ratio at deployment and don’t revisit it end up with a mismatch between the system’s current capabilities and the mix they’re running. Build the governance cycle into your operating model from day one.

    2. Letting the agentic layer expand into its adjacent deterministic territory without formal review

    Once a team is comfortable with the agent’s performance on its defined task, there is a strong temptation to let it “handle” adjacent cases that are technically within its capability but were originally designated as deterministic for good reasons. This is scope creep at the architectural level. The original reasons for keeping a step deterministic should be revisited formally, not bypassed informally.

    3. Making the boundary layer an afterthought

    The boundary between agentic and deterministic systems receives a fraction of the design attention given to the agent itself or the downstream deterministic logic. But most production failures originate at the boundary. Design the boundary layer as a first-class component: specify it, test it, version it, and monitor it with the same rigor you apply to the systems on either side of it.

    4. Using another LLM as the safety check for the first LLM

    A common and dangerous pattern: an agent produces an output, and a second LLM is used to verify whether that output is safe or correct before it crosses the boundary. This is probabilistic safety checking on top of probabilistic generation. The safety checker shares many of the same failure modes as the agent it’s checking. Hard policies, deterministic rules, and schema validation should be the primary safety mechanism at the boundary — not another model.

    5. Not specifying a structured output contract

    When the boundary between the agentic layer and downstream systems is defined only informally — “the agent should produce something like X” — the boundary will fail unpredictably as the agent’s output format drifts. Define, version, and enforce a structured output contract. It takes time to specify upfront and saves multiples of that time in debugging and incident response.

    6. Calibrating confidence thresholds once and not revisiting them

    The confidence threshold at which an agent’s output is allowed to proceed vs. escalated for human review is typically set during testing on a sample dataset. As the agent sees real production traffic — which is always more variable than the test sample — its confidence calibration shifts. Confidence thresholds need to be recalibrated regularly against production data, not set once and forgotten.

    7. Running agents with broader permissions than each specific task requires

    The principle of least privilege — give each component only the permissions it needs for its current task — is foundational in security, but it’s frequently violated in agentic deployments because it’s easier to give an agent broad permissions and let it figure out what it needs. This creates systematic over-privileging that turns any agent failure or compromise into a high-blast-radius event. Task-scope permissions, issued fresh for each workflow instance, are the right model.

    8. Treating human-in-the-loop as sufficient safety for high-risk actions

    Human review is valuable, but “a human looked at it” is not a substitute for deterministic enforcement of high-risk action constraints. Humans reviewing high volumes of agent outputs develop automation bias — they tend to approve what the agent recommends because approval is the norm. For actions above a defined risk threshold, deterministic constraints should prevent the action even if a human approves it, unless a separate elevated-authorization workflow is triggered.

    9. Not testing boundary behavior under adversarial conditions

    Most boundary layer testing covers normal inputs. Adversarial inputs — prompt injection payloads, malformed structured outputs designed to bypass validation, inputs that combine valid-format fields with policy-violating values — require deliberate testing. Red-team your boundary layer regularly, with a focus on inputs that are designed to appear valid while bypassing the constraints the boundary is supposed to enforce.

    10. Optimizing for agentic throughput at the expense of deterministic safety

    When there’s pressure to process more volume faster, the path of least resistance is to relax boundary validation, reduce human review checkpoints, and let the agent handle more without oversight. This is exactly the wrong direction under volume pressure. High volume means errors compound faster. The appropriate response to volume pressure is to harden the boundary layer and improve the agent’s efficiency within its defined scope — not to expand its scope without the safety infrastructure to match.

    Auditing and Rebalancing Your Current Stack: A Step-by-Step Process

    If you already have agentic components running in production, or you’re about to deploy them, this section provides a structured audit process for evaluating your current mix and making informed rebalancing decisions.

    Step 1: Inventory every step in every production workflow that touches an AI component

    This sounds obvious, but most teams don’t have a complete inventory. Shadow deployments, team-level experiments, and vendor integrations that include AI under the hood frequently mean AI components are operating in production workflows that the central operations team doesn’t know about. Do a full inventory before you audit. Include every workflow that uses an LLM, a classification model, a recommendation engine, or a generative AI tool — not just the ones explicitly labeled as “agentic AI.”

    Step 2: Apply the four-axis classification to each step

    For each AI-involved step in the inventory, apply the four-axis classification from Section 2. Document the score. Flag any step where the current mode (agentic or deterministic) doesn’t match what the classification suggests it should be. These mismatches are the candidates for rebalancing.

    Step 3: Evaluate the boundary layer for each AI-involved transition

    For each point where an AI component hands off to a deterministic component (or vice versa), evaluate whether a proper boundary layer exists. Does it include translation, validation, routing, and logging? Is the structured output contract specified and enforced? Is there monitoring on boundary health metrics? Flag every transition that is missing any of these elements.

    Step 4: Review the exception queue for the past 90 days

    Pull the exception queue data for the past 90 days. Categorize exceptions by type. Identify the top three categories by volume. For each, determine whether the exception volume represents a system quality problem (the agentic layer is failing on cases it should handle), a scope problem (these cases should never have been sent to the agentic layer), or an edge case management problem (the agentic layer handles them correctly but the rules for escalation are too conservative).

    Step 5: Identify rebalancing candidates

    Based on the classification mismatch review and the exception queue analysis, identify specific workflow steps that are candidates for rebalancing in either direction: steps that could safely become more agentic (low failure cost, high input variability, exception queue shows deterministic rules are generating excessive escalations), and steps that should become more deterministic (high failure cost, sustained silent misbehavior, or compliance requirements that the agentic layer isn’t reliably meeting).

    Step 6: Sequence the changes

    Prioritize rebalancing changes by expected impact and risk. Changes that move steps toward more deterministic control are generally lower risk — start with those to improve reliability before attempting to expand agentic scope. For steps moving toward more agentic, require shadow mode testing: run the new agentic behavior in parallel with the current deterministic behavior for a defined validation period before switching traffic.

    Step 7: Update governance and monitoring for the new configuration

    Every rebalancing change requires updating: the structured output contract (if the agentic layer’s scope changes), the boundary layer validation rules (if the new step has different valid output constraints), the monitoring thresholds (reset for the new configuration’s expected distribution), and the governance documentation (the audit record of why the change was made and what evidence supported it).

    The Mix Is the Product

    Every article about agentic AI eventually arrives at “use the right tool for the right job.” That advice is correct, but it’s not actionable on its own. What makes it actionable is a systematic process for determining which tool is right for which job, engineering the interfaces between them carefully, monitoring the combined system in ways that reveal boundary-layer failures, and maintaining the governance discipline to adjust the mix as conditions change.

    The 79% vs. 11% gap — the distance between enterprises that have adopted agentic AI and those running it in real production — is filled almost entirely with teams that couldn’t answer the boundary question clearly enough to build with confidence. They ran a pilot, got good results in a controlled environment, tried to scale it, and encountered failures at the handoff points they hadn’t designed carefully enough. The failures weren’t in the agent. They were in the seam.

    Operators who understand the seam — who design the trust zones, specify the output contracts, monitor the boundary health metrics, manage the exception queue as a feedback signal, and govern the mix on a regular cycle — are the ones whose agentic deployments make it past the pilot stage and into durable production. That is not a technology advantage. It is an operational advantage. It is earned through deliberate design, not through model selection.

    The agentic/deterministic mix is not a configuration setting. It is the product you are actually building. Design it accordingly.

    Key takeaways for operators

    • Use the four-axis classification (input variability, failure cost, rule completeness, auditability requirements) to assign every workflow step to its correct mode.
    • Draw explicit trust zones in your architecture and enforce them through deterministic controls at every zone boundary — never through agent judgment alone.
    • Engineer the boundary layer as a first-class component: translation, validation, routing, and logging are all required.
    • Monitor boundary health metrics (agentic intervention rate, boundary validation failure rate, deterministic override count, handoff latency) alongside outcome metrics.
    • Treat the mix as a governance item on a defined review cycle, not a one-time architectural decision.
    • Test your boundary layer adversarially, recalibrate confidence thresholds against production data, and apply task-scoped permissions to every agent and sub-agent.
    • Use the 90-day exception queue audit as your primary signal for when the mix needs rebalancing.
  • Hook-First SBV Creative Testing: Inside the 7-Day Iteration Sprint That Cuts Wasted Ad Spend

    Hook-First SBV Creative Testing: Inside the 7-Day Iteration Sprint That Cuts Wasted Ad Spend

    7-Day Hook-First SBV Creative Testing Sprint Dashboard showing video hook variants and performance scores

    Most Amazon advertisers treat Sponsored Brands Video as a placement, not a laboratory. They produce one polished video, push it live against a broad keyword set, check the CTR a week later, shrug at the numbers, and wonder why they’re burning through budget without hitting their ACOS targets. The video plays. Nobody clicks. The creative ages. The ACoS climbs. Eventually someone commissions a new video — and the cycle repeats.

    The core problem isn’t production quality. It isn’t budget. It’s the absence of a systematic testing methodology built around the one thing that determines whether a viewer engages or scrolls: the first three seconds. The hook.

    Sponsored Brands Video (SBV) is currently Amazon’s highest-CTR ad format, delivering average click-through rates of 0.9–1.0% against a platform-wide average of approximately 0.4% for all Sponsored Brands formats. When that performance gap closes — when your SBV is pulling 0.4% like a static banner — it almost always traces back to a hook failure, not a body-copy problem or a CTA weakness. The opening frame is doing the heavy lifting or none of the work at all.

    This article lays out a complete 7-day iteration sprint for hook-first SBV creative testing. Not a loose framework. Not a theory deck. A day-by-day operating system — complete with the metrics you track at each stage, the kill thresholds that tell you when to pull a creative, the signal patterns that tell you when to scale, and the briefing process that ensures each new sprint is smarter than the last. If you run this process consistently, you will know more about what your audience responds to after four sprints than most of your competitors know after a year of running ads.

    What SBV Creative Testing Actually Measures

    SBV signal stack infographic showing hook rate, hold rate, completion rate, CTR, CVR, and new-to-brand benchmarks

    Before you can run a testing sprint, you need to be clear about what you’re measuring — and why the full signal stack matters more than any single metric in isolation. Brands that optimise solely for CTR regularly promote creatives that drive clicks but convert poorly. Brands that optimise solely for ACoS sometimes kill high-attention creatives that would have built brand awareness and new-to-brand customers at a reasonable cost over time.

    SBV creative testing uses six primary signals, each measuring something meaningfully different about how a viewer is responding to your video.

    Hook Rate

    Definition: 3-second video views divided by total impressions. This is your opening attention capture metric — it tells you what percentage of people who saw your ad actually stopped to watch the first three seconds rather than scrolling immediately. The 2026 benchmark for ecommerce SBV is a hook rate of 30% or above for solid performance, with top-decile creatives reaching 40–45%. Anything below 20–22% is a signal that your opening frame is failing to arrest attention, regardless of what else the video does well.

    Hold Rate

    Definition: The percentage of viewers who watched past the 3-second mark and continued engaging with the video. Where hook rate tells you about the opening grab, hold rate tells you whether the rest of your creative is delivering on the promise of that first frame. A high hook rate paired with a collapsing hold rate means your opening is misleading or tonally disconnected from the body of the ad. You grabbed them, then immediately lost them. That’s a structural problem, not a hook problem. Target 45% or above for competitive SBV performance.

    Completion Rate

    Definition: The percentage of video starts that result in the full video being watched. For SBV formats running at 15–30 seconds, strong completion rates sit at 35% or above. Completion rate tracks the overall narrative strength of the creative — does the argument you’re making hold attention all the way through to the CTA? Completion rate drops sharply when videos run too long, when transitions are jarring, or when the product demonstration section loses momentum after a strong hook.

    Click-Through Rate (CTR)

    Definition: Clicks divided by impressions. The headline metric most teams default to, and a legitimate one — but it’s most meaningful when read alongside hook rate and hold rate. A strong CTR of 0.9% or above from a low hook rate suggests you’re getting clicks from a small number of highly engaged viewers, but the creative is failing the majority. That’s an efficiency problem hidden behind a respectable number. CTR is the output; the attention metrics above are the inputs.

    Conversion Rate (CVR) and ACoS

    Definition: The percentage of clicks that result in a purchase, and the ratio of ad spend to attributed sales. CVR for strong SBV typically sits in the 10–12% range for ecommerce, though this is heavily category-dependent and also influenced by listing quality, price positioning, and review count — factors outside the creative itself. ACoS is your efficiency governor. It keeps CTR optimisation honest by measuring whether the traffic you’re generating actually converts at a cost that makes sense for your margin structure.

    New-to-Brand Rate (NTB)

    Definition: The percentage of purchases from customers who have not bought from your brand on Amazon in the past 12 months. SBV is a particularly powerful format for new-to-brand customer acquisition because it appears on search results pages and reaches buyers in active discovery mode. A healthy NTB rate of 30% or above from SBV suggests your creative is genuinely pulling in new customers, not just serving existing ones. Teams that ignore NTB often undervalue SBV’s contribution to long-term brand growth.

    Together, these six signals form your creative testing dashboard. The sprint methodology uses them in sequence: attention metrics first (hook rate, hold rate) to make fast creative decisions, then downstream metrics (CTR, CVR, NTB) to qualify those decisions with business impact data before you commit budget to scale.
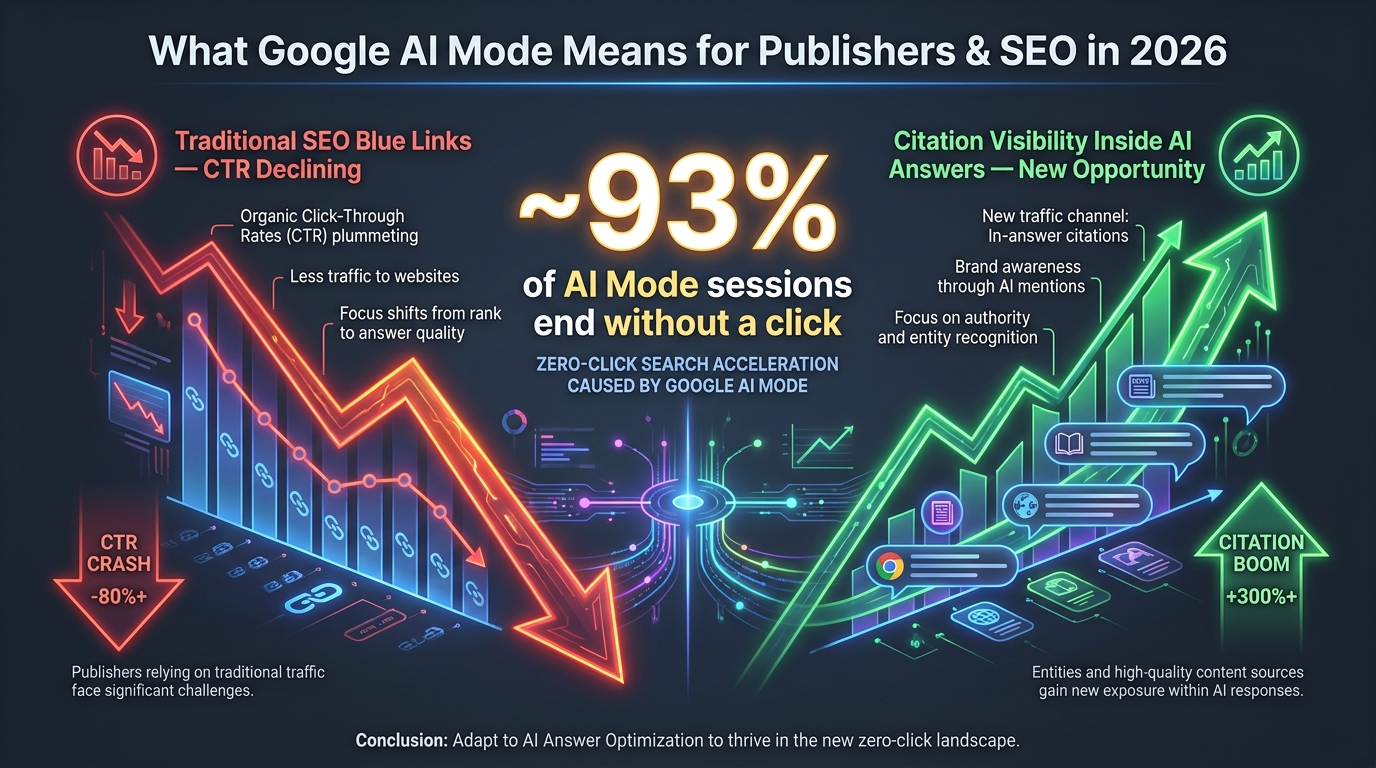
    The Hook-First Principle: Why the Opening Frame Decides Everything

    The hook-first testing approach rests on a simple but important operational insight: the hook is the highest-leverage variable in any SBV creative, and it’s also the cheapest and fastest variable to change.

    Re-editing the body of a video requires producer time, potentially re-shoots, and a full review cycle. Changing the hook — the opening 2–3 seconds of footage, motion, text overlay, or voiceover — often requires nothing more than a simple asset swap. You can produce four or five distinct hook openings in the time it takes to produce one complete alternate video. That asymmetry makes the hook the obvious first testing variable.

    The second reason hooks get tested first is that they disproportionately determine performance. Research consistently shows that in search-adjacent placements like SBV, viewers make their scroll-or-watch decision within approximately 1.5–2 seconds of the ad appearing. Your brand story, product demonstration, testimonials, and CTA are all invisible to anyone who scrolls past the opening frame. Optimising those downstream elements before optimising the hook is like repainting the interior of a house when the foundation is cracked.

    What Makes a Hook Work on Amazon Specifically

    Amazon SBV operates in a different attention environment than social platforms. Viewers on TikTok or Instagram are in browsing mode — they’re moving through content for entertainment and discovery. Amazon viewers are in buying mode — they typed a search query, they saw a product grid, and now an ad is interrupting the consideration process. That difference changes what works.

    On Amazon, effective hooks do three things simultaneously in the first two to three seconds: they establish product relevance (this is the thing you’re searching for), they communicate a distinct value proposition (here’s why this one specifically), and they create sufficient cognitive engagement to earn the next five seconds of attention. This is a narrower brief than social video, where emotional or entertainment-led hooks can carry a longer ramp. SBV hooks need to be commercially relevant faster.

    Amazon’s own published guidance reinforces this: the product should appear on screen within the first two to three seconds, its primary function or benefit should be visible within five seconds, and slow logo reveals or brand-first intros consistently underperform against product-forward openings. The viewer didn’t search for your brand — they searched for a solution. Your hook should mirror the intent behind that search query, not introduce your brand identity.

    Hook Taxonomy: The 5 Types That Actually Move SBV Metrics

    The 5 SBV Hook Types: Pattern Interrupt, Result-First, Problem Agitation, Curiosity Gap, and Proof Hook diagram

    Not all hooks are structurally equivalent. Through accumulated testing across SBV campaigns, five distinct hook archetypes have emerged as the most reliable performers. Each works through a different psychological mechanism, and each performs differently depending on category, funnel stage, and keyword intent. A 7-day sprint should typically include hooks from three or four different archetypes so that you’re testing strategic angles, not just surface-level copy variations.

    1. The Pattern Interrupt Hook

    This hook type opens with something visually or auditorily unexpected — a jarring cut, an unusual camera angle, rapid motion, a surprising statistic on screen, or a direct-address opening that breaks the viewer’s scanning pattern. The psychological mechanism is simple: novelty stops the scroll because the brain flags unexpected stimuli as potentially important. On a search results page full of static product images, any video doing something unusual commands attention.

    Structure: Unusual visual or motion element → immediate product reveal → benefit statement within 3 seconds.
    Best for: Competitive categories with high ad density, commodity products that need differentiation on attention.
    Watch for: Pattern interrupt hooks can drive high hook rates but lower hold rates if the unusual opening isn’t logically connected to the product. Test that hold rate carefully before scaling.

    2. The Result-First Hook

    This hook opens by showing the outcome — not the product itself, but what the product produces. A fitness product might open with the transformation. A kitchen gadget might open with the finished dish. A skincare product might open with close-up skin texture post-use. You’re leading with the most emotionally compelling part of the story and then working backward to the product.

    Structure: Compelling result or outcome on screen → product reveal → explanation of how the result was achieved.
    Best for: High-consideration categories where the benefit is visually demonstrable, beauty, health, home improvement, food and kitchen.
    Watch for: Result-first hooks require the result to be immediately legible to a viewer who doesn’t yet know what the product is. If the outcome requires context to understand, this hook type will underperform.

    3. The Problem Agitation Hook

    Opens by naming or showing a pain point the target customer experiences — directly, specifically, and fast. No preamble, no brand setup. Just: “You know that problem you have? We see it.” This hook type works because it creates instant relevance and emotional recognition. When the viewer sees their frustration mirrored in the opening frame, they feel the ad is speaking directly to them rather than broadcasting at everyone.

    Structure: Problem statement (visual, text overlay, or voiceover) → moment of agitation or emotional resonance → product as the pivot point toward resolution.
    Best for: Problem-solution products in health, organisation, pet care, baby, and any category where the purchase is pain-driven rather than aspiration-driven.
    Watch for: Problem agitation hooks can feel heavy-handed if the problem statement is too dramatic or generic. Specificity drives performance — “struggling to sleep through the night” outperforms “tired of bad sleep.”

    4. The Curiosity Gap Hook

    Opens with a partial statement, an intriguing question, or an incomplete visual that the viewer’s brain wants to resolve. “Here’s why most [product category] are actually making your [problem] worse.” “We tested every [product type] on the market. This happened.” The hook works by creating an information gap that the viewer wants to close — which means they keep watching.

    Structure: Partial claim or intriguing question → withhold the resolution for 3–5 seconds → product reveal as the answer.
    Best for: Educational or consideration-phase keywords, research-mode shoppers, and categories where the viewer has existing knowledge and opinions they’re willing to challenge.
    Watch for: Curiosity gap hooks tend to drive strong hold rates and completion rates but sometimes lower immediate CTR — the viewer is engaged but may not yet feel urgency to click. Works best in longer SBV formats (25–30 seconds).

    5. The Proof Hook

    Opens directly with social validation — a specific review snippet, a rating, a user count, a before/after image, or a bold data claim. “47,000 five-star reviews.” “Rated #1 by independent lab testing.” “Before and after: same product, 30 days.” This hook works because social proof is one of the most reliable decision shortcuts in ecommerce. Buyers on Amazon are pre-conditioned to weigh review signals heavily, and a proof hook activates that decision heuristic immediately.

    Structure: Bold proof claim on screen within 1 second → product visual alongside the proof → secondary benefit statement.
    Best for: Products with strong review velocity, established brands with credible third-party validation, or any product with a quantifiable performance claim.
    Watch for: Amazon has policies around specific claim types in ads. Ensure all proof-hook claims comply with advertising guidelines before launching. Unverifiable superlatives (“best in class,” “world’s most”) are typically rejected.

    Before the Sprint Starts: Setup, Budget, and Campaign Architecture

    A 7-day hook testing sprint is only as reliable as the infrastructure supporting it. Running multiple hook variants inside an existing scaling campaign, or testing against a broad match keyword list, introduces too many confounding variables to produce readable results. Setup matters before day one.

    Dedicated Testing Campaigns

    Isolate hook testing inside a separate Sponsored Brands Video campaign, completely distinct from your main scaling campaigns. This prevents test creatives from competing with your proven performers for the same impression pool and ensures budget is being allocated as designed rather than being auto-optimised toward incumbents. The testing campaign runs in parallel with your main campaign — it doesn’t replace it.

    Keyword Selection

    Use a tight keyword cluster of 10–20 exact-match terms that represent your core, highest-intent search queries. Avoid broad match or auto-targeting during the sprint — you want every impression to be from a searcher with equivalent intent so that performance differences between hook variants are attributable to the creative, not to audience variation. The same keyword set should be used across all hook variants to ensure a level testing environment.

    Budget Allocation

    The standard practitioner guidance for 2026 is to run 10–20% of your total SBV budget in testing campaigns and 70–80% in proven scaling campaigns. For a 7-day sprint with 4–5 hook variants, you need sufficient daily budget per variant to generate enough data for a readable signal. A common minimum is approximately $25–$50 per day per variant, which at typical SBV CPCs generates roughly 300–700 clicks per week per creative — enough to get directional hook rate, hold rate, and CTR signals, though CVR will require longer run times to stabilise.

    Ad Group Structure

    Run each hook variant as a separate ad within a single ad group, or in separate ad groups within the same campaign. The critical rule: one creative variable per test. All hook variants should use the exact same body copy, product shots, voiceover script (from second 4 onward), CTA text, and landing page. The only element that differs is the opening 3-second hook. This is what gives you causation rather than correlation when you see performance differences.

    Naming Conventions

    Use a clear naming convention that includes the sprint number, hook type, and variant identifier — for example: SBV_Sprint01_PatternInterrupt_v1, SBV_Sprint01_ResultFirst_v1. This prevents confusion during analysis and makes it easy to build a historical record across sprints that becomes searchable and learnable over time.

    Days 1–2: Hypothesis Building and Hook Brief

    7-day SBV sprint timeline showing Build phase Days 1-2, Monitor phase Days 3-5, and Decide phase Days 6-7 with kill, hold, and scale thresholds

    Days 1 and 2 are pre-launch. No ads are running yet (unless you’re in the second or later sprint, in which case your previous cycle’s winners are live in your main campaigns). These two days are for structured hypothesis building and creative briefing.

    The Hypothesis Document

    Every hook variant in a sprint should have a written hypothesis — not a vague intent, but a testable prediction. A good hook hypothesis looks like this:

    “We believe a problem-agitation hook opening with a shot of [specific pain point] and the text overlay ‘[specific customer frustration statement]’ will outperform our current result-first hook because our top-performing organic reviews consistently cite this pain point as the primary purchase trigger, and our current creative doesn’t address it until second 12.”

    The hypothesis should include: the hook type, the specific opening content, the rationale (drawn from customer data — reviews, search query reports, competitor analysis), and the predicted performance outcome. Writing the hypothesis forces clarity about what you’re actually testing and why — and it builds a learning database across sprints that tells you which rationales reliably predict wins.

    Sourcing Hypothesis Inputs

    The most reliable inputs for hook hypotheses come from four places. First, your top-performing product reviews — specifically the first sentence of your highest-voted reviews, which tends to be the most emotionally loaded and problem-specific language your customers use. Second, your search query report — the specific terms customers used to find your product tell you the intent frame they were in when they saw your ad. Third, competitor listing analysis — look at the bullet points, A+ content, and review language on your top three competitors to identify the angles and claims they’re leading with that you’re not. Fourth, previous sprint results — if you’ve run earlier sprints, which hook types outperformed? Are there patterns suggesting your audience responds to certain emotional registers or proof types more than others?

    The Hook Brief Format

    For each hook variant, provide the creative team or editor with a one-page brief that specifies: the opening visual (exact shot or stock asset, with timestamp reference if re-cutting existing footage), any text overlay (copy, font weight, position, timing), any voiceover or sound design for the first 3 seconds, and the specific frame where the hook transitions to the established body of the video. This brief-level specificity keeps hook variants genuinely distinct and prevents the creative team from making interpretive choices that blur your variables.

    Days 3–5: Live Monitoring and Early Signal Reading

    Ads launch at the start of day 3. The first 48 hours after launch are not decision-making time — they are observation time. Resist the urge to pause or adjust anything based on the first 24 hours of data. Amazon’s ad serving takes time to stabilise, and small sample sizes in day 1 produce wildly unstable metrics that will mislead you if you treat them as actionable. The platform learning phase needs room to work.

    What to Look At on Day 3

    Check that all variants are serving impressions at roughly equivalent rates. Large disparities in impression volume between variants — where one is getting 10x the impressions of another — often indicates a Quality Score difference, which itself is a useful signal: Amazon’s system may be predicting performance based on early engagement cues. Note the disparity but don’t intervene yet. If one variant is getting near-zero impressions by the end of day 3, investigate the creative for policy issues before assuming poor performance.

    Day 4: First Directional Read

    By day 4 with sufficient budget, you should have enough 3-second view data to see hook rates forming. This is your first genuine signal checkpoint. Look for the spread between variants — are hook rates clustered tightly (suggesting the hook type isn’t the differentiating variable) or spread across a wide range (suggesting strong hook-level performance differences)? A spread of 10+ percentage points between your best and worst hook rate after 48 hours of data is meaningful and directional.

    At this point, note but do not act. Log the current hook rates, hold rates, and any CTR data in your sprint tracking document. Tag your current hypothesis for each variant: “tracking as predicted,” “outperforming prediction,” or “underperforming prediction.” This annotation becomes the learning layer that improves Sprint 2’s hypotheses.

    Day 5: Operational Monitoring

    On day 5, run a more complete signal audit. You should now have enough data to see whether early hook rate leaders are maintaining their hold rates — or whether the relationship is inverting. Check all six signal metrics for each variant:

    • Hook rate: Is it above 20% (minimum viable), above 30% (healthy), or approaching 40%+ (strong)?
    • Hold rate: For any variant with a strong hook rate, is hold rate 45%+? A hook rate above 30% with a hold rate below 30% is a red flag — the opening is clickbait-adjacent.
    • Completion rate: Is the body of the video sustaining the attention the hook generated? Target 35%+.
    • CTR: Is it at or above the SBV benchmark of 0.9%? Below 0.5% after 5 days suggests a hook-to-body disconnect or a keyword-creative mismatch.
    • CVR: Too early for statistical significance, but note directional patterns — any variant showing 0 conversions after significant click volume deserves scrutiny.
    • Spend distribution: Is the campaign allocating spend relatively equally? Significant spend concentration toward one variant early may indicate Amazon’s algorithm has started optimising for a signal you can’t yet see.

    Days 6–7: Kill, Hold, or Scale — The Decision Framework

    The final two days of the sprint are decision time. Every active hook variant gets assigned one of three statuses: Kill, Hold, or Scale. These decisions should be rules-based, not intuition-based. Writing down your decision rules before the sprint starts prevents the cognitive bias of falling in love with a creative you spent time making.
    Kill Threshold

    Any variant meeting one or more of the following criteria gets paused immediately:

    • Hook rate below 20% with adequate impression volume (3,000+ impressions)
    • CTR below 0.5% with at least 500 clicks in flight or 5,000 impressions
    • Hold rate below 25% despite an adequate hook rate — meaning the opening is attracting the wrong audience or making a promise the body doesn’t fulfil
    • ACoS more than 2× your target ACoS with sufficient conversion data (minimum 10 purchases)

    Killing underperformers isn’t wasted effort — it’s the point of the sprint. Every kill generates a documented data point about what your audience doesn’t respond to, which is as valuable as knowing what they do respond to. Log the kill, the metric that triggered it, and your post-hoc hypothesis about why this hook underperformed.

    Hold Criteria

    Hold status applies to variants that show some promising signals but haven’t accumulated enough data for a confident call. Typical hold situations include: a variant launched late due to creative production delays (run it for one additional week), a variant with a hook rate between 22–29% that’s borderline on multiple metrics, or a variant that’s showing unusually strong CVR but weak CTR (which may indicate a highly specific audience self-selecting). Hold variants continue at current budget for an additional sprint cycle rather than being promoted or killed.

    Scale Criteria

    A variant earns Scale status when it meets all of the following:

    • Hook rate 30% or above
    • Hold rate 40% or above
    • CTR at or above 0.9%
    • CVR directionally in line with category benchmarks (10%+ for most ecommerce, though minimum 15 purchases needed for confidence)
    • ACoS at or below 1.5× your target ACoS

    Scale doesn’t mean dramatically increase budget overnight. The practitioner consensus in 2026 is to graduate winning SBV creatives into your main scaling campaign with an initial budget increase of 20–30%, then assess performance at 48–72 hour intervals before increasing further. Aggressive overnight budget multiplications typically trigger a new learning phase, which temporarily destabilises performance metrics and makes it difficult to distinguish scaling effects from learning-phase noise.

    The Iteration Loop: How Winners Feed the Next Sprint

    Creative sprint iteration loop diagram showing how sprint analysis feeds the next hypothesis batch for compounding performance lift

    The 7-day sprint is not a one-time event. Its value compounds when run as a continuous cycle where each sprint’s output directly informs the next sprint’s hypothesis set. This is what separates teams that genuinely improve creative performance over time from those that run tests without building institutional knowledge.

    The Sprint Retrospective (End of Day 7)

    Before closing the sprint, conduct a structured retrospective with your team. This takes 30–45 minutes and covers five questions:

    1. Which hypothesis predictions were accurate? Where the creative performed as predicted, what made the prediction correct — was it based on review language, keyword intent data, or pattern from a previous sprint? Reinforce that input method.
    2. Which predictions failed? Where performance diverged from prediction, what was the reasoning gap? Did the hook type not match the audience intent? Was the emotional register wrong for the category? Was the problem statement too generic?
    3. What did the data suggest about this audience that you didn’t know before? Look for surprising patterns — a hook type you expected to underperform that showed unusually high hold rate, or a hook type that drove strong CTR but weak CVR (suggesting it was attracting the wrong buyer intent).
    4. What’s the strongest creative hypothesis for Sprint 2? Based on the winner’s attributes, what is the next variation worth testing — a different execution of the same hook type, a bolder version of the winning claim, or a pivot to a new hook archetype informed by the hold rate patterns?
    5. Is the creative fatigue clock ticking on your main campaign? Check whether your current scaling campaign’s hero creative is approaching the 14–21 day fatigue window. If so, sprint 2 needs to move fast enough to have a replacement ready before performance starts degrading.

    Briefing Sprint 2

    Sprint 2’s hook brief should be meaningfully different from Sprint 1’s, not simply Sprint 1 with minor copy tweaks. Use the retrospective outputs to write hypotheses that are more specific and more informed than the first round. If your Sprint 1 winner was a problem-agitation hook using a specific pain point, Sprint 2 might test: a deeper version of that same pain point with more specific language, a result-first hook that uses the exact outcome language from your best-performing reviews, and two entirely new hook archetypes you haven’t tested yet (to ensure you’re not anchoring entirely on the Sprint 1 winner type).

    This deliberate broadening — testing new archetypes even when you have a winner — is important for long-term creative health. Over-indexing on a single hook type because it won Sprint 1 leads to a library of similar creatives that fatigue simultaneously, leaving you without a replacement bench when performance drops.

    Creative Fatigue: Why the Sprint Has to Keep Moving

    Creative fatigue comparison showing SBV ad performance declining from Week 1 to Week 4 with CTR dropping from 1.1% to 0.4%

    One of the most consistent findings from SBV advertisers in 2026 is that creative fatigue is arriving faster than it used to, and the consequences of missing the fatigue signal are more expensive than they were two or three years ago. Understanding why this is happening — and how the 7-day sprint system is specifically designed to outrun it — is important context for any team building a testing program.

    The Fatigue Timeline

    At modest Amazon ad spend levels, SBV creatives typically begin showing measurable performance degradation at roughly the 21–30 day mark, with hook rates and CTR starting to slide noticeably. At higher spend levels — where the same creative is generating significantly more impressions per day — fatigue can appear within 10–14 days. The mechanism is straightforward: viewers who have seen the same video two or three times in their search results start scrolling past it automatically. The pattern interrupt no longer interrupts. The curiosity gap has already been closed. The proof claim has been processed and discounted.

    The result is that hook rate starts dropping first — the leading indicator — and CTR and CVR follow within a few days. If you’re checking performance weekly rather than monitoring hook rate daily, you may not catch the fatigue signal until CTR has already dropped significantly and you’ve spent seven to ten days driving expensive, low-engagement impressions.

    The 7-Day Sprint as a Fatigue Prevention System

    The sprint methodology addresses fatigue structurally rather than reactively. Because you’re running a new sprint every week, you’re continuously building a bench of tested hook variants that can be rotated into your main campaigns before performance degrades. The goal is to never be in the position of scrambling to produce new creative because your current video is fatiguing — instead, you have the next winner ready and tested before it’s urgently needed.

    Practically, this means that after three to four sprints, you should have a portfolio of validated hooks — some actively scaling, some in reserve, and one sprint always in flight generating the next batch of candidates. This creative pipeline model, rather than the reactive “our video is failing, what do we do?” approach, is the operational advantage that consistent sprint practitioners build over time.

    Rotation Strategy

    Rather than running a single winning creative until it fatigues, experienced SBV advertisers run a rotation of two to three validated hooks simultaneously in their main campaigns, refreshing one hook variant every two to three weeks even when performance hasn’t visibly degraded yet. This proactive rotation prevents the sharp performance cliff that comes from replacing a fatigued creative with an untested one. Instead of: strong performance → rapid decline → scramble → uncertain replacement → slow ramp, the pattern becomes: consistent strong performance → controlled rotation of tested variants → no cliff.

    Common Sprint Failures and How to Avoid Them

    Teams new to sprint-based creative testing consistently hit a small number of predictable failure modes. Knowing them in advance significantly reduces the number of sprints you waste before the system starts delivering reliable results.

    Testing Too Many Variables at Once

    The most common mistake: running hook variants that differ in more than one element. If Hook A and Hook B differ in both the opening visual and the voiceover copy in the first three seconds, and Hook A wins, you don’t know whether it was the visual or the copy that drove the win. That means you can’t brief Sprint 2 with meaningful specificity. Every hook variant in a sprint should differ from the others in exactly one element. Everything else is held constant.

    Killing Too Early on Insufficient Data

    The 7-day minimum window exists for a reason. Hook rate can look extremely weak on day 1 and normalise by day 4 as the algorithm finds its footing. Pulling a creative after 18 hours because the CTR looks low wastes the creative production investment and guarantees you never accumulate enough data to make the kill/hold/scale decision confidently. Write your kill thresholds before the sprint starts, apply them only after the minimum data threshold is met, and do not deviate based on early snapshots.

    Conflating Hook Rate with CTR

    These are related but different signals measuring different things. A hook that drives a 42% hook rate but a 0.6% CTR is telling you something important: you’re capturing attention but failing to convert that attention into a click. The disconnect is happening somewhere in the body of the video, the CTA, or the product’s alignment with the searcher’s intent. Don’t kill the hook — investigate the body. Don’t scale the creative either, but use this data to brief a hybrid test: strong hook with a revised body and CTA.

    Running Tests Against Non-Comparable Audiences

    If your hook variants are served against different keyword sets — for example, Hook A against branded keywords and Hook B against category keywords — your results are unreadable. Branded and category audiences have different intent, different product familiarity, and different conversion propensity. Always keep the keyword set identical across all hook variants in a sprint.

    No Sprint Documentation

    Sprints without written hypothesis documents, signal logs, and retrospective notes produce data without learning. Teams that don’t document their sprint process find themselves running the same tests six months later because they don’t have a record of what was already tested and what those tests revealed. The 30-minute investment in documentation per sprint compounds into a genuinely differentiated creative intelligence asset within four to six sprint cycles.

    Measuring Sprint ROI: What Good Looks Like After 4 Rounds

    The question every team asks before committing to a sprint system: what does success look like, and how long does it take to get there? The honest answer is that Sprint 1 is unlikely to produce dramatic performance improvements — it’s primarily a calibration round that establishes your baseline signal stack, validates your testing infrastructure, and produces your first documented creative hypotheses. The compounding returns arrive from Sprint 3 onward.

    Four-Sprint Performance Trajectory

    Based on the patterns observed across mature SBV testing programs in 2026, here’s what a typical four-sprint progression looks like in performance metrics:

    • Sprint 1: Baseline establishment. Hook rates across variants typically spread across a 12–18 percentage point range. One or two hooks emerge as directional winners. CTR performance usually falls within 10–15% of pre-sprint baseline. Primary output: first set of validated hypotheses and a confirmed testing infrastructure.
    • Sprint 2: First meaningful performance gain. With better hypotheses built from Sprint 1 data, hook rate for the winning variant typically improves 5–8 percentage points above Sprint 1’s winner. CTR improvement of 15–25% over baseline is common. Primary output: first scalable creative and beginning of a rotation bench.
    • Sprint 3: Compounding intelligence. Hypothesis accuracy improves noticeably because you’re drawing on two rounds of actual audience response data. Hook type preferences are becoming clear, allowing more targeted creative briefs. CTR 30–40% above pre-sprint baseline is achievable for teams with strong creative execution. Primary output: second scalable creative, rotation strategy operational, fatigue prevention system working as intended.
    • Sprint 4: System maturity. The team is fluent in the sprint process, documentation is becoming a genuine creative intelligence database, and performance has stabilised at a materially higher level than the pre-sprint baseline. ACoS improvements of 15–25% are typical for teams that have successfully scaled two or more sprint winners. New-to-brand rate often improves as the optimised hook messaging aligns better with discovery-intent searchers. Primary output: a repeatable, self-improving creative engine that reduces dependence on any single creative asset.

    Tracking Sprint-Level ROI

    Calculate sprint ROI by comparing: the cost of running the sprint (creative production for 4–5 hook variants, plus the testing campaign ad spend) against the performance improvement in your main campaign attributable to the winning creative. If a sprint winner drives a 20% CTR improvement and a 12% CVR improvement in your main campaign over 30 days post-graduation, and your main campaign spend is $10,000/month, the attributable performance improvement should be quantifiable in ACoS and revenue terms. Most teams running this calculation consistently find that sprint 3 and beyond show a clear positive ROI on creative testing investment, with the creative production cost of a hook variant ($150–$500 for a well-structured sprint using existing footage re-cut with new hooks) representing a small fraction of the performance delta at meaningful ad spend levels.

    Conclusion: The Structural Advantage of Testing Before You Scale

    Sponsored Brands Video is one of the highest-leverage formats in the Amazon advertising ecosystem. But leverage is only realised when the creative doing the lifting is actually working. The hook-first 7-day iteration sprint is the operational system that ensures you’re not scaling a mediocre creative — you’re scaling a tested, signal-validated one that has earned its promotion.

    The core ideas to carry forward:

    • The hook is the first test because it’s the highest-leverage and lowest-cost variable to change. Never spend budget optimising body copy, CTA, or format when the hook hasn’t been validated.
    • Use the full signal stack, not just CTR. Hook rate tells you about attention. Hold rate tells you about creative integrity. Completion rate tells you about narrative strength. CTR and CVR tell you about commercial performance. You need all of them to make good decisions.
    • Decision rules belong on paper before the sprint starts, not improvised during it. Kill thresholds and scale criteria written in advance prevent confirmation bias from distorting your reads.
    • Creative fatigue is an inevitable physics problem. The only way to stay ahead of it is to have validated replacement creatives ready before degradation sets in — which requires a continuous sprint cycle, not a reactive production scramble.
    • Documentation compounds. Every sprint that’s properly documented makes the next sprint’s hypotheses more accurate. After four rounds, your creative intelligence is a real competitive asset. After eight, it’s defensible.

    The 7-day sprint won’t feel efficient in the first round. The infrastructure setup takes time. The hypothesis writing feels theoretical. The signal reads are ambiguous with small data sets. Run it anyway. The teams consistently generating the strongest SBV performance in 2026 aren’t the ones with the biggest production budgets or the most sophisticated creative. They’re the ones that test methodically, document honestly, and let the signal stack tell them what to scale — rather than guessing.

  • The Handoff Threshold: What Kimi, Devin, and ChatGPT Agent Can Actually Own — and Where You Need to Stay in the Loop

    The Handoff Threshold: What Kimi, Devin, and ChatGPT Agent Can Actually Own — and Where You Need to Stay in the Loop

    Three AI agent control rooms — Kimi swarm, Devin coding terminal, and ChatGPT Agent browser — separated by a red Handoff Threshold line

    The question used to be whether AI agents could do things. That debate is over. Kimi’s K3 Agent Swarm can coordinate up to 300 parallel sub-agents across more than 4,000 tool calls for a single task. Devin autonomously plans, codes, tests, and submits pull requests in production repositories. ChatGPT Agent operates a virtual computer — browsing websites, filling forms, editing spreadsheets, and connecting to external apps — while you’re nowhere near your desk.

    The new question — the harder question — is what you can safely hand off to them.

    That distinction matters enormously. Because “the agent can do this” and “you should let the agent own this” are not the same sentence. The gap between those two statements is where real workflows break, where security incidents begin, and where the most promising automation projects quietly stall out after six weeks.

    This piece is not a feature-by-feature comparison of three AI products. It is a practical framework for understanding the structural difference between these systems, the tasks each genuinely handles well without supervision, the failure modes that emerge when teams over-delegate, and the security and governance realities that most “AI agent” coverage skips entirely. If you are deciding what to put in front of one of these agents and what to keep in a human’s hands, this is what you need to know.

    The Architecture Underneath: Why These Three Systems Are Fundamentally Different by Design

    Technical architecture diagram comparing Kimi's 300-node swarm, Devin's cloud VM environment, and ChatGPT Agent's sandboxed browser setup

    Kimi, Devin, and ChatGPT Agent are often lumped together under the same “AI agent” label, but their underlying architectures were built to solve different problems. That difference shapes everything — which task types they excel at, where their failure modes live, and crucially, how much human oversight they actually require at scale.
    Kimi: A Swarm Intelligence Model

    Kimi’s K3-powered agent stack operates on a horizontal scaling principle. When you give Kimi Agent a complex task, a primary controller agent decomposes it into subtasks and dynamically spins up to 300 specialized sub-agents to execute those subtasks in parallel. There are no predefined roles you configure. The system designs its own organizational structure based on what the task requires.
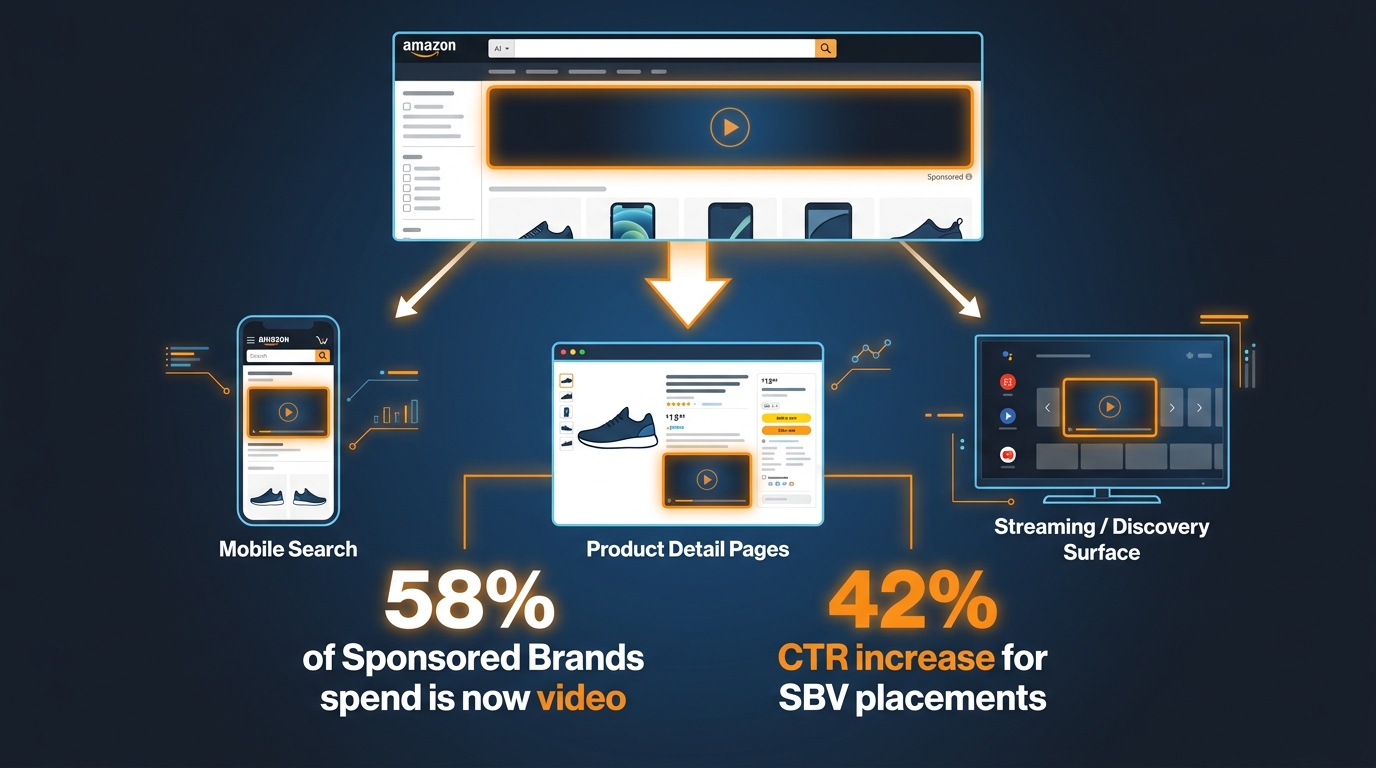
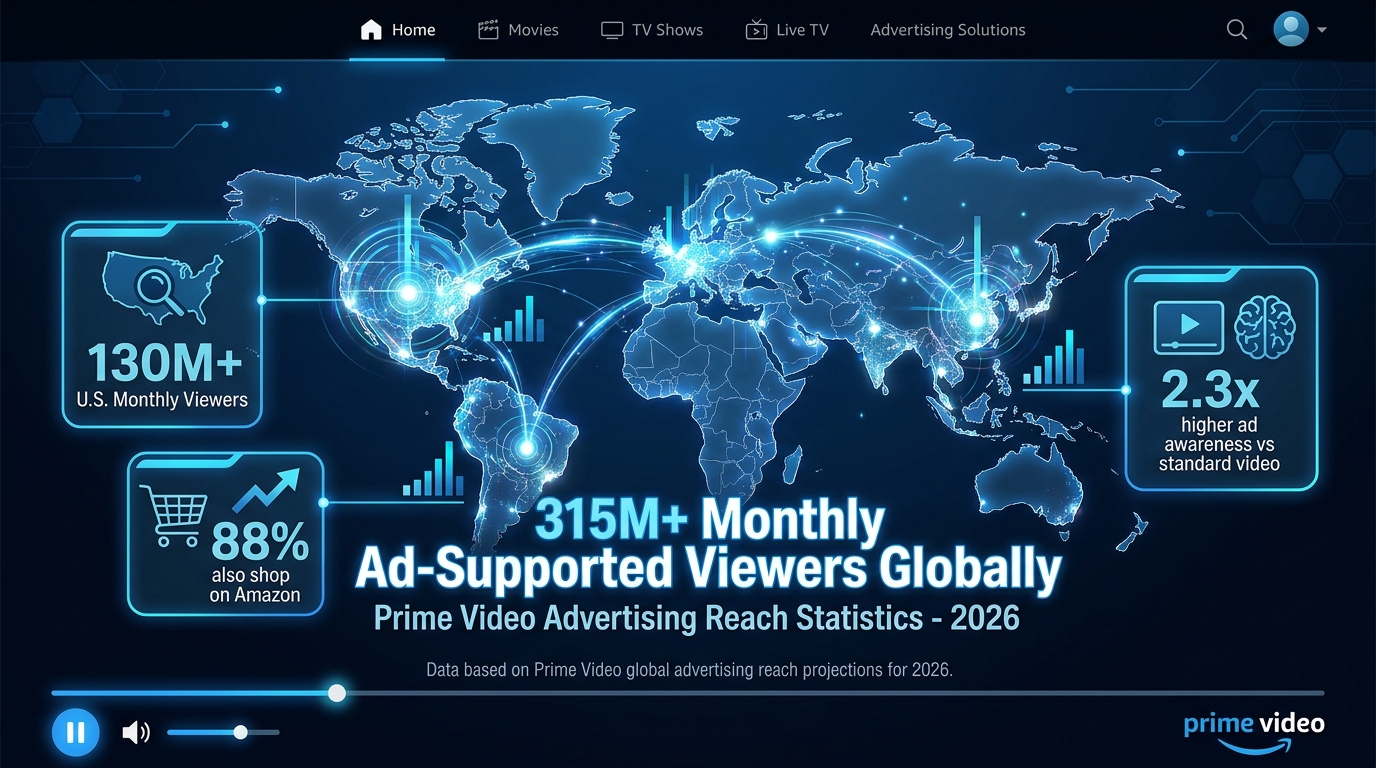
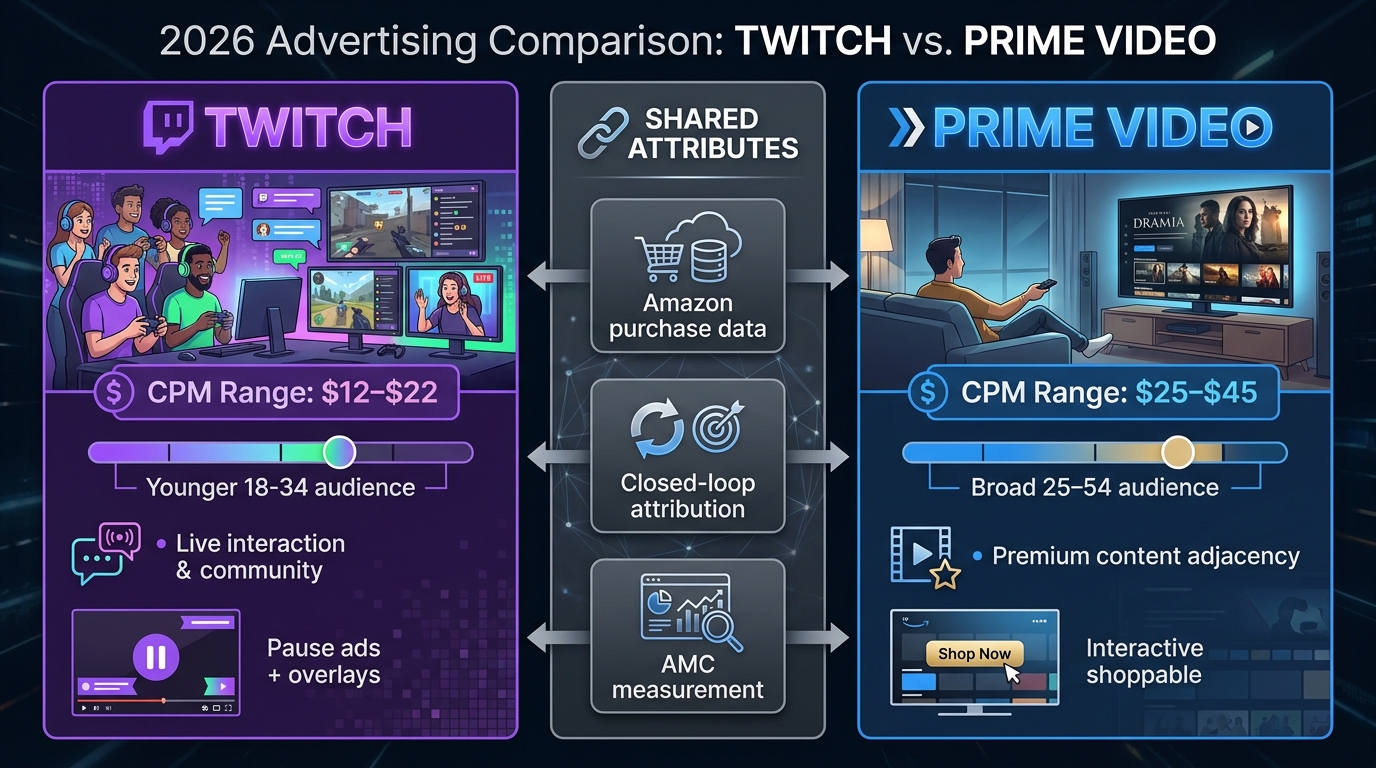
    The scale here is not marketing hyperbole — it’s a meaningfully different architectural choice. Kimi reports that Agent Swarm completes qualifying tasks approximately 4.5 times faster than single-agent, sequential execution. The system can sustain more than 4,000 coordinated tool calls per task, which enables multi-day autonomous operation. Kimi Claw, the cloud automation layer, extends this into desktop and web application control.

    The implication is that Kimi’s architecture is optimized for breadth and throughput: tasks where parallelism pays off — massive research synthesis, large-scale data enrichment, high-volume document processing, broad codebase analysis — fit naturally into this model. Narrow, judgment-heavy tasks with ambiguous success criteria do not.

    Devin: A Deep Domain Specialist

    Devin (Cognition) was purpose-built for one domain: software engineering. Rather than a general-purpose agent that can code among other things, Devin is an agent-native IDE: it gets its own sandboxed cloud VM, its own interactive development environment, access to your actual repositories, and the ability to submit pull requests with real code that goes into production.

    Devin 2.0 introduced three structural capabilities that changed how the system is actually used: Interactive Planning (Devin researches your codebase and produces a detailed plan before touching a single line of code, which you can review and modify before it acts), Devin Search (an agentic tool for querying the structure and logic of your codebase), and Devin Wiki (an auto-generated, regularly updated knowledge base of your repositories, including architecture diagrams and documentation). You can now spin up multiple parallel Devins on concurrent tasks, each with its own isolated IDE.

    What this architecture signals is that Devin was designed for depth within a defined domain. It works inside a boundary — your codebase, your tools, your PR workflow — rather than across a general-purpose action space. That constraint is actually a feature, not a limitation.

    ChatGPT Agent: A General-Purpose Workflow Executor

    ChatGPT Agent (previously Operator) takes the broadest approach: a sandboxed virtual computer with a browser, a code interpreter, file access, and a growing set of external app connectors. The system can research competitors across dozens of websites and return a structured report, fill out multi-step forms, pull data from a PDF and update a spreadsheet, help plan and book travel, and run scheduled monitoring tasks while you’re offline.

    Its architecture prioritizes generality and accessibility. It doesn’t require a specialized environment setup or domain-specific integration. It works in a browsable internet context, which means it can interface with virtually any web-based tool. The tradeoff is that it operates with monthly task caps that vary by subscription tier, and it is fundamentally session-based — it doesn’t maintain persistent context across disconnected tasks the way a specialized system like Devin does within a codebase.

    Kimi Agent Swarm: When 300 Sub-Agents Work While You Sleep

    Understanding where Kimi genuinely excels requires setting aside the 300-agent headline and focusing on the structural characteristics of the tasks it handles well. The swarm architecture earns its value in situations where a single problem can be legitimately decomposed into many parallel, mostly independent subtasks — and where the output is a synthesized result rather than a single judgment call.

    Where Kimi’s Swarm Architecture Actually Delivers

    Large-scale information retrieval is the clearest fit. If you need competitive intelligence across 200 websites, a literature review spanning 500 research papers, or a data enrichment pass across a 50,000-row CRM export, the parallelism of Agent Swarm directly reduces the wall-clock time of the task. Each sub-agent pulls data from a subset of sources, and the main controller synthesizes the results. The 4.5x speed advantage Kimi cites is most credible in exactly these scenarios.

    Long-form document production at scale — think generating 100 tailored product descriptions, producing technical documentation for a large software library, or creating a detailed research report pulling from dozens of data sources — also maps well to the swarm architecture. Sub-agents can handle individual sections or source documents in parallel, with a coordinating agent managing consistency.

    Kimi K3, which now powers all agent modes and includes a 1M-token context window with native vision, also handles complex coding tasks across large repositories — though in a different style than Devin. Where Devin works deeply and iteratively inside your actual codebase with a persistent IDE session, Kimi’s strength in coding is broader codebase analysis, documentation generation, and tasks that benefit from parallel sub-agent processing of multiple files or modules simultaneously.

    The Limits Kimi’s Architecture Creates

    The swarm model introduces a specific class of failure mode: coordination errors. When 300 sub-agents are synthesizing information in parallel, the quality of the final output depends on how well the main controller manages consistency, contradiction resolution, and priority weighting across their outputs. For well-structured data tasks with clear success criteria, this works well. For tasks requiring nuanced judgment — where ambiguity in one sub-agent’s output should cause the system to revise its entire approach — the swarm can produce results that are voluminous but directionally wrong.

    Multi-day continuous operation is technically supported, but it introduces a governance question that many teams underestimate: who is monitoring the agent over those days? What checkpoints exist? What triggers human review? Running a swarm of 300 sub-agents autonomously for 48 hours without visibility is not an AI strategy — it is an audit liability.

    Devin AI: The Myth of the Autonomous Engineer vs. What’s Actually Working

    Devin received significant press attention when it launched around claims of autonomous software engineering. Some of that coverage overstated what was actually happening. Getting this right matters for anyone considering deploying Devin in a real engineering workflow — because the actual performance data tells a more nuanced and ultimately more useful story.

    The Benchmark Reality

    On SWE-bench Verified — a standard evaluation benchmark that tests AI systems on real GitHub issues — Devin’s original published score was 13.86% autonomous resolution. That was a meaningful jump above prior autonomous agents, which typically scored between 1% and 4%. But it also means that roughly 86% of real, ambiguous GitHub issues were not resolved fully autonomously. Independent reanalyses placed the apples-to-apples figure closer to 9–10% in some configurations.

    On more structured benchmarks, the numbers improve considerably: WebArena (web-based development tasks) showed 28.4% success; Terminal-bench (terminal-based tasks) showed 23.89%. These numbers reflect the pattern that consistently emerges in real-world Devin deployments: the more defined and bounded the task, the higher the success rate.

    Where Devin Is Genuinely Strong

    On well-scoped, clearly defined tasks, Devin’s production success rates are meaningfully higher than benchmarks suggest. Bug-fix success rates for clearly scoped issues have been documented as high as 78% in real-world testing. For repetitive engineering work — database migrations, test suite generation, boilerplate scaffolding, API integration work where the spec is clear — Devin handles 60–80% of tasks with minimal intervention.

    The Interactive Planning feature in Devin 2.0 deserves specific attention because it changes the delegation dynamic in an important way. Before Devin executes anything, it researches your codebase, identifies relevant files and components, and produces a preliminary plan that you review and modify. This means the handoff is not “give Devin a task and walk away” — it is “collaborate on the plan, approve the approach, then let Devin execute.” That structure dramatically reduces the risk of Devin misunderstanding what you want and executing confidently in the wrong direction.

    The parallel Devin instances feature changes team economics. Rather than one developer reviewing and managing one Devin session at a time, an engineer can manage multiple concurrent Devin tasks across different subsystems — checking in on progress, steering when needed, reviewing PRs. This is an amplifier for engineers who are good at code review and architectural direction, not a replacement for the judgment those skills require.

    Where Devin Still Fails

    Ambiguous, architecture-heavy problems are where Devin’s limitations are most pronounced. “Redesign our authentication flow for scalability” or “figure out why the app is slow under load and fix it” are not well-scoped tasks. They require iterative investigation, contextual judgment about tradeoffs, and the kind of accumulated institutional knowledge that doesn’t live in a repository — it lives in the engineers who built the system. Devin does not handle these reliably.

    Novel problems — where there isn’t a clear prior pattern in the codebase or a well-defined success condition — also surface Devin’s limits. The system’s strength is pattern recognition and structured execution within familiar territory. When the territory is genuinely new, Devin tends to produce confidently wrong code rather than escalating for human input.

    ChatGPT Agent: The General-Purpose Workhorse and Its Real-World Limits

    ChatGPT Agent occupies a different position in the landscape: it is the most broadly accessible of the three systems and the one most likely to be used across a wide range of business functions rather than within a specialized technical domain. Understanding what it genuinely handles well — and where its architecture creates hard limits — matters for any team deploying it beyond basic research tasks.

    What’s Actually Working in Production

    Research and competitive intelligence gathering is ChatGPT Agent’s clearest strength. The ability to browse across dozens of websites, extract structured information, and return a synthesized report or populated spreadsheet is genuinely useful and works reliably when the task is well-framed. Market research, vendor comparison, pricing intelligence, and feature benchmarking all fall into this category.

    Data wrangling — extracting data from PDFs or web sources, cleaning it, and updating a spreadsheet or CSV — works well when the data structure is predictable. Form-filling and structured web interactions, including vendor onboarding workflows and repetitive data-entry tasks, also work reliably when the target website doesn’t have aggressive bot detection or dynamic form behavior that trips up the agent’s click sequence.

    Scheduled monitoring tasks are functional but require careful setup. ChatGPT Agent can check a set of websites for pricing changes, monitor a job board for specific listings, or pull updated data from a source on a recurring basis — but these are best thought of as monitoring and reporting tasks, not fully autonomous action tasks. The agent surfaces findings; a human decides what to do with them.

    Where the Architecture Creates Real Limits

    ChatGPT Agent is session-based and task-capped. This means it doesn’t maintain deep persistent context across disconnected sessions the way Devin maintains context within a codebase through its Devin Wiki and Search tools. For tasks that require continuity across days or weeks — tracking a complex negotiation thread, managing an ongoing project — the session model introduces friction.

    Monthly task caps create a practical budgeting problem for teams that try to use ChatGPT Agent at scale. The caps vary by subscription tier and can be exhausted faster than expected when agents are running multi-step tasks across large datasets. Teams that don’t model their task consumption upfront often hit ceilings mid-workflow.

    Judgment-heavy tasks — where the agent needs to weigh multiple competing considerations, exercise domain expertise, or make a call that depends on organizational context it doesn’t have — are where ChatGPT Agent is least reliable. It will produce an output that looks complete, but the quality of the judgment embedded in that output can be poor in ways that aren’t obvious until downstream consequences surface.

    The Handoff Decision Matrix: A Practical Framework for What to Delegate

    2x2 delegation matrix: Automate Freely, Human Gate Required, Automate with Logging, and Never Auto-Execute quadrants

    Across real enterprise deployments in 2026, a consistent pattern has emerged around what AI agents can safely own without supervision. The framework that best captures this pattern is built on two axes: reversibility (can the action be undone without significant cost?) and consequence scope (how broadly does a wrong output affect your business, your customers, or external parties?).

    The Four Zones of Task Delegation

    Zone 1 — Automate Freely (High Reversibility / Low Consequence): These are the tasks where full autonomy is genuinely safe. Data enrichment and deduplication. Email classification and prioritization. Ticket triage and routing — production systems show 95–96% routing accuracy in this category. Research synthesis for internal consumption. Generating first drafts of documentation. Populating templates from structured data sources. If the agent gets it wrong, the cost of correction is low and contained. These tasks should flow through AI agents without human checkpoints.

    Zone 2 — Automate with Logging (High Reversibility / Medium-High Consequence): These tasks can be automated, but every action should be logged with sufficient detail to audit and reverse if needed. Updating CRM records. Publishing internal knowledge base articles. Drafting external communications that go through a final human review before sending. Code changes that go through a PR review before merging. The key discipline here is that “automate with logging” means you have an actual logging infrastructure, not just an assumption that you could retrieve records if needed.

    Zone 3 — Human Gate Required (Low Reversibility / High Consequence): Here, the agent can do the preparation, analysis, and drafting — but a human must approve before anything executes. Contract terms. Customer-facing communications that carry implied commitments. Pricing changes that propagate to external channels. External API calls that trigger vendor workflows. The agent’s role is to compress the time between “decision point” and “ready to decide” — not to make the decision itself.

    Zone 4 — Never Auto-Execute (Irreversible / High Consequence): Financial transactions above defined thresholds. Regulatory filings. Deletion of customer data. Actions that create legal obligations. Security configuration changes in production environments. No AI agent — Kimi, Devin, ChatGPT Agent, or any other system — should be authorized to execute these autonomously in 2026. The technology is not the constraint here; the governance logic is correct regardless of capability level.

    Applying the Matrix in Practice

    The practical challenge most teams encounter is that real tasks often span multiple zones. A research-to-outreach workflow might have Zone 1 research, Zone 2 draft preparation, and Zone 3 message sending — all in a single automated sequence. The failure mode is treating the whole workflow as Zone 1 because the first step is low-risk. The governance rule is that a workflow’s zone classification is determined by its highest-consequence step, not its most common step.

    Industry data from 2026 deployments suggests that the practical “safe autonomy” ceiling for AI agents is roughly 70–80% of task volume — the portion of tasks that are well-bounded, reversible, and have clear success criteria. The remaining 20–30% requires human routing or approval gates, based on explicit risk signals, confidence thresholds, and contextual flags rather than a blanket rule.

    Trust Boundaries and Security Risks Nobody Is Talking About Enough

    Chain of AI agent nodes with privilege escalation sparks and security alert overlays showing transitive trust failure

    Most coverage of AI agents focuses on capability. Security professionals are focused on something different: the delegation chain itself. And the data from 2026 enterprise environments is concerning enough to warrant serious attention from anyone building or expanding an agent-based workflow.

    Transitive Trust: The Problem Most Teams Don’t See Coming

    When AI agents delegate to other agents — or when a main agent coordinates a swarm of sub-agents — each delegation step creates a trust handoff. The problem is that most current implementations handle this naively: sub-agents implicitly trust their parent, and agents often implicitly trust messages passed through shared tools or shared memory. This creates what security researchers are calling transitive trust escalation.

    The attack pattern works like this: a low-privilege sub-agent receives a task from a compromised or manipulated source. Because it trusts the delegation chain, it executes the task. If that sub-agent has access to a tool that a higher-privilege agent also uses — a shared file store, a shared API key, a shared database connection — the compromise propagates. A low-privilege agent effectively gains high-privilege access by routing through a peer with broader permissions.

    This is not a theoretical vulnerability. In 2026, multi-agent privilege escalation is a documented incident pattern in enterprise environments, and current identity and access management infrastructure was not designed to handle it. Only 18% of organizations report high confidence that their IAM infrastructure can manage agent identities effectively. Almost half of enterprises have simply extended their existing human IAM models to agents — which creates exploitable permission-scope mismatches because agents behave very differently from human users in how they acquire and exercise permissions.

    The Agent Identity Problem

    Traditional IAM assumes a relatively small number of identities (employees, service accounts) acting in predictable patterns. A Kimi swarm running 300 concurrent sub-agents on a single task represents 300 simultaneous identities acting across potentially thousands of tool calls. Tracking which sub-agent called which tool with which permissions, across a 4,000-step task, is not something current enterprise logging infrastructure handles well without specific architectural decisions made in advance.

    Emerging standards in 2026 are moving toward cryptographic “Know Your Agent” identity layers — essentially, each agent instance carries a signed credential that traces its authority back through the delegation chain, with permissions scoped explicitly at each hop. This is the right direction architecturally, but adoption is still early and most commercial agent platforms have not fully implemented it.

    Session Smuggling and Cross-Agent Injection

    A specific threat vector that enterprise security teams are tracking in 2026 is “agent session smuggling” — where a malicious instruction embedded in content that an agent is processing (a webpage, a document, an email body) causes the agent to take actions outside its intended scope. When ChatGPT Agent browses a website and encounters a hidden instruction in the page’s content telling it to forward data to an external endpoint, the agent may comply if its guardrails don’t catch the instruction.

    The mitigations are not complex, but they require deliberate implementation: strict permission scoping (the agent can only read data relevant to its task, and cannot write to external endpoints not pre-approved), content sanitization before agent consumption, and behavioral monitoring that flags unexpected action sequences. These are engineering disciplines, not product features — they require active decisions from the teams deploying the agents.

    The Reversibility Rule: Why This Single Factor Changes Everything

    Of all the dimensions in the handoff decision framework, reversibility deserves its own detailed treatment — because it is consistently the most underweighted factor in how teams actually make delegation decisions. Capability tends to dominate the conversation (“can the agent do this?”), but reversibility is what determines whether a mistake is a minor correction or a serious incident.

    Defining Reversibility Precisely

    Reversibility is not a binary. There are at least four meaningful categories: instantly reversible (undo the action with zero downstream consequence — a deleted draft, a reverted file change), reversible with cost (the action can be undone, but fixing it requires time, communication, or manual effort — a sent email requiring a follow-up correction, a database update that needs to be rolled back), partially reversible (some consequences can be undone, but others persist — a published article taken down still has search cache, screenshots, and RSS propagation that don’t disappear), and irreversible (the action cannot be meaningfully undone — transferred funds, deleted customer data beyond retention window, regulatory filings submitted).

    The correct governance approach is to require explicit documentation of the reversibility category for every task class you’re considering delegating to an AI agent. This is not bureaucracy — it is the decision that determines your fallback options when something goes wrong. And at the success rates currently achievable, something will go wrong.

    How Teams Get This Wrong

    The most common error is that teams evaluate reversibility at the task level but deploy agents at the workflow level. A task that is individually reversible can become effectively irreversible when embedded in a workflow that has downstream dependencies. A Devin agent that commits code to a branch is doing something reversible. But if that branch is connected to an automated CI/CD pipeline that pushes to staging and then to production on a schedule, the reversibility of the individual code commit is not the relevant measure — the reversibility of the production deployment is. And those are very different things.

    Designing agent workflows with explicit rollback procedures at each stage — not just at the task level — is a discipline that the teams running the most reliable agent deployments share. They think about “what does recovery look like if this step fails or produces bad output” before they enable automation, not after.

    What Breaks When Teams Over-Delegate

    Split screen showing over-delegation chaos with errors versus calibrated delegation with reversibility and consequence checkpoints

    The failure mode of over-delegation is distinct from the failure mode of under-delegation. Under-delegation is wasteful — you’re not capturing available productivity gains. Over-delegation is risky — you’re creating incidents that are expensive to recover from and corrosive to organizational trust in AI systems. In 2026, the more common and more consequential failure mode is over-delegation, and it follows recognizable patterns.

    Confidence Without Calibration

    All three systems — Kimi, Devin, and ChatGPT Agent — can produce outputs that look authoritative regardless of whether they’re correct. This is a property of large language models: they generate fluent, confident text. But in an agent context, fluent and confident is particularly dangerous, because the system is not just generating text — it is taking actions based on reasoning that may be plausible-sounding but wrong.

    Devin will write code that compiles and passes basic tests while introducing logic errors that won’t surface until edge-case inputs. Kimi’s swarm will produce a 60-page research synthesis that is internally consistent but draws incorrect conclusions because one set of sub-agents was working from low-quality sources. ChatGPT Agent will complete a vendor outreach form using data it inferred rather than data it was given, and the discrepancy won’t be visible in the output it returns to you.

    The teams that manage this well build verification checkpoints into their workflows — not just “did the agent finish the task?” but “did the agent finish the task correctly?” That often means sampling outputs for quality review, running automated tests on agent-generated code, or having a domain expert spot-check synthesized research before it informs decisions.

    Skill Atrophy in Supervised Domains

    A less-discussed but increasingly documented consequence of over-delegation is skill atrophy in human team members. When engineers stop reviewing and writing code in certain domains because Devin handles it, they gradually lose the depth of understanding needed to catch Devin’s errors. When analysts stop doing first-pass research because Kimi’s swarm produces full reports, they lose the source evaluation habits that would flag when a synthesis is drawing from unreliable inputs.

    This is not an argument against using AI agents — it is an argument for deliberate role design. The teams using these tools most effectively are distinguishing between skills that should be maintained through regular human practice (because they’re needed for verification and oversight) and tasks that can be fully delegated because the human skill is no longer needed in the workflow. That distinction requires intentional thinking, not just default delegation.

    The Accountability Gap in Multi-Agent Chains

    When a single human takes an action and it goes wrong, accountability is clear. When an AI agent takes an action as part of a multi-agent workflow — where the instruction came from another agent, which was acting on output from a third agent, which was processing a document retrieved by a fourth agent — accountability becomes genuinely murky. Who is responsible? The person who deployed the workflow? The team that configured the initial agent? The vendor who built the platform?

    Regulators and legal counsel are increasingly treating this as an open question with potentially serious consequences. The practical response is to treat the accountability chain as a design requirement, not an afterthought: every agent-executed action should be attributable to a named human authority who approved the delegation at each level. This requires workflow design discipline and logging infrastructure, but it is the foundation that makes regulated-industry deployment legally defensible.

    Building an Agent Governance Stack You Will Actually Use

    Most governance frameworks for AI agents fail not because they are wrong but because they are too heavy to sustain in practice. They produce policy documents that nobody reads and approval processes that get bypassed when deadlines hit. The governance stack that actually works in 2026 has three properties: it is lightweight enough to survive contact with real teams, it is automated enough that compliance doesn’t depend on human memory, and it provides enough visibility that problems surface early rather than late.

    Four Components That Matter

    1. A Task Classification Policy — Written Simply. A single document that lists task categories and their zone classification (using the reversibility/consequence matrix) and the approval required before agents are deployed on each category. This should be one page. If it’s longer, it won’t be used. The key commitment is that this policy is reviewed quarterly as agent capabilities and deployment scope evolve.

    2. Structured Logging at the Action Level. Not just “the agent completed the task” but: what actions did it take, what tools did it call, what decisions did it make, and with what stated reasoning? For Devin, this means PR-level audit trails with full commit history and planning session records. For Kimi, it means task-level logs of which sub-agents ran what steps. For ChatGPT Agent, it means session logs of what sites were visited, what forms were filled, and what data was passed to external connectors. This logging does not happen automatically — it must be configured.

    3. Permission Scoping by Task, Not by Agent. Rather than giving an agent a broad set of permissions and trusting it to use them appropriately, scope permissions to the minimum required for the specific task it’s running. Devin should only have repository access for the repositories it’s working in, not all repositories. ChatGPT Agent should only have connector access for the apps needed for the current workflow. This reduces the blast radius when something goes wrong and limits the value of any transitive trust escalation attempt.

    4. Anomaly Monitoring with Human Alert Routing. Automated monitoring that flags unexpected action sequences — an agent that was tasked with data enrichment suddenly attempting to access an external API it has no task reason to contact — and routes alerts to a named human reviewer with SLA-level expectations for response. This is the feedback loop that turns governance from a policy exercise into an operational reality.

    Where This Is Heading in the Next 12 Months

    AI agent evolution roadmap showing three milestones: multi-day agents mainstream, cryptographic identity standards, and human-agent co-piloting

    The trajectory of all three systems points toward capabilities that will raise new handoff questions — not answer the existing ones. Understanding where things are moving is important for teams designing workflows today, because the governance decisions you make now will need to accommodate architectures that look meaningfully different in 12 months.

    Multi-Day Autonomous Agents Going Mainstream

    Kimi’s K3 already supports multi-day continuous operation. Devin’s parallel instance model and persistent Devin Wiki make extended autonomous engineering cycles increasingly feasible. ChatGPT Agent’s scheduled task infrastructure is expanding. The direction is clear: the expectation that an agent needs to complete a task in a single session is eroding. What replaces it is an architecture where agents operate across days — sleeping, resuming, and continuing — with humans checking in at defined intervals rather than watching continuously.

    This shift changes the governance model significantly. Oversight that worked for session-based tasks (you watch the agent work, you approve before it sends anything) does not scale to multi-day autonomous operation. The governance replacement is checkpoint-based review: defined milestones at which the agent produces a status summary and a human reviews and approves continuation. Teams that build this checkpoint discipline now will not have to retrofit it when multi-day agents are the default.

    Cryptographic Agent Identity Standards

    The “Know Your Agent” identity layer concept — where every agent instance carries a signed, traceable credential through the delegation chain — is moving from research concept toward early implementation in enterprise security tooling. As regulatory pressure on AI accountability increases, the ability to cryptographically prove which agent took which action with which authorization will shift from a competitive differentiator to a baseline compliance requirement in regulated industries.

    This does not mean the three platforms discussed here will natively provide this out of the box in the next 12 months. It means that the governance infrastructure around them will need to implement it — and teams that have established structured logging practices and permission-scoping disciplines will be in a much stronger position to adopt these standards than teams that have been running agents in an ad hoc configuration.

    Real-Time Human-Agent Co-Piloting

    The current interaction model for all three systems is predominantly asynchronous: you assign a task, the agent works, you review the output. The direction in 2026 and into 2027 is toward real-time collaborative interfaces where the human and agent work on a task simultaneously, with the human providing judgment at key decision points while the agent handles execution velocity. Devin’s interactive planning and collaborative IDE already points in this direction. Kimi’s main-agent coordination layer has analogues in how it surfaces task decomposition for human review.

    This co-piloting model is likely to prove more durable than pure delegation — because it preserves the human judgment capacity that pure delegation erodes, while still capturing most of the productivity gains. Teams that invest in understanding how to work alongside these agents effectively, rather than just configuring them to work independently, are building a skill that will remain valuable as the capabilities evolve.

    The Right Way to Think About Handing Off

    Kimi, Devin, and ChatGPT Agent each represent genuine capability advances — not incremental improvements to chatbots, but systems that can take meaningful autonomous action across complex, multi-step workflows in a way that was not possible two years ago. That is real, and the productivity implications for well-designed workflows are significant.

    But the question “what can I safely hand off?” is not answered by reading capability documentation. It is answered by asking four questions about each task you’re considering delegating:

    1. How reversible is the output if the agent is wrong? Not just the task itself — every downstream step that depends on that output.
    2. What is the consequence scope if this fails? Internal friction, or external commitment, financial impact, legal exposure, customer harm?
    3. What does the accountability chain look like? Can you trace, with precision, which agent took which action, with which authorization, at whose direction?
    4. What is your recovery path? Not “what happens if everything works” but “what happens at step 3 when something goes wrong, and who notices, and how fast?”

    Teams that can answer these four questions clearly before deploying an agent are the ones running reliable, scalable, trustworthy agentic workflows. Teams that skip the questions and focus only on what the agent can do are the ones generating the incident reports that get shared at security conferences six months later.

    The threshold for safe handoff is not primarily a question of AI capability. It is a question of workflow design, governance infrastructure, and the disciplined thinking about what failure looks like before it happens. Kimi’s swarm, Devin’s IDE, and ChatGPT Agent’s virtual computer are ready to work. The question is whether the humans configuring them are ready to govern them — and in 2026, that readiness is still the rate-limiting factor for most organizations.

  • Google’s Connected Apps in AI Mode: The Real Operator’s Guide to Wiring Instacart, Canva, and YouTube Workflows

    Google’s Connected Apps in AI Mode: The Real Operator’s Guide to Wiring Instacart, Canva, and YouTube Workflows

    Google AI Mode Connected Apps showing Instacart, Canva, and YouTube Music integrations with search-to-action workflow

    Google Search has answered questions for over two decades. On July 16, 2026, it started completing tasks.

    That is the practical meaning of Connected Apps in AI Mode — a feature that sounds modest in the announcement but represents a fundamental shift in what Search is for. For the first time, a query issued inside Google can ripple outward and do something tangible in a third-party application: fill a grocery cart in Instacart, spin up a design template in Canva, or build a curated playlist in YouTube Music. The user never has to leave the conversation to make it happen.

    This is not Google adding a few shortcut buttons. The architecture underneath Connected Apps — the permission model, the personal context layer, the agent-style task routing — is the foundation for a much broader shift in how Google wants to sit between users and the rest of the internet. The three launch partners are the visible tip; the structural change happening underneath them is what will matter for years.

    This guide covers how each integration actually works from the keyboard forward, where the real friction lives, what the permission architecture allows and explicitly does not allow, and what the agentic expansion means for businesses, developers, and anyone who currently relies on Google Search as a traffic channel. Skip the press release framing. Here is the operator-level picture.

    What “Connected Apps” Actually Means — and Why the Framing Matters

    Before getting into the step-by-step mechanics, it is worth being precise about what this feature is — because the official descriptions can obscure how significant the underlying architecture change actually is.

    From Answer Engine to Task Layer

    Google AI Mode has, since its wider rollout in 2026, operated as a conversational interface layered on top of traditional search. You ask a question in natural language; AI Mode synthesizes an answer drawing on Google’s index and, optionally, your connected personal data. That is the answer-engine model.

    Connected Apps shifts the paradigm. Instead of answering “what ingredients do I need for a BBQ dinner for eight people,” AI Mode now takes the follow-through action: it generates the ingredient list and pushes those items into your Instacart cart. Instead of describing what a good birthday flyer might look like, it opens a Canva template with your brief already baked in. The distinction between generating information and executing an instruction is the dividing line between a search engine and an agent. Google just crossed it.

    Why Three Partners at Launch

    The choice of Instacart, Canva, and YouTube Music as launch partners is not arbitrary. Each one represents a different high-frequency task category: shopping and commerce, content creation, and entertainment curation. Together they let Google demonstrate that the connected-apps architecture works across meaningfully different types of actions — transactional (cart building), creative (design generation), and editorial (playlist curation). They also happen to be partners with whom Google has existing commercial relationships or API infrastructure, making them practical as a first cohort rather than a comprehensive rollout.

    Google has confirmed that more partners are coming. The three at launch should be read as proof-of-concept choices, not the final scope of this capability.

    The Language That Gets Used — and the Language That Gets Avoided

    Google describes Connected Apps as helping users “complete tasks.” What the company does not use prominently in official communications is the word “agentic” — though that is precisely the technical category this feature falls into. An agentic system perceives a goal, breaks it into sub-steps, accesses external tools, and executes actions on behalf of a user. That is exactly what AI Mode does when it takes a meal-planning prompt, consults your Google Calendar for the event date, generates a recipe, and populates an Instacart cart. The careful language choice is almost certainly deliberate: the word “agent” carries connotations of autonomous behavior that Google likely does not want consumers scrutinizing too closely at this stage.

    For operators building workflows around this, understanding what it actually is — an agent acting with delegated permissions in external systems — is essential for both using it effectively and evaluating the trust implications correctly.

    The Permission Architecture: What Google Actually Touches and What It Doesn’t

    Permission architecture diagram for Google AI Mode Connected Apps showing opt-in toggle controls for Gmail, Calendar, Photos, Instacart, Canva, and YouTube Music

    Before you wire anything, you need to understand what you are actually authorizing. The permission model for Connected Apps is layered, and conflating the layers creates either unnecessary anxiety or, more dangerously, misplaced trust.

    Two Separate Permission Systems

    Google AI Mode operates with two distinct categories of data access, and it is critical not to confuse them.

    The first is Personal Intelligence — the opt-in system that allows AI Mode to draw on your Gmail, Google Calendar, Google Photos, and other first-party Google services as context for its answers. This is what lets AI Mode know you have a dinner party next Saturday (because it is in your Calendar) or that you recently ordered a specific ingredient (because it showed up in a Gmail receipt). Personal Intelligence is off by default. You must explicitly turn it on in your Google Account settings, and you can toggle individual services independently.

    The second is Connected Apps — the OAuth-style links to third-party services like Instacart, Canva, and YouTube Music. These are also off by default and require a separate authorization step per app. When you connect Instacart, you are granting AI Mode specific delegated permissions to act inside Instacart on your behalf: in the current implementation, that means the ability to add items to a cart. It does not mean read access to your order history or payment information.

    What Google Says About Training Data

    Google has explicitly stated that data accessed through Personal Intelligence — including Gmail and Photos content — is not used to train AI models. This is a meaningful commitment, and one that mirrors similar assurances made when Workspace AI features were introduced. That said, it is worth noting that these commitments are made in terms of service documents that can be updated, and independent verification of model-training exclusions is not currently feasible for end users.

    For enterprise or professional use cases, particularly those involving sensitive calendar data or business email, this distinction between “context used for task execution” and “data used for training” warrants scrutiny of the specific terms in effect at the time of use.

    Granular Controls and Revocation

    Both Personal Intelligence settings and Connected App authorizations are manageable from a single location in Google Account settings, under the AI Mode or Search personalization section. Each connected app can be revoked independently. When you revoke access, AI Mode loses the ability to act in that app immediately — unlike some OAuth implementations where tokens persist until expiry.

    The practical implication for users who want to experiment without full commitment: you can connect an app, try a workflow, review what was created, and revoke the connection before leaving the session. The task outputs (the Instacart cart, the Canva template, the playlist) persist in the partner app after revocation, but Google’s ongoing access to act in those apps stops.

    The Minimum Viable Permission Approach

    For most personal use cases, the recommended setup is: connect only the apps you are actively using in a session, enable only the Personal Intelligence sources that are actually additive to the task (Calendar for event planning; not necessarily Photos for grocery shopping), and periodically audit your Connected Apps list in settings. This reduces your exposure while preserving the full functionality of the workflows described in the sections below.

    Wiring Instacart: From Meal Intent to a Pre-Filled Cart

    Four-step workflow diagram showing Google AI Mode BBQ planning query converting to a pre-filled Instacart grocery cart for checkout

    The Instacart integration is the most commercially tangible of the three launch workflows, and it is also the one where Google’s personal context layer adds the most visible value. Here is how to set it up and how to prompt effectively.

    Setup: Connecting Instacart to AI Mode

    Navigate to Google Search and switch to AI Mode (accessible via the AI Mode tab or google.com/ai if it is available in your account). Inside the AI Mode interface, look for the settings or apps management panel — typically accessible via a grid icon or “Manage apps” link within the conversation interface. Select Instacart from the available integrations and authorize the connection via Instacart’s OAuth flow. You will need an active Instacart account; the connection works with both free and Instacart+ accounts.

    Once connected, AI Mode will show Instacart as an active integration in your session. You do not need to re-authorize in subsequent sessions as long as you remain logged into the same Google Account and have not revoked the token.

    The Basic Workflow: Prompt → List → Cart

    The workflow Google demonstrated at launch — and the one that works most reliably — follows this sequence:

    1. State a meal or event goal, not just an ingredient request. “Plan a barbecue dinner for eight people this Saturday” produces a significantly better result than “what do I need for a BBQ.” The goal-framing gives AI Mode enough context to generate a complete, proportionally scaled ingredient list.
    2. Review the generated plan. AI Mode will produce a recipe or menu breakdown, often broken into categories (proteins, produce, pantry staples, condiments). This is the point to edit before committing to the cart — you can remove items, add substitutions, or adjust quantities in the AI Mode conversation.
    3. Confirm the cart action. AI Mode will present a summary of items it intends to add to your Instacart cart and ask for confirmation. This is a deliberate friction point — Google built a confirmation step into the flow rather than auto-populating the cart, which is the right call for a commerce-adjacent action.
    4. Finish in Instacart. After confirmation, AI Mode passes the item list to Instacart. You will be directed to your Instacart cart — in the app or on the website — where the items appear pre-populated. Store selection, substitution preferences, delivery scheduling, and checkout all happen within Instacart.

    Where Personal Context Changes the Output

    If you have Google Calendar connected via Personal Intelligence, the Instacart workflow becomes noticeably more useful. When AI Mode can see an upcoming calendar event — say, “Dinner with the Rodriguezes – 7 attendees” on Saturday evening — it can use that event as the guest count for scaling recipes, without you having to specify it. It can also cross-reference the event title or notes for dietary clues if any are present.

    Similarly, if AI Mode has access to Gmail and a previous Instacart order confirmation exists in your inbox, it may reference past purchases to flag items you regularly stock. This behavior is inconsistent in early testing — it works better when the relevant emails are recent and clearly formatted — but when it works, it meaningfully reduces the editing burden on the generated list.

    Prompt Patterns That Work Well

    Specificity on the occasion and constraints produces better outputs than vague food requests. Prompts that perform well include: “Plan a weeknight dinner for four people that takes under 30 minutes to cook, focusing on Mediterranean flavors, and add everything to my Instacart cart.” The combination of guest count, time constraint, and cuisine direction gives AI Mode enough parameters to generate a list that needs minimal editing.

    Dietary constraints work reliably: “gluten-free,” “vegetarian,” “nut-free” all modify outputs correctly in testing. Budget constraints (“under $80”) are supported but less precise — treat them as directional guidance rather than enforced limits at this stage of the product.

    The Handoff Gap: What Instacart Still Controls

    AI Mode hands off a list of items, not a complete order. Instacart’s own systems then match those items to available products from the selected store. This means you may see substitutions, out-of-stock warnings, or slightly different product matches than you intended. The quality of the handoff depends significantly on how specific AI Mode’s item descriptions are — “chicken thighs” will map more cleanly than “protein,” for example. Reviewing the cart in Instacart before checkout is still necessary, particularly for produce and specialty items.

    Wiring Canva: From a One-Line Brief to an Editable Template

    Split screen showing Google AI Mode design prompt on the left and a generated Canva template ready for editing on the right with connected app handoff arrow

    The Canva integration takes a different shape than Instacart’s. Where the grocery workflow is fundamentally about data transfer (a list of items moving from one system to another), the Canva workflow is about intent translation — taking a natural language design brief and converting it into a starting point inside a fully-featured design environment.

    Two Distinct Entry Points

    The Canva connection in AI Mode supports two different workflows, and they serve different purposes.

    The first is template discovery and launch: you describe a design need — a birthday invitation, a social media graphic, an event flyer — and AI Mode surfaces Canva templates that match the brief, then opens your chosen template directly inside Canva. This is essentially a turbocharged version of Canva’s own internal search, with the advantage that you can describe your need conversationally rather than navigating Canva’s template library manually.

    The second is AI image export: if AI Mode generates an image in response to a visual prompt (which it can do natively using Google’s image generation models), you can export that generated image directly into a Canva project as a design asset. This is useful for content creators who want to use AI-generated imagery as a foundation for further design work without a separate download-and-upload cycle.

    Connecting Canva to AI Mode

    The setup mirrors the Instacart flow. In AI Mode, open the apps management panel and authorize Canva via OAuth. You will need an active Canva account — the integration works with both free and Canva Pro accounts, though Pro users have access to the full template library and Brand Kit integration. Once connected, AI Mode recognizes Canva-specific requests and routes them appropriately.

    Prompt Patterns for Design Workflows

    Canva prompts work best when they include three elements: the format, the occasion or purpose, and at least one style or aesthetic signal. “Create a birthday party invitation flyer in a modern minimalist style” will produce more useful template matches than “make me an invite.” The format specification (flyer, Instagram post, presentation slide, LinkedIn banner) maps directly to Canva’s template categories, which influences what gets surfaced.

    For professional or brand-consistent work, including color palette or brand name in the prompt can help — particularly if you have a Canva Pro account with a Brand Kit configured, as the handoff can sometimes route into brand-consistent templates. This behavior is not yet fully reliable but appears to be improving.

    Some examples of prompts that perform well in testing:

    • “Design a promotional banner for a weekend sale, Instagram square format, bright colors, playful font — open in Canva.”
    • “Create a pitch deck title slide for a fintech startup, clean corporate look, blue and white palette.”
    • “Generate an image of a cozy coffee shop in autumn and export it to Canva so I can add text.”

    The Editing Handoff: What Canva Receives

    When AI Mode routes a design request to Canva, what lands in Canva is a template in the editing state — meaning it is fully editable, with placeholder text and image areas available for customization. AI Mode does not currently write copy into the Canva template (that is, it will not pre-fill your event date, location, or personalized text into the design). That editing still happens inside Canva. The value of the integration is primarily in collapsing the discovery and setup steps: instead of opening Canva, searching templates, and browsing results, you arrive at the right starting point from a single conversational prompt.

    For teams or frequent Canva users, this is a meaningful time saving, particularly for repetitive design tasks like weekly social graphics, recurring event announcements, or newsletter headers. The use case shines most for people who know roughly what they want but find template browsing friction-heavy.

    What Canva Pro Adds to the Workflow

    Canva Pro’s Brand Kit — which stores brand colors, fonts, and logos centrally — works within the connected-app workflow in a limited but useful way. When a Pro account is connected and a brand-relevant request is made, there is early evidence that AI Mode attempts to route to templates compatible with the Brand Kit configuration. This is not consistent enough to rely on for high-stakes brand work without human review, but for rapid first-draft generation, it reduces the “brand alignment” editing step.

    Wiring YouTube Music: Prompt-Driven Playlists and the Listening History Advantage

    The YouTube Music integration is structurally simpler than Instacart or Canva but arguably showcases the personal context layer most vividly. The core function is playlist creation from a natural language description, but the sophistication of the output scales sharply with how much listening context AI Mode has access to.

    Two Paths to AI Playlist Creation

    It is worth distinguishing between two related but separate AI playlist systems, because they are easy to conflate.

    The first is AI Playlist inside YouTube Music directly: within the YouTube Music app (or website), there is a native AI playlist feature available to YouTube Music Premium subscribers. You access it via Library → New → AI Playlist, describe the mood or occasion, and the app generates a playlist without leaving YouTube Music. This uses Gemini models under the hood but operates entirely within YouTube Music’s own interface.

    The second is AI Mode Connected App workflow: from within Google Search’s AI Mode, you can describe a playlist and have it created and saved to your YouTube Music library via the connected-app link. This second path is what falls under the Connected Apps feature announced in July 2026, and it adds the possibility of using cross-app context (Calendar events, activity in other connected apps) to inform the playlist creation.

    Setup and Connection

    Connect YouTube Music in AI Mode via the same apps management panel. Note that full AI playlist functionality requires a YouTube Music Premium subscription; basic users can create playlists but may find that some features — particularly those leveraging listening history for personalization — are limited or unavailable.

    Once connected, ensure that YouTube Music listening history is enabled in your Google Account (this is the data that powers the personalization layer). If listening history is paused, AI Mode can still create playlists, but they will be based on the described criteria alone rather than your personal listening patterns.

    Prompt Strategies: Genre, Mood, Occasion, and Energy Level

    YouTube Music AI playlist prompts work along four primary axes, and using multiple axes together substantially improves the output quality:

    • Mood: energetic, mellow, contemplative, celebratory, melancholic
    • Occasion: workout, dinner party, study session, road trip, morning commute
    • Genre or era: 90s R&B, indie folk, classical piano, late-night jazz, 2020s pop
    • Energy curve: “starts slow and builds,” “consistent high energy,” “winds down toward the end”

    A prompt like “a playlist for a long drive through desert landscapes, mostly instrumental, a mix of ambient electronica and post-rock, that gradually builds energy over two hours” will produce a substantially more coherent result than “road trip music.” The additional parameters are not just style preferences — they map to Gemini’s understanding of both musical structure and your listening history to weight the selections.

    Where Listening History Changes Everything

    The most significant differentiator for the YouTube Music integration versus any generic AI playlist tool is the listening history access. When AI Mode can see your actual listening patterns — what you return to, what you skip, how your tastes vary by time of day or day of week — the playlist output shifts from a generically competent selection to something that feels tailored. Heavy users of YouTube Music who have a rich listening history available will notice this most acutely; casual listeners may find the base quality of the output without personalization entirely adequate.

    The privacy note here: listening history data used for playlist personalization falls under the Personal Intelligence opt-in framework. If you have not explicitly connected YouTube activity as a personal context source, AI Mode will generate playlists based on prompt criteria only, without the listening history layer. Both modes are useful; which you choose depends on your comfort level with that data being accessed.

    Saving, Sharing, and Iterating

    Generated playlists land in your YouTube Music library and are immediately playable. From there, you can edit the tracklist directly in YouTube Music, add or remove songs, change the playlist name, and share via standard YouTube Music sharing links. The AI-generated playlist is not locked or read-only — it behaves identically to any manually created playlist once it is in your library.

    Iterative refinement also works. If the initial playlist misses the mark, you can follow up in the AI Mode conversation: “Remove anything with vocals” or “Add more tracks from the early 2000s” will trigger a revision. This conversational refinement loop is one of the cleaner UX experiences in the current implementation.

    Cross-App Workflows: When All Three Work Together

    Most early coverage of Connected Apps treats each integration in isolation. The more interesting — and currently underexplored — territory is what happens when all three are active simultaneously, combined with Google Calendar’s personal context. Here are three practical cross-app scenarios that illustrate the actual potential.

    Scenario 1: The Event Planning Stack

    You have a dinner party in Google Calendar next Saturday evening, eight guests, tagged “Italian theme.” With Calendar connected via Personal Intelligence, Instacart connected, Canva connected, and YouTube Music connected:

    • A single prompt — “Help me plan Saturday’s dinner party” — can kick off a multi-branch workflow: AI Mode generates an Italian menu scaled for eight, adds ingredients to Instacart, suggests a mood-appropriate playlist for a dinner party atmosphere in YouTube Music, and offers to create a “Welcome” table card design in Canva.
    • Each branch is confirmed separately before action is taken. You are not handed a completed plan with no review; you are offered a structured set of actions that you approve or modify at each step.

    This is a genuine demonstration of agentic behavior across multiple systems, and it works today — not as a future roadmap item.

    Scenario 2: The Content Creator’s Rapid Production Loop

    A social media manager needs to produce assets for a product launch campaign. With Canva connected and AI Mode’s image generation active:

    • They describe the campaign in AI Mode: “Product launch for a new espresso machine, modern brand aesthetic, earthy tones, Instagram-first.”
    • AI Mode generates a hero image and exports it to Canva as a base asset.
    • They request a set of matching social graphics in different formats (story, square post, banner) and AI Mode routes template discovery for each format into Canva with the same brief applied.
    • A background playlist for the creative session — “focus music for a design sprint, lo-fi and instrumental” — gets created in YouTube Music simultaneously.

    The time saving here is not dramatic in per-task seconds but in context-switching cost. Keeping a complex creative brief alive across three production tools without re-entering it multiple times has measurable productivity value for creative teams running multiple campaigns in parallel.

    Scenario 3: Weekly Meal Planning at Scale

    For households that run structured weekly meal plans, the Instacart integration combined with Calendar has a recurring-use case that compounds in value. Set up a repeating pattern: each Sunday, ask AI Mode to “plan five weeknight dinners for the week, incorporating any dinner events on the calendar, and add the full ingredient list to Instacart.” The Calendar context prevents double-ordering for nights already covered by restaurant plans or social events. The grocery list generated covers only the cooking nights that actually need provisioning.

    This workflow benefits most from the memory-adjacent behavior that emerges when AI Mode can reference recent Gmail order confirmations — it can, in some cases, identify items already in your typical shopping rotation and focus the generated list on the incremental items you actually need.

    Where the Friction Actually Lives

    Diagram showing five friction points in Google AI Mode Connected Apps: US-only rollout, only 3 apps at launch, half-finished handoffs, compute-gated responses, and privacy complexity

    No honest evaluation of a feature this new avoids the limitations. Here is where Connected Apps actually breaks down, frustrates users, or underdelivers relative to the promise.

    Geographic Gating

    As of July 2026, Connected Apps in AI Mode is available only in the United States, in English. Users outside the U.S. — including regions where AI Mode itself is available — do not yet have access to the third-party app connections. This is a significant constraint for a global platform, and while Google has not given a specific timeline for international expansion, the pattern from AI Mode’s own rollout suggests a phased geographic expansion is likely but will take quarters, not weeks.

    The Half-Finished Handoff Problem

    Across all three integrations, the flow ends inside the partner app rather than completing inside Google. This is partly by design — checkout, brand editing, and music listening all happen in the apps that built them — but it creates a user experience that feels fragmented at the last step. You build a cart in AI Mode and then transfer to Instacart for checkout; you get a template opened in Canva but still do all the text editing there; you get a playlist but manage it in YouTube Music. The value is in the setup and discovery stages; the execution still requires leaving the AI Mode context.

    For users who expected a fully contained “I asked for it in Google, it’s done in Google” experience, this limitation is disappointing. For users who understand that partner apps exist for good reasons (their specialized UI, their checkout infrastructure, their full feature sets), it is a reasonable tradeoff. Setting expectations correctly when describing the feature to new users matters.

    Compute-Gated Response Times and Usage Limits

    AI Mode queries involving personal context and multi-app actions are significantly more computationally intensive than standard AI Mode answers. In practice, this means response times for complex connected-app prompts can be 5–15 seconds, which is noticeably slower than the snappy answers users are accustomed to from Google Search. During peak usage periods, this can extend further.

    Additionally, AI Mode operates under compute quotas — heavy users may encounter limits on how many complex multi-app queries they can run in a given session or day. These limits are not publicly documented in precise terms, which creates an inconsistent experience when they appear.

    Personalization Errors from Personal Context

    The personal context layer adds value in the best cases, but it introduces a new failure mode: when AI Mode incorrectly interprets a Gmail message, Calendar entry, or Photos content, the downstream task action can be based on faulty premises. A calendar event titled ambiguously, or a receipt email that doesn’t parse cleanly, can cause AI Mode to generate a plan that misses the actual intent.

    The practical mitigation is to review AI Mode’s stated reasoning before approving any cart action or design routing. When AI Mode explains what context it used (“Based on your Saturday calendar event for 7 guests…”), verify that interpretation before confirming. The confirmation step exists precisely for this reason.

    Limited App Coverage at Launch

    Three apps is a narrow integration surface. Many of the most obvious candidates — grocery alternatives to Instacart, design tools beyond Canva, streaming services beyond YouTube Music, booking platforms, productivity apps — are not yet connected. The more you look at the potential scope of what Connected Apps could eventually do, the more the current three-app implementation feels like a minimal viable launch rather than a mature platform.

    This is not a criticism of the feature as shipped; it is an accurate characterization of where it stands. Businesses and developers who want to understand the trajectory should watch the partner announcement cadence over the next two quarters carefully.

    What Connected Apps Does to Search Traffic, SEO, and the Publisher Equation

    Data visualization showing approximately 93% of AI Mode sessions ending without a click, with diverging trend lines for declining blue link CTR versus rising citation visibility opportunity

    Connected Apps does not exist in isolation. It is one component of a broader AI Mode architecture that is materially changing where users go — and crucially, whether they go anywhere at all — when they issue a query to Google.

    The Zero-Click Acceleration

    Research tracking AI Mode behavior in 2026 suggests approximately 93% of AI Mode sessions end without a click to an external website. That figure represents a qualitatively different challenge than the zero-click problem that AI Overviews introduced for informational queries. AI Overviews answer questions and the user stops there. Connected Apps answers questions and takes action — the entire user journey from intent to task completion occurs within Google’s interface and partner apps, bypassing the open web entirely.

    For publishers whose traffic depends on Google Search referrals for transactional or task-oriented content — recipe sites, product comparison pages, how-to guides that feed affiliate commerce — this is the more serious structural threat. The queries that previously drove high-intent clicks to external properties (“best recipe for a BBQ chicken dinner for 8”) are precisely the query types that Connected Apps is designed to absorb and complete.

    What Changes for Brands That Are Partner Apps

    For Instacart, Canva, and YouTube Music, being a Connected App is a distribution advantage that is hard to overstate. Each has essentially bought a placement at the most valuable moment in the consumer journey — the moment of intent formation inside Google Search. Users who would previously have moved from Google to Instacart via a click now arrive inside Instacart with a pre-built cart, a significantly higher-conversion starting point than an organic search click. The economics of being inside the agentic flow are structurally superior to any paid search or organic traffic strategy.

    For businesses in categories not yet covered — other grocery services, other design tools, other music platforms — the question is not whether to become a Connected App partner but how urgently to pursue it. Google has not published an open API or partner program application; the initial cohort appears to be by direct partnership arrangement. Monitoring official developer channels and Google partner announcements is the practical path for businesses that want to position for the next cohort.

    The Citation Visibility Counter-Strategy

    For publishers who are not positioned to become Connected App partners, the emerging counter-strategy is to optimize for citation inside AI Mode answers rather than clicks from AI Mode answers. When AI Mode generates a recipe plan before handing off to Instacart, it may cite sources for the recipes it uses. When it explains a design principle before opening Canva, it may reference relevant educational content. These citation appearances drive lower traffic volume than traditional search clicks, but qualitatively different behavior — users who follow a citation from an AI Mode answer tend to be higher intent and better informed than average organic visitors.

    The practical moves for publishers: structure content explicitly for AI citation (clear, factual, well-attributed, semantically organized); build brand recognition that makes citations more likely; and shift success metrics away from session volume toward lead quality, citation frequency, and brand search volume as proxy measures.

    The Developer API Question

    The most significant open question for the broader business ecosystem around Connected Apps is whether Google will publish a developer API that allows any app to integrate into the Connected Apps framework, or whether the system will remain a curated set of partnerships. A closed-partnership model concentrates the agentic distribution advantage with a small number of large platforms. An open API model creates a new category of competitive surface for app developers — and a new form of Google platform dependency risk.

    Google has not made a public commitment either way as of the July 2026 launch. The language in Google’s developer communications suggests openness to a broader ecosystem over time, but nothing has been confirmed. This is the most consequential strategic unknown in the Connected Apps story, and it deserves close attention from anyone building products that depend on Search-originating traffic.

    What’s Coming Next: Reading the Roadmap Signals

    Google rarely launches a product feature with a single cohort and no expansion plan. Several signals from the July 2026 launch and the surrounding announcements point clearly toward where Connected Apps is heading.

    More App Categories, Likely This Year

    The three launch categories — commerce, creative, entertainment — are deliberately varied. The next wave of expansions most likely targets: restaurant reservations (OpenTable and competitors have been mentioned in Google’s broader AI commerce initiatives), travel and booking (Hotels, flights, and Airbnb-style properties are natural fits for the task-completion model), and productivity tools (where Google’s own Workspace apps are the obvious first expansion, potentially followed by external productivity platforms). Home automation and smart device control have also been referenced as a category Google is exploring for AI Mode integrations.

    The Universal Cart Ambition

    Separate from Connected Apps but architecturally adjacent, Google has been developing what internal teams have described as a “Universal Cart” concept — a persistent, AI-managed shopping aggregator that can hold items from multiple retailers simultaneously and optimize for price, availability, or delivery speed before routing to checkout. If that architecture matures, the Instacart integration would become one input into a multi-retailer layer rather than a single-partner integration. This would substantially change the commerce dynamics for every retail partner involved.

    Gemini as the Cross-Surface Agent

    The underlying model powering all of these integrations is Gemini, and the trajectory of Gemini’s deployment across Google surfaces — Search, Gmail, Workspace, Android, Chrome, the Gemini standalone app — points toward a future where the same agentic capabilities available in AI Mode are available everywhere in Google’s ecosystem simultaneously. A Canva task started in Gmail, continued in AI Mode, and finalized on an Android device is a near-term possibility given the infrastructure already in place. The Connected Apps framework, in this light, is the beginning of a cross-surface agent system rather than a Search-specific feature.

    Competitive Pressure From Elsewhere

    Google is not building this in a vacuum. OpenAI’s ChatGPT Connectors, Microsoft Copilot’s plugin ecosystem, and Anthropic’s tool-use capabilities in Claude all represent parallel attempts to become the agentic layer between users and their most-used applications. The race to occupy the “front door to apps” position in the AI era is multi-competitor, and the trajectory of each platform’s partner ecosystem will influence which users develop workflow habits around which agent interface. Google has an advantage in starting from inside Search — the highest-traffic user intent surface in existence — but that advantage is not permanent if competitors build more functional or broader integration ecosystems faster.

    How to Position Yourself for This Shift — Practical Next Steps

    Across the different audiences reading this — regular users, content creators, business operators, developers, and publishers — the practical implications differ substantially. Here is a structured way to think about positioning.

    For Individual Users: Get Connected, Then Get Selective

    The lowest-risk way to engage with Connected Apps is to connect one integration at a time, try it on a real task, and evaluate whether it genuinely saves time versus using the app directly. For meal planning around events, the Instacart integration has a strong enough use case to test immediately. For design-heavy workflows, the Canva integration adds value primarily if template discovery is your bottleneck. For music curation, YouTube Music’s own native AI playlist features may be sufficient without the AI Mode layer, particularly if you are not a heavy Google Calendar user.

    Start with the minimum permissions needed for each workflow and expand if you find the personal context layer genuinely additive rather than just theoretically useful.

    For Content Creators and Marketers: Rethink the Creative Brief Process

    The Canva integration specifically has implications for how creative briefs are developed and executed. If a single natural-language prompt in Google AI Mode can produce a functional starting template in Canva within seconds, the cost-per-first-draft for social and marketing content drops materially. The practical opportunity is to build prompt templates — structured, reusable descriptions of your typical content formats — and run them through AI Mode as a systematic first-draft production step, reserving designer time for refinement and brand-critical work rather than blank-canvas starts.

    For Business Operators: Watch the Partner Expansion

    If your business is in a category adjacent to the launch partners — food and beverage, retail, design services, media — the question of whether and how to pursue a Connected Apps partnership deserves strategic consideration now, not after a broader rollout makes the competitive environment more crowded. Google’s developer relations and partner program teams are the right contact points. Even if you cannot become a Connected App immediately, understanding what the partner criteria and integration architecture requirements are will let you build toward it.

    For SEO and Digital Marketing Professionals: Expand the Success Metric Stack

    The 93% no-click rate in AI Mode is not something that can be optimized around with traditional SEO tactics. Chasing blue-link rankings for the query types AI Mode is absorbing is increasingly a diminishing-return investment. The expansion of the success metric stack — adding brand mention tracking, AI citation monitoring, branded search volume, and direct traffic as leading indicators alongside organic session counts — is not optional for professionals advising clients in categories affected by AI Mode’s task-completion sweep.

    For Developers: Start Building for Agent Compatibility

    Regardless of whether a public Connected Apps API materializes, building products that are agent-compatible is table stakes for anything launching in 2026 and beyond. That means: structured data that AI systems can read cleanly, clear action semantics (what your app can do, not just what it contains), OAuth flows that support granular permission scoping, and event-level data models that let agents understand task completion states. These are the architectural characteristics of apps that will integrate cleanly into agentic frameworks — Google’s or anyone else’s — when the API surfaces become available.

    Conclusion

    Google’s Connected Apps in AI Mode is a genuinely significant change in what Search does — not in what it answers. The shift from a query-response architecture to a query-action architecture has been discussed in theory for years; it is now a product that real users in the United States can enable today for grocery shopping, design creation, and music curation.

    The three launch partners are a proof of concept, not a ceiling. The permission model is more carefully designed than initial press coverage suggested — opt-in, revocable, with explicit commitments about training data exclusions. The friction is real and documented: geographic limitations, half-finished handoffs, compute-gated response times, and a three-app integration surface that is narrow for the scale of the ambition.

    But the trajectory is clear. Search is becoming a task layer. The apps that end up inside that layer will have a distribution advantage that compounds over time as users build habits around it. The publishers and businesses that treat this as a traffic metric problem will misread what is actually at stake. What is actually at stake is where the front door of the internet sits — and Google just made a significant move to ensure it sits inside AI Mode, with a connected app on the other side of every intent.

    The operators who understand that distinction early — and who build their content, products, and partnerships accordingly — will be better positioned than those who wait for the full scale of the shift to become impossible to ignore.

  • Amazon’s Expanded Video Ad Ecosystem: What the New SBV, Prime Video, and Twitch Placements Actually Change for Advertisers in 2026

    Amazon’s Expanded Video Ad Ecosystem: What the New SBV, Prime Video, and Twitch Placements Actually Change for Advertisers in 2026

    SBV, Prime Video, and Twitch combined video advertising ecosystem in 2026

    For most of its history, Amazon’s video advertising story was simple: put a short autoplay clip into shopping search results, point it at your product detail page, and let the purchase intent of the search context do the heavy lifting. Sponsored Brands Video (SBV) was efficient precisely because it was narrow — a single-surface, purchase-ready placement where budget efficiency was almost guaranteed.

    That story changed in 2026. Amazon’s video ad stack now spans three meaningfully different surfaces — SBV in search, Prime Video’s ad-supported streaming tier, and Twitch’s live-content ecosystem — and the way these surfaces interact has created both significant opportunity and significant confusion for advertisers who haven’t recalibrated their thinking.

    This isn’t a change at the margin. Prime Video now delivers over 315 million monthly ad-supported viewers globally, with 130 million in the U.S. alone. SBV now accounts for approximately 58% of total Sponsored Brands ad spend across many advertisers. Twitch offers CPMs that are materially below the rest of the Amazon video stack, but with audience profile and interaction mechanics that work differently from anything else on the platform. Together, these three surfaces form something that hasn’t existed on Amazon before: a genuine full-funnel video environment with closed-loop purchase attribution across all layers.

    What changes when that’s true? Quite a lot. Budget logic changes. Creative requirements diverge sharply across surfaces. Measurement frameworks that worked in a search-only video context break down. Attribution models built on last-click radically undercount the contribution of upper-funnel placements. And the audience targeting possibilities, because all three surfaces run on Amazon’s first-party purchase data, create combinations that no other platform can currently replicate.

    This post works through what’s actually different, what the data says about each surface, and how advertisers need to think about the combined stack — not surface by surface, but as a connected system with distinct roles for each channel.

    SBV’s New Footprint: From Search Rows to a Wider Discovery Surface

    Amazon Sponsored Brands Video placement expansion showing 58% of Sponsored Brands spend is now video with 42% CTR increase

    Sponsored Brands Video entered 2026 as the dominant format within the Sponsored Brands product — not because Amazon mandated it, but because advertiser performance data pushed it there. SBV now accounts for roughly 58% of total Sponsored Brands spend across many accounts, a shift driven by consistently higher click-through rates and conversion performance compared to static creative alternatives.

    Where SBV Actually Appears Now

    SBV’s core placement remains the shopping results row: autoplay video ads appearing above, alongside, or within search results on both desktop and mobile, triggered by keyword and product targeting. That foundation hasn’t changed. What has changed is how Amazon treats that placement in the broader context of its video inventory.

    In 2026, Amazon introduced a dedicated video-only Sponsored Brands creative type under the Grow Brand Impression Share goal, which is explicitly eligible for top-of-search placements only. This matters because it separates SBV’s placement auction from standard Sponsored Brands, giving video campaigns their own bidding and targeting logic without competing directly with image-based SB formats for the same inventory slice.

    Beyond core search rows, SBV now surfaces in several additional contexts that didn’t exist two years ago. These include placement within Amazon’s AI-powered discovery surfaces — including the Rufus AI shopping assistant, which has begun incorporating video assets into product recommendations — and vertical video inventory that mirrors the autoplay streaming behavior familiar from social platforms. For mobile users in particular, this creates a video experience that feels less like a search ad and more like a discovery feed.

    The Performance Numbers Behind the Shift

    Amazon’s own case studies document the impact clearly. HP’s SBV campaigns showed impressions growing 224% year-over-year with a 142% YoY increase in clicks and a 42% improvement in clicks specifically for Sponsored Brands video placements. These aren’t outliers — they reflect a broader pattern of SBV outperforming static alternatives on almost every engagement metric when creative quality is controlled for.

    The practical implication for campaign structure is significant. Advertisers running Sponsored Brands campaigns with primarily static or store spotlight creatives should now treat SBV as the default starting point, not an optional add-on. The question has shifted from “should I use SBV?” to “which surfaces should my SBV be optimized for, and how does it connect to what I’m running on Prime Video and Twitch?”

    Vertical vs. Horizontal: A Creative Fork in the Road

    One structural change that deserves specific attention: SBV now supports both horizontal and vertical video assets. Horizontal (16:9) remains the standard for desktop search results. Vertical (9:16) is increasingly served in mobile placements and the discovery feed surfaces that Amazon has been quietly expanding.

    Most advertisers haven’t adapted. The majority of SBV assets in circulation are horizontal, cut from brand videos originally produced for other purposes. Advertisers who invest in native vertical SBV creative for mobile placements are finding materially better performance in those inventory types — largely because vertical video occupies significantly more screen real estate on mobile devices and doesn’t require the viewer to mentally re-frame a landscape-oriented asset.

    Prime Video’s Ad Tier by the Numbers — The Scale That Changes Everything

    Prime Video ad-supported tier reaches 315 million monthly viewers globally with 130M+ in the US

    When Amazon introduced ads to Prime Video in January 2024, the initial advertiser reaction was cautiously optimistic but uncertain. The inventory was new, CPMs were untested, and the question of whether premium streaming viewers would tolerate advertising — or would simply upgrade to the ad-free tier — was unresolved.

    In 2026, those questions have answers, and the answers are meaningful.

    The Audience Reality

    Prime Video’s ad-supported tier now reaches over 315 million monthly viewers globally, up from approximately 200 million in April 2024 — representing roughly 58% growth in under two years. In the United States specifically, Amazon reports 130 million monthly viewers in the ad-supported tier, up from 115 million a year earlier.

    The demographic profile of this audience matters as much as its size. An estimated 88% of Prime Video ad-supported viewers are also active Amazon shoppers. This is the stat that separates Prime Video from every other streaming ad platform: it’s not just reach, it’s reach among people whose purchase behavior Amazon has directly observed and can use for targeting and attribution.

    For comparison, a brand running the same creative on a traditional broadcast or cable network reaches viewers whose shopping behavior is entirely opaque. On Prime Video, Amazon can tell you not just how many people saw the ad, but how many subsequently searched for the brand, viewed the product detail page, added to cart, and completed a purchase. That closed loop is the structural advantage that justifies Prime Video’s premium CPM.

    The CPM Reality

    Prime Video CPMs in 2026 range from approximately $25–$45 for standard inventory, with premium placements around tentpole content — Thursday Night Football, original series premieres, and live events — reaching $40–$65. Guaranteed inventory runs at mid-$30s CPMs; preemptible placements are available in the low-$30s range. Q1 2026 saw CPMs approximately 18% below the Q4 2025 peak, suggesting that initial premium pricing is being absorbed by increased inventory supply as Amazon scales the ad tier.

    These CPMs are meaningfully above what most advertisers pay for SBV in search results, which creates a real budget allocation question. The answer isn’t that Prime Video is more expensive and therefore less efficient — it’s that Prime Video and SBV are measuring different things, and comparing their CPMs directly is like comparing the cost of a billboard to the cost of a search keyword.

    Brand Lift Performance

    Amazon’s own data on Prime Video brand lift is strong, and while advertisers should always apply appropriate skepticism to platform-supplied metrics, the directional signals are consistent across multiple documented cases. Prime Video campaigns show 2.3x higher ad awareness compared to standard video ad campaigns. Brand favorability lifts 4x. Purchase intent lifts 3x.

    Interactive video formats add another layer: interactive ads on Prime Video have driven +30% brand awareness and +36% orders versus non-interactive control groups. These numbers reflect not just passive viewing but active engagement — viewers using their remotes to interact with pause screen ads, QR codes, or shoppable overlays are expressing a level of intent that standard impression delivery can’t capture.

    Ad Load and Frequency Management

    Prime Video’s ad load runs approximately four to six minutes of ads per hour of content. For context, traditional broadcast television runs 14–16 minutes per hour; premium cable runs 8–10 minutes. Prime Video’s lighter load is a deliberate choice to preserve perceived content quality, but it also constrains total inventory supply — which is one reason CPMs remain at premium levels rather than normalizing downward quickly.

    Frequency management has become an important operational concern as Prime Video inventory scales. Because 88% of viewers are active Amazon shoppers with unified profiles, it’s technically possible to reach the same person across Prime Video, Sponsored Brands, Sponsored Display, and Sponsored Products within a single day. Without frequency caps that account for the full cross-surface view, advertisers risk burning through budget against an audience that has already seen their messaging multiple times.

    Twitch’s Unique Role: Not Just Smaller Prime Video

    Twitch vs Prime Video advertising comparison showing CPM ranges, audience demographics, and shared Amazon measurement capabilities

    Twitch occupies an unusual position in Amazon’s video ad ecosystem. It’s smaller than Prime Video by most reach metrics, commands lower CPMs, and targets a meaningfully different audience. But characterizing it as “lower-tier” misreads what Twitch actually does for advertisers who understand the platform.

    What Makes Twitch Different

    The fundamental difference between Twitch and Prime Video as an ad environment is the nature of the viewing experience. Prime Video viewers are leaned back, passively watching scripted or unscripted content they’ve chosen. Twitch viewers are actively engaged with a live stream, often simultaneously participating in chat, watching gameplay or IRL content, and reacting to what they’re seeing in real time.

    This creates an entirely different attention dynamic for advertising. A standard pre-roll or mid-roll on Prime Video interrupts a passive experience that the viewer expects to resume. A pause screen ad or interactive overlay on Twitch surfaces during a moment when the viewer is already in an active, responsive state. The interaction mechanics are different. The emotional register is different. The creative that performs on Prime Video is not the same creative that performs on Twitch.

    Twitch CPMs and Audience Profile

    Twitch CPMs in 2026 sit in the $12–$22 range for standard video placements, with non-interruptive overlay formats available at $4–$10+ CPM depending on placement and seasonality. This is materially below Prime Video’s pricing, but the audience profile commands a different kind of value.

    Twitch skews younger (18–34 is the dominant age band) and male-skewed relative to Prime Video, with heavy indexing in gaming, tech, entertainment, and lifestyle categories. For brands targeting these demographics, Twitch’s lower CPMs with precise contextual targeting can deliver cost-efficient reach that would be significantly more expensive on other premium video platforms.

    Critically, Twitch viewers are still connected to Amazon’s purchase data infrastructure. A viewer engaging with a Twitch ad can be attributed back to subsequent Amazon purchases with the same closed-loop accuracy as Prime Video — a capability that no other gaming or live-streaming platform can match.

    Twitch-Specific Ad Formats

    Amazon has been expanding Twitch’s ad format portfolio in ways that reflect the platform’s live, interactive nature rather than simply porting TV ad formats onto a gaming stream. The current active format slate includes:

    • Pause screen ads: Display or video ads that surface when a viewer pauses the stream, capturing attention during a deliberate moment of re-engagement without interrupting live content.
    • Pre-roll and mid-roll video: Standard interruptive video with skippable and non-skippable variants, primarily relevant for broad-reach objectives.
    • Interactive overlays: Non-interruptive units that appear over the stream, allowing viewers to interact with branded content, polls, or commerce actions without leaving the stream.
    • Shoppable livestream formats: Early-stage interactive units that allow viewers to browse and purchase products directly during creator-led commerce streams, integrating creator content with Amazon’s catalog.

    Amazon has also introduced a sentiment analysis tool for Twitch chat tied to sponsored content — a capability that allows advertisers to see how a live audience reacts to branded moments in real time. This is genuinely novel: it’s the first Amazon advertising measurement tool that captures audience sentiment rather than just behavioral signals.

    The New Placement Hierarchy: How SBV, Sponsored TV, and DSP Actually Interact

    One of the most consistent sources of confusion in 2026’s Amazon video stack is the relationship between its three primary video buying paths: Sponsored Brands Video (a self-serve, auction-based product), Sponsored TV (a self-serve CTV product that buys Prime Video and streaming inventory), and Amazon DSP (a programmatic platform that can access all of the above plus third-party inventory).

    These aren’t interchangeable. Understanding what each layer does and where it sits in the funnel is essential for structuring a coherent strategy.

    Sponsored Brands Video: The Search Performance Layer

    SBV operates in keyword and product-targeted auctions within Amazon’s search results. It’s the lowest-funnel video format in the stack — reaching shoppers who are actively searching for relevant products and are therefore closest to purchase. SBV should be evaluated on ROAS, conversion rate, and new-to-brand customer acquisition metrics. It’s the layer where video drives direct, measurable commerce outcomes in the shortest attribution window.

    Sponsored TV: The Self-Serve Streaming Layer

    Sponsored TV allows brands to buy video inventory across Prime Video, Freevee, Fire TV, Twitch, and third-party streaming apps via a self-serve interface, typically with lower minimum commitments than DSP. It’s positioned between pure-performance SBV and the high-investment DSP layer, making it accessible to mid-market brands that want streaming video reach without an enterprise-level managed service commitment.

    Sponsored TV is optimized for reach and brand awareness metrics rather than direct conversion. Measurement is primarily through Amazon Brand Lift studies, search lift reports, and new-to-brand metrics tracked via Amazon Marketing Cloud.

    Amazon DSP: The Full-Stack Programmatic Layer

    DSP provides access to the full Amazon video inventory plus partner publisher networks, with advanced audience segmentation, sequential messaging capabilities, and the deepest integration with AMC for cross-campaign measurement. DSP campaigns on Prime Video and Twitch can be coordinated with SBV campaigns to create sequenced messaging — for example, serving a brand awareness video on Prime Video to a defined audience segment, then targeting that same segment with SBV in search results 24–72 hours later.

    This sequencing capability is arguably the most powerful feature of the combined stack. It mirrors the way broadcast TV + radio retargeting worked in traditional media, but with first-party purchase data enabling attribution that was impossible in analog media environments.

    Creative Requirements Have Diverged — What Works on Which Surface

    Three different creative strategies required for SBV search ads, Prime Video shoppable ads, and Twitch interactive ads

    The single most underestimated implication of Amazon’s expanded video stack is what it demands from creative production. Many advertisers are attempting to run one video asset across all three surfaces, then wondering why performance is inconsistent. The problem is structural: SBV, Prime Video, and Twitch require fundamentally different creative approaches because they reach viewers in fundamentally different mental states.

    SBV Creative: Product-First, Decision-Optimized

    SBV viewers are in search mode. They typed a query, and a video interrupted their results row. They are not there to be entertained — they are there to find the right product. SBV creative that works leads with the product, demonstrates a clear benefit or differentiator in the first two seconds, and gets to a reason to click before the viewer scrolls past.

    Effective SBV lengths run 15–30 seconds. Auto-captions are essential because most search browsing happens with audio off. Background should be simple and product-forward. The call to action should be explicit. Any storytelling or brand narrative should be compressed to the final few seconds, after the product case has been made.

    Amazon’s technical specs require SBV assets to be 6–45 seconds in length, 16:9 or 1:1 aspect ratio (with 9:16 now available for mobile placements), and a minimum resolution of 1920×1080 for horizontal. Importantly, logos or text cannot appear in the bottom 14 pixels of the frame, where Amazon’s branding and pricing overlay appears.

    Prime Video Creative: Cinematic, Brand-Led, Emotionally Resonant

    Prime Video viewers are in entertainment mode. They’ve chosen a show or film, settled in, and the ad represents an interruption to an experience they value. The creative imperative is almost opposite to SBV: instead of getting to the point immediately, Prime Video ads benefit from building a narrative moment, establishing brand personality, and earning attention before making a product claim.

    Cinematic production quality matters more on Prime Video than on any other Amazon surface. A product-demo video that performs well in SBV’s search context can feel jarring and cheap against the production quality of the content surrounding it on Prime Video. Advertisers who repurpose SBV assets directly to Prime Video are not just leaving performance on the table — they’re potentially damaging brand perception by appearing low-budget in a premium environment.

    Interactive formats on Prime Video add another creative dimension: assets designed for pause screen engagement or remote-enabled interaction need to account for the fact that the viewer is on a TV screen, using a remote control, at distance from the screen. Designs optimized for mobile tap interaction don’t translate to 10-foot TV UI. Text needs to be larger, CTAs need to be simpler, and the interaction model needs to feel native to a TV remote rather than a touchscreen.

    Twitch Creative: Live-Aware, Community-Fluent, Fast

    Twitch creative has different rules still. Twitch viewers are attentive and reactive, but they’re also community-aware — they know what advertising looks like, they recognize when they’re being sold to, and they will respond negatively to creative that feels out of touch with gaming or live-streaming culture. Brands that speak Twitch’s visual and cultural language perform. Brands that import polished broadcast TV spots unmodified tend to underperform relative to the platform’s capability.

    For pause screen ads and interactive overlays specifically, Twitch creative benefits from humor, directness, and acknowledgment of the platform context. A pause screen ad that says “You paused your stream. Here’s something worth adding to cart” works better than a brand manifesto. Twitch viewers respect brevity and irreverence in ways that Prime Video’s more passive audience does not require.

    Amazon’s AI creative tools — including the Creative Agent and AI video generation capabilities introduced in 2026 — can dramatically reduce the cost of versioning creative across these three surfaces. Rather than producing three separate campaigns from scratch, brands can now prototype surface-specific creative variants faster than ever, though the creative strategy still requires human direction to ensure each version aligns with its surface’s behavioral context.

    CPMs, Bidding, and Budget Allocation Across the Three-Surface Stack

    One of the practical questions advertisers ask most frequently is how to allocate budget across SBV, Prime Video, and Twitch when they can’t run everything at full scale. The answer requires a clear-eyed view of what each surface is being asked to do and what return metric is being used to evaluate it.

    The CPM Comparison in Context

    The surface-level CPM story looks like this: SBV CPMs in search typically run significantly below Prime Video’s $25–$45 range; Prime Video runs at $25–$45 for standard inventory and higher for premium; Twitch runs at $12–$22 for standard video, with overlay formats at $4–$10+.

    On a pure cost-per-impression basis, Twitch looks cheapest and Prime Video looks most expensive. But this comparison is almost meaningless without accounting for where each surface sits in the purchase journey. An SBV impression delivered to someone actively searching for your product category is worth far more than an equivalent Prime Video or Twitch impression delivered to someone watching a show — even at a higher absolute CPM — because the SBV viewer’s intent is categorically different.

    The right comparison isn’t CPM across surfaces. It’s cost-per-outcome, where “outcome” is defined differently for each surface: cost-per-click for SBV, cost-per-new-to-brand customer for Sponsored TV/Prime Video, and cost-per-brand-lift-point for Twitch awareness campaigns.

    Budget Allocation Models That Make Sense

    For brands with limited video budgets (under $20K/month), the evidence strongly favors concentrating spend in SBV first, building brand familiarity through consistent search-surface video presence before layering in the higher-CPM awareness surfaces. SBV’s combination of purchase intent and video engagement delivers the strongest short-term ROAS, which generates the proof-of-concept needed to justify upper-funnel investment to stakeholders.

    For brands with moderate video budgets ($20K–$100K/month), a hybrid allocation makes sense: approximately 60–70% into SBV and Sponsored Products video for conversion performance, with the remaining 30–40% allocated to Sponsored TV across Prime Video and/or Twitch for reach building and brand lift measurement. At this level, the Sponsored TV spend is generating data about audience behavior that informs SBV targeting and creative iteration.

    For brands at scale ($100K+/month video budgets), the full three-surface strategy with DSP orchestration becomes viable and measurable. DSP’s ability to sequence messaging — awareness on Prime Video, retargeting via SBV in search — creates a flywheel where upper-funnel impressions feed directly into lower-funnel conversions in a way that AMC can track and quantify. The attribution data from scale campaigns consistently shows upper-funnel video contributing meaningfully to conversion outcomes that last-click models credit entirely to Sponsored Products.

    Bidding Mechanics: What’s Changed for SBV Specifically

    SBV uses a separate placement and auction from standard Sponsored Brands, which means bidding strategy should be managed independently rather than grouped with static SB campaigns. In 2026, SBV bids should be set based on the expected contribution of the video impression to the full purchase path, not just the direct click-through conversion — which means using AMC data to understand the halo effect of SBV impressions on organic search performance and Sponsored Products conversion rates before deciding whether to scale bids up or down.

    Full-Funnel Attribution: Why AMC Changes the Measurement Game

    Amazon Marketing Cloud full-funnel attribution connecting Prime Video awareness through SBV consideration to Sponsored Products conversion

    The expanded video stack creates a measurement problem that SBV-only advertisers never had to solve: how do you attribute a purchase that was influenced by a Prime Video impression, an SBV click, and a Sponsored Products click that happened across three days and two devices?

    Last-click attribution — still the default in Amazon Campaign Manager’s standard reporting — credits the final Sponsored Products click and ignores everything that came before it. In a world where advertisers only ran SBV and Sponsored Products, this was an acceptable simplification. In 2026’s three-surface environment, it’s a systematic misrepresentation of how customers actually decide to buy.

    Amazon Marketing Cloud: The Attribution Layer That Changes Everything

    Amazon Marketing Cloud (AMC) is Amazon’s clean room analytics environment, which allows advertisers to run SQL-based queries across their full campaign dataset — including event-level data from SBV impressions, Prime Video ad exposures, Sponsored TV, Sponsored Display, and Sponsored Products — to build multi-touch attribution models that reflect the actual customer journey.

    When AMC data is queried across combined video and search campaigns, the impact of upper-funnel video on lower-funnel conversion is consistently measurable and almost always positive. The typical finding: customers who were exposed to a Prime Video or Twitch ad before engaging with SBV in search convert at a higher rate and with a higher average order value than customers who encountered SBV without prior video exposure. Last-click reports credit the SBV campaign; AMC reveals that the Prime Video exposure was doing meaningful preparatory work.

    This changes the budget case for Prime Video and Twitch investment significantly. An advertiser looking at last-click ROAS for their Sponsored TV campaigns will see numbers that appear unimpressive compared to SBV. An advertiser using AMC to measure the full-path contribution of that awareness spend will often find that the incremental ROAS contribution — factoring in the downstream effect on SBV and Sponsored Products performance — is substantially higher than the surface metrics suggest.

    Conversion Lift and Brand Lift Studies

    For advertisers who aren’t yet set up for AMC analysis, Amazon’s native Brand Lift and Conversion Lift studies provide a more accessible window into upper-funnel performance. Brand Lift studies use Amazon Shopper Panel data to measure changes in awareness, favorability, consideration, and purchase intent among exposed versus unexposed audiences. Conversion Lift studies use a holdout methodology to measure incremental sales driven by specific campaign exposure.

    These tools are available through Amazon Ads for Prime Video and Twitch campaigns and represent a significant improvement over the prior state of play, where streaming video ad spend on Amazon sat in a measurement black box. Brands running Sponsored TV or DSP video campaigns without activating lift measurement studies are effectively flying blind — and missing the data needed to justify ongoing streaming investment.

    Key Attribution Metrics for Each Surface

    A practical AMC measurement framework for the three-surface stack should track distinct primary KPIs for each layer:

    • SBV: Branded search lift, new-to-brand purchase rate, detail page view rate, ROAS on a 14-day attribution window
    • Prime Video/Sponsored TV: Incremental ROAS (from conversion lift), new-to-brand customer percentage, purchase intent lift (from brand lift studies), downstream Sponsored Products conversion lift for exposed audiences
    • Twitch: Brand awareness lift, purchase intent lift (via Brand Lift beta), engagement rate on interactive formats, post-exposure search lift for brand terms

    Audience Targeting: Where the Overlap Gets Genuinely Interesting

    All three surfaces in Amazon’s video stack draw from the same first-party data foundation: Amazon’s customer purchase history, browsing behavior, search patterns, and demographic data across its hundreds of millions of active shoppers. This common data layer creates targeting possibilities that are structurally impossible on platforms that don’t have the same commerce data depth.

    In-Market and Lifestyle Audiences Across Surfaces

    Amazon’s in-market audiences — segments of shoppers who have recently shown buying signals in specific product categories — can be applied across SBV, Sponsored TV, and DSP campaigns. This means an advertiser can reach people who have purchased competitive products in the past 30 days simultaneously in search results (SBV), on their streaming TV (Prime Video), and in live content (Twitch), with a sequenced message tailored to each context.

    The targeting continuity across surfaces is what makes the sequencing strategy viable. On a traditional media plan, reaching the same consumer on TV, digital video, and social requires stitching together third-party data from multiple sources, with inevitable signal loss at each handoff. On Amazon’s stack, the consumer is identifiable across all three surfaces with first-party accuracy.

    Lookalike Audiences and New-to-Brand Acquisition

    For new-to-brand customer acquisition — a priority metric for most Amazon advertisers in 2026 — the ability to build lookalike audiences based on existing buyer data and deploy them across Prime Video and Twitch is particularly powerful. Upper-funnel streaming exposure to lookalike audiences who haven’t yet purchased the brand creates incremental awareness that eventually converts through lower-funnel search campaigns.

    Amazon’s NTB (new-to-brand) measurement, available across all three surfaces, allows advertisers to track whether their video investment is growing their customer base or simply recycling existing buyers. Brands finding that a high percentage of their conversions are repeat purchases should prioritize Prime Video and Twitch for acquisition-oriented creative targeting NTB lookalike segments, rather than using streaming inventory to reach people who already know the brand.

    The Frequency Overlap Problem

    The same data infrastructure that enables powerful targeting also creates a frequency management challenge. Because Amazon’s user profiles are unified across shopping, streaming, and gaming, an active shopper might receive SBV impressions throughout their Amazon browsing session, Prime Video ads during their evening viewing, and Twitch overlay ads during weekend gaming — all from the same brand, on the same day, without the advertiser having set any cross-surface frequency controls.

    Managing cross-surface frequency requires either DSP-level control (which enables unified frequency capping across all placements) or explicit cap settings within each self-serve product, with manual coordination between campaign managers. For advertisers running SBV through Campaign Manager and Sponsored TV through its own interface simultaneously, this coordination is a manual process — and one that many teams currently neglect.

    What to Expect From Interactive and Shoppable Formats

    Interactive and shoppable video formats are the area where Amazon’s stated ambition most clearly outpaces current advertiser adoption. The formats exist, the early data is encouraging, and the potential — turning a passive TV viewing moment into an instant purchase — is commercially compelling. But the operational reality is more complex than the marketing materials suggest.

    Prime Video Interactive Formats

    Prime Video’s interactive ad formats include pause screen ads (which surface when a viewer pauses content), remote-enabled CTAs (which allow Fire TV remote interaction with ad content), QR code integration for second-screen engagement, and shoppable carousel units that allow product browsing without leaving the viewing interface.

    The performance data on interactive formats versus standard video is striking: interactive ads have shown +30% brand awareness lift and +36% order volume versus non-interactive controls in Amazon’s own studies. However, these numbers come from campaigns where the interactive mechanic was genuinely well-integrated with the creative — not simply a “Shop Now” button appended to an awareness spot.

    Interactive Prime Video creative needs to be designed with the interaction in mind from the outset, not retrofitted. The viewer’s decision to interact with an ad in a TV viewing context is a high-friction action relative to a mobile tap — they need a compelling reason to reach for the remote, and the purchase path after interaction needs to be seamless enough to reward the effort.

    Twitch Shoppable Formats: Early Stage, High Potential

    Twitch’s shoppable formats are earlier in their development than Prime Video’s interactive inventory. The most promising emerging format is the shoppable livestream unit, which integrates creator-led product demonstrations with direct purchase capability — essentially bringing the shopping livestream model that has dominated Asian e-commerce into Twitch’s live-content environment.

    Early case studies from beauty brand e.l.f. and other early adopters have shown strong engagement with Twitch shoppable formats, particularly when creator talent is authentically integrated with the product rather than reading from a script. The format works best when the creator’s audience has genuine overlap with the product’s target consumer — and when the purchase mechanic is simple enough that it doesn’t require the viewer to context-switch out of their gaming or viewing flow.

    Amazon’s new sentiment analysis tool for Twitch chat adds a measurement dimension that doesn’t exist anywhere else: real-time audience reaction data that tells brands how their sponsored content is landing with a live community. This is still an early capability, but it represents the kind of measurement innovation that can make Twitch a more defensible media choice for brands willing to invest in genuinely platform-native creative.

    Who Should Be Running What: A Practical Tier Framework

    Not every advertiser on Amazon needs to be running all three video surfaces simultaneously. The right configuration depends on budget, category, brand maturity on the platform, and the specific outcomes being prioritized. Here’s a practical framework for matching advertiser profile to platform strategy.

    Tier 1: SBV-First (Monthly Video Budget: Under $15K)

    For brands with limited video budget, SBV remains the highest-priority allocation. The combination of purchase-intent context, direct conversion attribution, and relatively accessible CPMs makes SBV the strongest short-term ROAS driver in the video stack. At this budget level, Prime Video and Twitch will generate insufficient impression volume to drive statistically meaningful lift measurements, which means spending there before SBV is optimized is premature.

    The Tier 1 priorities are: build a library of SBV assets in both horizontal and vertical formats, establish keyword and product targeting that covers the full relevant search landscape, and run ongoing A/B creative testing to understand which messaging approaches drive the highest detail page conversion rate.

    Tier 2: SBV + Sponsored TV (Monthly Video Budget: $15K–$75K)

    At this budget level, adding Sponsored TV for Prime Video and/or Twitch reach becomes viable. The recommended split is roughly 65% SBV / 35% Sponsored TV, with the streaming allocation oriented primarily toward awareness objectives and new-to-brand customer acquisition. Brand Lift studies should be activated on all Sponsored TV campaigns to generate measurement data that can justify or rebalance the streaming allocation over time.

    Twitch is worth testing at this tier if the brand’s product category has meaningful relevance to gaming, tech, entertainment, or lifestyle audiences. For categories with weak Twitch audience overlap (home improvement, certain food categories, B2B products), Prime Video will typically deliver stronger results at similar spend levels.

    Tier 3: Full-Stack Video with DSP Orchestration (Monthly Video Budget: $75K+)

    At scale, the full three-surface strategy with DSP coordination becomes viable. This is where sequential messaging — Prime Video or Twitch for awareness, SBV for search-stage consideration, Sponsored Products for conversion — can be implemented with proper frequency management and end-to-end AMC attribution.

    Brands at this tier should invest in AMC setup and analysis as a first priority. The attribution data that AMC provides is the foundation for every subsequent optimization decision: which surfaces are contributing incrementally, which audience segments show the strongest path-to-purchase behavior, and where budget reallocation would improve total campaign efficiency.

    Interactive and shoppable formats on both Prime Video and Twitch become worth testing at this budget level, where impression volume is sufficient to generate statistically meaningful interaction rate and lift data within reasonable testing windows.

    The Window Before CPMs Reflect the Reality

    There’s a pattern that recurs every time a major ad platform opens new high-reach inventory: early movers gain access to audiences at CPMs that don’t yet reflect competition. Prime Video CPMs are premium now — $25–$45 is not cheap. But they are almost certainly lower than they’ll be in 12–18 months as advertiser adoption scales and the auction becomes more competitive. Twitch CPMs, still in the $12–$22 range, represent meaningful underpriced access to a specific audience cohort that may prove difficult to reach as efficiently later.

    The 2026 window for Amazon’s three-surface video stack is analogous to the early periods of Sponsored Products adoption (2013–2015), Sponsored Brands adoption (2018–2020), and even early Prime Video ad inventory testing. In each case, the brands that built operational and creative competency early captured a period of below-equilibrium pricing before competition normalized CPMs upward.

    What Builds Durable Advantage Now

    The durable advantage being built by sophisticated advertisers in 2026 isn’t just reach — it’s data. Running Prime Video and Twitch campaigns now generates AMC data on how streaming exposure affects downstream Amazon purchase behavior for your specific brand, audience, and product category. That data builds a proprietary understanding of your customer’s path to purchase that competitors who wait another year to enter the market won’t be able to replicate.

    Similarly, creative learning is cumulative. Brands that are now iterating on Prime Video interactive formats, Twitch pause screen creative, and mobile-vertical SBV assets are building a production and testing infrastructure that gets better over time. The brands entering these surfaces in 2027, when CPMs are higher and competition is stiffer, will be doing so without the creative and measurement foundation that early movers are establishing now.

    Key Takeaways for Advertisers Acting on This Now

    • Don’t conflate surfaces. SBV, Prime Video, and Twitch require different creative, different measurement frameworks, and different success metrics. Running the same asset across all three and evaluating all three on the same KPI is a structural mistake.
    • Set up AMC before you need it. Multi-touch attribution data is only useful if you’ve been collecting it. Brands that activate AMC after building a streaming + search video stack have clean historical data to analyze; brands that activate it after the fact are starting from scratch.
    • Invest in surface-specific creative production. The cost of under-performing creative on Prime Video isn’t just missed impressions — it’s brand exposure in a premium context that damages perception. Budget for creative quality that matches the environment.
    • Test interactive formats now. The brands learning how to convert pause-screen and shoppable ad interactions today are building a competency that becomes a real advantage as Amazon continues to push these formats into wider inventory.
    • Manage cross-surface frequency actively. The same data that makes Amazon’s targeting powerful makes frequency overlap a genuine risk. Build explicit cross-surface frequency management into campaign architecture from the outset.

    Conclusion

    Amazon’s video advertising stack in 2026 is not three separate products that happen to live on the same platform. It’s a connected ecosystem where search-level intent signals (SBV), premium streaming reach (Prime Video), and live-content engagement (Twitch) can be orchestrated together, measured in a closed loop via AMC, and targeted with first-party purchase data that no other platform can match.

    The implication isn’t that every Amazon advertiser needs to be running all three surfaces at full investment immediately. It’s that the logic for how you structure, budget, and measure Amazon video has fundamentally changed. SBV is no longer just a search ad with a video creative. Prime Video is no longer just a TV-style awareness play that can’t be measured in commerce terms. Twitch is no longer a niche platform too small to warrant serious budget allocation.

    What they are, collectively, is the most complete first-party video advertising stack available to commerce brands anywhere — one that reaches over 315 million streaming viewers, tens of millions of live-content viewers, and hundreds of millions of active shoppers, all connectable through a single attribution infrastructure.

    Getting the most out of that stack requires treating it as a system rather than a collection of individual placements. The brands doing that in 2026 are building advantages — in creative capability, measurement infrastructure, and audience understanding — that will compound as the ecosystem matures and the window of below-competition CPMs closes.

  • AI-Generated Visuals Without Suppression: A Practical Playbook

    AI-Generated Visuals Without Suppression: A Practical Playbook

    Split-screen showing suppressed AI image on left with red stamp and lost reach versus verified AI image on right with green checkmark and full distribution — AI Visuals That Don't Get Buried, the 2026 Platform Suppression Map

    You followed the tutorials. You used the right tools. You generated a batch of clean, professional AI visuals, scheduled them across your platforms, and waited for the reach to roll in. Instead, your posts flatlined. Impressions were a fraction of normal. Engagement barely moved. No violation notice, no appeal link — just silence.

    This is not a niche problem. Across Instagram, TikTok, LinkedIn, and YouTube, AI-generated visual content is running into a new and poorly understood set of suppression mechanisms in 2026. Some of these are explicit policy rules — label requirements, disclosure mandates, outright bans on deepfakes. But the more consequential suppression is quieter: algorithmic downranking based on authenticity signals, engagement quality scoring, metadata fingerprinting, and account trust tiers that platforms rarely document publicly.

    Most of the advice circulating about this problem is either too vague (“just be authentic!”) or too focused on the obvious violations — the realistic deepfakes, the political impersonations, the NSFW content that platforms are clearly targeting. What’s missing is practical, technical guidance for the creators and brands operating in the legal middle ground: people generating product images, marketing visuals, conceptual illustrations, and branded content with AI tools, only to find that their content is being quietly buried.

    This playbook is for that group. It covers how platform detection actually works, where the false positive problem is causing real damage, what the C2PA and watermarking standards mean in practice, and how to build a workflow that produces AI visuals capable of reaching the audience they were made for — without triggering the systems designed to suppress the ones that weren’t.

    How Platforms Actually Detect AI Visuals (It’s More Than Just Metadata)

    Infographic flowchart showing the four detection layers platforms use to screen AI-generated images in 2026: metadata scan, visual pattern analysis, behavioral signals, and engagement quality

    The common assumption is that platforms detect AI-generated images by checking for a specific tag or watermark embedded in the file. That’s one layer — but it’s far from the whole picture. In 2026, the detection infrastructure across major platforms is multi-layered, and each layer operates on different signals with different levels of reliability.

    Layer 1: Metadata and Provenance Signals

    The most straightforward detection check is metadata. AI-generated images typically lack the EXIF data that camera-captured photographs carry — information like camera model, GPS coordinates, aperture, shutter speed, and lens data. Platforms including LinkedIn have been reported to flag images as probable AI when EXIF camera metadata is absent and the visual characteristics match AI generation patterns.

    More structurally, platforms are increasingly reading C2PA Content Credentials — a cryptographically signed metadata standard that logs the origin, tools used, and editing history of an image. If an image was generated by Adobe Firefly or exported from a C2PA-compliant tool, that provenance chain is readable by platforms that have integrated the standard. The absence of any provenance metadata on an image that has the visual fingerprint of AI generation is itself a signal.

    Layer 2: Visual Pattern Analysis

    Beyond metadata, platforms and their third-party detection partners run visual analysis on uploaded images. AI image generators — even the most advanced 2026 models — still produce statistically detectable artifacts under certain conditions. These include unnaturally perfect symmetry in faces, anomalous texture rendering in hair and fabric, subtle geometry errors in hands and backgrounds, and frequency domain patterns that differ from optical lens captures.

    Benchmark accuracy for AI image detection tools in clean, unedited conditions reaches 85–95% according to 2026 evaluations. However, this figure drops sharply under real-world conditions. When images are compressed during upload, resized, filtered, or run through any additional editing step, detection accuracy in practice falls to the 60–85% range. This degradation is significant: it means platforms cannot reliably distinguish AI from human-made content purely on visual grounds, which is one reason they increasingly combine visual signals with other data layers.

    Layer 3: Behavioral and Account Trust Signals

    This is the layer most creators don’t think about — and arguably the one with the most practical impact. Platform algorithms assess not just the individual image but the behavioral context surrounding it. Key signals include:

    • Posting frequency and content diversity: Accounts that suddenly post high volumes of visually similar content are flagged for potential spam or mass AI generation. TikTok reporting in 2026 indicates that five or more flagged AI videos within a seven-day window can trigger automated posting restrictions.
    • Account age and historical trust: Newer accounts with no engagement history posting AI content face steeper suppression thresholds than established accounts with strong track records.
    • Content variation patterns: Uploading images that share telltale similarities — identical aspect ratios, matching lighting temperatures, near-identical compositions — signals mass generation even if individual images appear clean.
    • Negative feedback rates: Users who click “not interested” or report content as misleading signal to the algorithm that the content is low-quality or inauthentic, which compounds any existing AI-related suppression.

    Layer 4: Engagement Quality Scoring

    The final and increasingly dominant detection layer is not really about AI detection at all — it’s about content quality as measured by audience behavior. Saves, shares, comments, and dwell time all signal that content is worth distributing. Scrolls, skips, and low watch time do the opposite. In 2026, platforms are explicit that “originality” and “authentic human value” are ranking criteria — language that creates systematic headwinds for mass-produced AI content regardless of its visual quality.

    Understanding that these four layers operate simultaneously and independently is the foundation of any suppression-avoidance strategy. Passing one layer is not enough. Compliant metadata won’t save low-engagement AI content. Strong engagement won’t protect an account that’s posting at spam-like volume with zero content variation.

    The False Positive Crisis: When Real Photos Get Buried Too

    Real photograph incorrectly flagged as AI-generated by a detection system showing 87% confidence, illustrating the false positive crisis — 13% of real photos flagged as AI and 435 false positives per 436 flags in one audit

    Before diving into how to protect AI-generated content from suppression, it’s worth examining a problem that complicates this entire conversation: platform detection systems are wrongly flagging authentic, human-made photos at rates that should concern any creator — AI or otherwise.

    The Numbers Are Worse Than Most People Know

    A 2026 audit of leading AI image detection tools found that approximately 13% of genuine photographs were misclassified as AI-generated. A separate evaluation of a cloud-based image safety system produced what may be the most striking data point of 2026: 435 false positives out of 436 total flagged images in a single moderation run — an accuracy rate of less than 0.3% in that specific dataset context.

    Broader 2026 research puts real-world false positive rates for practical creator workflows in the 10–40% range, depending on the type of imagery, the editing history, and the detection tool. These are not edge cases. Stock photographers using HDR processing, product photographers using studio lighting rigs that produce “too-perfect” results, and photographers shooting with modern mirrorless cameras that apply heavy in-body processing are all generating images with visual characteristics that overlap with AI generation signatures.

    Why This Matters for AI Content Creators

    The false positive problem has two direct implications for creators working with AI visuals.

    First, it means that suppression cannot be reliably predicted by looking at your content and deciding “this doesn’t look AI.” Detection systems don’t work the way human eyes do. An image that looks obviously hand-crafted to a person can look statistically AI-like to a pattern-matching algorithm. This makes understanding the underlying signals — not just the surface appearance — essential.

    Second, it means that the suppression problem is not a matter of platforms cleanly separating “authentic” from “fake” content. The detection layer is imprecise by design, which shifts the practical burden to creators. Passing the detection filter is not about making your AI images look less like AI images — it’s about surrounding your content with signals that increase algorithmic confidence in its legitimacy, regardless of how it was made.

    The Practical Response

    The most reliable response to false positive risk — whether you’re shooting real photos or generating AI visuals — is to build a content presence with strong provenance signals. This means consistent EXIF data where applicable, C2PA credentials on AI-generated work, account-level trust built over time, and engagement patterns that demonstrate genuine audience value. The false positive problem is largely unsolvable at the image level. It’s much more manageable at the workflow and account level.

    The C2PA and Watermarking Stack: What It Actually Does for You

    Diagram of the dual-layer C2PA Content Credentials and SynthID invisible watermarking system showing how they create a trusted AI content zone across the workflow from Adobe Firefly to Instagram upload

    In January 2026, the Content Authenticity Initiative published its State of Content Authenticity report, marking what CAI called “a turning point for Content Credentials, interoperable provenance, and trust in an AI-driven media world.” By mid-2026, the organization had grown to over 5,000 members, and the Singapore Content Authenticity Summit brought together nearly 200 policymakers, technologists, and platform representatives to align on implementation.

    If you’re working with AI visuals at any scale, understanding what C2PA actually does — and what it doesn’t do — is now a practical requirement, not an optional technical deep-dive.

    What C2PA Content Credentials Are

    C2PA (Coalition for Content Provenance and Authenticity) is an open technical standard for attaching a cryptographically signed provenance record to a digital file. When you generate an image with a C2PA-compliant tool like Adobe Firefly, the image is embedded with a manifest that records what tool created it, what inputs were used, when it was created, and any subsequent editing steps. This manifest is cryptographically signed, meaning it can’t be retroactively altered without breaking the signature.

    Platforms that integrate C2PA can read this manifest and use it to display provenance information to viewers — the “Made with AI” labels you see on Instagram and YouTube are increasingly being populated from C2PA data rather than user self-disclosure. For platforms, this shifts the disclosure burden from creator compliance to technical verification, which is more reliable and more scalable.

    What Invisible Watermarking Adds

    The practical limitation of C2PA metadata is that it’s stored in the file container, not in the image pixels themselves. Social platforms routinely strip metadata during upload and recompression. An image that carries a clean C2PA manifest when you download it from Firefly may arrive at Instagram’s servers without that manifest, depending on the platform’s image processing pipeline.

    This is where invisible watermarking — primarily Google’s SynthID for AI-generated content — becomes important. SynthID embeds an imperceptible signal directly into the image pixels, not in the metadata layer. This watermark survives typical compression, resizing, and resampling operations. It can be read by platforms that have integrated SynthID detection even after the EXIF and C2PA metadata have been stripped.

    The 2026 industry standard that’s emerged is the dual-layer approach: C2PA credentials for platforms and viewers that can read them, plus watermarking for resilience against the metadata stripping that happens routinely in upload pipelines. The two technologies solve different parts of the provenance problem.

    The Practical Takeaway for AI Visual Creators

    If you’re generating images with Adobe Firefly, DALL-E 3 via API, or other C2PA-compliant generators, your content already carries credentials. The key decisions you control are:

    • Don’t strip metadata before uploading. If you’re running images through editing tools before posting, verify that your workflow preserves the C2PA manifest. Some third-party editors break provenance chains.
    • Choose generators that output SynthID-compatible watermarks where available. For content that will go through heavy reprocessing, the watermark layer provides resilience that metadata can’t.
    • Understand that credentials don’t prevent all suppression — they prevent misclassification. C2PA marks your content as “declared AI” not as “high-quality content.” The distribution benefits come from accurate labeling allowing the algorithm to treat your content appropriately rather than penalizing it for being unidentifiable synthetic media.

    Platform-by-Platform Suppression Triggers in 2026

    Comparison grid showing AI visual content suppression rules across Instagram, TikTok, LinkedIn, and YouTube — covering label requirements, detection methods, penalties for unlabeled content, and safe content types

    Platform policies on AI-generated visual content diverged significantly in 2026. Understanding that Instagram, TikTok, LinkedIn, and YouTube each have distinct suppression triggers — and distinct levels of enforcement — is essential for anyone managing content across multiple channels.

    Instagram and Meta

    Meta’s publicly stated position is that AI-generated content labeled with the “AI Info” disclosure is not algorithmically penalized. This is technically accurate but practically incomplete. What Meta does suppress is AI content that is unlabeled, misleading, or that falls into the “Made with AI” detection threshold without a matching disclosure. The system applies a label — and potentially restricted distribution — when its automated detection concludes an image is AI-generated and the creator hasn’t disclosed it.

    The more significant suppression pathway on Instagram is quality-based rather than AI-specific. Instagram’s recommendation algorithm has moved firmly toward “originality” as a ranking criterion. Mass-produced AI content — even if labeled — that generates high skip rates and low save rates will see suppressed distribution in Reels, Explore, and feed recommendations. Creator accounts posting large volumes of visually similar AI-generated images have reported engagement declines of 30–50% on affected posts, though Meta has not published specific penalty data.

    Key rules to follow on Instagram: Use the AI label proactively via the Creator tool at upload rather than waiting for automated detection to apply it. Avoid batching identical-style AI images into a rapid posting cadence. Anchor AI visuals to strong captions and calls-to-action that generate comments and saves, since engagement quality significantly mediates any detection-related reach impacts.

    TikTok

    TikTok’s Synthetic Media Policy in 2026 is among the most detailed and actively enforced of any major platform. The platform requires a creator-applied label for any “realistic” AI-generated or heavily AI-manipulated video or image content. Automated detection runs independently and can apply labels or restrict distribution even if creators don’t self-disclose. TikTok also reads C2PA metadata where present.

    The most consequential enforcement mechanism on TikTok isn’t individual post suppression — it’s account-level throttling triggered by repeated violations. Five or more AI-content issues within a seven-day window can activate posting restrictions that limit distribution across an entire account, including content that has nothing to do with AI generation. This cascading effect makes TikTok the highest-stakes platform for AI visual workflow design.

    Key rules to follow on TikTok: Always apply the AI label for any content that depicts realistic people, locations, or events synthetically. For clearly stylized or illustrated AI content — artwork, animations, abstract product visuals — the risk of automated flagging is lower, but when in doubt, label. Never mass-upload AI content batches; space AI-generated posts across multiple days and mix them with non-AI content to avoid behavioral suppression triggers.

    LinkedIn

    LinkedIn’s AI content moderation is less formally documented than Instagram or TikTok, but in practice it operates through a combination of EXIF-based metadata analysis and engagement quality signals. LinkedIn’s algorithm has been reported to flag images lacking camera metadata and displaying visual characteristics associated with AI generation, with reduced distribution in feed and search surfaces.

    LinkedIn’s audience also skews toward professional skepticism around AI-generated content, which creates an organic engagement headwind. AI-generated imagery in LinkedIn posts tends to generate lower saves and shares than real photography among professional audiences, compounding any algorithmic suppression with an audience-behavior suppression effect.

    Key rules to follow on LinkedIn: Use AI visuals for conceptual illustration rather than for depicting realistic professional scenarios. When using AI-generated images of people, use clearly non-photorealistic styles. Supplement AI visuals with authentic context — real company data, actual quotes, genuine expertise — so the content value is clearly human-generated even if the visual is AI-assisted.

    YouTube

    YouTube’s approach to AI-generated visual content is primarily disclosure-focused in the context of Shorts and video thumbnails. The platform requires creators to disclose when AI has been used to generate realistic content that could be mistaken for real. Thumbnail images generated by AI are subject to the same disclosure requirements as video content in 2026.

    YouTube’s suppression mechanism for AI content is more closely tied to click-through rate and audience retention than to detection per se. AI-generated thumbnails that don’t match video content — or that appear misleading — trigger negative audience feedback that algorithmically reduces distribution. The enforcement is behavioral first, policy-based second.

    The Human-in-the-Loop Principle: Why AI-Only Workflows Keep Getting Penalized

    Circular workflow diagram of the Human-in-the-Loop AI visual content pipeline showing the five stages: Creative Brief, AI Generation, Human Review, AI Refinement, and Final QA — with 40-60% faster production and 20% higher engagement results

    The most consistent finding across 2026 research into AI visual content performance is that hybrid human-AI workflows outperform AI-only pipelines on every measurable dimension — reach, engagement, brand safety incidents, and suppression rates. The data suggests hybrid approaches deliver 40–60% faster production than traditional creative workflows while achieving 20% higher engagement than AI-only visual strategies.

    This isn’t a coincidence. Platform suppression systems are explicitly designed to target the content patterns that emerge from fully automated AI pipelines.

    What AI-Only Workflows Get Wrong

    When a team builds an AI visual pipeline that runs from brief to published content without meaningful human intervention, several suppression-triggering patterns emerge almost inevitably.

    Volume without variation. Automated pipelines optimized for throughput generate large batches of visually similar content. Even when individual images are technically distinct, the compositional and stylistic similarity across a batch creates behavioral fingerprints that platform algorithms associate with spam and low-quality content generation.

    No quality gates. AI generators don’t know when an image is off-brand, culturally inappropriate for a specific audience, or visually bland. Without human review, below-threshold content reaches audiences and generates the negative engagement signals (skips, “not interested” reports, low saves) that compound into algorithmic suppression.

    Missing contextual judgment. Platform safety systems increasingly evaluate whether content makes sense in context — whether it’s being posted by an account that has historically created relevant, value-adding content. AI-only pipelines that generate and post content without strategic editorial judgment break the contextual coherence that trust-scoring systems look for.

    What Human-in-the-Loop Actually Means in Practice

    The hybrid loop is not about adding a rubber-stamp review step at the end of an AI pipeline. The research on what works points to human involvement at specific high-leverage stages:

    Brief and creative direction (fully human-led). The strategic framing of what you’re trying to communicate, to whom, and why. This sets the context that makes AI-generated content feel intentional rather than generic.

    Generation filtering (human selects from AI outputs). Rather than automatically posting the first AI output, humans select from a batch — choosing the images that have genuine visual interest, brand alignment, and a quality that’s likely to generate saves rather than skips.

    Editorial refinement (human edits AI output). Even light editing — a crop, a color adjustment, an added text element — does two things. It improves the visual and creates a mixed-provenance signal that reduces the AI-detection confidence score. Images that have clearly been touched by human editing are harder to classify as purely AI-generated.

    Disclosure and contextual copy (human-authored). The caption, the disclosure label, the surrounding copy — these are the human layer that platforms and audiences read to make sense of a visual. Strong, specific, genuine captions are one of the most effective suppression shields available.

    Building the Loop Into Your Team Structure

    The practical question is where human review sits in a workflow that’s trying to maintain speed and volume. The answer depends on what you’re producing. For high-volume social content, a single experienced editor reviewing and selecting from AI batches can process 30–50 images per hour, which is fast enough to maintain meaningful oversight without creating a bottleneck. For brand-critical or audience-facing content, deeper review cycles with specific brand safety checklists are worth the additional time. The key is that “human-in-the-loop” doesn’t mean “slow” — it means thoughtful at the right stages.

    Prompt Engineering for Platform Safety

    Most prompt engineering advice focuses on getting better-looking images from AI generators. Very little of it addresses a different goal: generating images that are less likely to trigger platform suppression systems. These are not always the same objective — and understanding the difference matters.

    What Makes an Image Algorithmically Safe

    Platform suppression at the visual analysis layer is triggered by specific image characteristics. The following prompt engineering principles reduce exposure to those triggers:

    Reduce photorealism where you don’t need it. The highest-risk visual category for AI content suppression is photorealistic images of people, places, and events that could be mistaken for real. Prompts that push into illustration, stylized rendering, graphic design, or clearly conceptual territory generate images that are less likely to be flagged as misleading synthetic media, and less likely to confuse platform detection systems. “Illustrated,” “infographic-style,” “watercolor,” “vector art,” and “flat design” are useful style modifiers for content that doesn’t require photorealism.

    Avoid prompting for real identifiable locations and people. Even when you’re not intentionally generating deepfake content, prompts that include recognizable architecture, brand logos, or characteristics of real individuals create output that can be flagged under impersonation and misleading content rules. Keep your prompts in clearly synthetic territory.

    Use consistent style anchors across your content series. Paradoxically, consistency in visual style is both a suppression risk (if it signals mass generation) and a brand safety asset (if it signals intentional design). The key is establishing a distinctive visual identity — a specific color palette, a particular rendering style, a consistent compositional approach — rather than generating visually varied images from the same generic prompt. Branded consistency reads differently to platform algorithms than cookie-cutter mass output.

    Build in imperfection intentionally. Platform research has identified that the most suppressed AI content tends to be visually “over-perfect” — images with too-smooth textures, impossibly perfect lighting, and zero contextual noise. Adding intentional imperfection through prompts (natural lighting variations, slight depth of field, candid-style compositions) produces output that is both more visually interesting and less algorithmically suspicious.

    The Prompt Review Checklist

    Before submitting any prompt at scale, run it through these four questions:

    1. Does this prompt require generating realistic humans? If yes, shift to illustration or use model-released AI avatar tools specifically designed for this use case.
    2. Does this image need to depict a real place or event? If yes, use clearly stylized or clearly labelled representation rather than photorealistic recreation.
    3. Am I generating a batch of 10+ visually similar images? If yes, introduce deliberate variation in composition, palette, and framing — don’t use the same base prompt repeatedly.
    4. Does this output serve a clear audience value? If the honest answer is “it fills space,” it will perform like filler — low engagement, high suppression risk, brand damage.

    The Engagement Gap: Why AI Visuals Underperform and What Fixes It

    Bar chart comparing 2026 engagement rates across four visual content types: pure AI visuals at 1.8%, AI plus stock blend at 2.4%, AI plus human edit at 3.6%, and human UGC style at 4.2% — with callout noting real photos outperform pure AI by 42% on organic reach

    The most consistent data point in 2026 research on AI visual content is one that many AI enthusiasts don’t want to hear: authentic human-made photos still outperform purely AI-generated images by approximately 42% in organic engagement rate across platforms and industries. This isn’t a trivial gap — it’s the difference between content that the algorithm distributes and content that it quietly deprioritizes.

    Understanding why this gap exists is more useful than arguing about whether it does. Because once you understand the mechanisms, you can address them specifically.

    Why the Gap Exists

    The engagement gap between AI and human visuals in 2026 is driven by three reinforcing factors that are distinct from detection and suppression.

    Audience intuition. People don’t need to consciously identify an image as AI-generated to respond differently to it. The subtle uncanny valley effects in AI imagery — the too-smooth skin, the slightly-off shadows, the backgrounds that don’t quite cohere — register below conscious awareness and reduce the emotional response that drives saves and shares. Audiences interact with AI content more passively than with content that feels human and contextually real.

    Context mismatch. Human-created content tends to carry authentic contextual signals — a real location, a specific moment, an identifiable person — that AI content typically lacks. On social platforms where audiences are looking for genuine experiences and relatable perspectives, the absence of authentic context creates a fundamentally weaker emotional hook.

    Quantity effect. The low marginal cost of AI image generation has flooded feeds with AI visuals. Audience fatigue with generic AI aesthetics is measurable in 2026 engagement data. The visual styles that AI generators defaulted to in 2024 and 2025 — the hyperpolished product shots, the luminous landscape renders, the idealized portrait styles — are now overrepresented to the point of invisibility. Content that looks like everyone else’s AI content gets scrolled past at the same rate as content that is everyone else’s AI content.

    How to Close the Gap

    The engagement gap is not a reason to abandon AI visuals — it’s a brief for using them differently. The data on what performs well points in a clear direction.

    Hybrid production for flagship content. Use AI as a starting point and human editing, real photography overlays, or genuine context-addition as the closing step. Images that combine AI generation with human editorial touch perform closer to authentic human photography than to pure AI output on engagement metrics. The AI provides the efficiency; the human provides the authenticity signal that engagement algorithms reward.

    AI visuals for functional content. AI-generated images perform well — and sometimes outperform human-created alternatives — in specific content categories: product visualization, infographic illustration, conceptual diagram, and abstract brand imagery. These are use cases where photorealism and emotional authenticity are less critical than clarity and visual impact. This is where AI visual investment delivers the best return without fighting the engagement gap.

    Style distinctiveness over aesthetic quality. Generic high-quality AI visuals underperform because they’re indistinguishable from other generic high-quality AI visuals. Developing a distinctive visual style — a specific color palette, a signature compositional approach, an unusual rendering technique — creates content that stands out in feeds even when viewers can identify it as AI-generated. Distinctiveness, not quality alone, is what drives the saves and shares that protect distribution.

    Pair visuals with strong editorial content. Across every platform, the single most consistent engagement driver for AI visual content is high-quality written or spoken context that surrounds the image. Captions that provide specific information, personal perspective, or genuine expertise compensate for the emotional distance that AI visuals sometimes create. Think of the visual as the stop-scroll mechanic and the surrounding content as the engagement driver.

    Building a Compliant AI Visual Workflow in 2026

    The practical question for most teams isn’t “should we use AI visuals?” — that decision is effectively made for most content operations by the time and cost advantages. The real question is how to build an AI visual workflow that is compliant with platform policies, resilient to detection errors, capable of producing engaging content, and sustainable at scale without creating suppression debt that compounds over time.

    The Core Workflow Architecture

    A compliant AI visual workflow in 2026 has six components, each of which addresses a specific suppression risk:

    1. Tool selection with provenance in mind. Choose AI image generators that are built on licensed datasets, that output C2PA Content Credentials by default, and that are either SynthID-compatible or use an equivalent transparent watermarking approach. Adobe Firefly is the current benchmark for this combination. DALL-E 3 via the OpenAI API supports C2PA credentials in its current configuration. Generators with no provenance output create content that arrives at platforms with no authenticity signal — which is a suppression risk by default.

    2. Metadata preservation in your editing pipeline. If you use Photoshop, Lightroom, Canva, or any other editing tool between generation and upload, verify that C2PA credential chains are preserved. Adobe’s tools maintain C2PA manifests through their native editing pipeline. Third-party tools vary — some explicitly strip metadata as a processing step. Run test images through your full editing workflow and check the metadata output before deploying at scale.

    3. Human review gates at generation and pre-publish. Establish two mandatory review points: once immediately after batch generation (to select and reject), and once immediately before publishing (to verify compliance, caption quality, and contextual appropriateness). These gates prevent the low-quality output that drives engagement-based suppression.

    4. Content calendar design that avoids behavioral flags. Structure your AI visual content in your publishing calendar to avoid the rapid-batch-posting patterns that trigger account-level suppression. A maximum of two to three AI-generated visual posts per week per platform is a conservative guideline for accounts without established high-trust signals. Interleave AI content with non-AI content — photography, video, text-based posts — to create the behavioral diversity that distinguishes an editorial content operation from an AI content farm.

    5. Disclosure as a standard operating procedure. Apply AI disclosure labels at upload for any content generated primarily by AI. Do this proactively rather than waiting for automated detection to apply it, for two reasons: proactive disclosure builds audience trust and demonstrates editorial integrity, and it prevents the scenario where automated detection applies a label to unlabeled content, which can trigger additional scrutiny and restrict distribution.

    6. Performance monitoring with suppression-awareness. Track not just engagement metrics but distribution metrics — impressions relative to follower count, reach rate, and exploration vs. follower reach split. Early suppression signals show up in distribution data before they appear in engagement data. Establishing baseline distribution benchmarks for your accounts lets you detect suppression events quickly and trace them to specific content variables.

    Tool Stack Recommendations

    For a compliant 2026 AI visual stack, consider this configuration based on current platform compatibility:

    • Primary generation: Adobe Firefly (best-in-class C2PA support, trained on licensed data, native Creative Cloud integration for metadata preservation)
    • Supplementary generation: DALL-E 3 via API with C2PA output enabled for content requiring different aesthetic capabilities
    • Editing and finalization: Adobe Photoshop or Lightroom with C2PA chain preservation enabled
    • Content scheduling: Platforms that don’t strip metadata during scheduling — verify this for any scheduling tool you use; some third-party schedulers reprocess images in ways that strip provenance data
    • Provenance verification: Adobe’s Content Credentials Verify tool (verify.contentauthenticity.org) to check credential chains before publishing

    Disclosure Done Right: How to Label AI Content Without Killing Your Reach

    The instinct among many creators when facing new disclosure requirements is to comply minimally — apply the required label in the least visible way, with the least informative text, as late in the process as possible. This is exactly the wrong approach, both strategically and practically.

    Why Proactive Disclosure Outperforms Reactive Compliance

    Platform suppression systems in 2026 increasingly distinguish between content that is transparently disclosed as AI-generated and content where AI labels are applied by automated detection after the fact. The latter category triggers additional scrutiny and restricted distribution at higher rates than the former — partly because unlabeled AI content that gets auto-labeled has already demonstrated an intent signal that algorithms read as potentially deceptive.

    More practically, audience reception of AI-disclosed content has shifted significantly in 2026. The widespread awareness that AI visual tools exist means audiences aren’t shocked by disclosure — they expect it. What builds trust is not hiding AI generation but being honest about it while being clear about the human value being added. A disclosed AI visual accompanied by a strong expert caption performs better than an undisclosed AI visual accompanied by generic filler text, in both audience trust and algorithmic distribution.

    How to Write AI Disclosure That Works

    Disclosure language that preserves trust and engagement should do three things: acknowledge the AI tool, state the human purpose it serves, and make clear what genuine value the content provides.

    Generic: “Created with AI.”
    Better: “Visual created with Adobe Firefly to illustrate this data — the analysis and recommendations are ours.”

    Generic: “AI-generated image.”
    Better: “We used AI to visualize this concept — here’s why it matters in practice: [substantive insight].”

    The pattern is consistent: lead with the AI disclosure, follow immediately with the human contribution. This framing positions AI as a tool in service of human expertise rather than a replacement for it — which is how audiences read trustworthy AI content in 2026.

    Platform-Specific Disclosure Mechanics

    Instagram: Use the “AI Info” creator label at upload time via the advanced settings menu. This populates the platform label and prevents automated detection from applying a different label later. In your caption, optional but recommended: a brief one-line acknowledgment.

    TikTok: Apply the “AI-generated content” toggle at upload. For video content that uses AI-generated still images, this applies to the video post overall.

    LinkedIn: LinkedIn does not currently have a native AI disclosure tool. The community norm and best practice is a brief caption disclosure. A parenthetical “(visual created with AI)” at the end of your caption is sufficient and increasingly standard among professional creators on the platform.

    YouTube: Use the AI Disclosure option in the YouTube Studio details panel at upload. This is required for realistic content and best practice for any AI-assisted visual in thumbnails or within videos.

    The Account Trust Investment: Building the Suppression Resistance That Takes Time

    Platform algorithms don’t evaluate every piece of content in isolation. They evaluate it in the context of the account that posted it — its history, its consistency, its audience relationship, and its track record of producing content that audiences value. This account-level trust score functions as a suppression modifier: high-trust accounts get more distribution benefit of the doubt; low-trust or new accounts face tighter suppression thresholds.

    This creates a counterintuitive reality for AI visual strategy: the most important investment you can make in protecting AI-generated content from suppression is not in the AI content itself. It’s in the non-AI content that builds the account trust that protects all of your content.

    How to Build Account Trust Alongside AI Production

    Anchor accounts in authentic human content first. Accounts that launch with exclusively AI-generated visuals have no authenticity history. Platforms signal the inverse — human-made content that establishes authentic engagement patterns creates a trust buffer that makes subsequent AI content less likely to be aggressively suppressed.

    Maintain consistent publishing behavior. Erratic posting patterns — long dormancy followed by sudden high-volume AI content batches — are among the strongest behavioral suppression signals. Consistency in posting frequency, even at lower volume, builds the account regularity that trust-scoring systems reward.

    Engage with your audience genuinely. Platform algorithms measure not just how audiences respond to your content but how you respond to your audience. Accounts that reply to comments, engage with followers, and demonstrate active community participation have higher trust scores than passive broadcast accounts. This is particularly important for accounts that post AI visuals at scale — the human engagement signal compensates for the potentially automated-feeling content pipeline.

    Protect negative feedback rates. The “not interested” report and the unfollow triggered by low-quality content are among the most damaging suppression signals available to audiences. For AI visual content, this means ruthlessly filtering low-quality AI output before it reaches your audience. One batch of poorly-received AI content can erode account trust that takes months to rebuild.

    What Staying Visible Actually Requires: The Honest Summary

    The suppression challenge for AI-generated visual content in 2026 is real, multi-layered, and not going away. Platforms are not accidentally catching AI content in their moderation nets — they are deliberately moving toward authenticity-biased ranking systems that favor content with strong provenance signals, genuine audience value, and human editorial intentionality.

    The creators and brands navigating this successfully are not doing so by hiding the AI provenance of their content or by finding suppression loopholes to exploit. They’re doing it by building workflows that make AI generation serve genuinely human creative and editorial purposes — and by making that human purpose visible to both audiences and algorithms.

    The Non-Negotiable Foundation

    If you take nothing else from this playbook, these five practices are the foundation of suppression-resilient AI visual content in 2026:

    1. Use C2PA-compliant generators and preserve provenance through your editing pipeline. This is not optional bureaucracy — it’s the technical foundation that allows platforms to accurately classify your content rather than suppressing it for ambiguity.
    2. Build human review into your workflow at the selection stage, not just the approval stage. Humans choosing from AI outputs perform better than humans rubber-stamping AI outputs. The selection judgment is where editorial quality gets built.
    3. Disclose AI use proactively and frame it around the human value being added. This is both ethically correct and algorithmically advantageous. Transparency and reach are not in conflict when disclosure is done well.
    4. Design your content calendar to avoid behavioral suppression patterns. Volume, velocity, and variation matter as much as individual image quality. A thoughtful content calendar is part of your suppression defense.
    5. Invest in non-AI content to build the account trust that protects all of your content. AI visual strategy is not separable from overall account health strategy. The trust you build with authentic content protects the AI content you produce alongside it.

    Where This Is Heading

    Platform policies on AI visual content are tightening, not loosening. India’s 2026 regulatory amendments on synthetic content, the Singapore Content Authenticity Summit’s cross-platform provenance alignment, and the rapid growth of C2PA adoption across tool and platform ecosystems all point toward a future where provenance is table stakes, not a differentiator. The creators who build compliant, human-grounded AI visual workflows now will be operating in an environment they understand when the next round of policy tightening arrives. The ones who don’t will be navigating each new restriction reactively — and losing distribution every time.

    AI-generated visuals are a permanent and powerful part of the content creation toolkit. The question was never whether they’d survive platform scrutiny — it was always about building the right workflow to make them thrive within it.

  • What Rufus Actually Sees in Your Image Stack — And Why Most Stacks Are Built Backwards

    What Rufus Actually Sees in Your Image Stack — And Why Most Stacks Are Built Backwards

    Split-screen showing Amazon Rufus AI on a smartphone alongside a structured 7-frame product image stack — What Rufus Sees in Your Image Stack

    There’s a quiet assumption baked into most Amazon image strategies: images are for humans. You shoot a clean hero, drop in some lifestyle photos, maybe add a spec callout or two, and call it a complete listing. The buyer scrolls through, decides they like what they see, and clicks Add to Cart. Job done.

    That model worked fine for keyword-driven search. It’s increasingly wrong for the way Amazon’s AI surfaces and recommends products in 2026.

    Amazon’s Rufus — now integrated into the broader Alexa for Shopping experience — handles roughly 274 million queries per day and has driven an estimated $10 billion in incremental annualized sales. It doesn’t browse listings the way a shopper does. It parses them. It reads your image text through OCR. It classifies lifestyle context through computer vision. It generates embedding vectors from your visuals and matches them against what shoppers describe in natural language. And then it decides whether your product is worth surfacing in a conversational recommendation — or quietly skipping.

    Most image stacks aren’t built for that. They’re built for a human browsing session, laid out in a sequence that feels intuitive to a product photographer but communicates almost nothing to a multimodal AI model trying to answer “What’s a good BPA-free water bottle for hiking that fits in a cup holder?”

    This piece isn’t about making your images prettier. It’s about understanding what Rufus and Catalog Intelligence 2.0 actually extract from your visual stack — and restructuring your images so that extraction produces the right signals. Frame by frame.

    The Shift Nobody Announced: From Keyword Matching to Visual Embeddings

    Amazon didn’t publish a changelog when it started treating images as structured data. There was no seller announcement, no help doc update, no Seller Central notification. The shift happened gradually — and then, with the June 2026 rollout of Catalog Intelligence 2.0, significantly all at once.

    To understand why this matters, it helps to understand what changed architecturally. Before Catalog Intelligence 2.0, Rufus primarily relied on three data sources to match products to conversational queries: listing text (titles, bullets, descriptions), customer review language, and structured catalog attributes (brand, category, dimensions, material). Images were decorative — included in the listing but not meaningfully parsed for discovery purposes.

    The Three-Layer Stack Now Running Under the Hood

    Catalog Intelligence 2.0 introduced a fundamentally different architecture. Rather than treating product matching as a text retrieval problem, Amazon now runs three parallel layers:

    • Conversational/Agent Layer: This is the Rufus interface itself — the natural language understanding engine that processes shopper questions and determines intent. “What sunscreen won’t break me out?” is matched to product attributes using semantic understanding, not keyword presence.
    • Structured Catalog Layer: Traditional catalog data — category, attributes, ASINs, parent-child relationships, brand registry data. This is the backbone of how products are filed and retrieved.
    • Visual Similarity Layer: The new addition. Image embeddings — dense numerical vectors generated from your product photos — are used for grouping, similarity matching, and visual retrieval. When a shopper uploads a photo to Amazon Lens, or when Rufus tries to find “something that looks like this but comes in black,” the visual layer takes precedence.

    The critical implication: image embeddings now influence product retrieval in ways that are completely decoupled from your text copy. A listing can have perfectly optimized bullet points and still rank poorly in visual queries because the images themselves don’t communicate the right signals to the embedding model.

    Diagram showing Amazon's three-layer Catalog Intelligence 2.0 search architecture with visual image embeddings as a primary ranking signal

    What “Image Embeddings” Actually Means in Practice

    An image embedding is a compressed mathematical representation of visual content. When Amazon’s models process your product photo, they’re not saving the pixels — they’re generating a vector that encodes what the image represents: shape, color, texture, context, objects in the scene, spatial relationships, and yes, any text that appears in the frame.

    These vectors are then stored and compared. A shopper describing “a minimalist matte black desk lamp that’s adjustable” generates a query embedding. Amazon’s retrieval system finds ASINs whose image embeddings are closest to that query vector. If your lamp’s images show a cluttered workspace, heavy shadows, and no clear demonstration of the adjustable arm, your embedding won’t match — even if your bullet points say “minimalist, matte black, adjustable” three times.

    This is the core mechanic most sellers are missing: what your images say visually now determines whether you appear in AI-driven searches, independent of what your text copy says.

    How Rufus Processes an Image (Step by Step)

    Understanding the processing pipeline helps you make better creative decisions. Rufus doesn’t evaluate your image stack the way a shopper scrolls through it. It runs multiple passes, each extracting different data.

    Pass 1: Object and Category Recognition

    The first pass identifies what category of product is in the image and extracts primary attributes: product type, dominant colors, visible materials, approximate dimensions relative to context objects. This is where your hero image does its heaviest lifting. A clean white background isn’t just a visual convention — it removes noise from this classification step. Background objects, shadows, and clutter introduce competing signals that degrade classification confidence.

    At this stage, Amazon’s vision model is answering: “What kind of product is this, and what are its primary visible attributes?” The cleaner and more unambiguous your main image, the higher the confidence score on this classification — which correlates directly with how accurately your product is indexed and grouped.

    Pass 2: Context and Use-Case Extraction

    Secondary images are analyzed for scene context. A product photographed in a kitchen registers differently from the same product on a hiking trail. This context isn’t decorative — it’s used to answer questions like “Is this appropriate for outdoor use?” or “Would this work in a home office?” without requiring that information to be explicitly stated in your bullet points.

    This is the pass where lifestyle images contribute to discovery. A running shoe photographed only on a white background misses the opportunity to register “outdoor running” as a contextual signal. The same shoe photographed on a trail, in motion, in natural lighting generates a context embedding that ties it to queries about trail running, outdoor footwear, and active lifestyle categories.

    Pass 3: OCR — Reading Your Image Text

    This is arguably the most underutilized signal in most image stacks. Amazon’s OCR pipeline reads text that appears in your product images — callout boxes, spec tables, feature annotations, claim headers — and adds that text to the product’s indexed data. This is separate from and additive to your listing copy.

    A feature callout saying “48-Hour Battery Life” in your infographic frame is read as text, indexed, and can influence whether your product surfaces for conversational queries like “wireless headphones that last more than two days.” If that claim only appears in your bullets and not in your images, you’re getting half the signal strength you could have.

    Pass 4: Semantic Consistency Check

    Perhaps the most sophisticated pass: Rufus cross-references what it extracts visually against what your listing copy claims. Misalignment between the two — products that appear to be one thing in images but are described differently in text — lowers confidence scores and can suppress your listing in AI-driven placements. This is partly a quality signal, and partly a trust/accuracy signal that feeds into how reliably Amazon thinks your listing represents the actual product.

    The Conversion Data Behind Rufus-Optimized Stacks

    None of this optimization work matters if it doesn’t move conversion. Fortunately, the data is compelling — though it requires some context to interpret correctly.

    Rufus-engaged shoppers convert at roughly 2.7x the rate of non-Rufus shoppers. Sessions where Rufus is actively involved in the discovery path show conversion rates in the 8–14% range, compared to the 6–9% baseline for traditional search. For products with fully optimized visual stacks, practitioners report conversion lifts in the 20–35% range versus listings with minimal or unstructured images.

    Side-by-side comparison showing Traditional Stack with 6-9% CVR versus Rufus-Ready Stack with 20-35% CVR lift — The Conversion Gap

    Why the Lift Is So Large

    The magnitude of the conversion lift is worth examining. A 20–35% CVR increase from image optimization alone is a substantial number — larger than most A/B tests on copy variations or pricing experiments. There are two mechanisms driving it.

    First, Rufus-engaged shoppers have higher purchase intent to begin with. They asked a specific question, got a curated answer, and your product was surfaced as relevant to that specific need. You’re not just getting a browse — you’re getting a qualified referral. When someone lands on your listing because Rufus told them “this matches what you described,” they arrive pre-sold on the category fit.

    Second, a well-structured image stack does conversion work that your text copy can’t fully replicate on mobile. With more than 70% of Amazon traffic now mobile, shoppers frequently scan images before reading a single bullet. A stack that visually communicates use case, scale, key features, and differentiation in the first three frames converts shoppers who never scroll to your bullets. The image stack is doing independent conversion work — and Rufus optimization forces you to build stacks that are genuinely information-dense, which benefits human shoppers too.

    The Visibility Prerequisite

    It’s important to be precise about causality here. Image optimization doesn’t guarantee a conversion lift in isolation — it first has to generate a discovery lift. A beautifully optimized stack on a suppressed or low-visibility listing will show minimal conversion improvement because the traffic volume is too low to move the needle.

    The sequence is: better image embeddings → improved AI-driven discovery → higher-quality traffic → elevated conversion rate → stronger sales velocity → improved organic ranking. Each step depends on the previous one. Sellers who report the largest lifts from visual stack optimization are typically those who saw meaningful increases in impressions from Rufus-driven placements first, followed by the conversion rate improvement on that incremental traffic.

    The 7-Frame Architecture Built for AI Parsing

    Amazon allows up to nine images in most categories. Most sellers use somewhere between four and six. The research consistently points to seven as a high-performing configuration — enough to cover each functional category of visual information without padding the stack with redundant shots that dilute signal quality.

    Here’s how a Rufus-ready 7-frame stack should be structured, and why each position exists.

    The 7-Frame Rufus-Ready image stack showing all seven frames labeled from Hero to Trust Signal

    Frame 1: The Compliance Hero

    This is non-negotiable: pure white background (RGB 255,255,255), product filling at least 85% of the frame, no props, no people, no text overlays. Amazon’s main image policy hasn’t changed, and neither has its function. Frame 1 is your classification anchor — the primary input to Amazon’s object recognition pass. Every deviation from compliance introduces noise into that classification step and risks suppression.

    Resolution matters here more than most sellers realize. Amazon requires a minimum of 1,000 pixels on the longest side to enable zoom, but Catalog Intelligence 2.0 image embedding models produce more accurate, higher-confidence vectors from images at 2,000 × 2,000 pixels or above. Higher resolution gives the model more pixel data to work with, which produces richer embeddings. Shoot at 2,500+ pixels and downscale for upload — don’t shoot at spec.

    Frame 2: The Lifestyle Context Shot

    This is where most stacks make their first mistake. Convention says Frame 2 is a second angle of the product, still on white. That’s the wrong call for Rufus-era optimization. Frame 2 should establish scene context — where this product lives, who uses it, and in what setting. This is the primary input to Rufus’s use-case extraction pass.

    The scene should be unambiguous and specific. “A kitchen” is weaker than “a modern kitchen counter at breakfast time.” “Outdoors” is weaker than “a trail runner on a mountain path.” The more precisely the scene context communicates a specific use case, the more accurately your product gets categorized for related conversational queries. Natural light, realistic settings, and human interaction all strengthen context signal — provided the product remains clearly visible and central to the composition.

    Frame 3: The Primary Feature Infographic

    Frame 3 carries the heaviest informational load. This is your main OCR-indexed frame — a clean product shot overlaid with callout text highlighting two to four primary features or differentiating claims. The text in this frame is machine-read and indexed as searchable data, so the language matters as much as the design.

    Write callouts the way a shopper would ask for them. “BPA-Free” is good. “Dishwasher Safe” is good. “Professional-Grade Stainless Steel” is marginal — it’s a vague claim that doesn’t map well to specific queries. Think about the exact questions shoppers ask Rufus (“Is this safe to put in the dishwasher?”) and write callouts that answer them literally.

    Frame 4: The Scale Reference

    Size misrepresentation is one of the top return reasons across most categories. A dedicated scale reference frame — showing the product next to a common object (hand, coffee cup, laptop, ruler) — reduces return risk and gives the AI a dimensional anchor for image embedding accuracy. It also directly answers one of the most common conversational queries: “How big is this actually?”

    Frame 5: The Close-Up Detail

    Material texture, build quality, connection ports, threading, stitching, screen quality — whichever physical detail drives purchase confidence in your category should be isolated here. Close-up shots improve embedding specificity for material and quality attributes, which matters for queries filtering by build quality or material composition (“real leather,” “heavy duty,” “medical grade”).

    Frame 6: The Secondary Use-Case Scene

    A second lifestyle frame showing a different use scenario broadens the contextual footprint of your listing. If Frame 2 shows the product in a home kitchen, Frame 6 might show it in an office break room or outdoor camping setting. Each distinct use-case scene adds to the contextual diversity of your image embeddings, which increases the range of conversational queries your product can surface for.

    Frame 7: The Trust Signal Frame

    The final frame should communicate proof — awards, certifications, warranties, compatibility standards, sustainability claims, or a social proof summary (star rating callout, review count). This frame is less about AI parsing and more about finalizing the human conversion journey, but it also provides indexed claim data for certification-specific queries (“FDA approved,” “Certified organic,” “Compatible with Alexa”).

    Infographics as Machine-Readable Data — Not Just Design Assets

    Most sellers think of infographic frames as visual aids for shoppers who won’t read bullet points. That’s true — but it’s only half the story. In a Rufus-era stack, an infographic frame is also a structured data input for OCR indexing. How you design it determines how much indexed data you’re generating.

    AI scanner reading OCR text from Amazon product infographic image — showing machine-parseable claims like BPA-Free, 48hr Battery Life, Waterproof IPX7

    The Text Legibility Threshold

    Amazon’s OCR pipeline performs significantly better on text that meets specific legibility standards. Minimum effective font size in a 2,000-pixel image is approximately 30 points — smaller text is frequently missed or misread. High contrast between text and background is critical: black on white or white on dark backgrounds produce the most reliable reads. Styled or decorative fonts with unusual letterforms have lower recognition rates than clean sans-serif typefaces.

    This isn’t just about design aesthetics — it’s about whether the claims in your infographic actually get indexed. A beautifully designed frame where “Hypoallergenic Formula” appears in a 20pt italic script over a gradient background may look great in the gallery but generate zero indexed text. The same claim in a 36pt bold sans-serif with adequate contrast gets read, indexed, and cross-referenced against conversational queries about hypoallergenic products.

    Claim Specificity and Query Matching

    The language of infographic callouts should be optimized for the way shoppers phrase queries, not the way marketers write features. There’s an important difference. Marketing language tends toward the aspirational: “Superior Performance,” “Advanced Formula,” “Engineered for Excellence.” Query language is functional and specific: “lasts all day,” “won’t cause irritation,” “fits in a backpack.”

    Rufus answers natural language questions. The closer your infographic text matches the natural language patterns shoppers use, the more directly it contributes to query matching. Run your top-performing search terms through a conversational filter — ask yourself how a real person would phrase that need as a question — and rewrite your callouts to match those phrasings where possible.

    Spec Tables Versus Feature Callouts

    Both work for OCR indexing, but they serve different query types. Spec tables — formatted grids showing dimensions, weight, capacity, voltage, compatibility — are optimized for attribute-specific queries (“What voltage does this run on?” “How much does it weigh?”). Feature callouts are optimized for benefit-driven queries (“Will this fit in a carry-on?” “Is this waterproof?”).

    A high-performing infographic frame for complex products often combines both: a feature callout header with a compact spec table below. This satisfies both query types from a single indexed frame and works well for categories like electronics, sporting goods, and kitchen appliances where shoppers ask both types of questions.

    Lifestyle Images: Context Signals for Conversational Queries

    Lifestyle photography has always served a conversion purpose — showing the product in use creates aspiration and reduces imagination friction. In the Rufus era, it’s doing something additional: providing context embeddings that determine which conversational queries your listing surfaces for.

    Scene Composition as Keyword Strategy

    Everything in a lifestyle scene generates signal. The demographic of the model using the product suggests who the product is for. The setting establishes use-case context. Props and background objects add category and occasion signals. This means lifestyle scenes should be composed with the same strategic intent as keyword research — because in a multimodal search environment, they’re performing the same function.

    Before shooting a lifestyle scene, list the top three to five conversational queries you want your product to surface for. Then ask: does this scene communicate the context, demographic, and use case that a shopper would describe in those queries? If someone asks Rufus for “a gift for a dad who likes camping,” does your camping-adjacent lifestyle scene feature a middle-aged man? If not, you’re missing a demographic context signal that could be generating relevant traffic.

    The Difference Between Scene-Rich and Scene-Cluttered

    More context is not always better. Lifestyle images that are visually crowded — too many competing objects, overly complex backgrounds, poor product-to-scene ratio — generate noisier embeddings. The AI has more objects to classify, more scene relationships to parse, and a lower confidence score on what the image is actually communicating about the product.

    The product should occupy at least 40% of the visual frame in any lifestyle shot. Background complexity should support rather than compete with the product’s visual presence. A single clear contextual message per frame — this product, this setting, this use — outperforms multi-message scenes that try to communicate everything at once.

    Mobile-Optimized Composition

    With over 70% of Amazon sessions happening on mobile, lifestyle images need to read clearly at 375–414 pixels wide — typical smartphone screen widths. This means foreground subjects should be large enough to be recognizable at thumbnail scale, text overlays (if any) should be readable without zooming, and the primary subject should be unambiguous in the first half-second of viewing.

    A useful test: view all your images in the Amazon app at natural scroll speed. Whatever you can’t process in roughly one second per frame is too visually complex for the average mobile browsing session. Simplify compositions until each image communicates its primary message at a glance.

    The OCR Factor: Writing Image Text That AI Can Read and Index

    OCR indexing through product images represents one of the clearest, most actionable opportunities in current Amazon optimization — and it’s almost entirely overlooked. The mechanism is straightforward: Amazon reads text in your images, indexes it, and uses it to match your listing to relevant queries. But getting that mechanism to work reliably requires understanding its constraints.

    What Gets Read and What Gets Missed

    Amazon’s OCR pipeline performs well on standard Latin characters in common typefaces at adequate size and contrast. It struggles with: stylized or script fonts, text on complex or gradient backgrounds, text rotated beyond approximately 15 degrees from horizontal, text smaller than roughly 30pt in a 2,000px frame, and text that overlaps with the product itself in ways that create visual interference.

    A practical approach: for any text claim you want indexed, test it by photographing the image at a reasonable distance, then running a standard OCR tool (Google Vision, AWS Textract, or similar) against the exported JPG. If a standard commercial OCR tool misreads or misses your text, Amazon’s pipeline likely will too. Fix legibility issues before uploading.

    The Additive Indexing Benefit

    The reason OCR indexing is so valuable is that it’s additive to your listing text. You’re capped on bullet point space. Your title has character limits. Your product description can only say so much before it becomes walls of text that shoppers won’t read. Your image text has no direct character limits (beyond practical legibility), and it indexes as additional data for your listing’s search profile.

    A listing with seven infographic-rich images can effectively double or triple the amount of indexed claim text associated with the ASIN compared to a listing relying only on text copy. For competitive categories where the top ten listings share similar keyword coverage in their text fields, that additional indexed image text can provide meaningful differentiation in AI-driven matching.

    Consistency Between Image Text and Listing Copy

    Amazon’s semantic consistency check — the fourth processing pass described earlier — compares what image OCR extracts against listing copy. Claims that appear in images but nowhere in your listing text aren’t necessarily problematic, but claims that contradict your listing text or appear only in images with no supporting copy create lower confidence scores in cross-modal validation.

    Best practice: every claim in your infographic text should be reflected somewhere in your listing copy, even if not in identical language. “48-Hour Battery Life” in your infographic should be supported by at least a mention of battery duration in your bullets or description. This reinforces the consistency signal and ensures both text and image data point in the same direction for the claims you most want matched.

    A+ Content and the Metadata Layer Rufus Also Reads

    The image stack in the main gallery isn’t the only visual layer Rufus processes. A+ Content — enhanced brand content below the fold — contains its own set of images, and those images come with an often-ignored feature: alt text fields.

    A+ content optimization checklist for Rufus showing alt text fields, image description boxes, and connection to Rufus AI chat window

    A+ Alt Text: The Least-Used Optimization in Seller Toolkits

    Every image module in Amazon’s A+ Content builder has an alt text field. The vast majority of sellers either leave these blank or fill them with generic placeholders like “product image 1.” This is a significant missed opportunity.

    Alt text in A+ Content modules is indexed by Amazon’s search and AI systems. It’s essentially free structured text tied directly to specific visual contexts. A 150-character alt text description for a comparison chart image — “Comparison table showing Model X at 48-hour battery life, 32oz capacity, and waterproof IPX7 rating versus competitor models” — adds indexable claim data that neither your main listing text nor your gallery images may cover.

    The framework for writing effective A+ alt text: describe what the image shows (the visual content), what it demonstrates (the product attribute or claim being communicated), and why it matters to the shopper (the benefit or use case). This three-part structure ensures the alt text contributes to discovery, conversion, and accessibility simultaneously.

    Module Structure and the AI Reading Order

    Amazon’s A+ module templates have different visual layouts, but they all share one common characteristic from a data perspective: the text fields and alt text fields associated with each module are processed in order, creating a sequential narrative that Amazon’s AI can follow. The order in which you present modules matters — not just visually, but structurally.

    A+ modules should follow the same information architecture logic as your main image stack: lead with use-case context, progress through feature specifics, provide comparison data mid-way, and close with trust and brand signals. This creates a coherent narrative that the AI can follow and summarize — which matters because Rufus sometimes generates product summaries from A+ content for conversational responses.

    Premium A+ and Video Consideration

    Premium A+ content (available to brand-registered sellers who meet eligibility thresholds) includes additional module types, including video embeds, interactive hotspot images, and comparison carousels. From a Rufus optimization perspective, these are valuable primarily because they increase the amount of parseable, indexable content below the fold.

    Video in A+ is worth special attention: Amazon can extract both visual frames and audio transcriptions from embedded product videos, adding another data layer. A product demonstration video with clear narration — “I’m placing the 32-ounce bottle upside down to show the leak-proof seal” — generates both visual scene context and indexed text from the transcript. Sellers in competitive categories with strong Premium A+ programs are building meaningful informational advantages that pure text or gallery optimization can’t replicate.

    Testing Your Stack for Rufus Readiness — A Practical Audit Framework

    Optimization without measurement is just guesswork. Here’s a structured approach for auditing your existing image stacks and prioritizing improvements.

    The Five-Question Audit

    Run each ASIN’s image stack through these five questions before deciding what to change:

    1. Does Frame 1 meet technical compliance without ambiguity? Pure white background, 85%+ product fill, minimum 2,000px resolution, no text or props. If not, this is your first fix — gallery suppression or deprioritization in object classification costs everything downstream.
    2. Do Frames 2–6 collectively cover all major use cases for this product? Map each frame to a specific query type: demographic use, setting context, feature claim, dimensional reference, material quality. Missing categories mean missing query coverage.
    3. Is every text claim in your infographic frames readable by a standard OCR tool? Export your infographic frames as JPGs and test them. Fix legibility issues before worrying about anything else in the infographic design.
    4. Is there semantic consistency between your image text and listing copy? Every claim in your images should have a corresponding mention in your text fields. Identify gaps and patch them in bullets or description.
    5. Are your A+ alt text fields populated with descriptive, claim-specific content? If not, this is often the fastest, lowest-effort optimization available — it requires no reshooting, no design work, just writing.

    Using Rufus Itself as a Diagnostic Tool

    One of the most underused testing approaches is simply asking Rufus (now Alexa for Shopping) about your own products. Log in with a test account, open the AI assistant, and ask the kinds of questions your target shoppers would ask. Does your product surface? What does Rufus say about it? Does its summary accurately reflect your key claims, or does it describe your product in ways that suggest the AI parsed it differently than you intended?

    Pay attention to which features Rufus mentions in product summaries. Those are the signals it successfully extracted from your listing and images. Features it doesn’t mention — even if they’re prominent in your bullets — may indicate extraction failures that image optimization can address. This diagnostic approach can reveal specific gaps much faster than broad optimization testing.

    Prioritizing Changes by Impact

    Not all image stack changes deliver equal ROI. In order of expected impact based on available practitioner data:

    1. Hero image compliance and resolution upgrade — Highest impact, affects all downstream AI processing.
    2. OCR legibility fixes on existing infographic frames — High impact, low cost, no reshooting required.
    3. A+ alt text completion — High impact, zero cost, purely a writing task.
    4. Moving lifestyle context to Frame 2 — Medium-high impact, may require reshooting or reordering.
    5. Adding missing use-case frames — Medium impact, requires new photography.
    6. Claim language optimization in infographic text — Medium impact, requires design iteration.

    Start with the highest-impact, lowest-cost interventions. Items 1–3 can often be completed without any new photography, making them week-one priorities. Items 4–6 require production investment but deliver the most significant long-term improvement to AI-driven discovery.

    What This Means for Product Launch Strategy

    The implications of Rufus-era image optimization extend beyond existing listings. For new product launches, the image stack is now a pre-launch strategic asset — not a post-launch optimization task.

    Building the Stack Before the Shoot

    The most efficient approach for new launches is to define your image stack architecture before booking the photo shoot. Identify which queries you want to surface for. Map those queries to scene contexts, feature claims, and demographic signals. Then brief your photographer on specific scenes, compositions, and prop requirements derived from that query mapping — not from generic “Amazon photography best practices.”

    This reverses the traditional workflow where photography happens first and then gets optimized for listing requirements. In a Rufus-optimized workflow, listing requirements (specifically, AI query coverage) drive photography briefs. The difference in outcomes is substantial: a photographer briefed to “shoot lifestyle scenes that answer specific shopper questions” will produce very different images than one briefed to “shoot the product in use.”

    Category-Specific Stack Considerations

    Different product categories have different AI parsing priorities. In electronics, spec legibility and compatibility signals dominate — a buyer asking “Does this work with my MacBook?” needs to find that compatibility claim in your image text. In apparel, fit, material, and styling context matter most — lifestyle scenes need to communicate how the item looks on real bodies in real settings. In supplements and health products, certification and ingredient claim visibility is primary — “Third-party tested,” “No artificial colors,” “NSF certified” need to be OCR-indexed and not just buried in description copy.

    Audit the top-performing listings in your category (not your current competitors — the category leaders) and analyze what their image stacks are doing. What types of claims appear most consistently in infographic frames? What scene contexts do their lifestyle images share? What trust signals appear in Frame 7? This competitive visual analysis will give you a category-specific optimization template that goes beyond generic best practices.

    Conclusion: Your Image Stack Is a Data Structure, Not a Photo Gallery

    The fundamental shift Rufus and Catalog Intelligence 2.0 require is a change in how you think about product images. A gallery is passive — it waits for a shopper to scroll through it and decide whether the product looks appealing. A data structure is active — it communicates specific signals to an AI system that uses those signals to match your product to shopper queries you may never see directly.

    Sellers who continue to build image stacks as galleries will see increasing marginalization in AI-driven discovery. Sellers who rebuild their stacks as structured visual data — with each frame serving a specific parsing function, text claims optimized for OCR legibility and query matching, lifestyle context deliberately mapped to target queries, and A+ metadata populated with indexed claim text — are building a compounding advantage in how Rufus surfaces and recommends their products.

    The 274 million daily Rufus queries aren’t going away. The $10 billion in incremental sales they represent will flow disproportionately to listings that communicate clearly to AI — not just to shoppers. The conversion data is clear: Rufus-engaged sessions convert at 2.7x the baseline rate, and optimized stacks drive 20–35% CVR lifts on top of that. The only question is whether your image stack is earning those recommendations or being quietly skipped.

    Actionable Takeaways

    • Audit Frame 1 for compliance and resolution first. Everything downstream depends on accurate object classification. Upgrade to 2,500px minimum and ensure pure white background compliance.
    • Move lifestyle context to Frame 2. Scene context extraction happens early in the processing pipeline. Don’t waste that position on a second angle shot.
    • Test all infographic text with a commercial OCR tool before uploading. If it can’t be read by standard OCR, Amazon’s pipeline likely misses it too.
    • Write infographic callouts in query language, not marketing language. Think “How would someone ask for this feature in a Rufus chat?” and write to match.
    • Complete every A+ alt text field with descriptive, claim-specific copy. It’s the fastest, zero-cost optimization currently available and almost universally neglected.
    • Audit your own ASINs through Rufus/Alexa for Shopping. What Rufus says about your product tells you exactly what signals it successfully parsed — and what it missed.
    • Brief photography shoots from query mapping, not generic best practices. Build the stack architecture before the shoot, not after it.

    The image stack has always been a conversion asset. In 2026, it’s also a discovery asset, a data structure, and increasingly, the primary input to AI-driven product matching. Build accordingly.

  • The Discipline of Less: How to Ship Multi-Agent Workflows Without Tool Sprawl Killing Them

    The Discipline of Less: How to Ship Multi-Agent Workflows Without Tool Sprawl Killing Them

    Diagram contrasting chaotic tool sprawl in a single AI agent versus a clean hierarchical multi-agent architecture with scoped tools

    There is a particular kind of confidence that hits engineering teams around the six-week mark of a multi-agent build. The orchestrator is wired up. The sub-agents are firing. The demo runs clean. And because it runs clean, someone — usually the person closest to the product — asks: Can we also add the Salesforce connector? And maybe pull in Jira? And while we’re at it, the billing system needs to be in scope too.

    This is how tool sprawl starts. Not with a bad decision, but with a series of individually reasonable ones.

    By the time the system hits production, it is not uncommon to find a single agent wired to thirty, forty, sometimes sixty tools it will never actually call on any given task. The context window is bloated before a single token of real work is generated. The agent’s tool-selection logic — never perfect to begin with — degrades under the weight of too many options. Latency climbs. Costs balloon. And when something goes wrong, the trace spans read like a map of a city no one designed.

    The engineering community has a name for this now: tool sprawl. And in 2026, it has become one of the most documented, most discussed, and most underestimated failure modes in production multi-agent systems. A Q1 2026 survey of enterprise AI deployments found that the average large enterprise runs approximately 12 distinct AI agents, with nearly half operating in silos and exhibiting overlapping, poorly governed tool access. The percentage of multi-agent pilots that fail within six months of production deployment sits at roughly 40%.

    The fix is not better models. It is not a smarter orchestration framework. It is discipline — architectural discipline around what tools exist, which agents can see them, and when they are loaded. This post is about building that discipline before you ship, and recovering it if you already haven’t.

    What Tool Sprawl Actually Looks Like in Production

    Tool sprawl does not announce itself. It accumulates. The pattern typically unfolds in three distinct phases, and recognizing them early is the fastest way to avoid the mess they create.

    Phase One: The Generous Scope

    In early development, it feels safe — even sensible — to give agents broad access. You are still discovering what the workflow needs. Restricting tools at this stage feels like premature optimization. So the agent gets everything: the CRM, the database, the file system, the email client, the calendar API, the internal knowledge base, the billing system, and a handful of MCP servers someone found on GitHub.

    This is fine for prototyping. It becomes a structural liability the moment you stop prototyping.

    Phase Two: The Feature Creep Multiplier

    Every stakeholder who touches a multi-agent workflow eventually asks for one more integration. The support team wants ticket creation. Finance wants expense categorization. The data team wants a direct hook into the warehouse. Each request is legitimate in isolation. Each one adds another tool to the agent’s manifest. No one removes the tools that were added for previous use cases, because removal feels risky — what if something depends on it?

    The MCP ecosystem has made this dramatically worse. A Q1 2026 census of MCP servers across public registries found 17,468 distinct MCP servers available for agent integration. The barrier to adding a new tool has never been lower. That accessibility is genuinely useful. It is also the reason tool lists metastasize.

    Phase Three: The Silent Degradation

    This is the phase most teams notice too late. The system is in production. It mostly works. But accuracy on complex tasks has quietly dropped. Certain prompts return wrong tool calls — the agent reaching for a search API when it should be writing to a database, or calling a read endpoint when a write was intended. Token costs are higher than projected. Response times are inconsistent.

    None of these symptoms trigger an obvious alert. There is no “too many tools” exception in your logs. The degradation is statistical, not categorical. And that makes it extraordinarily hard to diagnose without purpose-built observability from the start.

    The core mechanism is straightforward: when you give an LLM more tools to choose from, tool-selection accuracy drops. Research across production deployments consistently identifies a practical ceiling of roughly 5 to 8 tools per agent before selection errors become a meaningful reliability risk. Above 15 tools, the signal-to-noise ratio in tool descriptions degrades to the point where the model frequently selects plausible-but-wrong options — a failure mode that compounds across multi-step workflows in ways that are difficult to trace.

    The Compounding Reliability Math Nobody Likes to Run

    Staircase infographic showing compounding failure rates in multi-agent chains from 95% reliability at one agent to below 60% at ten agents in sequence

    One of the most uncomfortable facts in multi-agent engineering is that system reliability is multiplicative, not additive. Every agent in a sequential chain introduces its own failure probability. Those probabilities compound.

    If each agent in your pipeline has a 95% step-level success rate — which is optimistic for complex real-world tasks — the math looks like this:

    • 1 agent: 95.0% end-to-end success
    • 3 agents in sequence: 85.7%
    • 5 agents: 77.4%
    • 8 agents: 66.3%
    • 10 agents: 59.9%

    A ten-agent workflow where every individual step is 95% reliable will fail to complete successfully four times out of ten. In production, that is not a reliability problem. It is an unusable system.

    Tool Sprawl Degrades the Per-Step Rate

    The compounding math becomes even more damaging when tool sprawl is involved, because sprawl directly lowers the per-step success rate. An agent that calls the wrong tool does not get a partial credit — the error propagates downstream, carrying corrupted context into the next step. Recent analysis of production multi-agent systems found that when agent topology does not match task shape, collapse rates can reach 90.7%.

    This is the core reason tool discipline matters so much in multi-agent systems specifically: a single poorly scoped agent in the middle of a pipeline can corrupt the reliability of every agent that follows it. The failure is not local; it is systemic.

    The Coordination Overhead Tax

    Beyond individual step failures, tool sprawl adds a coordination overhead that compounds latency at scale. Every time an agent must select from a large tool set, that selection requires more context processing, more model inference, and in some architectures, multiple sampling passes. Multiply that overhead across every step in a workflow, across every concurrent workflow run, and the cost trajectory becomes nonlinear fast.

    One documented 2026 production consolidation effort found that simplifying agent topology — reducing trace spans from 18–34 down to 5–8 per run — dropped median task cost from $0.62 to $0.11 and median latency from 47 seconds to 14 seconds. The model did not change. The underlying tools did not change. The architecture around them did.

    Context Window Contamination: The Hidden Token Tax

    Infographic showing how tool descriptions, schemas, and prior tool results consume the majority of an LLM context window before any actual task content is processed

    Here is a test worth running on any multi-agent system you are currently operating: count the tokens consumed by tool definitions before the first meaningful user-task token is processed. The results are often alarming.

    Tool definitions in an LLM context are not free. Each tool requires a name, a description, a parameter schema, and often example invocations. A well-documented tool might consume 300–500 tokens. An agent wired to 30 tools is starting every single call with 9,000–15,000 tokens of overhead — before the system prompt, before conversation history, before the actual task content. On a 128K context model, that is already 7–12% of the available window consumed by tool schema alone.

    The Cascade Effect on Long-Running Workflows

    The contamination problem compounds in long-running agentic workflows. Frameworks like LangGraph and CrewAI, by default, append every step’s output — including full tool call records and responses — to the agent’s state. In a ten-step workflow where each step involves two or three tool calls with verbose JSON responses, the accumulated state can consume the majority of the context window before the final steps execute. This produces one of the most frustrating failure modes in multi-agent systems: the silent degradation at the end of a long workflow.

    The model does not announce that it is operating on compressed context. It does not throw an exception when it hits the window limit. It simply begins to reason less accurately, hallucinating tool behaviors, misremembering earlier steps, or selecting actions that contradict decisions made earlier in the same run. The output looks plausible. It is wrong.

    What This Means for Tool Design

    Every tool you add to an agent’s context is a permanent tax on every call that agent makes. The discipline here is treating tool descriptions the same way good engineers treat code comments: concise, precise, purposeful, and regularly pruned. Verbose tool documentation that reads beautifully in a README is costly overhead when it runs in a context window ten thousand times a day.

    There is also a second-order consideration that most teams miss: the quality of tool descriptions affects selection accuracy more than the quantity. An agent with ten tightly written, clearly differentiated tool descriptions will outperform an agent with thirty loosely described tools every time. The investment in schema quality pays compound returns across the entire system’s operational life.

    The Topology Trap: Why Architecture Shape Matters as Much as Tool Count

    Multi-agent workflows fail not only because of too many tools, but because the structure of the agent graph does not match the structure of the underlying task. This mismatch — what practitioners now call the topology trap — is one of the least discussed root causes of multi-agent production failures.

    Task Shape vs. Agent Shape

    Every task has a natural shape. Some tasks are sequential: output A feeds input B, which feeds input C, with strict ordering. Others are parallel: five independent subtasks that can be executed simultaneously and merged at the end. Still others are hierarchical: a planner decomposes a goal into subgoals, each handled by a specialist, with results synthesized back up. When your agent architecture mirrors the task’s natural shape, coordination overhead is minimized and tool routing is clear. When it does not, you get bottlenecks, redundant work, and agents calling tools they should not need.

    The most common mismatch in practice is building parallel architectures for sequential tasks. Teams reach for parallelism because it sounds faster. But if task step B requires the output of step A to determine which tool to call, forcing parallelism means either guessing or re-doing work. The apparent speed gain evaporates, and the tool call surface expands because each parallel agent must defensively cover multiple branches of the task instead of one narrowly scoped path.

    The Orchestrator Bottleneck

    Many teams default to a centralized orchestrator — one manager agent that routes all work to sub-agents. This pattern is sound in principle but creates a specific failure mode at scale: the orchestrator becomes a single point of both performance bottleneck and context accumulation. Every delegated task result flows back through the orchestrator’s context. If the orchestrator is also the entity managing tool selection across the entire workflow, you have effectively concentrated all the tool-sprawl risk into a single agent.

    The fix is not to eliminate the orchestrator, but to make it deliberately narrow. The orchestrator should know which sub-agent to call, not which tools those sub-agents use. Tool knowledge belongs inside the sub-agent boundary, scoped to its domain. The orchestrator should never need a direct connection to a tool it does not personally invoke.

    Matching Topology to Task: A Practical Heuristic

    Before building any multi-agent architecture, map the task’s dependency graph explicitly. If the graph is a straight line, build a sequential chain with prompt chaining, not a full multi-agent system — the single-agent baseline will likely be cheaper and more reliable. If the graph has genuine parallelism (truly independent subtasks), parallelize. If the graph is hierarchical, build a one-level hierarchy and resist the urge to add additional layers unless the data explicitly requires them. Each additional orchestration layer adds coordination overhead and multiplies the tool-management surface.

    The Least-Privilege Principle, Applied to Agent Tools

    Architectural diagram showing least-privilege tool design with specialized sub-agents each enclosed in security boundaries containing only 3-4 scoped tools, contrasted with a bad single-agent pattern holding 40+ tools

    Security engineers have enforced the principle of least privilege for decades: a process should have access to only the resources it needs to complete its current task, and nothing more. It is time for multi-agent architects to apply the same discipline to tool access.

    The instinct in most multi-agent builds is to be generous with tool access because it feels safer. What if the agent needs this tool for an edge case? What if we restrict too much and the workflow breaks? This instinct is precisely backwards. Generous tool access creates more failure modes, not fewer, because it increases the space of wrong actions an agent can take.

    Defining the Minimum Viable Tool Set

    Every agent in a well-architected multi-agent system should be able to answer the question: What is the exact set of tools I need to complete my assigned task? If the answer includes tools needed by other agents in the same system, that is a boundary problem — those tools belong with those agents, not shared across the graph.

    The practical exercise is to enumerate each agent’s core task, then work backward to the minimal set of tools that task requires. This exercise consistently reveals two things. First, most agents need far fewer tools than they were initially given. Second, many “tools” that appear in the initial list are actually multi-step operations that should themselves be broken into smaller, more precisely scoped tool definitions.

    A research agent, for instance, might be given a generic “web access” tool that can search, retrieve, parse, and summarize arbitrary web content. Decomposing that into a targeted search tool, a URL fetch tool, and a text extraction tool — each with tight parameter schemas — dramatically improves selection accuracy and makes failures much easier to attribute and debug.

    Read vs. Write Permissions as a First-Order Concern

    One of the fastest wins in agent tool design is enforcing read/write separation explicitly. Most agentic tasks spend the majority of their steps reading: gathering information, retrieving context, validating current state. Write operations — creating records, sending messages, triggering actions in external systems — are typically a small fraction of total steps but carry the majority of risk.

    Giving every agent read/write access to every system because “they might need to write eventually” violates least privilege and creates serious security and reliability exposure. An agent that can write to the CRM, send email, and create support tickets has a much larger blast radius when it makes a wrong tool selection than one that can only read from those systems and must hand off to a dedicated action agent for writes.

    Building this separation into the architecture — not just into prompts or guidelines, but into the actual tool permissions assigned to each agent — gives you a genuine safety layer that does not depend on model behavior. That matters, because model behavior under edge-case inputs is never fully predictable.

    Tool Registry and Agent Gateway: The Control Plane That Actually Works

    Architecture diagram showing an Agent Gateway control plane handling auth, policy, routing, and audit between agents and a Tool Registry containing approved tools with schema versions and access policies

    For teams operating at any real scale — multiple agents, multiple workflows, multiple teams contributing tools — ad hoc tool management becomes unworkable fast. The solution that has emerged across 2026 production deployments is a two-component control plane: a tool registry paired with an agent gateway.

    The Tool Registry: Single Source of Truth for Agent Capabilities

    A tool registry is a centralized catalog of every approved tool available to agents in a system. Each entry contains the tool’s name, schema, ownership, version history, access policy, and production readiness status. Agents do not hard-code their tool lists — they query the registry to discover what is available to them, filtered by their assigned permissions and the current task context.

    The registry pattern solves several problems simultaneously. It eliminates the “which version of this tool does this agent use?” confusion that plagues ad hoc multi-agent systems. It gives platform and security teams a single point of control for approving, deprecating, or restricting tools without touching agent code. And it provides an audit surface: if a tool is called unexpectedly in production, the registry log tells you exactly which agent called it, when, and in what context.

    The scale of the problem this addresses is significant. That Q1 2026 census of MCP servers found 17,468 servers across public registries — with only a fraction production-ready under enterprise governance standards. Without a registry layer, every team in an organization can independently wire their agents to any of those servers. With one, the catalog of approved, tested, policy-compliant tools is defined once and enforced everywhere.

    The Agent Gateway: Policy Enforcement at the Boundary

    If the registry is the catalog, the gateway is the door. An agent gateway sits between all agents and all tools, intercepting every tool call and enforcing authentication, authorization, rate limits, and policy rules before the call is allowed through. No tool call happens outside the gateway’s visibility.

    This architectural pattern has clear analogues in API management and service mesh design — it is the same principle as an API gateway in microservices, applied to the agent-to-tool interaction layer. The gateway does not contain business logic. It enforces policy. That separation of concerns is what makes it maintainable: security policies change independently of agent behavior, and neither side needs to know the internal details of the other.

    Production implementations of this pattern — including work done with Solo.io’s agentgateway project — have shown that centralizing MCP and LLM traffic through a gateway improves cost visibility, enables governance across heterogeneous agent types, and removes the need to modify individual agents or MCP servers when policies change. The gateway abstracts the policy layer entirely.

    What This Architecture Does Not Solve

    It is worth being direct about the limitations. A registry and gateway control plane is an infrastructure-layer solution. It does not fix poorly designed tool schemas. It does not prevent an agent from making a logically wrong tool call when the tool is technically permitted. And it adds an operational surface that must itself be maintained, monitored, and versioned.

    Teams that implement this pattern without also investing in schema quality and agent-level tool minimization will find that they have built an excellent auditing layer over a still-sprawling tool estate. The control plane is necessary but not sufficient. It works best as the enforcing layer around sound architectural decisions already made upstream.

    Dynamic Tool Loading vs. Static Tool Injection: A Decision Framework

    One of the most important architectural decisions in multi-agent tool management is whether each agent receives its tool set statically at initialization or dynamically at the point of each task. Both patterns have legitimate use cases, and choosing the wrong one for your workload has meaningful consequences for both cost and reliability.

    Static Tool Injection: When It Makes Sense

    In static injection, agents are initialized with a fixed, predetermined set of tools. Every call that agent makes sees the same tool manifest. This is the simpler pattern and the right default for workflows where the task domain is well-defined and the tool set is small — ideally under eight tools.

    Static injection is predictable. The context overhead per call is constant and known. Testing is straightforward because tool availability does not vary across runs. And for agents that always operate in the same domain — a customer support agent that only ever queries tickets, reads account records, and creates follow-up tasks — the fixed set is not a constraint; it is a design feature.

    The failure mode of static injection is when it gets applied to general-purpose agents. A general-purpose agent with a static 40-tool manifest is paying the full context tax on every call, regardless of what the current task actually needs. The math makes this untenable at scale.

    Dynamic Tool Loading: The Right Pattern for General Agents

    Dynamic loading — retrieving tool definitions at task time based on the current context, intent, or task metadata — solves the context bloat problem for general-purpose agents. Instead of including all tool schemas in every call, the agent’s orchestration layer queries the registry for the relevant subset, fetches only those definitions, and injects them into the context for that specific call.

    This pattern requires more infrastructure. The retrieval mechanism itself needs to work reliably, quickly, and with semantic understanding of the task context — a tool retrieval step that adds 500ms of latency before every agent call defeats much of the purpose. The most effective implementations use embedding-based semantic search over tool descriptions, retrieving the top-k most relevant tools for the current intent rather than pattern-matching on keywords.

    Expert guidance in 2026 consistently favors dynamic loading over static injection for any agent that will operate across more than one domain or handle task variety beyond a narrow scope. The retrieval overhead is real but manageable; the context savings across thousands of daily runs are substantial.

    A Practical Decision Heuristic

    The framework is simple: if your agent does one thing and does it consistently, static injection with a minimal tool set is correct. If your agent handles varied requests across multiple domains, dynamic loading with a centralized registry is worth the infrastructure investment. And if you find yourself justifying static injection for a general-purpose agent because dynamic loading “sounds complicated,” that is typically a signal that the agent’s scope is too broad to begin with.

    MCP as the Consolidation Layer: What It Solves and What It Doesn’t

    Model Context Protocol has become the dominant standard for tool access in multi-agent systems in 2026, with adoption across OpenAI, Google, Microsoft, and AWS and 97 million monthly SDK downloads reported at its peak. MCP’s promise is real: a standardized way for models to access tools, data sources, and external services without every integration requiring bespoke glue code.

    For teams wrestling with tool sprawl, MCP appears at first glance to be a direct solution. One protocol, one integration model, one way to connect any agent to any tool. If everything speaks MCP, the proliferation problem should solve itself.

    It does not. And understanding why is important for any team treating MCP adoption as a tool-sprawl mitigation strategy.

    What MCP Actually Standardizes

    MCP standardizes the interface between models and tools. It defines how a model requests tool invocation, how parameters are passed, how results are returned, and how errors are communicated. It does not standardize what tools exist, how many an agent should use, what they should be permitted to do, or how they should be governed across an organization.

    In practice, MCP makes it dramatically easier to add new tools to an agent’s repertoire — which, without accompanying governance, makes tool sprawl faster, not slower. The Q1 2026 census of 17,468 MCP servers is partly a testament to MCP’s success as a standard and partly a warning label. Most of those servers were created by developers exploring the protocol’s possibilities. A significant portion have no security posture, no versioning discipline, and no organizational ownership structure suitable for production use.

    The 2026 Spec Changes That Matter

    The 2026-07-28 MCP release candidate addresses some of this by introducing a stateless core designed to scale on standard HTTP infrastructure. This makes multi-agent, multi-tool topologies more operationally tractable — stateless tool servers are simpler to deploy, scale, and recover than stateful ones. The spec also strengthens OAuth/OIDC-aligned authentication, tightening the security posture that earlier MCP deployments left under-specified.

    The clearest architectural guidance from 2026 MCP practice is a division of responsibility: use MCP for the model-to-tool layer (standardizing how agents invoke capabilities), and use a separate agent-to-agent (A2A) protocol for agent-to-agent coordination (delegation, negotiation, result sharing between agent nodes). Conflating these two layers — trying to make MCP do both — creates architectural confusion and governance gaps that are difficult to remediate after the fact.

    The Right Way to Think About MCP and Sprawl

    MCP is a tool for integration quality, not tool quantity. Adopting MCP reduces the cost of each individual integration. The discipline of deciding which integrations to make, how many an agent should access, and under what governance they operate — that discipline is entirely separate from the protocol and must be enforced at the architecture and policy level. MCP is necessary infrastructure. It is not a substitute for the harder organizational work of tool governance.

    Observability-First Shipping: Measuring What Actually Matters

    Before-and-after comparison showing production metrics after tool consolidation: latency from 47s to 14s, cost per task from $0.62 to $0.11, eval pass rate from 71% to 84%, incident resolution from 45 minutes to 8 minutes

    One of the clearest markers of teams that successfully ship multi-agent workflows — versus teams that ship and then spend months firefighting — is the presence or absence of purpose-built observability from day one. Observability in multi-agent systems is not optional, and it is not the same as the observability you already have for monolithic services or single-LLM deployments.

    Why Standard Monitoring Falls Short

    Traditional application monitoring tells you whether services are up, whether requests are succeeding, and how long they are taking. Multi-agent workflows require a different category of instrumentation because the most important failures are semantic, not technical. The service can be up. Requests can succeed. Latency can be within spec. And the agent can still be consistently selecting the wrong tool, producing subtly wrong outputs, and propagating errors downstream through a pipeline that looks, from the outside, like it is working fine.

    The documented improvement in mean time to root-cause — from 45 minutes down to roughly 8 minutes in the consolidation case study cited earlier — came primarily from trace span reduction, not from better monitoring tools. Fewer spans meant that when something went wrong, the failure was localized in a smaller search space. Observability quality is a direct function of architectural simplicity. You cannot instrument your way out of a system that is too complex to reason about.

    The Metrics That Matter

    In multi-agent production systems, the metrics worth tracking fall into four categories:

    • End-to-end task success rate: Not per-agent accuracy, but the rate at which complete workflows produce correct, usable outputs. This is the number that reflects actual user value, and it is the number most teams measure too late.
    • Tool call accuracy: For each agent, what percentage of tool calls are to the correct tool? This metric, tracked over time and segmented by agent and task type, is the earliest signal of tool-selection degradation from context bloat or scope creep.
    • Token cost per successful task completion: Total token cost normalized to successful completions. This denominates cost by value, not just by volume, and surfaces the hidden cost of failed runs that consume tokens without producing usable output.
    • Trace span count per run: A high and rising span count is a leading indicator of architecture complexity growth. The teams that caught tool sprawl early were tracking this metric and setting alert thresholds on it before problems became visible in downstream metrics.

    Human-in-the-Loop Checkpoints as Observability Tools

    Beyond instrumentation, the most operationally mature multi-agent deployments in 2026 use human-in-the-loop checkpoints not just as safety mechanisms but as signal collection points. Every time a human reviews and approves or overrides an agent decision, that event is a labeled data point about the accuracy of that agent’s behavior in that context.

    Teams that track override rates by agent and by tool type are building a continuously updated picture of where their workflows are unreliable. That picture, reviewed weekly, often reveals that specific tools are being called correctly 99% of the time — and certain other tools are being misused chronically. The fix is either better schema descriptions, narrower agent scope, or, frequently, the recognition that a tool should not be in that agent’s manifest at all.

    The discipline of treating human feedback as structured observability data — rather than one-off corrections — is one of the clearest differentiators between teams shipping reliable multi-agent systems and teams perpetually fighting fires in them.

    The “Agents as Tools” Inversion That Changes Everything

    There is a counterintuitive architectural pattern that deserves more attention than it typically gets: treating entire agents as tools that other agents can invoke, rather than building monolithic multi-agent systems where every agent has direct access to the full tool surface.

    In this pattern, a specialist agent — say, a data retrieval agent with deep access to your warehouse, your CRM, and your analytics layer — is exposed to an orchestrator not as a peer participant in the workflow, but as a callable capability. The orchestrator calls data_retrieval_agent(query=...) the same way it would call a tool. The specialist agent handles its own tool access internally, exposing only a clean interface to the outside world.

    Why This Pattern Reduces Sprawl

    The “agents as tools” inversion naturally enforces the scoping that least-privilege design requires. Because each specialist agent is encapsulated behind an interface, the orchestrator never needs to know — or have access to — the tools that specialist uses internally. The orchestrator’s tool manifest contains only the callable agents it coordinates, not the underlying capabilities each one wraps. This single architectural choice can reduce the orchestrator’s effective tool surface from dozens of specific capabilities to a handful of well-defined agent interfaces.

    It also dramatically simplifies debugging. When a workflow fails, the failure trace points to a specific agent-as-tool invocation. The failure is contained within that agent’s scope and diagnosable in isolation, without needing to trace through the full workflow graph to understand which underlying tool call was the actual root cause.

    Versioning and Upgrading Agent Capabilities

    The encapsulation benefit extends to lifecycle management. When a specialist agent’s underlying tool set changes — a new API version, a deprecated endpoint, a revised data schema — none of that change propagates to the orchestrator or to other agents in the system. The interface stays stable; the internals change independently. This is the same modularity principle that makes microservices maintainable, applied to the agent layer.

    Teams that have adopted this pattern consistently report that it dramatically reduces the coordination cost of upgrading individual components of a multi-agent system, because interface stability means changes are local by default.

    Building the Habit Before You Need It: An Engineering Checklist

    The most effective time to prevent tool sprawl is during initial system design, before the first agent makes its first tool call in production. The patterns described throughout this post are significantly harder to retrofit than they are to build from the start. The following checklist captures the key decision points where architectural discipline prevents future pain.

    Before You Build

    • Map the task dependency graph. Write out every step of the workflow explicitly. Identify which steps can run in parallel, which are strictly sequential, and which require human review. Let the task structure determine the agent structure — not the other way around.
    • Default to single-agent. Ask honestly whether a single well-prompted LLM with a minimal tool set could handle this workflow. If the answer is yes, that is your starting point. Add agents only when you have measured evidence that the single-agent approach is insufficient.
    • Define each agent’s minimum viable tool set before writing any code. For each agent in your planned architecture, document: what is its single responsibility, what specific tools it needs to fulfil that responsibility, and what tools it should explicitly not have access to. Treat this document as a design constraint, not a suggestion.
    • Separate read tools from write tools at the permission level. Do not rely on prompt instructions to keep agents from writing when they should only be reading. Enforce this at the tool permission layer.

    Before You Ship

    • Count your trace spans in staging. If a workflow produces more than 8–10 spans per run for a single task, that is a signal worth investigating before production. It often reveals redundant agent invocations or unnecessary tool calls that can be eliminated without changing workflow outcomes.
    • Run a tool utilization audit. After a week of staging traffic, produce a count of how often each tool in each agent’s manifest is actually called. Tools called in fewer than 5% of runs are candidates for removal from that agent’s default manifest — and possibly for dynamic loading if they are genuinely needed for edge cases.
    • Establish baseline eval pass rates and cost-per-completion targets. Ship with pre-committed alert thresholds on these metrics. Without targets established before launch, there is no objective basis for distinguishing normal operational variance from systematic degradation.
    • Document the governance owner for every tool in the registry. Every tool in production should have a named owner responsible for its schema, its uptime, and its deprecation. Tools without owners become orphaned liabilities that no one is willing to remove.

    After You Ship

    • Review tool utilization monthly. Agent workflows drift. New task patterns emerge. Tools that were once frequently called become rarely used. Tools that were added for edge cases become load-bearing for common cases. Monthly review catches this drift before it becomes architectural debt.
    • Treat rising span counts as a primary incident trigger. A significant increase in average trace spans per run — even without a corresponding increase in error rates — indicates that the workflow is doing more coordination work to accomplish the same task. That is almost always a warning sign worth investigating.
    • Run quarterly “can we remove this?” reviews on the tool registry. The default organizational inertia is to add tools and never remove them. A deliberate removal practice — requiring justification for keeping a tool rather than for removing it — counteracts this inertia.

    Conclusion: Narrow First, Expand Deliberately

    The multi-agent AI landscape in 2026 is characterized by a growing gap between ambition and operational reality. The ambition — autonomous, interconnected agent systems that handle complex enterprise workflows end to end — is legitimate and achievable. The operational reality — sprawling tool estates, cascading reliability failures, context windows consumed by schema before real work begins, and debugging experiences that resemble archaeology more than engineering — is also legitimate and widespread.

    The gap between the two is not filled by better models, smarter frameworks, or more expressive protocols. It is filled by engineering discipline: the willingness to start narrow, to enforce scoping as a design constraint rather than an optimization, to measure what matters rather than what is easy, and to resist the gravitational pull of adding one more tool because it might come in handy.

    The data is consistent. Teams that ship reliable, cost-effective multi-agent workflows in production share a common trait: they treat architectural simplicity as a first-class concern, not an afterthought. They run fewer agents with fewer tools. They instrument before they scale. They audit regularly and remove aggressively. They build agents as encapsulated modules with clean interfaces, not as sprawling processes with broad permissions.

    This is not a limitation on what multi-agent systems can do. It is the foundation that makes it possible for them to do it reliably, at scale, over time.

    Build narrow first. Measure everything. Expand only where the data says to. That is the architecture that ships — and keeps shipping — in production.

    Key Takeaways

    • Keep each agent’s tool set to 5–8 tools maximum. Above 15, selection accuracy degrades materially and context costs compound nonlinearly.
    • Model your agent topology on your task dependency graph — not on your organizational structure or your instinct for parallelism.
    • Enforce read/write separation at the permission layer, not the prompt layer. Prompts are not a security boundary.
    • Implement a tool registry + agent gateway control plane before you scale beyond three agents or two teams contributing tools.
    • Use dynamic tool loading for general-purpose agents operating across multiple domains. Static injection only for narrow, domain-specific agents.
    • MCP standardizes the interface to tools, not the discipline around their use. Governance must be built separately and deliberately.
    • Trace span count is a leading indicator of architectural complexity growth. Set thresholds before launch, not after problems appear.
    • Treat every human override of an agent decision as structured observability data. Review override rates by agent and tool type monthly.